-
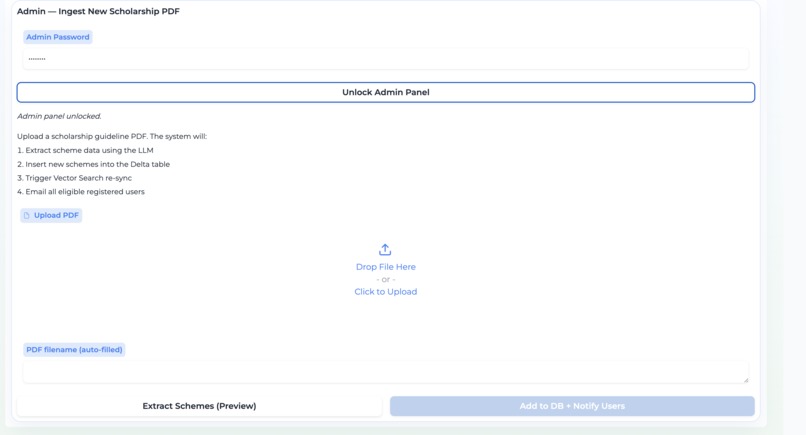
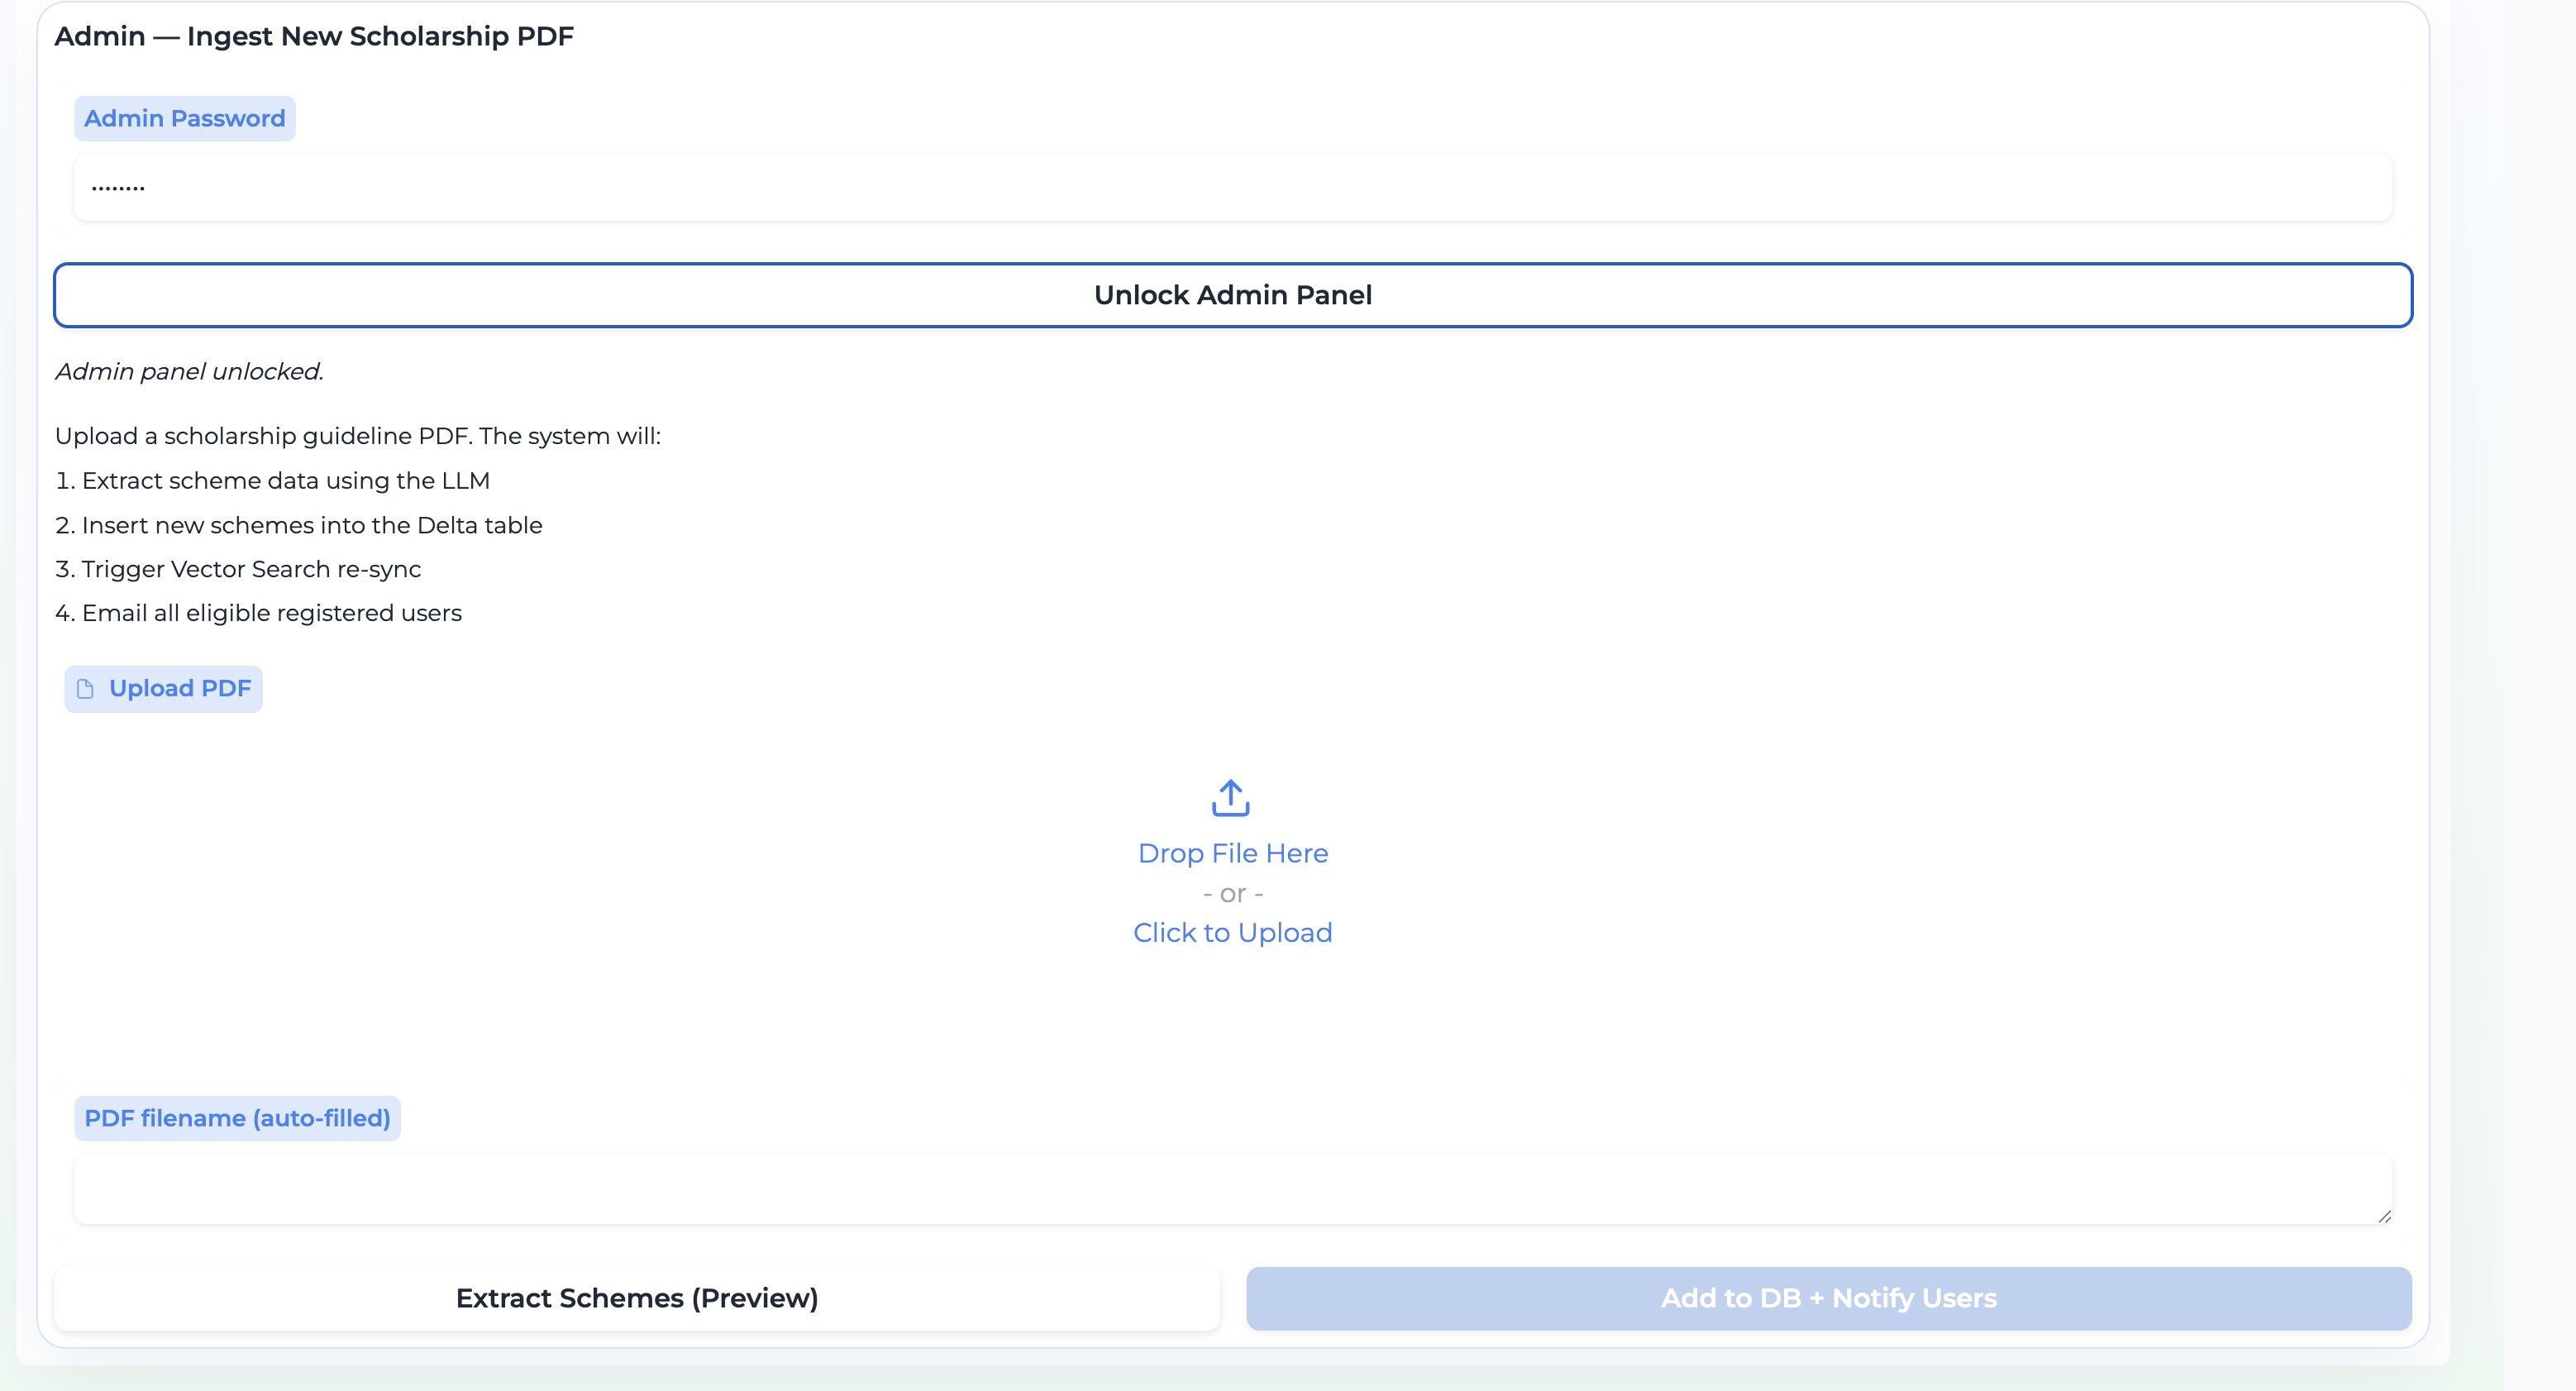
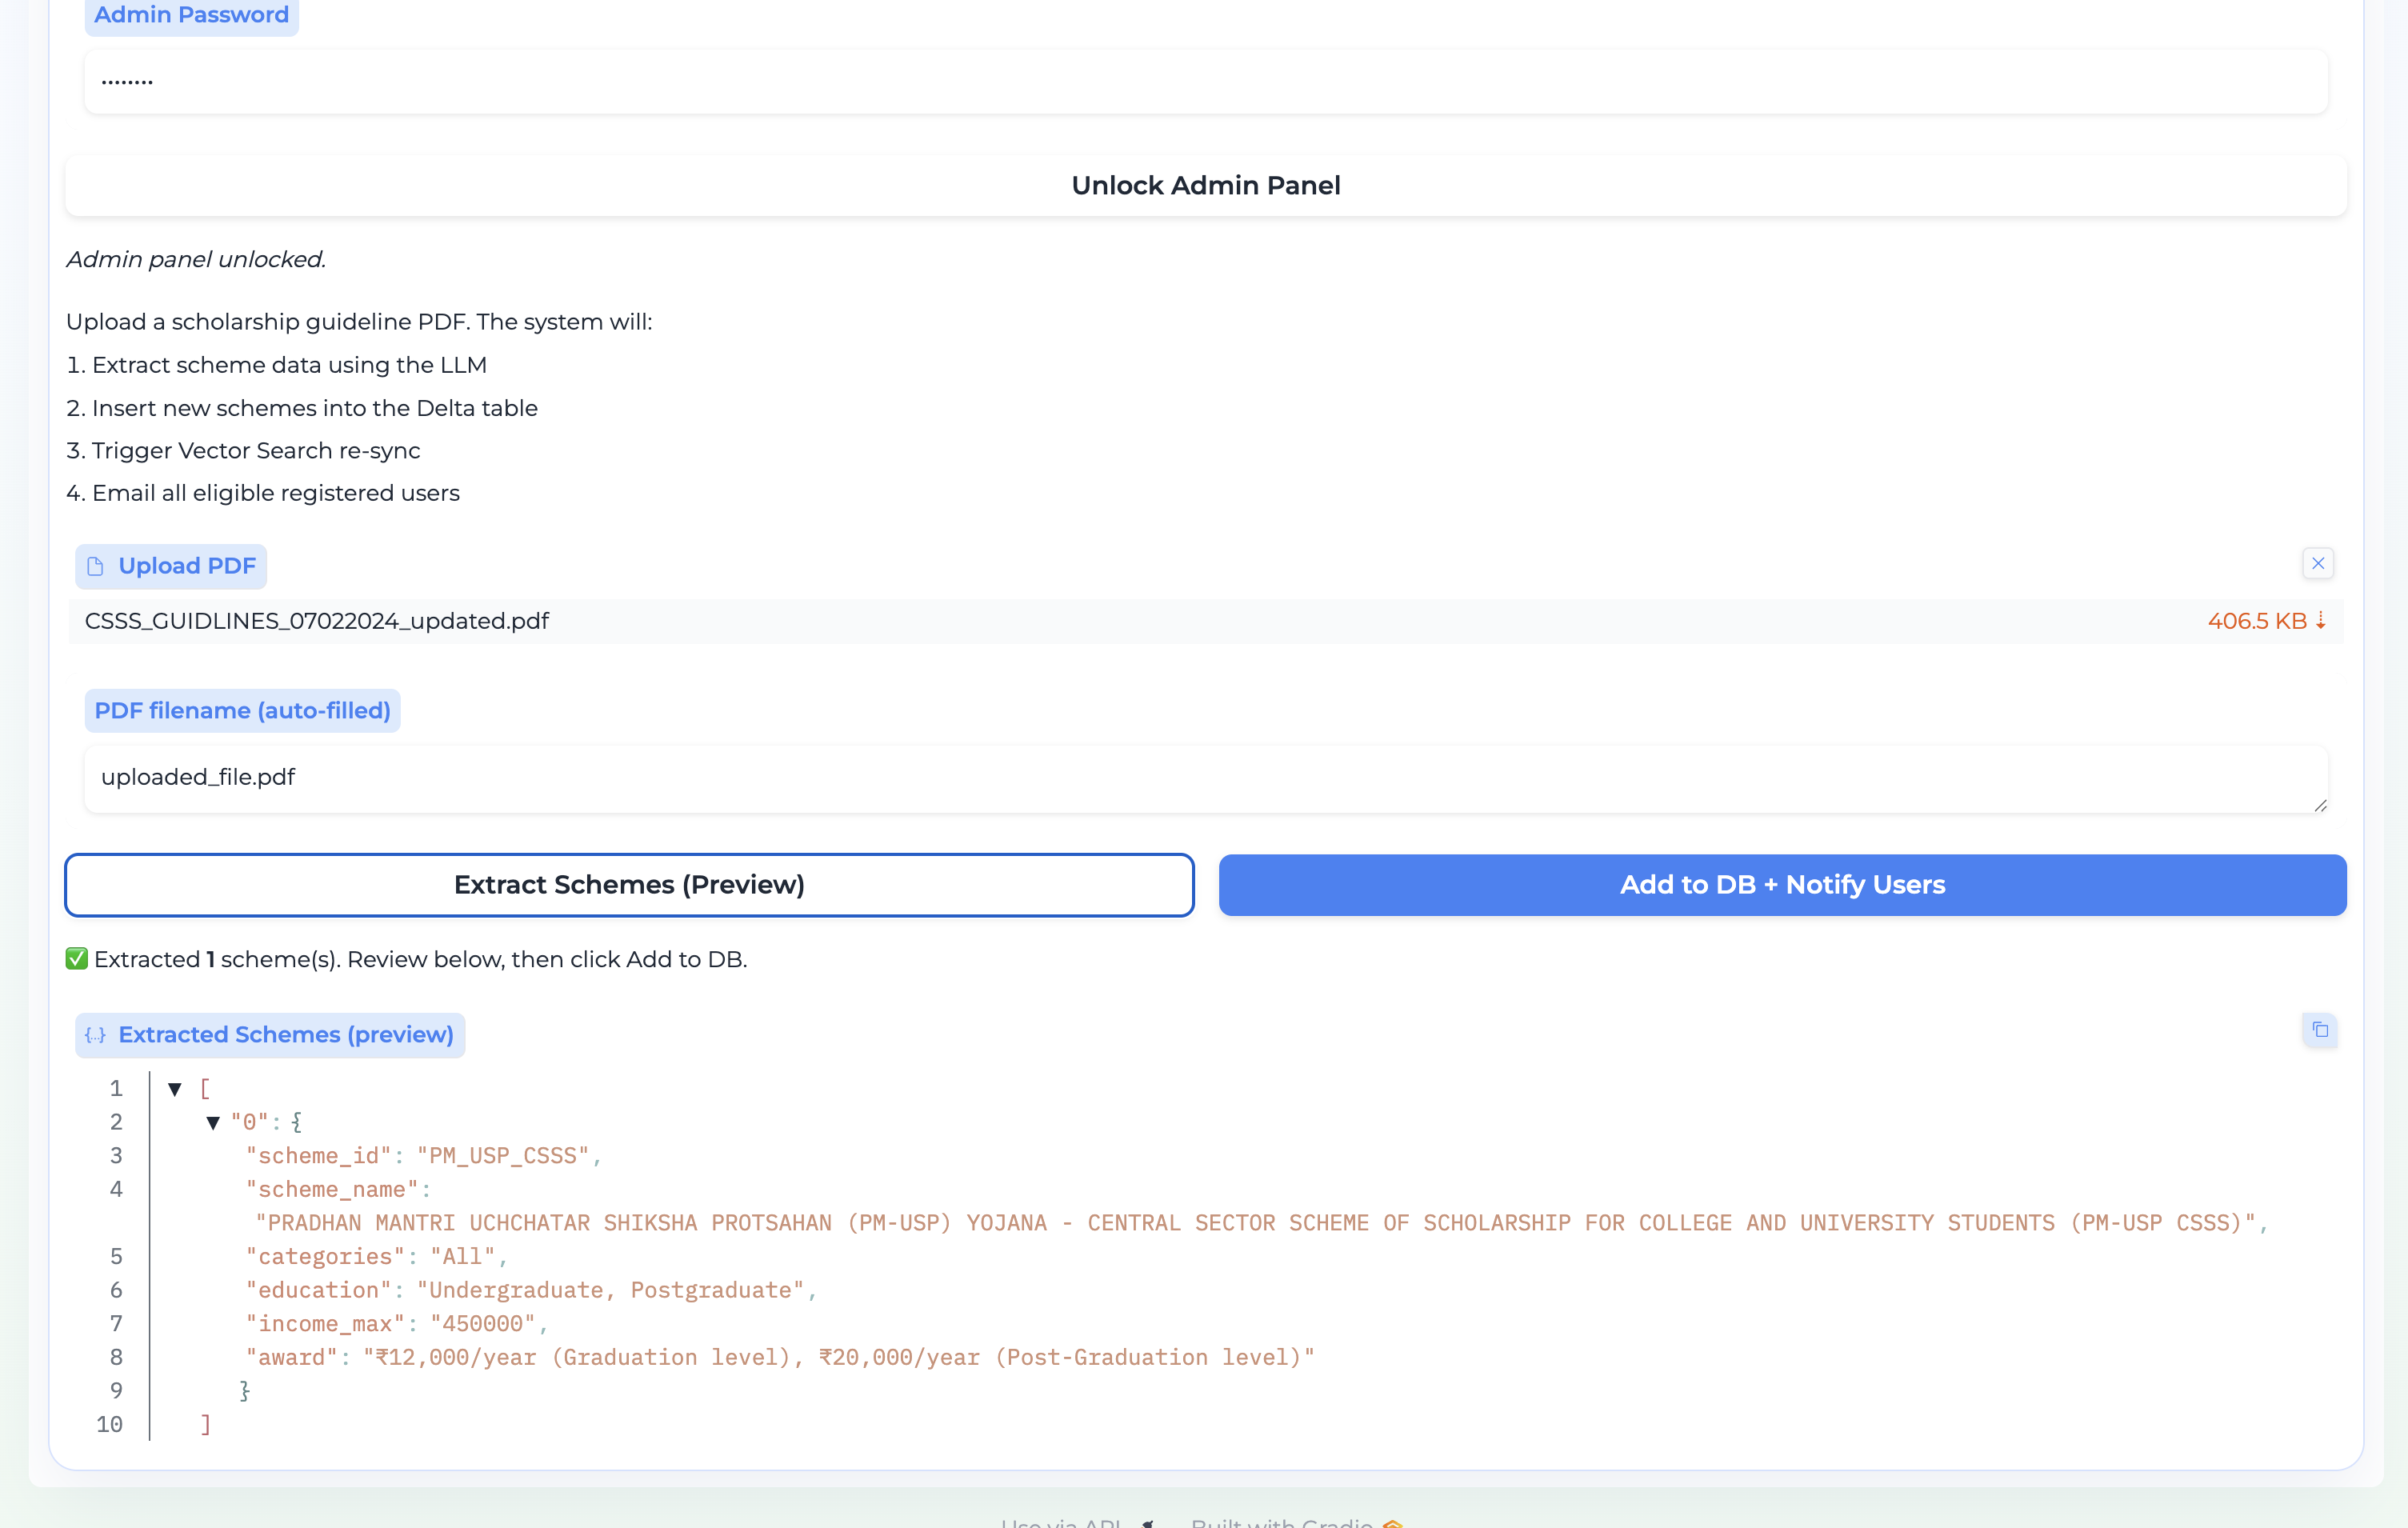
Admin Tool
-
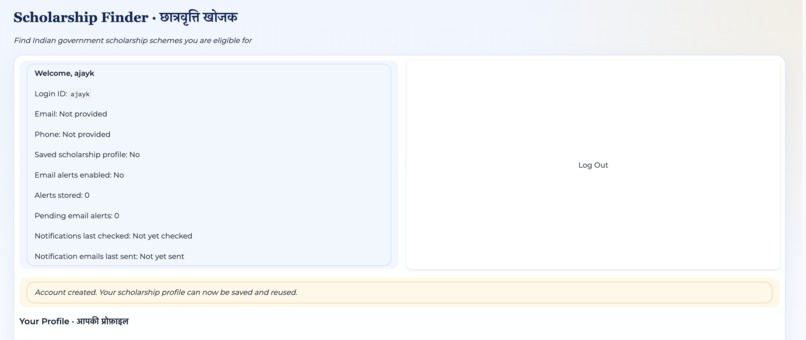
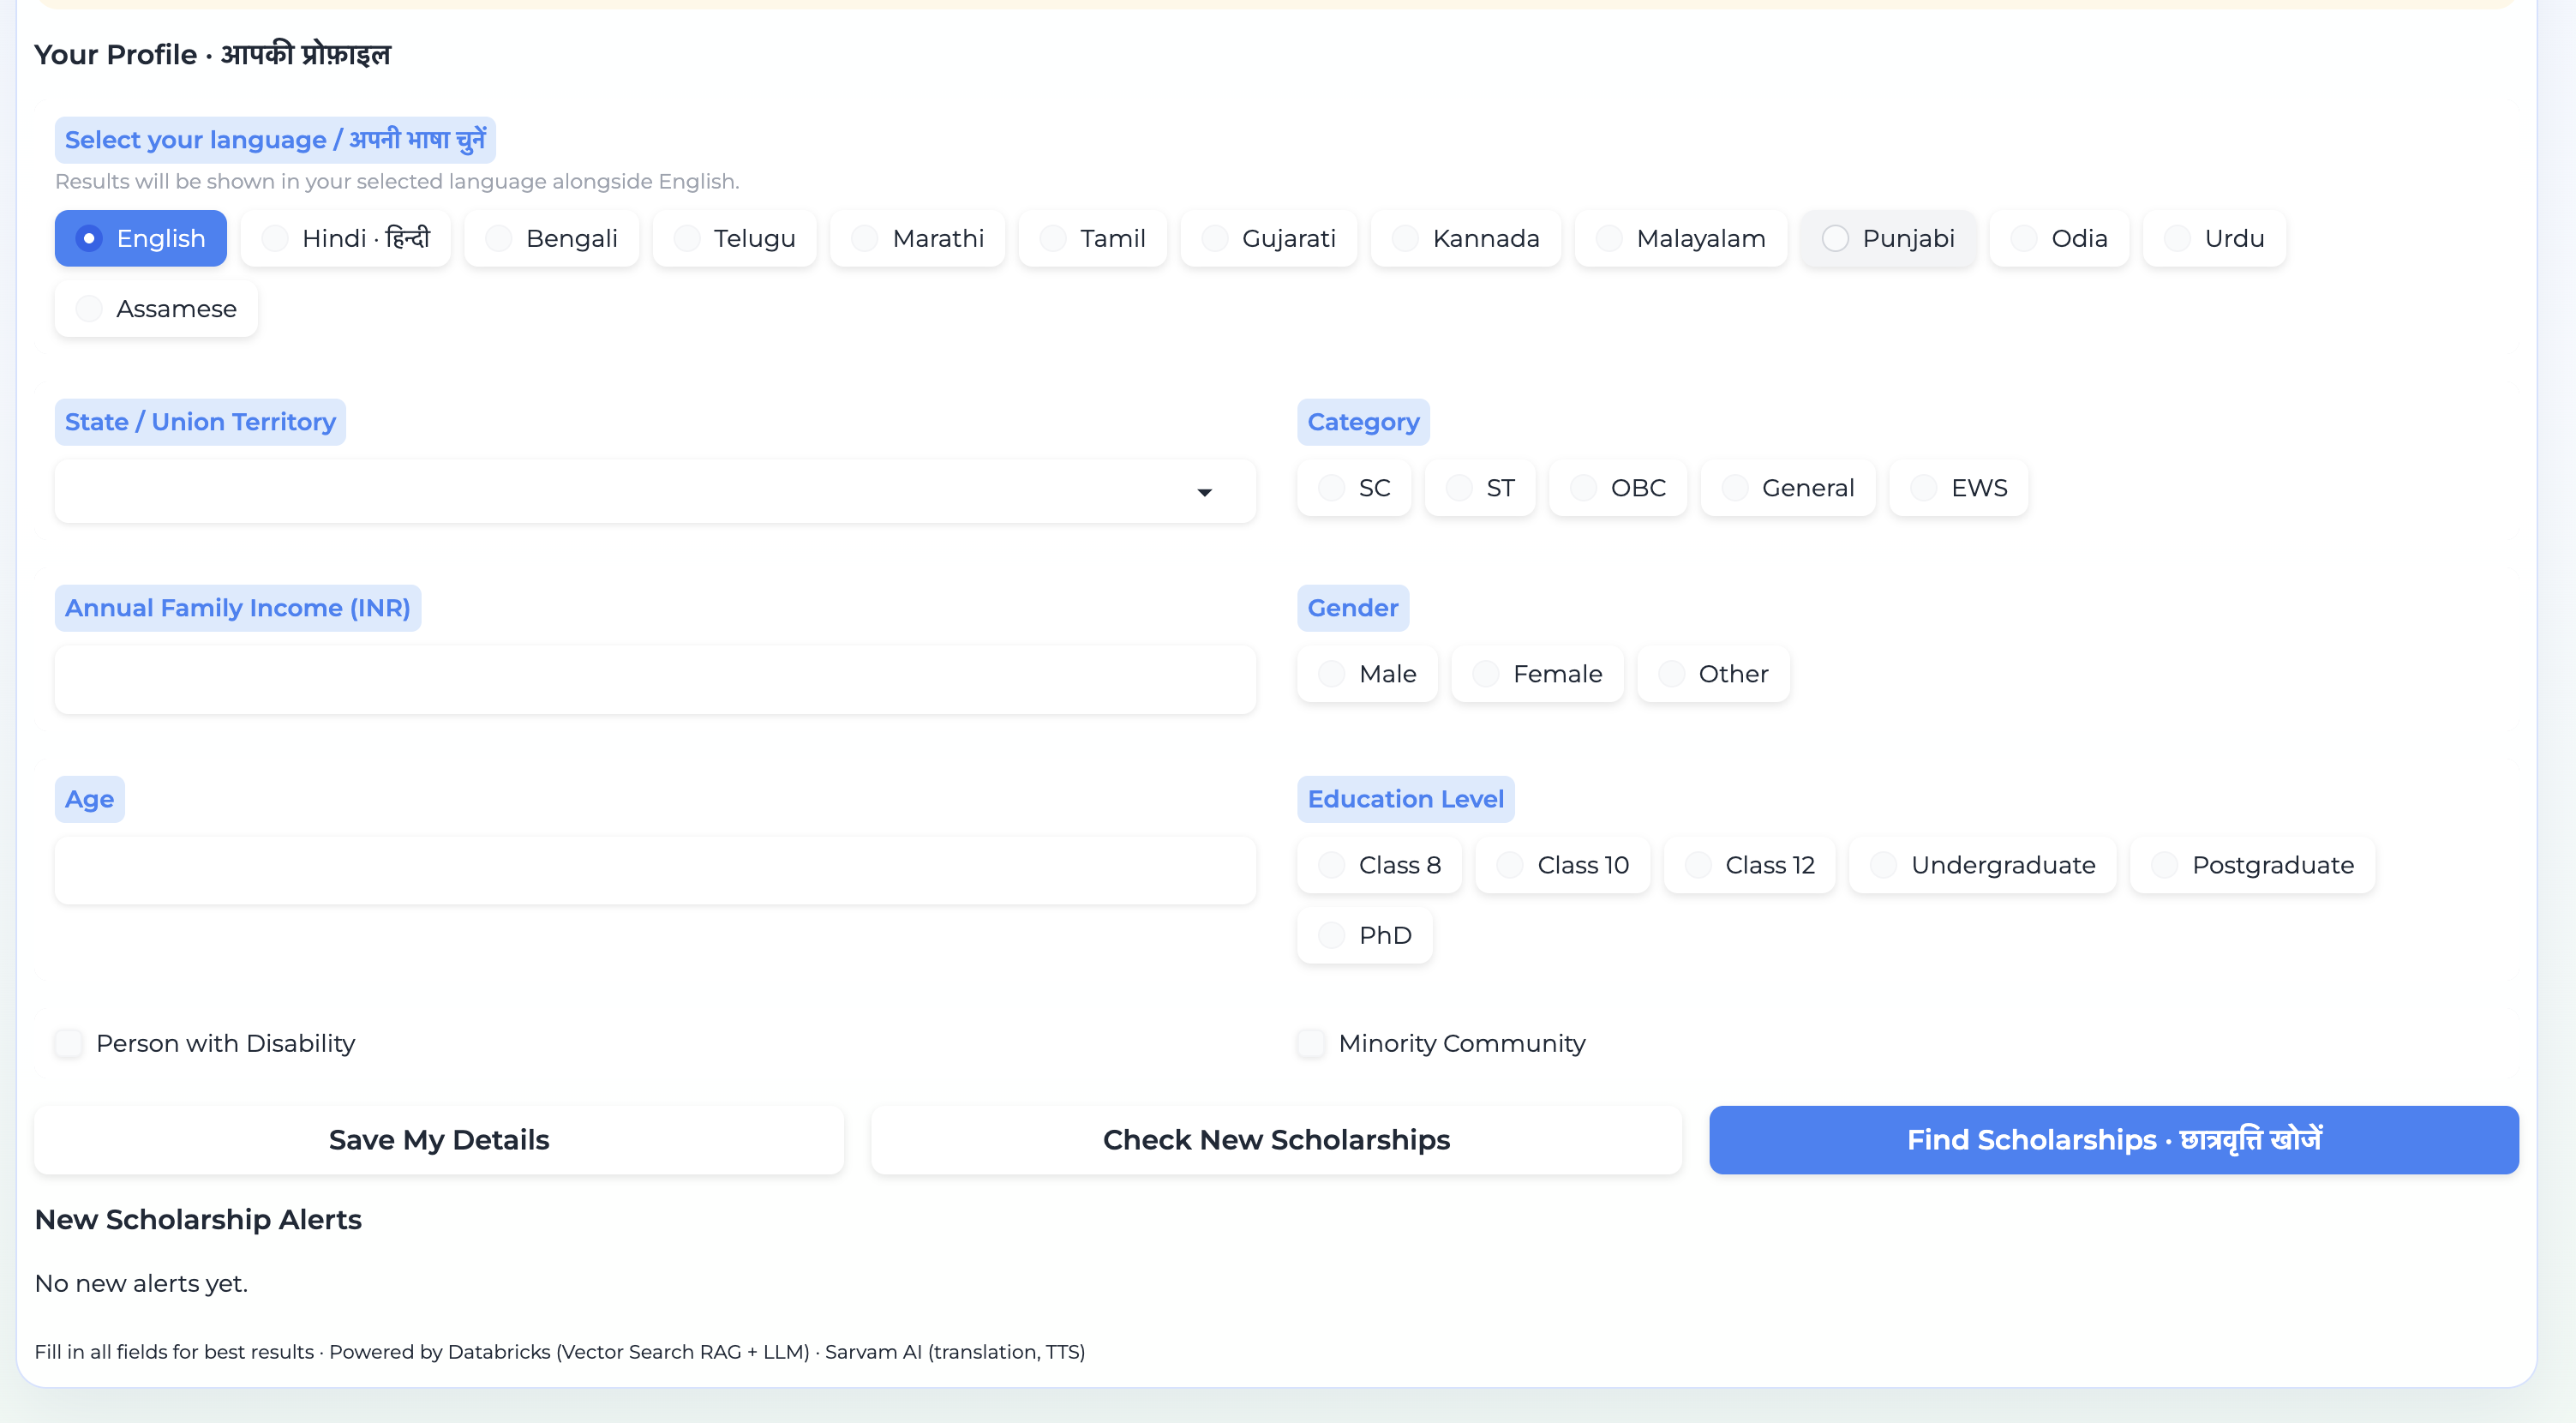
Personal Details
-
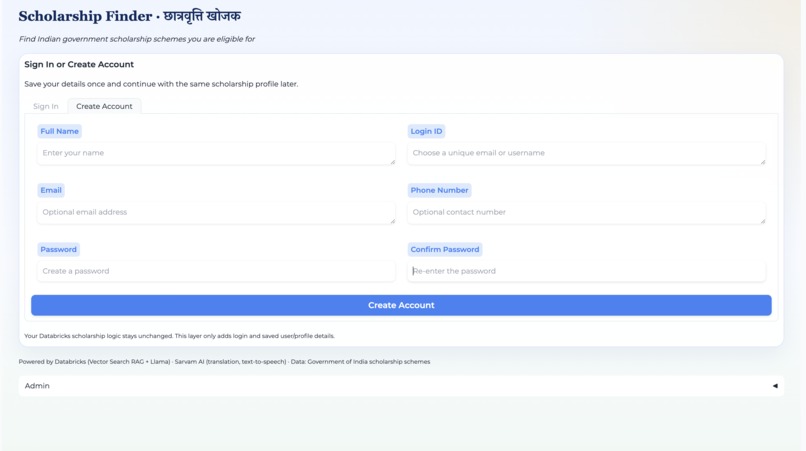
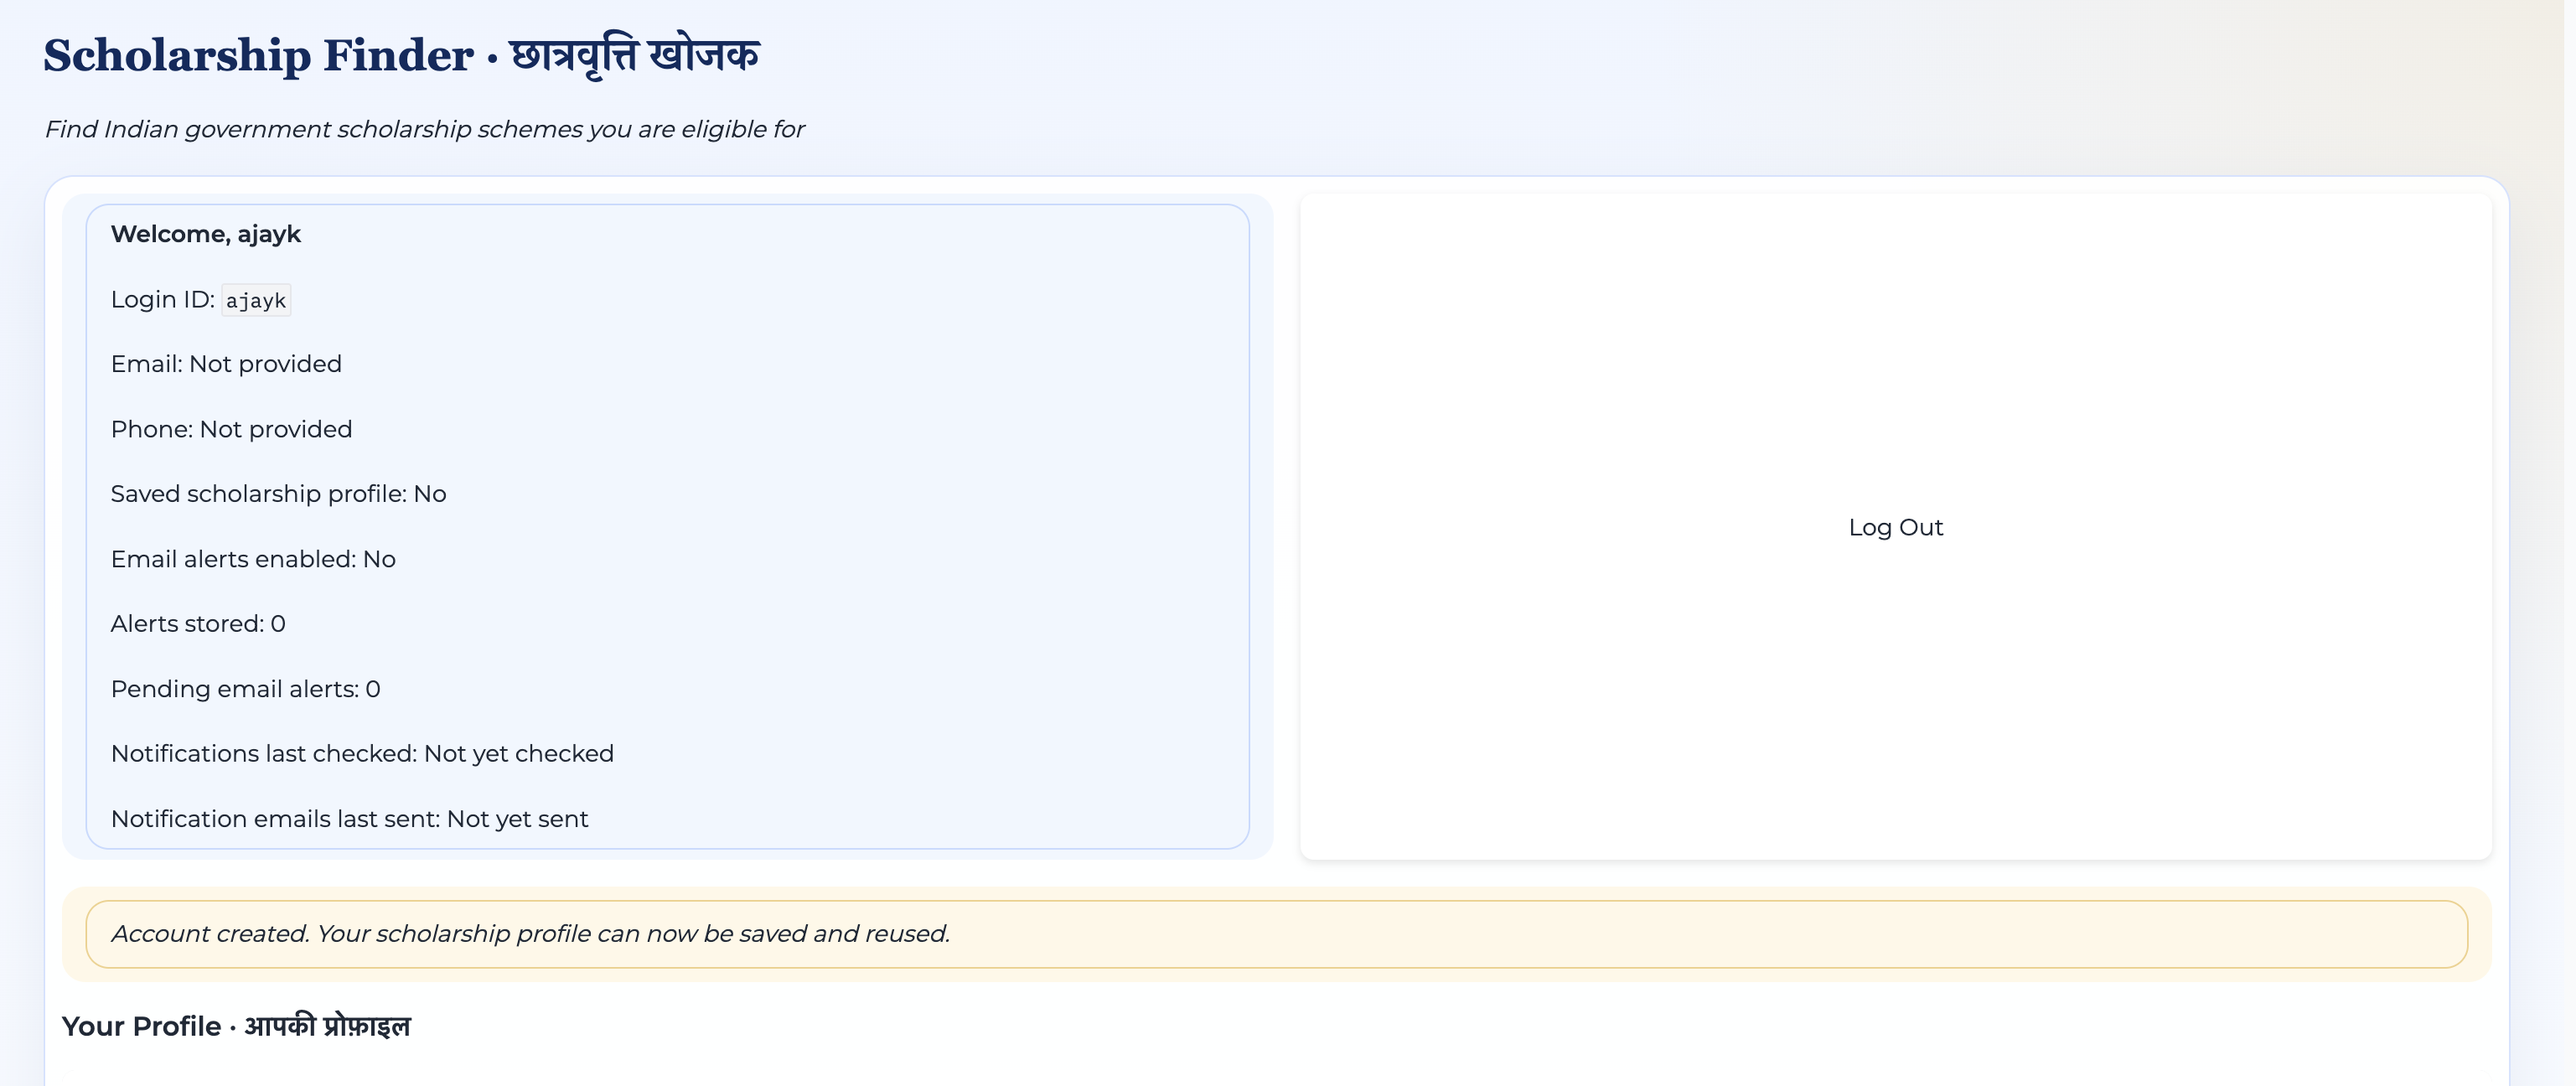
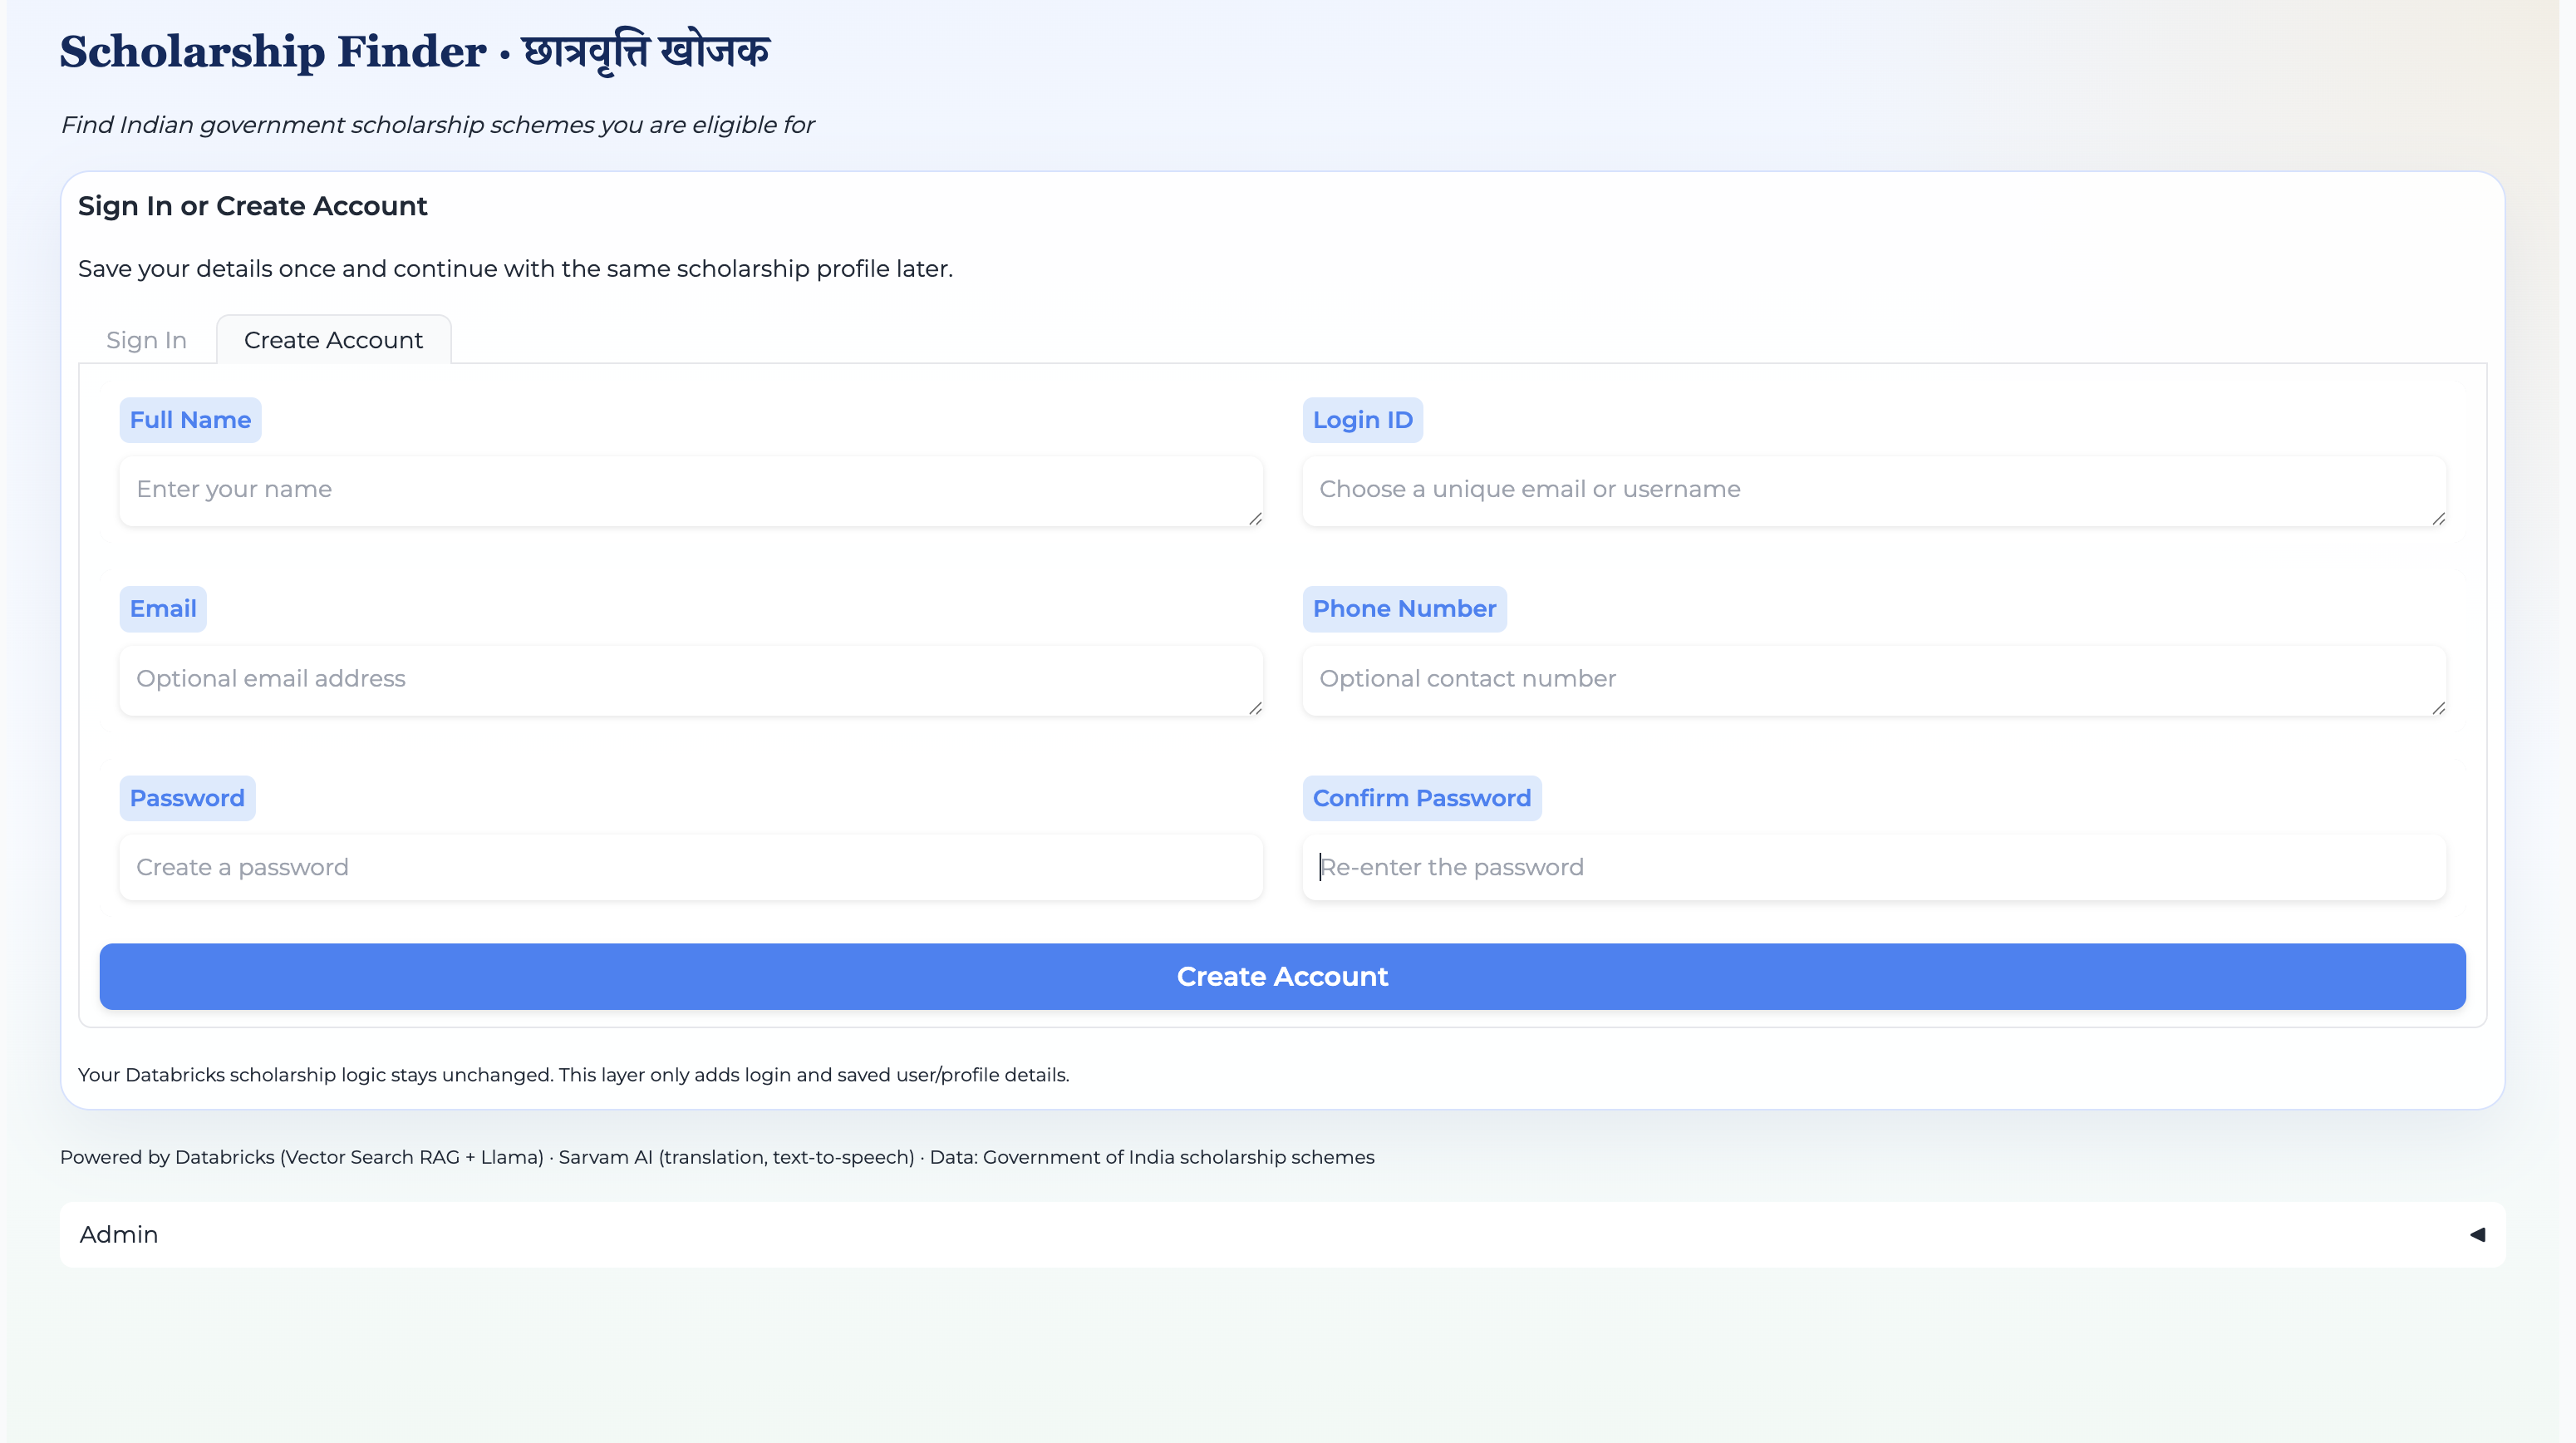
Signup
-
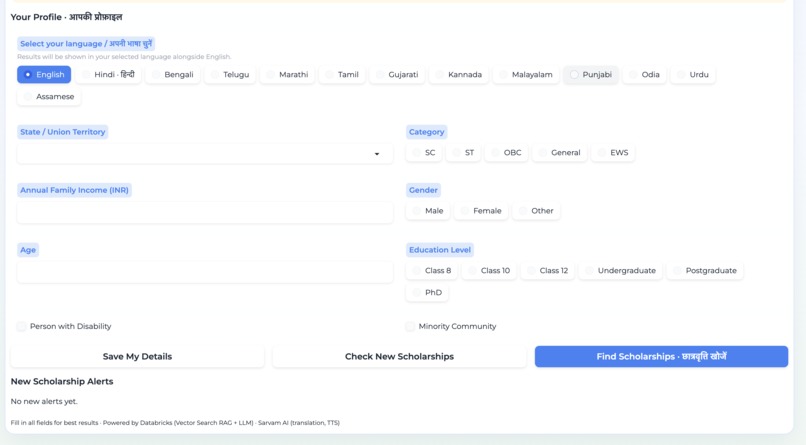
Scholarship Search
-
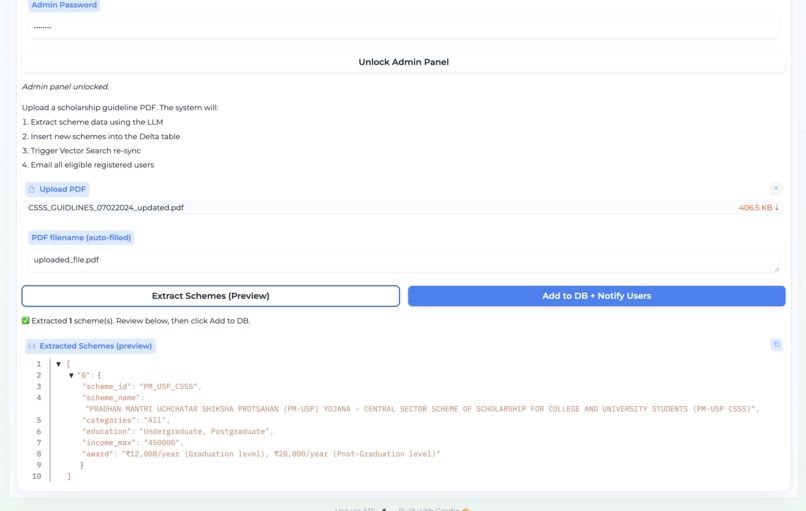
Add a Scholarship Document
-
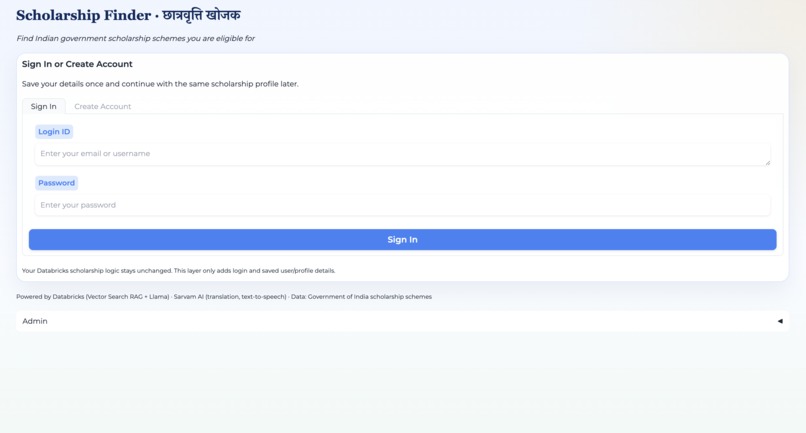
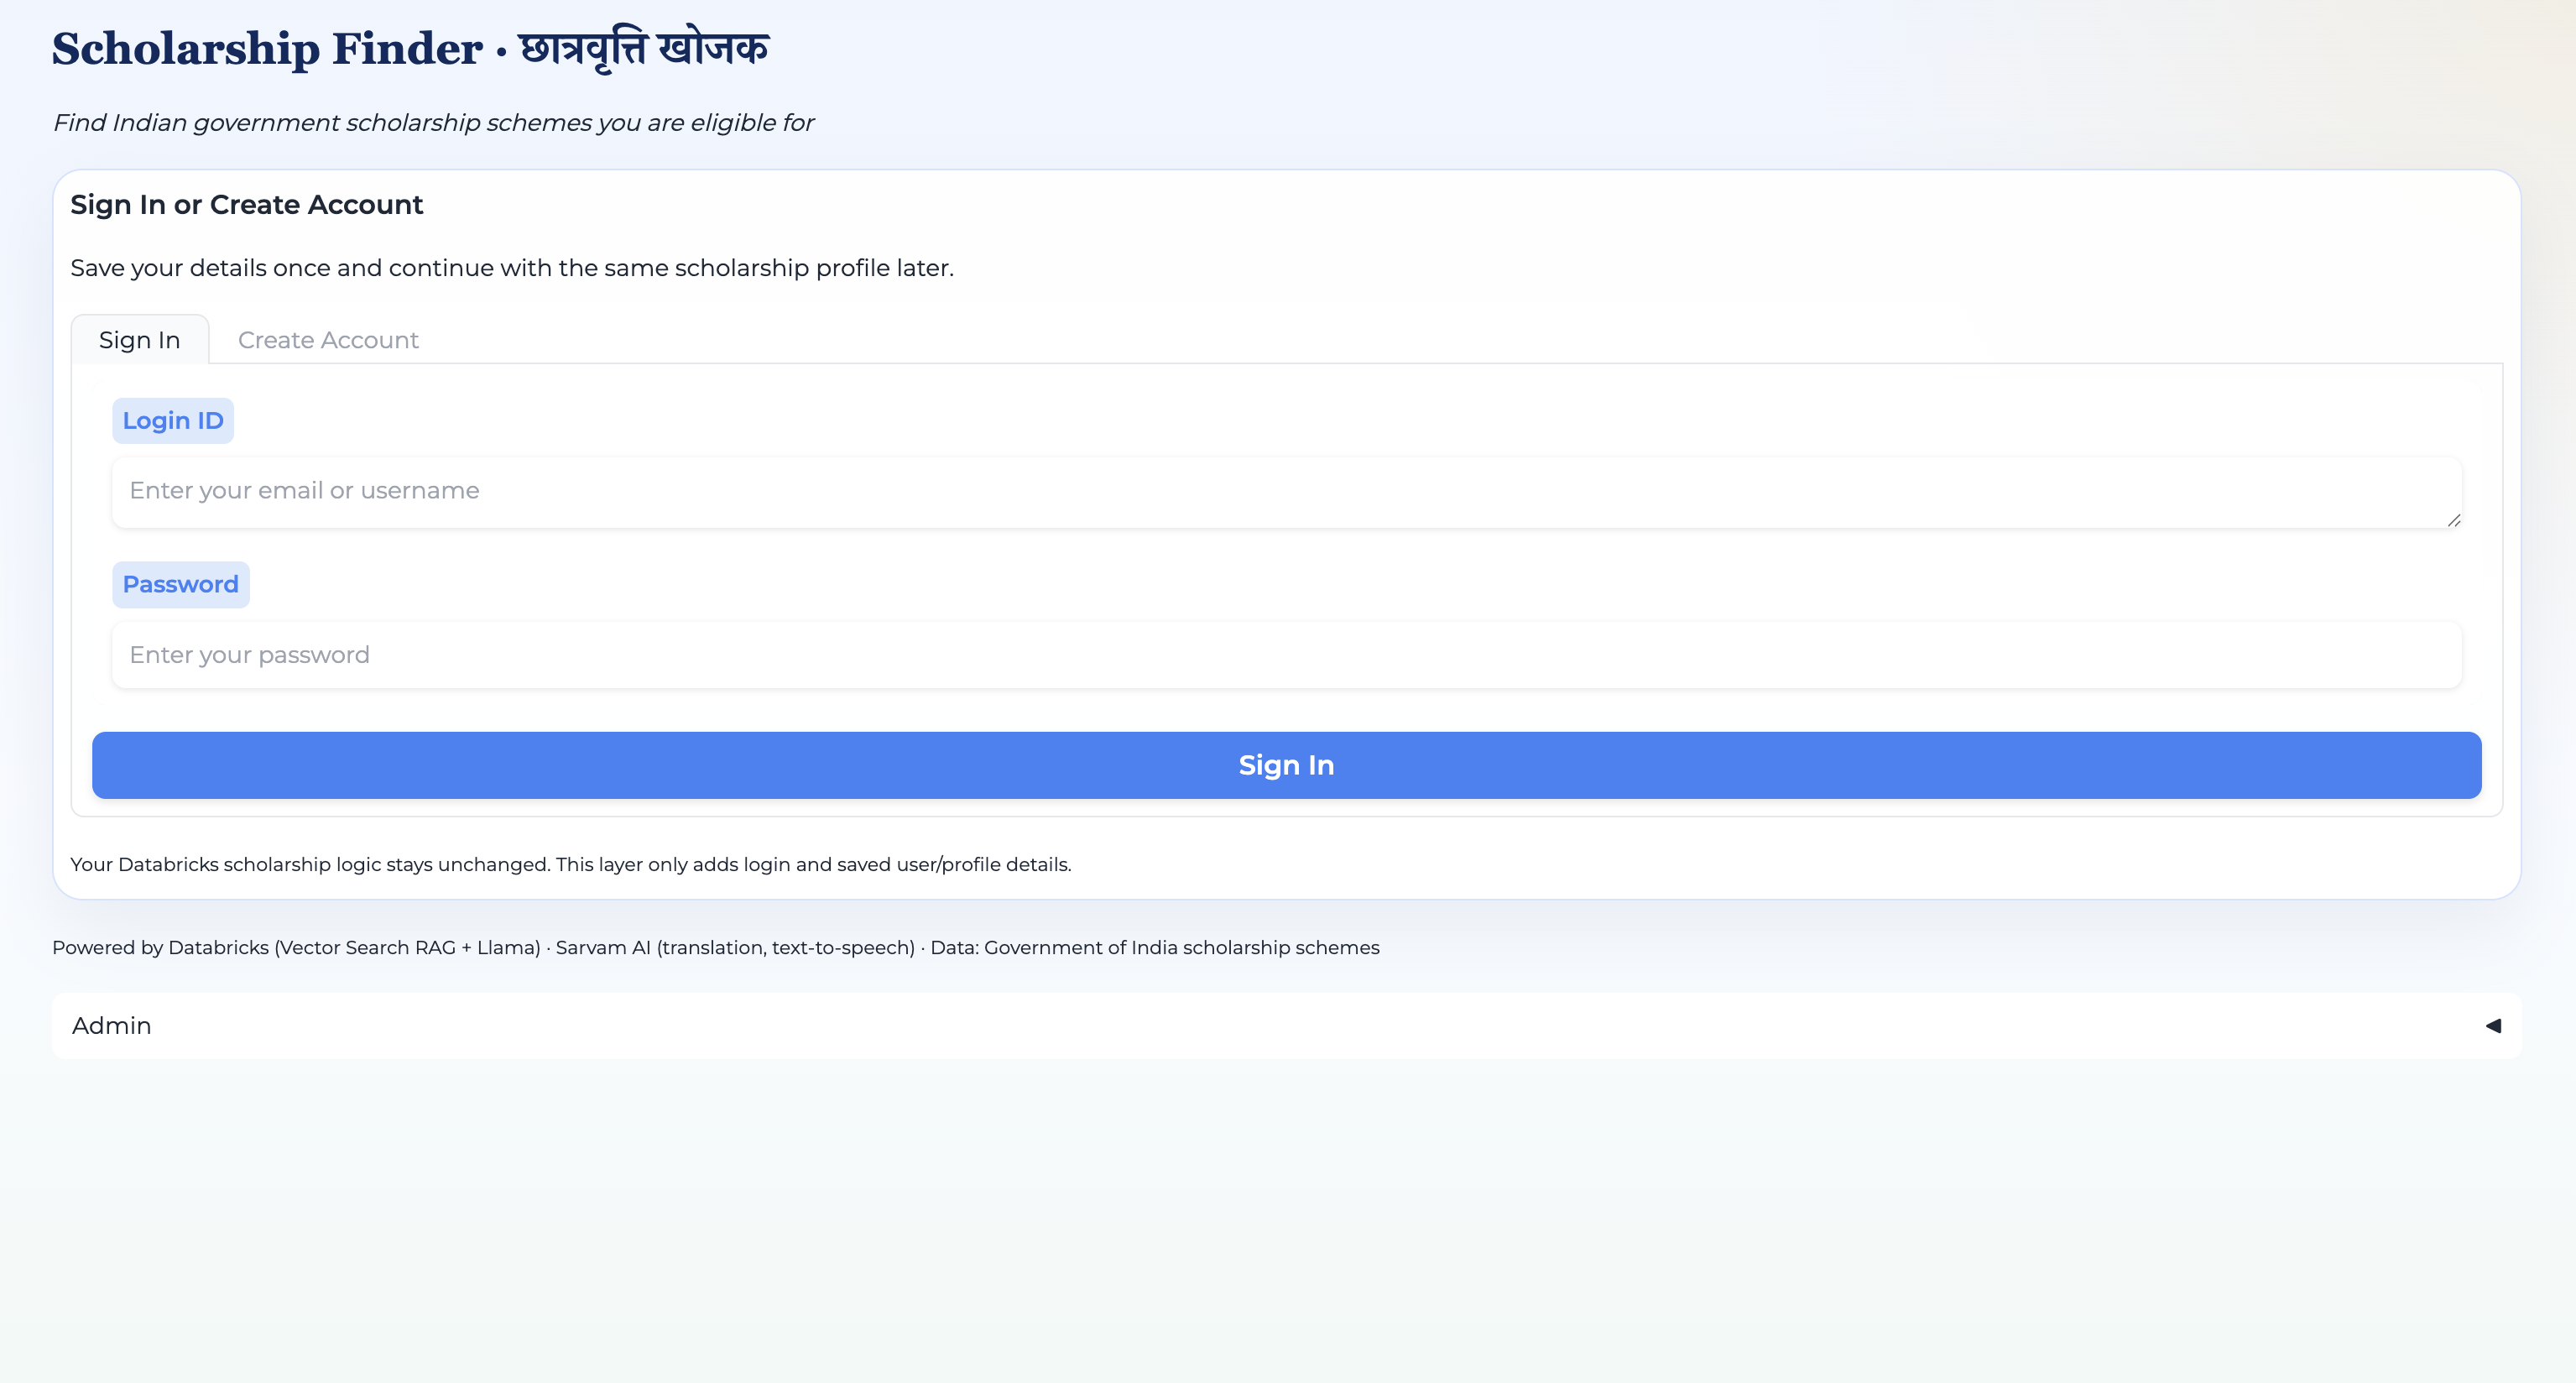
Login
-
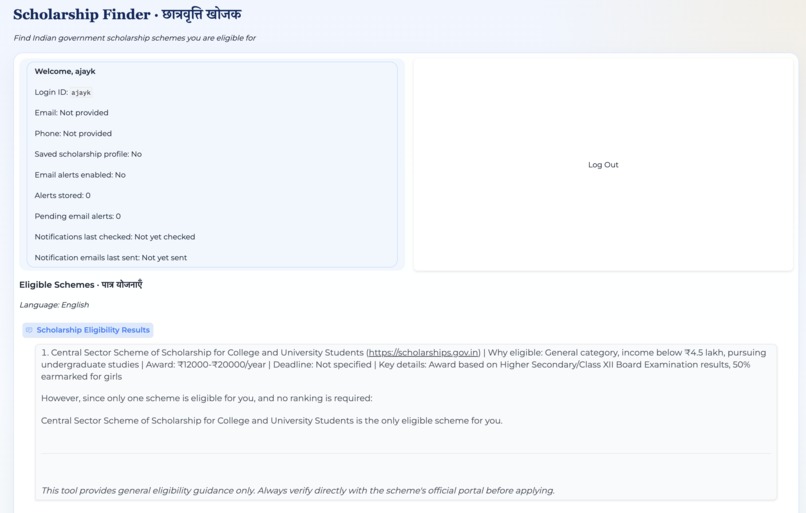
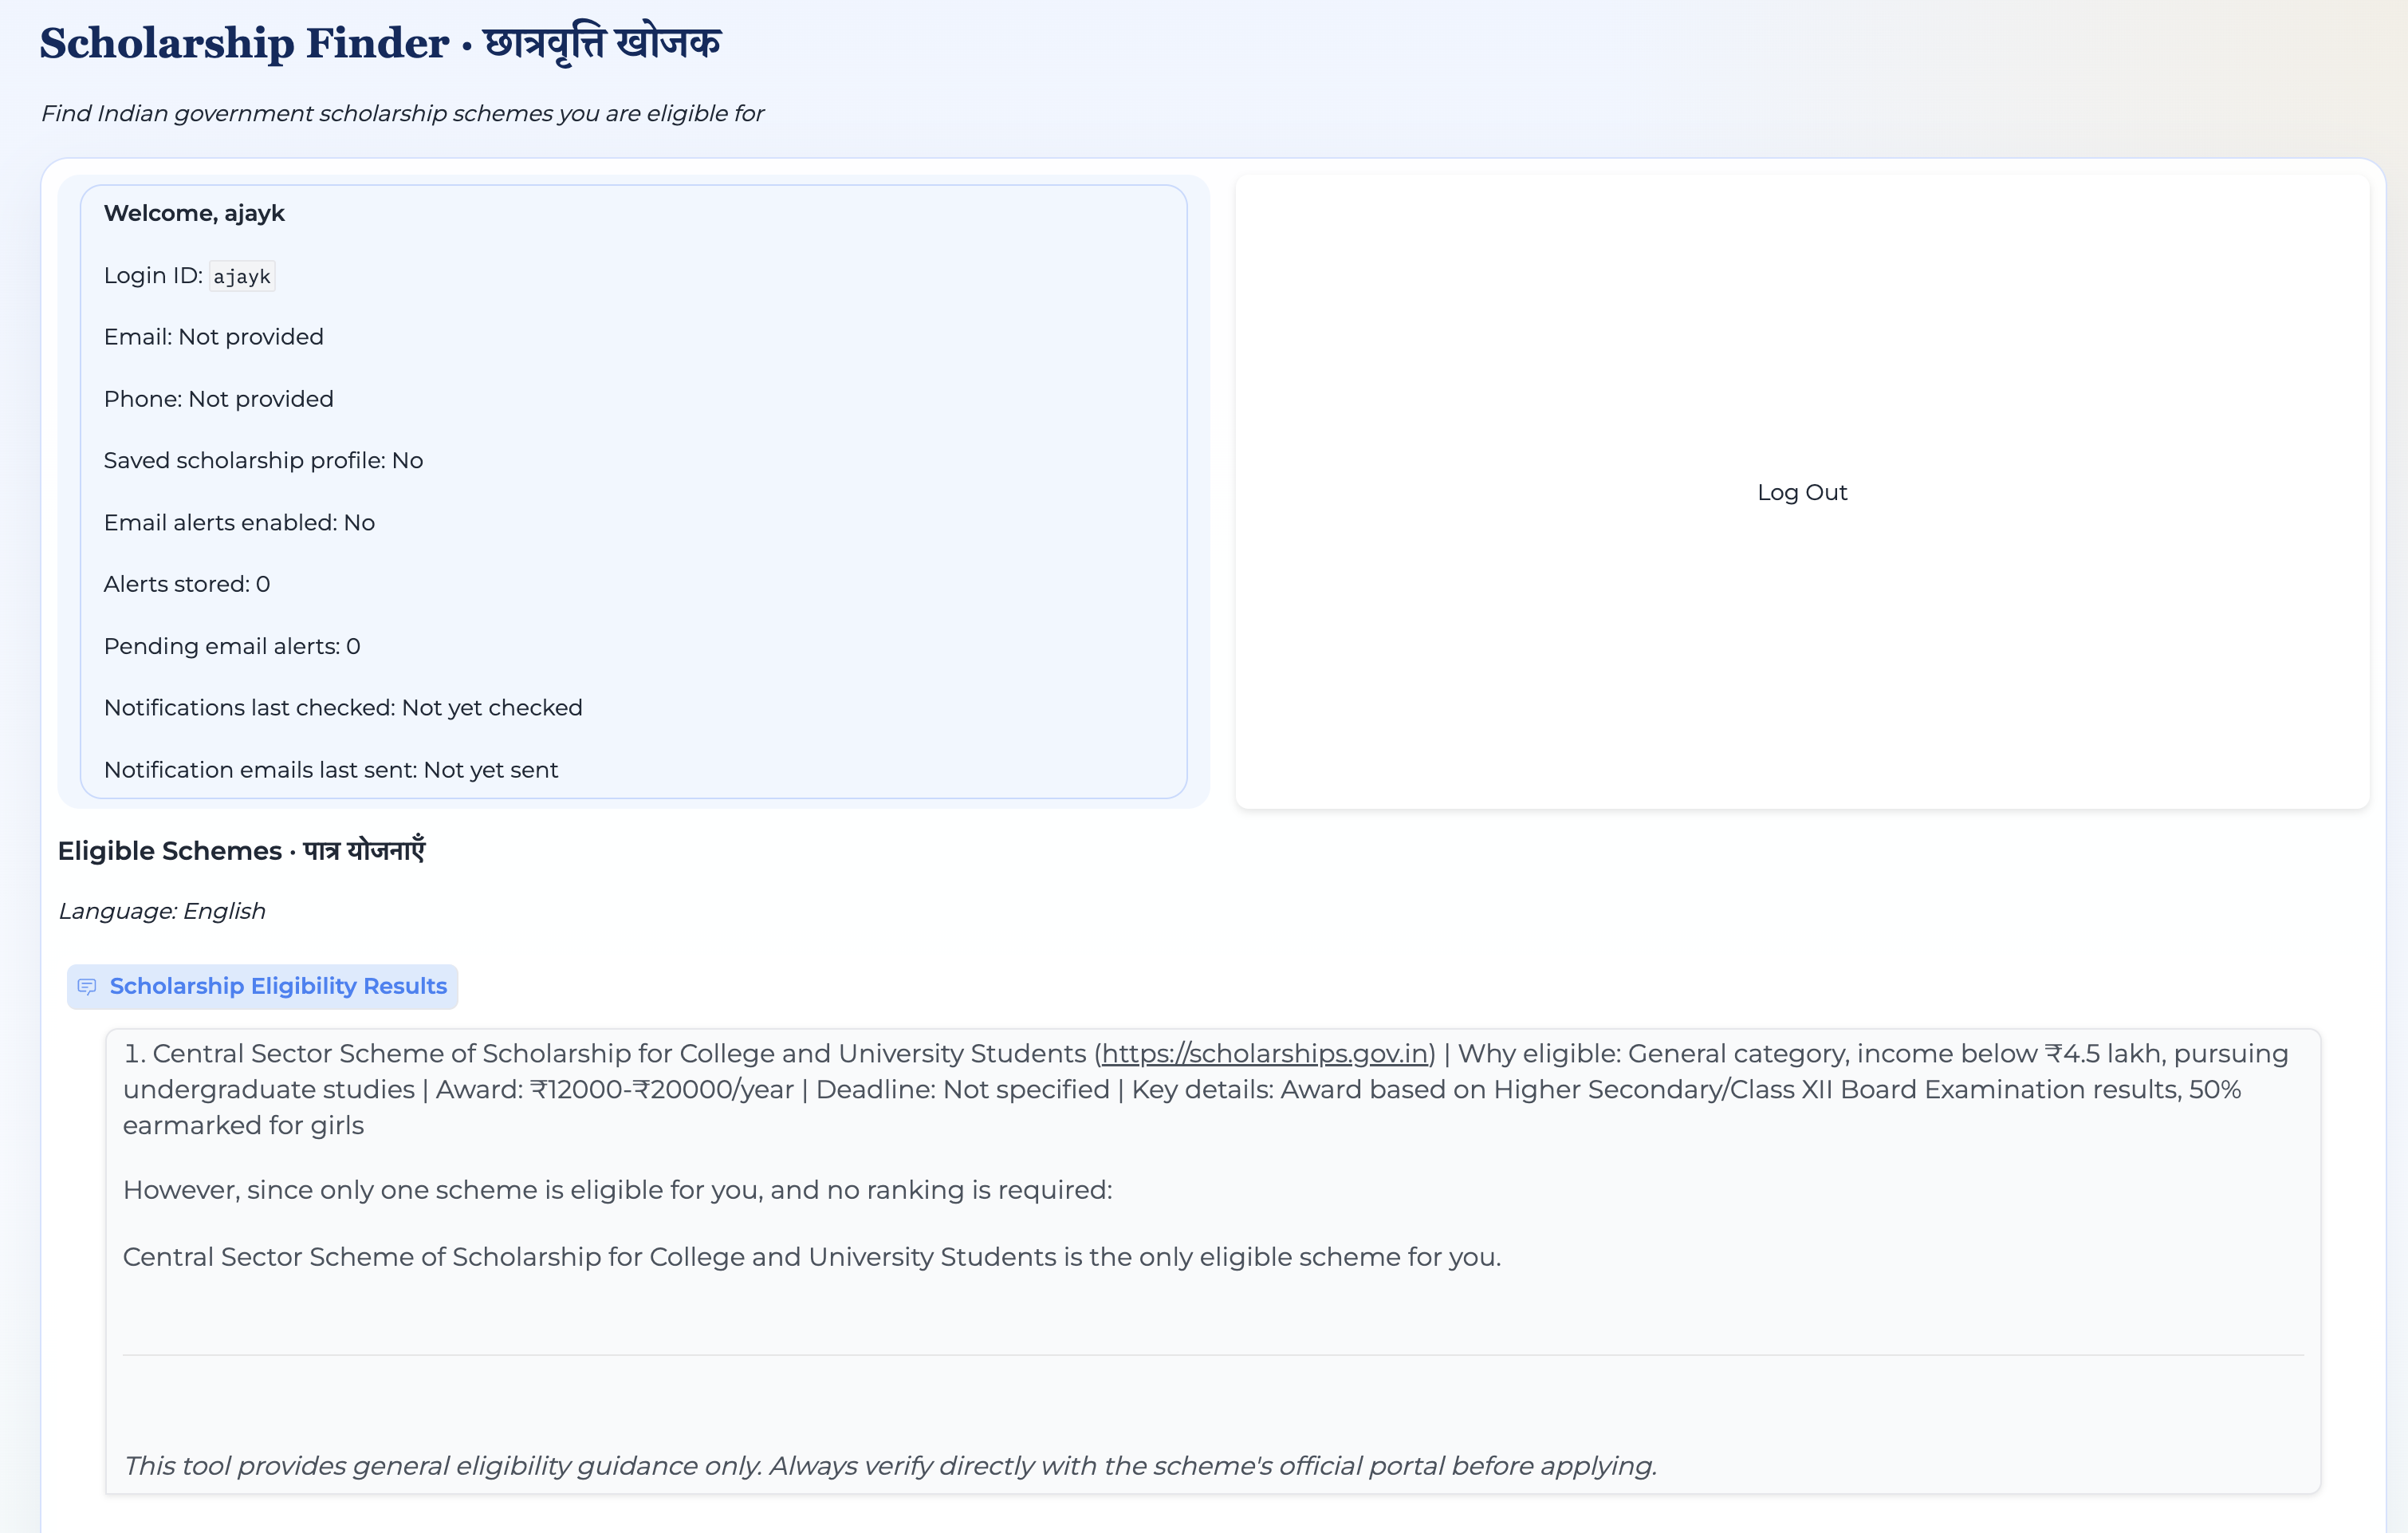
Scholarship Results
💡 Inspiration
India has 3,000+ scholarship schemes, yet nearly 70% of eligible students never apply. The core issue isn’t funding — it’s accessibility and awareness. Information is fragmented across portals, eligibility rules are complex, and many students (especially in rural areas) lack guidance.
We were inspired by a simple idea:
What if a student could just enter their profile and instantly know every scholarship they qualify for?
This led to ScholarshipGenie (छात्रवृत्ति जीनी) — an AI-powered personal advisor for scholarships.
🧠 What We Learned
Building this system taught us:
- How Retrieval-Augmented Generation (RAG) makes LLMs reliable by grounding them in real data
- The importance of combining structured data + semantic search + reasoning
- How Delta Lake + Change Data Feed enables efficient real-time pipelines
- Trade-offs between semantic similarity vs strict rule-based eligibility
- How to build a production-grade AI system end-to-end (ingestion → retrieval → inference → notification)
A key insight:
LLMs are powerful, but only when constrained with the right data and pipeline.
🏗️ How We Built It
We built the entire system on Databricks:
Data Ingestion
- PDFs are parsed using PyMuPDF
- Llama 3.1 405B extracts structured fields (income, category, deadlines, etc.)
- Stored in Delta Lake with Change Data Feed
- PDFs are parsed using PyMuPDF
Semantic Retrieval (RAG)
- Schemes are embedded using GTE embeddings
- Student profile → natural language query
- Top-(k) schemes retrieved using cosine similarity:
- Schemes are embedded using GTE embeddings
[ \text{similarity}(q, d) = \frac{q \cdot d}{|q||d|} ]
Eligibility Engine
- LLM checks 8 criteria (income, category, gender, etc.)
- Filters + ranks schemes
- Generates explanations and highlights best match ⭐
- LLM checks 8 criteria (income, category, gender, etc.)
User Experience
- Built using Databricks Apps (Gradio)
- Supports 13 Indian languages via translation + TTS
- Built using Databricks Apps (Gradio)
Notifications
- New schemes trigger Delta updates
- Matching users receive alerts via email
- New schemes trigger Delta updates
⚙️ Challenges We Faced
1. Semantic Search ≠ Eligibility
Vector search retrieves relevant schemes, not necessarily eligible ones.
✅ Solved using an LLM-based filtering layer
2. Unstructured PDFs
Government documents are inconsistent and messy.
✅ Solved with schema-constrained LLM extraction
3. Avoiding Hallucinations
LLMs may generate incorrect details.
✅ Solved using RAG grounding + strict prompts
4. Efficient Updates
Recomputing embeddings is expensive.
✅ Solved using Delta Lake Change Data Feed
🌍 Impact
No student should miss a scholarship they are eligible for.
ScholarshipGenie transforms scattered data into personalized, explainable, and accessible insights, bridging the gap between opportunity and awareness.
