
🛡️ SchemaSentinel-Strands
Autonomous Self-Healing Data Reliability Agent for Streaming Pipelines
Powered by Strands Agents SDK with Cognitive Multi-Cloud Synthesis (Nebius Studio SOTA LLM + AWS Bedrock Mantle Fallback) • AST Security Sandbox • Dynamic Fingerprint Cache • Dead Letter Queue (DLQ)
Inspiration
"Data engineers spend over 40% of their working hours manually firefighting broken data pipelines instead of building strategic infrastructure." — Gartner & Monte Carlo Data Reliability Study
"The cost of bad data in the US alone is estimated at a staggering $3.1 Trillion per year." — IBM & Harvard Business Review Research
Imagine this: It’s 2:00 AM. An upstream third-party API or microservice pushes a silent update, changing a single payload field from user_id to userId. Instantly, an enterprise streaming pipeline crashes, PagerDuty sirens wake on-call data engineers, executive dashboards freeze, and downstream ML models ingest corrupt data.
Behind every failed pipeline is a cascading disaster: delayed business decisions, broken user experiences, and millions of dollars bled into emergency incident responses.
Modern data pipelines are astonishingly brittle. Traditional ETL systems depend on rigid schemas or fail completely on unknown mutations. When data breaks, the only historical solution was human intervention: wake an engineer, write a manual SQL/Python patch, test it, and redeploy—hours after the damage is done.
We asked ourselves: Why can’t streaming data pipelines have an autonomous immune system?
We built SchemaSentinel-Strands to act as a self-healing shock-absorber for real-time data streaming—intercepting breaking schema drifts, dynamically synthesizing deterministic Python transformations using cognitive multi-cloud AI agents, executing them inside a secure AST sandbox, and caching schema signatures for sub-10ms (<0.01s) subsequent execution—all guaranteeing zero pipeline downtime and zero human intervention.
What it does
SchemaSentinel-Strands is an autonomous self-healing data reliability engine that prevents streaming pipeline outages caused by schema drift:
- Real-Time Contract Interception & Grounding: Intercepts streaming JSON payloads (tested against live GitHub repository streams and search grounding) and evaluates them against strict SQLite warehouse schema contracts (
tech_projects). - Dynamic Shannon Entropy Query Guard: Mathematical entropy analysis and symbol-guard filtering prevent keyboard mash, corrupted strings, or malicious queries from reaching the ingestion loop.
- Autonomous Multi-Cloud Code Synthesis: When schema drift is detected, the agent extracts a structural skeleton (reducing prompt tokens by ~90%) and invokes a cognitive multi-cloud reasoning engine (Nebius Studio SOTA LLM with seamless AWS Bedrock Mantle fallback) to synthesize a deterministic Python transformation function (
transform_record). - AST Security Sandbox Execution: Every synthesized transformation undergoes static AST bytecode parsing to enforce return signatures, block filesystem access, and prevent malicious code execution (
os,sys,eval) before touching production memory. - Zero-Pollution Dead Letter Queue (DLQ): Non-recoverable or alien IoT payloads that lack core entity attributes are quarantined into an isolated Dead Letter Queue with full audit traces, ensuring zero database pollution.
- Dynamic Fingerprint Cache (Sub-10ms Execution): Once an agent heals a drift signature, the compiled Python bytecode is cached in-memory. Recurring drift patterns execute instantly in
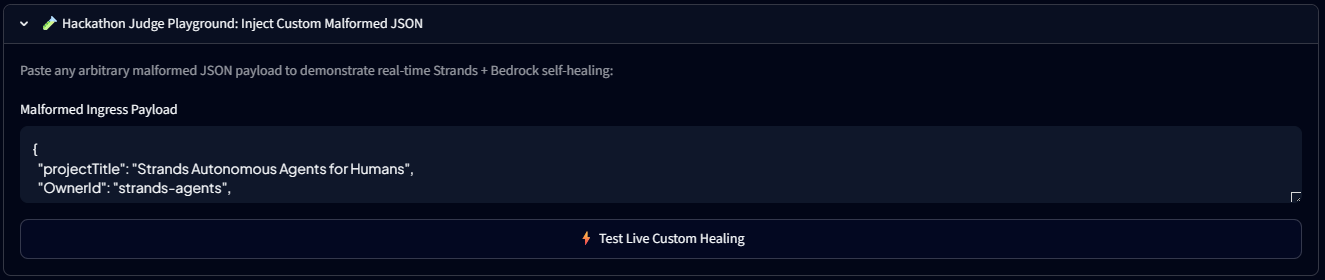
<0.01sat zero token cost. - Interactive Observability & Judge Playground: A production Streamlit dashboard displaying live session Reliability SLA, synthesis latency, conformed records, and a custom JSON injection playground for real-time stress testing.
How we built it
- Core Agent Architecture: Built using the Strands Agents SDK pattern coupled with a multi-cloud failover strategy.
- LLM Reasoning & Failover Engine:
- Primary Fast-Inference Engine: Nebius Studio (
Qwen/Qwen3-30B-A3B-Instruct-2507) for ultra-fast, token-efficient transformation synthesis. - Resilient Enterprise Fallback: AWS Bedrock Mantle (
Amazon Nova/Grok) to guarantee uninterrupted pipeline uptime if cloud quotas or auth holds occur.
- Primary Fast-Inference Engine: Nebius Studio (
- AST Sandboxing: Python's native
astcompiler validates function structure and isolates global execution scope viaSandboxExecutor. - Structural Skeleton Optimizer: Strips repetitive array elements and payload noise down to 1 representative structural schema before prompting the agent, optimizing prompt latency and eliminating token truncation bugs.
- Data Ingestion & Grounding: Live GitHub REST API event stream dynamically grounded with Tavily Search API.
- Storage Layer: SQLite structured relational warehouse maintaining conformed tables (
tech_projects) alongside an isolated DLQ quarantine table (tech_projects_dlq). - Frontend & Telemetry: Streamlit dashboard featuring custom CSS, live DAG pipeline visualizer (
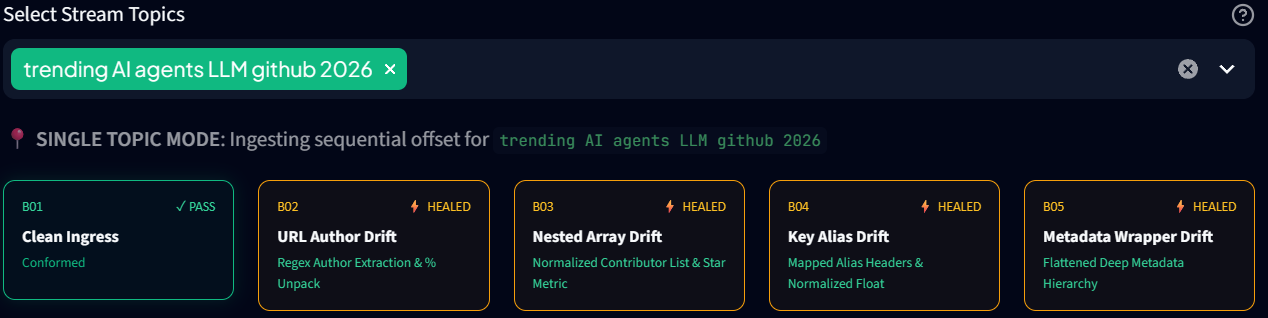
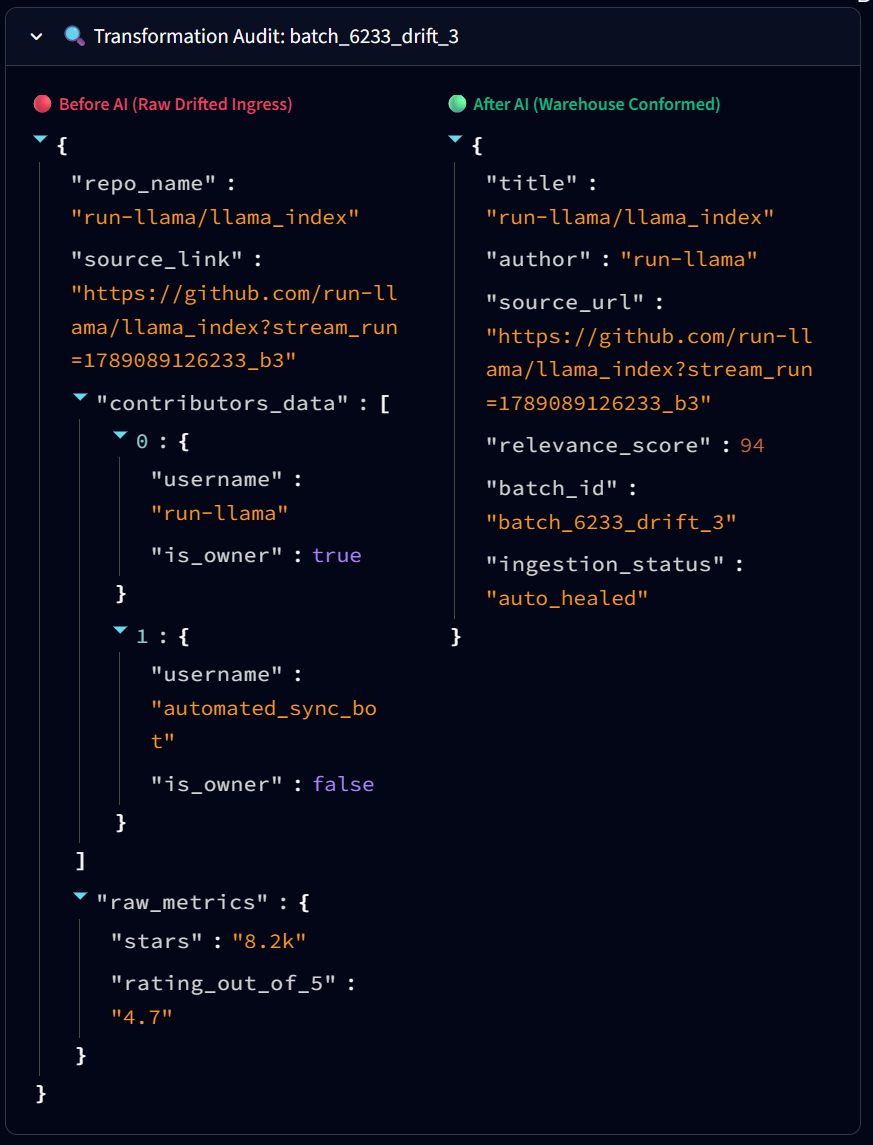
STAGE 01toSTAGE 05), session SLA calculation, and raw JSON transformation diffs.
🏗️ Multi-Cloud Resilience Architecture
[ Upstream Ingress Stream ] (GitHub REST API + Tavily Grounding)
            │
            ▼
[ Dynamic Shannon Entropy Guard ] (Rejects keyboard mash in 0.1ms)
            │
            ▼
[ Warehouse Contract Validator ]
    ├── Matches DDL  ────────► [ ✅ Clean Ingress ] ────┐
    └── Drift Detected                                  │
            │                                           ▼
            ▼                                 [ Live Warehouse ]
  [ Schema Fingerprint Cache ]                (tech_projects)
    ├── Hit (<0.01s) ────────► Bytecode Exec ───────────┤
    └── Miss (1.5s - 2.5s)                              │
            │                                           │
            ▼                                           │
  [ Cognitive Multi-Cloud Agent ]                       │
    ├── Primary: Nebius Studio SOTA LLM                 │
    └── Fallback: AWS Bedrock Mantle                    │
            │                                           │
            ▼                                           │
  [ AST Security Sandbox Gate ]                         │
    ├── Passed ──────────────► Conforms Record ─────────┘
    └── Malicious / Alien ───► [ Dead Letter Queue (DLQ) ]
                               (tech_projects_dlq)
                               (Zero Warehouse Pollution)
Challenges we ran into
- Eliminating Artificial Timeouts & Token Caps: Early prototypes suffered from syntax truncations (
'{' was never closed) caused by artificial token caps and client timeouts. We solved this by removing artificial ceilings and introducing a structural skeleton pre-processor that reduced prompt token payloads by 90% while ensuring complete, valid AST compilation. - Multi-Cloud Quota & Auth Failover: Developing against cloud AI providers revealed that unexpected account-level authorization holds or rate limits could stall mission-critical data pipelines. We architected an automated multi-cloud failover layer that seamlessly reroutes synthesis prompts between Nebius Studio and AWS Bedrock without dropping in-flight stream batches.
- Mathematical Accuracy in Session SLAs: Tracking cumulative vs. active session metrics initially led to skewed SLA percentages. We engineered a dedicated session-level tracking model (
session_conformed / session_total) that honestly and transparently reflects current-run reliability. - The "Alien Payload" Boundary: Autonomous healing must know when not to heal. We established clear triage heuristics: genuine schema mutations (renamed keys, nested objects, stringified ratings) are conformed, while irrecoverable garbage (alien IoT metrics) is quarantined to DLQ to protect data warehouse integrity.
Accomplishments that we're proud of
- Deterministic Self-Healing (1.5s Cold Synthesis, <0.01s Warm Cache): Achieved reliable, pure-function synthesis with zero regex hardcoding, transitioning to sub-10ms cached bytecode execution for continuous streams.
- Zero Warehouse Pollution Guarantee: Conformed data retains 100% data fidelity with preserved
extra_metadata, while unhealable payloads are safely quarantined. - Multi-Cloud Redundancy: Seamless failover between Nebius and AWS Bedrock guarantees that no single cloud outage halts pipeline operations.
- No Mock Data: Tested and validated on real GitHub upstream repos, real LLM endpoints, and real relational warehouse persistence.
What we learned
- Agentic Code Generation > Brittle Mappings: LLMs are remarkably proficient at writing defensive data engineering transformations (handling string-to-float coercion, percentage cleanups, nested alias keys) when provided strict DDL contract schemas.
- Multi-Provider Resilience is Mandatory: Production AI agents must never depend on a single provider; active-passive LLM failover is non-negotiable for enterprise data infrastructure.
- Sandboxing is the Real Linchpin: Autonomous code generation is only enterprise-ready if guarded by strict AST bytecode verification prior to execution.
What's next for SchemaSentinel-Strands
- Kafka & Apache Flink Native Operator: Package SchemaSentinel as an out-of-the-box Kafka Streams consumer and Apache Flink transformation operator for high-throughput enterprise event backbones.
- Automated Pull Request Generator: Enable the agent to automatically submit Git Pull Requests back to the data engineering dbt/Airflow repository containing permanent SQL/Python migration patches and unit test fixtures.
- Vectorized Schema Drift Clustering: Use vector embeddings of schema ASTs to cluster and auto-classify drift taxonomies across enterprise data meshes.
Built With
- agentic-ai
- ai-agents
- amazon-web-services
- ast-sandbox
- aws-bedrock
- data-engineering
- data-pipelines
- github-api
- llm
- nebius
- python
- sqlite
- streamlit
- tavily

Log in or sign up for Devpost to join the conversation.