-
-
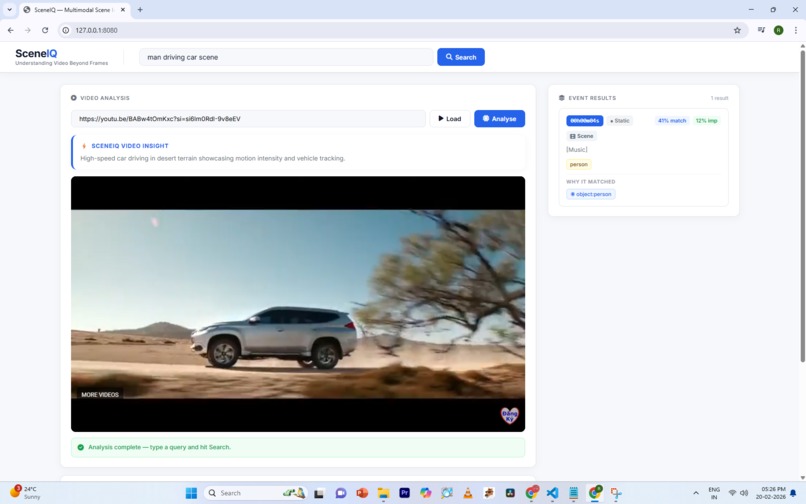
Query-driven retrieval showing motion-aware scene matching with importance scoring and exact timestamp output.
-
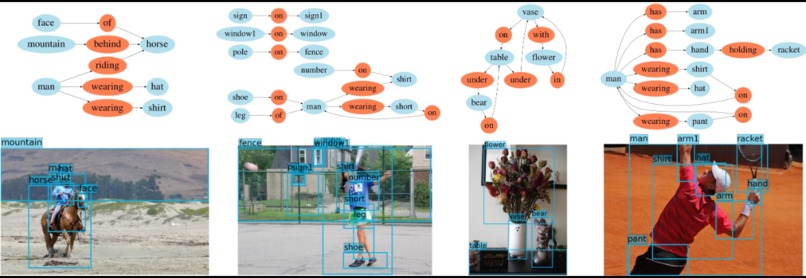
Examples of generated scene graphs showing entity relationships such as riding, wearing, holding, and spatial positioning.
-
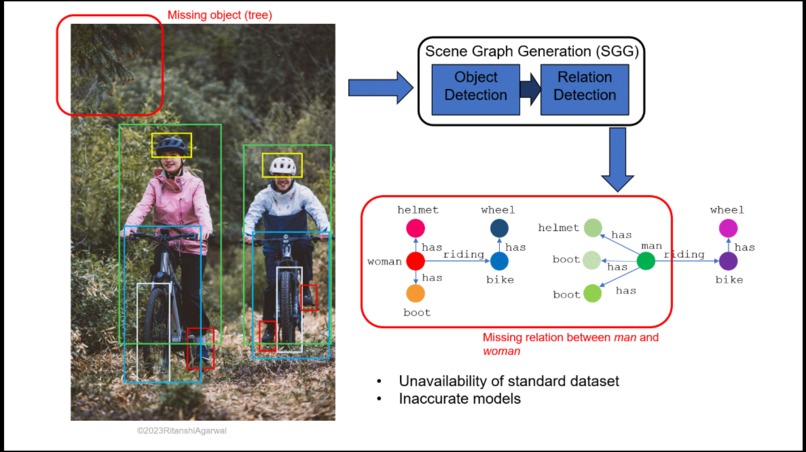
Demonstrates object detection and highlights limitations of traditional models in capturing missing relational context.
-
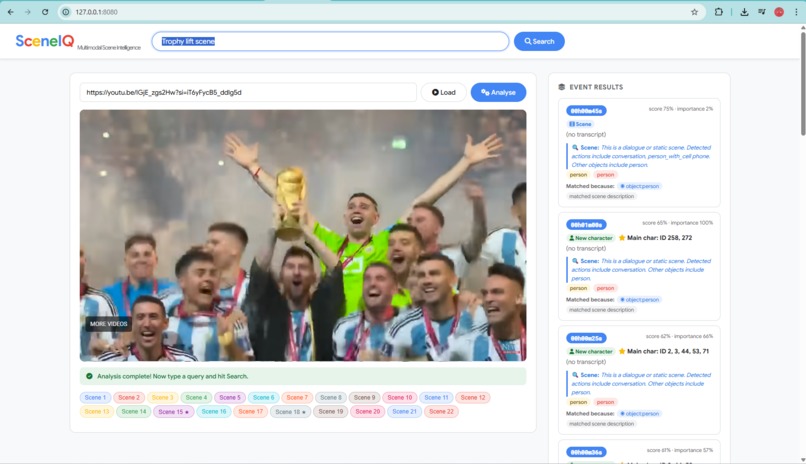
SceneIQ retrieves the trophy lift moment using persistent character IDs and motion-aware ranking for instant timestamp navigation.
-
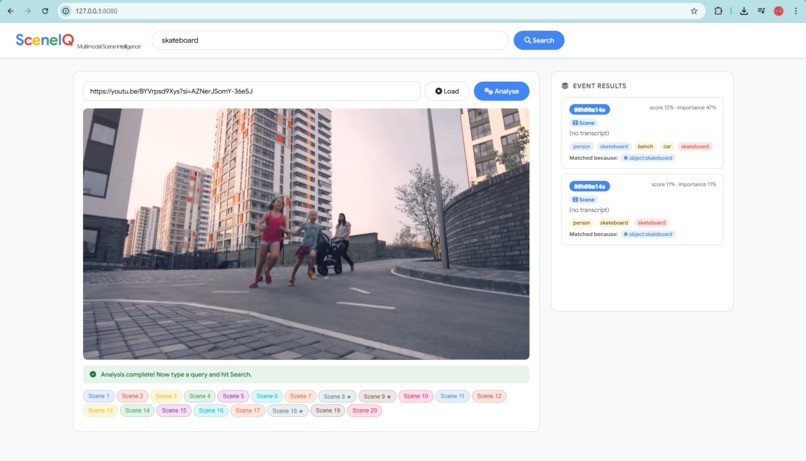
SceneIQ analyzes a YouTube video, segments scenes, and enables semantic timestamp-based retrieval.


Inspiration
Modern cities generate massive amounts of video from CCTV, drones, and public recordings, yet identifying critical moments still requires manually reviewing hours of footage. During emergencies, this delay can cost valuable time. We built SceneIQ to transform video from passive footage into structured, searchable intelligence so critical moments can be found instantly.
What it does
SceneIQ converts raw video into structured scene intelligence. It segments video into scenes, detects and tracks entities over time, analyzes motion patterns, models interactions, and ranks scenes by importance. Users can search using natural language queries such as “person driving car” or “crowd panic moment”, and SceneIQ instantly retrieves the exact timestamp of the event.
How we built it
The system processes video through a multi-stage AI pipeline. First, videos are segmented into narrative scenes using structural scene segmentation. Each frame is then analyzed using YOLOv8 object detection and persistent multi-object tracking to maintain entity identity across time. Motion intelligence models analyze velocity patterns, while an interaction graph layer captures relationships between entities. Finally, scenes are ranked using importance scoring and indexed for semantic retrieval using natural language queries.
Challenges we ran into
One of the biggest challenges was maintaining persistent identity tracking across long video sequences, especially when objects temporarily disappear or overlap. Another challenge was designing a scene importance scoring system that highlights meaningful events rather than random motion spikes. Balancing efficiency with accurate scene reasoning while keeping the system fully local was also a key technical challenge.
Accomplishments that we're proud of
We successfully built a fully local, explainable video intelligence pipeline capable of modeling temporal events rather than isolated frames. SceneIQ performs scene segmentation, persistent entity tracking, motion reasoning, and semantic retrieval within a modular architecture. Most importantly, we demonstrated that meaningful video understanding can be achieved without heavy black-box transformer models.
What we learned
Building SceneIQ taught us that temporal continuity is essential for understanding video narratives. Motion dynamics and interaction density reveal the importance of moments far better than frame-level object detection alone. We also learned that carefully engineered pipelines can deliver strong semantic reasoning while remaining efficient and interpretable.
What's next for SceneIQ: Structured Temporal Scene Intelligence
Next, we plan to enhance SceneIQ with graph neural networks for deeper interaction reasoning, multimodal fusion with speech transcripts, and cross-video narrative linking. Our long-term vision is to make video fully searchable by meaning, enabling applications in public safety monitoring, disaster response analysis, education, and intelligent media indexing.
