Inspiration
This month, Uzbekistan's Ministry of Internal Affairs announced that 69,962 crimes were committed using information and communication technologies in just six months — the vast majority of them money stolen from ordinary people through electronic payment systems. Almost every one of those crimes started the same way: a single message engineered to create fear, greed or urgency.
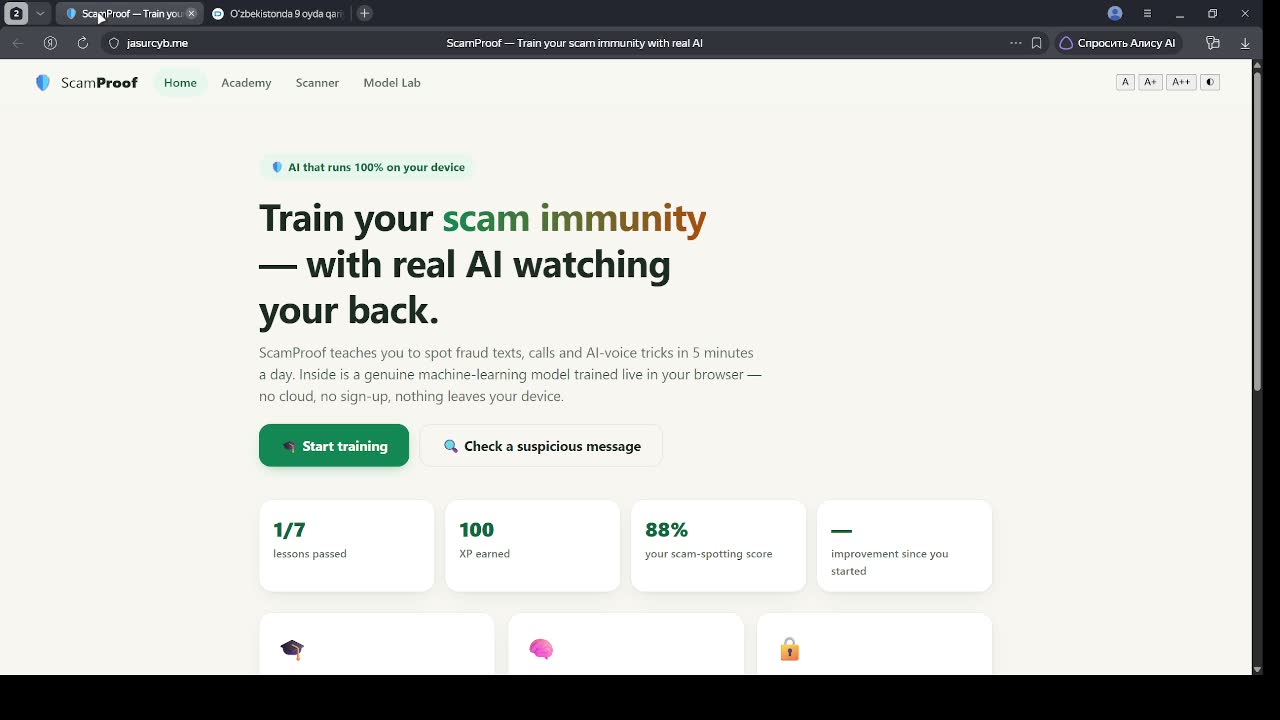
We knew the research: fraud awareness training is the most effective defence — once a person can name the trick, the trick stops working. But today's training is either a boring leaflet or a cybersecurity course. Meanwhile adults 60+ alone lose $3.4 billion a year to fraud (FBI IC3), and generative AI made scams sound like your own family: 3 seconds of audio from a social media video is enough to clone a voice. We wanted to turn protection into a daily 5-minute habit — like Duolingo for scam immunity — and to do it honestly: with a real ML model, not an API wrapper.
What it does
ScamProof is a free, private web app with four modules:
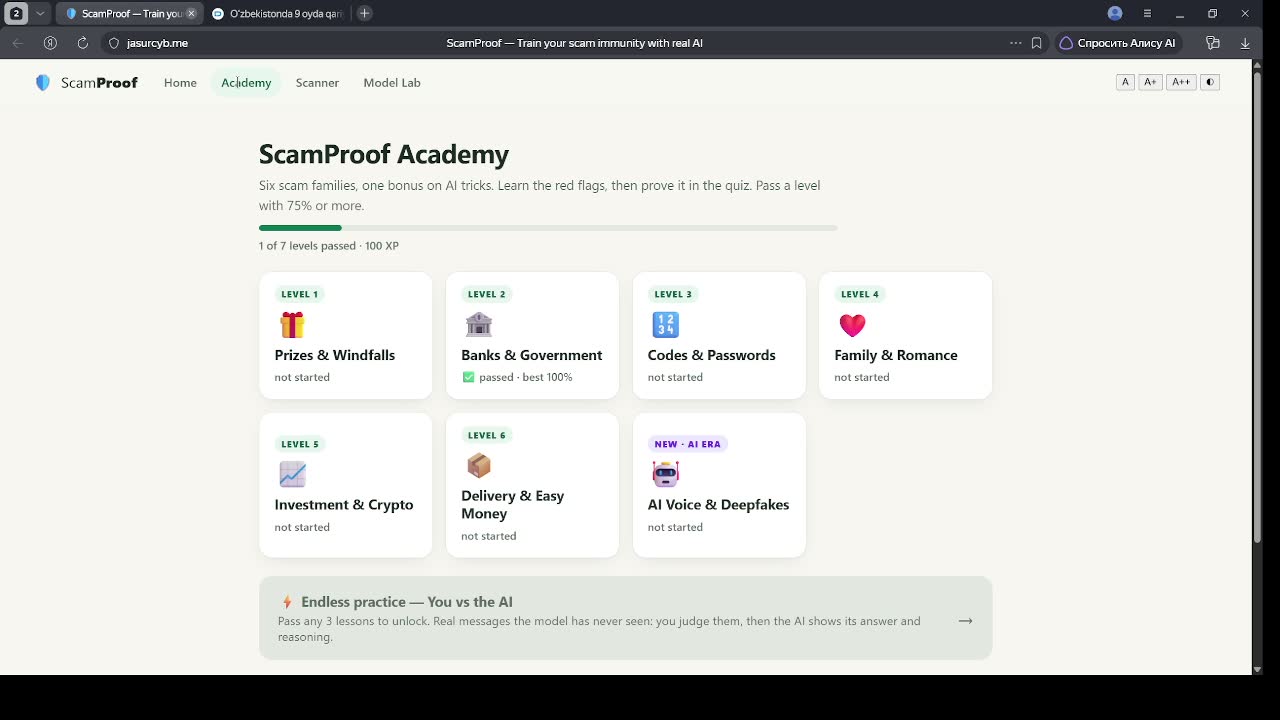
- Academy — six scam families (prizes, fake banks, OTP theft, family/romance, investment, delivery) plus a bonus level on AI voice & deepfakes. Each level: three memorable red flags, a "golden rule", then a quiz on realistic messages with instant plain-language feedback. The app tracks each user's scam-spotting score and improvement since their first session.
- You vs the AI — endless practice on real messages the model has never seen. You give your verdict first; then the AI reveals its verdict, confidence and reasoning. You learn both to trust your intuition and to question the model.
- Scanner — paste any suspicious text: scam probability in ~0.2 ms, classic red flags found (links, urgency, gift cards, OTP requests), and the exact words that pushed the decision. Nothing is uploaded — there is no server to upload to.
- Model Lab — watch the model train from scratch in the browser: loss curve, accuracy/precision/recall/F1/ROC-AUC, confusion matrix, top scam & safe signals. Press Retrain and the numbers hold up on a fresh random split.
Senior-first by design: three text sizes, high-contrast mode, shame-free tone, works offline once loaded, runs on a 10-year-old phone.
How we built it
Vanilla HTML/CSS/JavaScript — zero frameworks, zero dependencies, zero build step. The ML pipeline is our own implementation (~200 lines):
- Tokenizer — URLs, phone numbers, money amounts and shouty punctuation are mapped to dedicated signal tokens; unigrams + bigrams.
- Vectorizer — sparse binary features, top 6,000 n-grams.
- Model — class-weighted, L2-regularized logistic regression, full-batch gradient descent, 1,200 epochs — trained live in the browser in under a second.
- Evaluation — on the UCI SMS Spam Collection (5,574 raw → 5,118 cleaned messages), 80/20 split: 98.9% accuracy, 99.2% precision, 92.2% recall, F1 95.5%, ROC-AUC 0.988 — 118 of 128 scams caught, 1 false alarm in 895. Metrics are computed only on the held-out set; retraining re-splits the data so users can verify stability.
- Hybrid layer — a transparent rule engine surfaces classic red flags with human explanations alongside the learned model.
Challenges we ran into
- Class imbalance (87% ham / 13% spam) silently destroyed a naive classifier — it could claim 87% accuracy by always saying "safe". Class weighting mattered more than anything else.
- Training fast enough to be interactive. A full pipeline in a browser tab is a performance problem: we chose sparse binary features and full-batch GD over anything fancier, and got sub-second training.
- Honest evaluation. It is tempting to show train-set numbers. Every metric in the UI is computed on messages excluded from training, and the Retrain button re-splits so anyone can check.
- Designing for the actual victims. Large text and high contrast initially felt like constraints — they ended up improving the design for everyone.
Accomplishments that we're proud of
- A from-scratch ML model that beats many published baselines on this dataset — small enough to retrain in a browser tab in 0.6 s.
- Zero-cloud, zero-account architecture: the whole project is a folder anyone can run by double-clicking
index.html. - Lesson content that covers the newest tricks, including AI voice cloning — not just 2010-era Nigerian prince emails.
What we learned
- Feature engineering beats model complexity: mapping URLs/phones/money to dedicated tokens was worth more than any fancier architecture.
- Interpretability is not a luxury for safety tools — it is the product. A verdict you can't question is a verdict you shouldn't rely on.
- Trust is built by showing your work: the Model Lab convinced more people than any slide ever could.
What's next for ScamProof
- Multilingual interface and lessons (Russian and Uzbek first — the scams in the news above happen in those languages, on Click/Payme-style rails).
- Family mode — caregivers generate fresh practice quizzes from recent real scam reports.
- Voice-clone awareness mini-game with synthetic audio examples.
- Community lesson packs for new scam families as they emerge.
Built With
- css
- html
- javascript
- logistic
- machine-learning
- natural-language-processing
- sms
- spam
- uci

Log in or sign up for Devpost to join the conversation.