Inspiration
The user is every Bee wearer who has read a fact about themselves and thought "I never said that." The complaint is public and specific:
- "My @bee__computer AI app heard me watching @SHO_Dexter and now it thinks I'm a serial killer. (I deleted this "fact" about me.)" (AttractionsMatt on X)
- One week in, stetzinger on X counts 48 facts about himself with most of them the same claim.
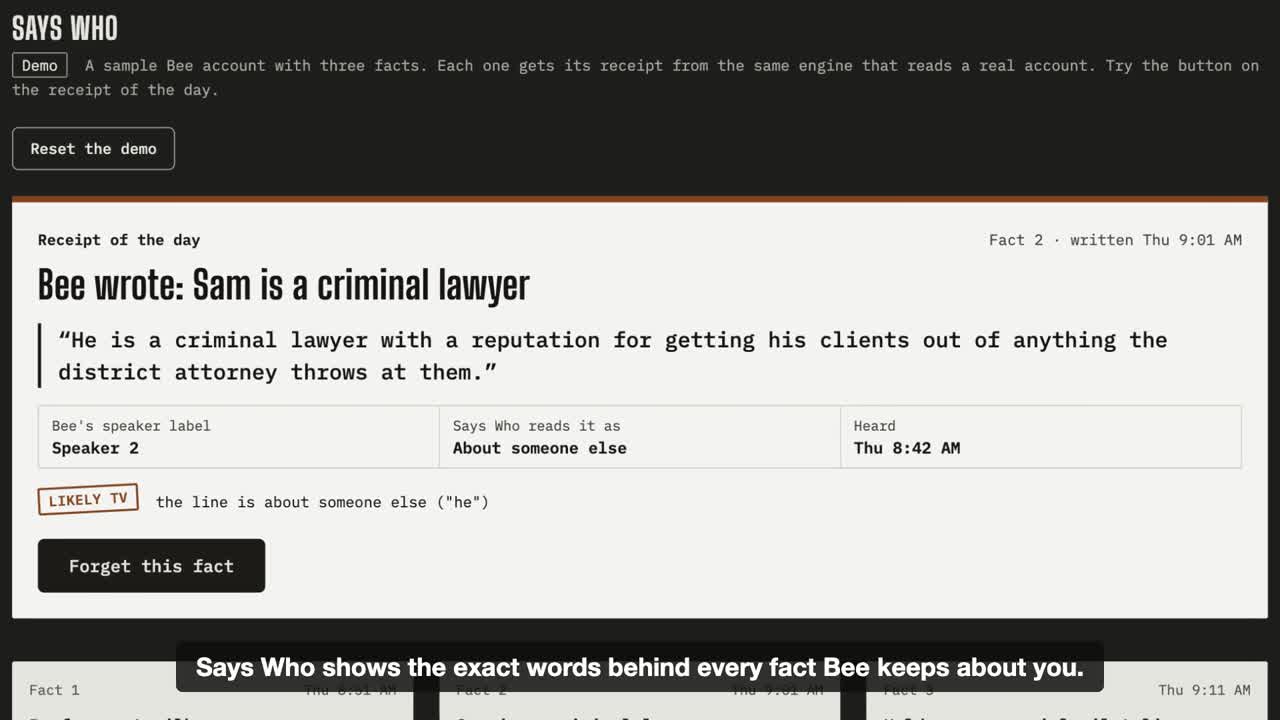
- A Forbes Vetted reviewer's facts included "Dave is a criminal lawyer", pulled from a TV show.
Bee's own review screen shows a bare claim and asks for a swipe. The reason behind the claim is missing, so the wearer has to guess whether a TV line or their own sentence produced it. We built the missing reason, and put the decision where the wearer already is: the wrist.
What it does
Every fact Bee writes gets a receipt:
- the verbatim utterance that matches it, never a summary,
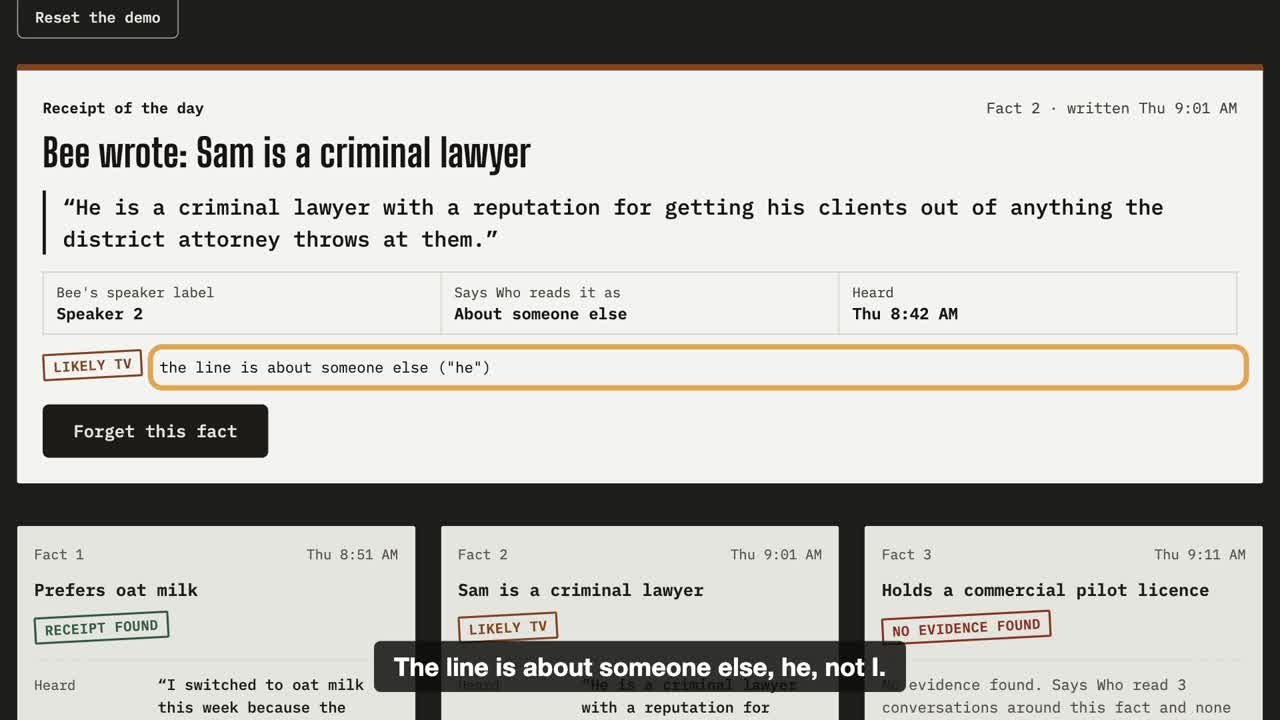
- who said it, by Bee's own speaker label and by what the words themselves say (first person, "my brother", a named participant),
- when it was said, in which conversation, and how long before Bee wrote the fact ("19 min before Bee wrote it"),
- a TV signal for that conversation with every cue listed (a non-wearer voice, other voices, scripted cadence, show and podcast phrases, third person),
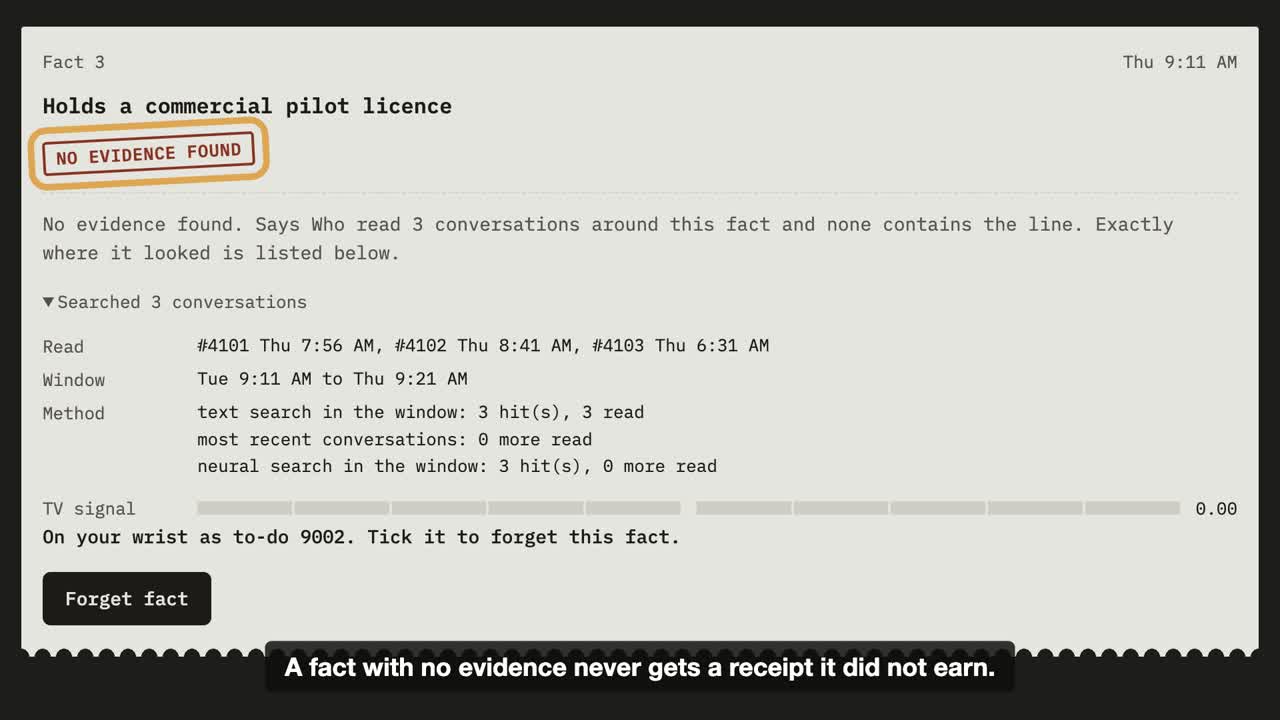
- exactly where Says Who looked: the conversations read, their times, the search window and the method,
- for a close but inconclusive match, a row "Checked by Amazon Bedrock" with the model's verdict and reason.
The verdict is one of six: supported, likely-tv, unattributed, no-evidence, duplicate, contradicts.
Every verdict except supported becomes a Bee reminder on the Watch with alarm_at set to now, phrased as a question over the matching line: "Did you say it, or hear it?" The wearer ticks it. Says Who then runs facts delete, reads the fact back with facts get, and records the decision only when Bee answers not found. The post-condition is Bee's own answer, not our request.
Three details carry the trust:
- A planted fact that no utterance supports comes back
no-evidenceeven when search returns every conversation. - "My brother is vegan" never supports "is vegan", and "does not like oat milk" is never supported by "I switched to oat milk". Negation is read per clause.
- Every receipt lives in a local SQLite ledger (fact id, verdict, 25-word quote, speaker, time, TV score, decision), so the evidence outlives Bee's history window and the recordings Bee deletes.
A review page on http://127.0.0.1:8790 opens with the receipt of the day in three numbered steps: (1) Bee writes a fact, (2) Says Who finds the line, with Bee's speaker label beside Says Who's reading of the words, the time and the gap, (3) your wrist decides, drawn as a watch face holding the reminder word for word as Bee stores it. A live tape shows new facts, matched lines and wrist ticks as they land. npm i && npm run demo opens /demo, a sample account with no Bee login: a supported, a heard-on-TV and a no-evidence receipt, plus a jazz fact only Amazon Bedrock can receipt when a key is set. Its Tick button completes the to-do in the sample Bee, the live loop's own reconcile deletes the fact and reads it back, the hero flips to "Forgotten 7:22 PM, read back from Bee: gone." in about 50 ms, and the next reminder takes the wrist.
An Agent Skill (skills/receipts/SKILL.md, bundled as skills/receipts.skill) lets Claude Code answer "why does Bee think I'm a lawyer?" with the quote, speaker, time and score, and carries a worked exchange end to end. npm run why -- --demo "criminal lawyer" and npm run report -- --demo --md run it on the sample account with no login. The markdown report is a self-review the wearer keeps: every questionable fact with its quote and decision time, and "Questionable facts in Bee: before 2, now 1" once one is forgotten.
How we built it
TypeScript on Node 22.13+. createBeeClient from @beeai/cli/lib is the runtime hook, so every Bee call shells through the real bee binary.
says-who watchreadsbee changed --cursorevery 60 seconds and saves the cursor only after the batch is processed, as the bee-skill requires.- Each new fact is searched against conversations: BM25 first, the most recent conversations next, neural search when those find nothing. Candidates are re-read through
conversations getand matched on utterances. Between two equally good lines, the one spoken closest to when Bee wrote the fact wins. - A close but inconclusive match goes to Amazon Bedrock (
openai.gpt-oss-120bthrough the OpenAI-compatible endpoint), on wheneverAWS_BEARER_TOKEN_BEDROCKis set. Attribution, negation, duplicate and contradiction rules run in code. Duplicates are the same claim against an older stored fact (token Jaccard 0.8 or more). Contradictions are opposite polarity against a fact the wearer confirmed (0.6 or more). - The wrist step creates a reminder with the fact id carried as
[rcpt:<id>], and abee stream --typeswake-up plus a poll finds the tick. - Facts the wearer already confirmed get a receipt and no reminder. Supported facts are confirmed from the review page with a read-back on
confirmed.
Proof that the checks can fail:
- 100 tests pass, including the real client calling the bundled
beebinary, a fullsays-who oncepass through a spawnedbeeprocess, the demo wrist tick throughreconcile, and two live Amazon Bedrock calls. npm run mutationbreaks the guarded code 35 ways (matcher always hits, forget without a tick, reconcile ignoring the tick, TV signal removed, cursor handling, search scope, attribution, Unknown speaker handling, the recency tiebreak, the self-review count and more), requires red each time, restores and requires green.npm run viewport-checkframes the review page at 320, 390 and 1440 px and fails on horizontal scroll, clipped text or small tap targets. A control run with deliberately broken CSS must fail or the check itself fails.- An unticked reminder produces no delete.
Challenges we ran into
- A fact has no pointer to its conversation. The fact object is
{ id, text, tags, created_at, confirmed }. Provenance is reconstructed from search plus a lexical match over utterances. The matcher has to refuse the easy yes: a line about someone else shares the fact's words and still must not count. - The wearer is not labelled. Speech arrives as
Unknownand names drift, so "who said it" combines the label with other voices, cadence, show cues and person.Unknownis unknown attribution everywhere, never the wearer. - Bee does not stream new facts. New facts arrive by polling
bee changed, so the cursor logic and its failure fallback matter more than the wake-up. - Short recordings vanish. Under about 50 words, a recording is deleted, so nothing may depend on a short spoken command. The wrist tick is the input, and the ledger keeps the evidence after Bee drops the source.
Accomplishments that we're proud of
- A verdict that says why, and says where it looked.
no-evidencenames the conversations it read instead of asserting a negative. - A destructive action with a read-back: the fact is forgotten only when
facts getanswers not found. - A wrist interaction with no speech. The wearer ticks a reminder, and the review page shows that exact reminder on a watch face with a Tick that runs the real reconcile path.
- Amazon Bedrock doing visible work: in the demo it receipts "Enjoys jazz" from "Jazz records are all I play in the evenings.", a paraphrase word matching cannot prove, and the receipt says "Checked by Amazon Bedrock".
- A self-review the wearer can keep: questionable facts before and now, each with its quote and the time it was decided.
- Competitor sweep result: across the other Bee entries read from source, none checks Bee's facts against utterances, and none calls fact confirm or update.
What we learned
- Provenance is a product feature, not a debug tool. The same fact with its quote beside it is a different decision for the wearer.
- A false receipt costs more than an extra wrist reminder, so mixed clauses ("my brother is vegan and I am too") resolve to "about someone else" on purpose.
- A heuristic with a printed reason is easier to trust than a score with none. Every cue is listed on the receipt.
What's next
- Run the wrist loop across a full week of a real account and publish the verdict split by fact.
- Fact provenance as a recipe in the Bee skill, and a
source_conversation_idon the fact object, which would turn reconstructed provenance into exact provenance. - Show cues for more languages and shows.
Built With
- amazon-bedrock
- apple-watch
- bee-agent-skills
- bee-api
- bee-cli
- node.js
- server-sent-events
- sqlite
- typescript

Log in or sign up for Devpost to join the conversation.