Inspiration
Shifting flexible electricity use (EV charging, data-center jobs, building pre-cooling) into the cleanest hours cuts CO₂ with no new hardware. But a 2025 Nature Communications paper by Stanford researchers shows what happens when everyone gets the same advice ("2 AM is cleanest"). They all pile into the same hour, the spare wind runs out, and gas plants ramp up to cover the rush. We call this herding: companies are promised savings that never show up. We wanted to know whether it happens on a real grid, and whether coordinating competing companies, and paying them for it, could fix it.
What it does
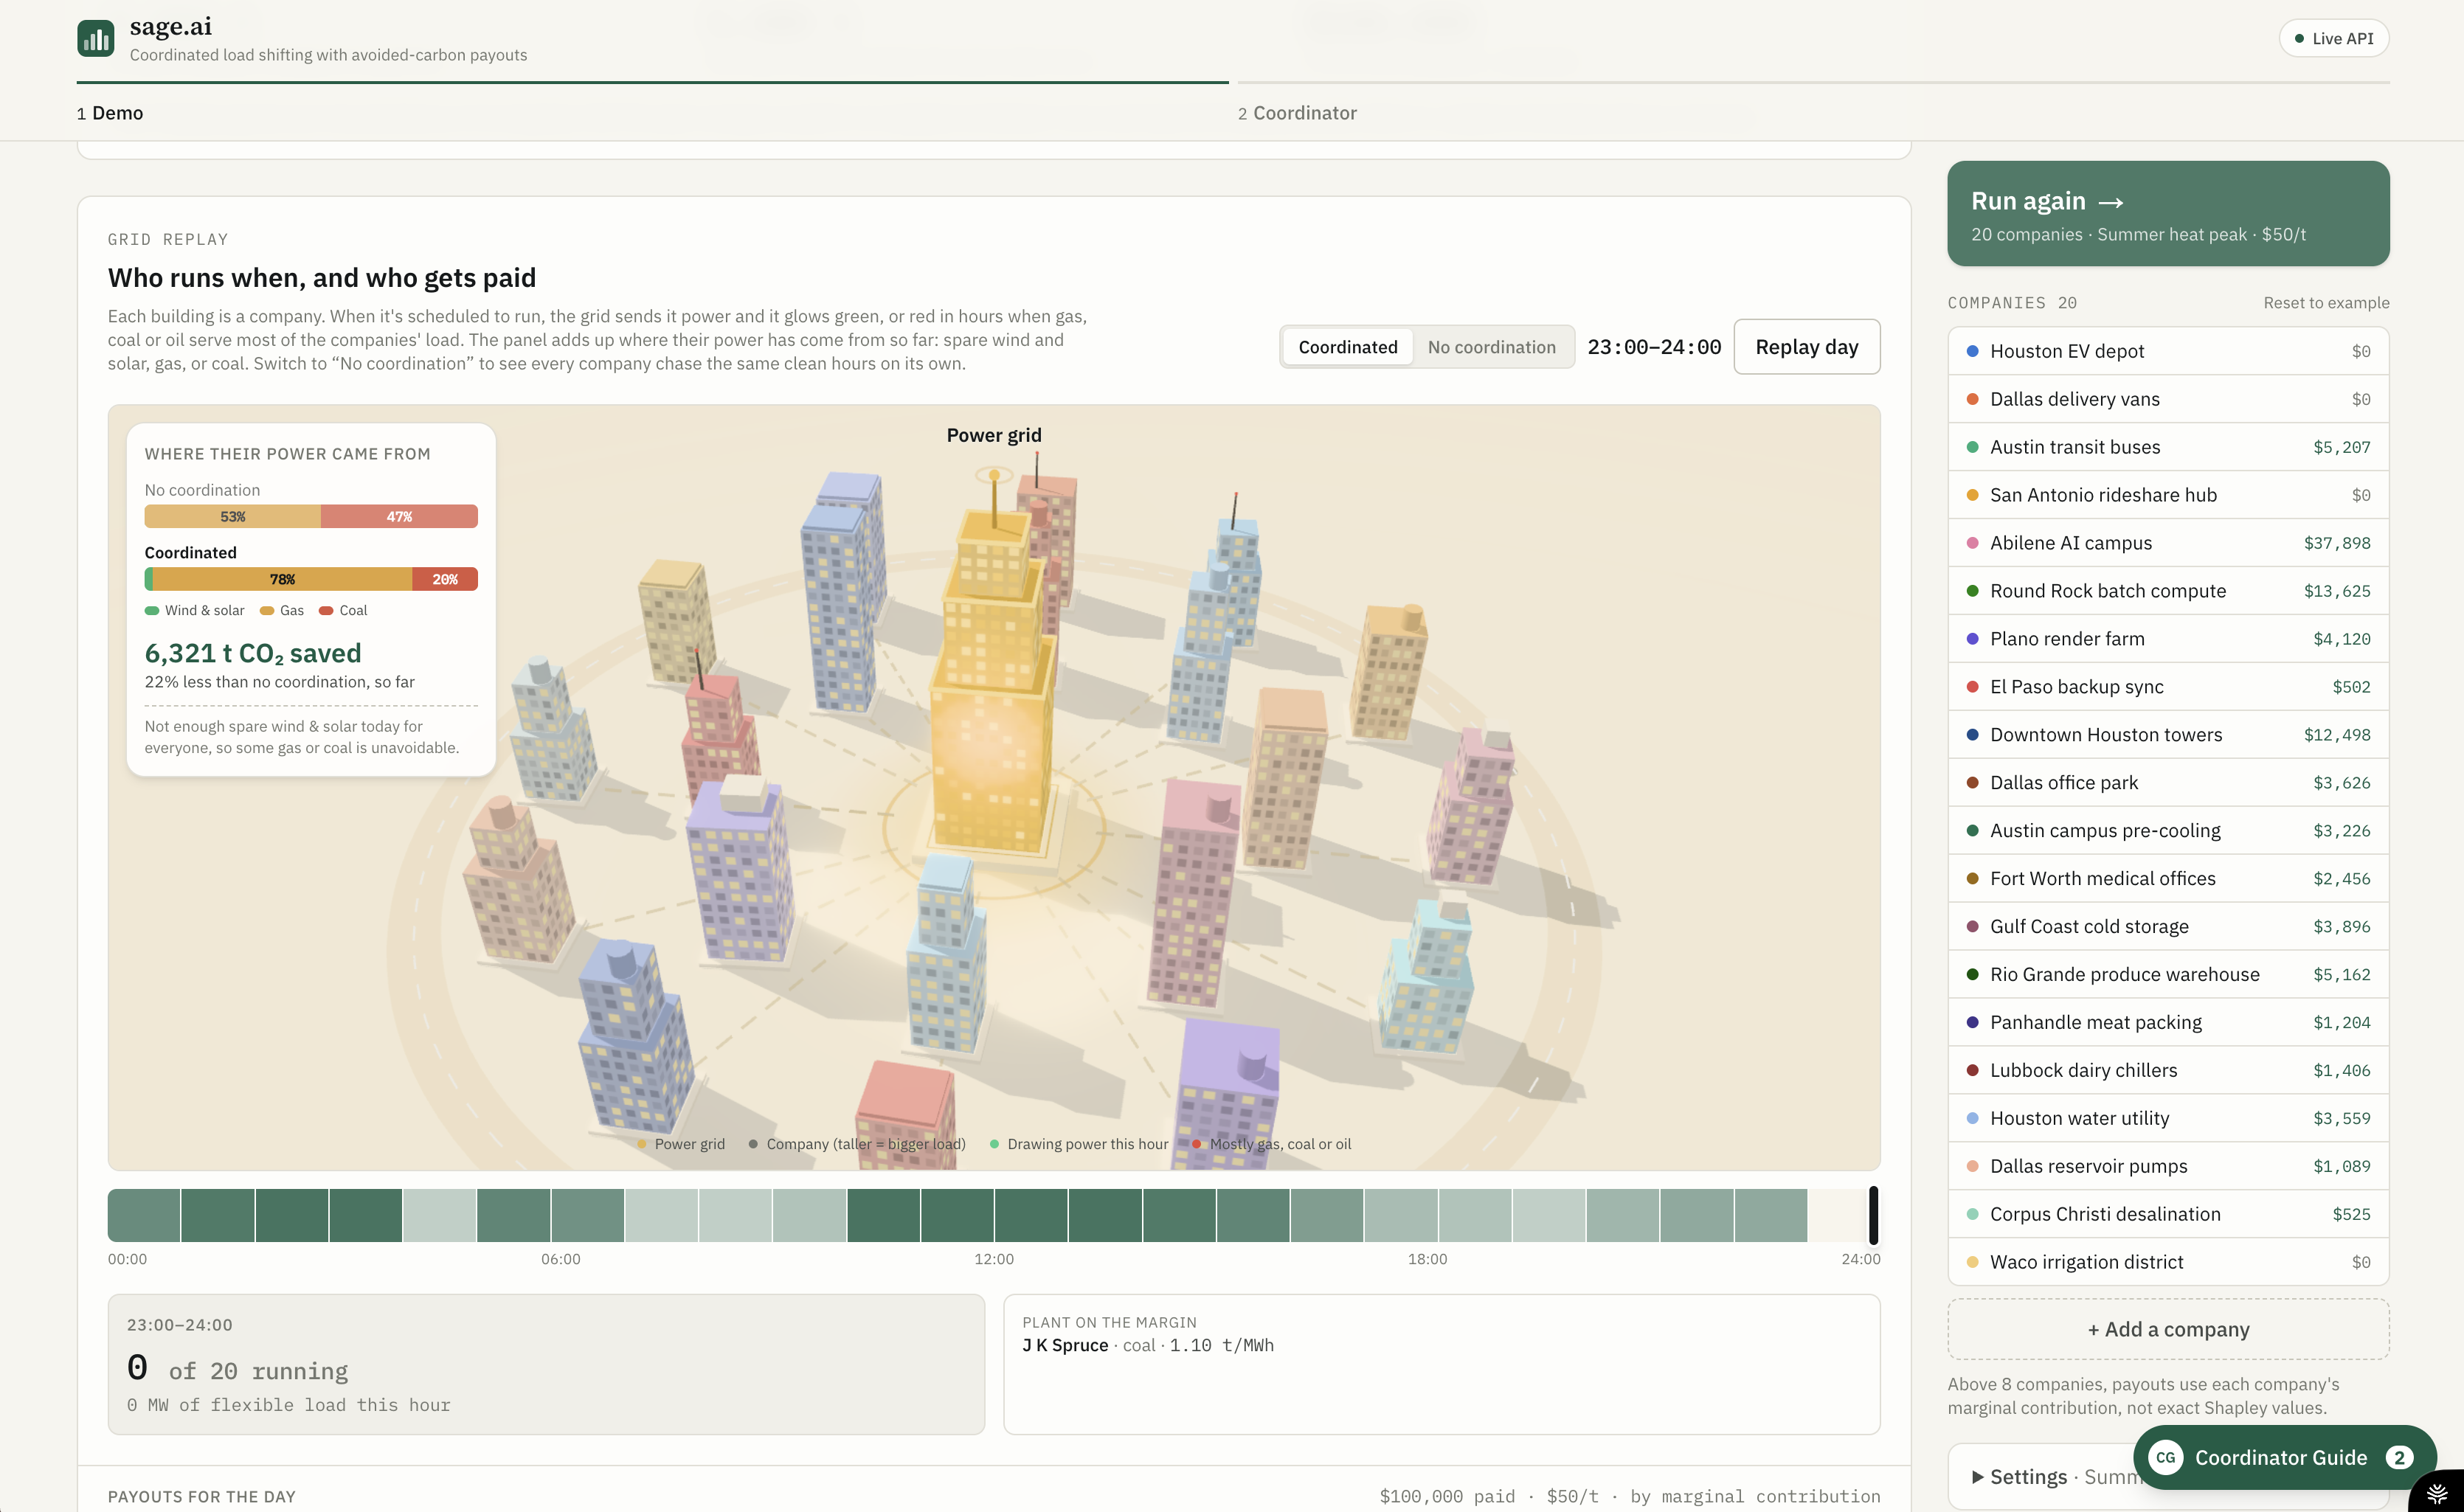
Sage.ai coordinates flexible demand across competing companies so their clean-power efforts don't cancel each other out.
- Companies submit sealed bids: energy, time window and max power. No usage history is shared.
- We schedule everyone jointly on a digital twin of the Texas (ERCOT) grid, so no one tramples anyone else's clean hours.
- Plans are made on a forecast and graded on reality: we schedule at midnight, then re-score on what the grid actually did.
- Each company gets paid its fair share of the CO₂ that coordination avoided, computed with Shapley values.
The Coordinator Guide, an AI agent built on Chalk, helps users build valid bids. It explains fields, checks feasibility, finds the cleanest hours and proposes one-click fixes. It can also turn an uploaded utility bill into a bid.
How we built it
- Real data: EIA-930 hourly grid data, EPA eGRID (283 fossil plants), EIA fuel prices, ERCOT curtailment and forecasts, and GFS weather forecasts, all for 2024.
- Grid twin: a NumPy merit-order simulator, calibrated on 248 days. It gets within 7.7% hourly CO₂ error on 104 held-out days.
- ML forecast: gradient-boosted models for tomorrow's demand (1.92% MAPE), wind and solar.
- Chalk:
- The feature store serves the forecast and bid features on every clear.
- The Model Gateway runs the Guide on Claude Sonnet 5.5, grounded only in live app data.
- A sandbox Function turns uploaded bills into bids.
- Evaluations grade the agent with deployed scorers plus an LLM judge.
- Stack: FastAPI, scikit-learn, Next.js, React Three Fiber and Recharts.
How we evaluated the agent:
- Chalk Evaluations (44 graded questions):
- facts correct 1.000
- numbers grounded in the data 0.991
- suggested fixes valid and correct 1.000
- LLM judge 0.75
- bill extraction 10/10
- Real-use scenarios (15, over HTTP): these include multi-turn chats, prompt injection and concurrent load. The deployed app passed 9/15, exposing 5 bugs. After fixing them it passes 15/15 locally, with a regression test for each fix.
Challenges we ran into
- Our first grid model burned no coal at all. Calibration fixed it with named, bounded parameters.
- We pre-registered the herding test before building anything. If it had failed, we would have stopped.
- Coordination doesn't win every day. Forecast error can flip a plan that looked best at midnight, so we report the losses.
- Our first eval scorers graded wording instead of meaning, so a correct LLM scored 0.41. We rewrote them.
Accomplishments that we're proud of
- Confirmed herding on a real grid: a pre-registered test found it on 6 of 7 held-out days.
- Coordination works at scale: across 2,760 out-of-sample runs in late 2024, it beat companies optimizing alone by ~300 t CO₂/day at 10% flexible load and ~960 t/day at 20%.
- An agent we can measure: it got every fact right and grounded 99% of the numbers it cited. Our scenario suite then caught 5 bugs, which we fixed with regression tests.
- Every number on screen traces to data or code, and we publish the misses.
What we learned
- Your extra load gets whichever plant is next in line, not the grid's average mix. That marginal plant is the signal that matters.
- When everyone acts on the same good signal, it stops being good. Coordination is a different lever from better forecasting.
- Pre-registering tests and grading on reality kept us honest.
What's next for Sage.ai
- Richer grid: transmission congestion, more grids (CAISO, PJM) and an optimization-based scheduler.
- Real pilots with EV-charging and data-center schedulers, plus extraction tested on real bills.
- Close our eval gaps: run the scenario suite on the Chalk LLM path and improve how the agent explains infeasible bids.
Built With
- anthropic
- chalk
- claude
- eia-930
- epa-egrid
- ercot
- fastapi
- next.js
- numpy
- open-meteo
- pandas
- pyarrow
- pydantic
- pytest
- python
- react
- react-three-fiber
- recharts
- scikit-learn
- tailwindcss
- three.js
- typescript
- uv
- uvicorn

Log in or sign up for Devpost to join the conversation.