Inspiration
I have about 50,000 people across my exports and no idea who is in the room. Over the last month I built a personal CRM that fuses Instagram, LinkedIn, iMessage, WhatsApp, Gmail, Google Calendar, Contacts, and Luma and Partiful guest lists into one identity graph. Tonight's brief, build a brain, build an agent, make it do something, was the push to put an agent on top of it. The thing I wanted most: to know when the people I follow change, the way a friend would notice a new bio or a new job, without checking 9,000 profiles by hand.
What it does
Two questions, answered from my own data.
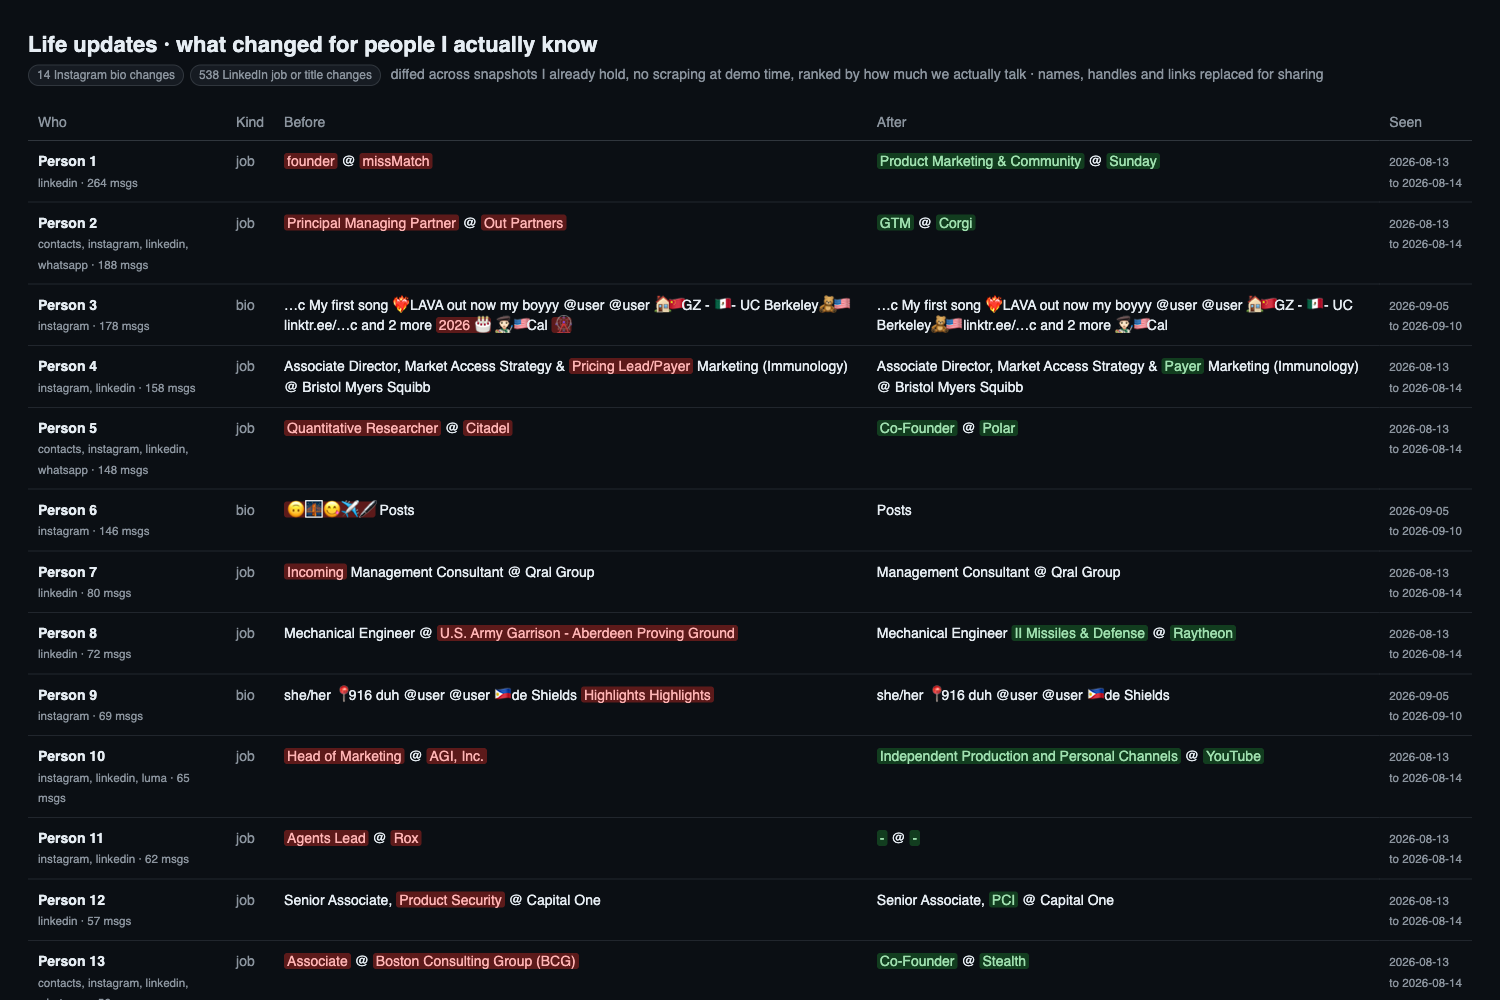
What changed? It re-scrapes the public Instagram bio of everyone I follow, keeps every snapshot, and diffs them. The same diff runs over LinkedIn job titles across my Connections.csv exports. Tonight that found 159 bio changes and 905 job or title changes in my own snapshots, ranked by how much I actually talk to each person.
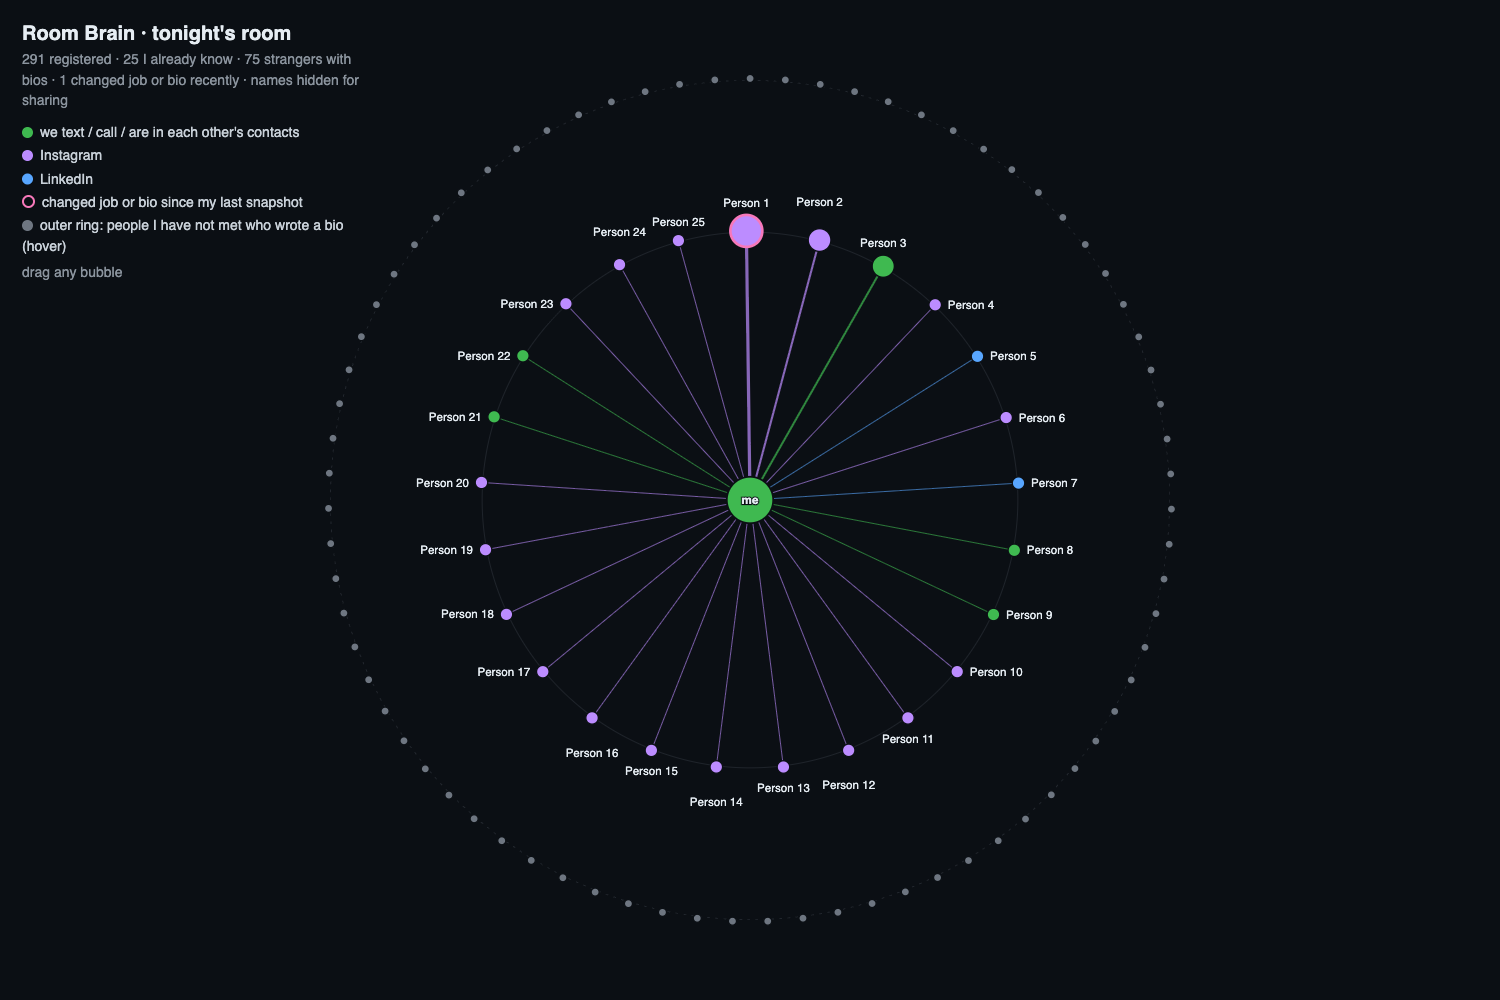
Who do I know here? I pulled tonight's Luma guest list (291 registered) into the graph: 25 people I already know and 75 strangers who wrote a bio, drawn as a map I can drag around.
The agent drafts messages and writes notes back into the CRM. It never sends anything.
How we built it
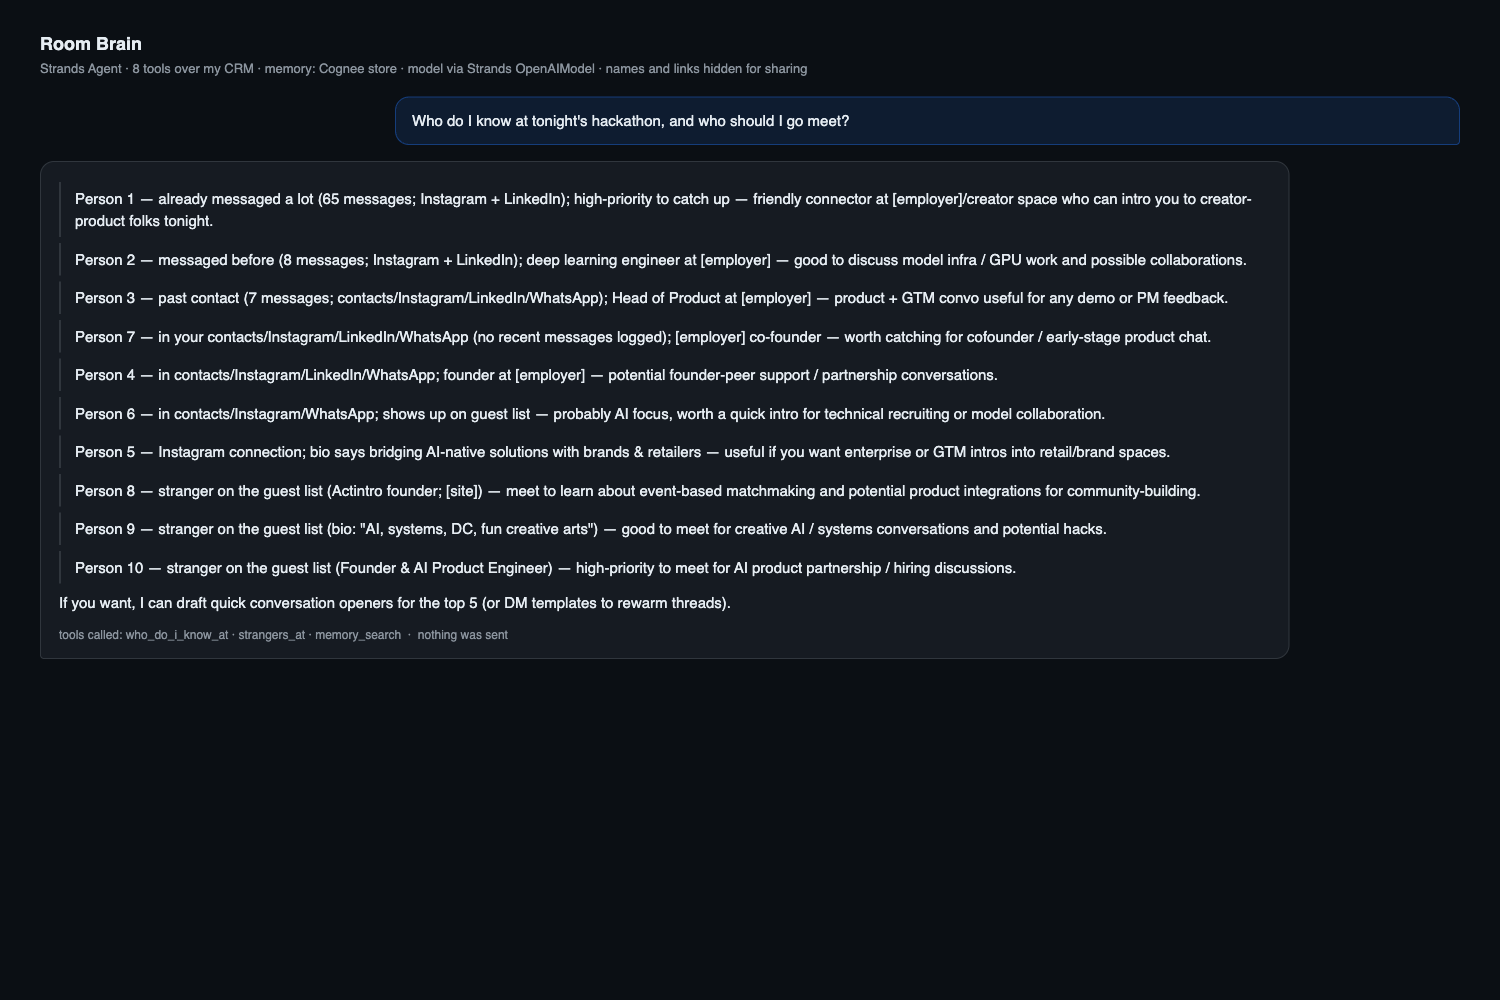
Strands Agents is the harness. One Agent, eight @tool functions over the CRM (who_do_i_know_at, strangers_at, find_person, dossier, life_updates, enrich_url, remember_note, list_events), and a MemoryManager so the model gets memory_search and memory_add, with recall injected into every turn. Model providers swap at runtime: AnthropicModel, OpenAIModel (OpenAI direct or OpenRouter) and OllamaModel for a fully local run.
Cognee is the memory. brain/memory.py implements Strands' MemoryStore protocol over Cognee with three backends. The local graph was built tonight with cognee.remember from 99 fact lines about the guests and the recent changes, and cognee.recall serves search. A Cognee Cloud client for add_text, cognify and search is one environment variable away. A keyword fallback keeps a demo alive while a graph is still building.
Bright Data is the web. enrich_url goes through the Web Unlocker API to read a stranger's public page before the agent recommends them, and it is the path for re-scraping all 9,243 bios at scale instead of my own slow scraper.
Underneath: SQLite with five layers (immutable evidence, identities, people, derived tables, my own notes), d3 for the map, Playwright for the screenshots, uv for the environment.
Challenges we ran into
- I was on my own guest list, so the agent listed me as someone I know. Self-exclusion now comes from the CRM's
self_identitytable. - Two Instagram accounts belonging to one person read as a bio change. The diff now runs per account and joins to the person afterwards.
- My Bright Data token could not create a zone, so tonight's enrichment calls fell back to direct fetches. The client is wired and every result reports which path it took.
- The first force-directed map was a hairball. A radial layout with horizontal labels fixed it.
Accomplishments that we're proud of
- It ran end to end on the judges' own guest list, in one evening, on top of a real graph of 50,135 people rather than a toy dataset.
- Identity resolution on strong identifiers only. A display-name match never counts, which is why "25 people I know" is true rather than flattering.
- The change detection is exact and offline: first-versus-last snapshot per account, no scraping at demo time, and 905 job changes plus 159 bio changes came out of exports I already had.
- Every claim the agent makes comes from a tool result, and it cannot send anything. Its only write is a note into the layer of the CRM reserved for my own judgment.
What we learned
Time is the feature. A brain that overwrites is a phone book; a brain that keeps every snapshot can notice. And "is anyone else doing this?" is a question to check, not to assert: per-account Instagram bio trackers exist (instagram_monitor, instatracker, several apps), and Dex sells LinkedIn job-change alerts. What I did not find is anything that re-scrapes an entire following list over time and fuses the diffs with LinkedIn and message history so they are ranked by real relationships. That is the claim, and only that.
What's next for Room Brain
Run the re-scrape on a schedule through Bright Data, move the memory to Cognee Cloud, add Twitter and website snapshots to the same diff engine, and ship the life-updates feed as the first feature of the CRM I am turning into a product.


Log in or sign up for Devpost to join the conversation.