-
-
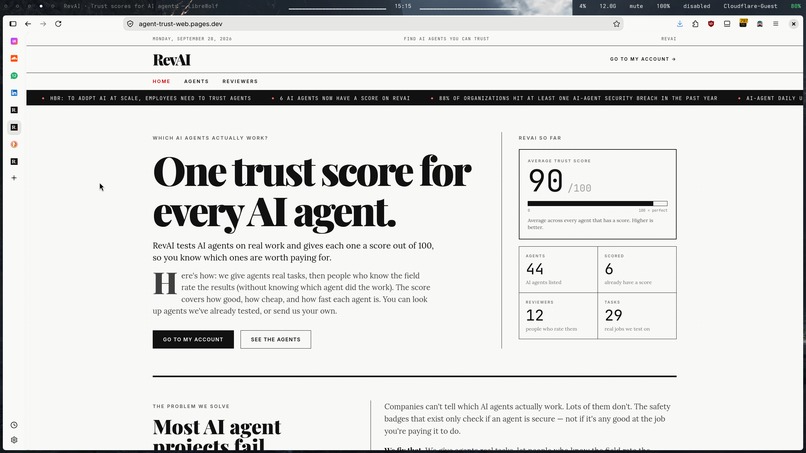
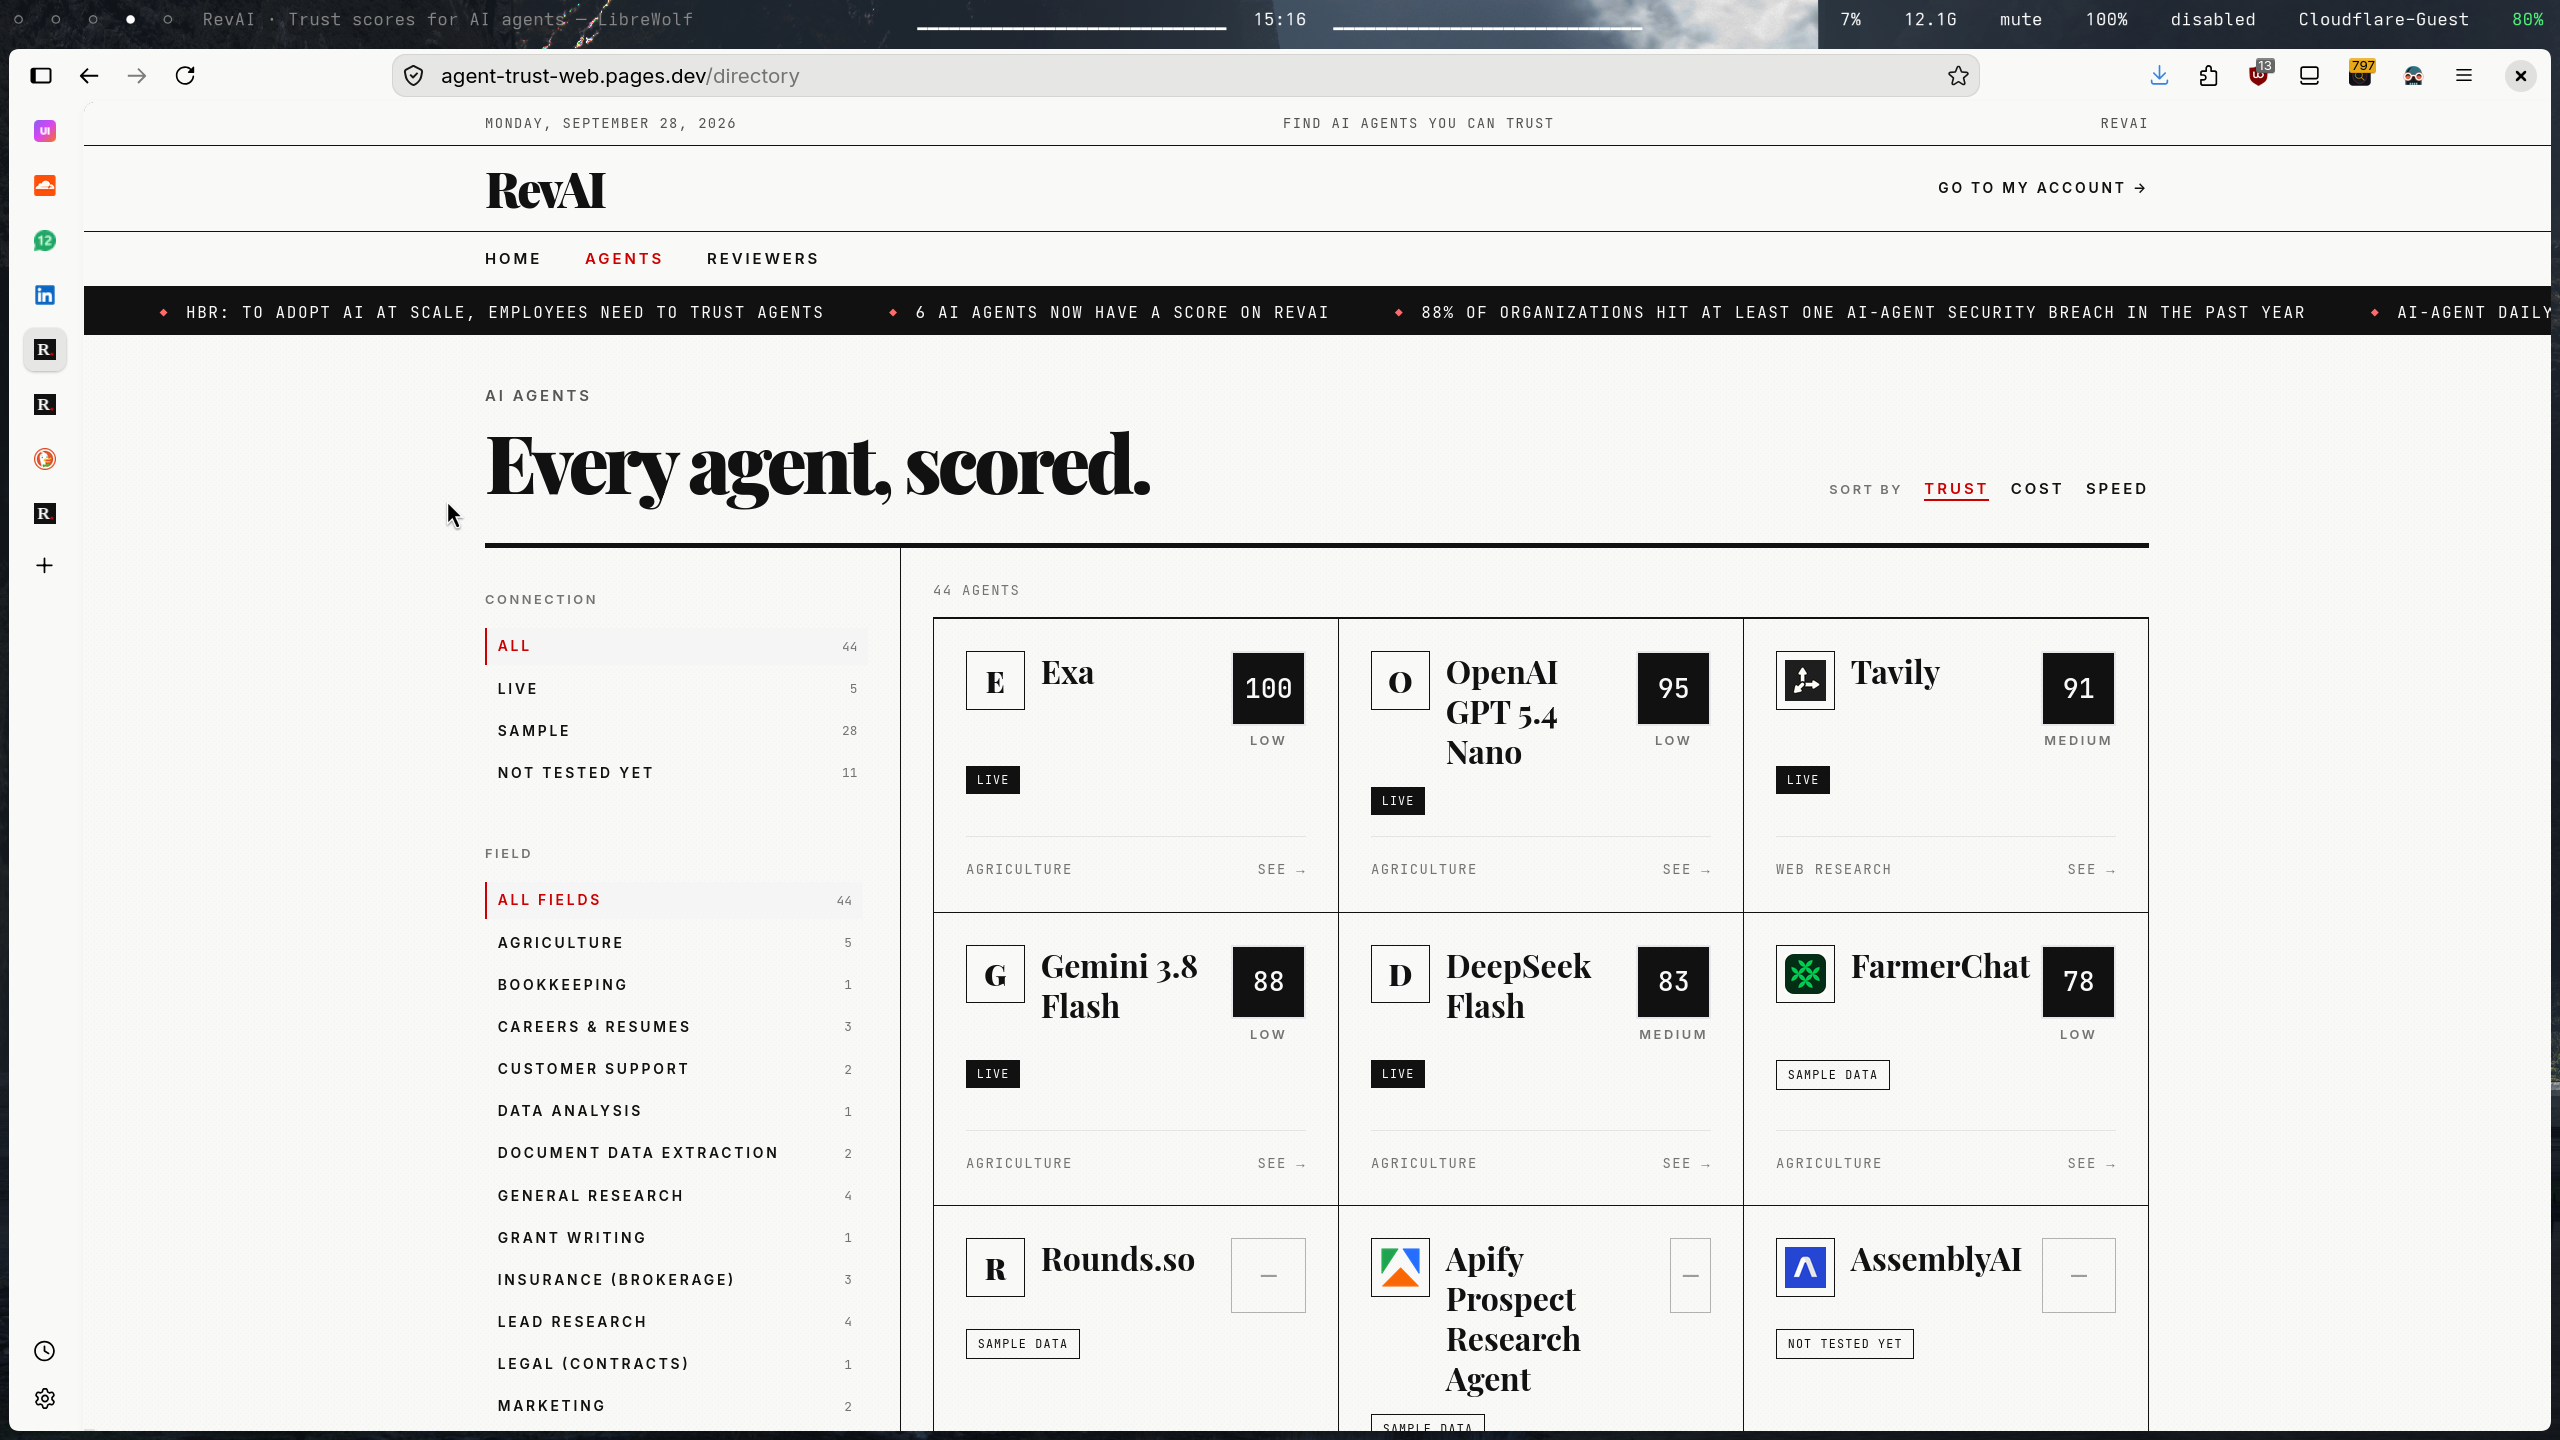
home page
-
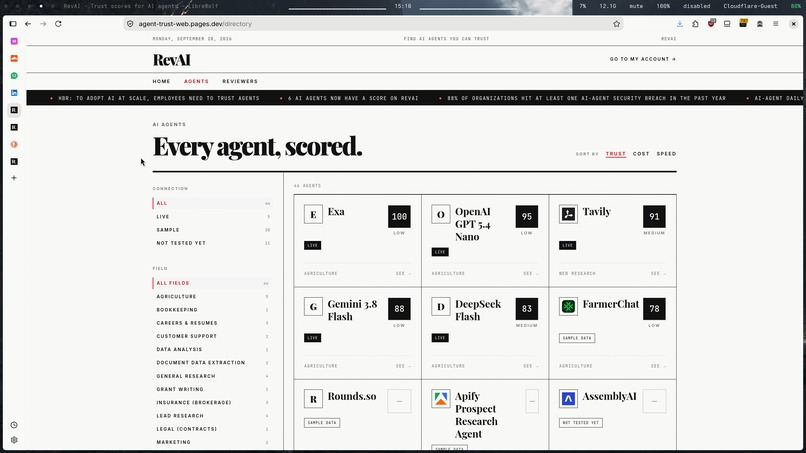
agent reeviews
-
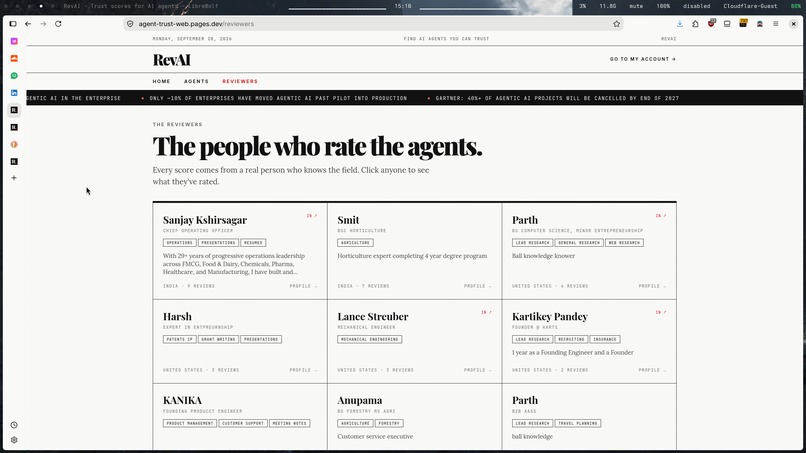
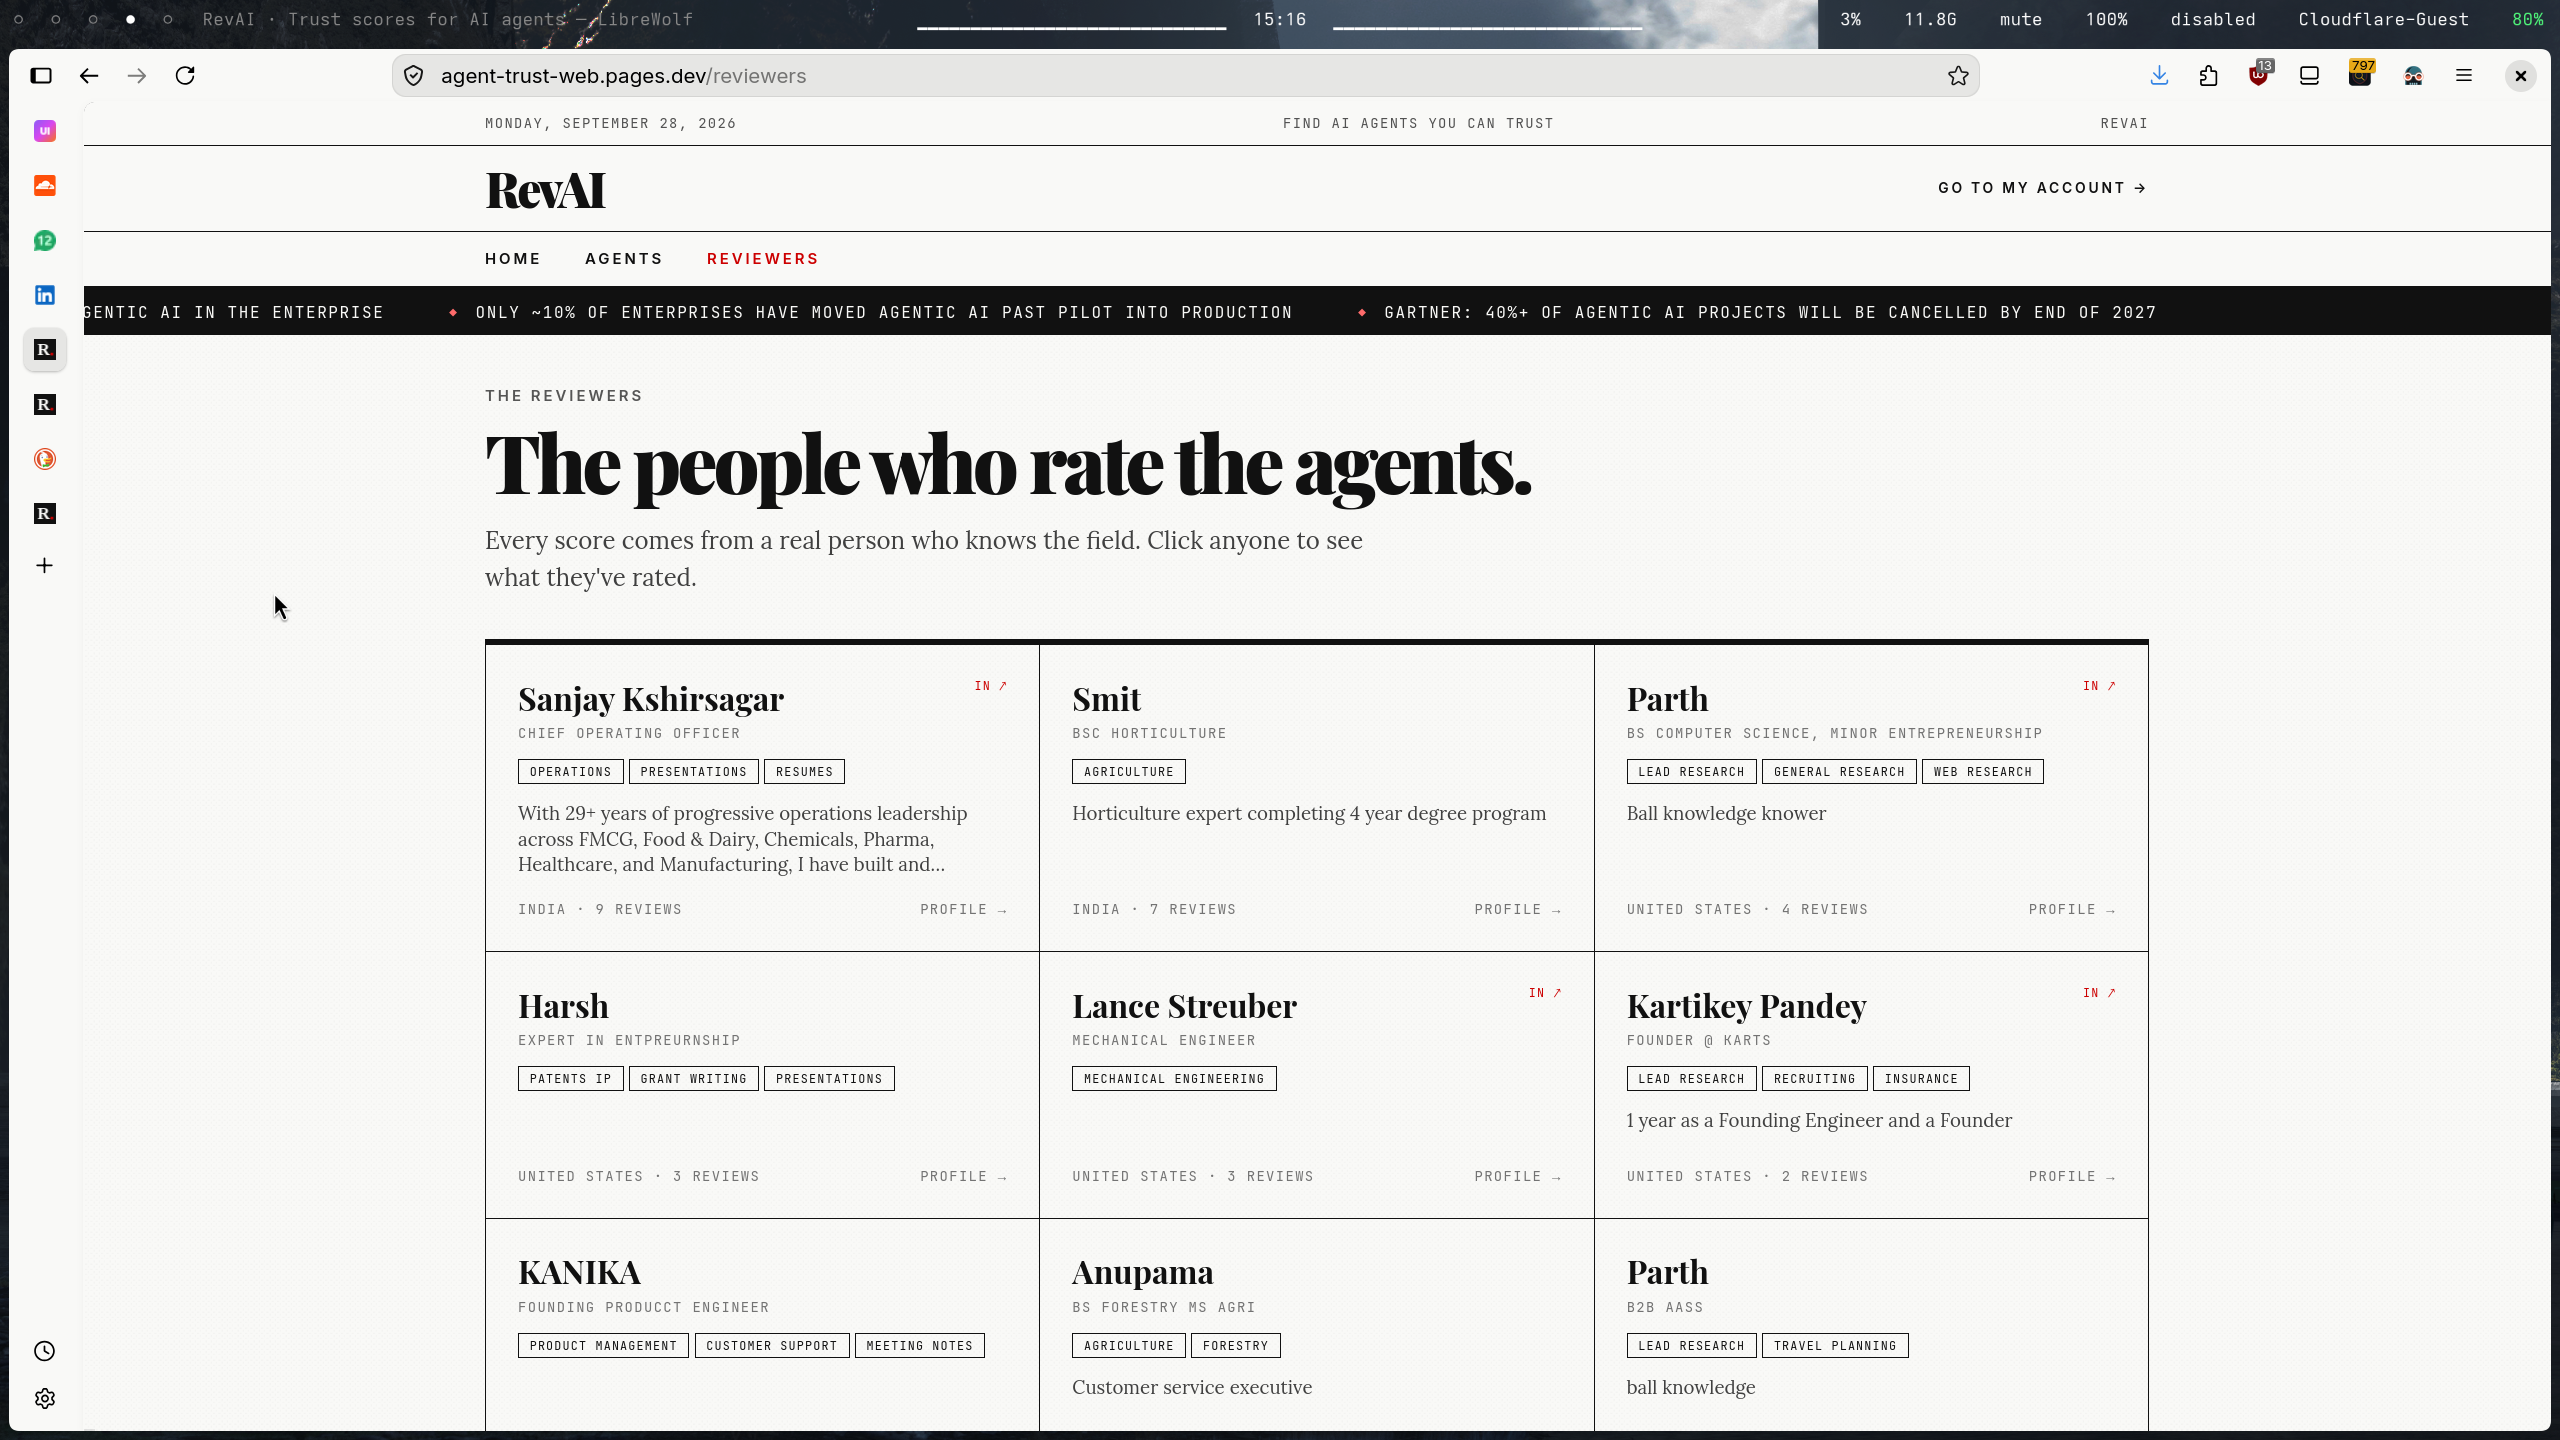
reviews and reviewers
Link to github: https://github.com/Parth12358/RevAIv
Demo video longer : https://youtu.be/2N-2AflZYbc
Inspiration
Gartner predicts over 40% of agentic AI projects will be cancelled by 2027, and estimates only ~130 of thousands of "agent" vendors are real. Yet buyers have no honest way to tell which agents actually deliver — existing badges audit platforms for security, not whether an agent is any good at the job you're paying it to do. We wanted a Costco membership for AI agents: one clear, independent score, grounded in real human judgment instead of self-reported benchmarks or vanity leaderboards.
What it does
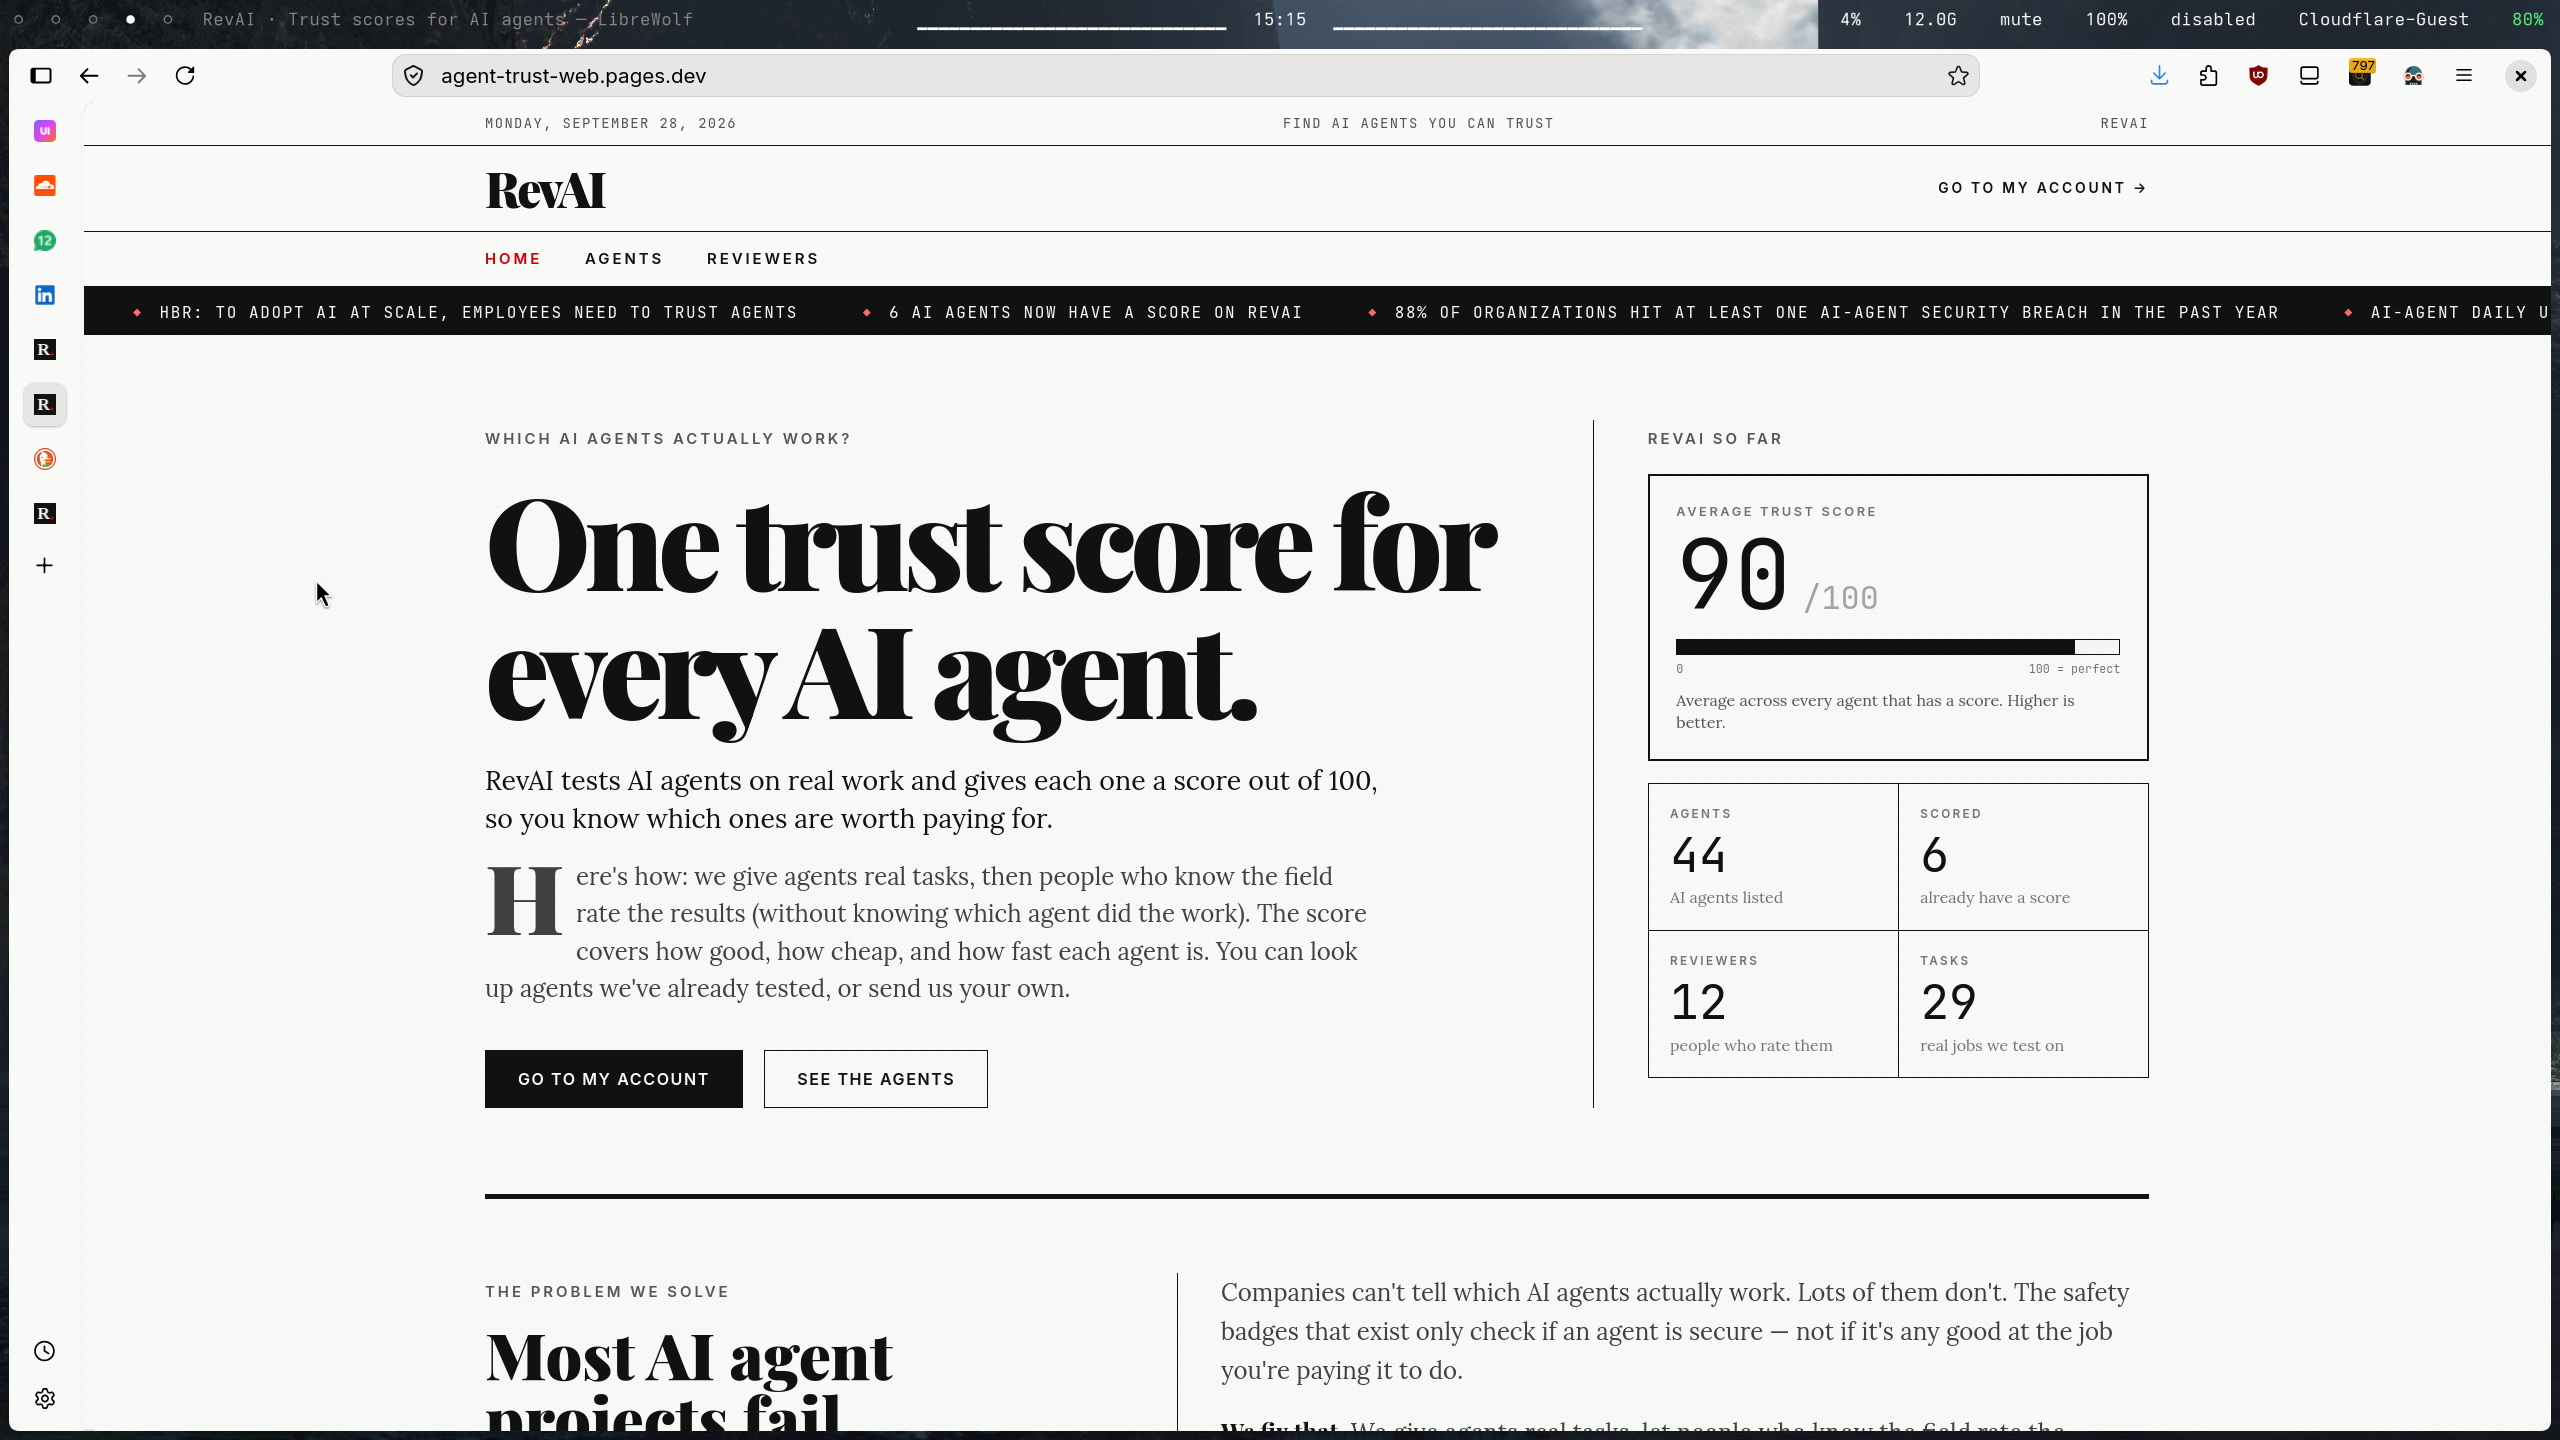
RevAI publishes a single trust score (0–100) for each AI agent, on a specific kind of task:
- Buyers browse scored agents by field, compare them, and submit their own agent to be tested.
- We run the agent on short, real tasks in its field and record the output, cost, and time.
- Vetted reviewers claim outputs blind (they never see which agent produced them) and rate quality, cost, and speed against a rubric. ~10% of the queue is a hidden gold-standard check to keep reviewers honest.
- A trust score is computed and published, recomputed live as new reviews land, and every score is fully traceable back to the reviews and reviewer accuracy behind it.
The score is:
$$\text{Trust} = 10 \times (0.6\,Q + 0.2\,C + 0.2\,S)$$
where \(Q\) is the accuracy-weighted mean quality across reviews, \(C = 10\,\min(1,\ \text{median cost} / \text{agent cost})\), and \(S = 10\,\min(1,\ \text{median time} / \text{agent time})\).
How we built it
Everything runs on the Cloudflare stack, on the free plan:
- API: Cloudflare Workers (TypeScript + Hono)
- Database: Cloudflare D1 (SQLite) — also stores raw agent outputs
- Sessions/secrets: Workers KV + encrypted secrets (PBKDF2 auth, API keys encrypted at rest)
- Frontend: React + Vite on Cloudflare Pages, one editorial "Newsprint" design system
- Agents: a multi-provider adapter layer that runs real agents end-to-end — an OpenAI-compatible adapter (OpenAI, DeepSeek, Groq, Gemini), plus Claude, HTTP, and search adapters. Submitting an agent runs it against the field's tasks inline and drops the outputs straight into the blind review queue.
- Extras: live LaTeX rendering (KaTeX) for technical agent outputs, and Fiverr expert sourcing via Tavily search.
Challenges we ran into
- Free-tier constraints: we designed around R2 and Queues (which need paid plans) by storing outputs in D1 and executing runs inline via
ctx.waitUntil. - Blind, honest reviews: keeping reviewers blind to agent identity while still surfacing field-scoped tasks, and catching rubber-stamping with hidden gold checks.
- Real agents, real math: technical outputs came back full of LaTeX (\( \sigma = F/A \)) that rendered as raw text — we had to normalize
\(…\)/\[…\]delimiters to KaTeX while protecting currency like "$400" from being parsed as math. - A subtle qualification bug: new reviewers were silently staying unqualified because signup created the row one way and onboarding never flipped the flag.
Accomplishments that we're proud of
- A working end-to-end loop on real infrastructure: submit an agent → it runs on real tasks → outputs get rated blind → a trust score publishes and updates live.
- Real contestants scored across many fields (DeepSeek, OpenAI, Tavily, Exa) with real human reviews from friends we invited.
- A fully transparent score — every number is traceable to the reviews and reviewer accuracy that produced it.
What we learned
- The hard part of "trust" isn't the model — it's the process integrity: blindness, gold checks, and traceability matter more than the formula.
- Shipping real third-party agents means handling the messy reality of their outputs (LaTeX, JSON, markdown, varying cost/time metadata).
- The whole thing fits comfortably on Cloudflare's free tier with the right architecture.
What's next for RevAI
- Real reviewer payouts (Stripe Connect + Wise/Payoneer) and live Stripe membership billing.
- Second-reviewer consensus and dispute handling for higher-confidence scores.
- Automated re-testing on every agent version change, with score-drift alerts.
- Automated outreach to source and onboard expert reviewers (currently search-only).
- More verticals beyond the current fields.
Built With
- ai
- cloudflare
- cron
- react
- typescript
- vite

Log in or sign up for Devpost to join the conversation.