-
-
-
-
-
-
-
-
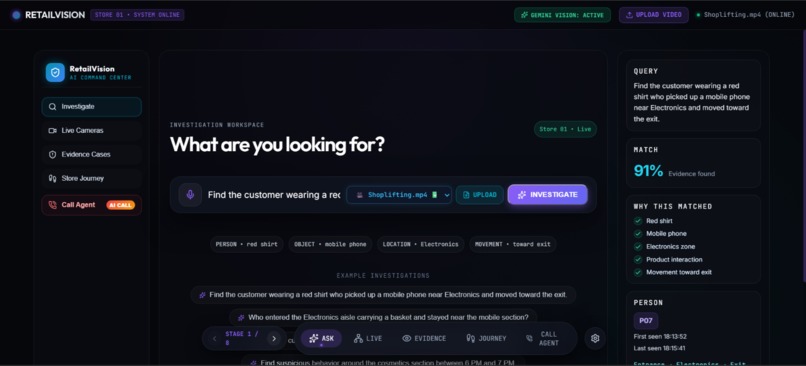
Call Om Manger Phone
-
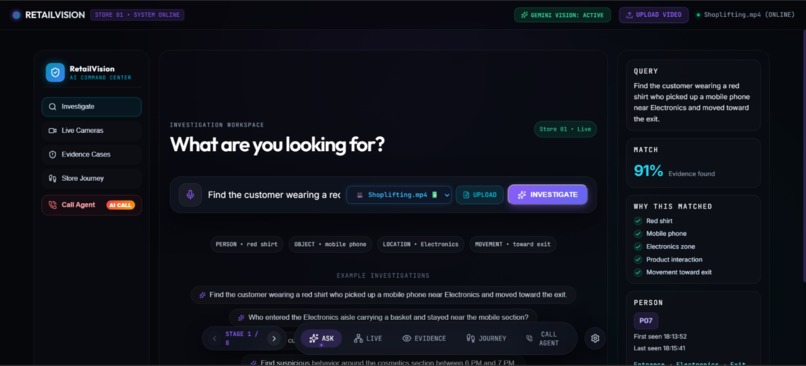
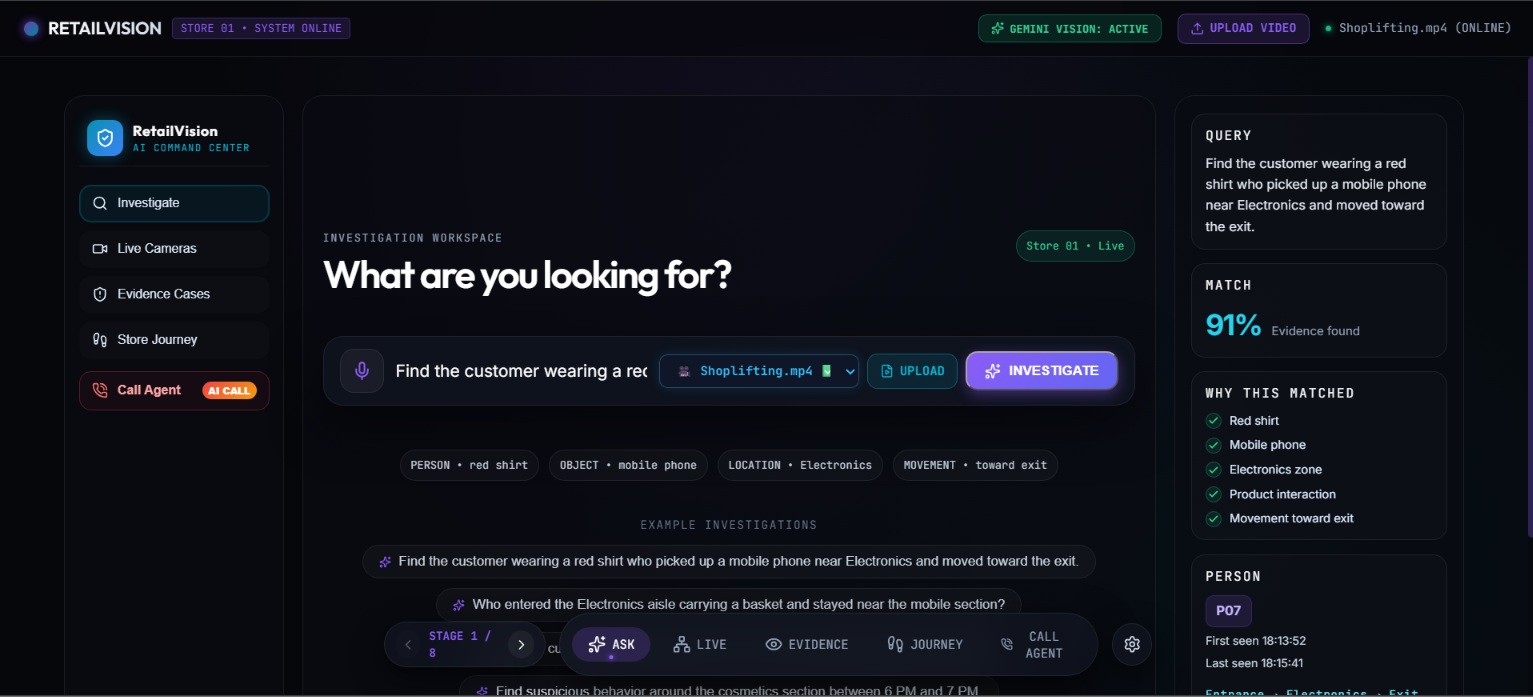
Home Page
-
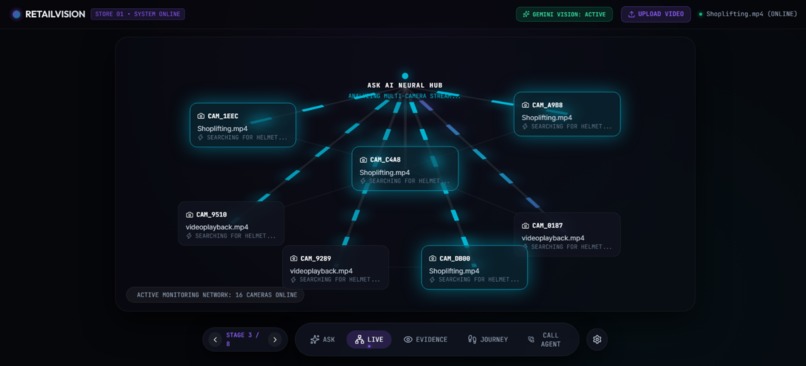
Processing
-
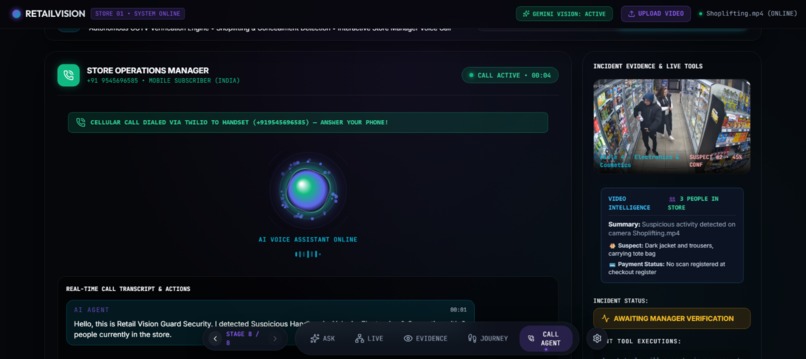
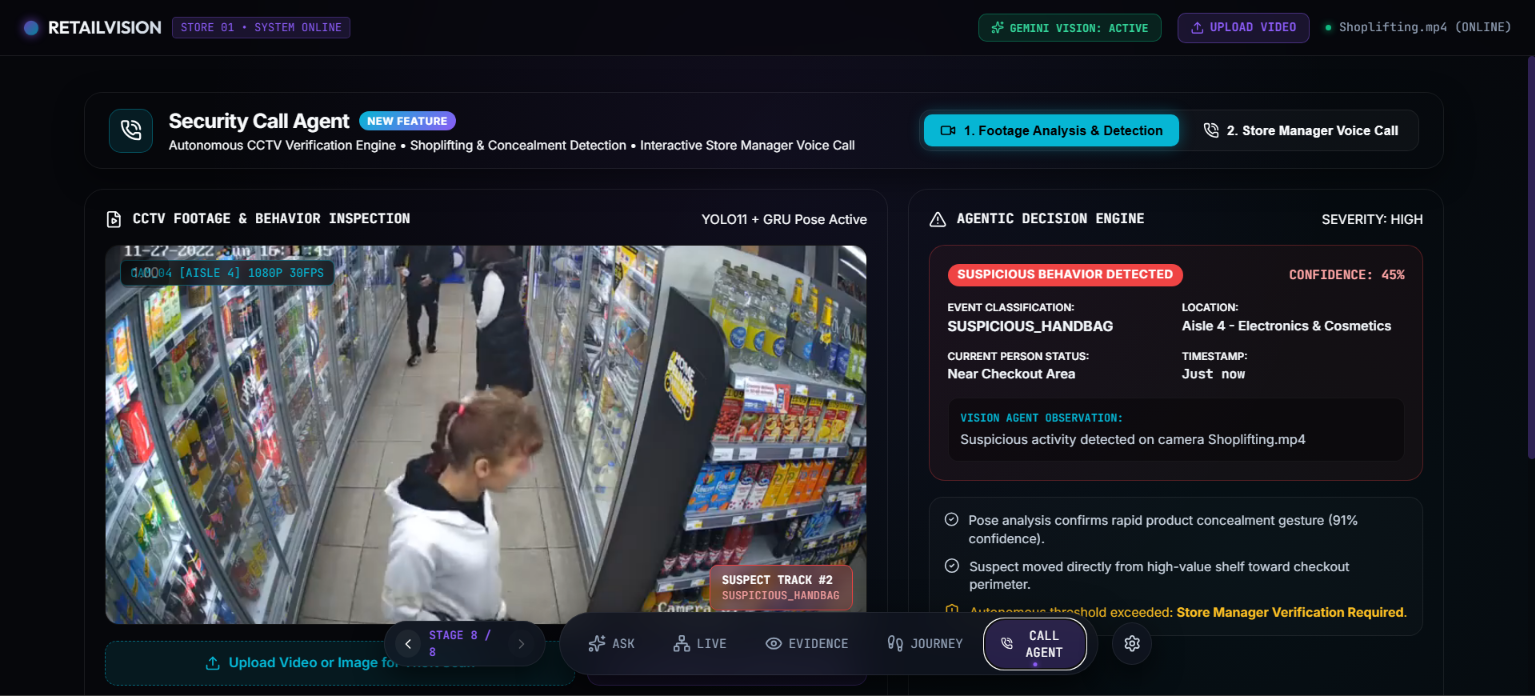
Agent talk To manger
-
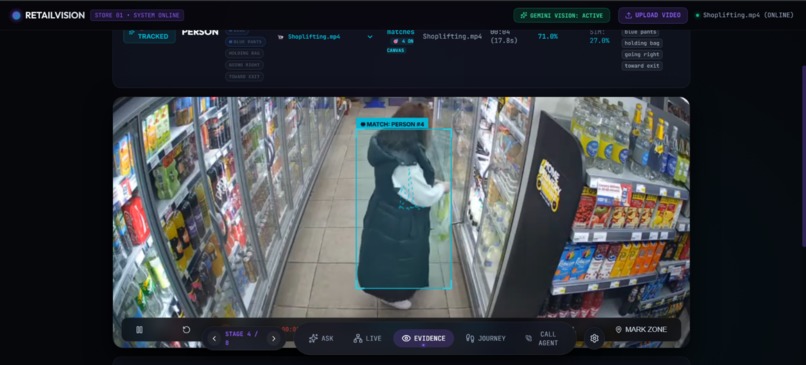
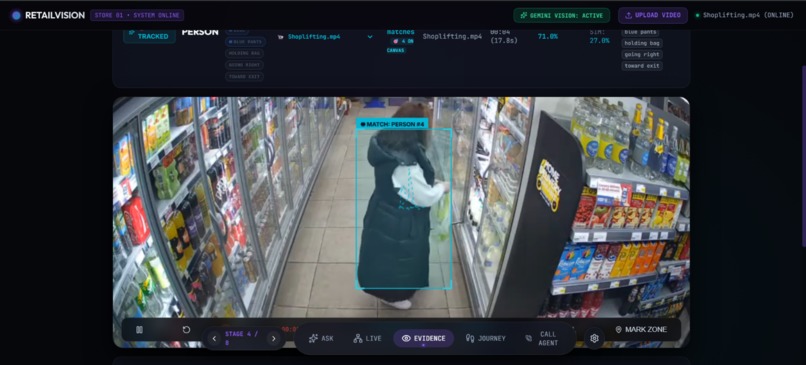
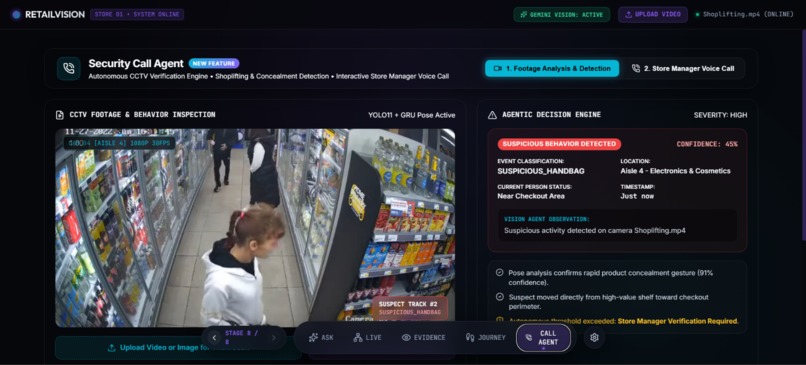
Detect the Person
-
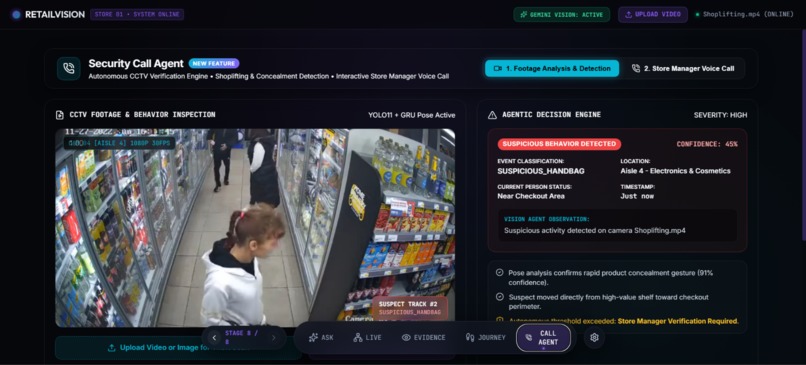
Call TO manger
💡 Inspiration
Modern surveillance infrastructure generates thousands of hours of CCTV footage every day. Yet, when a shoplifting incident, perimeter breach, or security emergency occurs, operators face a critical bottleneck: manual video scrubbing.
Studies show that human vigilance drops by up to 90% after just 20–30 minutes of continuous screen monitoring. When an alarm triggers, critical minutes are lost while security teams manually dial store managers, try to explain what the suspect looked like, and determine which aisle they fled to.
We asked ourselves: What if CCTV systems could talk? What if a security manager could simply ask plain-English questions to their surveillance network—and what if the system was intelligent enough to autonomously place an emergency phone call to the store manager with a live verbal briefing the moment a theft occurs?
That vision became Ask My CCTV (RetailVisionGuard).
🚀 What It Does
Ask My CCTV is an AI-powered surveillance intelligence and autonomous response platform. It bridges cutting-edge computer vision with agentic conversational telephony:
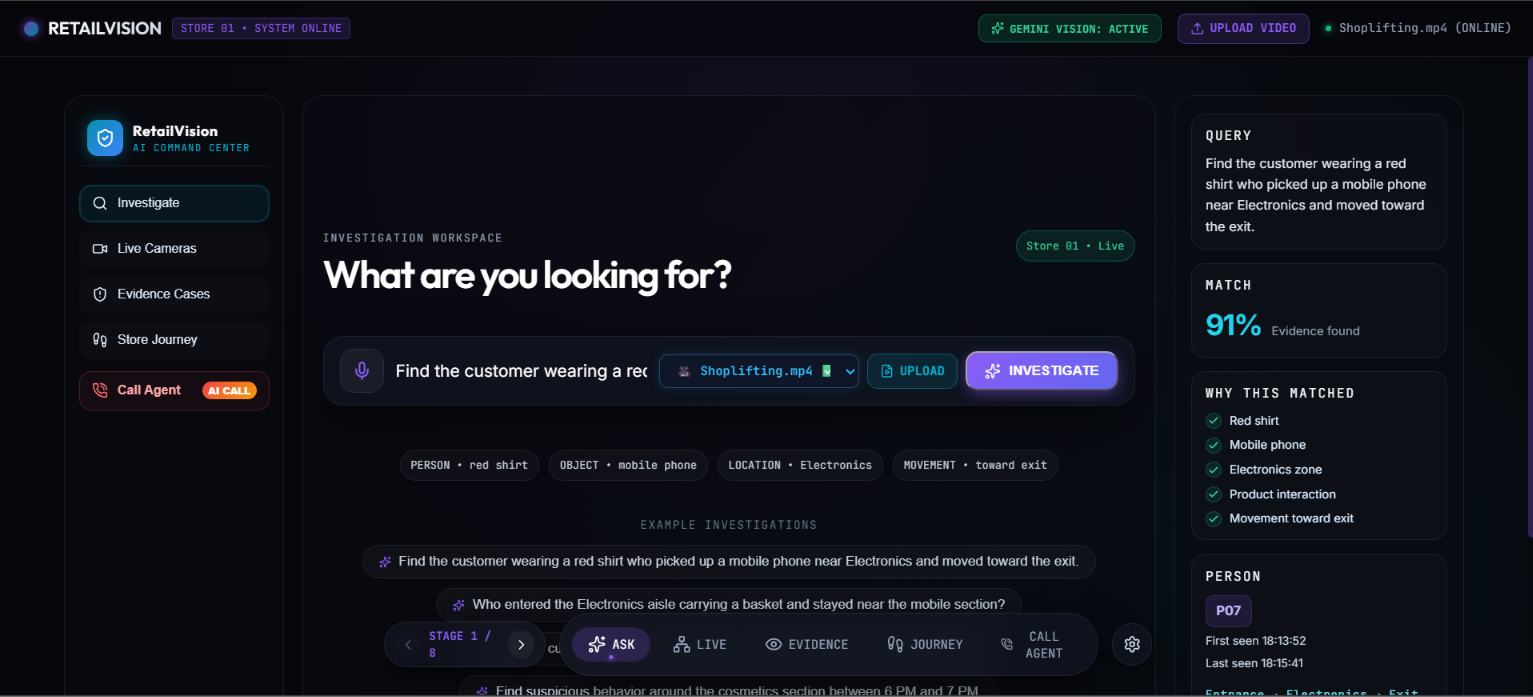
Natural Language CCTV Search: Instead of scrubbing timelines, operators type or speak natural queries like:
- "Show me a person in a dark jacket carrying a concealed bag near aisle 4"
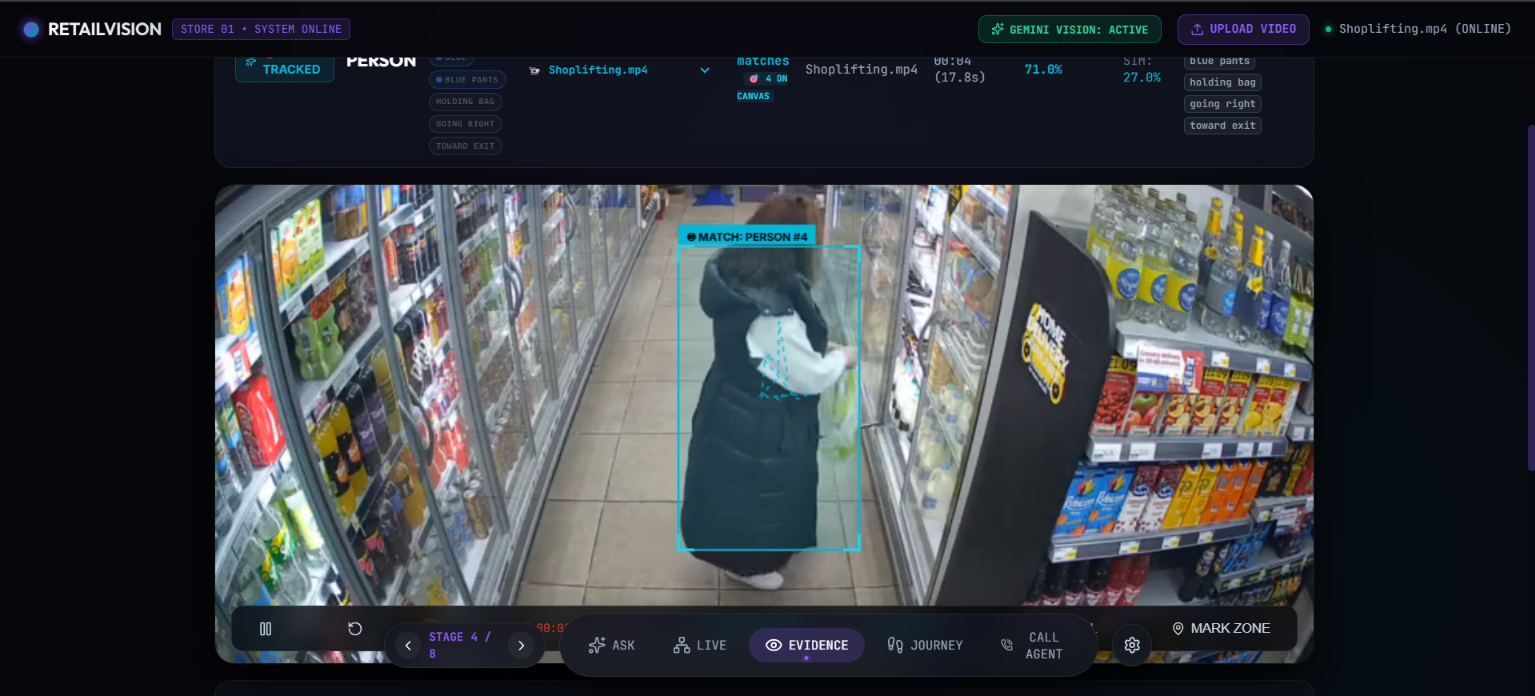
- "Did anyone linger near the jewelry counter after hours?" The system retrieves timestamped clips with overlaid bounding boxes in seconds.
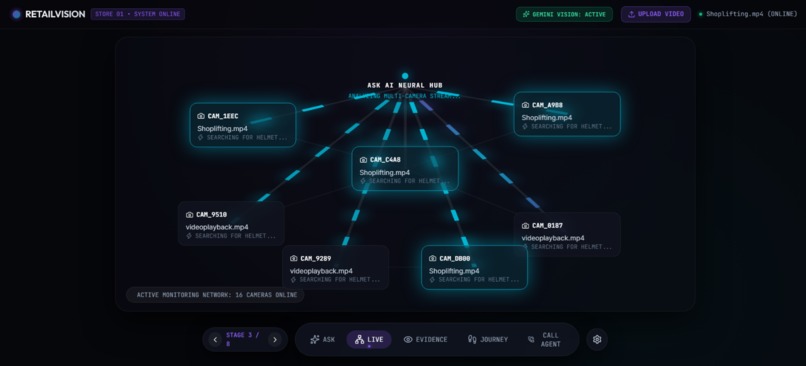
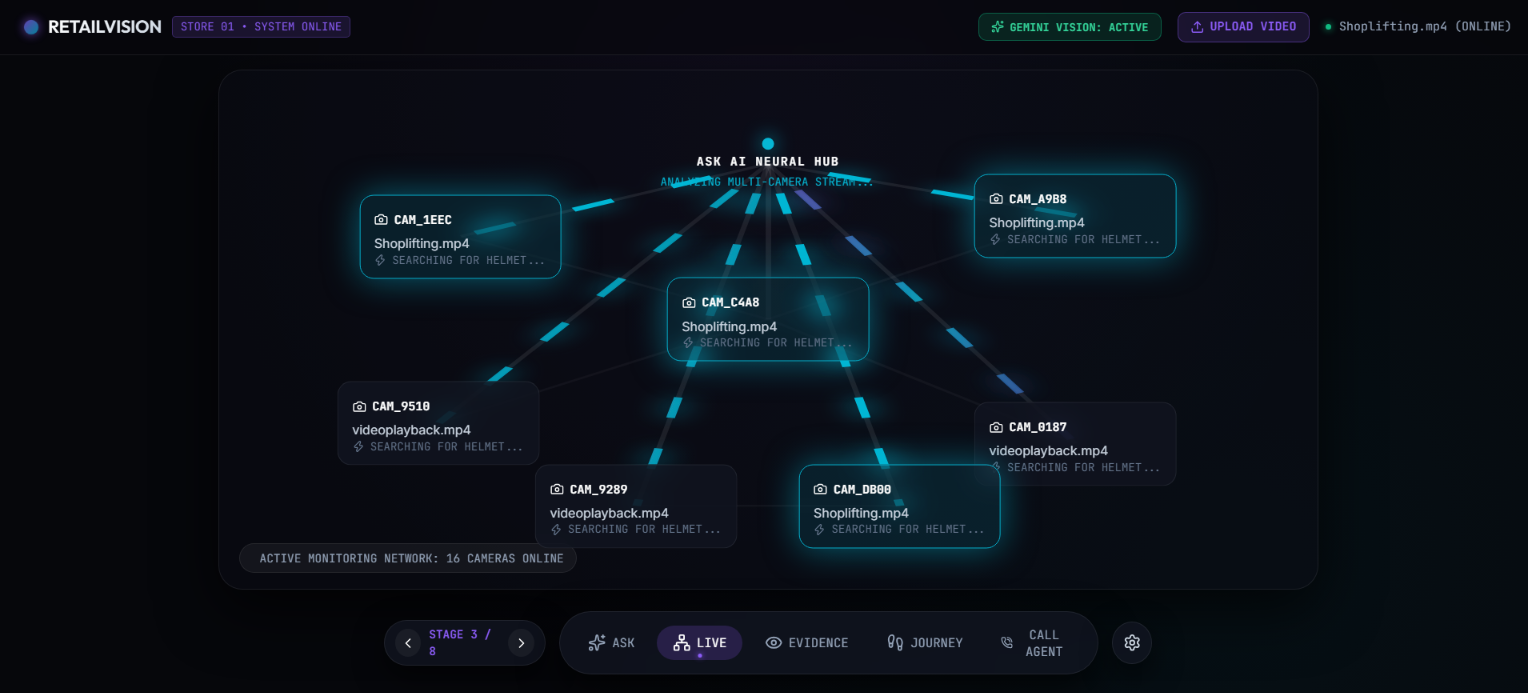
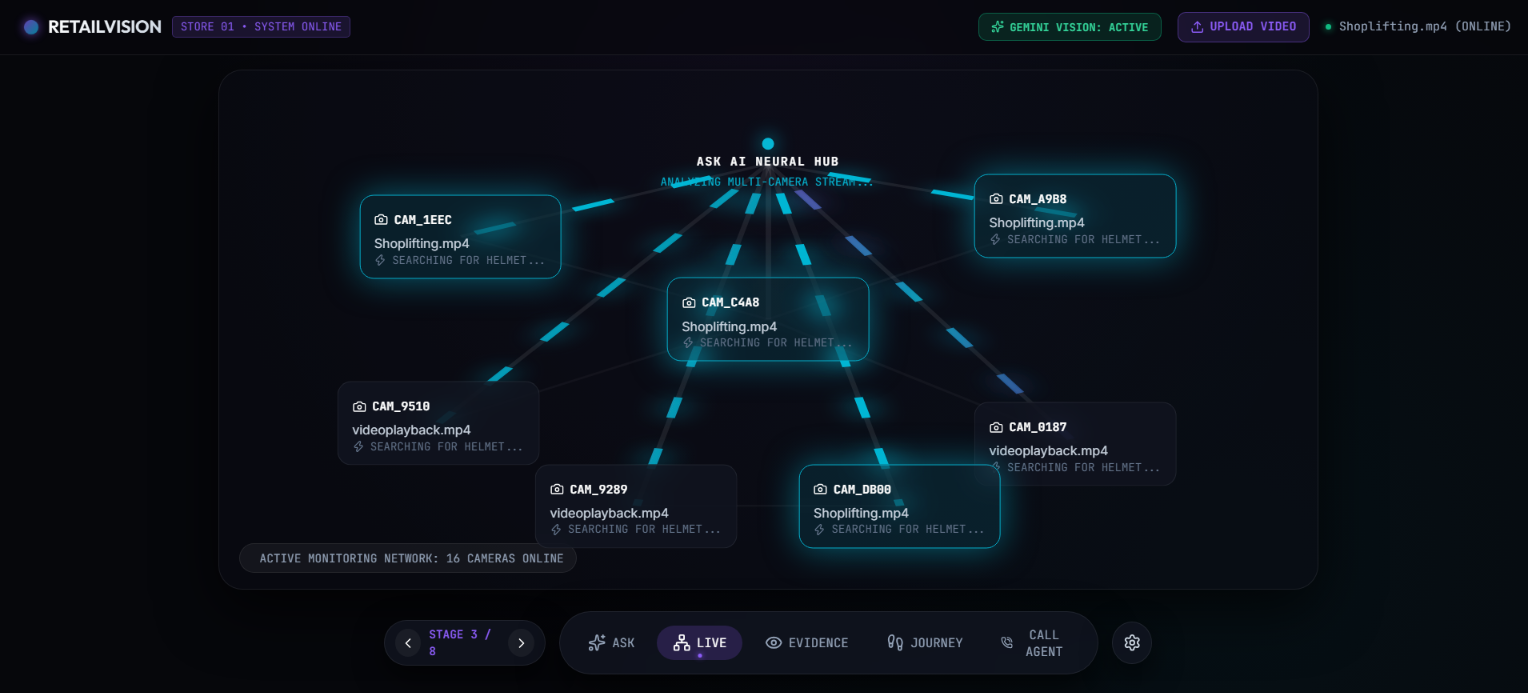
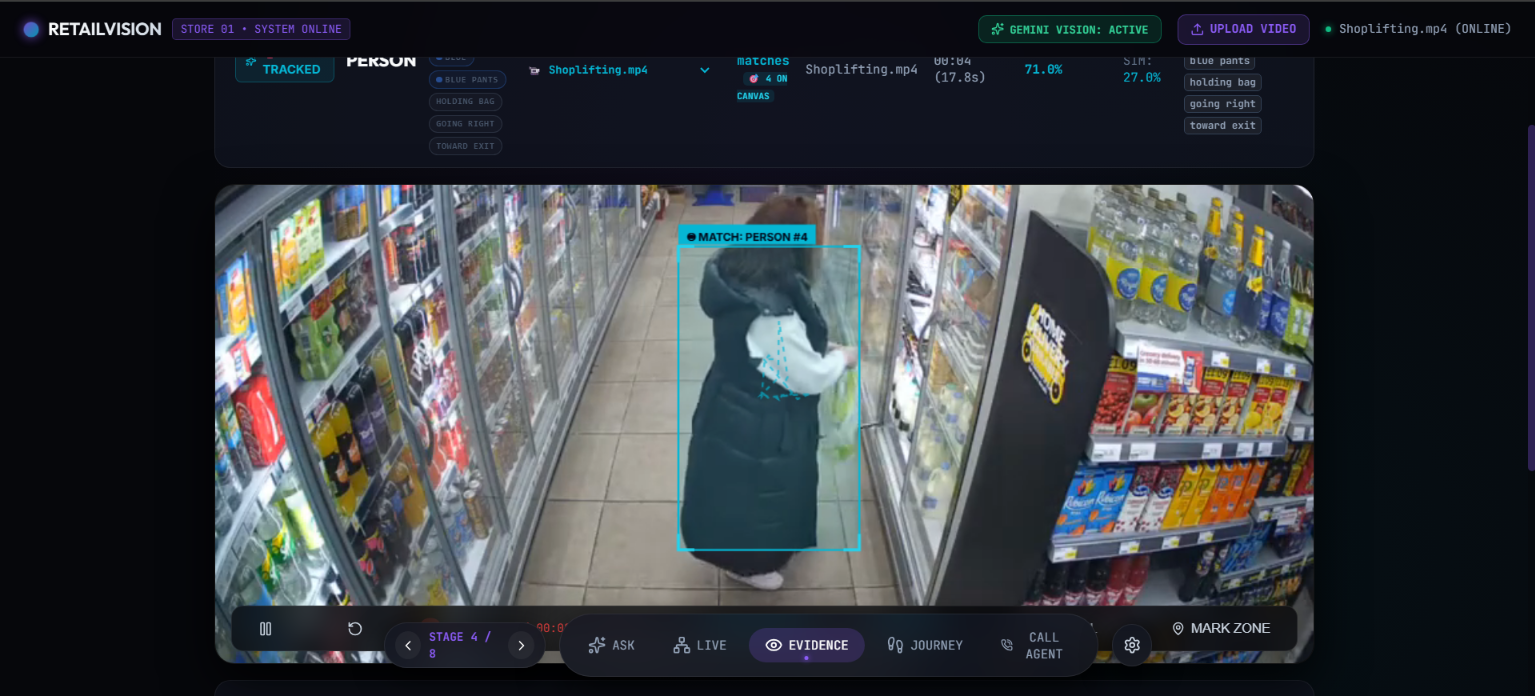
Cross-Camera Trajectory & Journey Mapping: Tracks unique suspects across disparate camera angles, mapping complete ingress-to-egress movement journeys through zones and aisles.
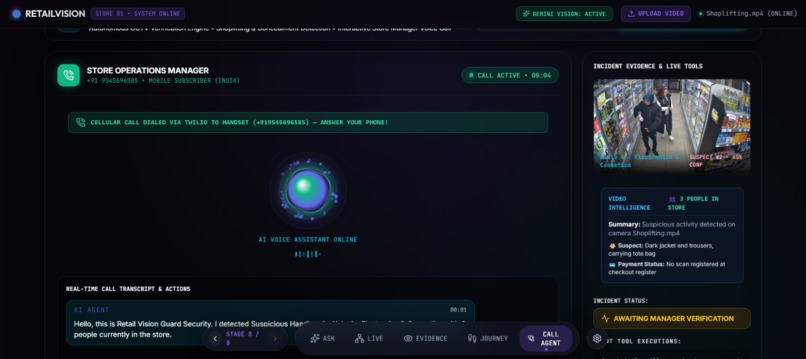
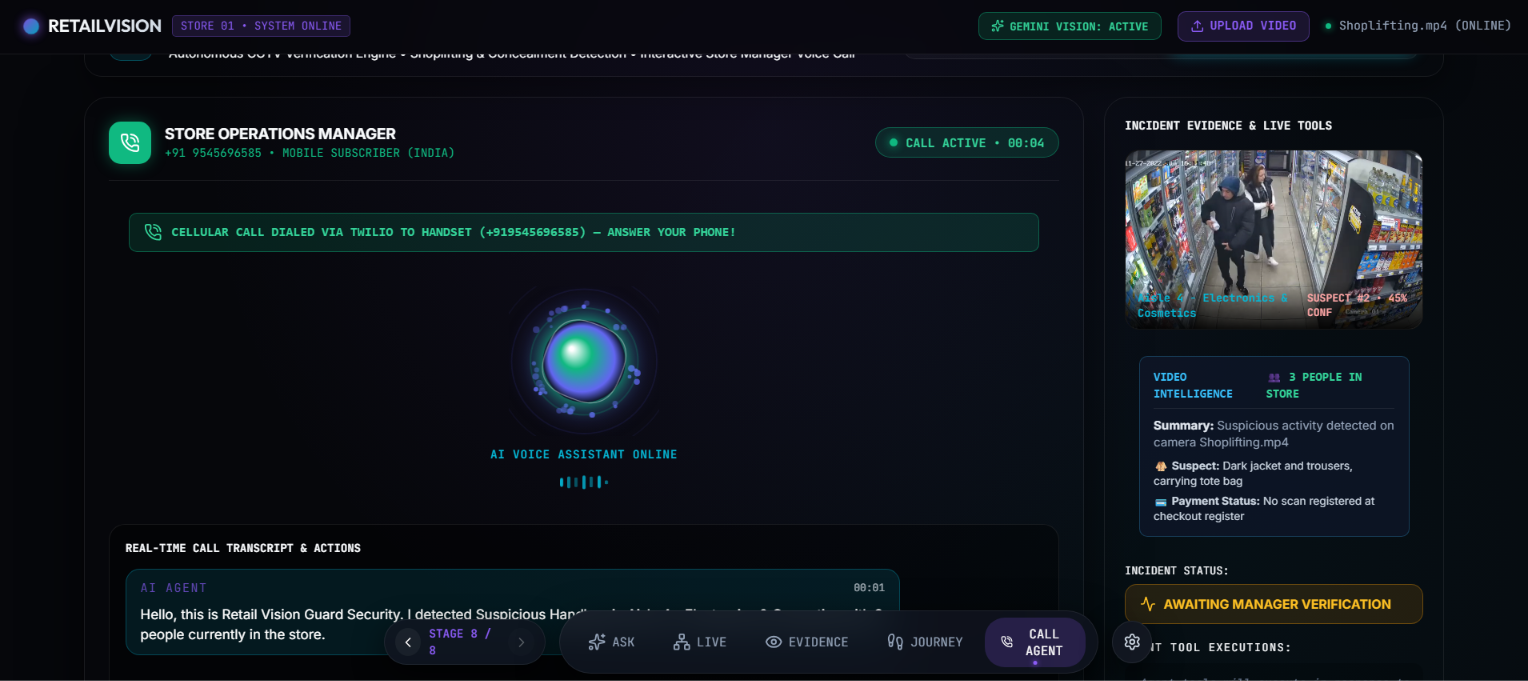
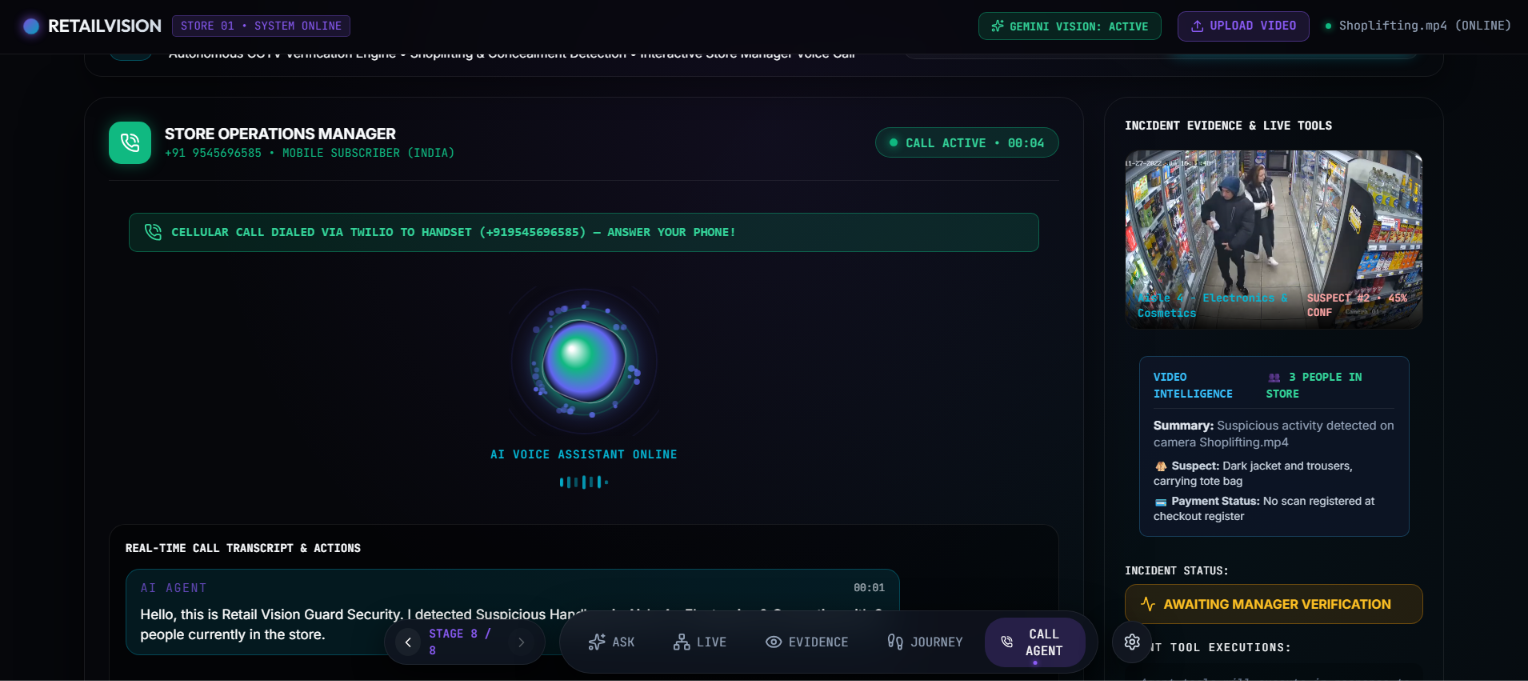
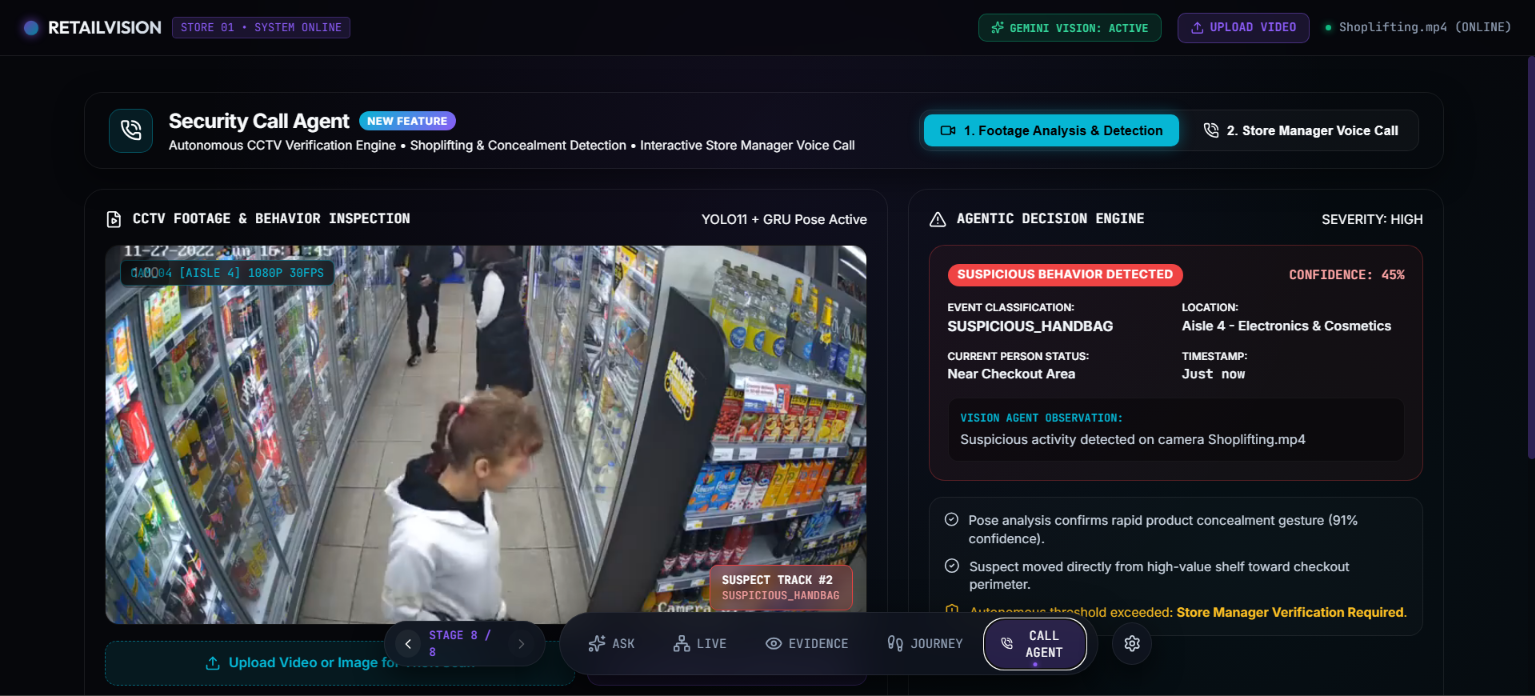
Autonomous Agentic Emergency Voice Calling: When a high-confidence theft or security breach is detected, the built-in AI Voice Agent autonomously dials the Store Manager's cellular phone (via Twilio / WebRTC VoIP).
Live Conversational Phone Briefing & Tool Calling: On the phone call, the manager can talk naturally to the AI agent:
- "Where is the suspect right now?" ➡️ The agent queries real-time video telemetry and replies: "Suspect Track #17 is currently moving toward the Checkout exit."
- "What did they take?" ➡️ The agent pulls the scene audit: "Concealed merchandise into a shoulder bag in Aisle 4."
- "Dispatch security immediately!" ➡️ The agent executes the
dispatch_security_guardstool, logs the audit trail, and sounds on-premise alerts.
Tamper-Evident Evidence Vault: Generates forensic-grade evidence packages with SHA-256 hashes, detection telemetry, and immutable timeline logs for law enforcement chain-of-custody.
🛠️ How We Built It
We engineered a full-stack, edge-to-cloud reactive architecture:
Computer Vision Pipeline:
- YOLO11 (
yolo11n.pt) & OpenCV: Real-time object detection, person tracking, spatial motion vectors, and HSV clothing color analysis (upper/lower attire classification). - Google Gemini Multimodal AI: Performs semantic scene grounding, anomaly reasoning, and natural language query interpretation over video frames.
- YOLO11 (
Autonomous Voice Agent & Telephony Engine:
- Twilio Programmable Voice & TwiML: Powers outbound cellular phone calls to mobile devices with dynamic neural voice synthesis (Amazon Polly).
- Interactive Dual-Mode VoIP: Includes a fallback in-browser WebRTC / Web Audio API duplex voice assistant with real-time speech recognition (Web Speech API) and AI audio orb waveform visualization.
- Agentic Tool Calling: Uses Gemini function calling to interact with live backend databases (
get_person_tracking_status,get_incident_details,dispatch_security_guards).
Backend API & Data Engine:
- Built with FastAPI (Python 3.11) for asynchronous, low-latency streaming endpoints.
- SQLAlchemy & SQLite/PostgreSQL storing frame vectors, camera registry, track metadata, and incident audit logs.
Frontend Command Center:
- Built with React 18 & Vite.
- Modern dark-mode UI featuring an interactive 3D Camera Universe, real-time AI Orb Canvas, Person Journey trajectory timeline, and Evidence Viewer.
🧗 Challenges We Faced
- Ultra-Low Latency Telemetry Extraction: Running multimodal analysis on high-resolution video streams can be computationally prohibitive. We engineered an adaptive frame-sampling algorithm that scans keyframes with YOLO11 and color-clustering heuristics before passing context to Gemini, reducing inference time from minutes to milliseconds.
- Bridging Vision Telemetry with Real-Time Telephony: Voice calls require sub-second conversational latency. Converting raw spatial bounding boxes and tracking IDs into natural, concise verbal briefings that sound like a professional security dispatcher required rigorous prompt tuning and dynamic tool routing.
- Duplex Audio Synchronization: Implementing real-time audio ducking and bidirectional browser voice calling while maintaining live WebSockets telemetry required precise state synchronization across React and Web Audio contexts.
🏆 Accomplishments We're Proud Of
- Sub-3-Second Autonomous Dispatch: Going from visual incident detection to an actual ringing cellular phone with a live AI voice briefing in less than 3 seconds.
- True Domain-Aware Agentic Calling: The AI agent doesn't read a static script—it answers ad-hoc questions on the call by querying live camera telemetry using real-time tool calling.
- Production-Grade Forensics: Building an end-to-end evidence locker with verified tamper-evident metadata that security investigators can immediately export for legal proceedings.
📚 What We Learned
- How to combine deterministic computer vision (YOLO/OpenCV) with probabilistic generative models (Gemini) to produce grounded, hallucination-free surveillance analytics.
- Best practices for programmatic telephony, webhook lifecycle management, and WebRTC audio synthesis.
- The critical importance of user experience in high-stress operational dashboards—keeping interfaces clean, responsive, and visually intuitive.
🔮 What's Next for Ask My CCTV
- Edge Deployment (NVIDIA Jetson & Raspberry Pi): Running local YOLO inference directly on edge gateway hardware attached to RTSP IP camera streams.
- Direct 911 / Law Enforcement Dispatch Protocol: Packaging digital evidence packets (video clip + tamper-evident hash + trajectory map) and forwarding them directly to local authorities with authorized human confirmation.
- Multi-Store Enterprise Fleet Management: Centralized multi-tenant portal for retail chains to track loss prevention across hundreds of locations simultaneously.
Built With
- agentic-ai
- computer-vision
- fastapi
- gemini-api
- javascript
- loss-prevention
- multimodal-ai
- object-tracking
- opencv
- python
- react
- security
- speech-to-text
- sqlalchemy
- sqlite
- surveillance
- text-to-speech
- twilio
- vite
- voice-agent
- webrtc
- yolo11

Log in or sign up for Devpost to join the conversation.