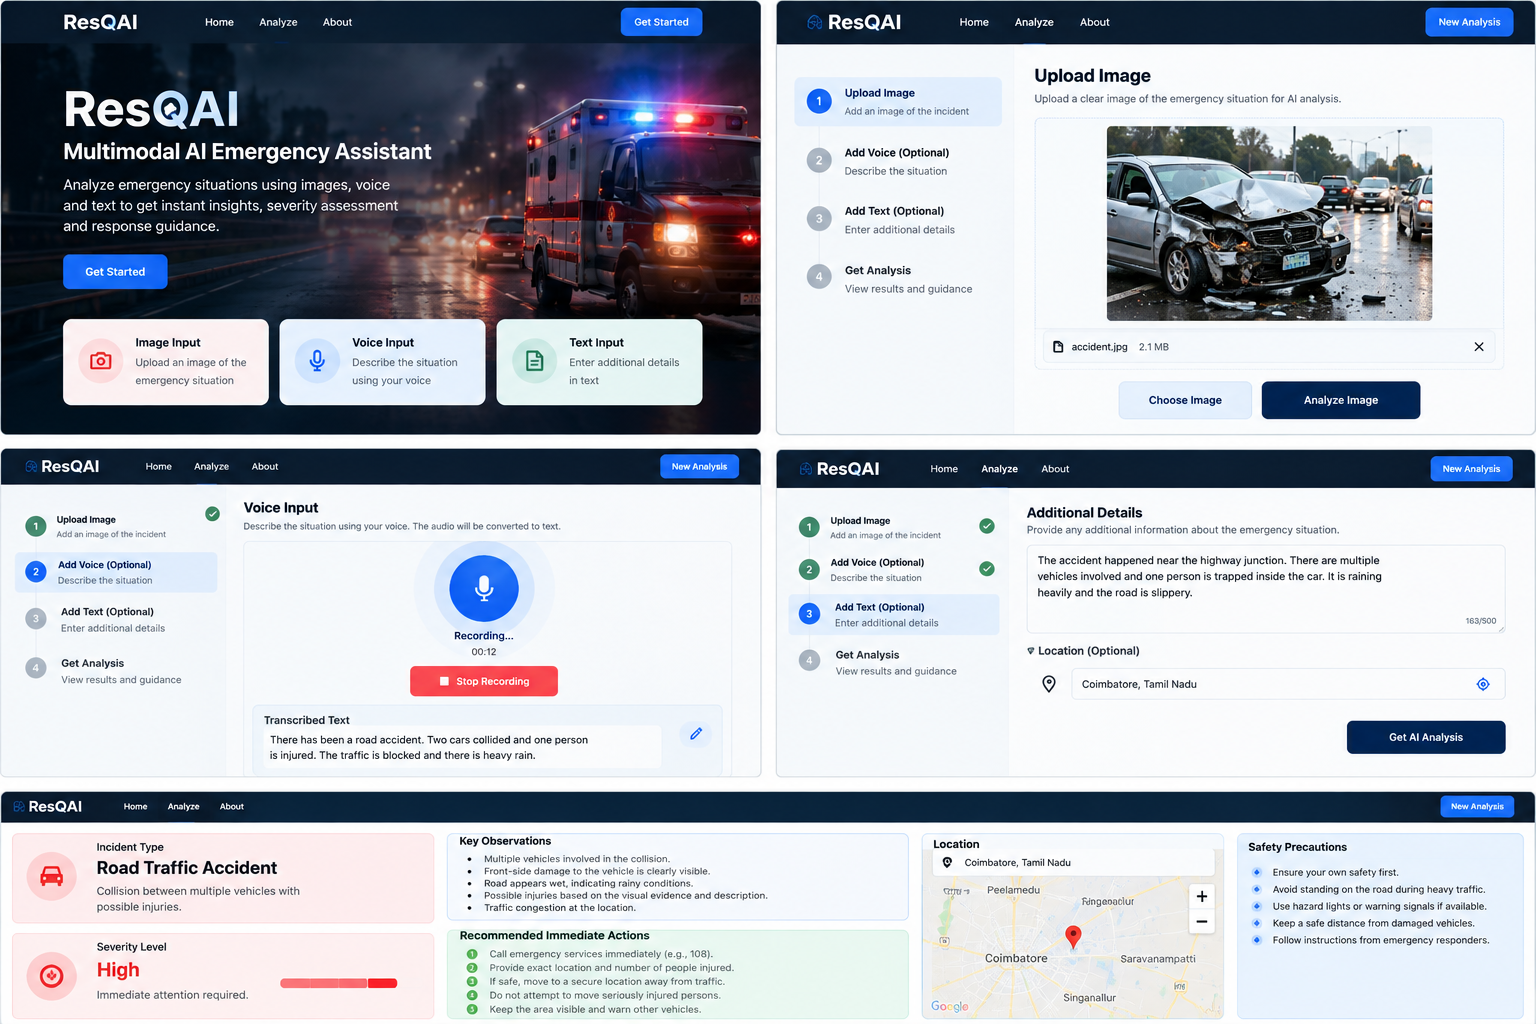
ResQAI — Multimodal AI Emergency Assistant
Inspiration
During an emergency, people often struggle to communicate what is happening clearly and quickly. A person may have a photo of an incident, a voice description, or a short text message, but these different pieces of information are usually treated separately.
We wanted to build a system that could understand different types of information together and turn them into useful emergency guidance.
This inspired us to create ResQAI, a multimodal AI emergency assistant that can understand images, text, and voice-based descriptions to identify potential incidents, assess their severity, and provide appropriate response guidance.
What It Does
ResQAI allows a user to provide information about an emergency through multiple modalities:
- Image — Upload an image of an accident, fire, damaged infrastructure, or other emergency situation.
- Voice — Describe the situation naturally using speech.
- Text — Enter additional details about what happened.
- AI Analysis — The system combines the available information to understand the situation.
- Severity Assessment — The incident is categorized based on its potential urgency.
- Response Guidance — The user receives clear, actionable recommendations about what to do next.
The goal is not to replace emergency professionals, but to provide fast initial guidance and structured information when every second matters.
How We Built It
We designed ResQAI as a multimodal pipeline.
First, the user's input is collected through the web interface. Depending on the input type, the system processes the image, converts voice into text, or directly analyzes the user's written description.
The processed information is then passed to the AI reasoning layer. The system combines the available inputs instead of treating each input independently.
For example, an uploaded image may show a vehicle accident, while the user's voice description explains that someone is injured.
By combining these inputs, ResQAI can produce a more meaningful assessment than analyzing the image alone.
The final result is presented through a simple interface containing:
- Incident type
- Severity level
- Key observations
- Recommended immediate actions
- Safety precautions
Multimodal AI
The key feature of ResQAI is its ability to work with multiple forms of information.
Instead of asking users to describe an emergency in one specific format, ResQAI allows them to communicate naturally.
Image + Voice + Text → AI Reasoning → Emergency Insight
This makes the system more flexible in situations where typing a detailed description may be difficult.
What We Learned
Building ResQAI taught us several important lessons:
- Multimodal AI is more powerful when different inputs provide complementary information.
- User experience is extremely important for emergency-oriented applications.
- AI outputs need to be presented clearly rather than overwhelming users with technical information.
- Input preprocessing and validation are critical for reliable AI results.
- AI systems used in safety-related scenarios should provide guidance carefully and
Built With
- artificial
- intelligence
- machine
- python
