-
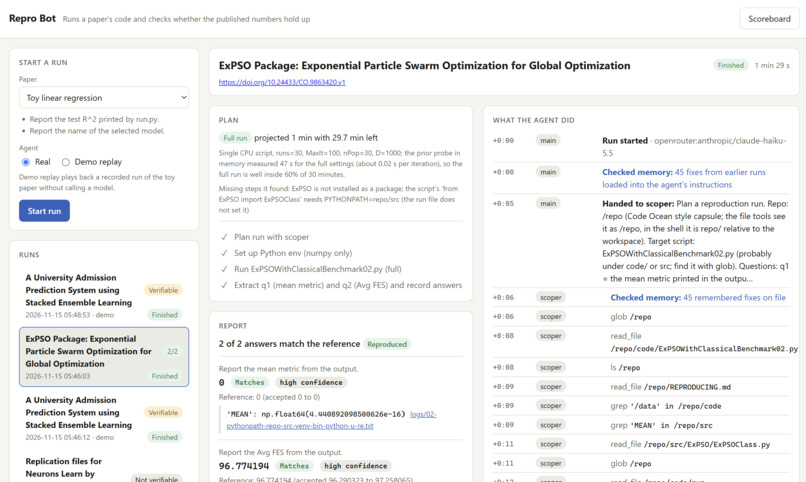
ReproBot frontend
-
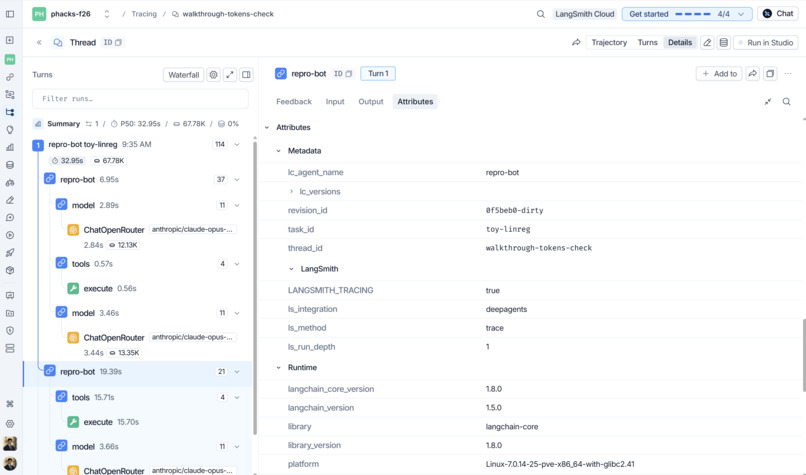
Lang Smith agent workflow
Inspiration
We're focused in data science and computer science. We know what it's like to, A. read through poorly prepared or reviewed LLM outputs, and B. spend time working on monotonous code fixes. We built an agentic system to tackle this on peer reviews. Building on a research paper often starts with days of just getting someone else's code to run.
What it does
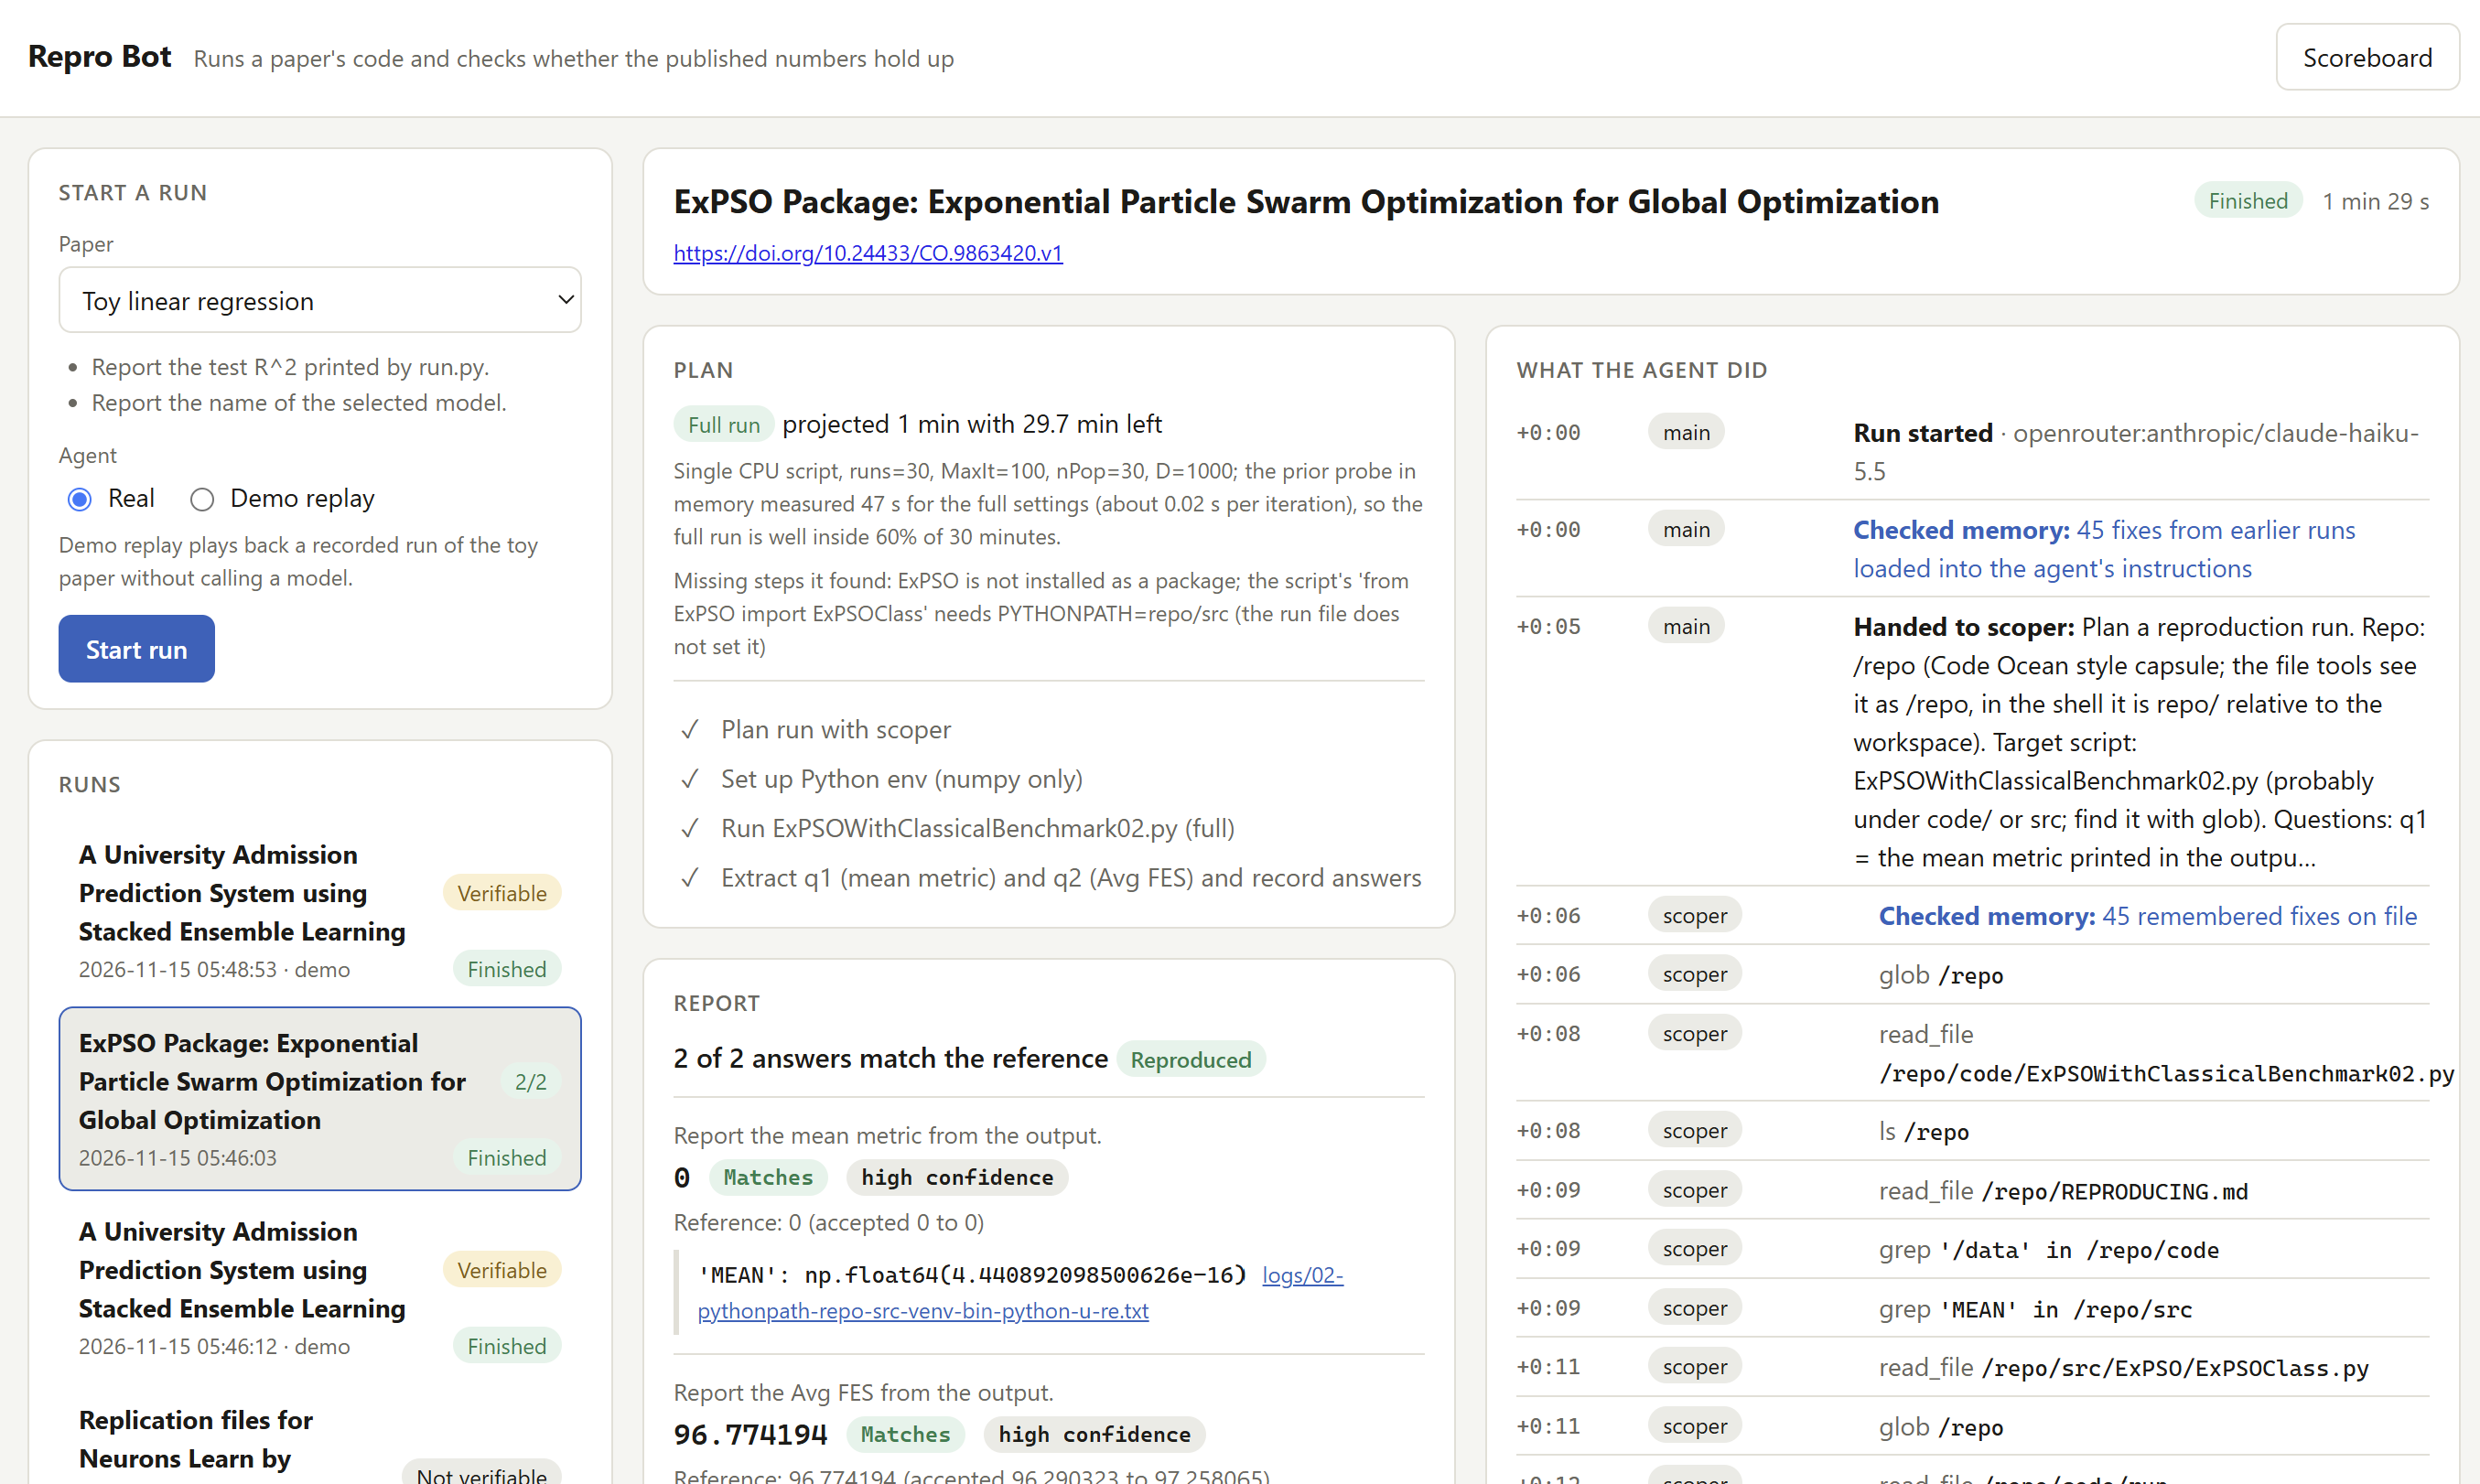
ReproBot runs a paper's code in a sandbox and tells you in minutes whether the published numbers come out, quoting the output line behind every answer.
How we built it
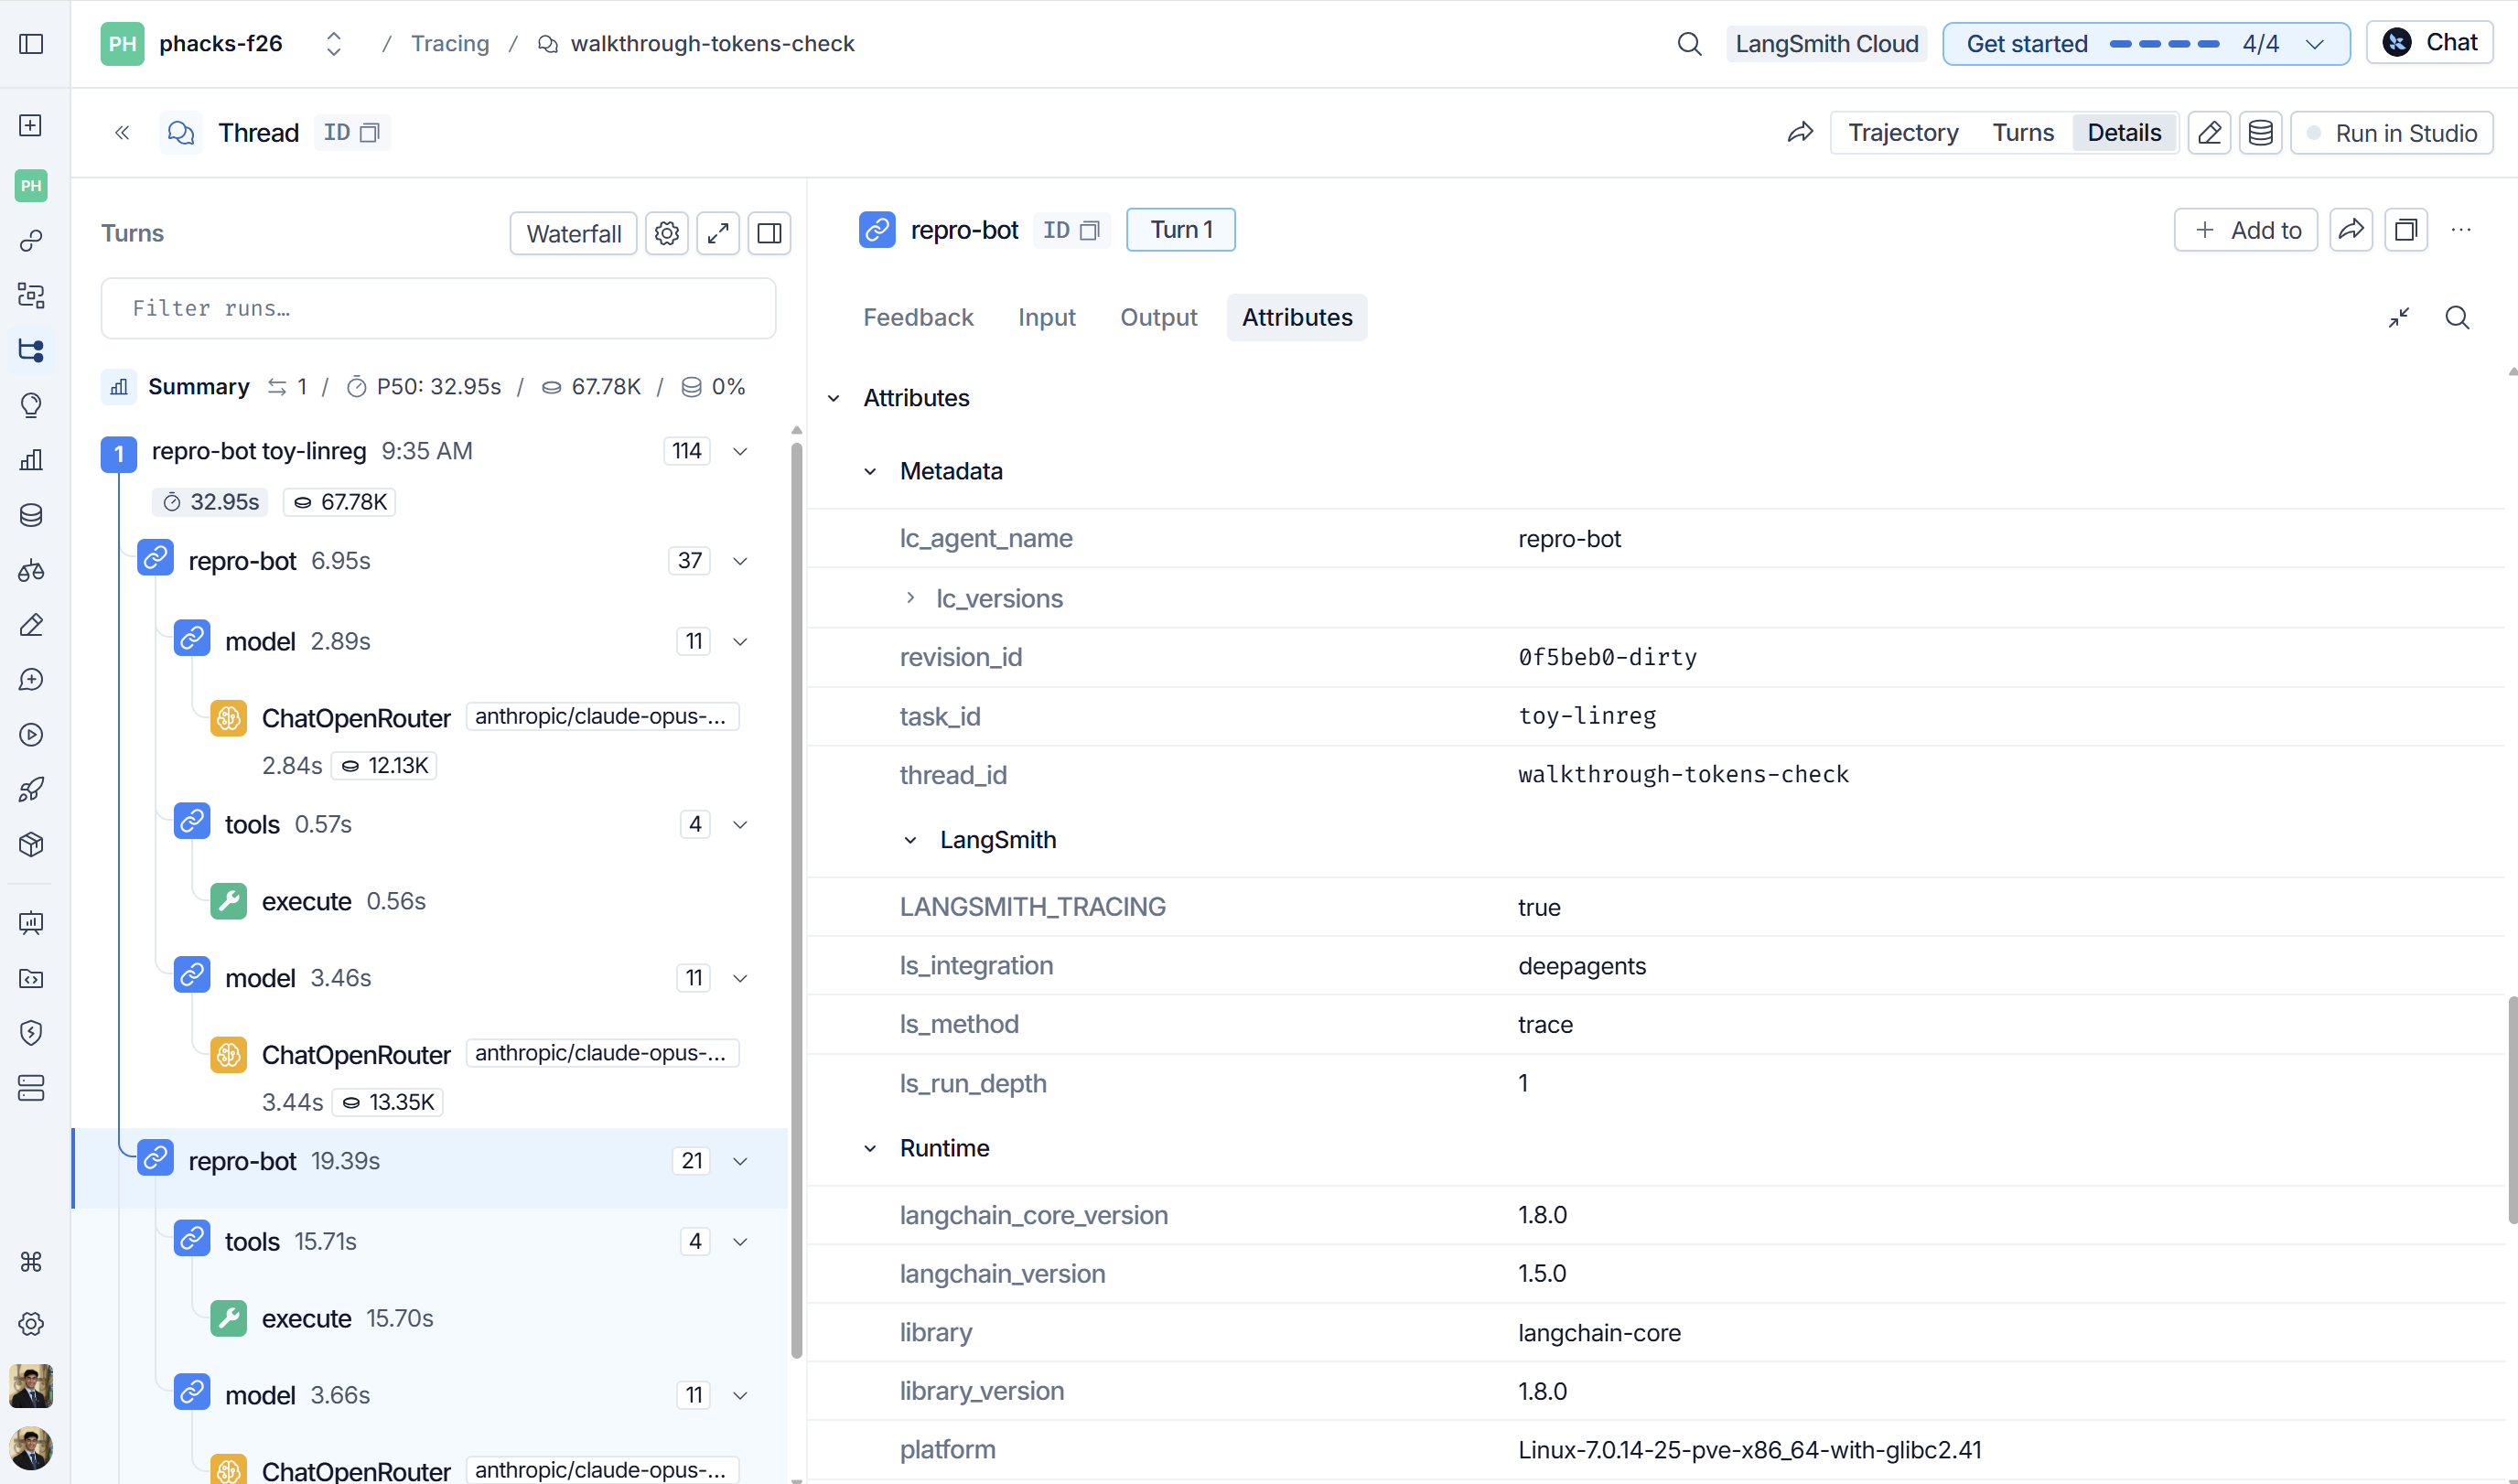
We built a LangChain deep agent with a planning subagent, a Podman sandbox, human approvals and memory, plus a harness that scores its runs on CORE-Bench papers.
Challenges we ran into
Old code is hard to install, and some papers need a GPU or hours of computing, so we taught the agent to plan first and say honestly when a paper won't fit.
Accomplishments that we're proud of
ReproBot reproduced 17 real CORE-Bench papers for under 10 cents each and never reported a wrong number as a result.
What we learned
Agents follow structure better than instructions: our subagents went unused until the code required a plan before any experiment.
What's next for ReproBot
Harder papers without setup instructions, longer runs with GPUs, and checking a paper's cited sources too.
Built With
- langchain
- langgraph
- langsmith
- podman
- python
