-
-
Remembrance Landing Page
Inspiration
Every general purpose assistant available today has the same failure mode. Ask it something it does not know and it produces an answer anyway, in the same confident tone it uses when it is right. Most people can catch that. Someone living with dementia usually cannot, and worse, a confident false answer does not just get ignored. It gets stored. Carers have a name for this. Reinforcing confabulation, where a well meaning aid ends up teaching a person things that never happened.
That is the reason most families will not put a chatbot anywhere near someone with memory loss, and it is a design problem rather than a model quality problem. You do not fix it by making the model bigger. A larger model is a more persuasive liar. You fix it by taking the pen out of the model's hand.
So the whole project comes down to one rule. The language models are never allowed to write a memory. They only get a vote on whether something a human already wrote is supported by the record. If the vote does not come back clean, the device says "I don't have a record of that, worth asking" and stops talking.
We designed it for AR glasses, because that is the right form factor. Hands are busy, there is no keyboard, and the thing you need help with is the person standing in front of you right now. We could not afford a headset, so we built it against a webcam with exactly the same constraints a headset would impose. Nothing in the interaction assumes a mouse or a keyboard.
What it does
You look at someone. A reticle finds their face and the overlay tells you who they are, along with how confident the match is and what is on file about them.
If they are not on file, it says "not on file" rather than picking the closest name. You tap Listen and say "this is Priya, my daughter." The device speaks back, "should I remember this face as Priya, your daughter?" You say yes. It files a cropped portrait and confirms out loud.
From then on, saying "remember that she brought the umbrella back" attaches that moment to her, with a photograph of the room, after you confirm it. Saying "who is this" reads the card back. Asking "did Priya visit on Friday" sends the question through the gate, and if Friday is not in the record, you get a refusal instead of a story.
There is an Unguarded button next to it that runs the same question through a single ungated model. It cheerfully invents a Friday visit, in detail. Putting those two answers side by side is the entire argument for the project, and it is why the button exists.
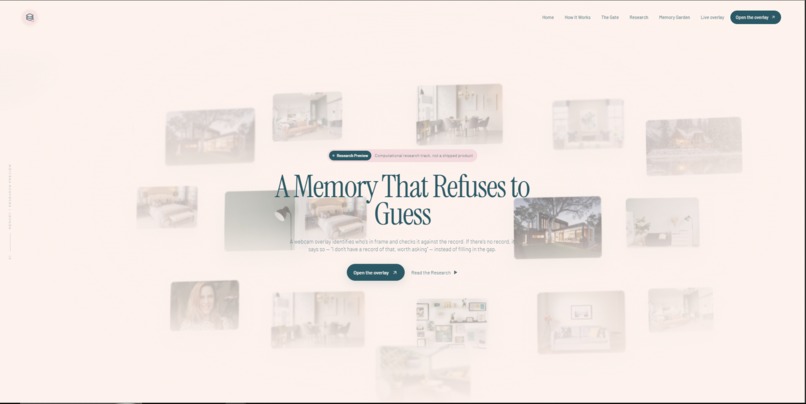
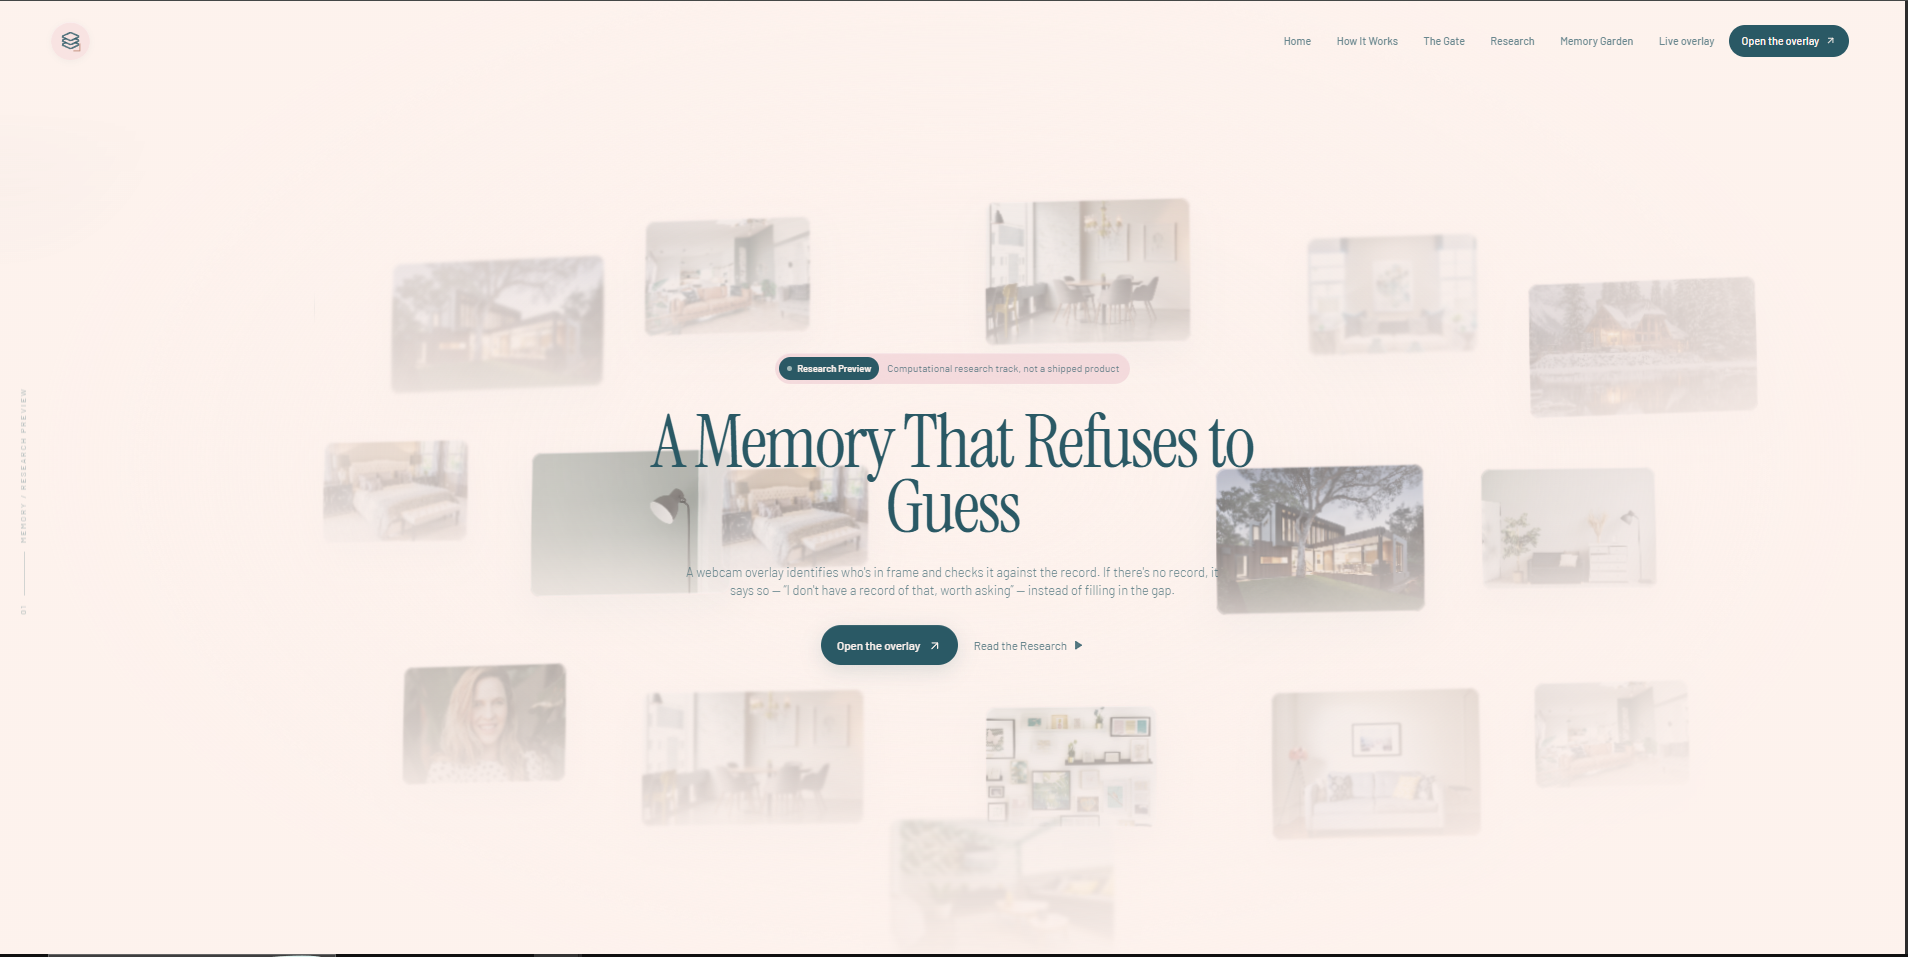
The Memory Garden is the record itself, rendered as a rotating sphere of photographs. Every tile is a real still captured at the moment it was filed, with the name or the caption printed onto it, so it reads at a glance rather than only when focused.
How we built it
The backend is Spring Boot on Java 21, leaning on virtual threads throughout. OpenCV Haar finds a face box on every frame at about twelve frames per second, and a DJL FaceNet model computes a 512 dimensional embedding every 450 milliseconds on a virtual thread, so tracking never blocks on inference. Embeddings go into an in process HNSW index and are matched by cosine distance across three bands: named, maybe, and not on file.
Tracking runs client side and is deliberately decoupled from detection. Detections arrive around eleven times a second and a display refreshes at sixty or more, so binding the overlay directly to the socket is what makes trackers look unfinished. Instead a small predictor keeps a constant velocity estimate, dead reckons up to 220 milliseconds ahead of the last real detection, and eases the drawn box toward it with a frame rate independent filter, smoothing position faster than scale because Haar is much noisier on scale. The reticle goes dashed while it is predicting rather than tracking, so nothing is hidden from the user.
Voice has two layers. A local grammar handles the commands that must never depend on a network round trip, and every command requires an explicit intent verb. Anything the grammar cannot place goes to Featherless, where a set of instruct models pull a name and a situation out of loose speech and snap the name onto a roster spelling with a fuzzy match. Either way the output is a proposal, never a write. Replies are spoken, and the narrator publishes a deaf window over its own speech so the microphone cannot hear the device and act on it.
The gate is called Quorum. A claim and the evidence block fan out across a panel of different model families. Votes are weighted by lineage, so a family with n members counts for the square root of n rather than n, because five fine tunes of the same base model are not five independent witnesses. Agreement is measured over the rationales rather than the labels, by embedding each rationale and union finding them into clusters, since two models saying "the record does not mention Friday" and "no Friday visit in the notes" are one position and label counting treats them as two. If entropy crosses one bit, a reserve of larger models is asked and the tally is recomputed. No key, no panel, or everybody abstaining all produce the refusal.
Challenges we ran into
The hardest bug was one we caused ourselves. Recognised identity was sticky, which stopped the overlay flickering, but it was sticky forever. Once a face was named, the name stayed on the box, so the next stranger to walk into frame inherited it. For a system whose only promise is that it will not guess, that was the most damaging line of code in the repository. The fix was a grace window rather than a latch: a name survives three consecutive empty embeddings, which covers a blink or a turned head, and is then dropped.
Voice was harder than the vision work. An early version accepted any short phrase as a name, so ordinary conversation in the room kept proposing new people to enrol. Speech recognisers also emit finals mid sentence, so "this is, Michael, my son" arrived as three separate results and the first one enrolled somebody called "This." Phrases are now buffered and flushed after a pause, every alternative transcript gets a turn through the grammar before the server is asked, and nothing is written without a yes.
We also had to make the device stop hearing itself. Once it started speaking confirmations out loud, the microphone picked those up and fed them straight back in as commands.
Accomplishments we are proud of
The refusal actually works, and it is measurable rather than asserted. There is a calibration endpoint that scores the gate against labelled claims and reports unguarded, naive, and lineage weighted accuracy side by side, along with mean cluster entropy on correct answers versus errors. Those numbers render live in the Why did you say that panel, so a judge can see the gate's own scorecard rather than take our word for it.
We are also proud that forgetting genuinely forgets. Removing a person deletes their episodes, their stills, and their descriptor from the vector index, so a face the record no longer knows stops matching. A memory aid that can only ever add is not safe to live with.
What we learned
Refusal is a feature you have to engineer, not a prompt you can write. Every layer has to be able to say no independently: the matcher through its bands, the identity tracker through its grace window, the voice layer through explicit confirmation, and the panel through fail closed behaviour. Any one of them silently guessing undoes all the others.
We also learned how much of "does this feel finished" lives in timing rather than features. The tracker and the recogniser did not gain a single capability during the last pass. They gained prediction, smoothing, hysteresis, buffering, and audible feedback, and that is the entire difference between a demo and something you would hand to a family.
What's next
Move to an on device recogniser and a stronger detector, both of which the current architecture already has a seam for. Run the calibration set properly, at a size where the numbers mean something. Then put it on real glasses, where it was always meant to live.
Built With
- djl
- featherless
- java
- javacv
- javascript
- opencv
- pytorch
- react
- vite
- web-speech-api
- websockets


Log in or sign up for Devpost to join the conversation.