Inspiration
Information flow falling on us increases every single day and oftentimes it is quite overwhelming trying to understand which things are important and which just repost/repeat what was said in other sources. A separate thing is to find connections, people mentioned and clustered on a topic, make it prioritized and sliced over time - what is fresh, what stayed, and what got superseded by other ideas.
There are projects that build connections over the data and make graphs, what stays out are the people, their profiles, connections across them, and how things change over time - what is the freshest layer on a topic.
What it does
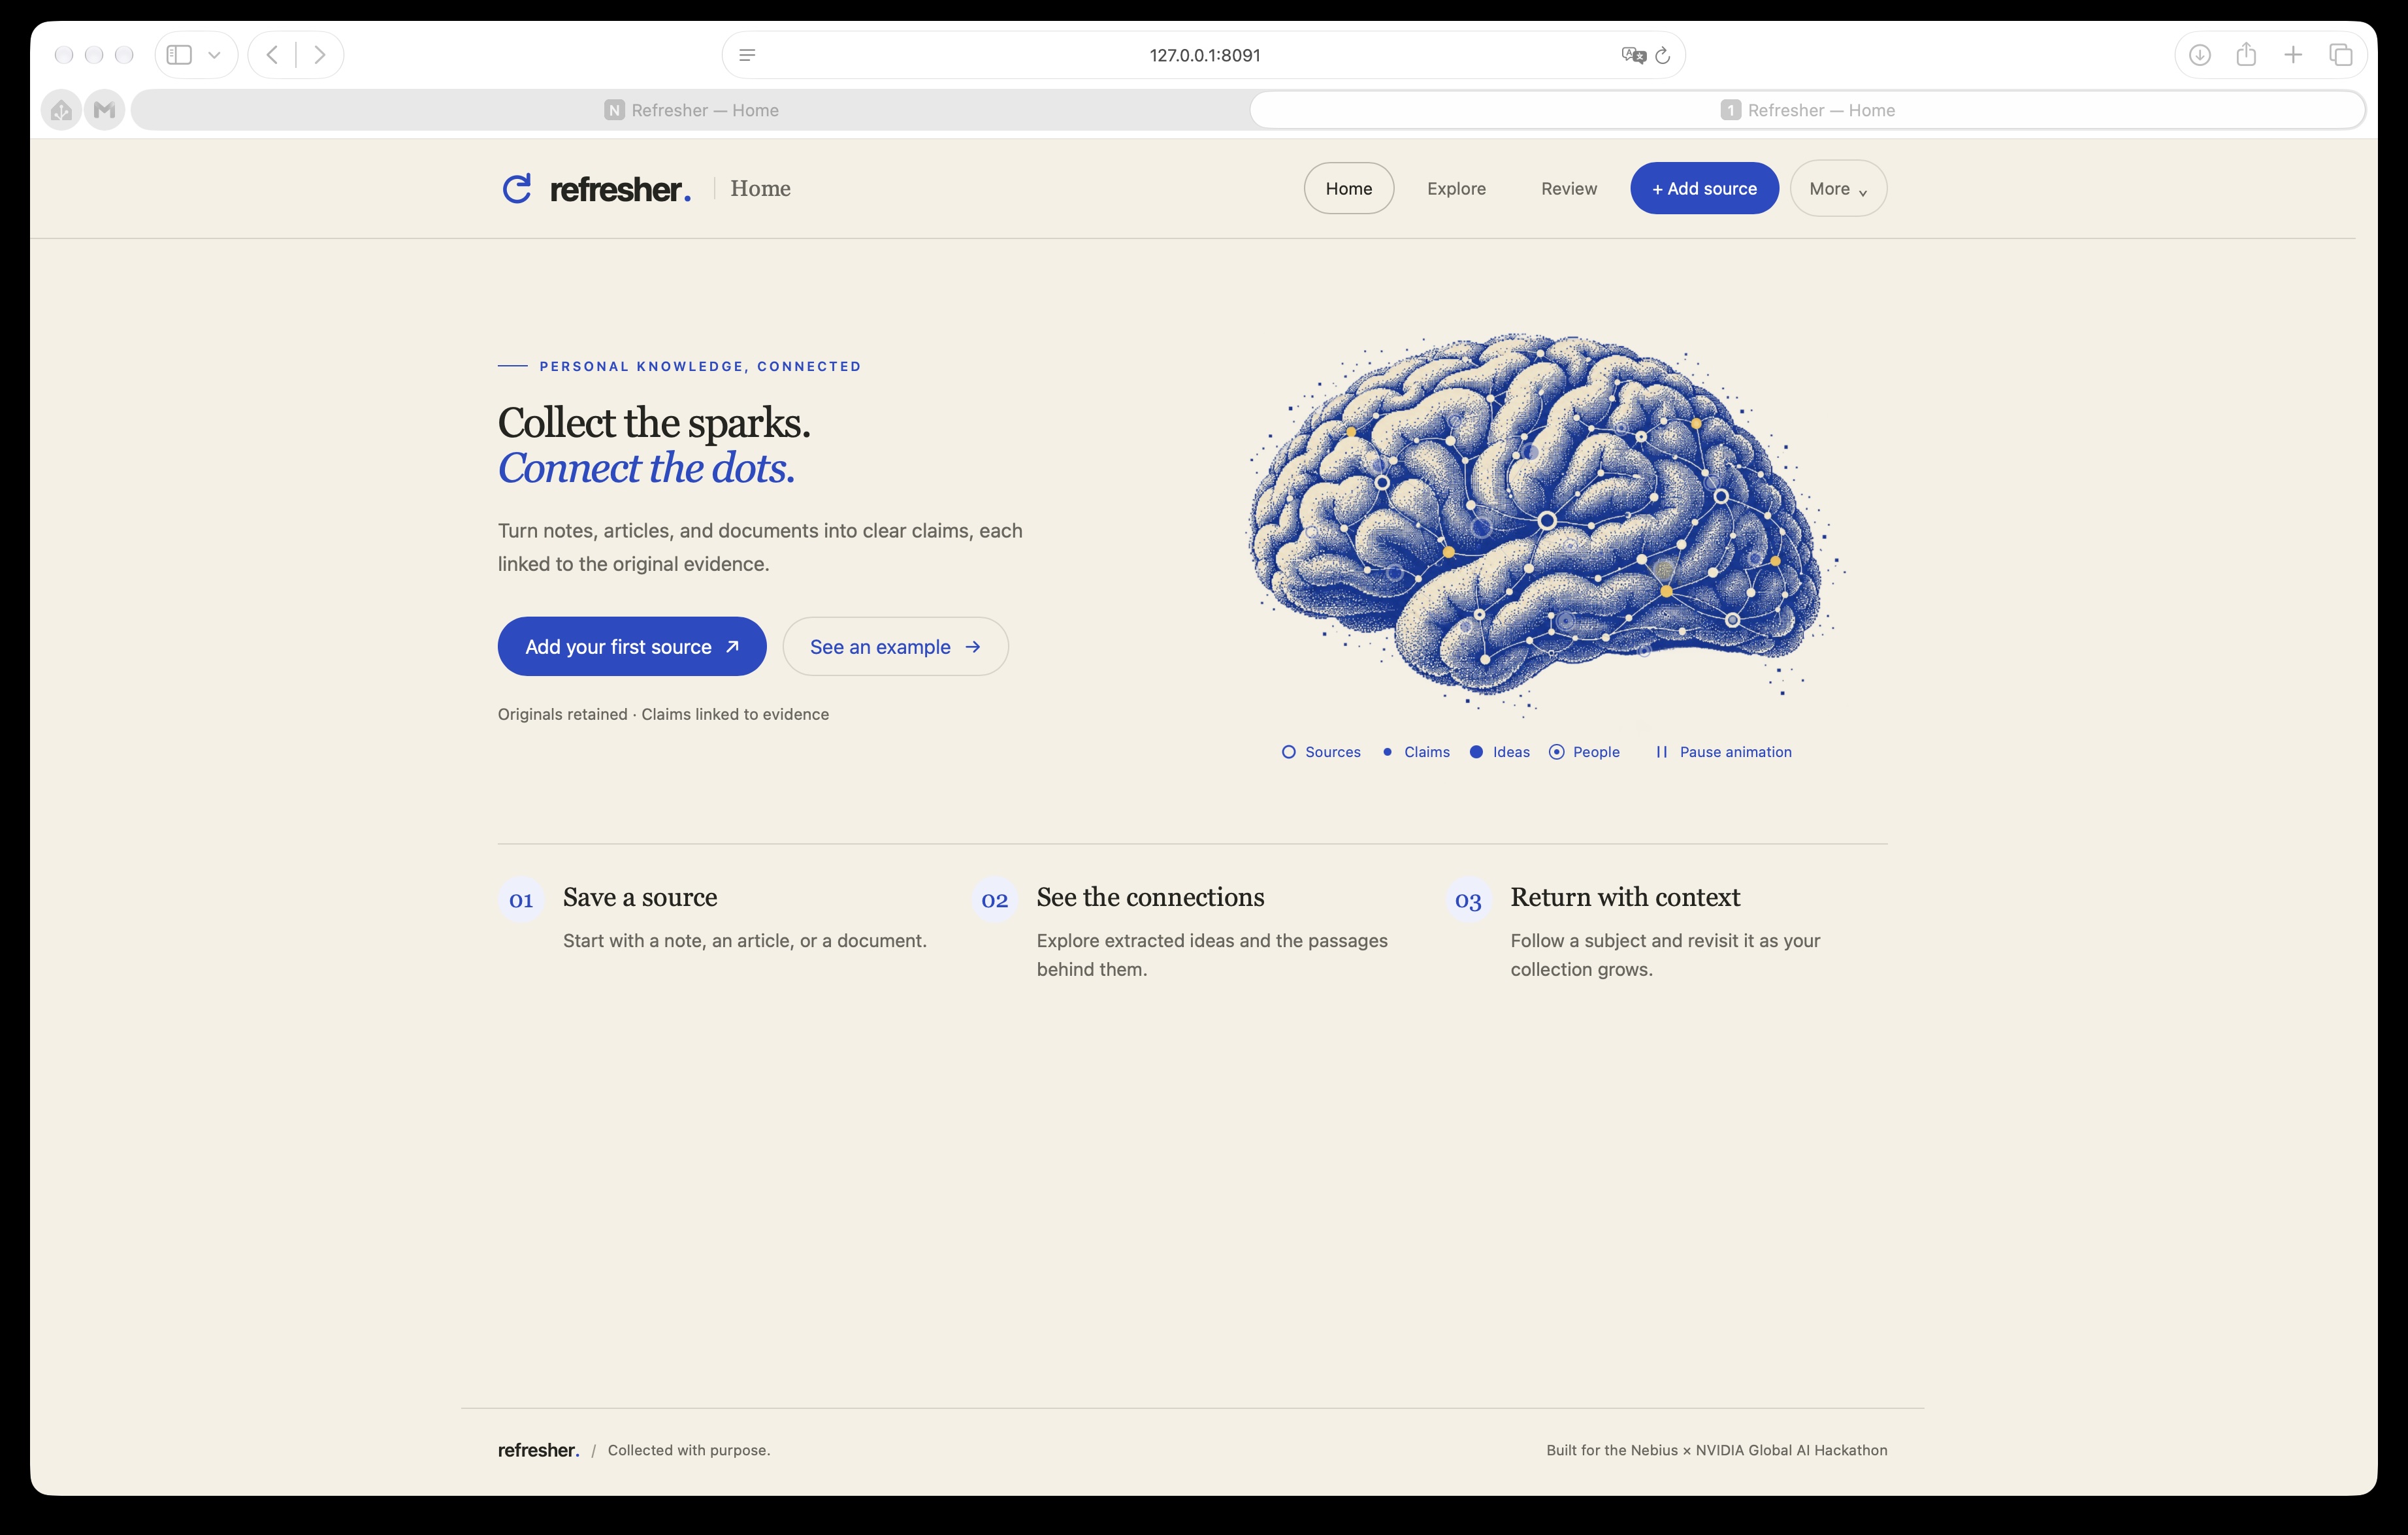
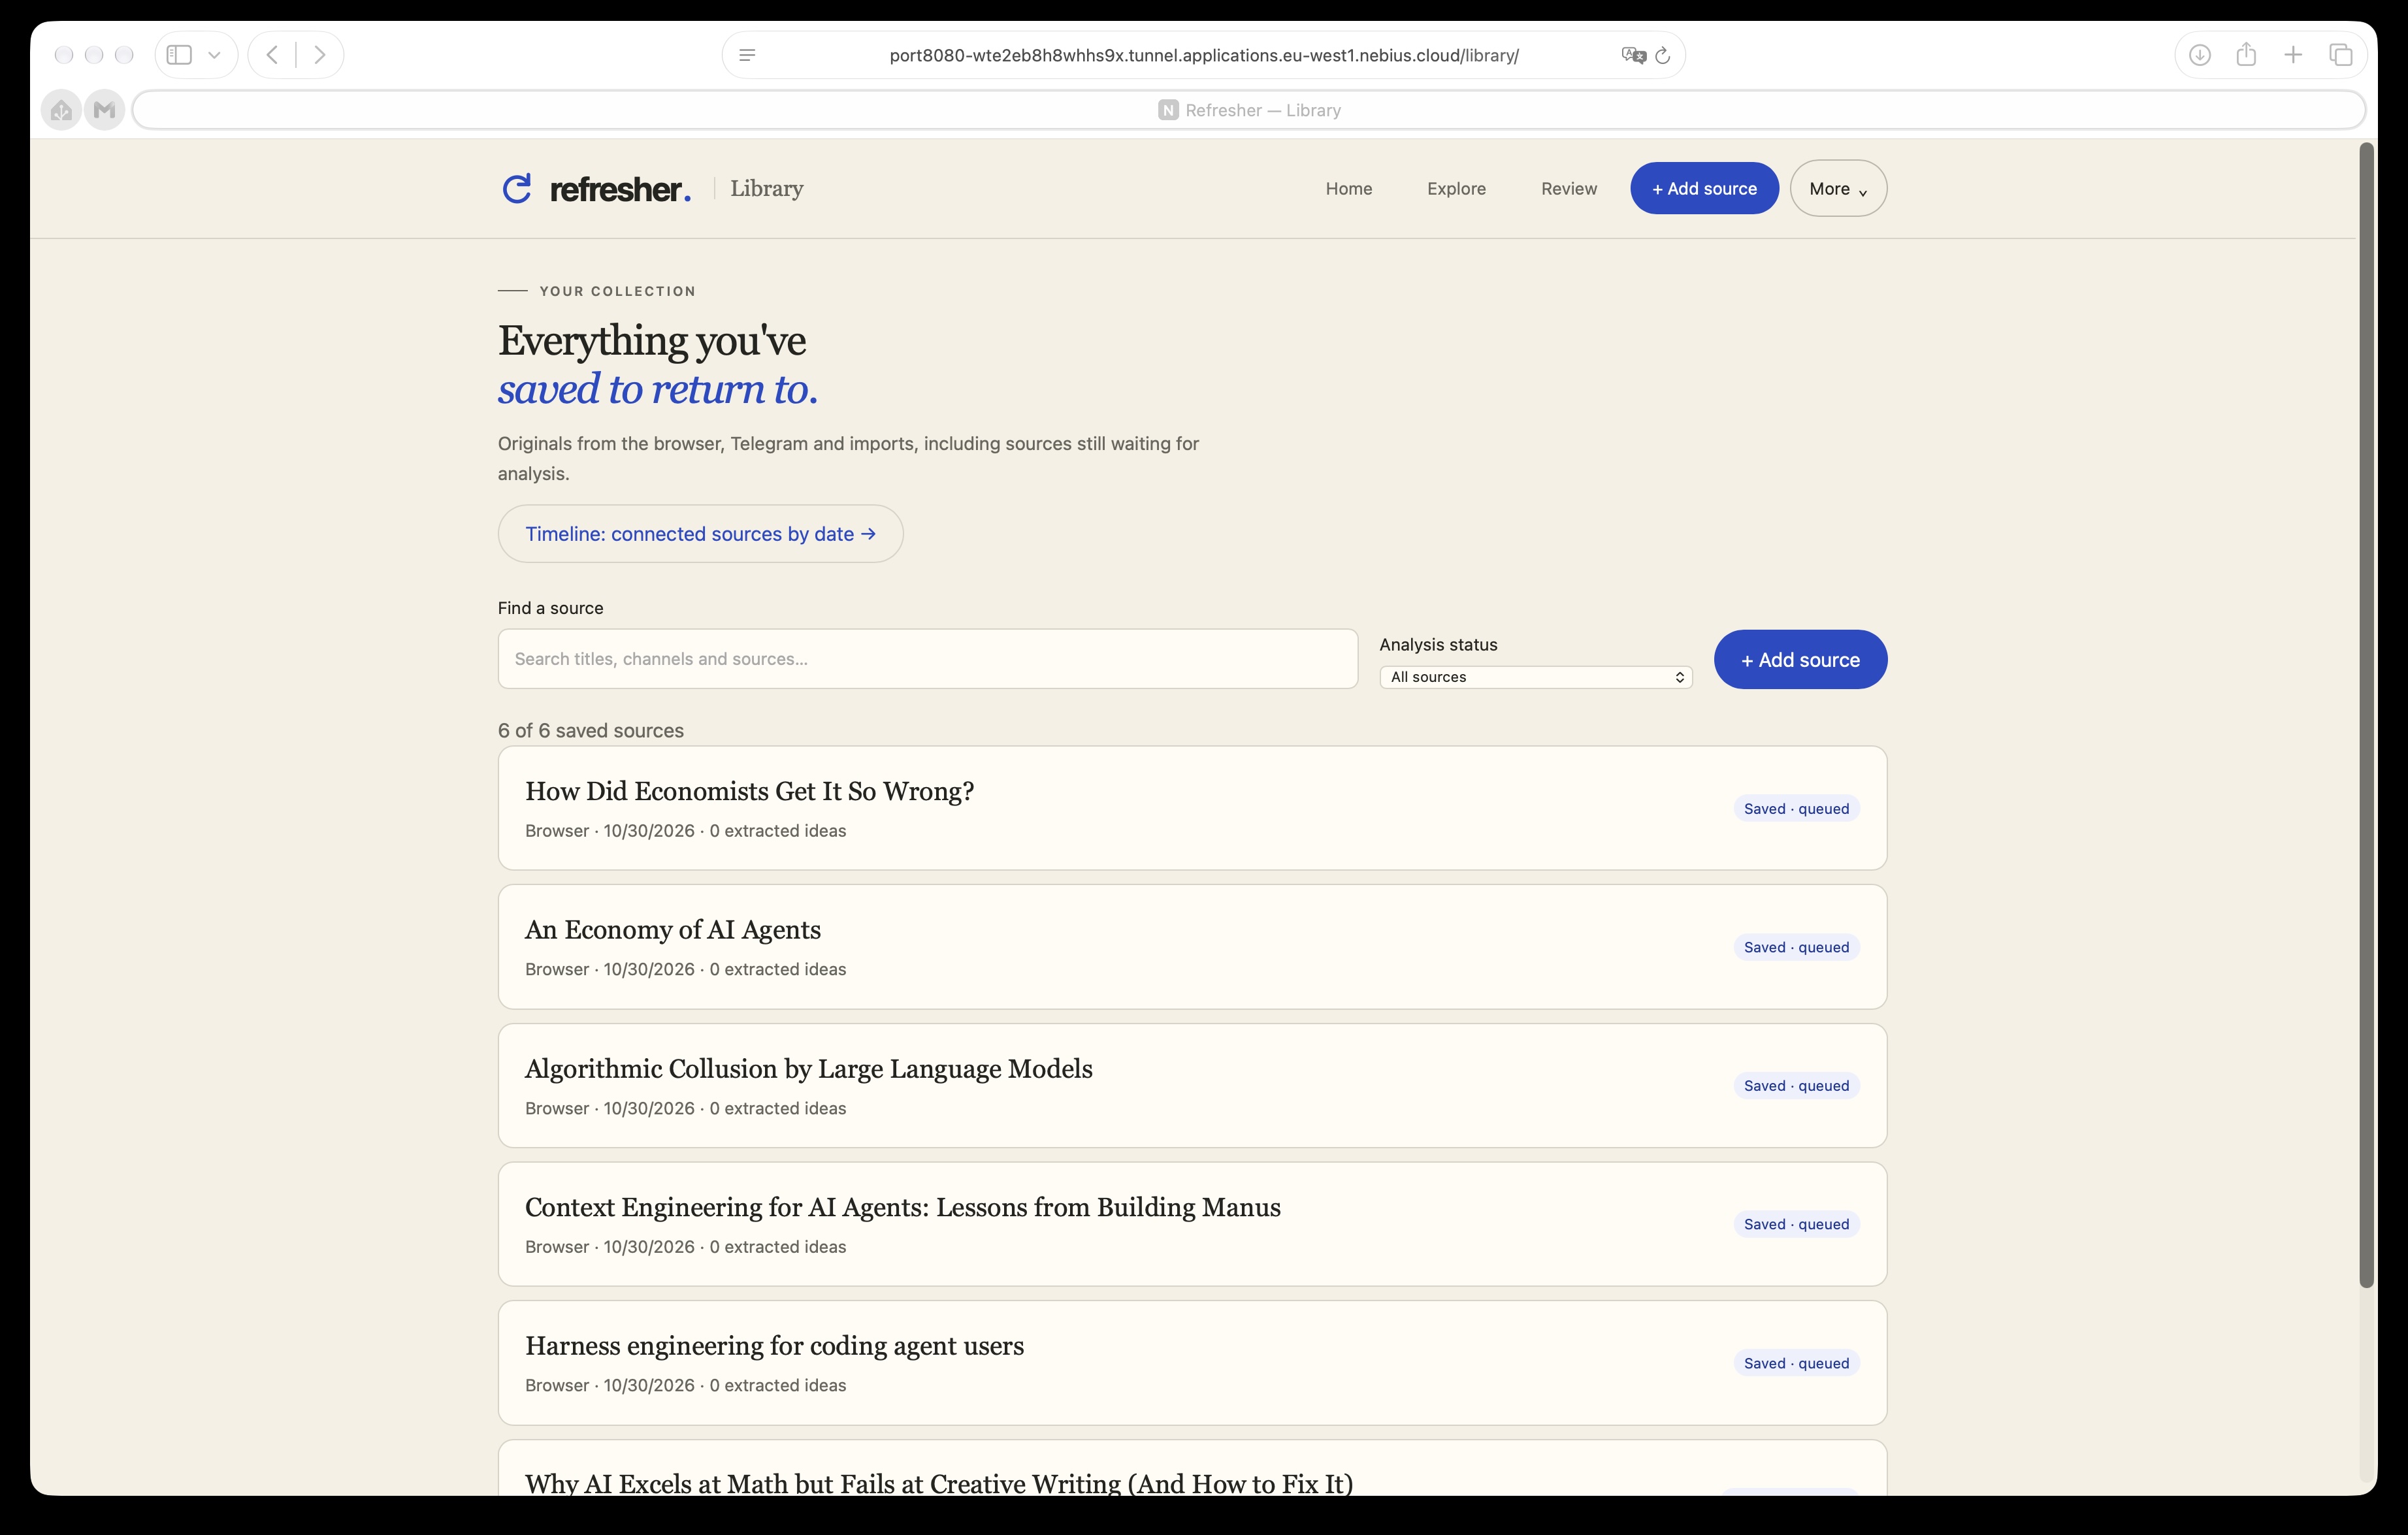
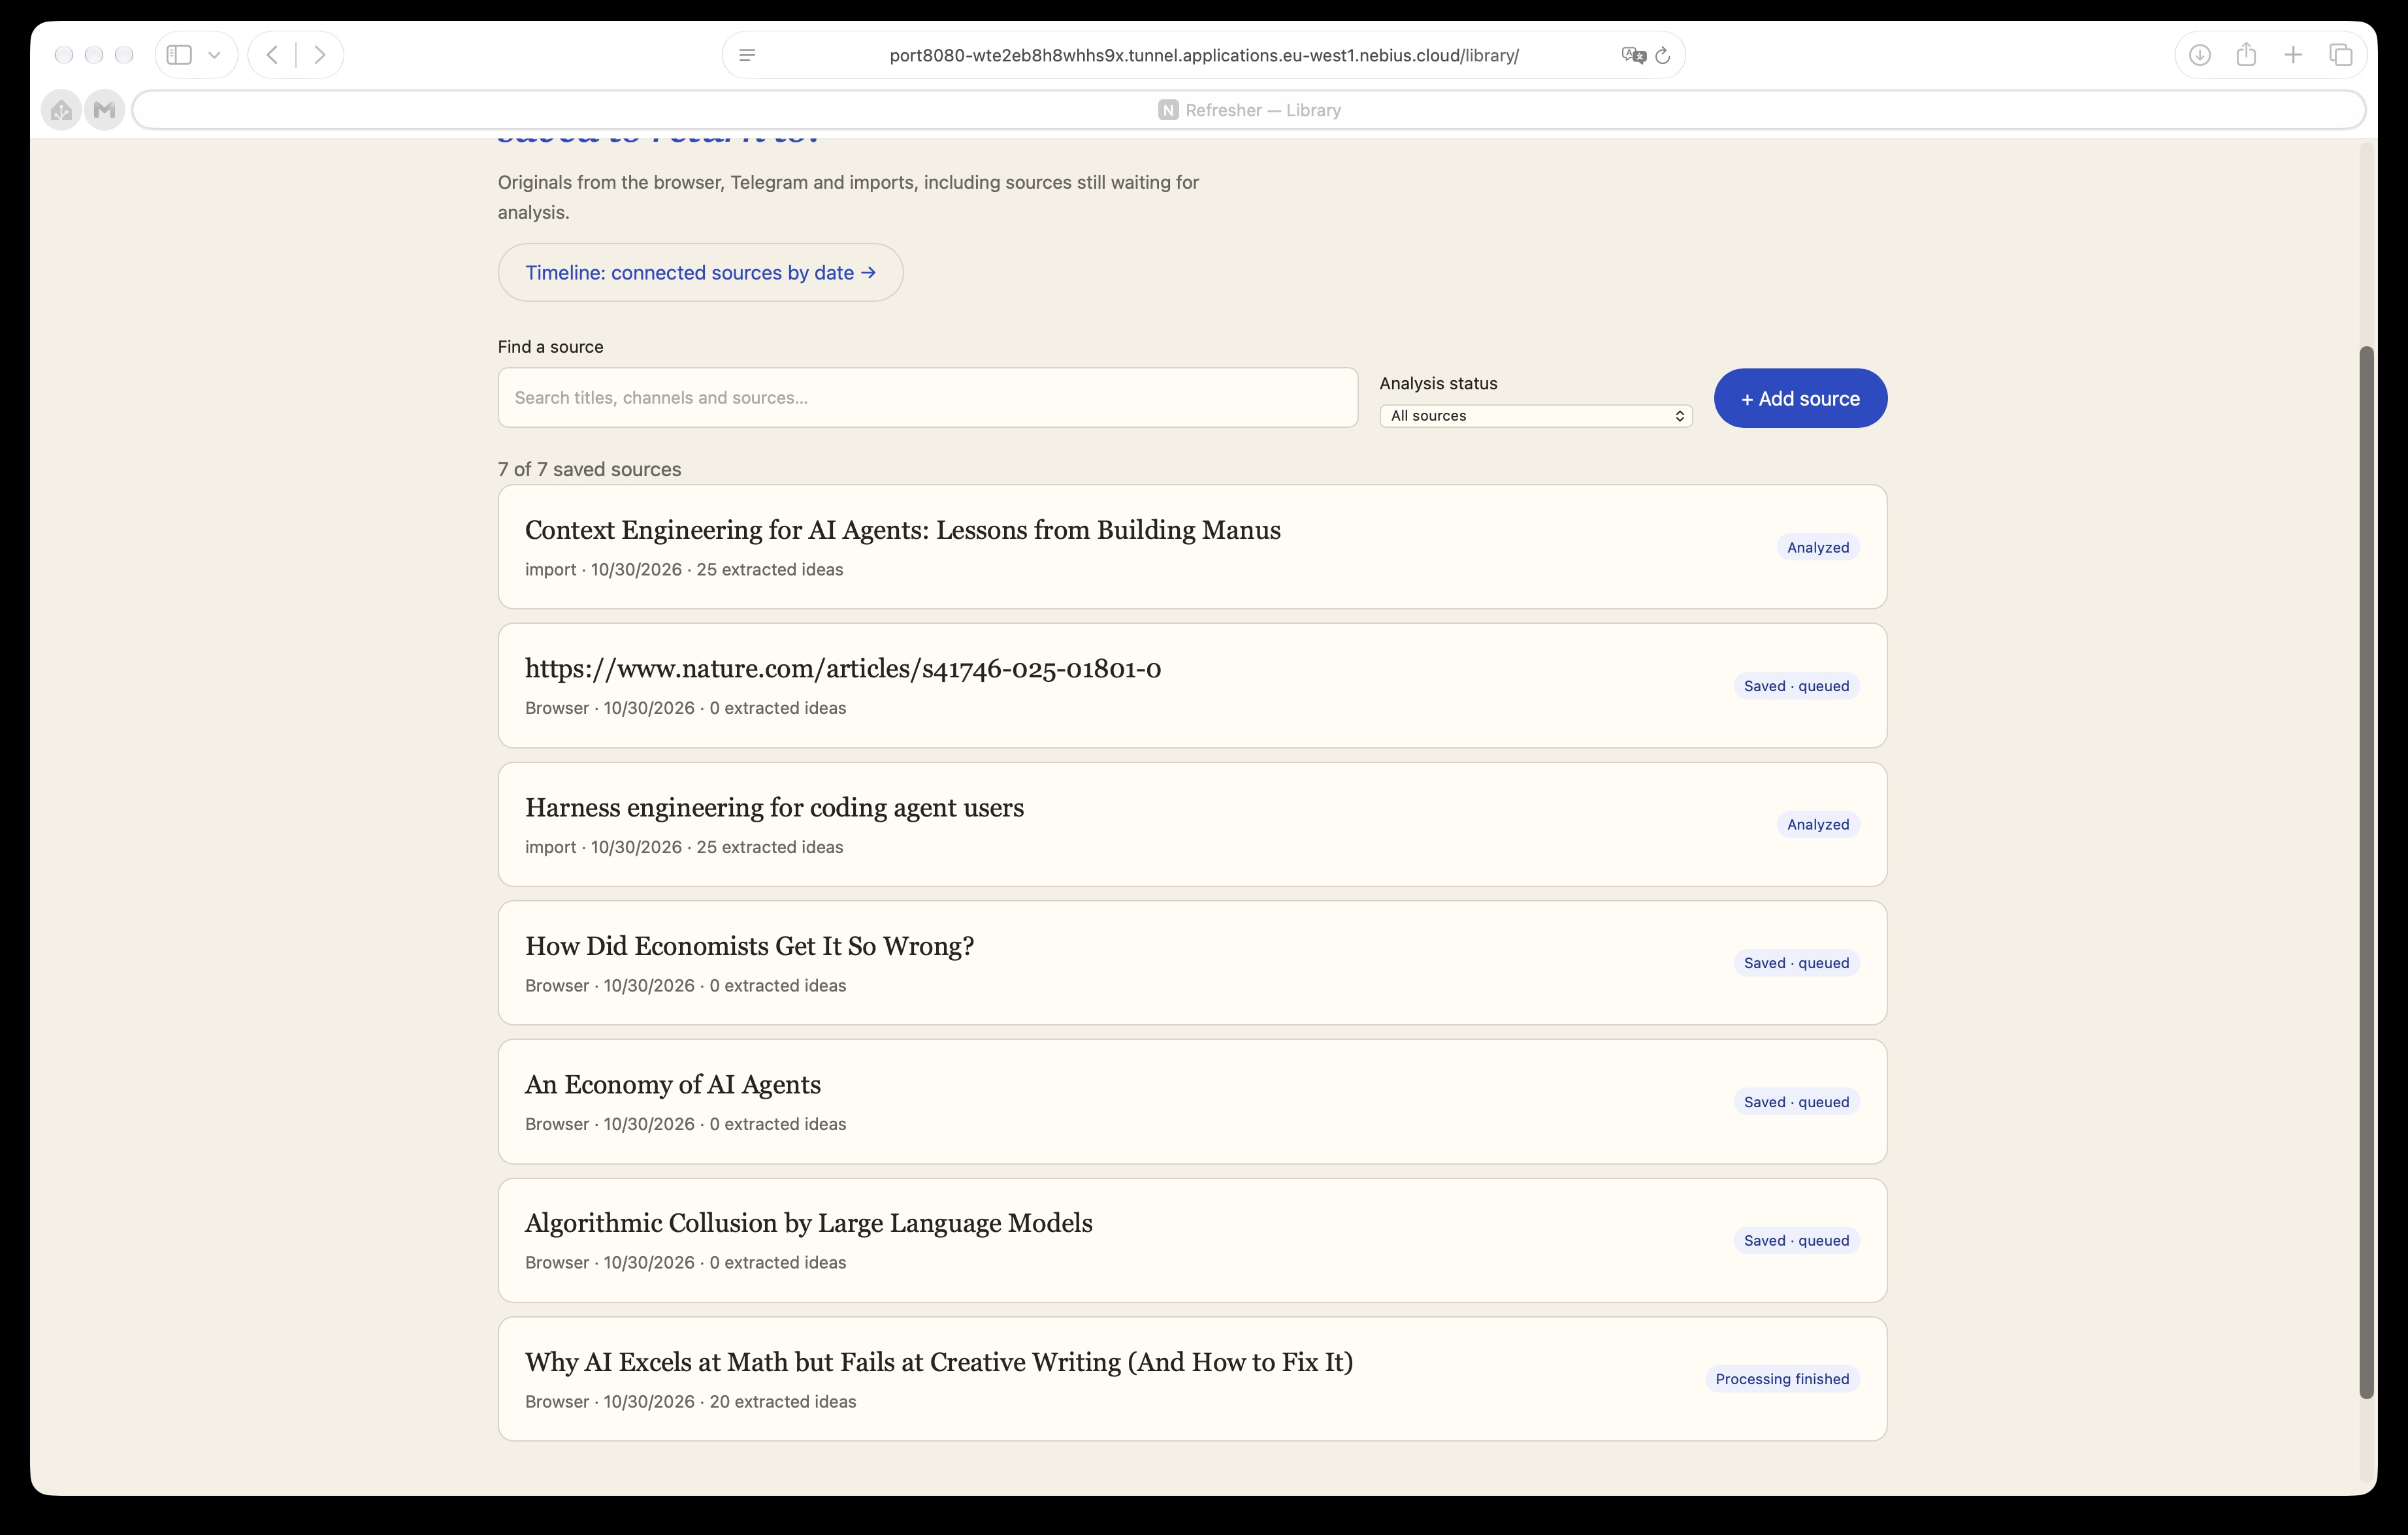
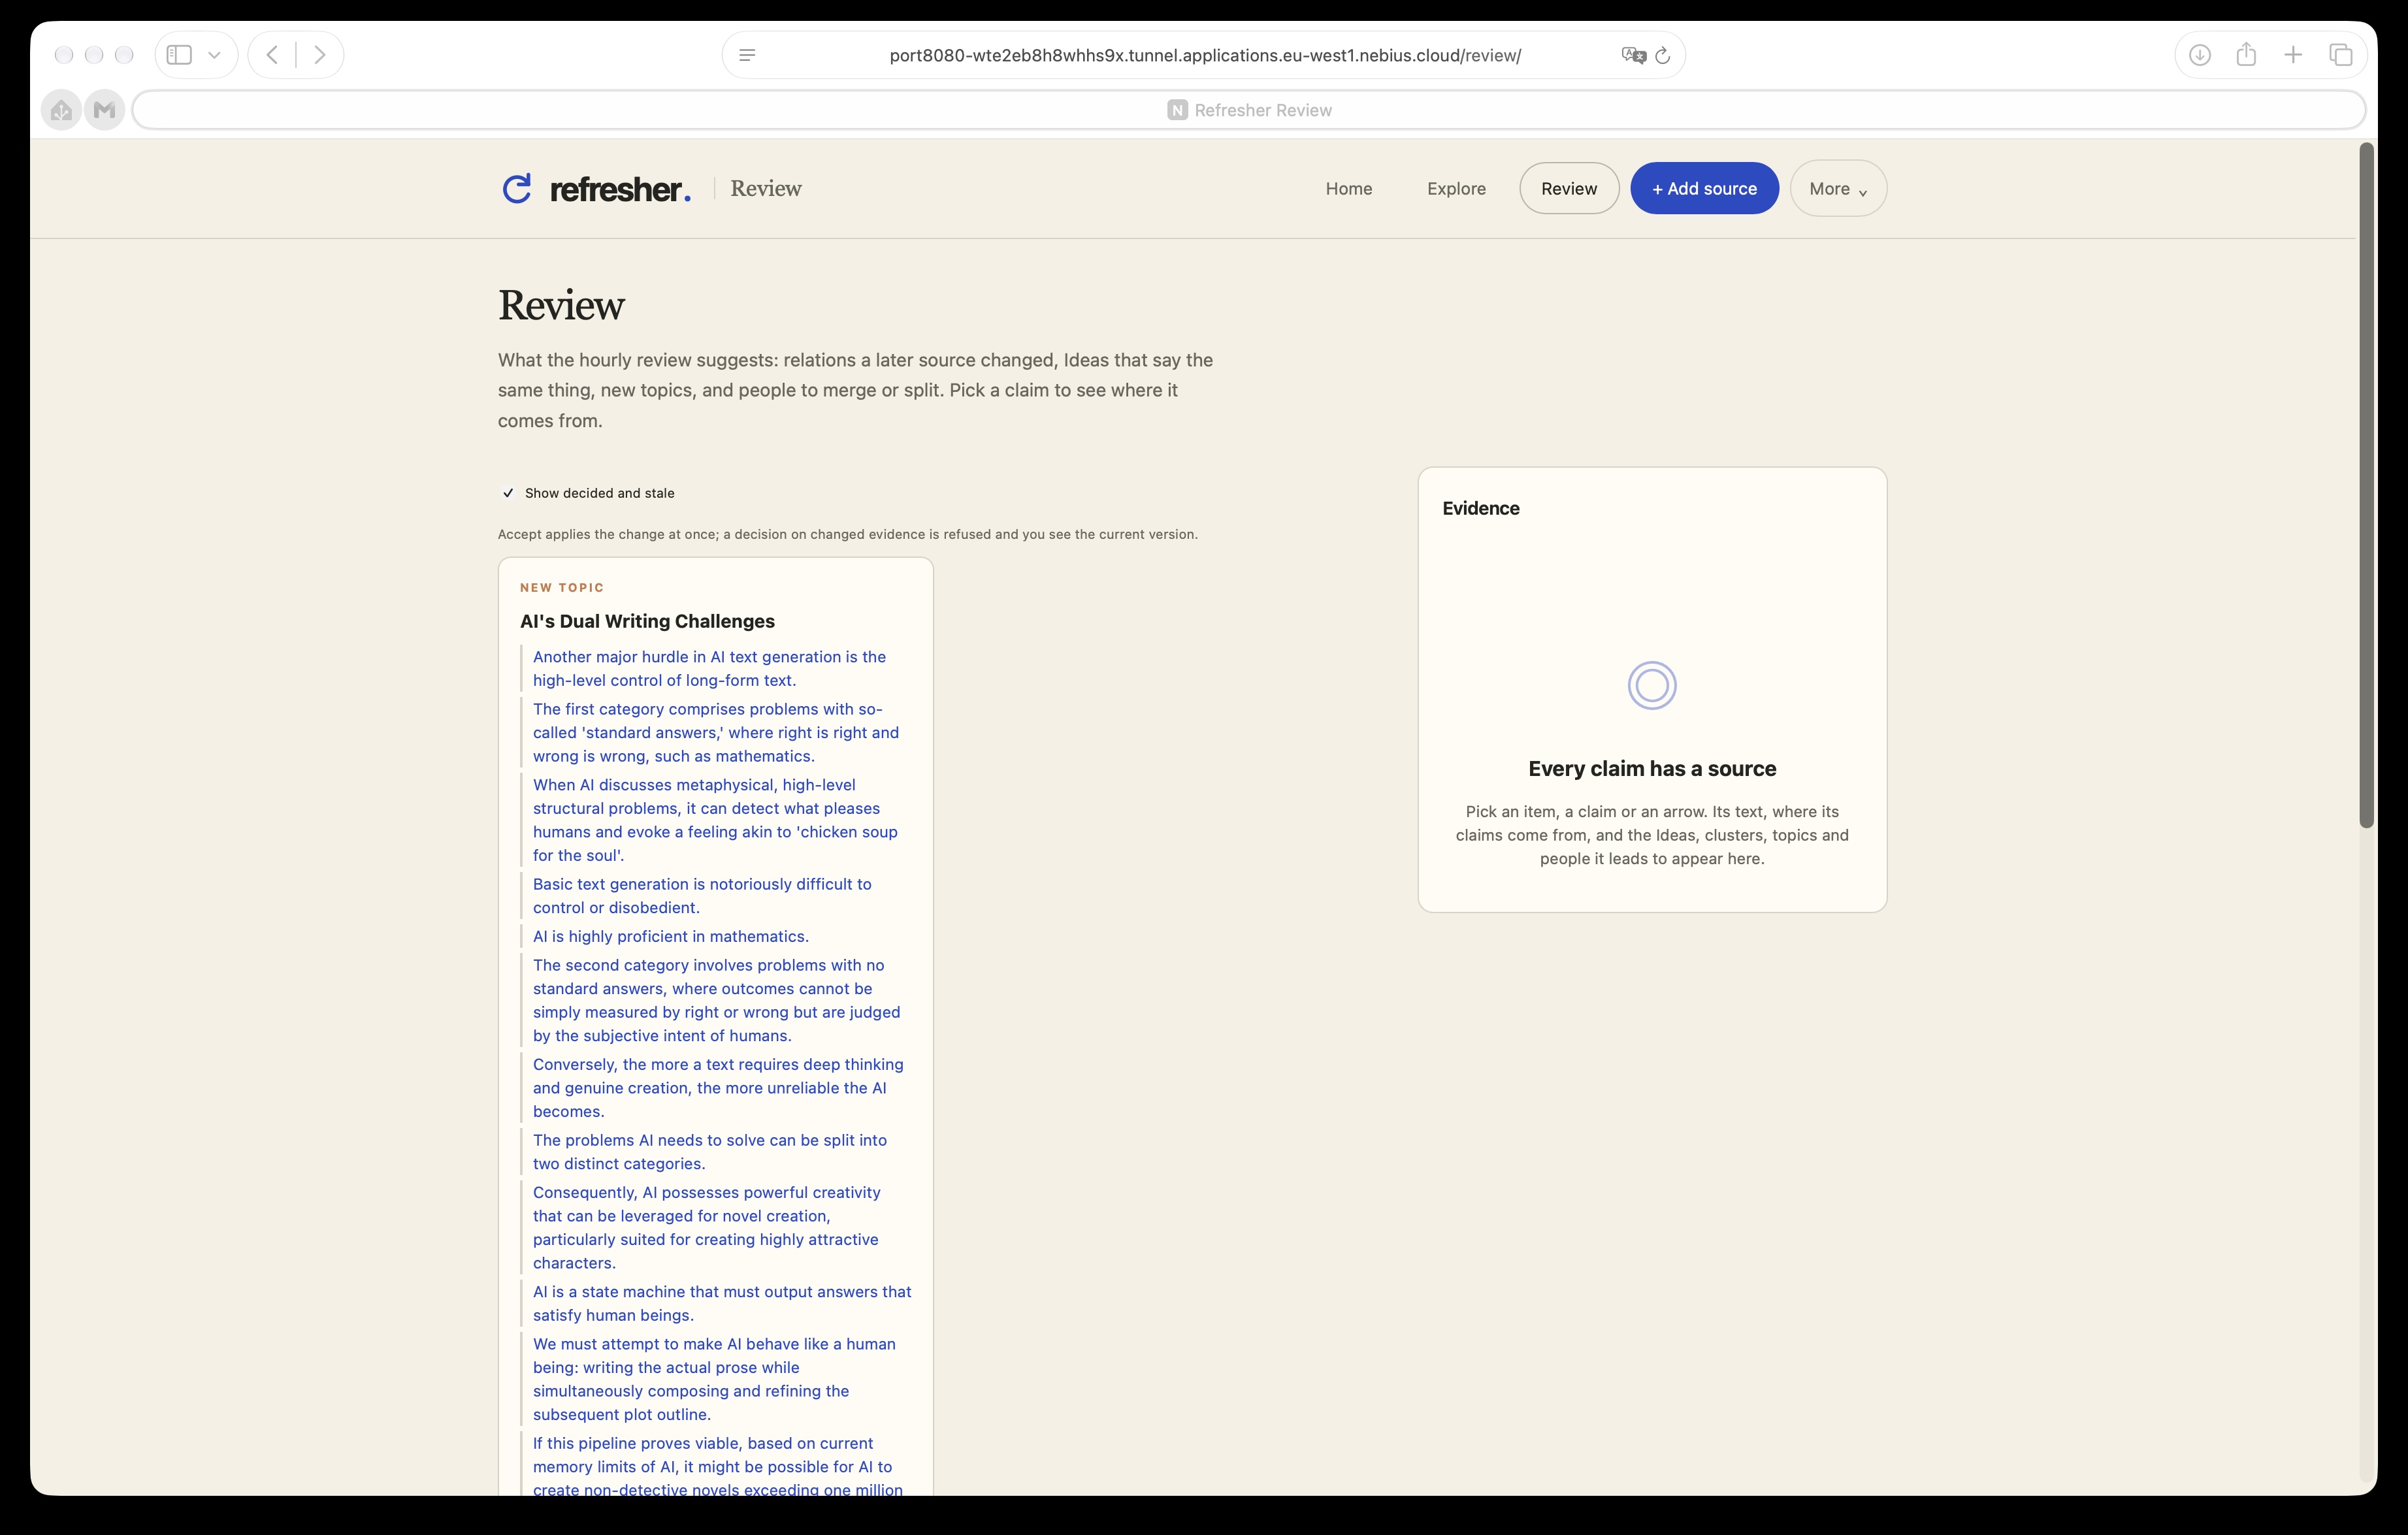
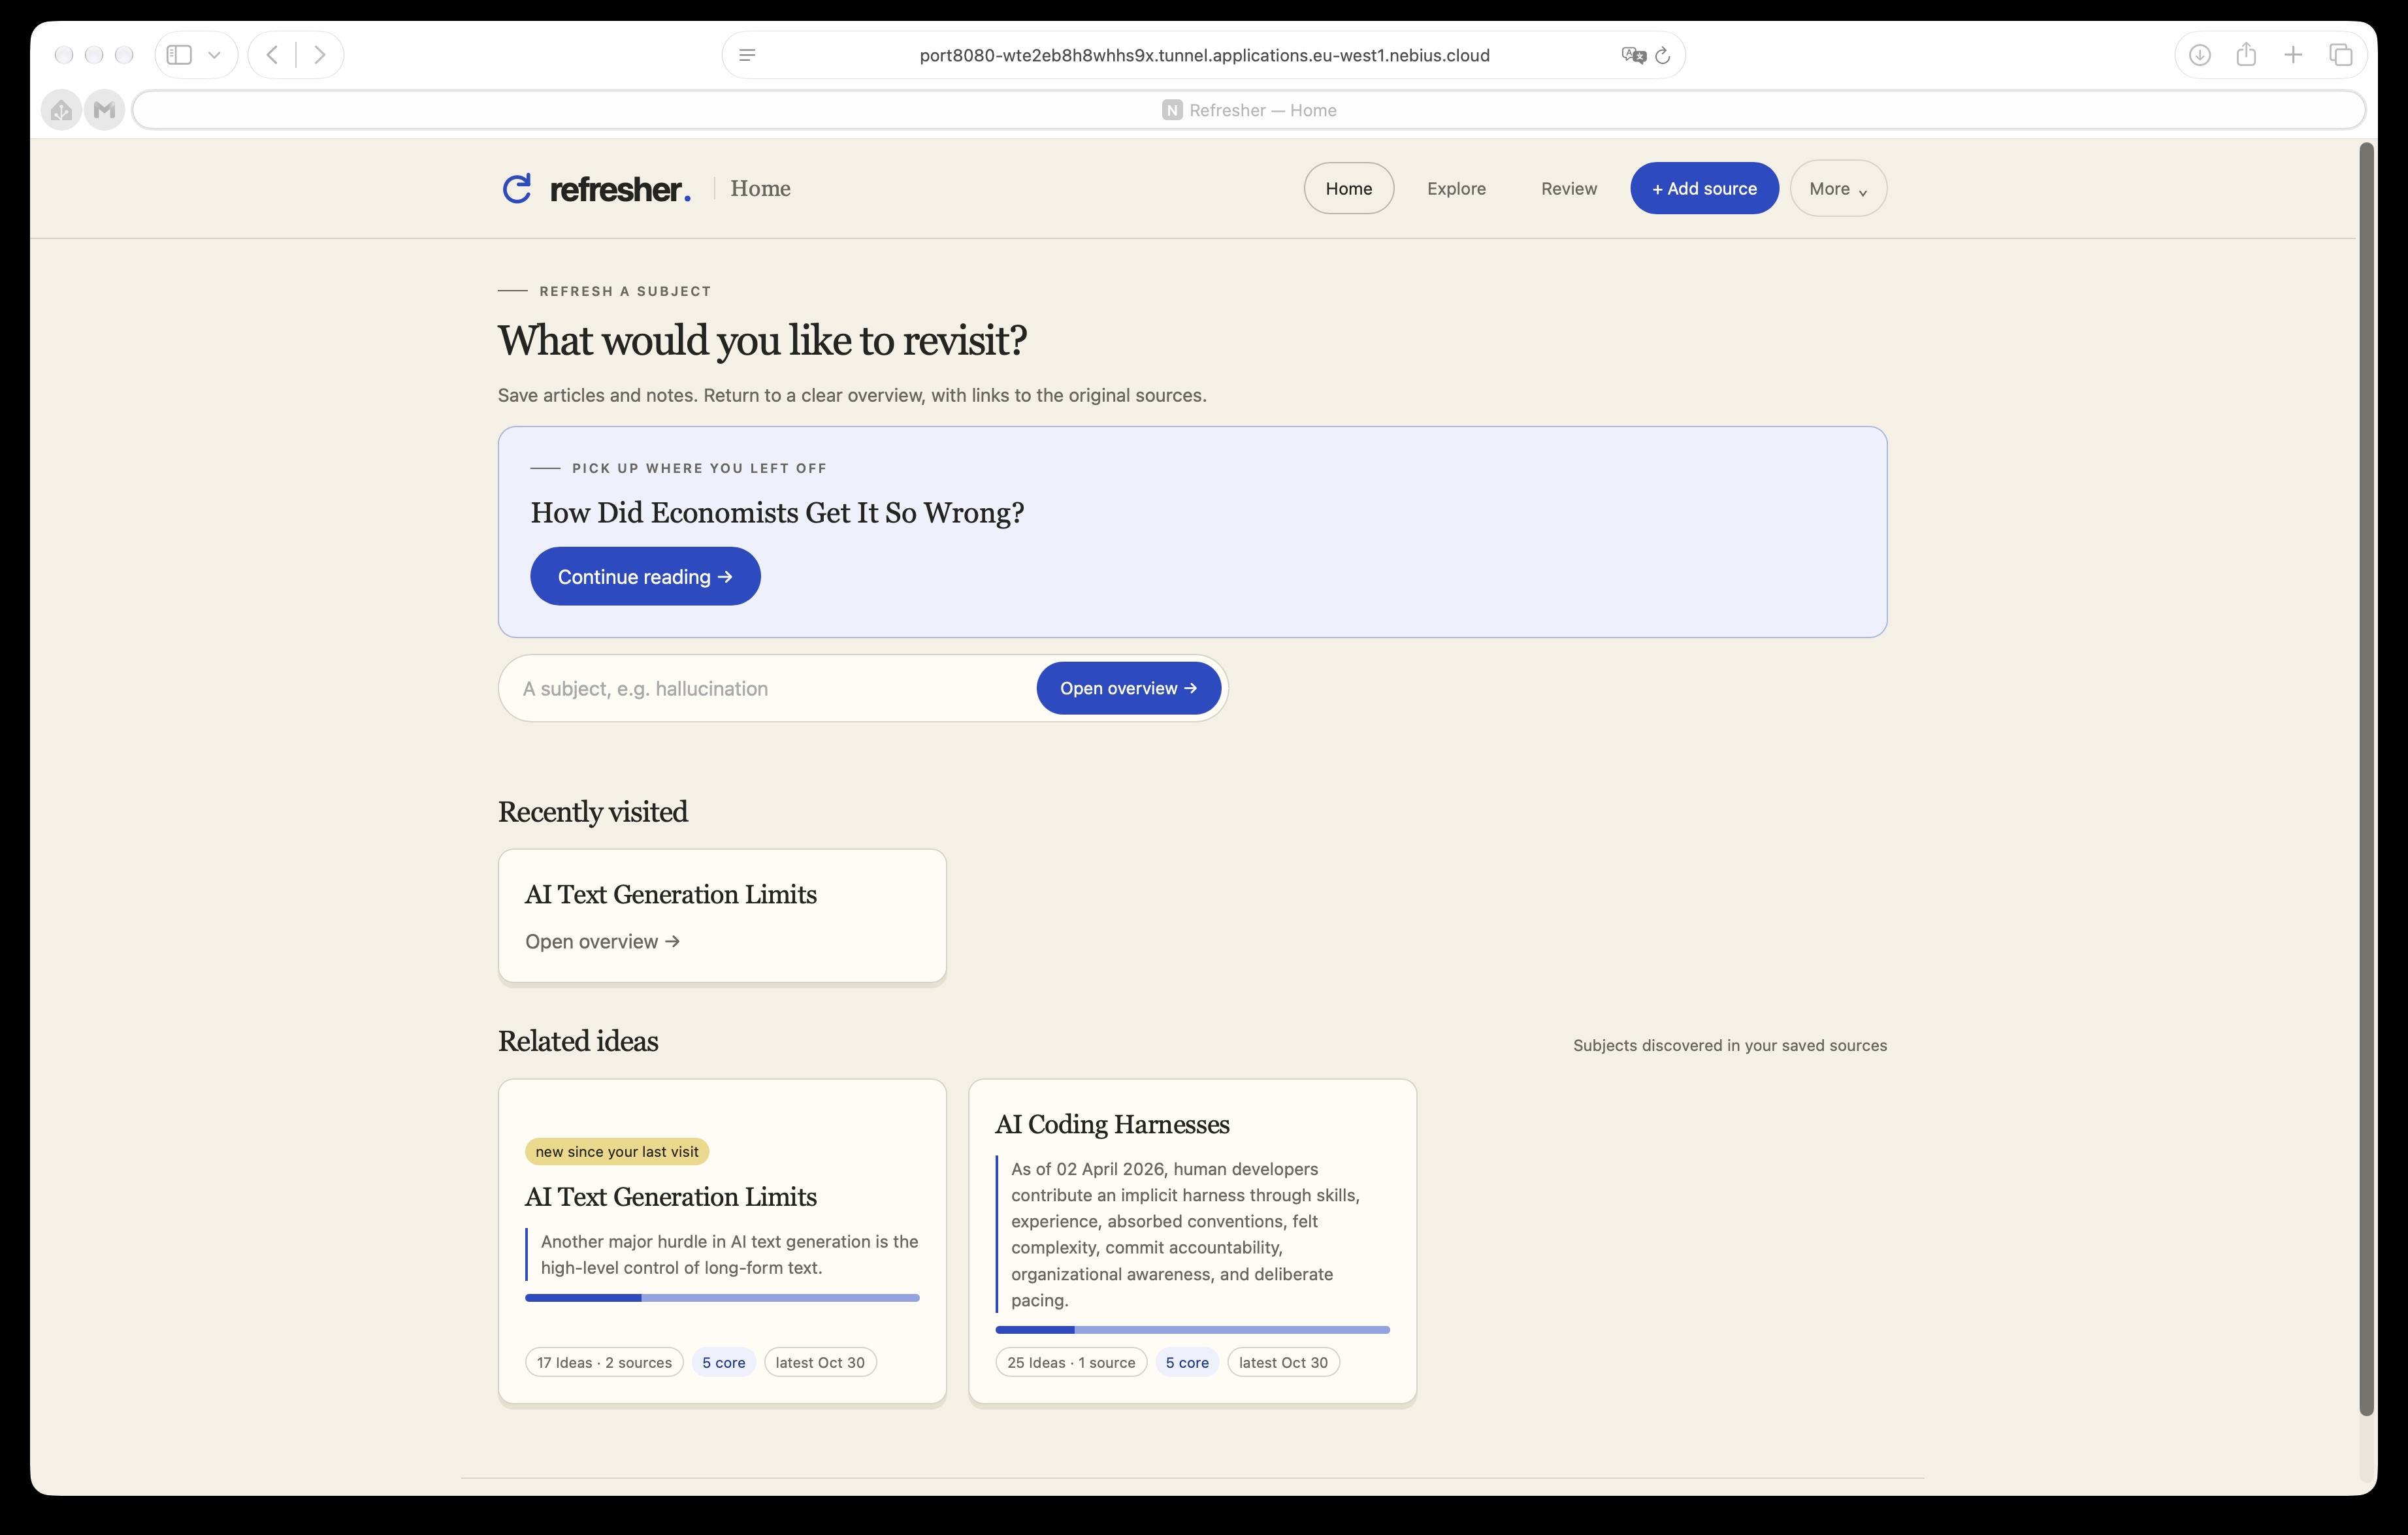
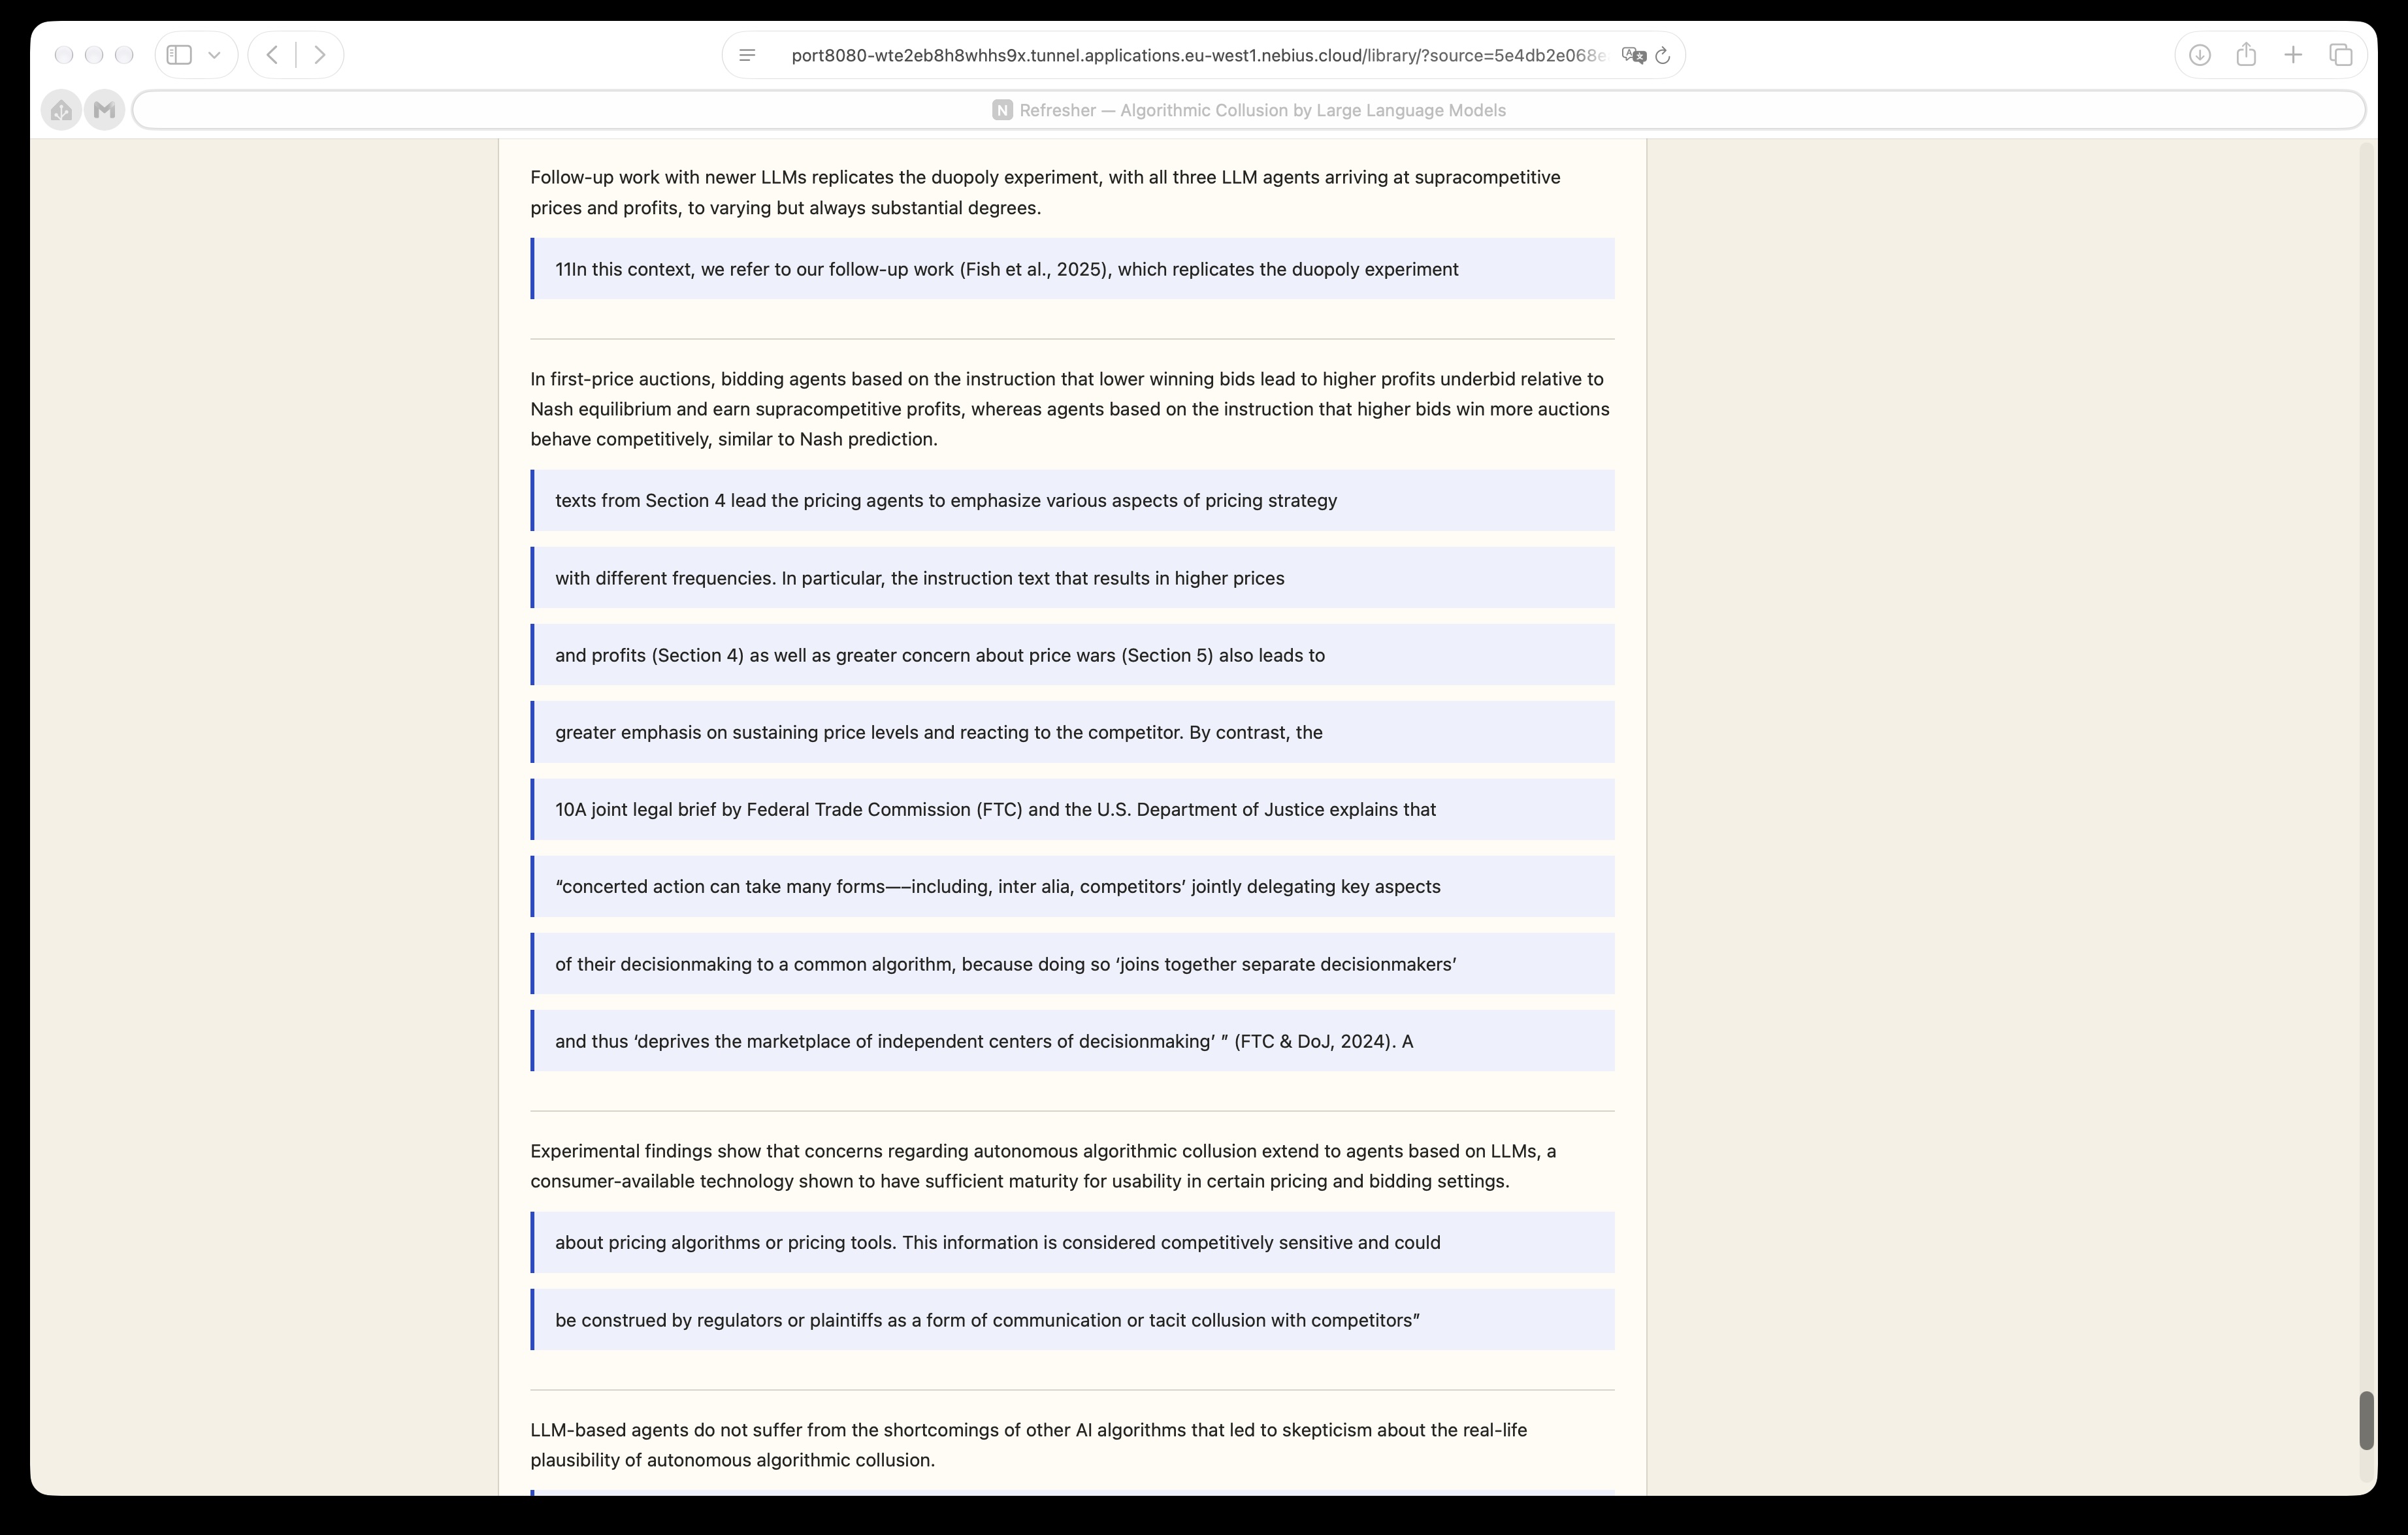
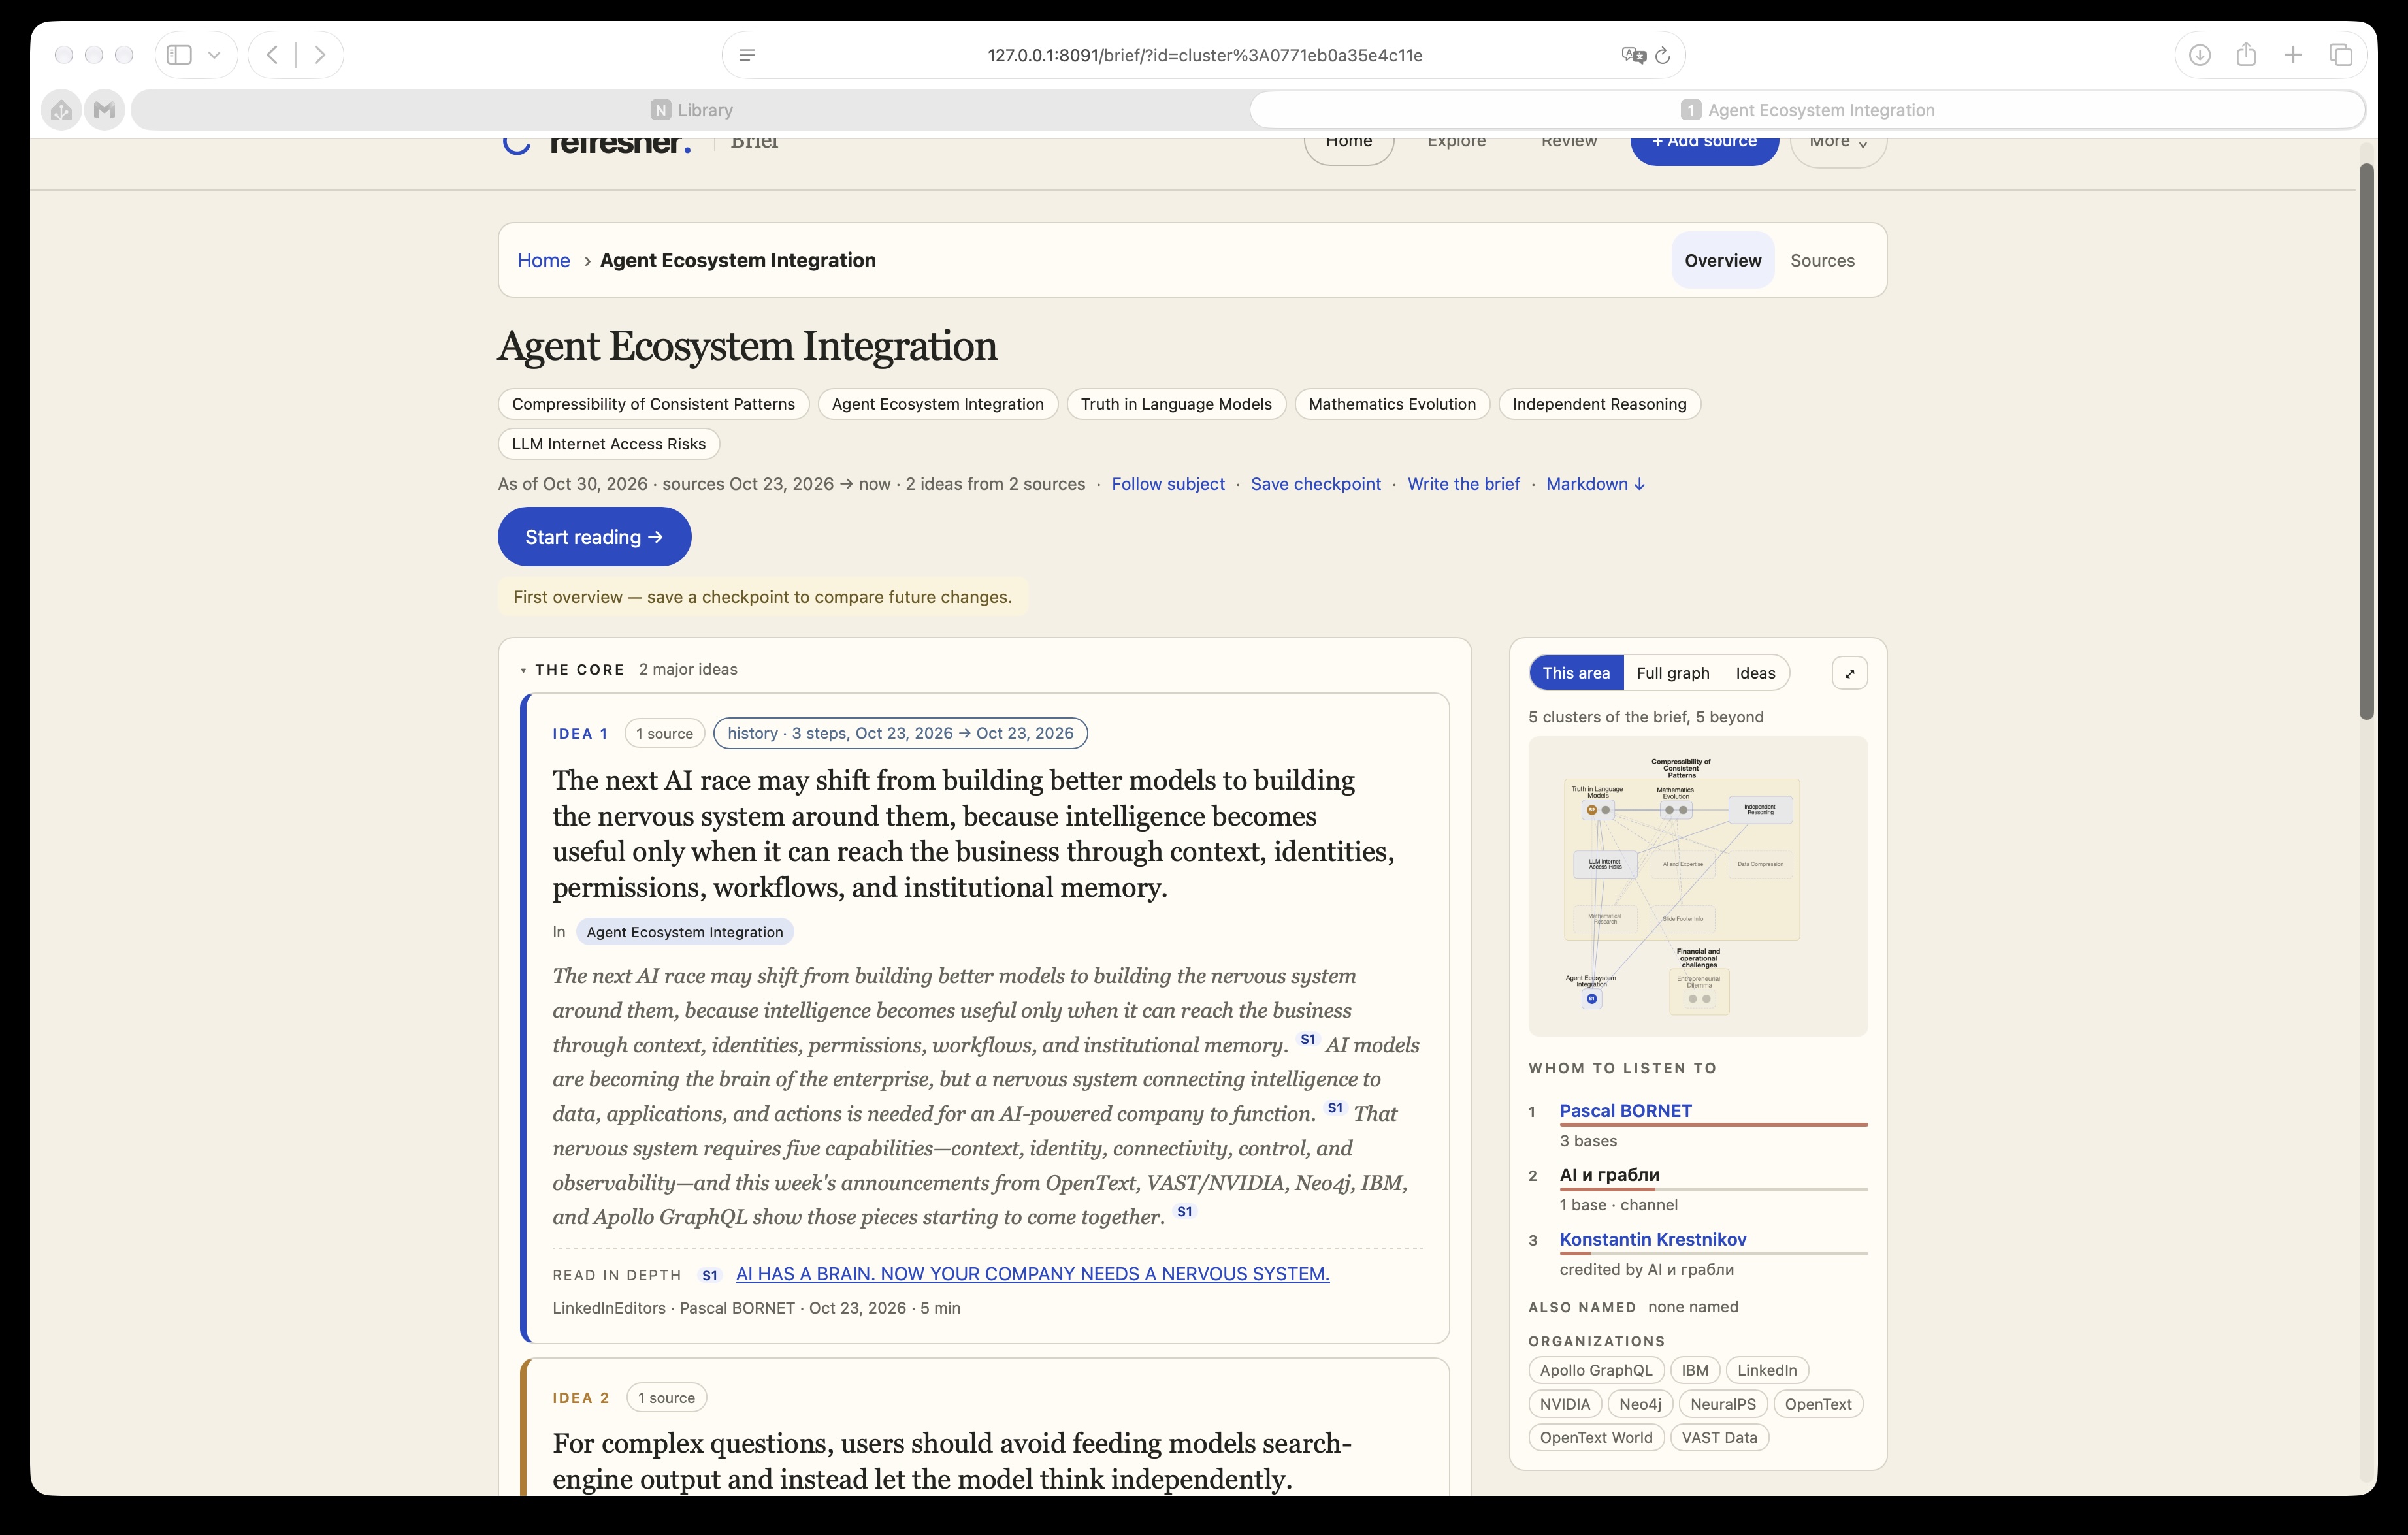
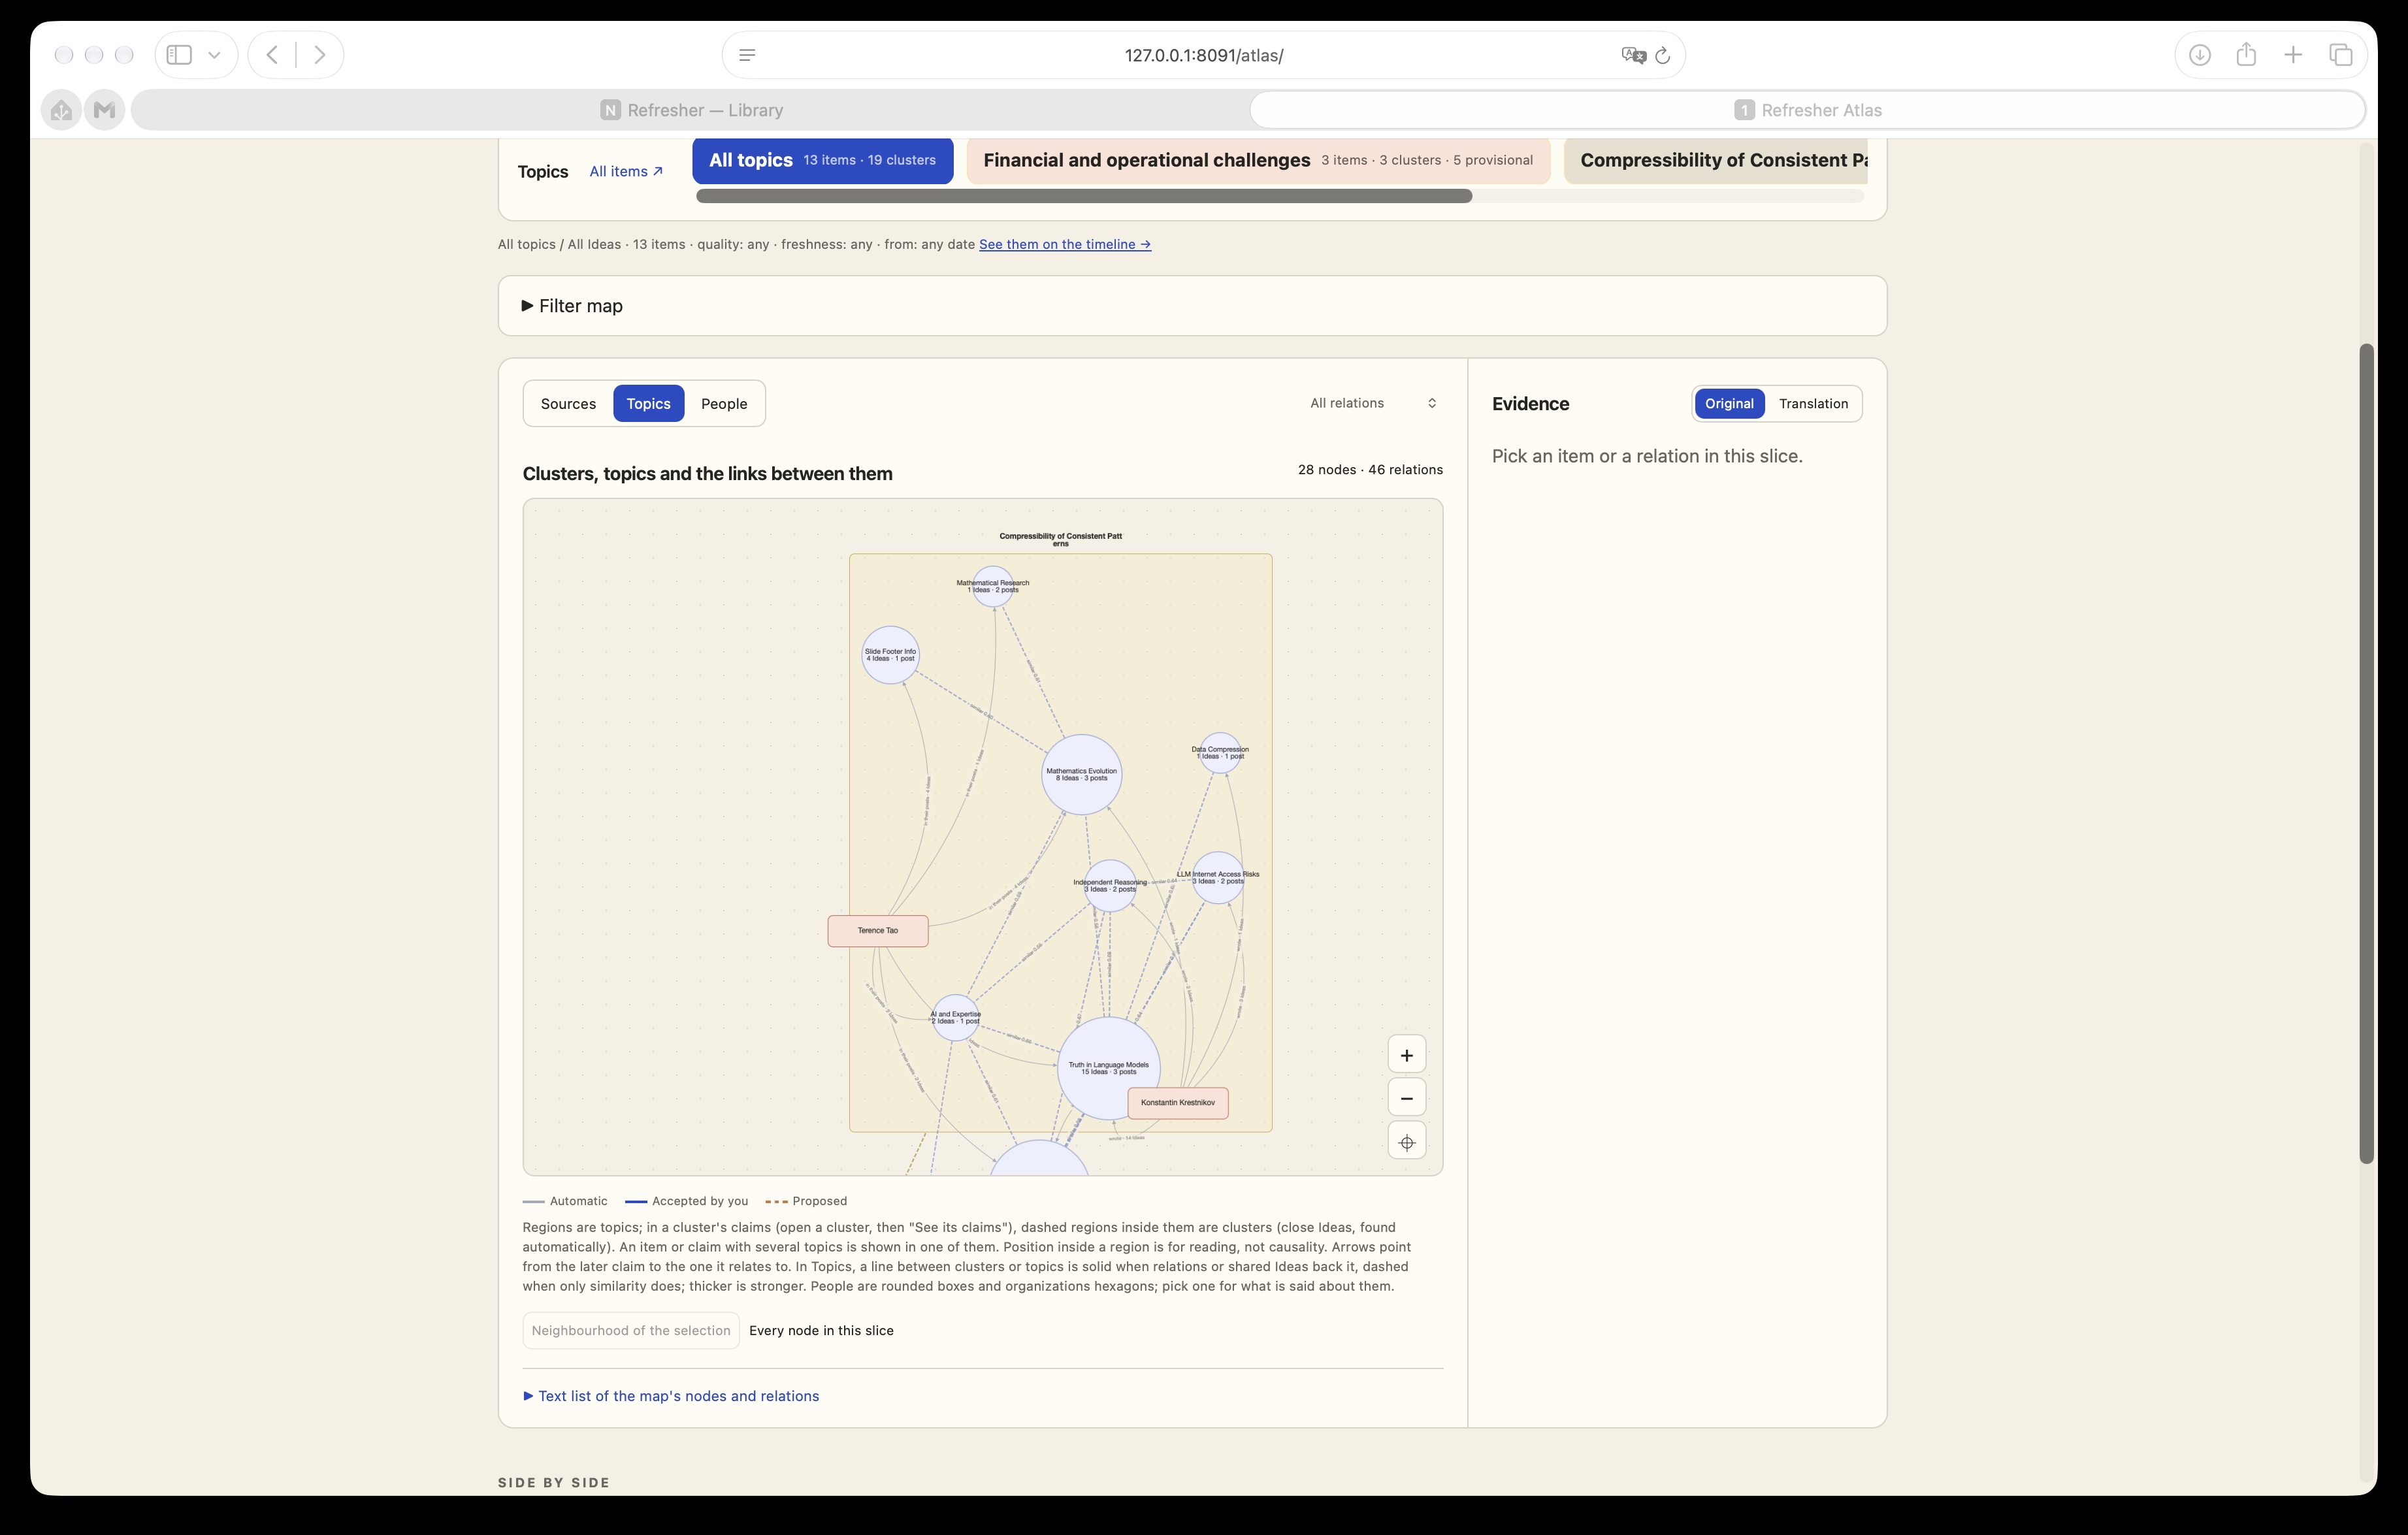
It ingests notes, articles, pdf from web interface or from Telegram bot, extracts claims, marking their type - facts, opinions, foundation information. Then claims get clustered into ideas, ideas flow into topics. In the extraction stage are also extracted people and organizations that are deduplicated and then search upon what they are and profiles are built for each. From the resulting topics, clusters of topics, and ideas is built a graph of the knowledge that helps in navigating or pulling a thread from idea or source text.
How we built it
First of all we sat down recollecting everything we know about the area and designed an architecture of the system. Reviewed the existing projects and discovered that compared to them we are adding functionality on top - that is temporal layer. There was a certain try to build trust profiles for people - helping to value which notes or ideas would have a more valued idea.
Challenges we ran into
- Multi-lingual sources create difficulties on ingestion - they should be reviewed and judged in the original language (and original language is sometimes mistaken for a different one by the models), then translated if we are to keep the the interface and texts from the models in the same language across the applications.
- People extraction, especially, again, in multiple languages may create more profiles than there are actually. Due to how they are written or if source languages use multiple cases for nouns. Sometimes names could contain typos.
- Serverless cloud feels quite slow.
- Imports may end up stuck in the process of analysis and require clearing up the imports and connections created so that they don't overload the graph and ideas.
Accomplishments that we're proud of
We made the graph to work like a graph system - with clusters and connections. We managed to reach a reasonable version of retrieval of the information and navigation over it.
What we learned
Unstructured data has lots of edge cases, especially when it is multilingual.
What's next for Refresher
It is to become a context engine for knowledge management in the agents. In the companies lots of knowledge is stored in the knowledge management systems but oftentimes it is difficult to distinguish which of that knowledge is relevant to a specific point in time.
Built With
- aiogram
- cytoscope.js
- model-context-protocol
- nebius-ai-cloud
- nebius-serverless-endpoints
- nebius-serverless-jobs
- nebius-token-factory
- nemotron-3-super
- nemotron-3-ultra
- nemotron-super
- nemotron-vl
- nvidia-nemotron
- pydantic
- pypdfium2
- python
- qwen3
- qwen3-embeddings
- telegram-bot-api
- trafilatura
