Inspiration
Every open role went through the same manual loop: check Gmail for Indeed application alerts, open each candidate's Indeed page, download the resume PDF, read it, copy the phone number, open WhatsApp, and write a personalized invite. For 15 candidates, that was a solid 3 hours of repetitive, error-prone work — and it didn't scale past a handful of postings a week. I wanted the exact same judgment calls (who to call, what to say) without the manual plumbing in between.
What it does
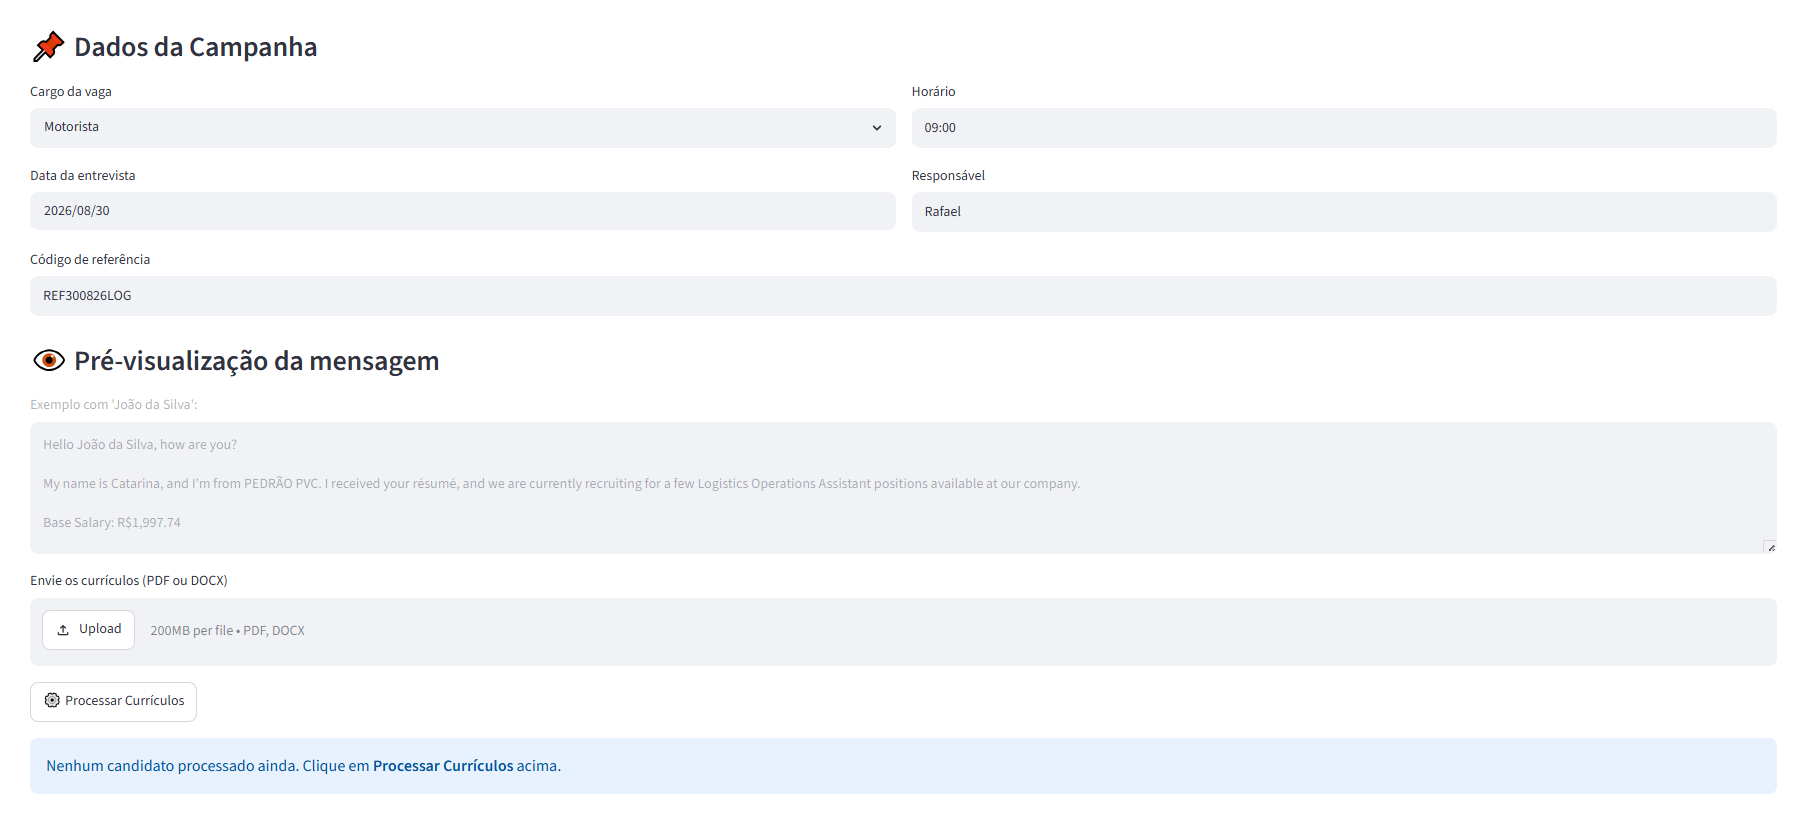
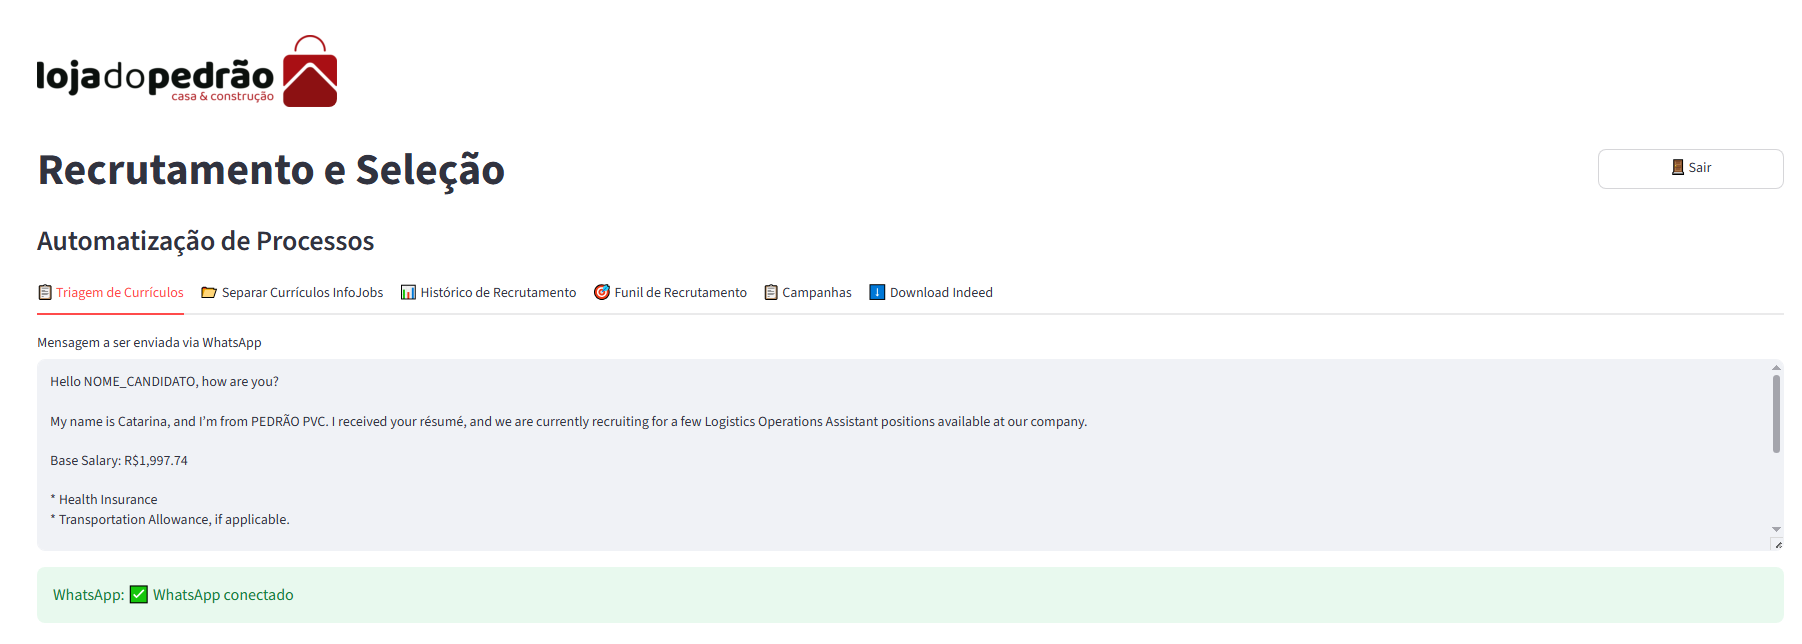
RecrutaFlow is an end-to-end recruiting pipeline that turns a flood of job-board application emails into personalized WhatsApp interview invites:
- Logs into Gmail via IMAP and reads every unread "new applicant" email from Indeed
- Drives a real Chrome session (Playwright over CDP) to open each candidate's Indeed profile and download their resume PDF automatically
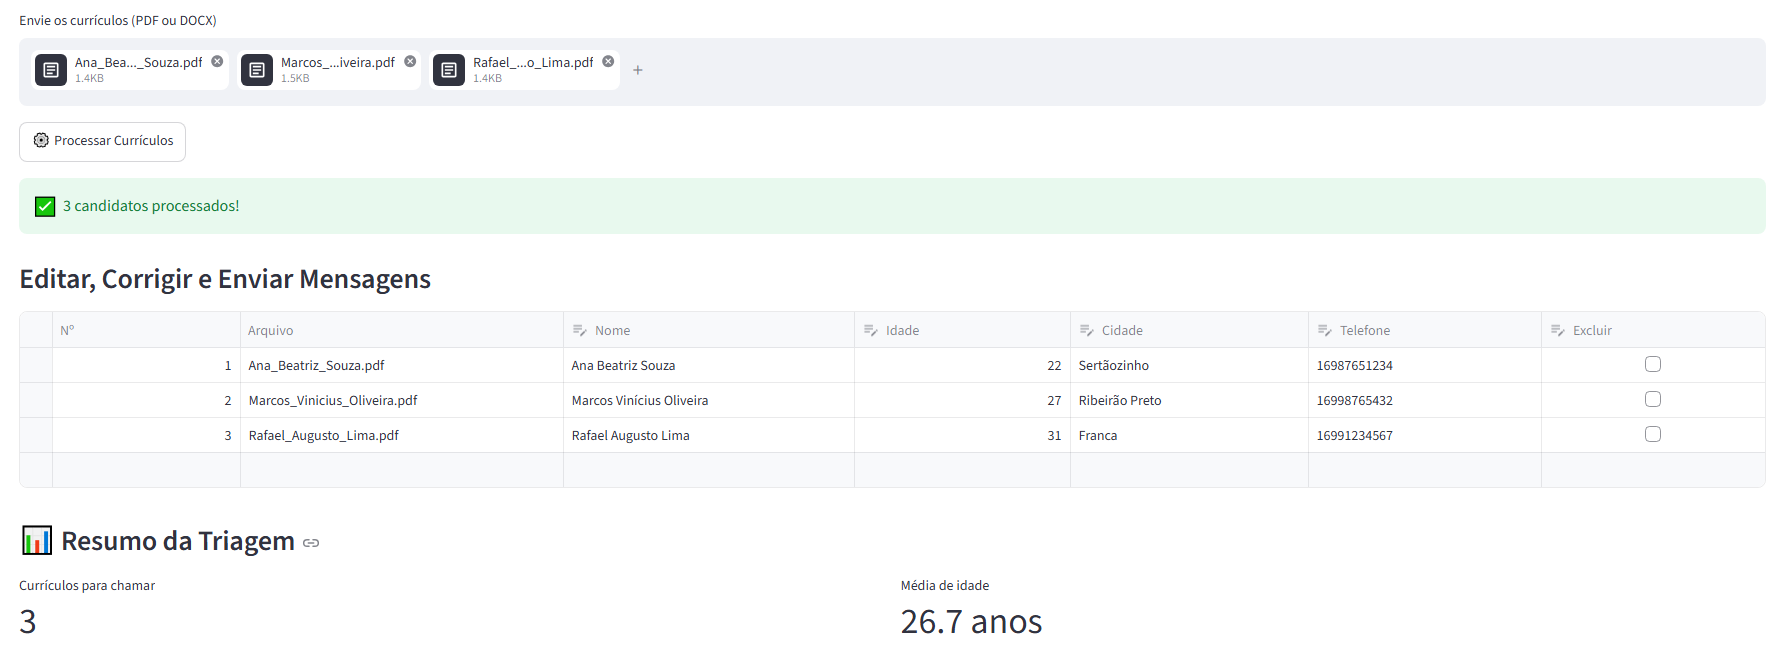
- Parses each resume (PDF and DOCX, including scanned/image resumes via OCR) and sends the text to Claude Haiku, which extracts name, age, city and phone number as structured JSON — with a regex/heuristic fallback if the API is unavailable
- Surfaces everything in a Streamlit review table where I can correct any field before anything gets sent
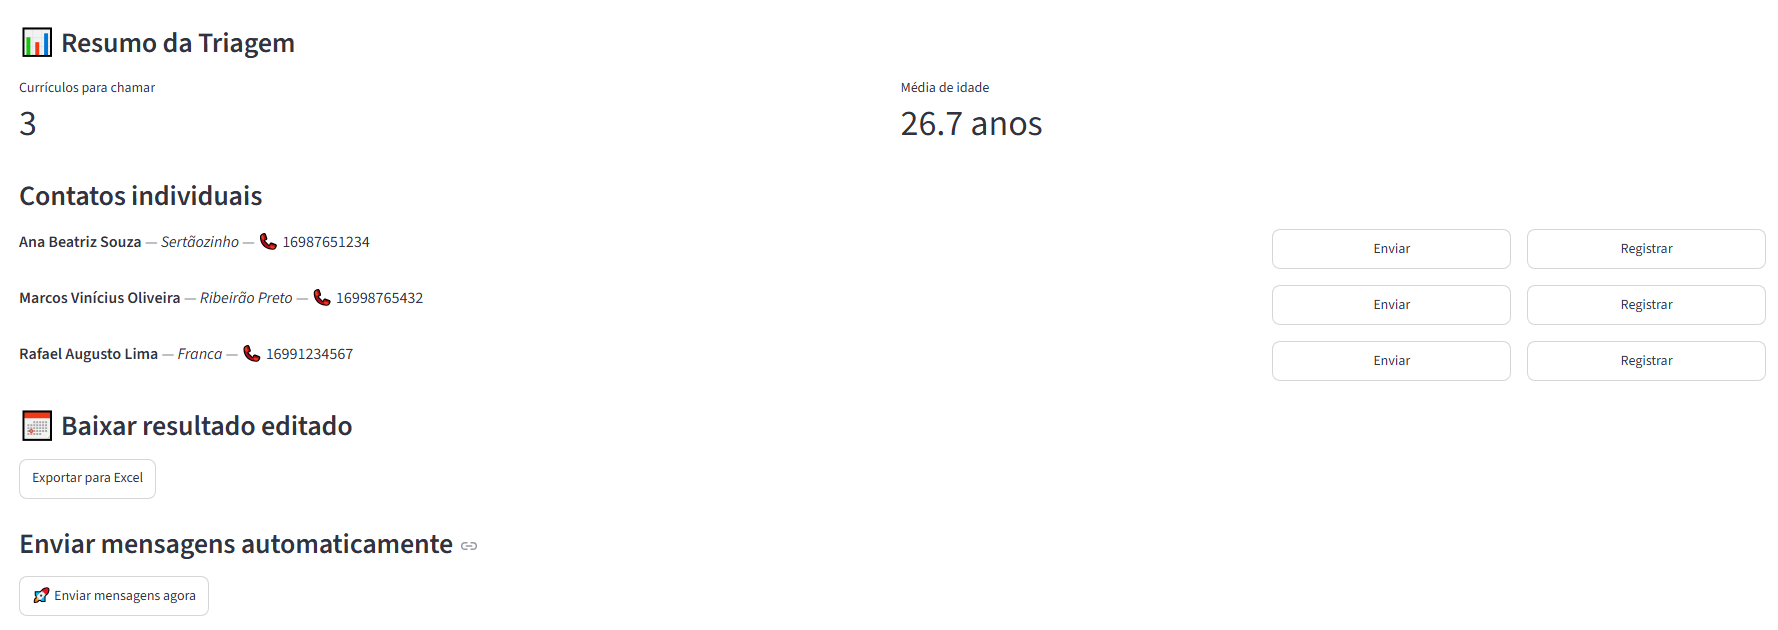
- Sends a personalized WhatsApp invite to every selected candidate in one click, through a self-hosted WhatsApp gateway
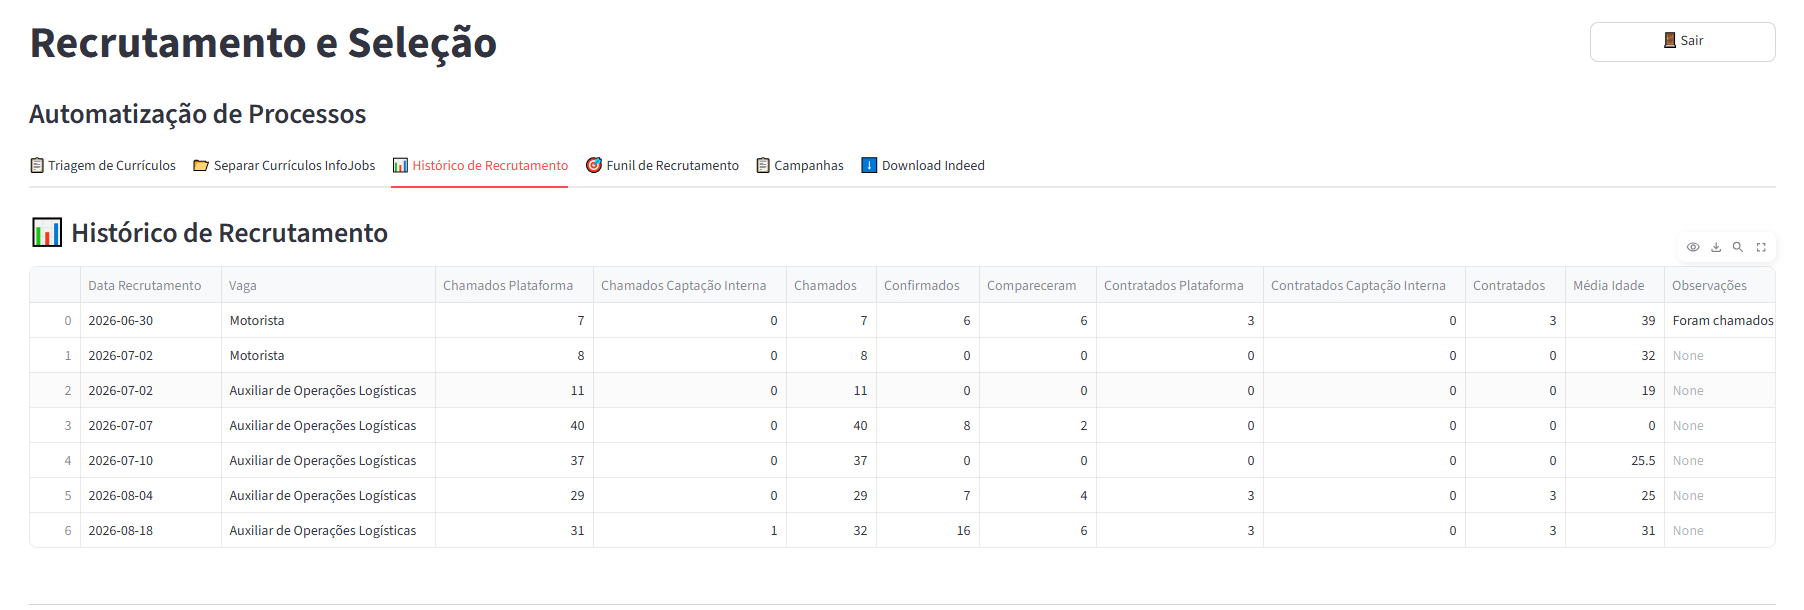
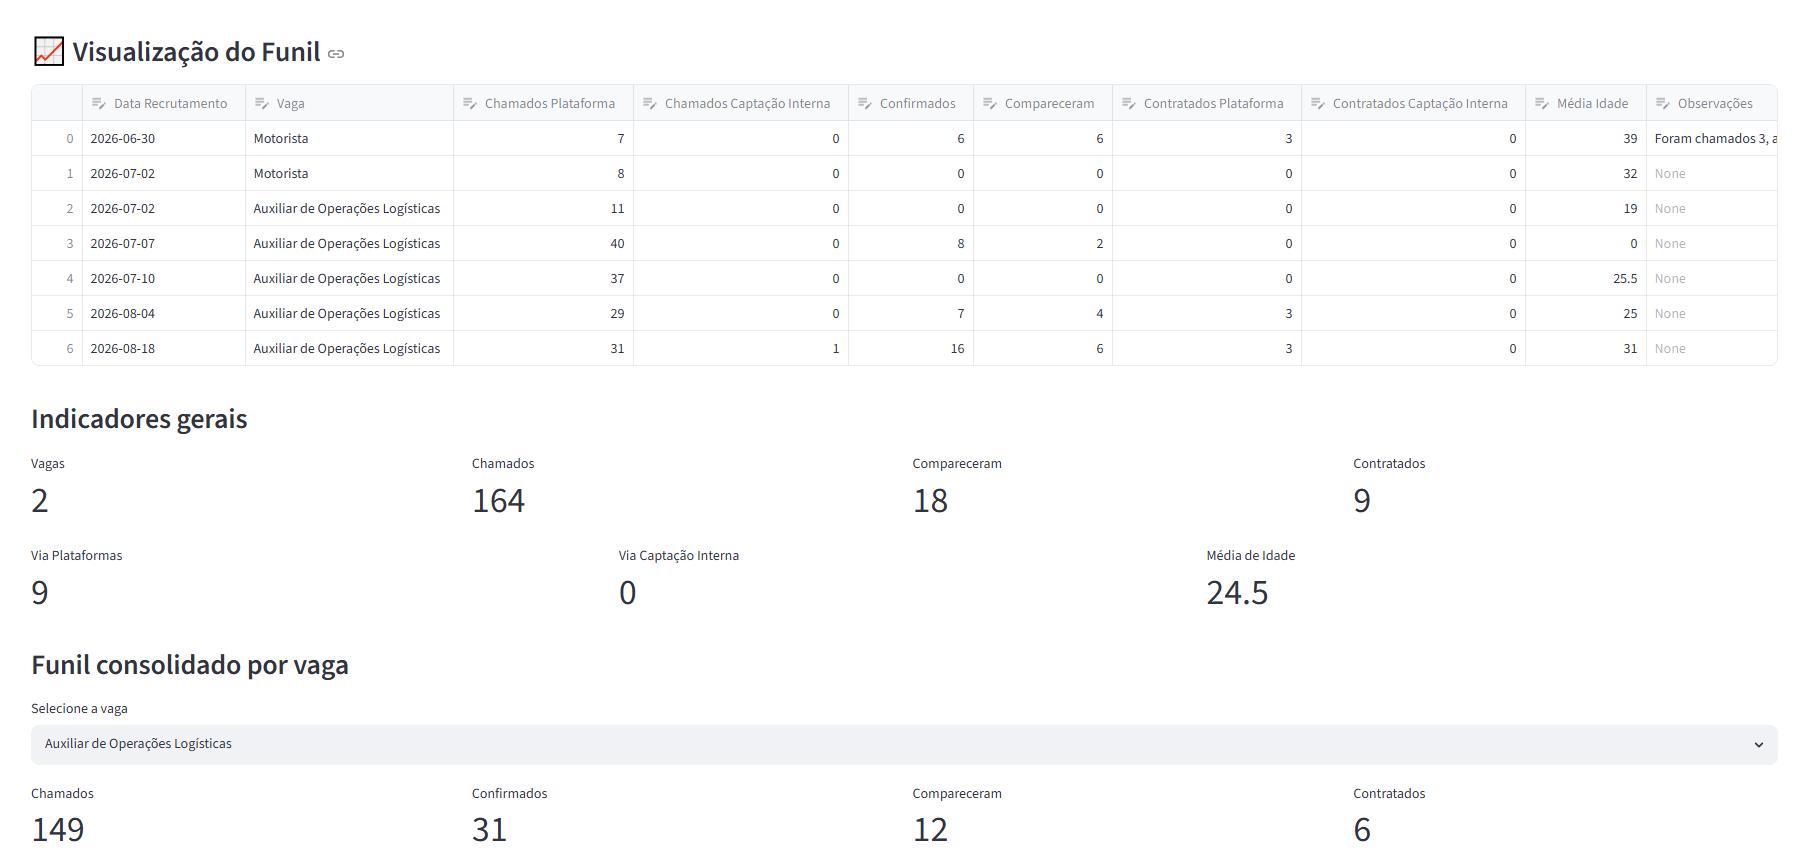
- Tracks every candidate through a recruiting funnel (sent → replied → confirmed → showed up → hired) in a local database, and automatically syncs WhatsApp replies back into that funnel
What used to take 3 hours to schedule interviews with 15 people now takes minutes for 80.
How we built it
- Ingestion (API): Python +
imaplibreading a dedicated Gmail label; BeautifulSoup + regex parse the HTML body (Portuguese and English patterns) to pull the candidate name and the Indeed application URL - Browser automation (API + Cloud): Playwright connects over CDP to a persistent, cookie-authenticated Chrome profile to click through Indeed's employer portal and download resumes — run as an isolated subprocess so Playwright's asyncio loop never collides with Streamlit's own event loop
- Document parsing: PyMuPDF for text extraction, Tesseract OCR fallback for scanned resumes, custom logic to split multi-resume batch files (PDF/DOCX) by header markers
- AI extraction (AI): Anthropic's Claude Haiku model with a tightly constrained prompt (exact-digit copying rules for Brazilian phone numbers, WhatsApp-label preference) returning structured JSON; a rule-based extractor is the fallback path
- Messaging (API + Cloud): A self-hosted, Dockerized Evolution API instance acts as the WhatsApp gateway — no Node bot in between, just HTTP calls from Python — sending personalized bulk invites and later polling for replies
- Data layer: SQLite tracks campaigns and per-candidate funnel status, with de-duplication by phone number and by already-processed resume file
- Deployment (Cloud): The Streamlit app runs on a cloud VPS behind a login screen, redeployed via a script that preserves the production database and processed-file history across releases
Challenges we ran into
- Playwright and Streamlit fight over the same asyncio event loop on Windows — solved by running the whole download flow as a separate subprocess and streaming its progress back over stdout
- Indeed sessions expire; built a one-click cookie-refresh flow using a debug Chrome instance instead of re-logging in from scratch every time
- LLMs are great at reading resumes but not always trustworthy on exact digits — the prompt explicitly forbids the model from "fixing" phone numbers, and a regex validator double-checks every LLM-extracted number against real Brazilian DDD/format rules before it's trusted
- Multi-resume batch PDFs and DOCX files (common with some job boards) needed custom splitting logic before they could be parsed individually
Accomplishments that we're proud of
Real, daily production use — not a demo. It has processed hundreds of real candidates for an actual company's logistics/retail hiring, cutting a 3-hour manual process for 15 candidates down to a few minutes for 80, with a full audit trail of every invite sent and every response received.
What we learned
Combining a small, fast LLM (Claude Haiku) with strict regex validation is far more reliable than trusting either one alone — the model handles the messy natural-language variance in resumes, while deterministic rules catch the one place (phone digits) where a hallucination would actually break something.
What's next for RecrutaFlow
- Extend beyond Indeed to other job boards (LinkedIn, InfoJobs, Catho)
- Auto-schedule interview slots directly from WhatsApp replies
- A recruiter-facing analytics dashboard over the existing funnel data
- Multi-tenant support so other small businesses can plug in their own Gmail/WhatsApp accounts

Log in or sign up for Devpost to join the conversation.