-
-
RecruitFlow AI an autonomous recruitment agent that reasons, verifies evidence, and keeps recruiters in control.
-
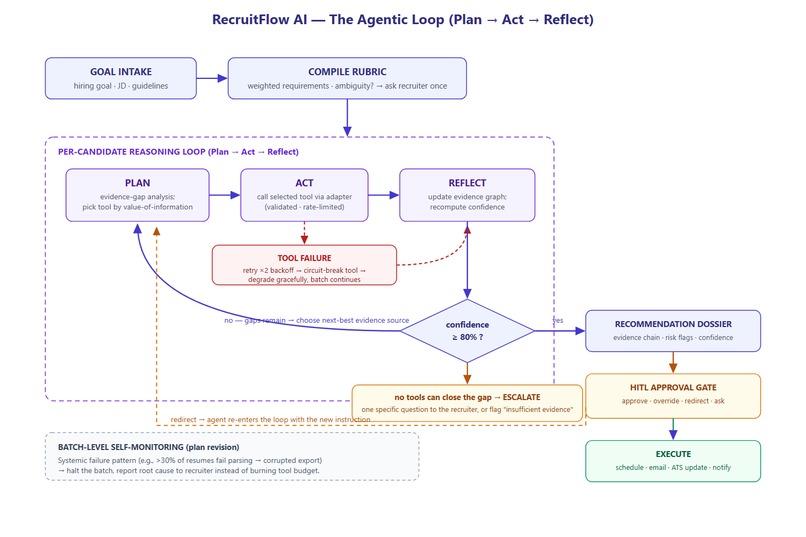
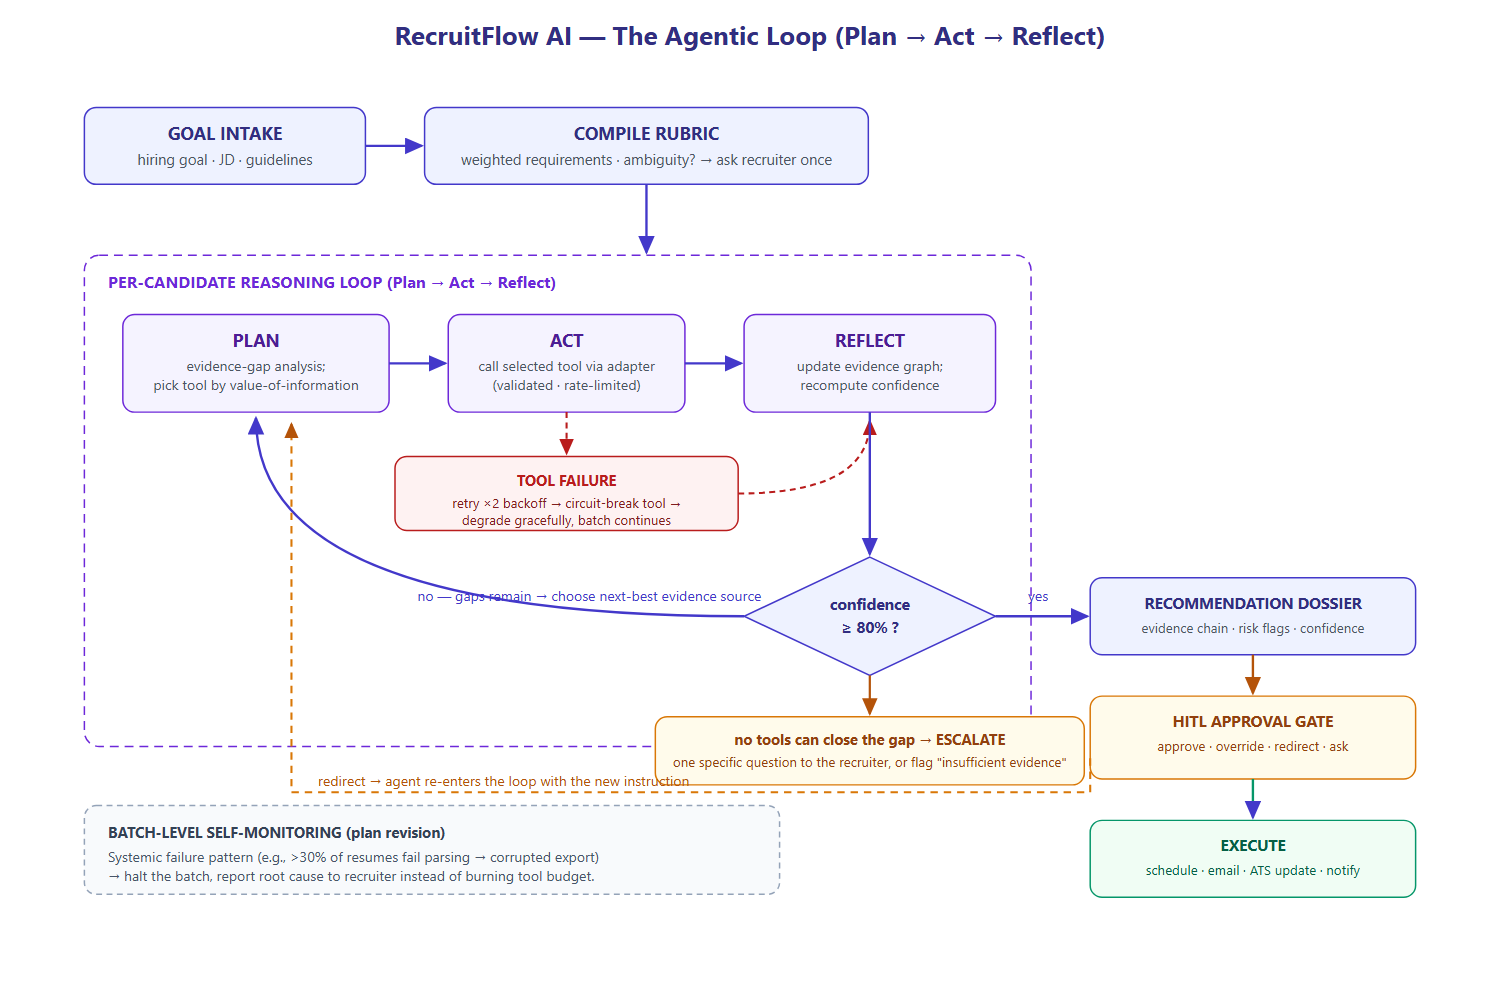
The agentic loop: Plan → Act → Reflect. Tool choice and next steps are decided per-candidate, not scripted.
-
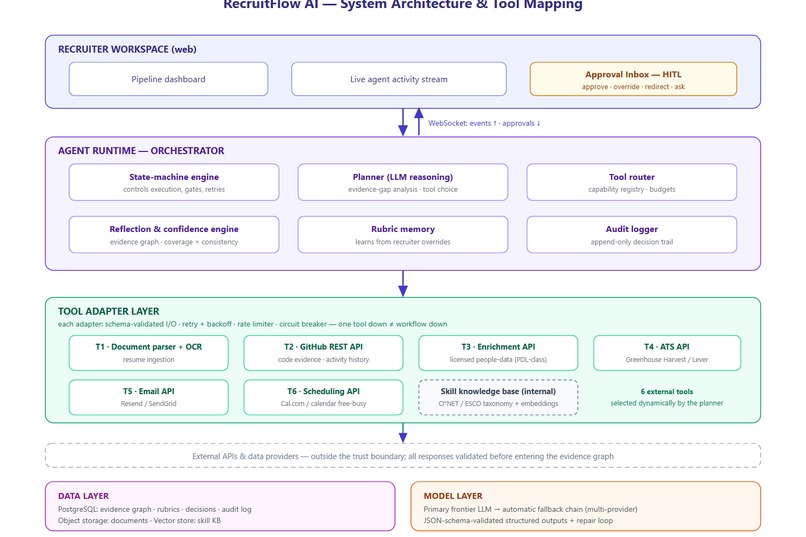
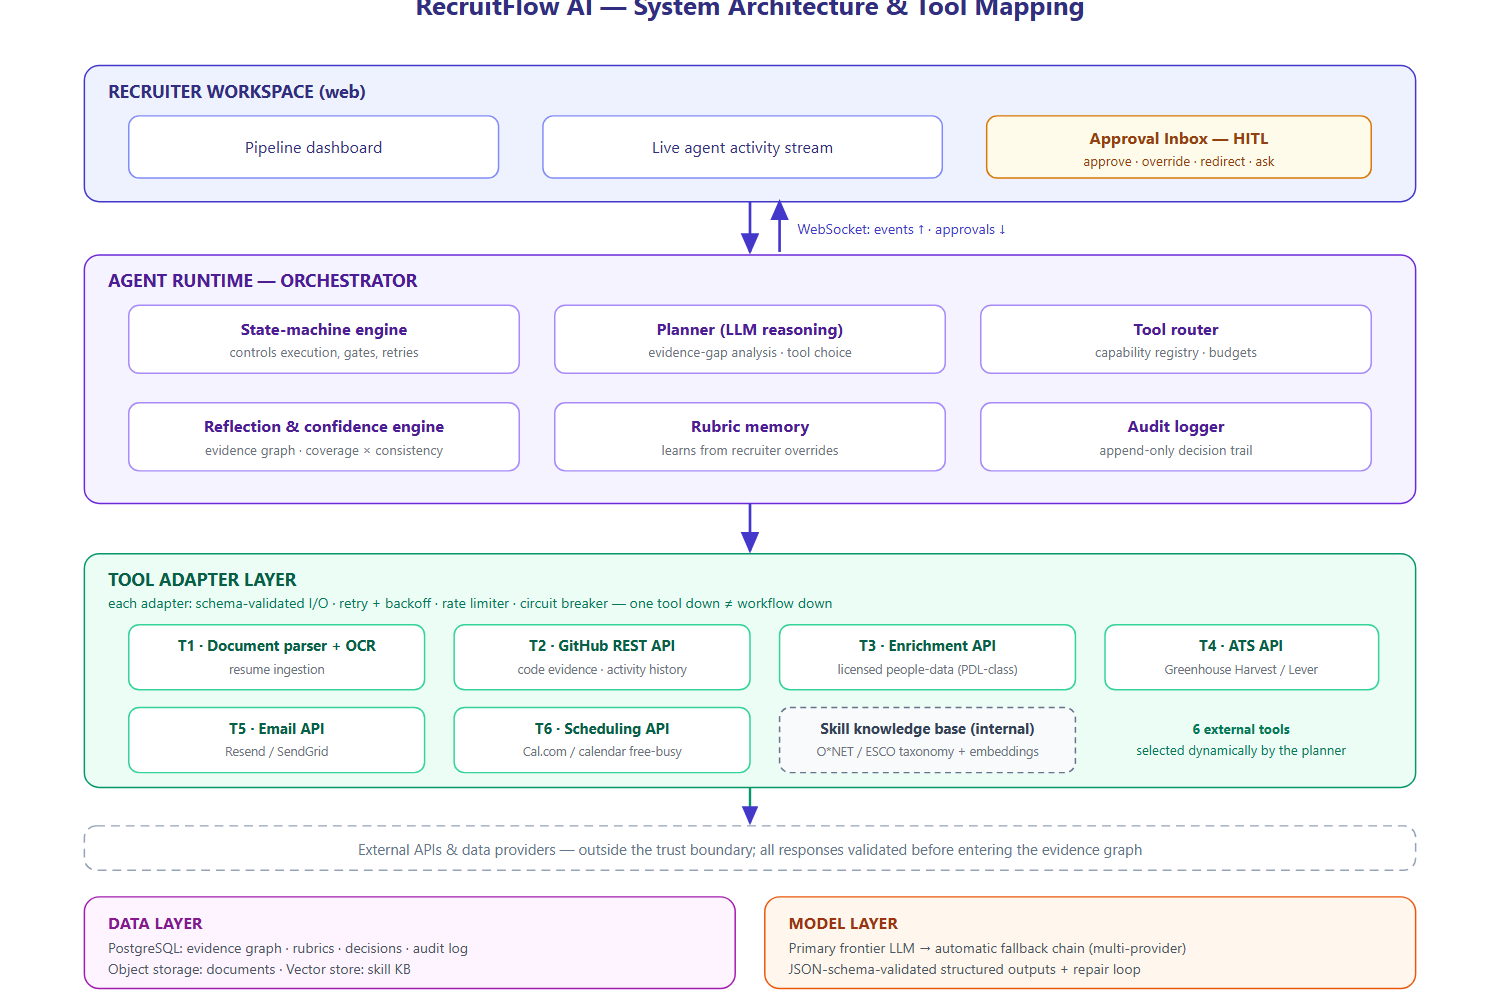
System architecture: 6 external tools behind failure-tolerant adapters, orchestrated by a state-machine agent.
-
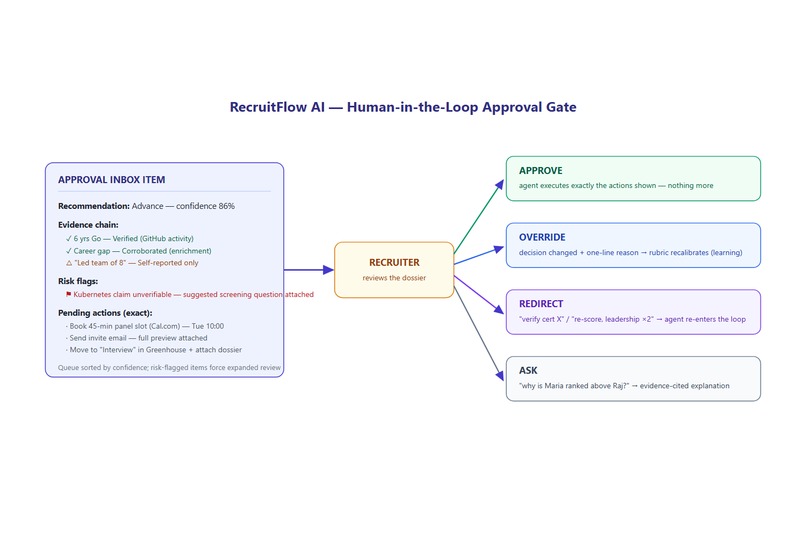
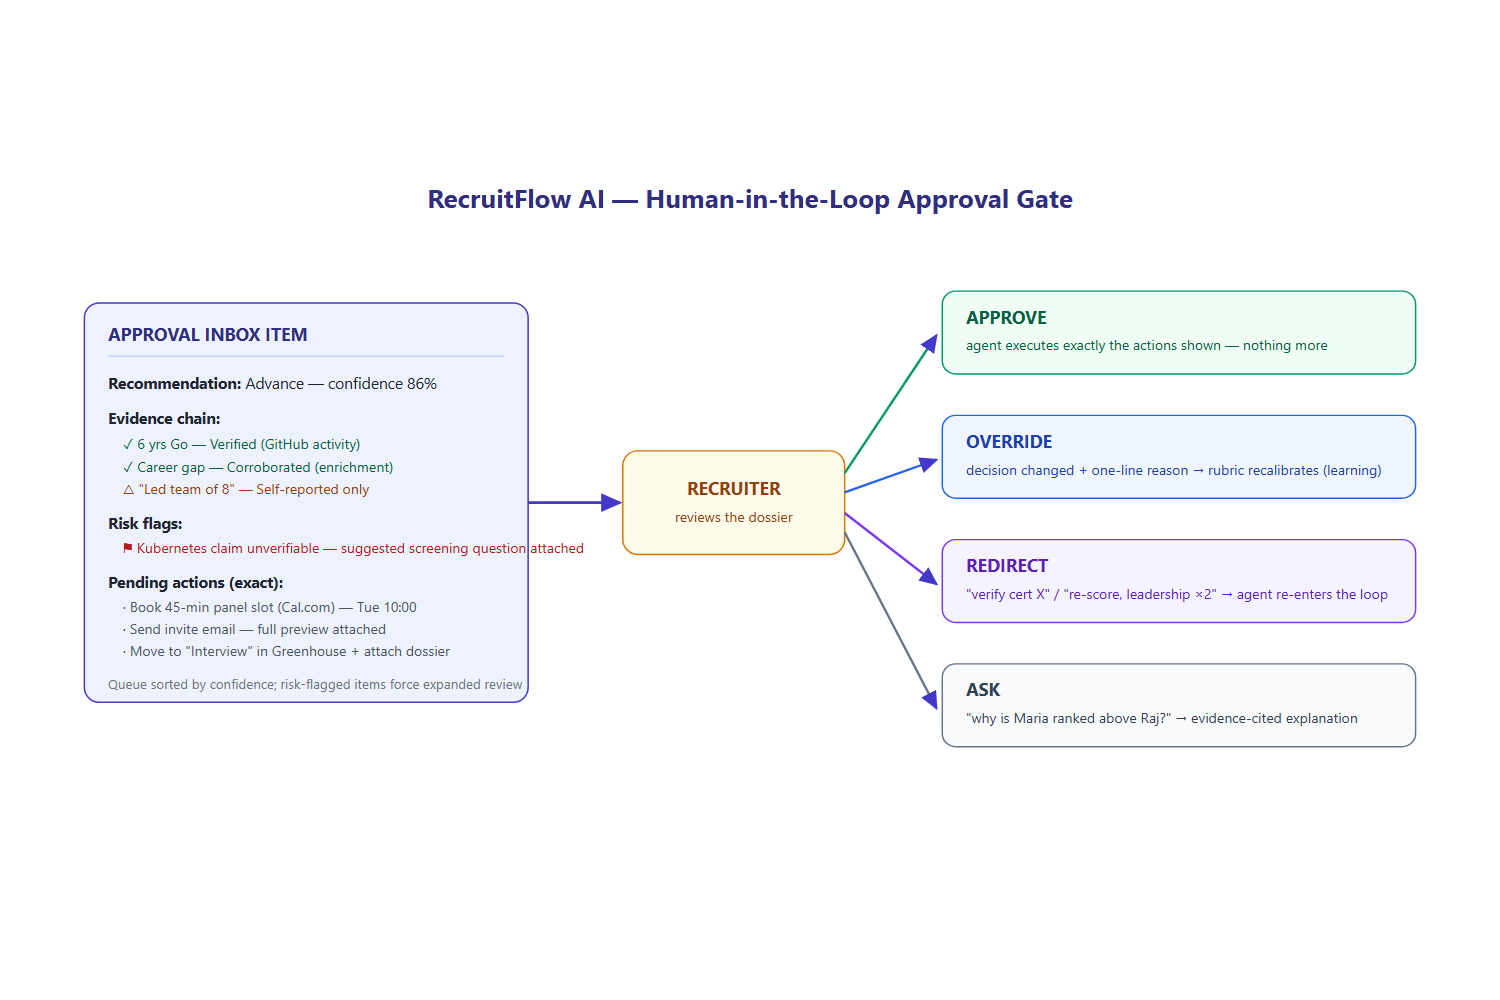
Human-in-the-loop: Approve, Override, Redirect, or Ask nothing external executes without recruiter approval.
Inspiration
A corporate job opening attracts ~250 applications, and eye-tracking research shows recruiters spend about 7 seconds on the first scan of each resume. Worse: in Harvard Business School's Hidden Workers study, 88% of executives admitted their automated screening filters out qualified candidates — because ATS keyword filters can't see that "K8s" means Kubernetes or that "led a 4-person platform team" is leadership. Six-figure hiring decisions are made in seconds, on unverified self-reported claims, with weeks lost to scheduling email ping-pong.
We asked: what if screening wasn't a tool a recruiter operates, but a colleague who does the work — and checks in before anything that matters?
What it does
RecruitFlow AI is an AI employee for recruiting teams, not another screening tool. Given a hiring goal, it:
- Compiles the job description into a weighted rubric — and if the JD contradicts itself ("Senior" but "2+ years required"), it asks the recruiter one targeted question and remembers the answer.
- Screens every applicant with a Plan → Act → Reflect loop. For each candidate it computes evidence gaps and dynamically decides which external tools to consult: GitHub for engineers with a profile, licensed enrichment data when work history is gapped, portfolio analysis for designers. No two candidates take the same path — tool selection is part of the reasoning, not a fixed pipeline.
- Verifies claims instead of trusting them. Every claim in the evidence graph is labeled Verified / Corroborated / Self-reported / Contradicted. "5 years of React" against a GitHub history that started 14 months ago becomes a cited risk flag — never a silent auto-reject.
- Scores with an explicit confidence model. Below 80% confidence, it doesn't guess — it either gathers more evidence or routes the candidate to an adaptive AI interview targeting exactly the gaps that are unresolved.
- Runs an adaptive AI interview when evidence is thin. The interview isn't a generic question bank — topics are planned from that candidate's specific evidence gaps, questions are asked one at a time (voice or text), vague answers get a probing follow-up, and the transcript is evaluated back into the evidence graph as corroborated or contradicted claims — which re-scores the candidate automatically.
- Pauses at a genuine human control point. The Approval Inbox shows the recommendation, the full evidence chain, risk flags, and the exact pending actions (email preview, calendar slot, ATS stage move). The recruiter can Approve, Override (with a reason the agent learns from), Redirect ("re-score with leadership weighted double"), or Ask ("why is Maria ranked above Raj?").
- Then executes: books the interview, sends the email, updates the ATS, notifies the hiring manager — idempotently, with a full audit trail.
Our operating principle: automate the reading, gate the acting.
How we built it
We designed the agent as a goal-driven state machine, not a prompt chain: the LLM provides judgment inside each state, while the state machine controls execution, retries, and approval gates. The architecture is modular and failure-tolerant — six external tools (document parsing, GitHub REST API, a licensed people-data enrichment API, ATS APIs, email, scheduling) each sit behind an isolated adapter with schema-validated I/O, retry with exponential backoff, rate limiting, and a circuit breaker. Structured LLM outputs are zod-validated with a repair loop, so a malformed model response never corrupts the evidence graph.
We didn't stop at the design — we built it. A working full-stack implementation exists today: the state machine, all six tool adapters (GitHub verification tested live against real profiles), the confidence engine, the recruiter dashboard with a live agent activity stream, the Approval Inbox with all four verbs, and — going beyond the original plan — an adaptive AI interview room: the agent asks each question aloud, the candidate answers by voice with live transcription, and the transcript feeds back into the evidence graph for re-scoring. Phase 2 isn't a plan anymore — it's hardening what already runs.
Challenges we ran into
- Avoiding the "linear script" trap. Our first workflow draft was a fixed pipeline. We redesigned it around evidence-gap analysis with a value-of-information heuristic, so the agent genuinely decides what to do next per candidate — and can loop, escalate, or halt a batch when it detects a systemic failure pattern (e.g., >30% parse failures = corrupted export, not 75 bad resumes).
- LinkedIn has no public profile API. Instead of pretending (or scraping against ToS), we designed around licensed enrichment providers and GitHub as the primary verification source — which turned a limitation into a compliance feature.
- Making HITL real, not theater. An "approve" button that people click blindly is not oversight. We added Override-with-reason (which recalibrates the rubric — the agent learns each company's hiring taste), Redirect, and evidence-cited Ask, and we refused to add "auto-approve after timeout."
- Keeping the AI interview honest. An interview can corroborate a claim, but it should never be treated as full verification — and we had to explicitly guard against scoring an honest "I haven't done that" as a contradiction just because it wasn't in the candidate's favor.
Accomplishments that we're proud of
- A reasoning design where the tool sequence is chosen at runtime from evidence gaps — demonstrably not a chatbot and not a script.
- It actually runs. Not a mockup: a real candidate was screened end-to-end in testing — resume parsed, GitHub claims verified live, confidence scored, routed to an AI interview when evidence was thin, and the interview's own evidence corroborated the resume and raised confidence automatically. The whole loop — screen → interview → re-score → approve → execute — works today.
- A fairness and compliance posture by design: evidence-only scoring, no inference of protected attributes, human approval on every adverse action, and an append-only audit trail — hiring AI is a high-risk category under the EU AI Act, and we treat that as a purchasing requirement, not fine print.
- An ROI story we can defend: ~25 recruiter-hours per requisition today → ~2 hours, with verification that currently never happens at all.
What we learned
- The hard part of autonomous agents isn't calling tools — it's knowing when not to (value-of-information), admitting uncertainty (confidence gating, "insufficient evidence" flags), and placing the human gate where judgment adds the most value per second.
- Error recovery has to be structural (adapters, circuit breakers, idempotency keys), not prompt-level wishful thinking.
- An interview should corroborate, never fully verify — and admitting the absence of something the resume never claimed (like open-source work) must never be scored as a contradiction. Getting that distinction wrong would silently punish honest candidates.
What's next for RecruitFlow AI — Autonomous Recruitment Agent
Phase 2 is hardening and going live: real credentials (email sending, calendar booking, employment-history verification) in place of today's dry-run/graceful-degrade mode, ATS sandbox integration, authentication and multi-tenancy, a production database and cloud deployment, and rubric weight-learning from recruiter overrides — the signal is already captured today; the learning loop is next. Long-term: distribution through ATS marketplaces.
Built With
- anthropic-claude
- cal.com
- docker
- fastify
- github-api
- greenhouse
- lever
- node.js
- openai
- pgvector
- postgresql
- react
- resend
- sendgrid
- typescript
- vite
- websockets
- zod


Log in or sign up for Devpost to join the conversation.