Inspiration
What it does
How I built it
Challenges I ran into
Accomplishments that I'm proud of
What I learned
What's next for qwen3 omni net
Inspiration
The future of AI lies in truly understanding and processing multiple modalities simultaneously - not just text, but audio, images, and video in real-time. We were inspired to create the first natively end-to-end omni-modal AI that can seamlessly switch between different input types while maintaining ultra-low latency for practical applications.
What it does
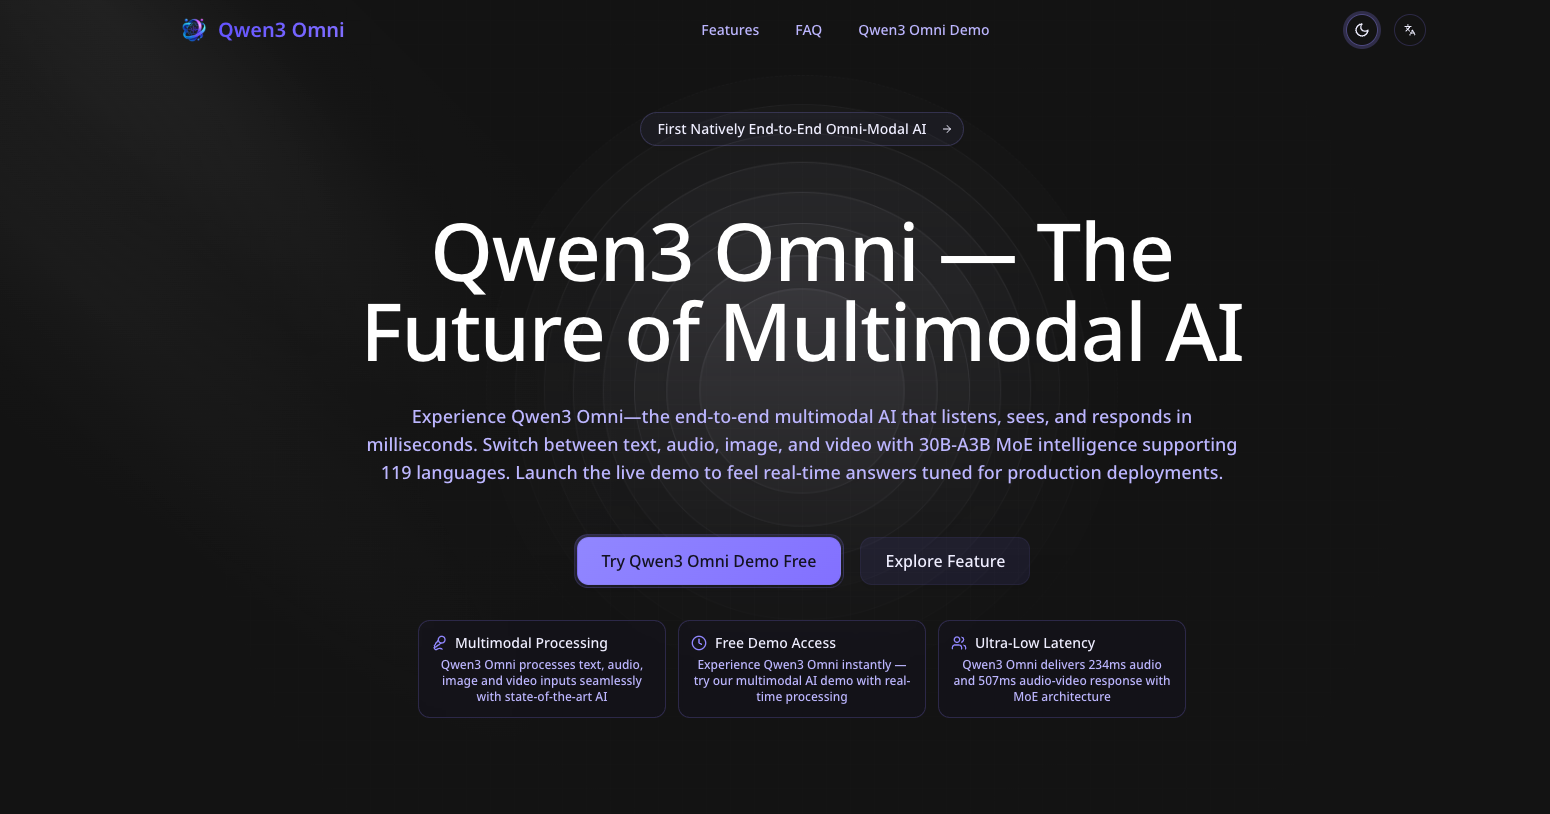
Qwen3 Omni is a revolutionary multimodal AI that processes text, audio, image, and video inputs simultaneously with state-of-the-art performance. Key capabilities include:
- Real-time multimodal processing with 234ms audio response and 507ms audio-video latency
- Multi-language support for 119 text languages and 19 speech languages
- End-to-end architecture enabling seamless transitions between modalities
- Production-ready deployment with comprehensive benchmarks and documentation
How we built it
The project leverages cutting-edge Mixture-of-Experts (MoE) architecture with:
- 30B total parameters with 3B activated parameters for efficient processing
- TMRoPE position embedding for synchronized timestamp handling across modalities
- Advanced neural architecture optimized for real-time inference
- PyTorch and CUDA implementation for high-performance computing
- Hugging Face integration for easy deployment and community access
Challenges we ran into
- Multimodal synchronization: Maintaining temporal alignment across different input types
- Latency optimization: Achieving sub-300ms response times without quality degradation
- Architecture complexity: Balancing model size with inference speed using MoE techniques
- Cross-modal understanding: Ensuring consistent interpretation across text, audio, and visual inputs
Accomplishments that we're proud of
- SOTA performance: Achieving state-of-the-art results on 22/36 benchmark tests
- Ultra-low latency: 234ms audio and 507ms audio-video response times
- Open source impact: Released under Apache 2.0 license on Hugging Face
- Real-world deployment: Production-ready with comprehensive documentation and examples
What we learned
- True multimodal AI requires fundamental architectural innovations beyond simple concatenation
- End-to-end training is crucial for achieving seamless cross-modal understanding
- MoE architecture provides the optimal balance between capability and efficiency
- Community-driven development accelerates AI innovation and adoption
What's next for Qwen3 Omni
- Extended modality support: Adding support for additional input types
- Performance optimization: Further reducing latency while expanding capabilities
- Community ecosystem: Building tools and integrations for developers
- Research advancement: Pushing the boundaries of multimodal AI understanding
Visit qwen3omni.net to experience the live demo and explore comprehensive documentation, benchmarks, and deployment guides.

