-
4
-
1
-
2
-
3
QueryMind AI – Intelligent Research Assistant
💡 Inspiration
In today's digital world, people work with large amounts of information stored in PDF files, documents, reports, and databases. Finding specific information from these resources manually can be time-consuming and frustrating.
We wanted to solve this problem by creating an intelligent assistant that allows users to interact with their documents using natural language.
This idea inspired us to build QueryMind AI, an AI-powered research assistant that combines IBM Db2 with Retrieval-Augmented Generation (RAG) to make information retrieval smarter, faster, and more accessible.
Our vision is simple: Instead of searching through hundreds of pages, users should be able to ask a question and receive a meaningful answer based on their documents.
🎯 What It Does
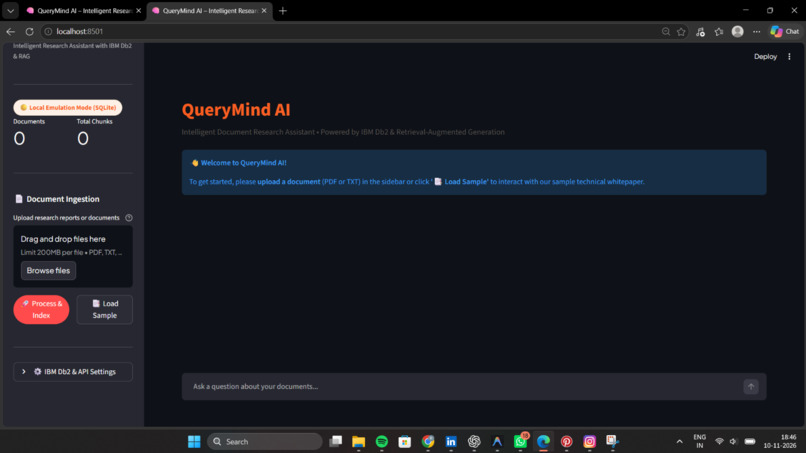
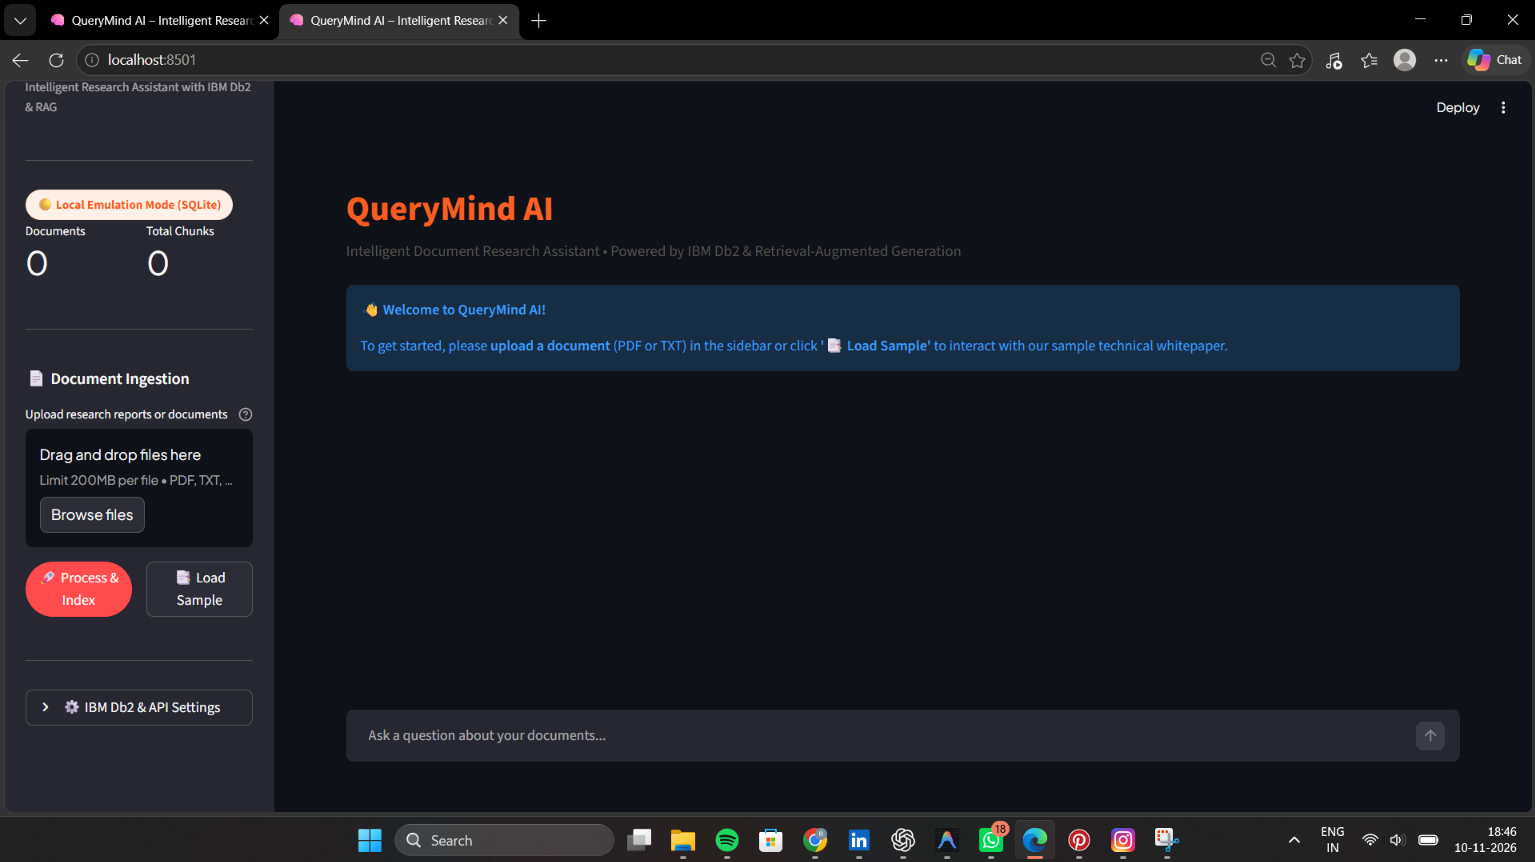
QueryMind AI is designed to help users understand and retrieve information from their documents through an AI-powered conversational interface.
Key features include:
- Document Understanding: Upload and process documents such as PDFs and text files.
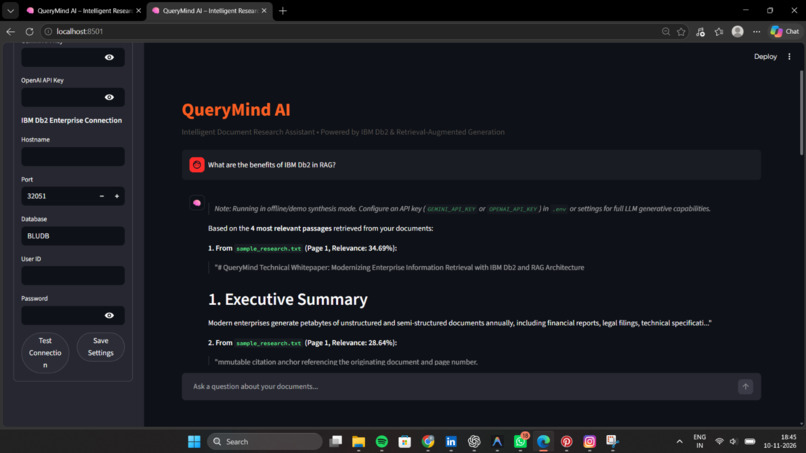
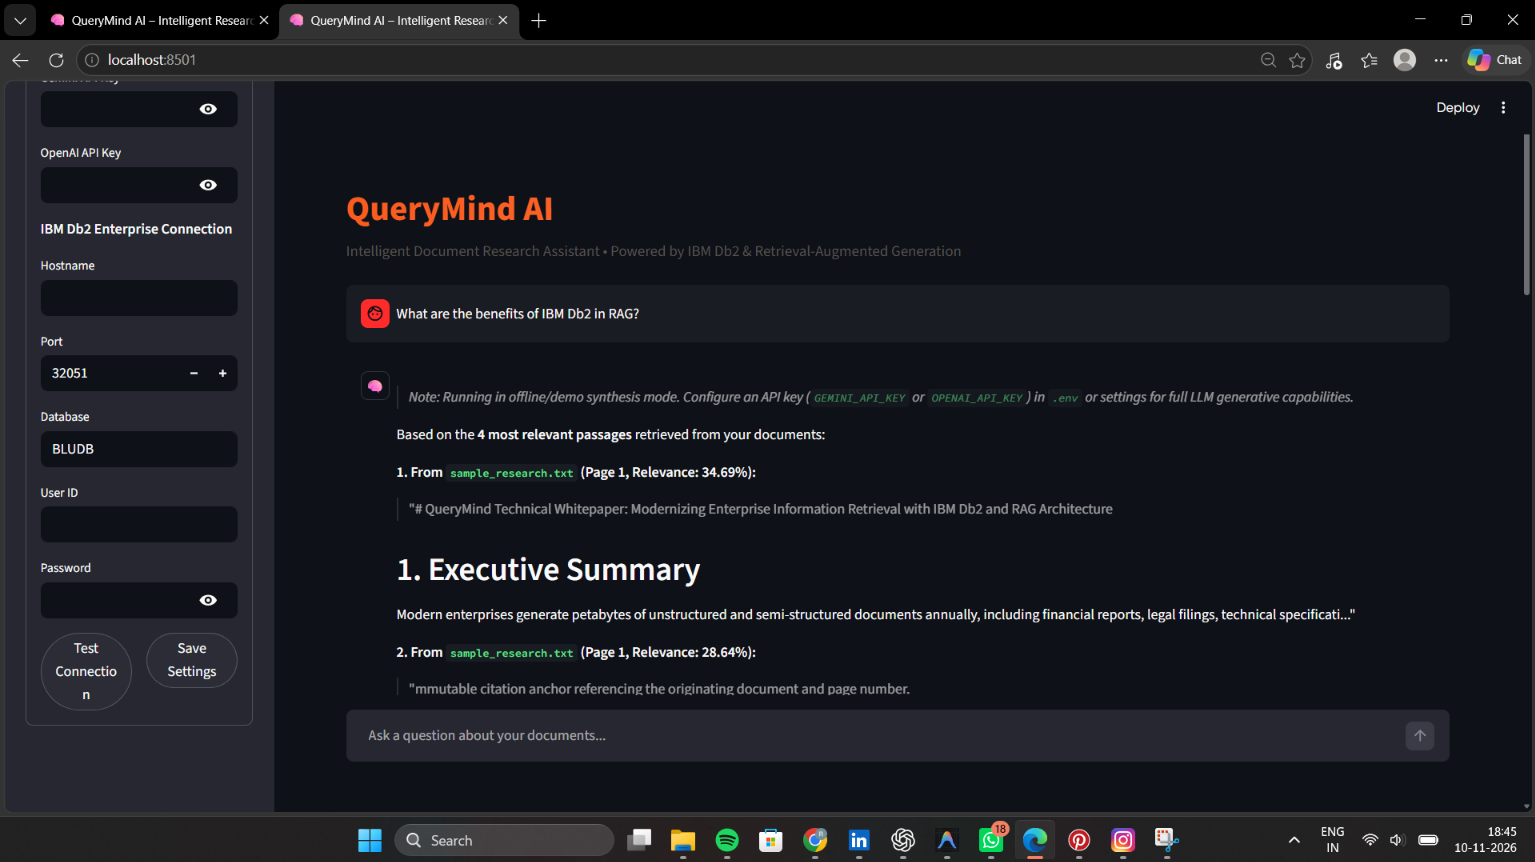
- Intelligent Question Answering: Ask questions in natural language and receive context-aware responses.
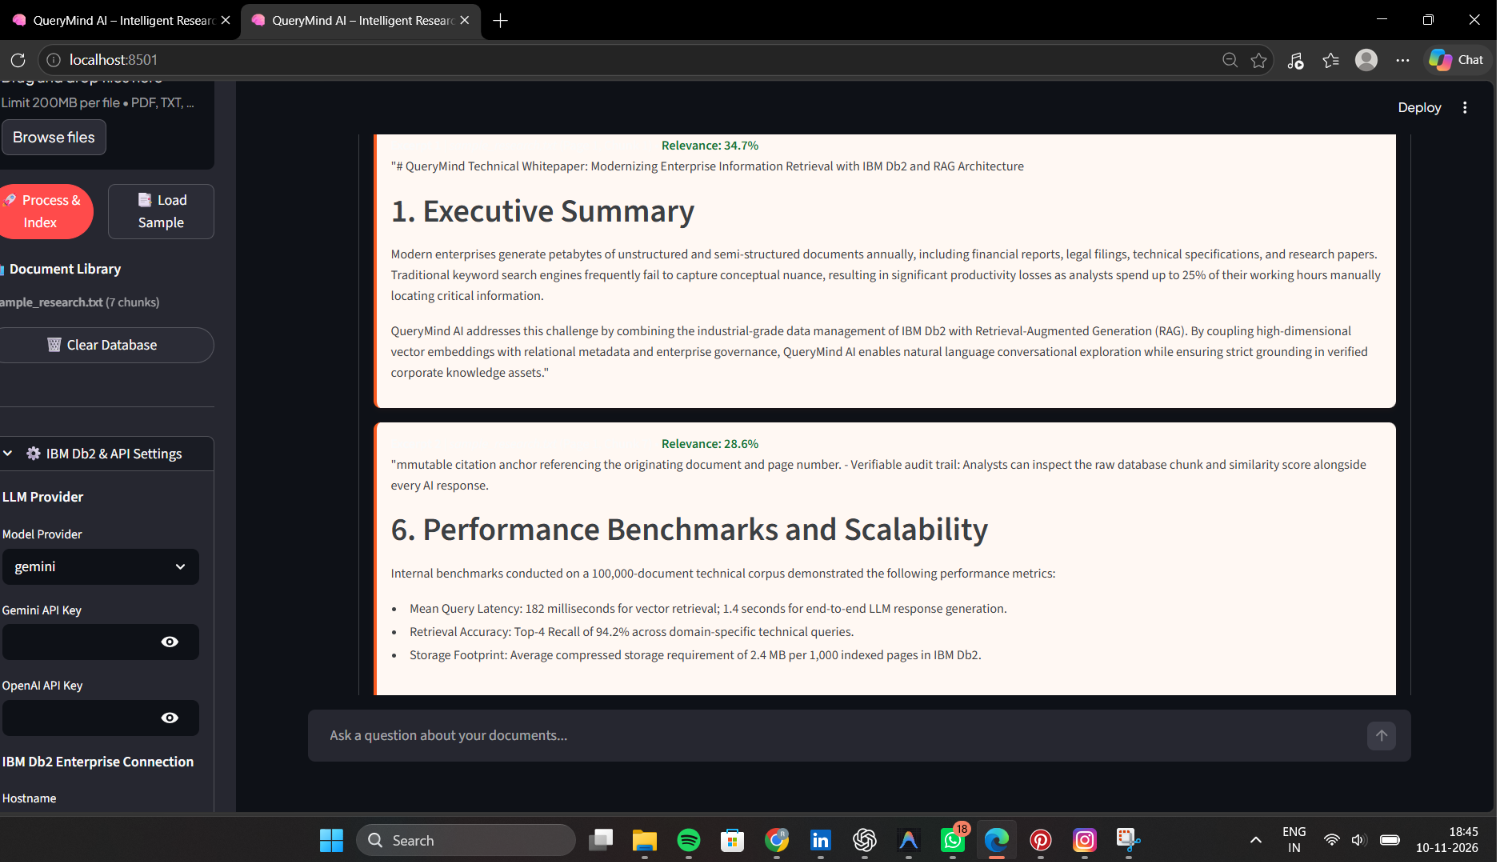
- Retrieval-Augmented Generation (RAG): Retrieve relevant document information before generating answers.
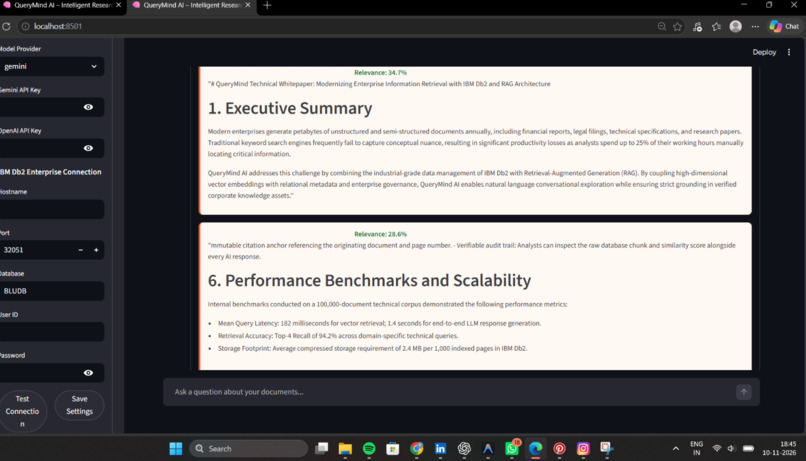
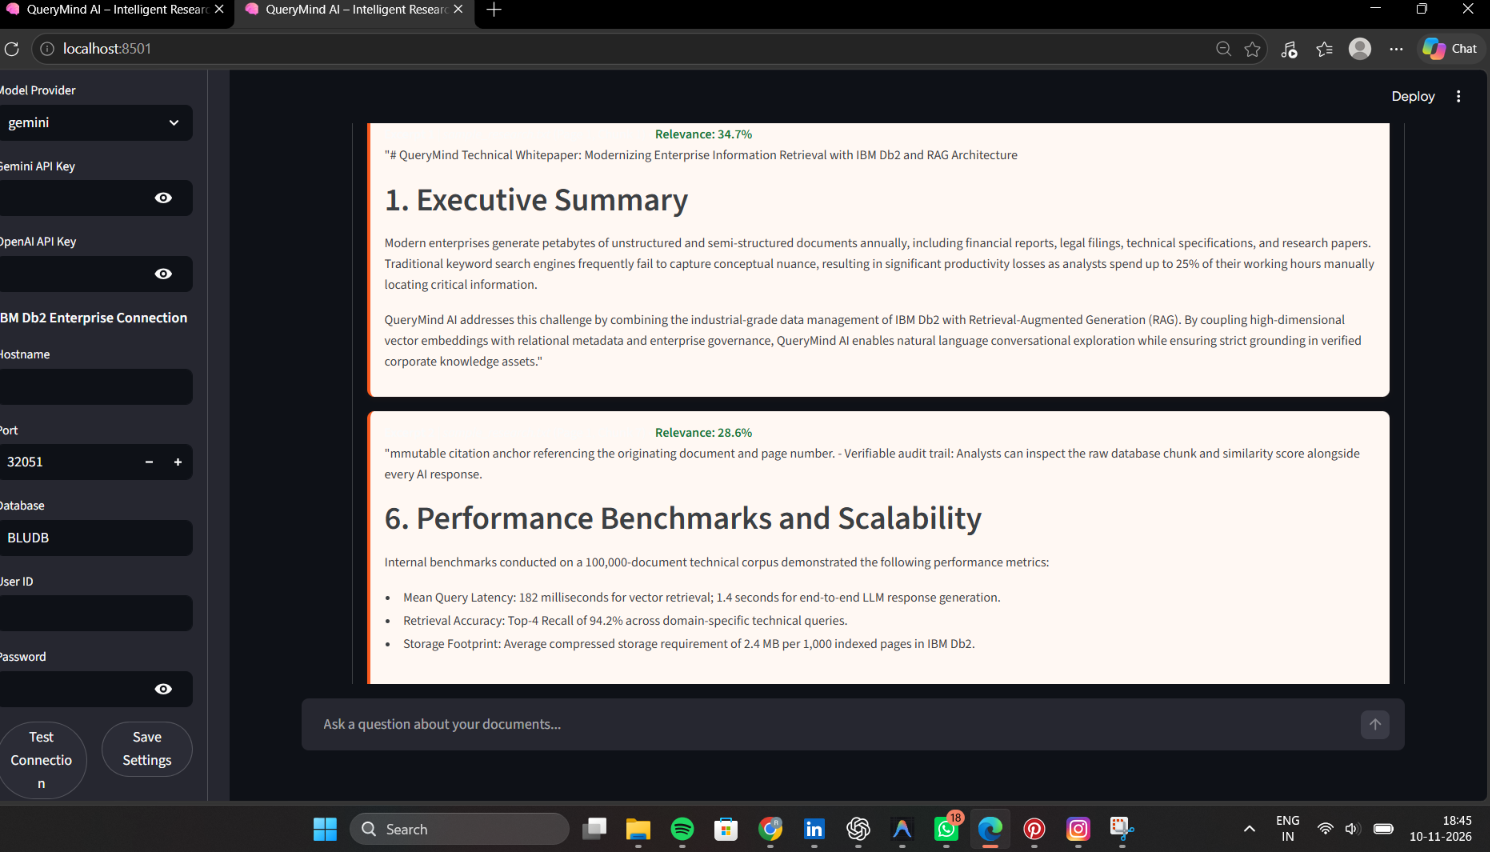
- IBM Db2 Integration: Use IBM Db2 as the database foundation for storing and retrieving application data and supporting intelligent information retrieval.
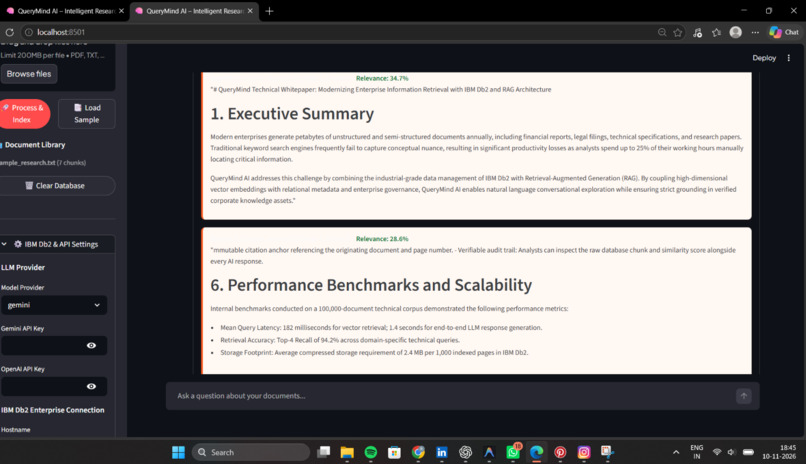
- Vector Search: Find semantically relevant information rather than relying only on exact keyword matches.
- Conversational Interface: Interact with documents through a simple chat-based experience.
⚙️ How We Built It
QueryMind AI is designed around a modular architecture that connects document processing, database storage, information retrieval, and AI-generated responses.
Our planned implementation workflow includes:
- Document Upload: Users upload their documents through the application interface.
- Text Extraction: Extract meaningful text from uploaded documents.
- Text Chunking: Divide large documents into smaller, manageable sections.
- Embedding Generation: Convert text chunks into numerical vector representations.
- IBM Db2 Integration: Store relevant document information and vector representations using IBM Db2 capabilities.
- Semantic Retrieval: Retrieve relevant information based on the user's question.
- AI Response Generation: Use an LLM with LangChain and retrieved context to generate meaningful answers.
- User Interaction: Display the generated response through a conversational interface.
🛠️ Technology Stack
The technologies selected for this project include:
- Programming Language: Python
- Database: IBM Db2
- AI Framework: LangChain
- AI Architecture: Retrieval-Augmented Generation (RAG)
- Search Technology: Vector Search
- Frontend: Streamlit
- LLM Integration: An appropriate LLM API
- Development Tools: Git, GitHub, Jupyter Notebook
📚 What We Learned
Through this project, we aim to gain practical experience in:
- Integrating enterprise databases with modern AI applications.
- Understanding Retrieval-Augmented Generation architecture.
- Working with vector embeddings and semantic search.
- Connecting LLMs with external knowledge sources.
- Building applications using LangChain.
- Developing complete AI-powered applications.
- Understanding the importance of database technology in modern AI systems.
🚧 Challenges
Some of the key technical challenges we are working to address include:
- Connecting IBM Db2 with the AI application architecture.
- Processing documents with different formats and structures.
- Generating meaningful embeddings from document content.
- Retrieving relevant information accurately.
- Reducing irrelevant or unsupported AI-generated responses.
- Maintaining efficient communication between the database, retrieval pipeline, and language model.
We aim to address these challenges through modular development, testing, and continuous improvements.
🌟 Future Scope
QueryMind AI has the potential to evolve into a more advanced enterprise knowledge assistant.
Future improvements could include:
- Multiple document format support.
- Multilingual question answering.
- Source references and citations in generated answers.
- Multi-user document management.
- AI-powered enterprise knowledge search.
- Advanced analytics and intelligent AI agents.
🏆 Our Vision
We believe that information becomes more valuable when people can access and understand it easily.
With QueryMind AI, our goal is to bring together the power of IBM Db2 and Generative AI to transform how people interact with information.
Ask. Retrieve. Understand.
QueryMind AI – Making Knowledge Accessible Through AI.
Built With
- ai-agents
- api-integration
- artificial-intelligence
- chatbot
- cloud
- data-analytics
- database-management
- document-intelligence
- embeddings
- enterprise-ai
- generative-ai
- github
- ibm-db2
- information-retrieval
- langchain
- large-language-models-(llm)
- machine-learning
- natural-language-processing-(nlp)
- python
- retrieval-augmented-generation-(rag)
- semantic-search
- streamlit
- text-processing
- vector-database
- vector-search
