-
-
QuantGate: evidence before deployment
-
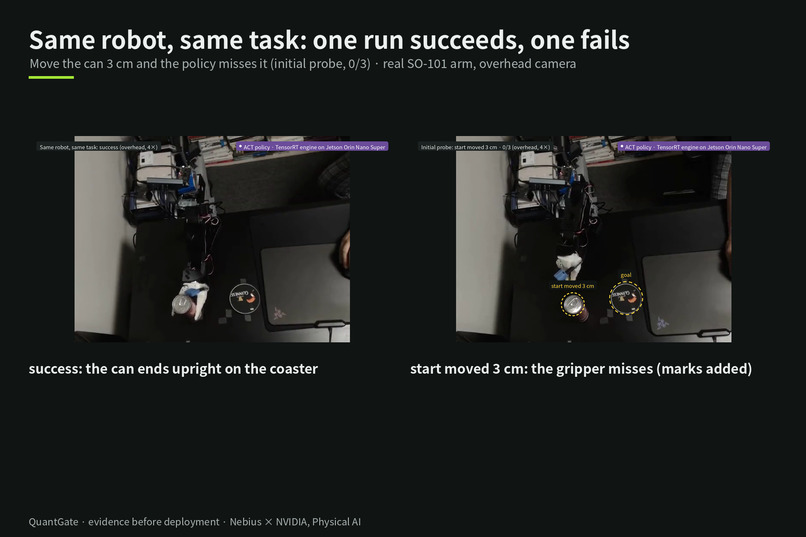
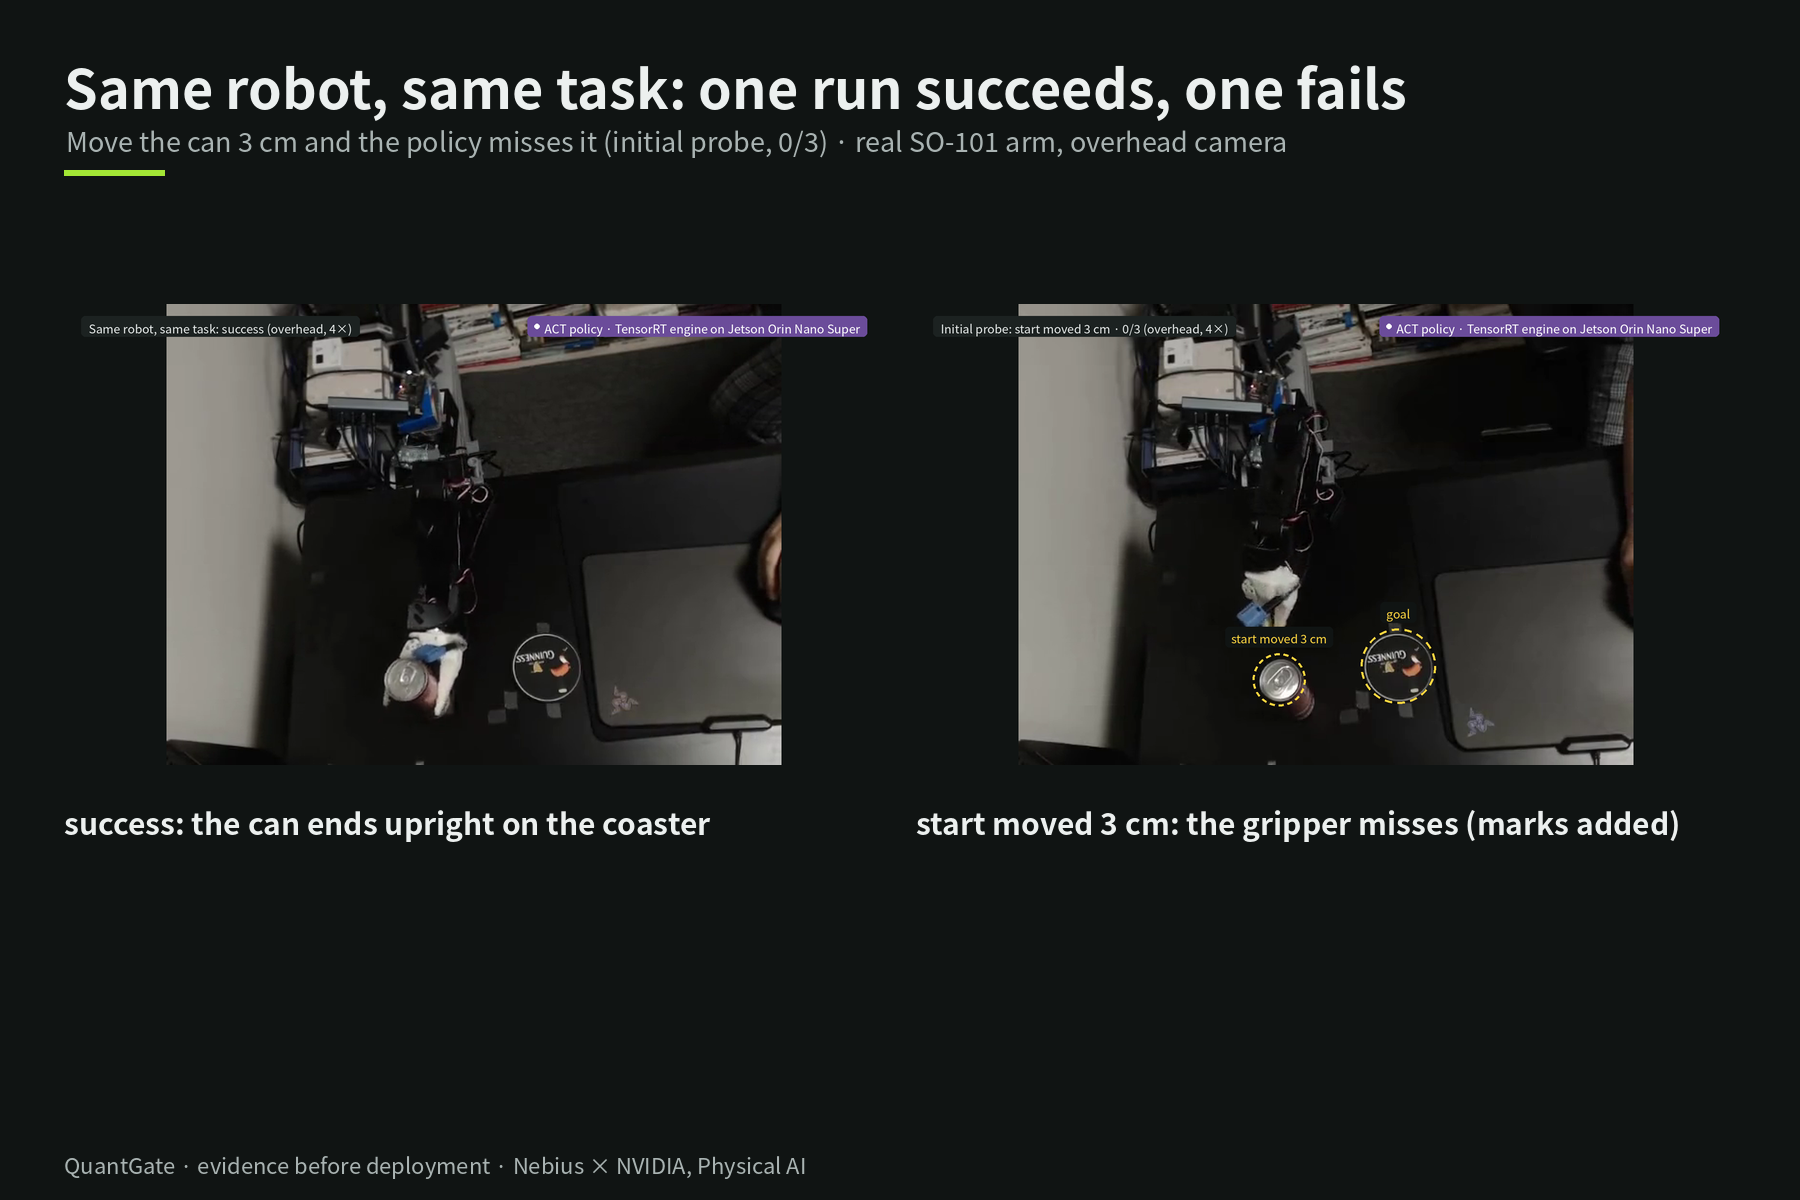
Same robot, same task: one run succeeds, one fails; a 3 cm shift makes it miss
-
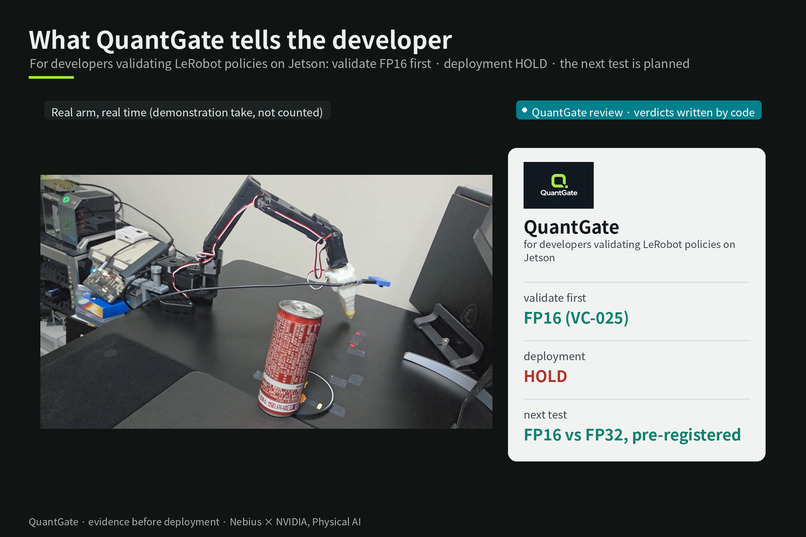
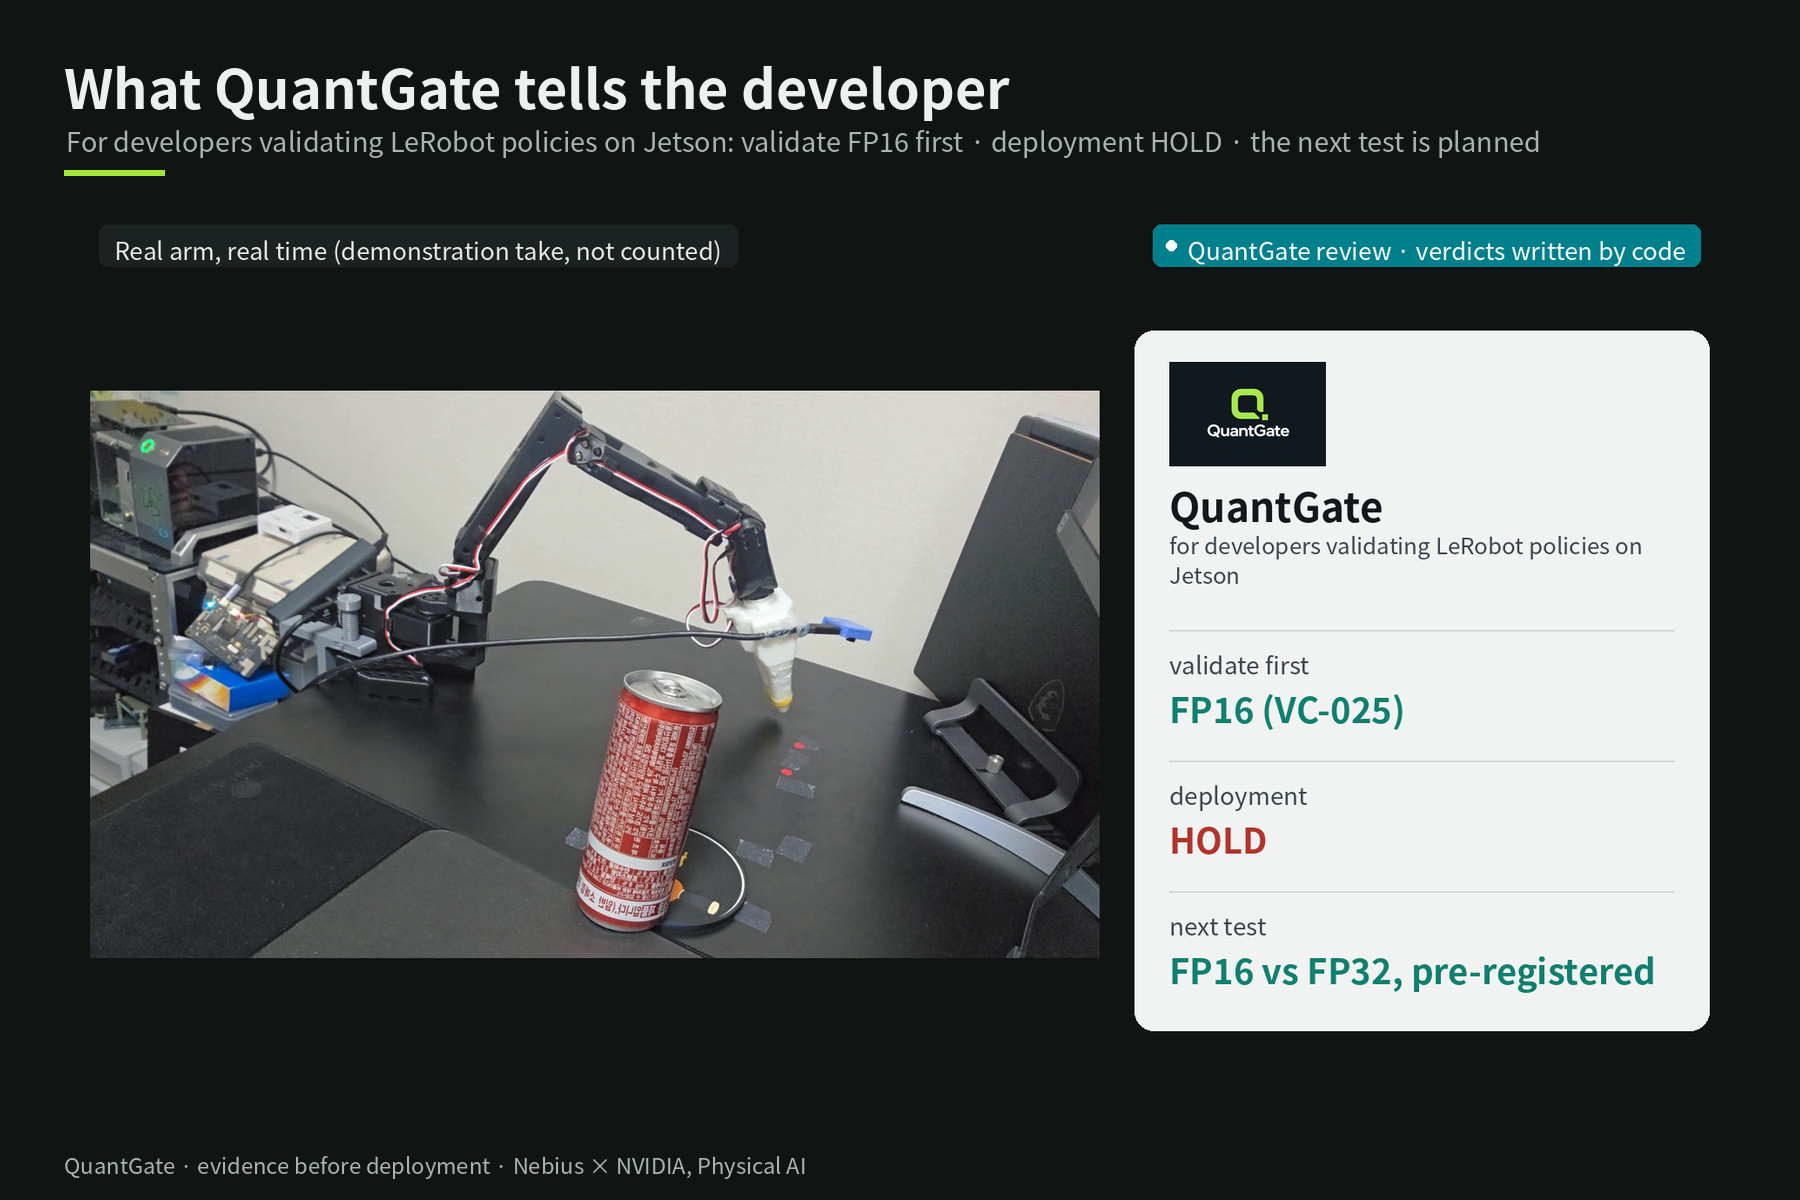
What QuantGate tells the developer: validate FP16 first, deployment HOLD, the next test planned
-
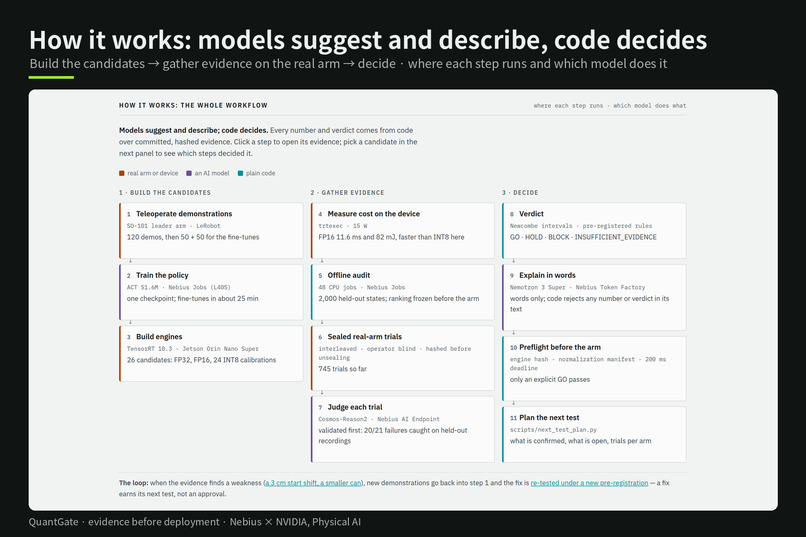
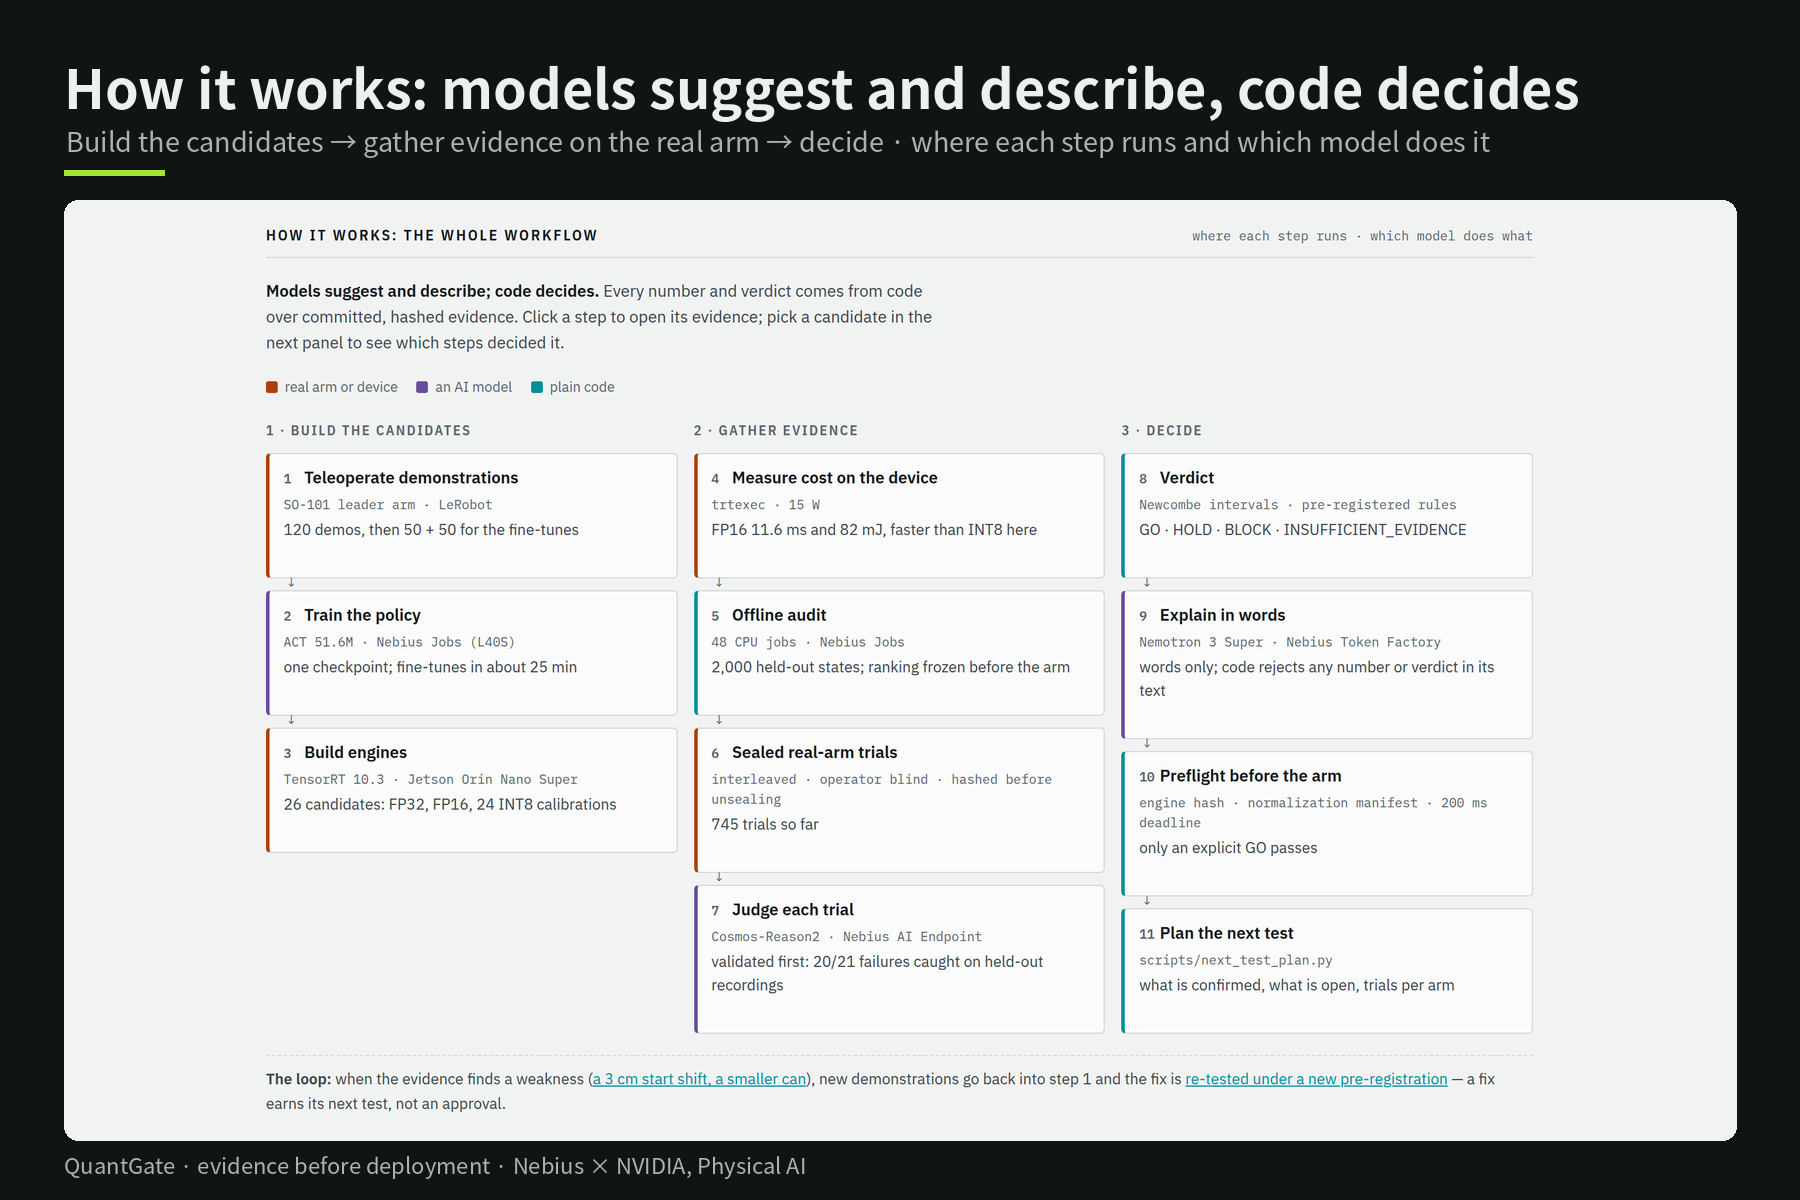
How it works: models suggest and describe, code decides
-
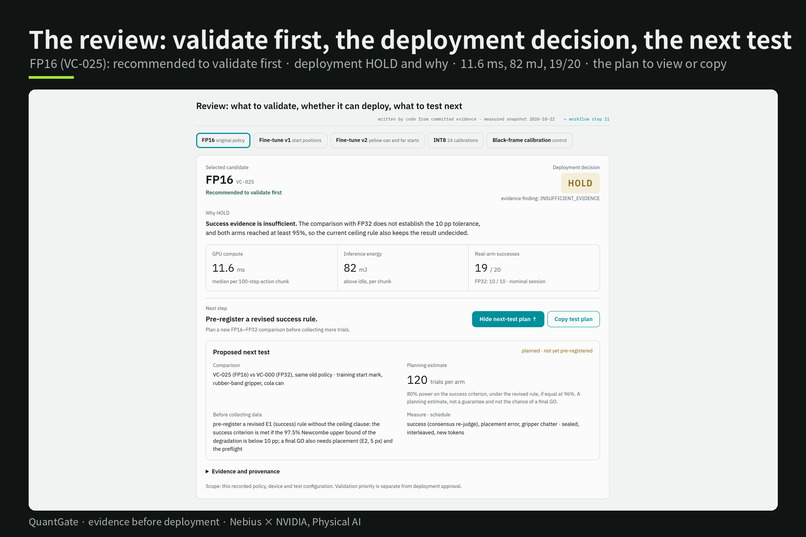
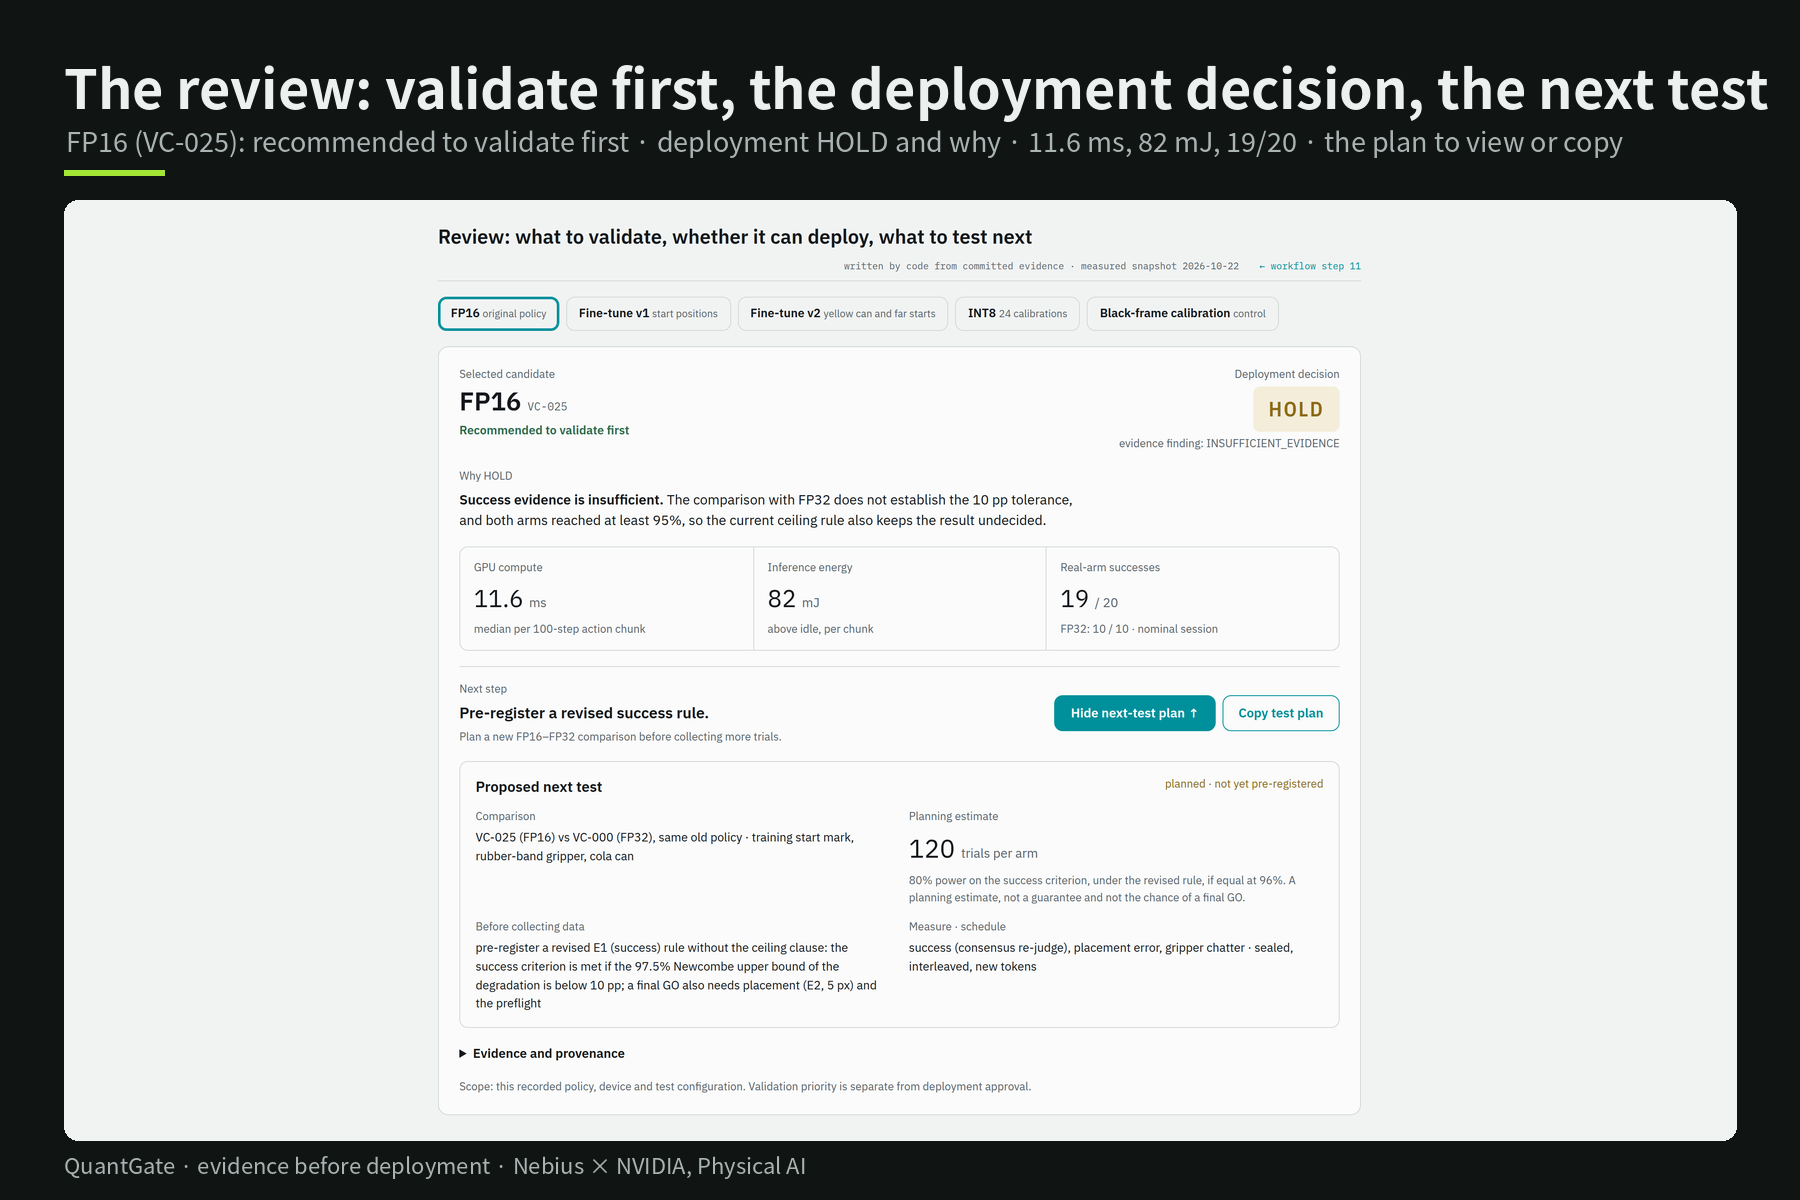
The Review panel: validate first, the deployment decision and why, the next test
-
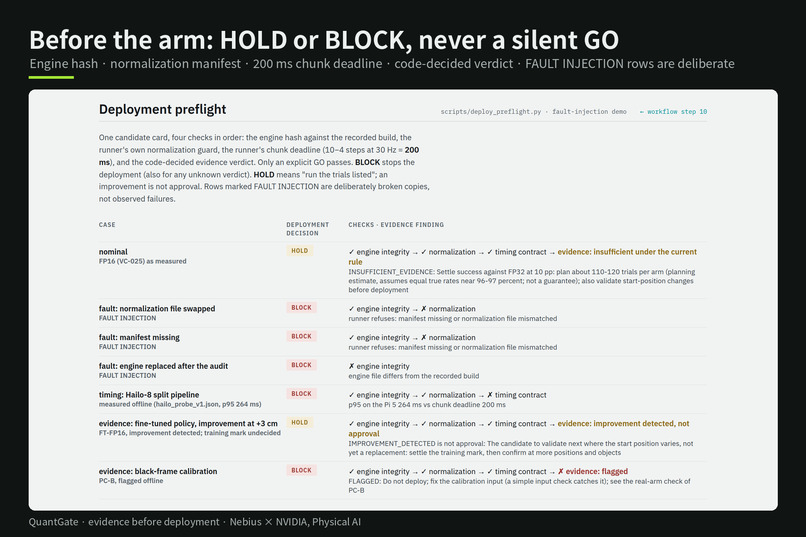
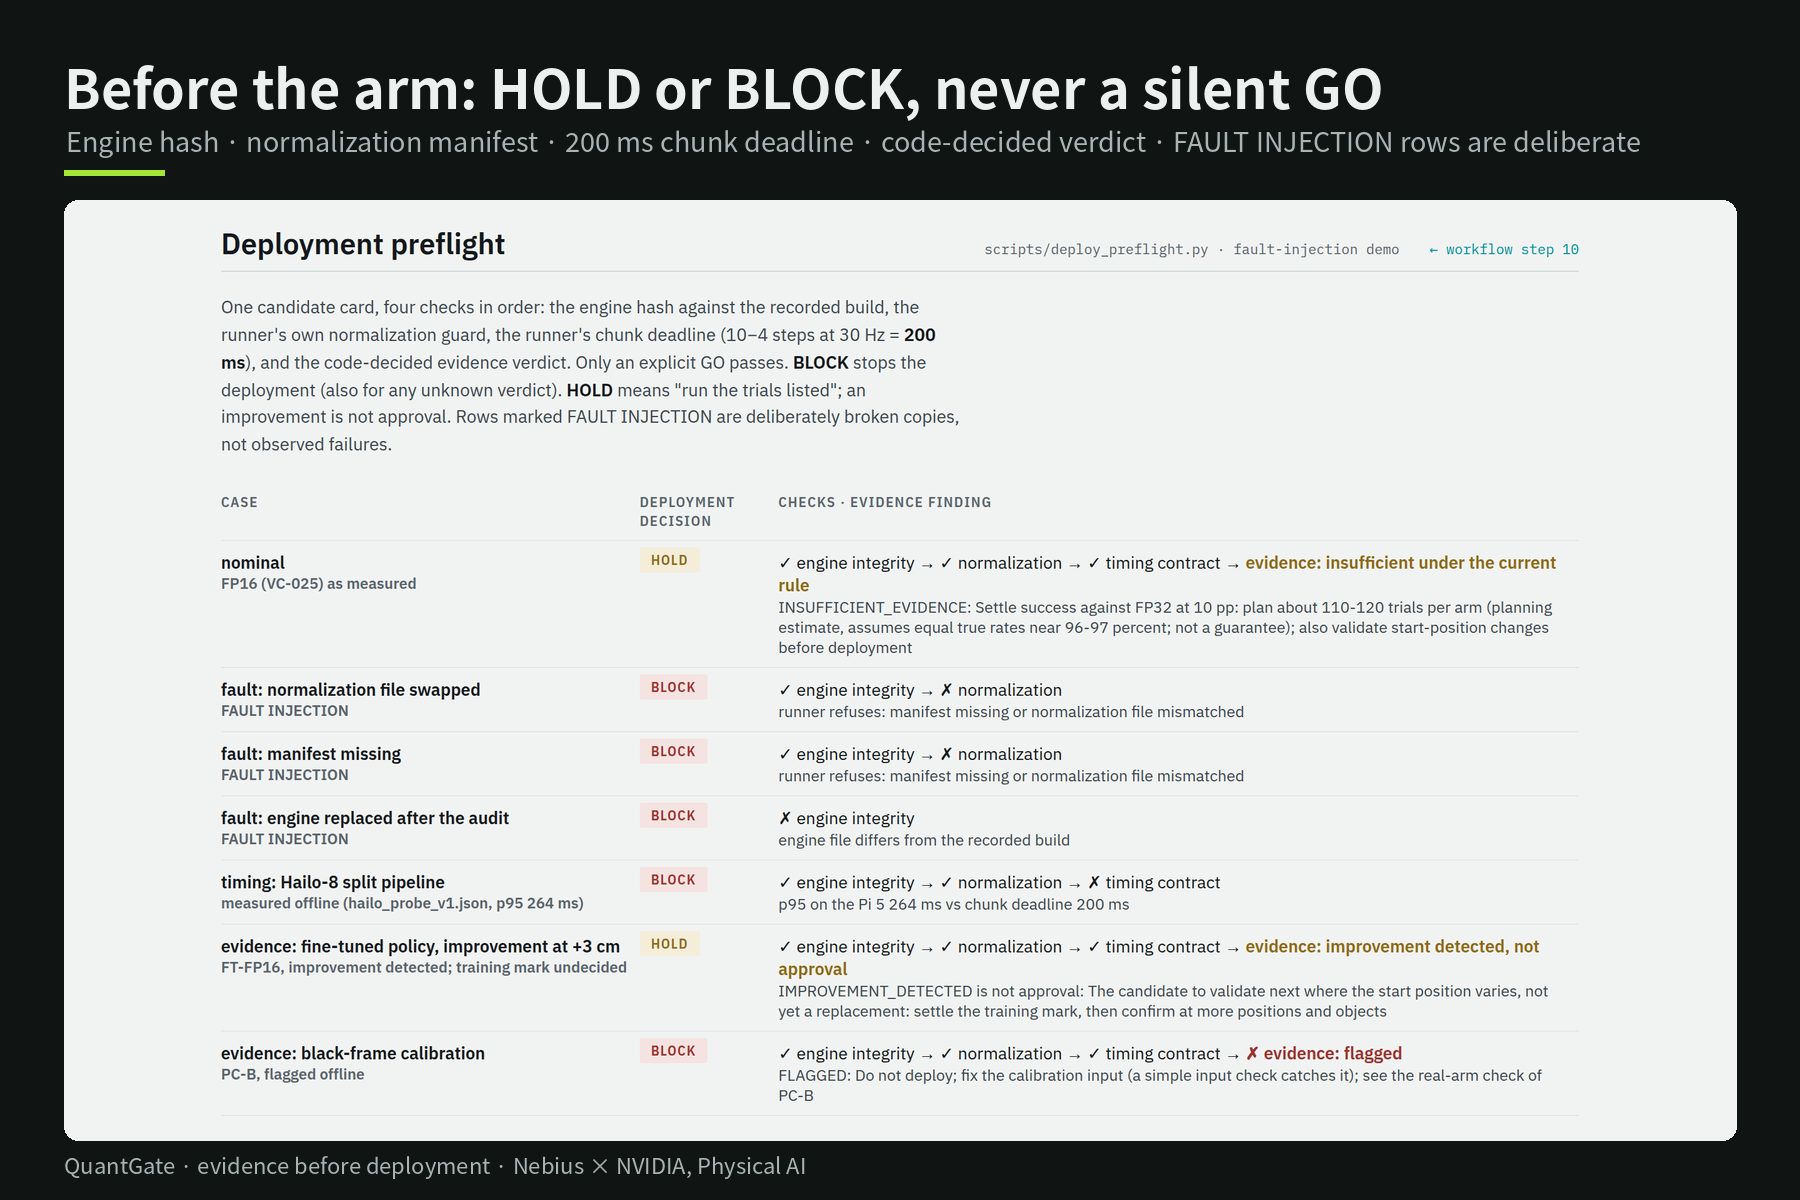
Before the arm: HOLD or BLOCK, never a silent GO
-
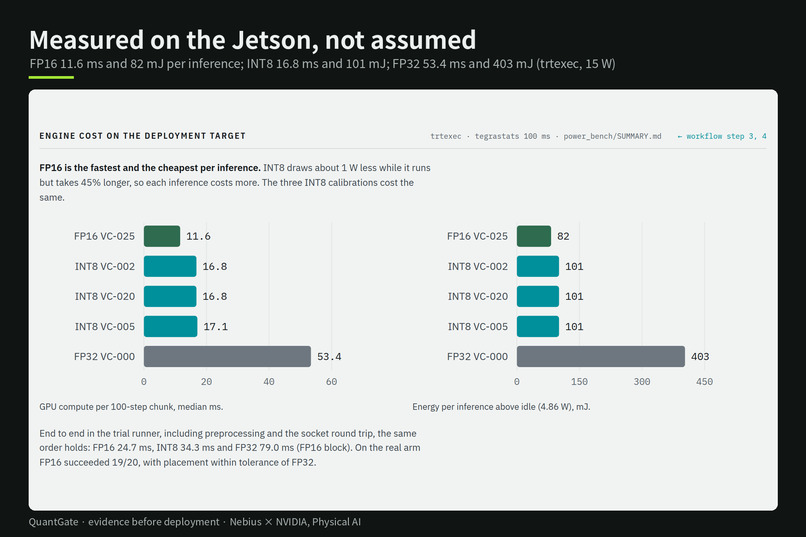
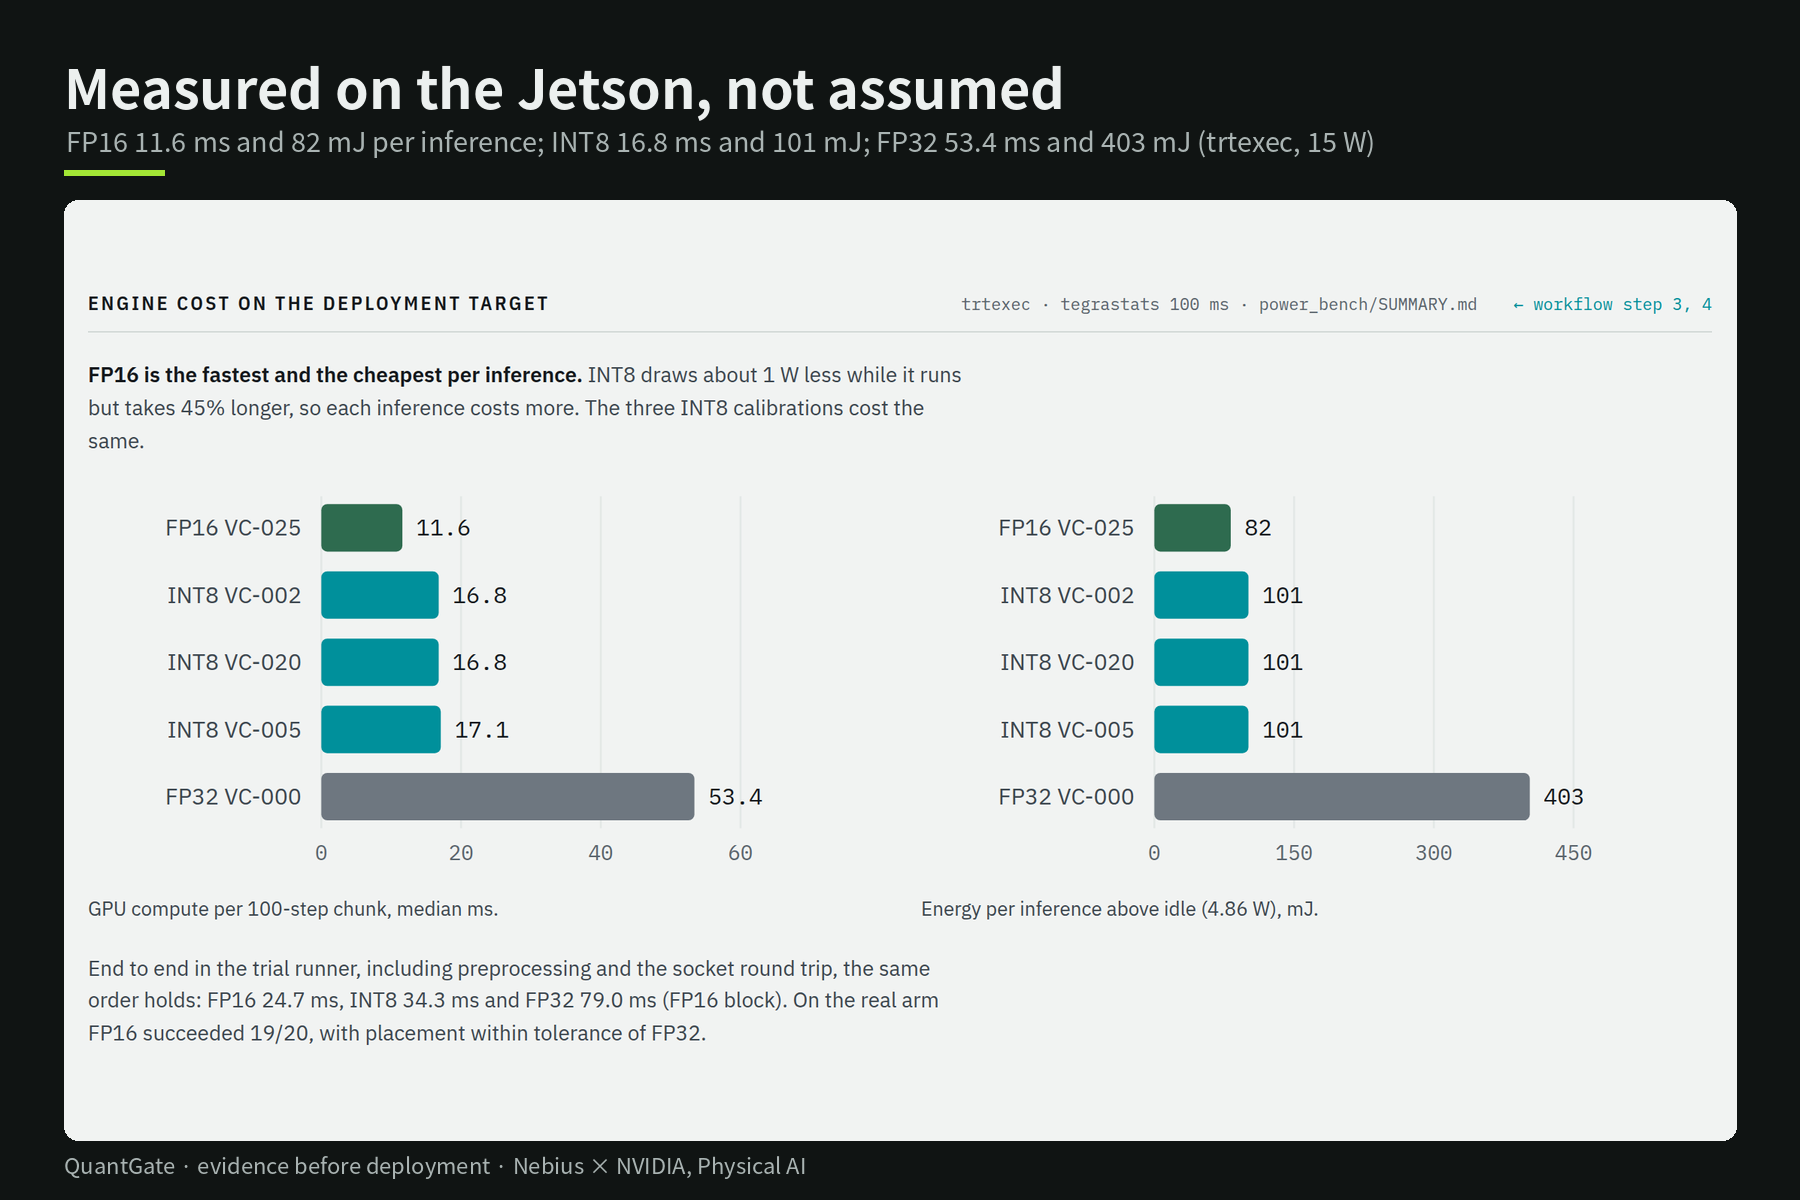
Measured on the Jetson: FP16 11.6 ms and 82 mJ per inference
-
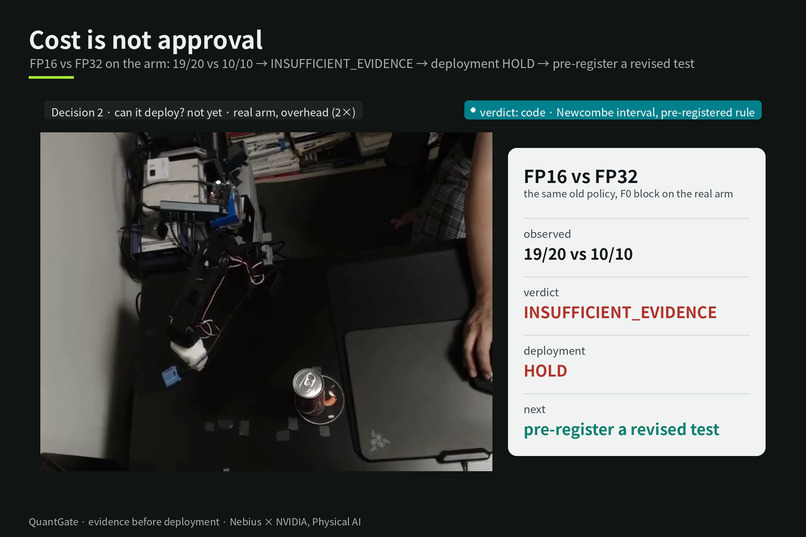
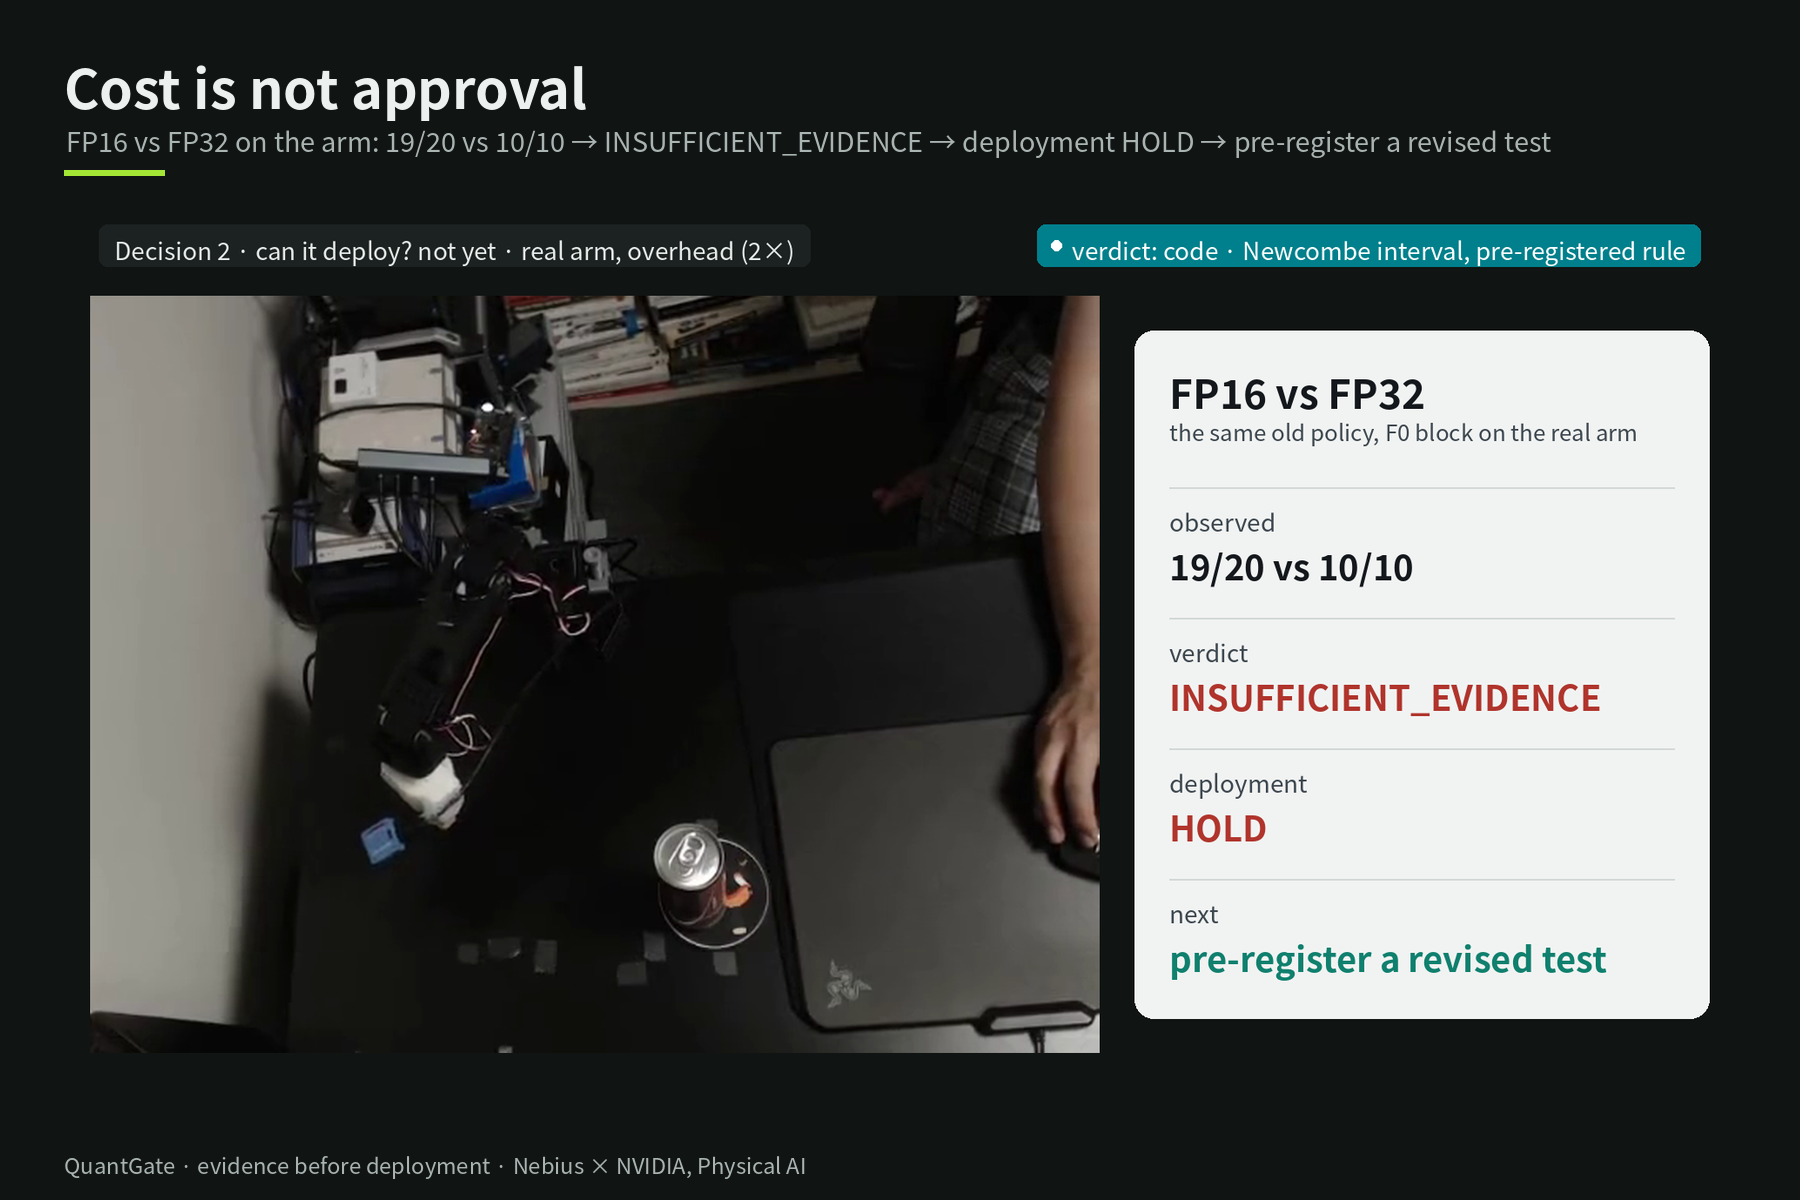
Cost is not approval: FP16 vs FP32 19/20 vs 10/10, INSUFFICIENT_EVIDENCE, HOLD
-
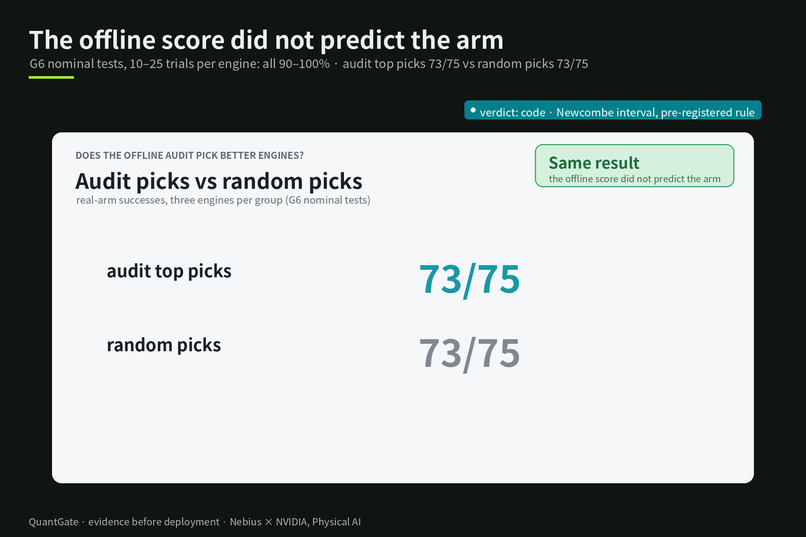
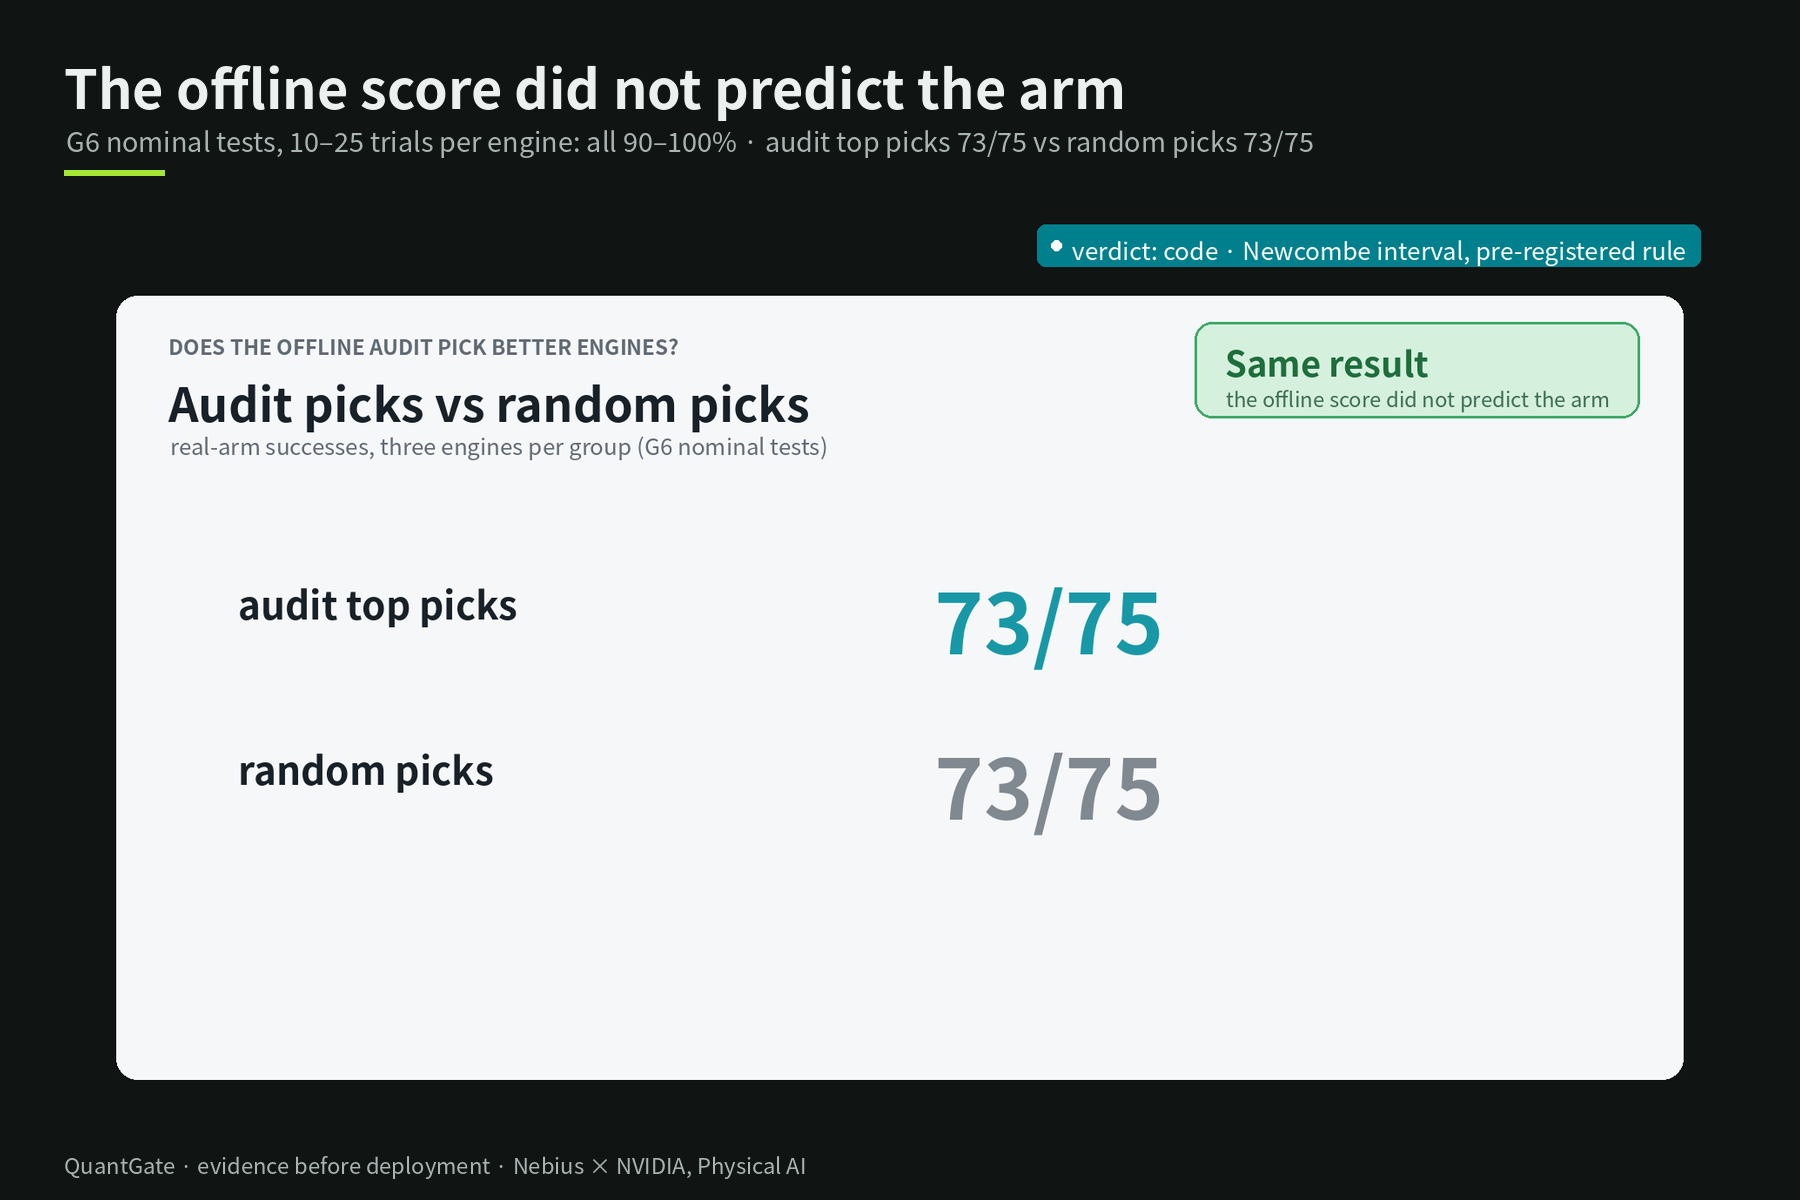
The offline score did not predict the arm: 73/75 vs 73/75
-
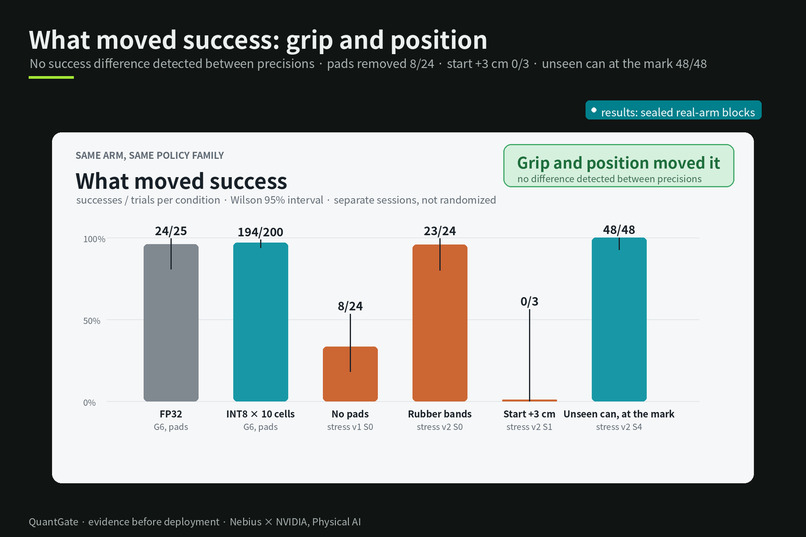
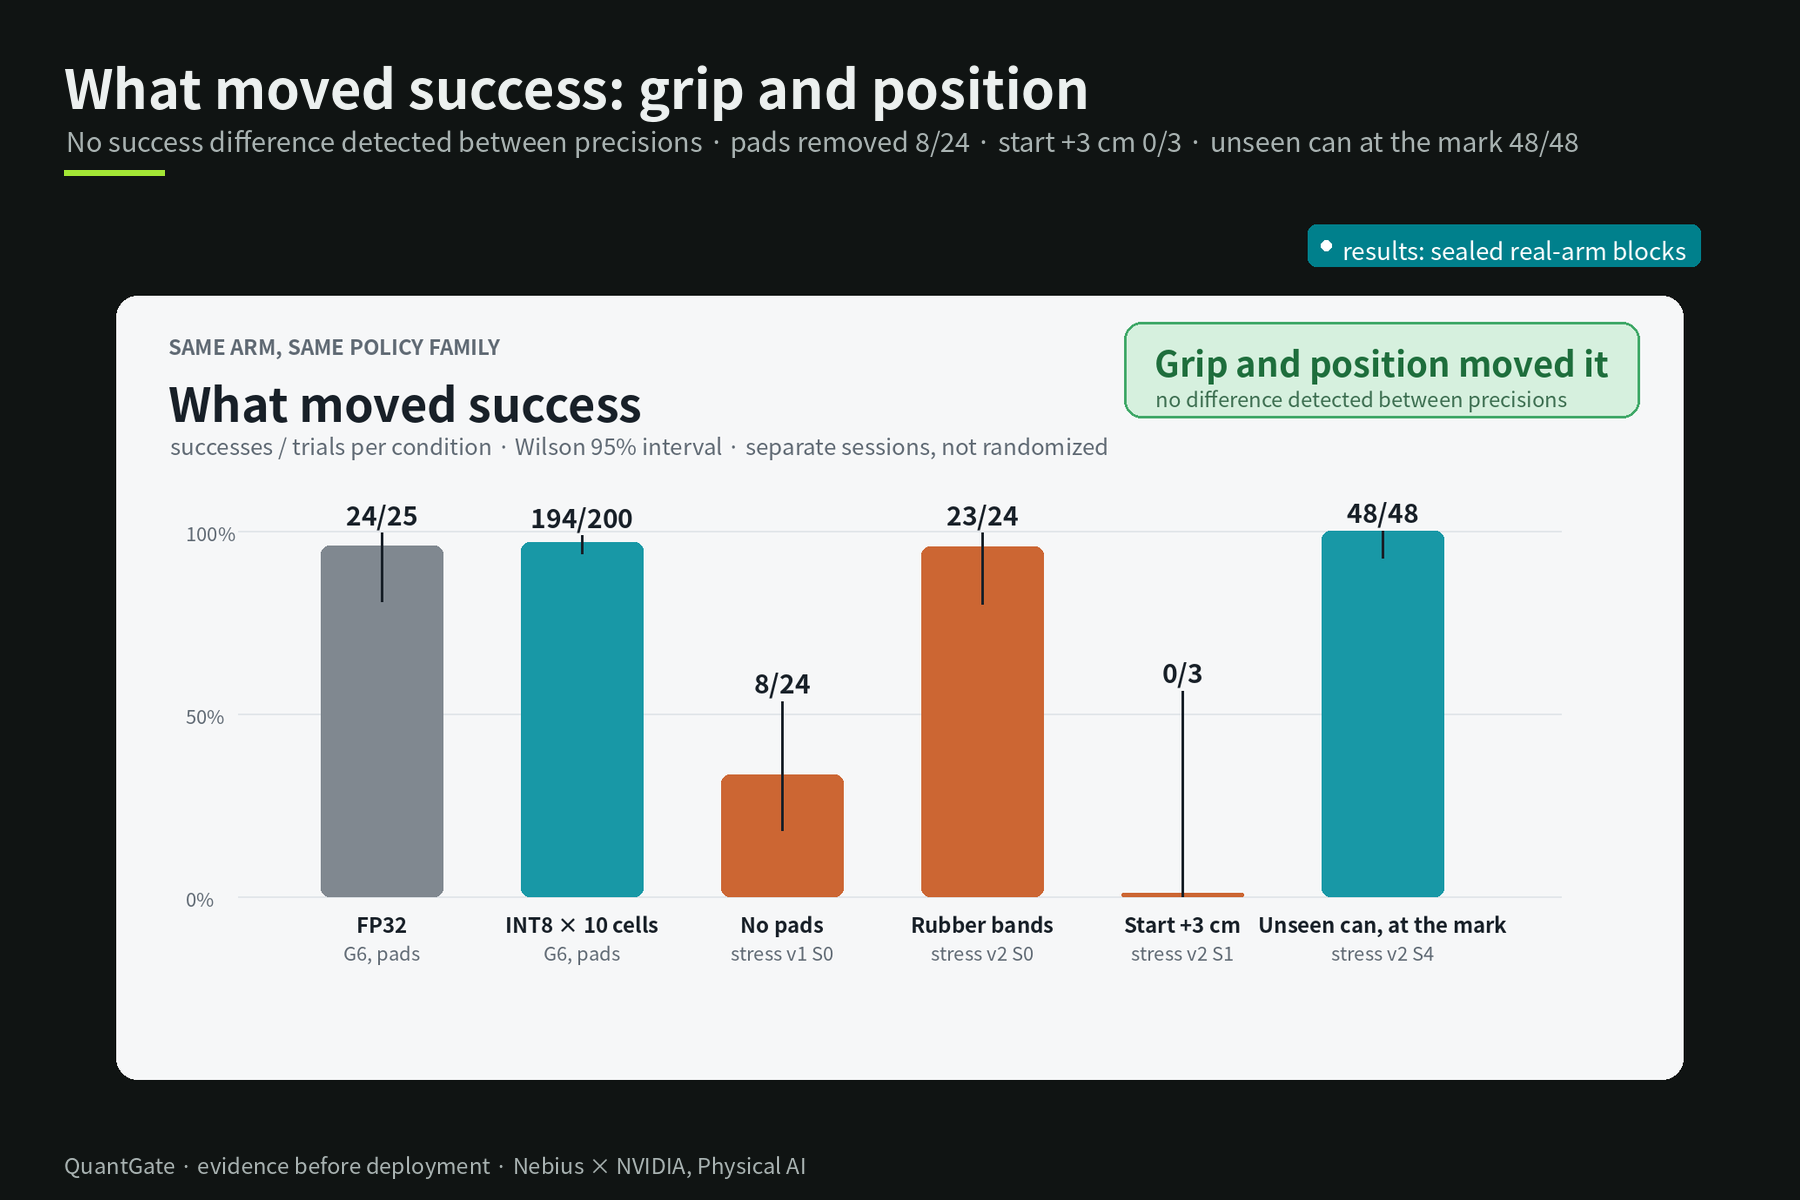
What moved success: grip and start position
-
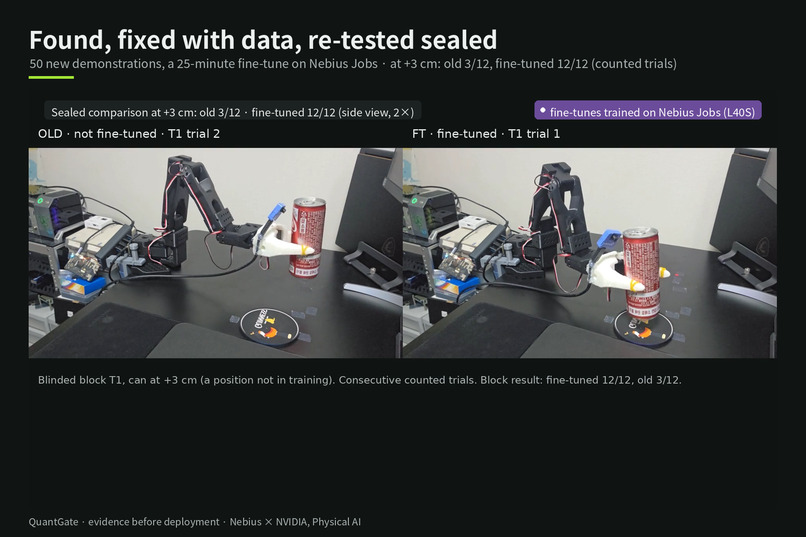
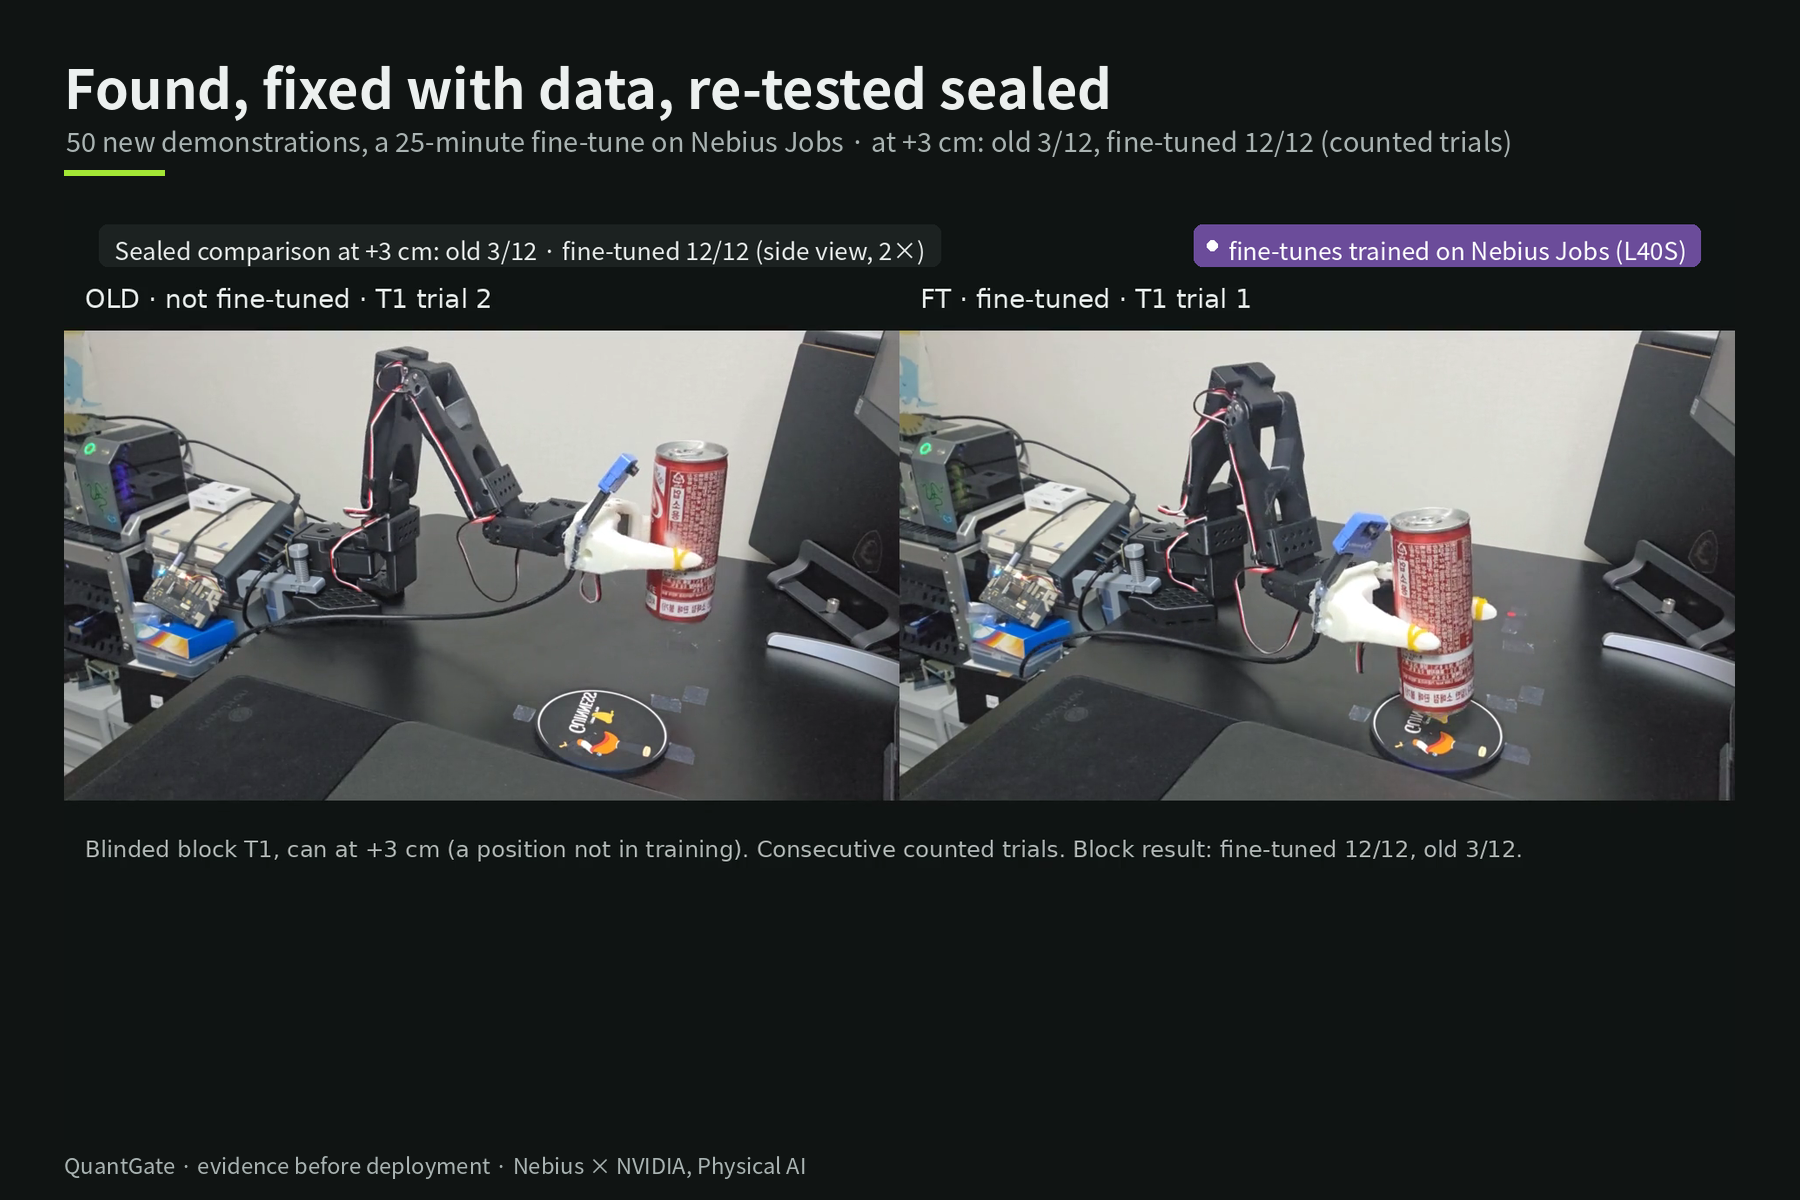
Found, fixed with data, re-tested sealed: +3 cm 12/12 vs 3/12
-
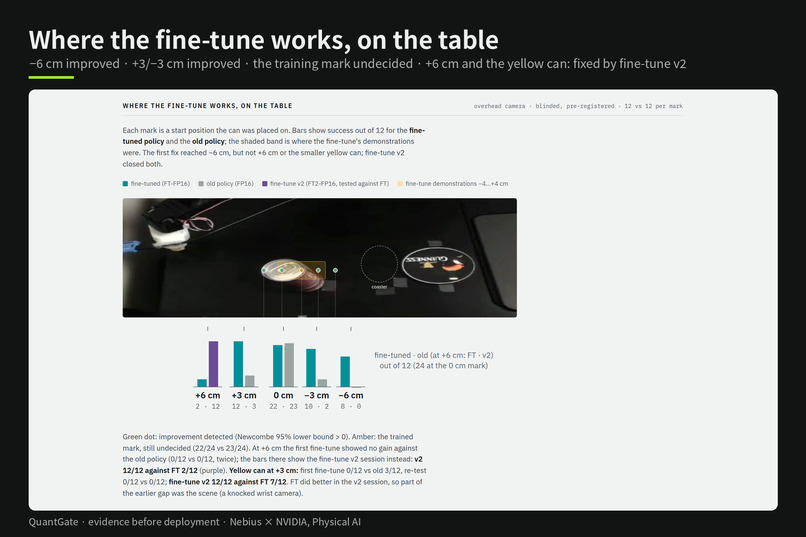
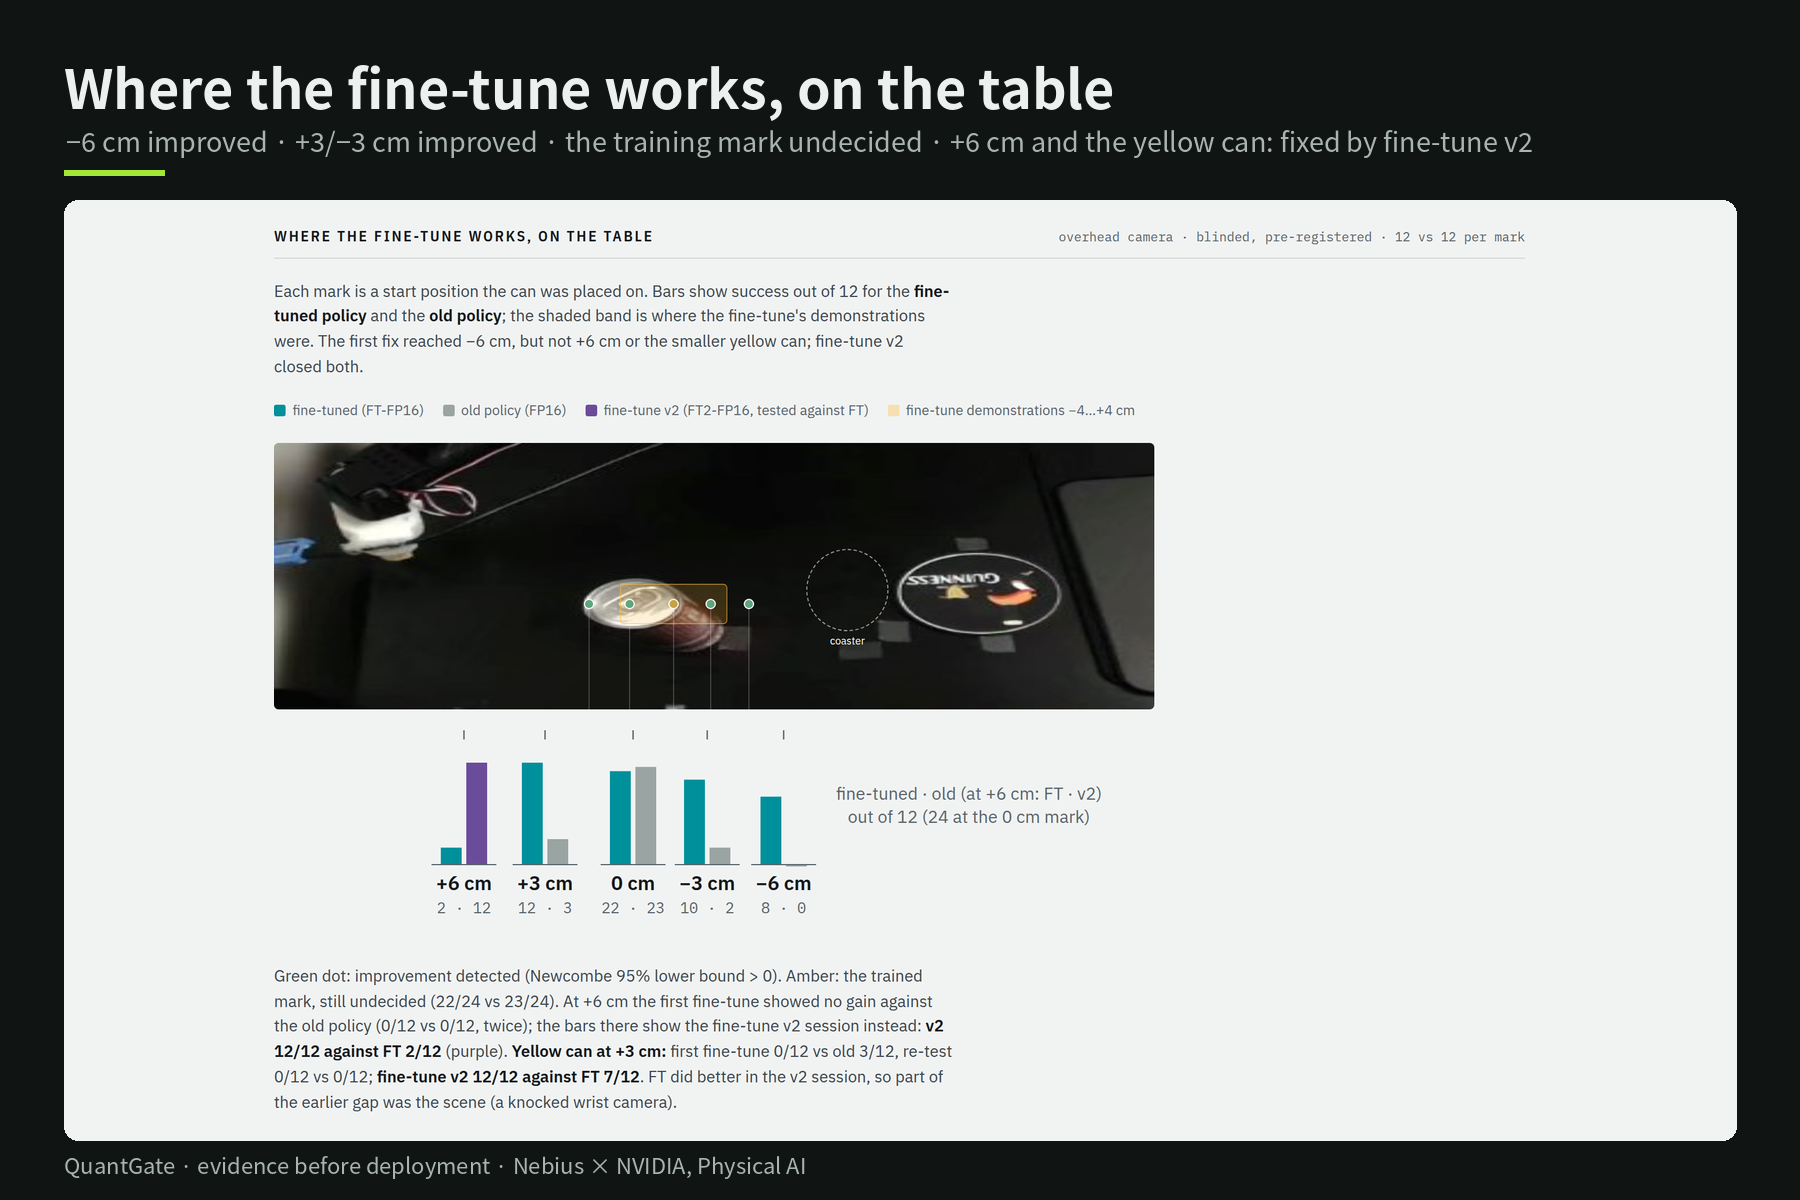
Where the fine-tune works, on the table
-
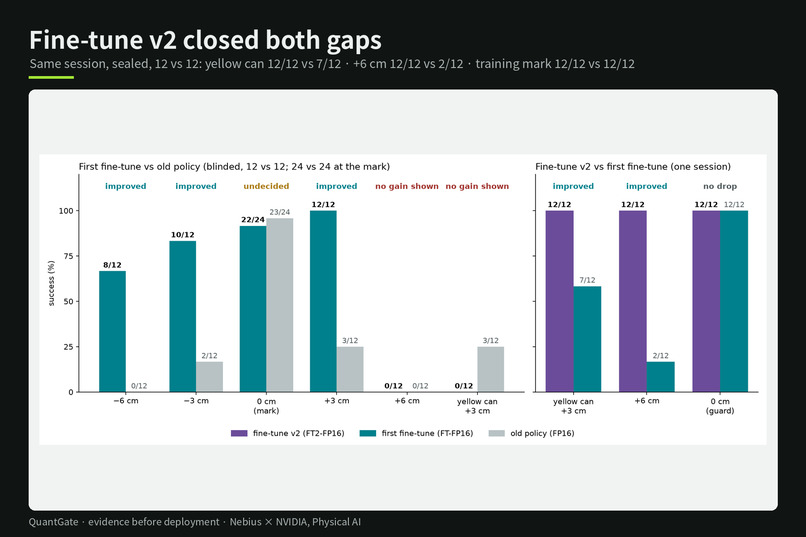
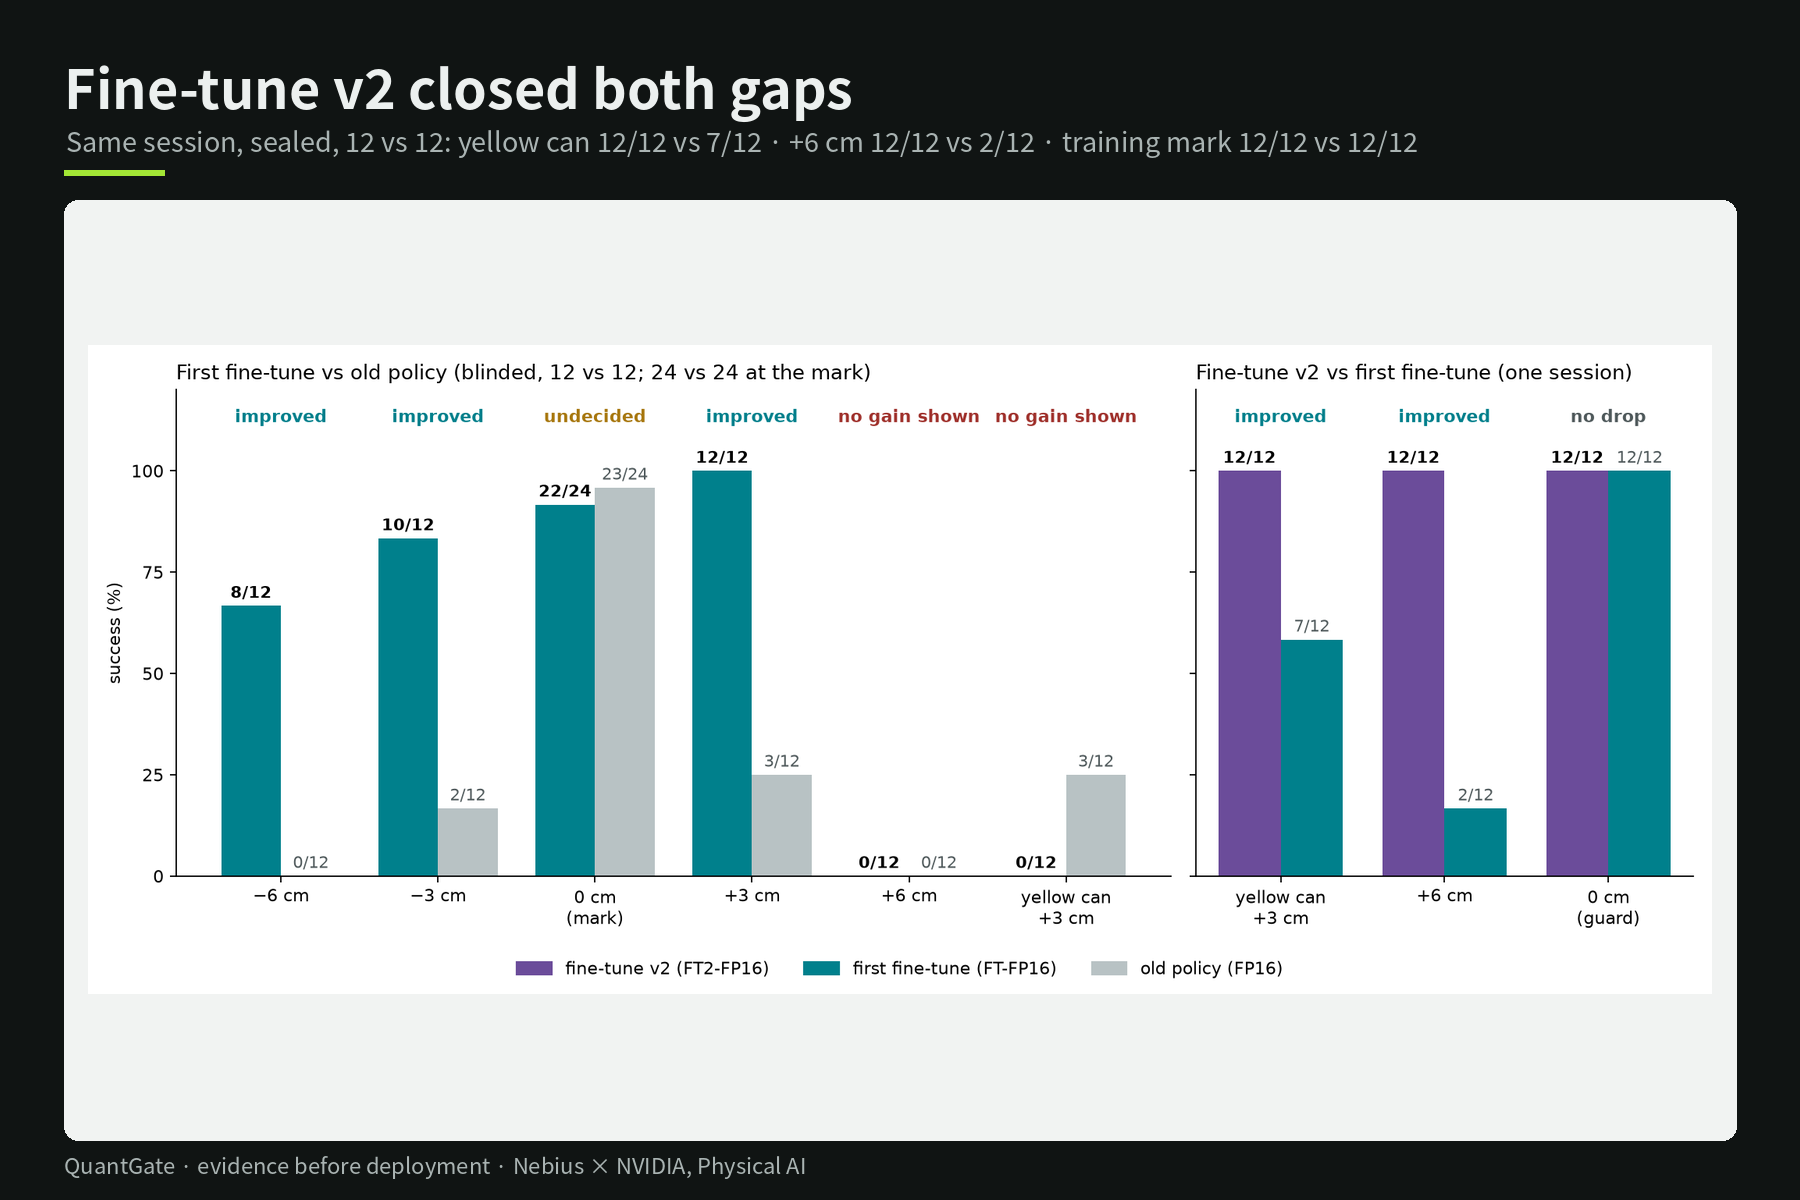
Fine-tune v2 closed both gaps: 12/12 vs 7/12 and 12/12 vs 2/12
-
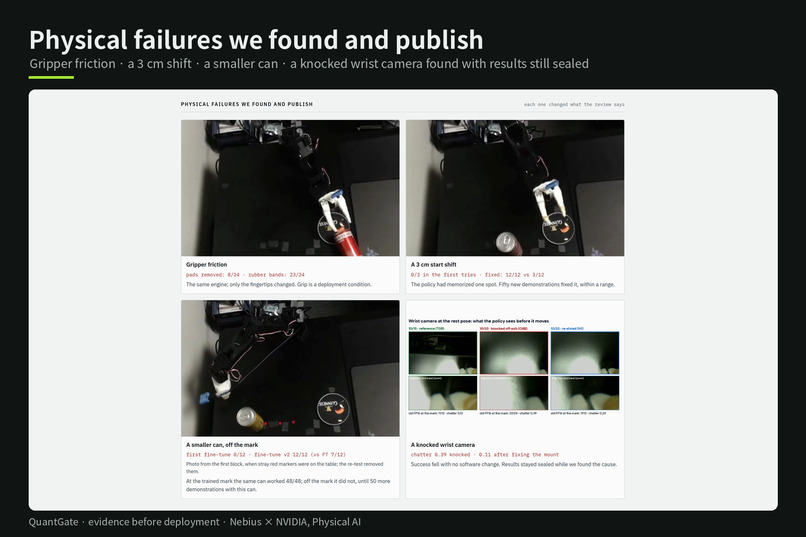
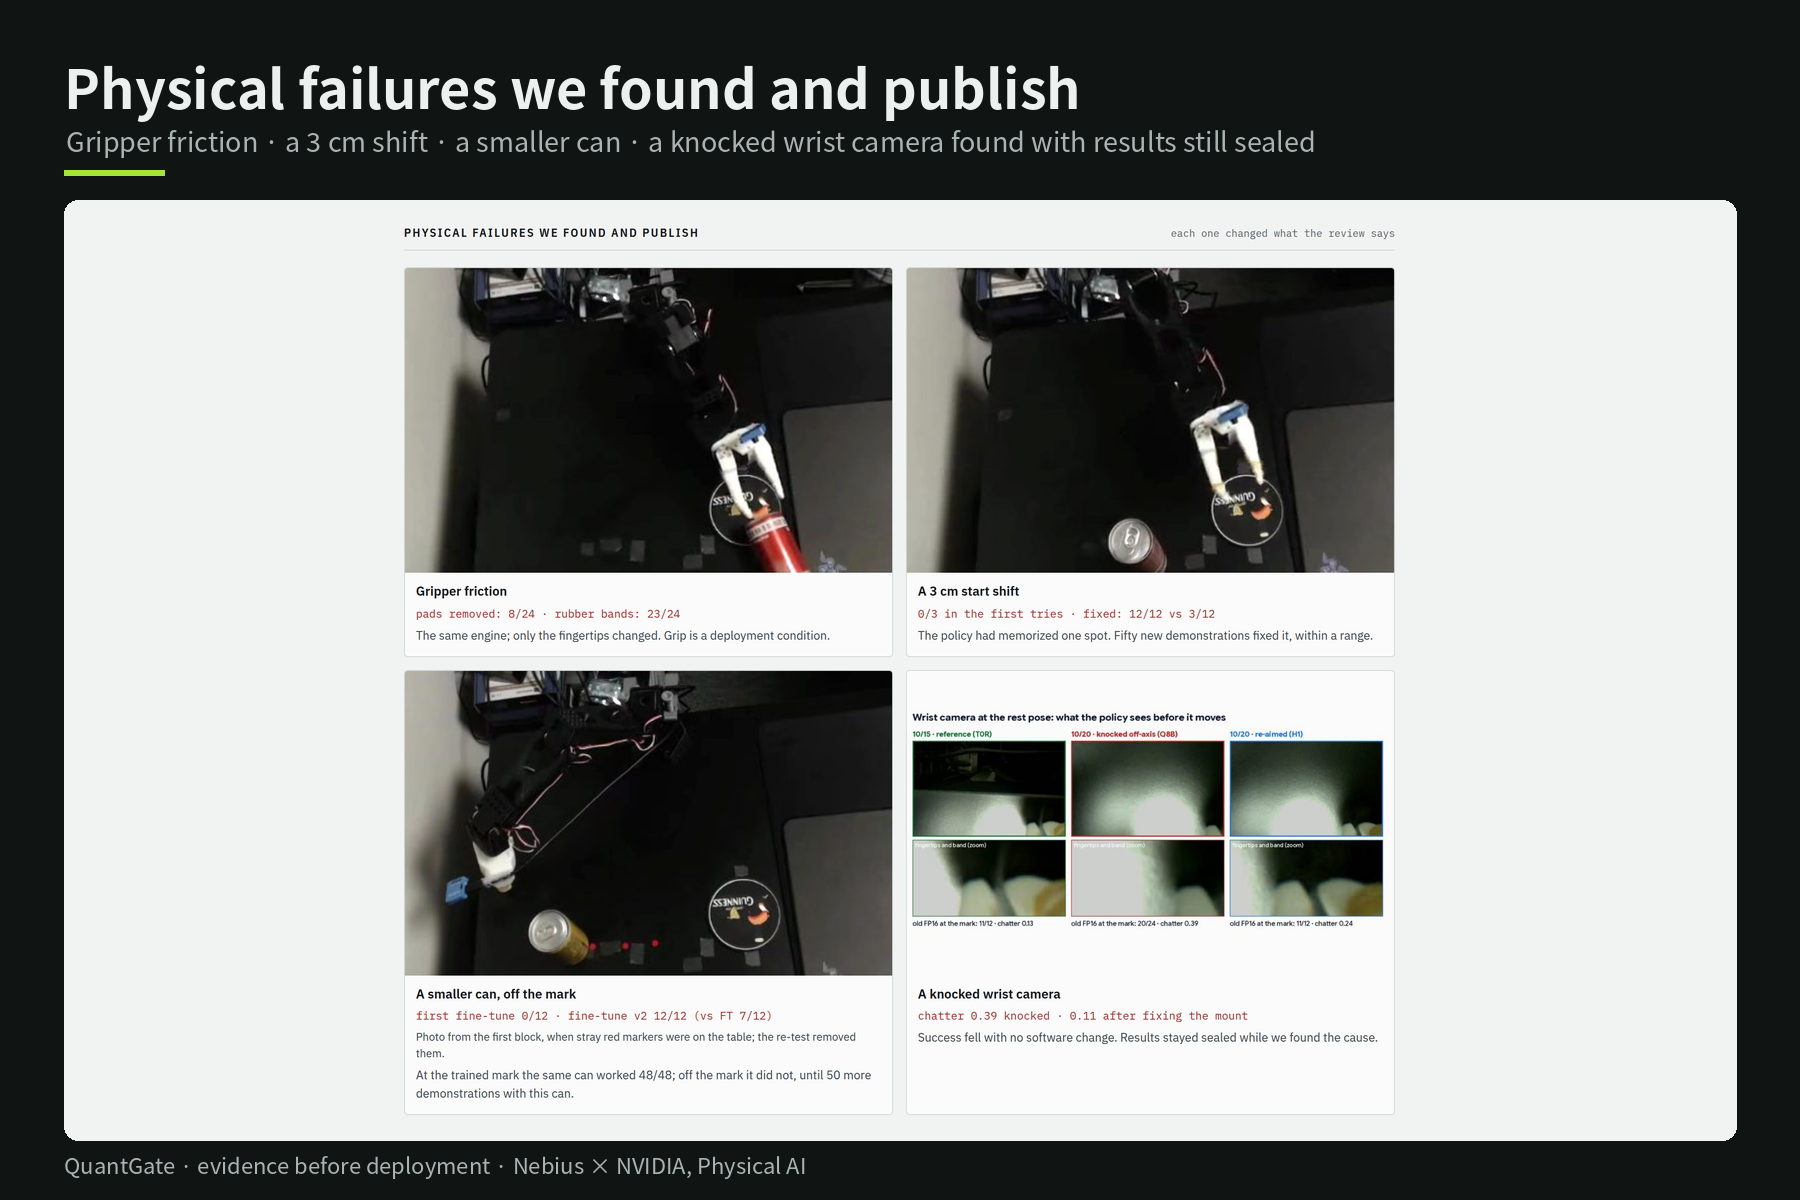
Physical failures we found and publish
-
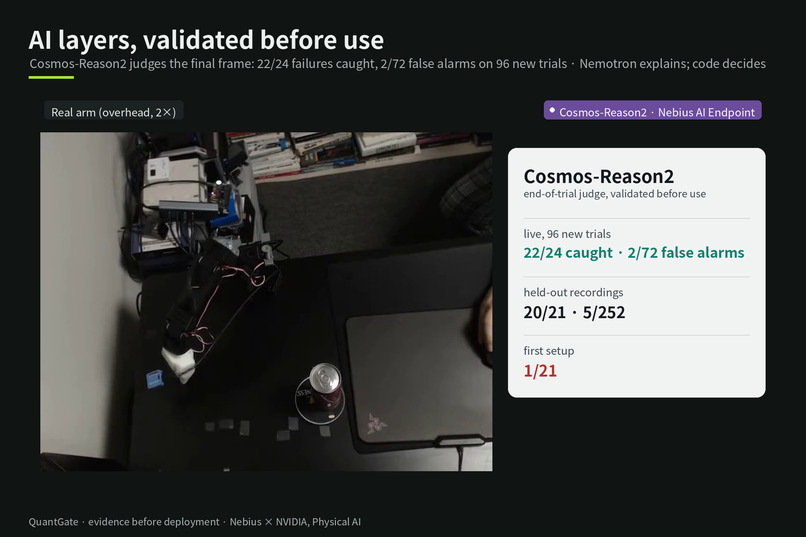
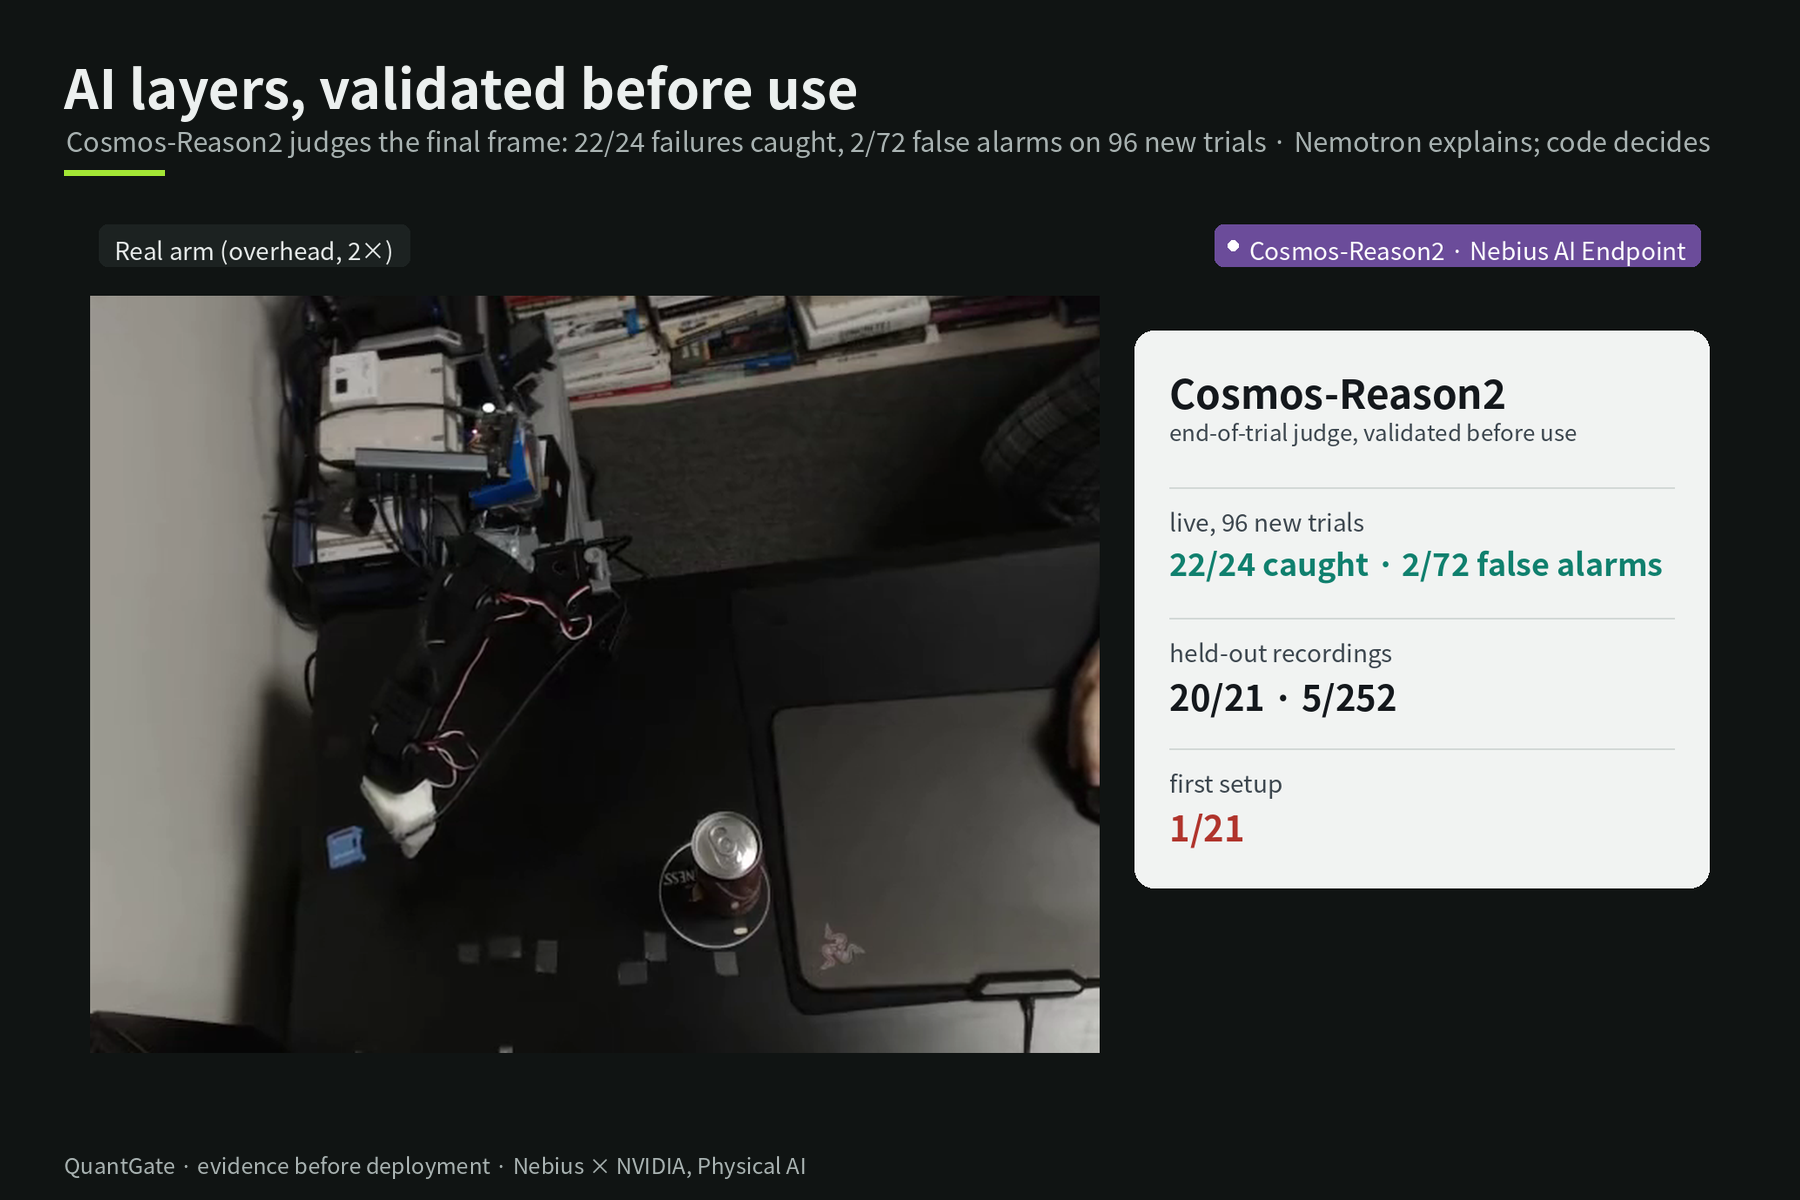
AI layers, validated before use: Cosmos-Reason2 22/24 live, Nemotron explains
In short
- In this study, FP16 was the cheapest build and the next one to validate. On the Jetson it was the fastest and used the least energy (11.6 ms, 82 mJ per inference), ahead of the three benchmarked INT8 builds.
- The INT8 offline ranking did not turn into a real-arm advantage. The top-ranked INT8 builds and randomly picked ones both succeeded 73/75.
- No build is approved for deployment yet. The evidence is not strong enough for any candidate, and the review names the next test that could change that.
The statistics behind each line follow below.
Inspiration
It started as a small gesture: a robot arm that brings a drink to someone working hard. Setting the can down properly on the coaster turned out to be the hard part, and we got curious about it.
We had a robot policy that worked: an SO-101 arm picks up a cola can and stands it on a coaster, driven by a LeRobot ACT (Action Chunking with Transformers) policy. Then we had to put it on a Jetson Orin Nano Super. That gave us 26 ways to ship the same checkpoint: FP32, FP16 and 24 INT8 builds that differ only in how they were calibrated.
Benchmarks told us speed, and open-loop metrics all looked fine. Neither told us whether the arm would still put the can on the coaster, or how sure we could be. Same robot, same task: one run succeeds, one fails.
So we built the tool we wanted: a deployment review that puts cost, offline scores and real-arm evidence side by side, and says plainly when the evidence is not enough.
What it does
For every candidate engine, QuantGate answers three questions.
- Which candidate do I validate first?
- It measures cost on the target device itself (trtexec, 15 W): FP16 takes 11.6 ms and 82 mJ per inference, INT8 16.8–17.1 ms and 101 mJ, FP32 53.4 ms and 403 mJ.
- On this Jetson, FP16 is the fastest and the cheapest, not INT8.
- Which do I distrust?
- Broken calibrations: a deliberately black-frame-calibrated build is caught by a simple input check.
- Builds that do not match what was audited: a preflight checks the engine hash, the normalization manifest and
the runner's 200 ms chunk deadline. Only an explicit
GOpasses.
Can I approve deployment? Not yet, and the review says why.
- Success against FP32 is compared as non-inferiority at a 10 pp tolerance, with a Newcombe interval. The success criterion is met when
$$\text{lower bound of } \big(p_{\text{cand}} - p_{\text{FP32}}\big) > -10\ \text{pp}$$
- That is one part of a final
GO. AGOalso needs placement error within its 5 px tolerance, the ceiling rule not holding the comparison undecided, and the deployment preflight passing. - With 25 trials per arm the success interval is about ±28 pp wide, so every comparison is
INSUFFICIENT_EVIDENCE. - The review also says what would settle it. Our pre-registered ceiling rule keeps two arms that are both at or above 95% undecided at any sample size, so more trials alone are not enough. A revised, pre-registered rule is needed. Under it, about 120 trials per arm give 80% power for the success criterion; that is not the chance of a final GO.
A one-command CLI (quantgate.py review | ask | preflight | cost | verify) rebuilds the whole review from
committed, hashed evidence.
Bring your own results: quantgate.py judge your_results.csv reads another team's success counts with the same
rules and returns a deployment decision, the reason and the next test (example: examples/my_results.csv).
What is new here
Which build to deploy, not which plan to run. Plan checkers decide whether one plan may run now. QuantGate decides whether a build of a policy (FP32, FP16, INT8, a fine-tune) may replace another on the device. It compares them by measured edge cost and real-arm behaviour, and holds approval when the evidence is not enough.
A gate in front of deployment, or a model that proposes while code decides, is not new on its own. What QuantGate adds is the combination, measured on a real arm:
- The same policy, compared across its deployable builds. FP32, FP16 and 24 INT8 calibrations of one checkpoint, with cost measured on the Jetson and behaviour measured on the arm, side by side.
- Physical causes kept apart from the build. Grip friction, the start position, a smaller can and a knocked wrist camera are tracked as deployment conditions, so a failure is not blamed on the precision by default.
- A fix that was checked, twice. Failure found → new demonstrations → fine-tune → sealed comparison at conditions never in training, then the same again for the gaps the first fix left.
- The line between "better" and "approved". An improvement, a cheaper build or a passing check is reported as what it is; deployment stays HOLD until the pre-registered rule says otherwise.
Which model does what
| Part | Model or tool | Its job | What it is not allowed to do |
|---|---|---|---|
| The robot policy | ACT (51.6M), trained on Nebius Jobs | picks up the can | — |
| The candidates | TensorRT FP32 / FP16 / INT8 engines on the Jetson | the builds under review | — |
| The judge | Cosmos-Reason2 on a Nebius AI Endpoint | says whether the can ended standing on the coaster | decide a verdict on its own; it was validated on held-out recordings first |
| The writer | Nemotron 3 Super on Nebius Token Factory | explains the review in words | write any number, verdict or approval word (code rejects them) |
| The verdicts | plain code | every number, interval and GO / HOLD / BLOCK | — |
Who it is for
Teams that ship learned robot policies to edge accelerators such as Jetson and Hailo: robotics startups, labs moving a policy into a product, and integrators who must sign off a build. The need recurs. Every retrain, quantization, compiler or device change makes a new artifact, and each artifact needs its own evidence.
- Free entry point (Apache 2.0): the on-device preflight that blocks a build that does not match what was audited, and the CLI that rebuilds the review from hashed evidence with no GPU or API key.
- What a team would pay for: a review per deployment artifact (cost on the target device, the blinded real-arm protocol, the validated judge and the evidence report), and the same check in CI on every new build. The compute behind it (fine-tuning jobs, the judge, the report agent) runs on Nebius.
- First users: the LeRobot and SO-101 community, reached through the public datasets and this repository.
- Why now: from 20 January 2027 the EU Machinery Regulation (2023/1230) puts machine-learning safety components under third-party conformity assessment. QuantGate does not claim compliance. Its pre-registered, hashed records are the kind of evidence such reviews ask for.
- Status: not yet tried by outside teams. Every number here comes from our own arm.
How we built it
- Data and training:
- 120 teleoperated demonstrations, recorded with LeRobot.
- ACT (51.6M parameters, 100-step chunks) trained on Nebius Jobs with an L40S GPU.
- 26 TensorRT engines built on the Jetson with a frozen timing cache, so the same file always behaves the same.
- Offline audit: 2,000 held-out states scored on Nebius Jobs, one CPU job per cell (25 cells; 27 jobs submitted, two re-run). The ranking was frozen before any real trial.
- Real arm: 745 trials in 18 sessions, all under sealed, interleaved schedules.
- The operator saw trial numbers only. In the fine-tune blocks the two policies moved visibly differently, so operator blinding there was partial; outcomes come from an automatic judge and a blind re-judge of the saved video by code (the same circle detector, rerun; no person or AI model).
- Logs are hashed before they are unsealed, so no rule can change after the results are seen.
- The primary analyses were pre-registered. Rules set after aggregate results and post-hoc observations are labelled as such in the decision log.
- AI layers on Nebius:
- Cosmos-Reason2 on a Nebius AI Endpoint judges the final frame of each trial.
- Nemotron 3 Super on Nebius Token Factory explains the review in words.
- Code writes every verdict and number. A validator rejects model text that contains digits, verdict labels or approval words.
- Cost of one review: about \$31 of Nebius cloud.
Open data, end to end
The training input of every policy is public: 120 base demonstrations with their train/val/audit split, 50 position demonstrations (fine-tune v1) and 50 yellow-can and far-start demonstrations (fine-tune v2), all LeRobot v3 under CC BY 4.0. The split, the checkpoint choice on the validation set, the held-out conditions and the sealed evaluations are linked in the README's "Data and lineage" table, so the path from a demonstration to an arm result can be checked.
What we found
- The offline audit did not predict the arm.
- Its top-ranked INT8 cells went 73/75, and randomly picked cells also went 73/75.
- The offline rank did not track placement error either (Spearman 0.02–0.08).
- No precision effect was shown in this study; problems tied to deployment conditions were.
- Removing the gripper's anti-slip pads dropped success to 8/24.
- Moving the start 3 cm gave 0/3.
- We fixed the weakness with data and re-tested it under a rule fixed in advance.
- 50 new demonstrations at −4…+4 cm and a 25-minute fine-tune on Nebius Jobs.
- At held-out positions: 12/12 vs 3/12 at +3 cm (+75 pp, 95% CI [+38, +91]) and 10/12 vs 2/12 at −3 cm.
- We then mapped how far the fix reaches, under a new pre-registration: 8/12 vs 0/12 at −6 cm, beyond the demonstrations, but 0/12 vs 0/12 at +6 cm and 0/12 vs 3/12 with a smaller yellow can at +3 cm. The review now states the range where the fine-tune is a candidate, and where it is not. A pre-registered re-test, after we found and removed a scene deviation (stray markers, a knocked wrist camera), gave the same no-gain readings.
- Then we fixed those gaps too. Fifty more demonstrations (the yellow can, starts at +5 and +7 cm) and a second fine-tune: 12/12 vs 7/12 with the yellow can and 12/12 vs 2/12 at +6 cm, both at conditions never in training, with no drop at the trained spot (12/12 vs 12/12).
- At the trained spot it is still undecided (22/24 vs 23/24, with a pre-registered replication), so the review does not approve it there.
Challenges we ran into
- Our own AI judge was wrong at first.
- Cosmos caught 1 of 21 failures with a one-word prompt. A validated prompt caught 20/21 on held-out recordings.
- It then held up live on 96 new trials: 22/24 failures caught, 2/72 false alarms.
- We learned to treat the judge as a component to test, not an oracle.
- INT8 was slower than FP16 on this device. That contradicts the usual assumption, and only on-device measurement showed it.
- Small samples. Honest intervals at 12–25 trials are wide. We had to design the review to say "not yet" instead of overclaiming.
- Blinding a visible fix. The fine-tuned policy moves visibly differently, so operator blinding was partial. Outcomes come from an automatic judge and a blind re-judge of the saved video by code (the same circle detector, rerun), which agree.
- Hardware is the unglamorous failure mode: empty episodes, voltage errors and gripper friction. Each became a recorded deployment condition.
Failure cases we publish
We keep these in the write-up on purpose; each one changed what the review says.
- A knocked wrist camera. Success at the trained spot suddenly fell. We kept every result sealed, ruled out the software, found stray markers and a wrist camera knocked off-axis, and fixed the mount. A pre-registered health check then read "back to nominal" (gripper chatter 0.11, near the earlier 0.13). Six trials run in the bad scene were discarded unopened.
- The fix has a reach, and the scene mattered. The first fine-tune worked from −6 to +3 cm with the cola can, but not at +6 cm or with a smaller yellow can. A second fine-tune fixed both (12/12). In that session the first fine-tune also did better than before (7/12 and 2/12 against 0/12), which fits the knocked camera having caused part of the earlier gap; a comparison across sessions cannot settle it.
- The first AI judge setup missed 20 of 21 failures. After validation it still misses some: cans left standing at the start look like successes to it.
- An offline warning that the arm did not confirm. A deliberately broken calibration scored badly offline but went 11/12 on the arm in 12 trials.
- A hypothesis we could not confirm. INT8 seemed to make the gripper chatter twice as much; a pre-registered test found 1.3x, not significant (p = 0.12).
- The simulator cannot predict the arm yet. An Isaac Sim twin agreed with 10 of 14 real runs only because it predicts failure every time.
What we learned
- Measure cost on the target device. The precision name does not tell you the cost.
- "No failure observed" is not safety evidence. A review should say how far the evidence goes.
- An AI supervisor or judge is a part to validate, with held-out data, before trusting it.
- Pre-registration and sealing are cheap, and they make every number defensible.
What's next
- On-policy audit and distillation from the 500+ logged rollouts.
- Hailo-8, which today misses the 200 ms deadline and is blocked by the preflight, in a shadow-mode run.
- The same review on an Isaac Sim twin of this task for thousands of closed-loop trials. The twin is kinematically calibrated to the real arm on a GB10 desktop but is not yet validated as an outcome predictor. So its candidates would be re-checked on the real arm.
Earn the next test, not the approval.
