-
-
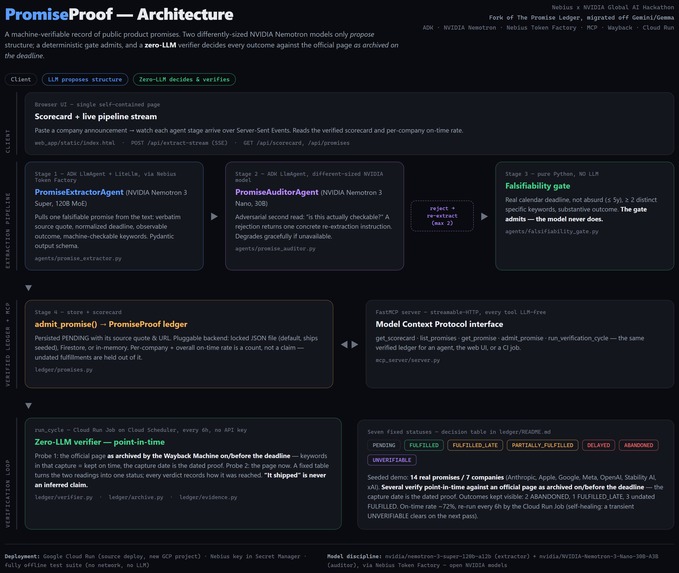
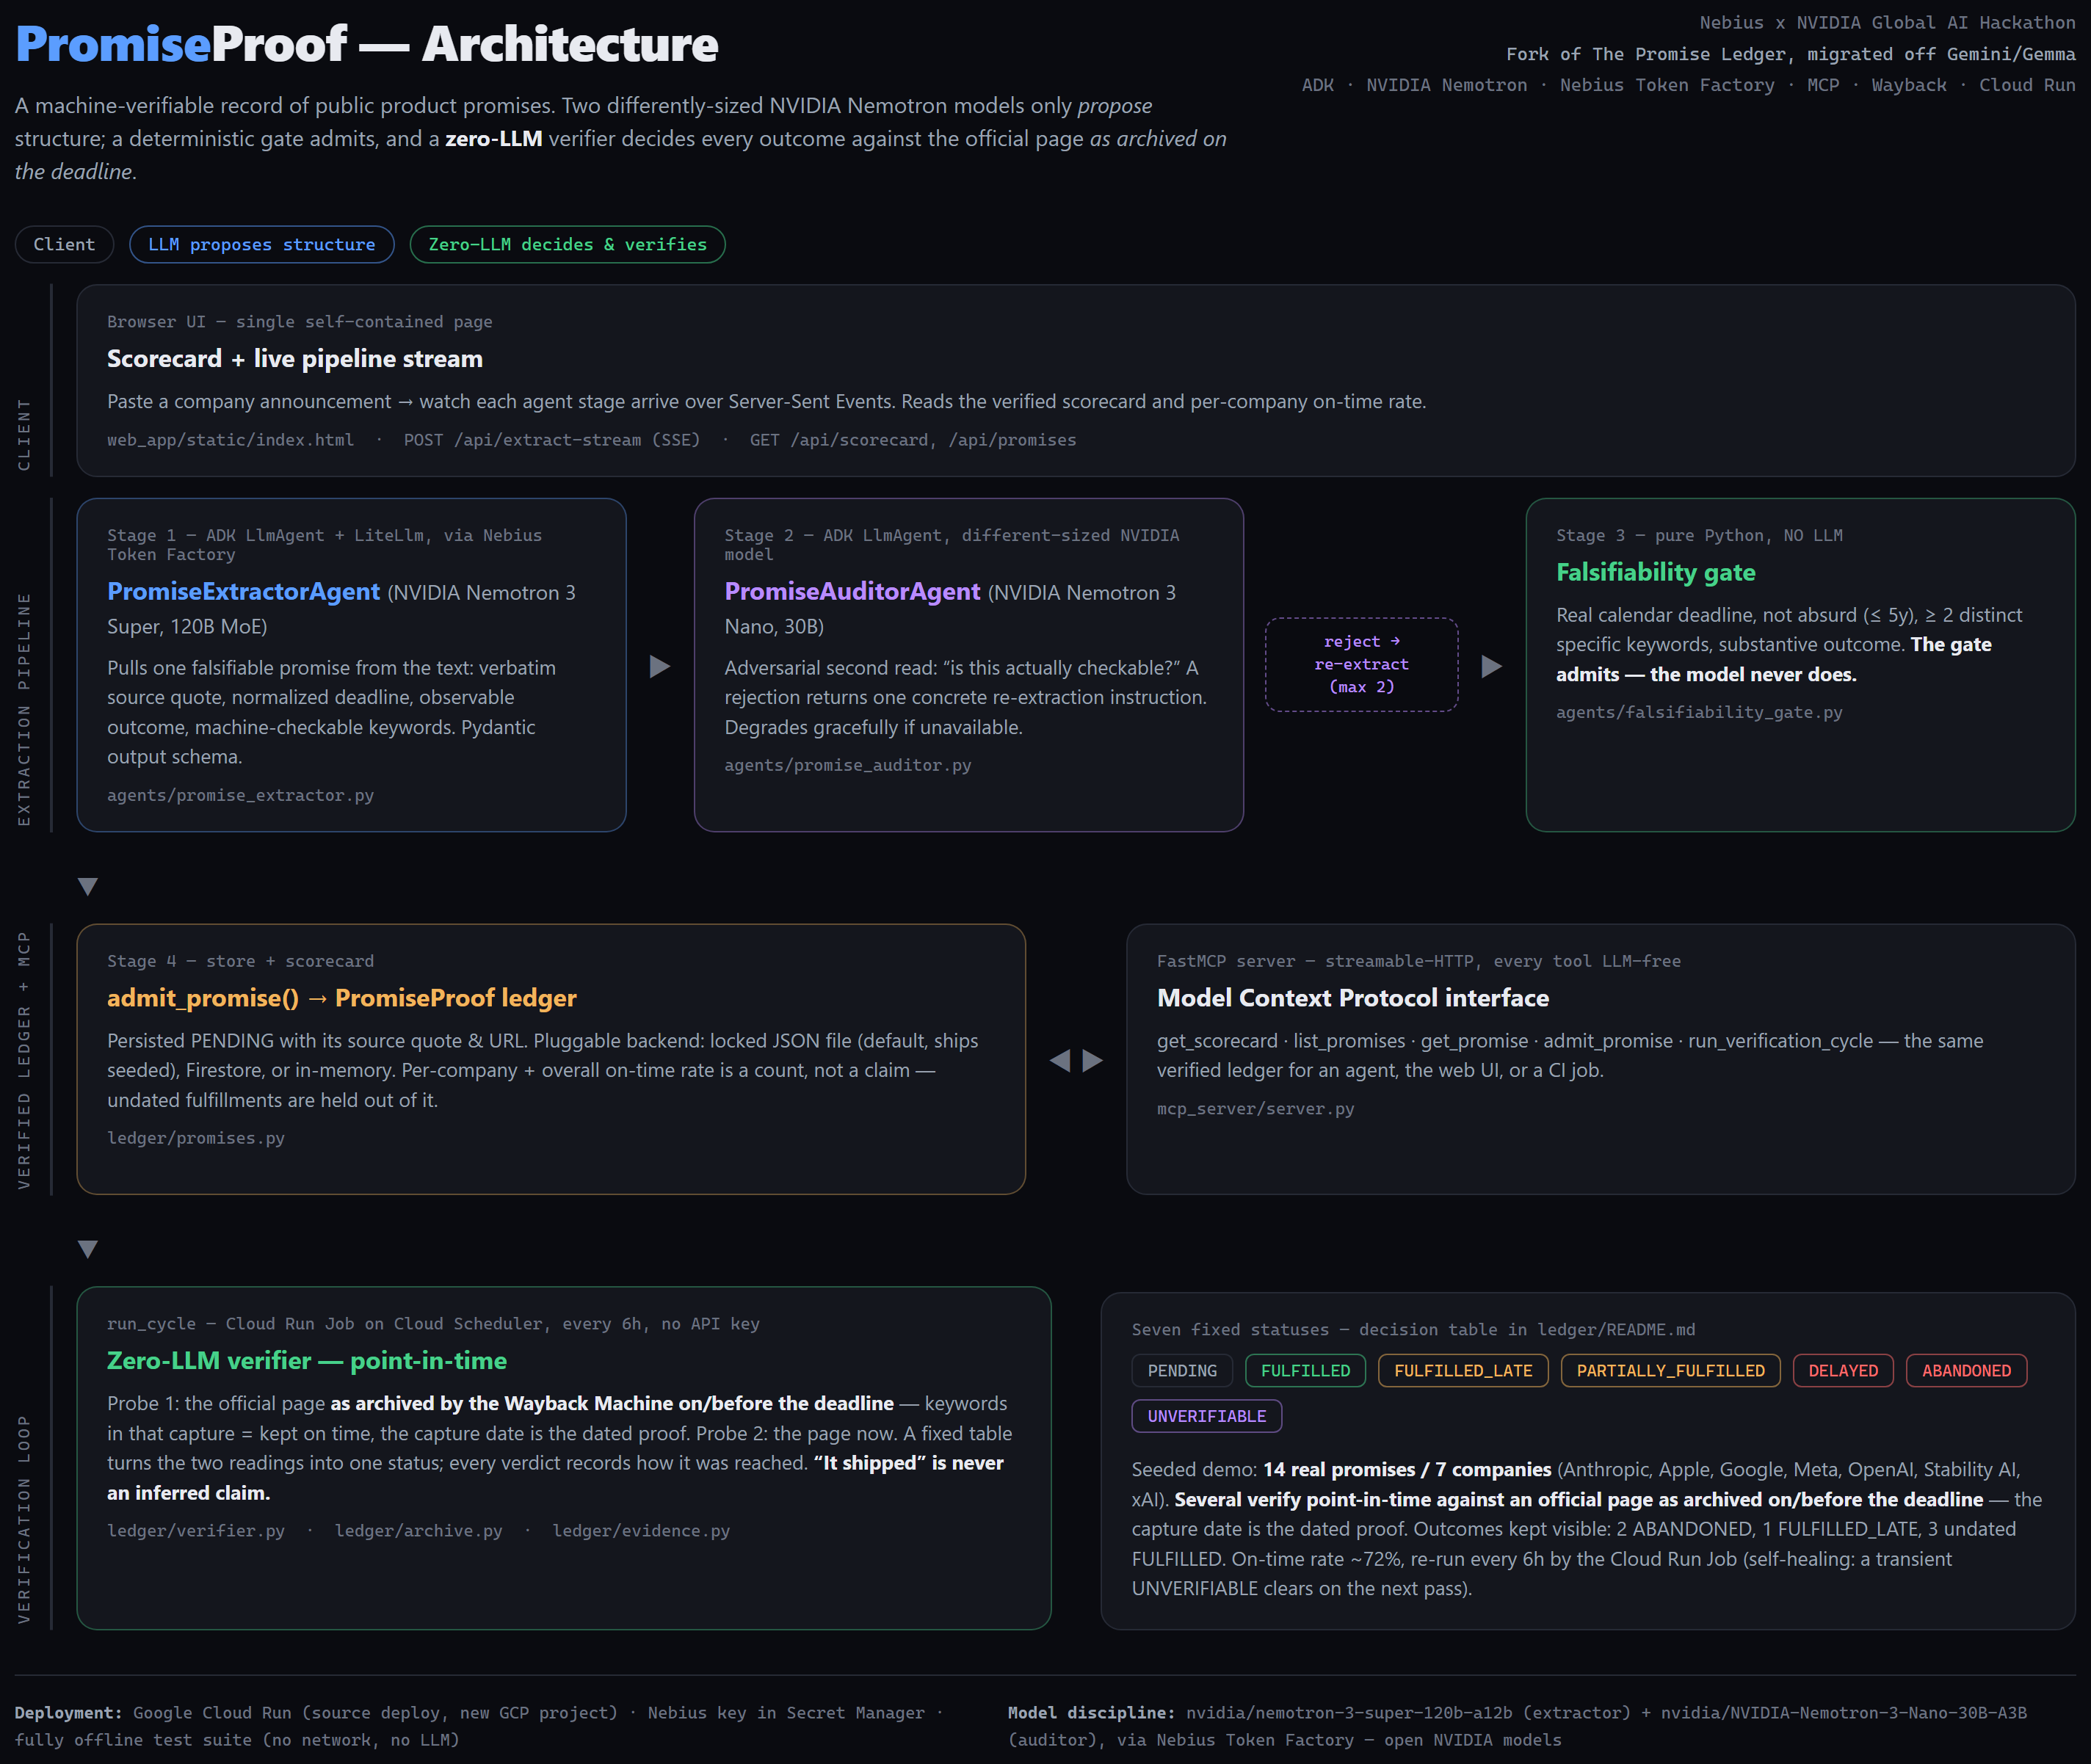
Announcement → Nemotron extractor → Nemotron auditor → deterministic gate → ledger. Verification is a separate zero-LLM Wayback path.
Inspiration
Every week a tech company makes a dated commitment: "open weights by the end of the year," "generally available next quarter," "available later this month." Some ship. Some ship late. Some quietly never happen. There is no honest, checkable scoreboard — only press releases and vibes. We wanted a ledger where the outcome of a promise is decided by a rule you can read, against a page anyone can open, with no model getting a vote.
Significantly updated for this hackathon
PromiseProof is a fork of an earlier project of ours, The Promise Ledger (repo), built for a different, earlier hackathon that used Google's Gemini and Gemma. For the Nebius x NVIDIA Global AI Hackathon we migrated the entire inference stack: both agents now run on open-source NVIDIA Nemotron models served through Nebius Token Factory, via ADK's LiteLLM integration, replacing every Gemini/Gemma call, key, config variable, test, and doc reference. The extractor and the adversarial auditor deliberately run two different-sized Nemotron models (Super and Nano) — the same "independent second opinion" integrity design as before, now built on NVIDIA's model family, which we believe satisfies the "at least one NVIDIA open source model" requirement twice over. This is a separate project, in a separate GitHub repo, deployed to a separate, new GCP project — the original submission keeps running unmodified for its own hackathon. The zero-LLM principle — no model ever decides a verdict — is unchanged, but the verifier itself was substantially extended for this hackathon: it now checks the official page as the Internet Archive captured it on or before the deadline (point-in-time evidence via the Wayback CDX API), every admitted promise is chained with SHA-256 so the ledger is tamper-evident, a GitHub Action re-verifies everything every 6 hours and commits the result, and the seeded ledger includes forward-dated promises that resolve during judging.
What it does
PromiseProof has already caught two AI companies quietly dropping a dated public commitment — Anthropic's "Claude 3.5 Haiku and Claude 3.5 Opus later this year" (Opus 3.5 was never released and the name left the roadmap) and Apple's personalized Siri — and it marks each ABANDONED with the original quote still attached.
It turns an announcement into an accountability record in four steps:
- Extract — an agent running NVIDIA Nemotron Super (Google ADK,
LiteLlmover Nebius Token Factory, structured output) pulls one falsifiable promise out of the text: the verbatim source quote, a normalized deadline, an observable outcome, and machine-checkable keywords. - Audit — a second agent on NVIDIA Nemotron Nano (a genuinely different, smaller model) adversarially checks whether the promise is actually checkable. A rejection sends the extractor back with a specific instruction, up to twice.
- Gate — pure Python, no LLM: a real calendar deadline that isn't absurd, at least two distinct specific keywords, a substantive outcome. The gate admits the promise — the model never does. The announcement text is untrusted and flows straight into the extractor's prompt, but a hostile announcement can't talk its way to a verdict:
FULFILLED/ABANDONED/ … is not a field any LLM in this system can write — only the gate and the zero-LLM verifier set a status. - Verify — zero-LLM, point-in-time. Two probes: (a) the official evidence page as archived by the Wayback Machine on or before the deadline — if the check keywords are in that capture, the promise was kept on time and the capture timestamp is the dated proof, no prose-date guessing and no source to trust but a neutral public archive; (b) the page now, which combined with (a) separates late from delayed from abandoned. A fixed decision table produces one of seven statuses (
PENDING,FULFILLED,FULFILLED_LATE,PARTIALLY_FULFILLED,DELAYED,ABANDONED,UNVERIFIABLE), and every verdict records how it was reached (wayback@deadline,live-page, …).
A per-company and overall scorecard rolls this up into an on-time rate that is a count, not a claim. When delivery is proven but nothing pins a date, the promise is FULFILLED (undated) and held out of the rate — neither on time nor late. The whole ledger is exposed over the Model Context Protocol — get_scorecard, list_promises, get_promise, admit_promise, run_verification_cycle — so an agent, the web UI, or a CI job all read and write the same verified record.
The demo ships seeded with 14 real promises across 7 companies (Anthropic, Apple, Google, Meta, OpenAI, Stability AI, xAI), each quote transcribed from the linked primary source. Several verify point-in-time against an official page as archived on or before the deadline — the Meta Llama 3 and Llama 3.1 posts, Anthropic's Claude 3 Haiku page — where the capture timestamp itself is the dated proof. Outcomes are kept visible, not smoothed: 2 ABANDONED (Anthropic's Claude 3.5 Opus and Apple's personalized Siri — no delivery evidence 180+ days past the deadline), 1 FULFILLED_LATE (Anthropic's Claude 3.5 Haiku, four days into November after a "later this month" promise), and 2 FULFILLED (undated) (delivery proven, nothing pins the date). OpenAI's ChatGPT-for-Windows page blocks non-browser clients, so on a slow pass it can fall to UNVERIFIABLE and the 6-hourly cycle recovers it to FULFILLED on the next run — the self-healing working. The seeded on-time rate sits around 75% and moves on its own every cycle — that's the design, not a bug.
How we built it
- Google ADK
LlmAgent+InMemoryRunnerfor the extractor and the auditor, both wired through ADK's LiteLLM integration (google.adk.models.lite_llm.LiteLlm) pointed at Nebius Token Factory's OpenAI-compatible endpoint — the extractor on NVIDIA Nemotron 3 Super (nvidia/nemotron-3-super-120b-a12b, 120B MoE), the auditor on NVIDIA Nemotron 3 Nano (nvidia/NVIDIA-Nemotron-3-Nano-30B-A3B, 30B). Structured Pydantic output schemas on both. - FastMCP server exposing the ledger over MCP (streamable-HTTP).
- FastAPI backend: a Server-Sent-Events endpoint streams every pipeline stage as its real agent result arrives, plus read endpoints for the scorecard. A single self-contained static page renders it.
- The verifier is plain Python +
httpx: the Wayback availability API for the point-in-time capture, then fetch → strip scripts/markup/Wayback-toolbar → decode entities → whole-token keyword match (word-boundary aware so "GA" doesn't match "navigation") → fixed decision table. Prose-date parsing is a fallback for when no capture near the deadline exists. - Storage behind a small backend protocol: a locked JSON file (the seeded demo ships this way, no cloud credentials needed), Firestore, or in-memory for tests.
- Google Cloud Run for the public web service, and a separate Cloud Run Job (
ledger-cycle) that runspython -m ledger.run_cycle --allevery 6 hours on Cloud Scheduler — the zero-LLM re-verification pass. No API key, no model call. The Job and the web service share one Firestore ledger, so a promise coming due, an official page changing after the fact, or a transient fetch failure clearing up is picked up on the next pass and the public scorecard moves with no human in the loop. - 120+ tests, no network, no LLM. Several adversarial QA passes plus judge-style audits hardened the verifier, the gate, the scorecard, XSS in the UI, and the MCP surface — started in the parent project, then extended and re-verified against the new inference stack, the point-in-time verifier and the hash chain.
Challenges we ran into
- Migrating a working, model-agnostic-by-design pipeline without breaking its integrity guarantee. The whole system's credibility rests on "the model proposes, deterministic code decides" — so the migration had to swap only the two
LlmAgentmodel wrappers and every place that named the old provider (env vars, health checks, docs, tests), while leaving the gate/verifier/ledger untouched. ADK's LiteLLM bridge made this a small, contained change rather than a rewrite. - NVIDIA Nemotron is a reasoning model. Gemini structured output was clean; Nemotron can wrap its answer in a
<think>…</think>trace. We handle it three ways: the system prompts ask fordetailed thinking off,LiteLlm(drop_params=True)tolerates request fields Nebius doesn't support for a given model, and the orchestrator's parser strips reasoning traces / fences and slices the outer JSON before validating. A parametrized test suite covers those output shapes. - An official page only shows its state today. A changelog is a rolling window; a pricing page shows this week's prices. So "was it true by the deadline" often can't be read off the live page at all. The fix is the Wayback Machine: fetch the official page as captured near the deadline, and let the capture timestamp be the dated evidence. That turned a hand-picked-URL problem into a deterministic, tamper-evident one.
- The archive isn't complete, and some vendor pages are anti-bot / JS shells. When there's no usable capture on/before the deadline, the verifier falls back to a date read off the current page — a weaker signal, biased toward
FULFILLEDoverFULFILLED_LATE. A few rows (xAIGrok-2,AppleChatGPT-in-iOS,GoogleGemini Advanced) point at the relevant Wikipedia article rather than the vendor page, because the vendor page renders as an empty JS shell to a non-browser client; Wikipedia is neutral, dated and archived, and every such row carries a comment saying so inseed_data.py. - Keyword brittleness. If a page describes a shipped feature in words that don't contain the check keywords, the verifier under-reports it — it stays
FULFILLED (undated)rather than being assumed on time. - Not letting the model decide. Every outcome stays in deterministic code — the LLM only proposes structure, it never grades.
What we learned
An "AI accountability" tool is only trustworthy if the AI isn't the judge. Pushing every verdict into a fixed, public rule made the product both defensible and genuinely useful — and forced us to be honest about the cases the rule can't settle. Migrating providers also proved the design's real claim: because verification never touches an LLM, swapping Gemini/Gemma for NVIDIA Nemotron changed zero verdicts in the seeded ledger.
What's next
- A larger, continuously growing promise set across more sectors (not just AI roadmaps).
- Corroborate against immutable registries too — HuggingFace / GitHub Releases APIs give a dated, machine-readable "when did X ship" with no scraping at all.
- An append-only, hash-chained ledger so a past verdict can't be quietly changed.
- A public, embeddable per-company badge driven by the live scorecard.
- Try more NVIDIA open models (Nemotron Ultra for the extractor on richer announcements) as they land on Nebius Token Factory.
Built With
- fastapi
- fastmcp
- google-adk
- google-cloud-firestore
- google-cloud-run
- google-cloud-scheduler
- httpx
- litellm
- model-context-protocol
- nebius-token-factory
- nvidia-nemotron
- pydantic
- python
- wayback-machine

Log in or sign up for Devpost to join the conversation.