-
-
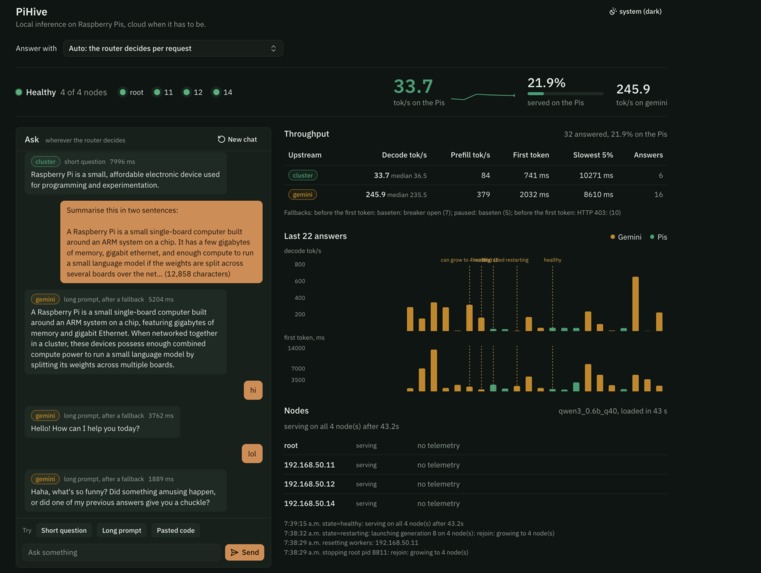
Overview
-
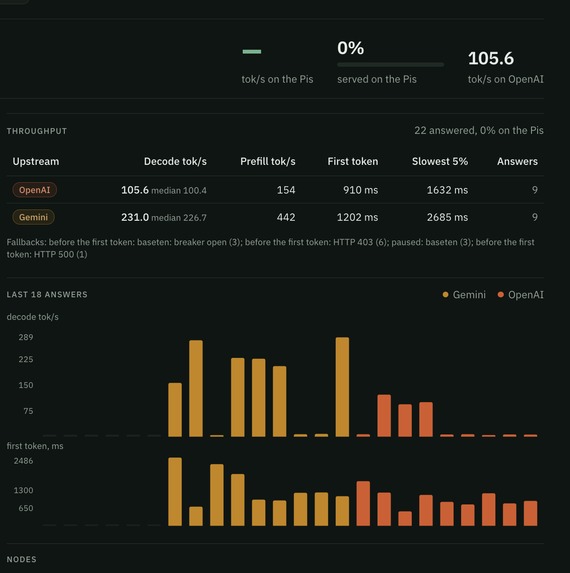
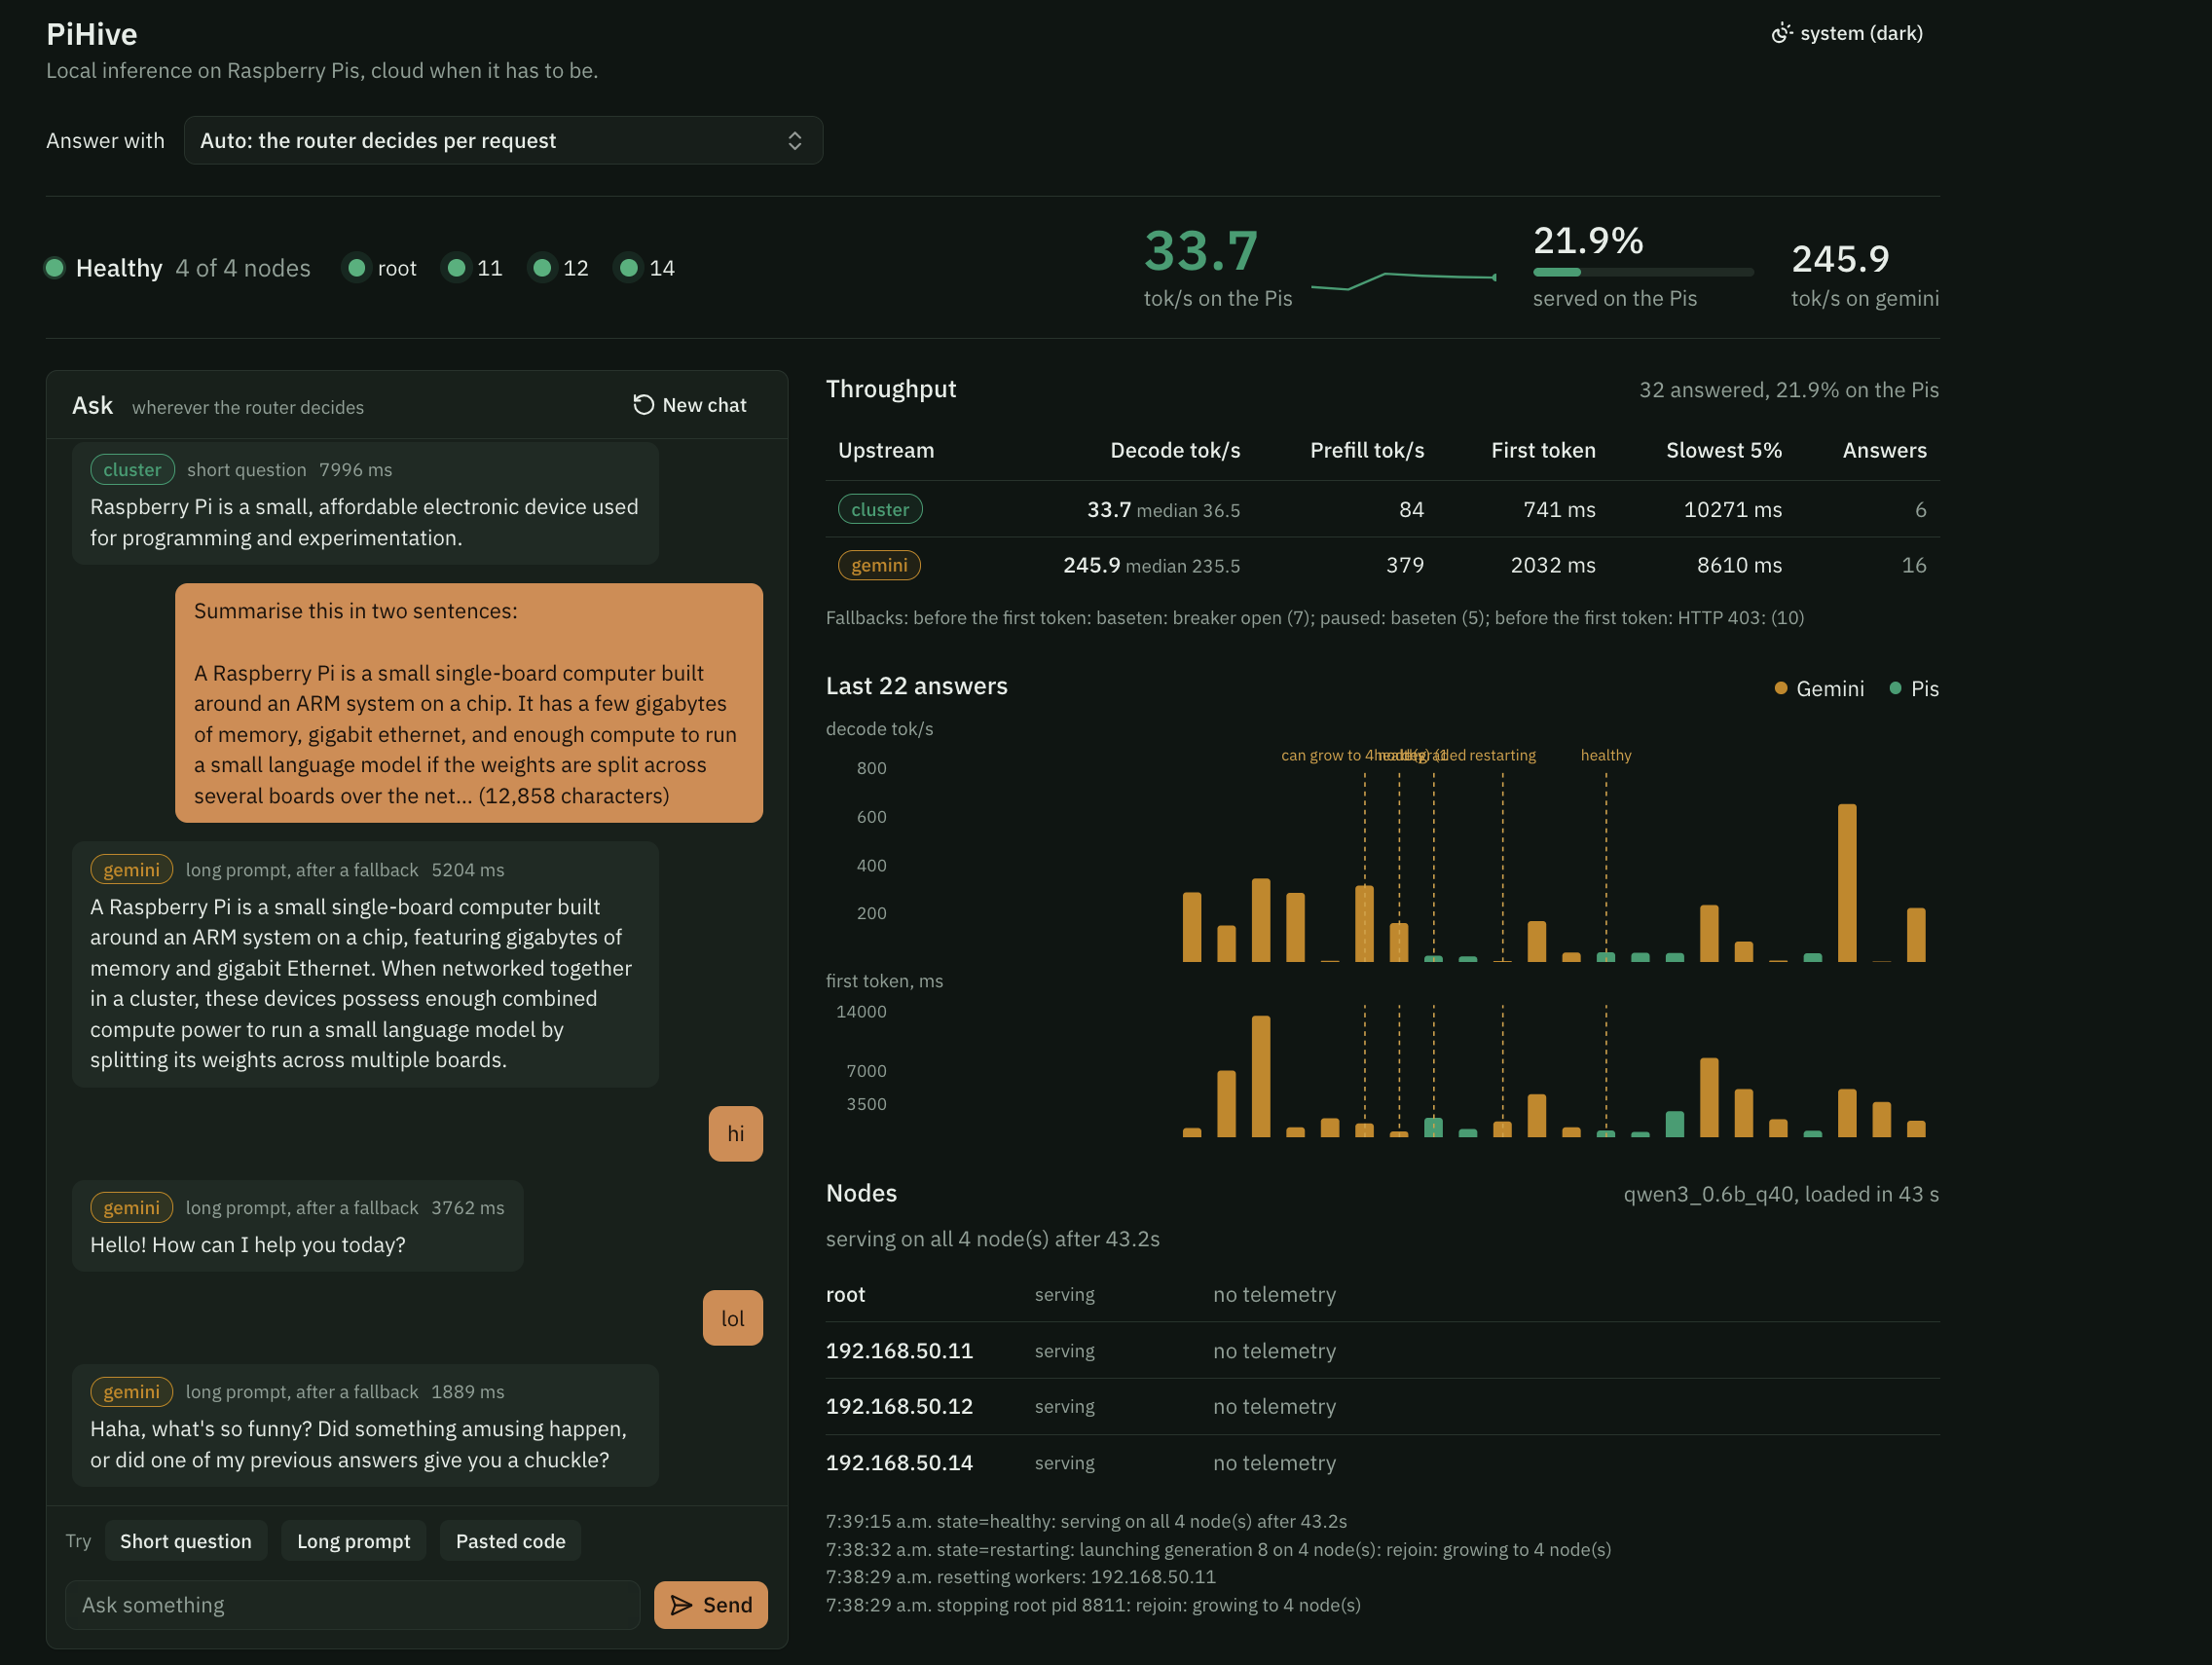
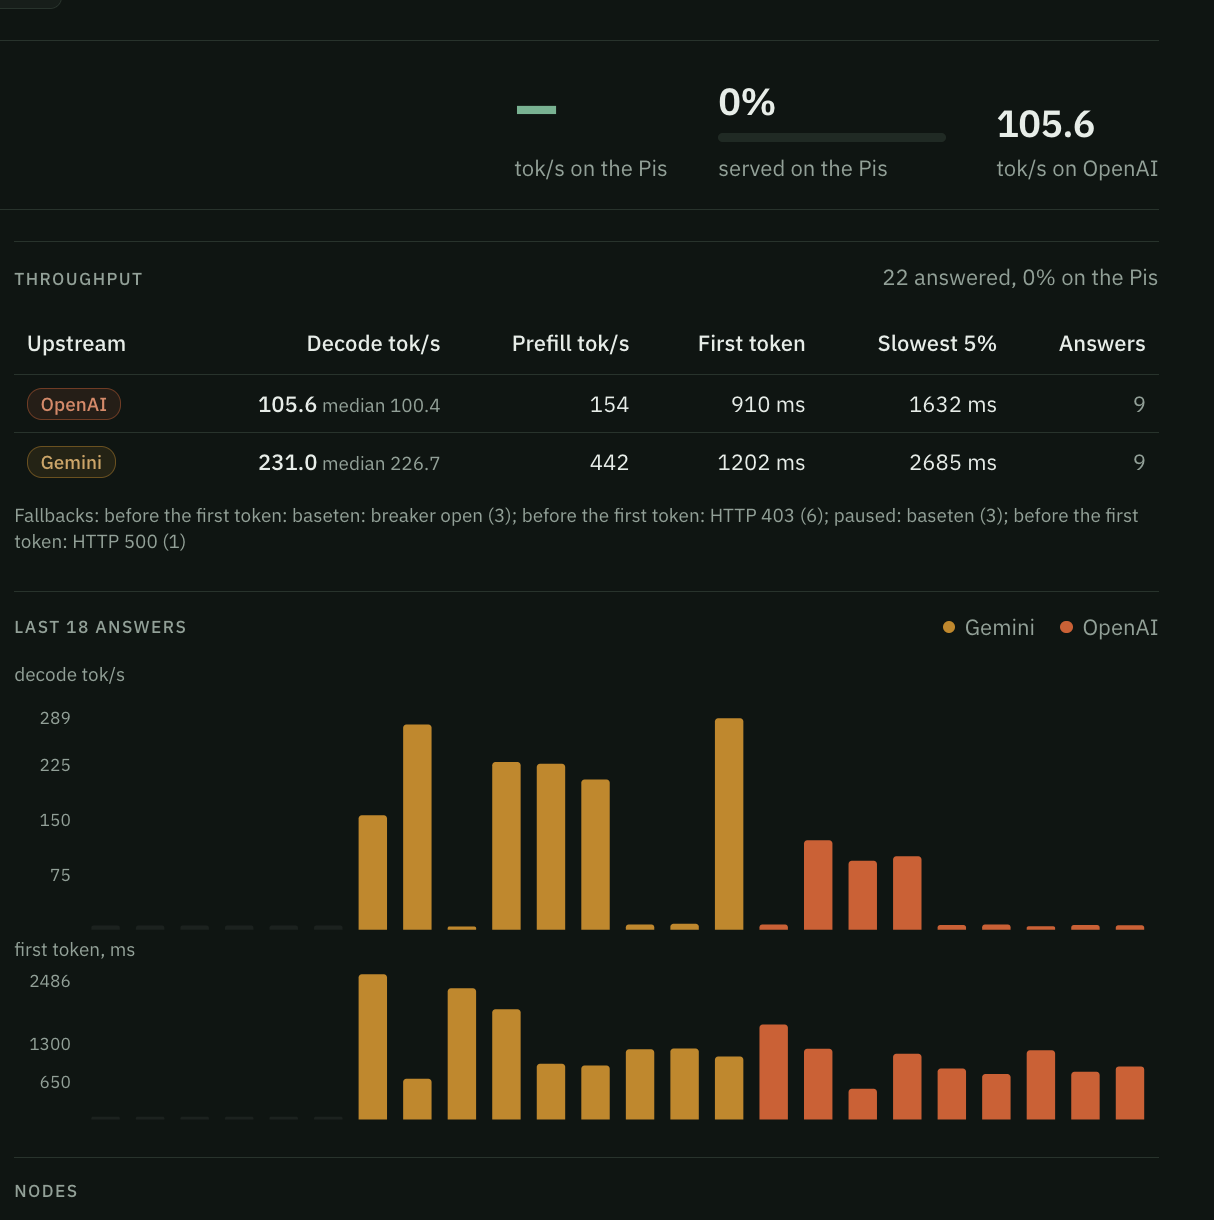
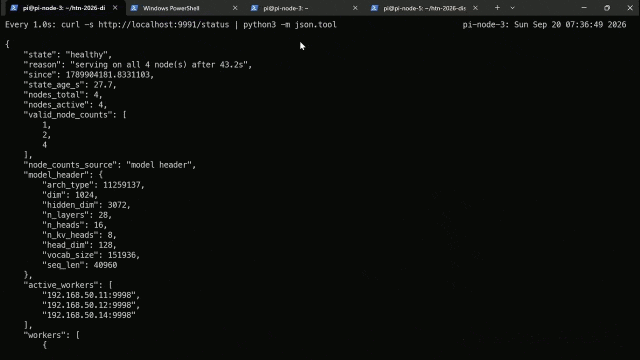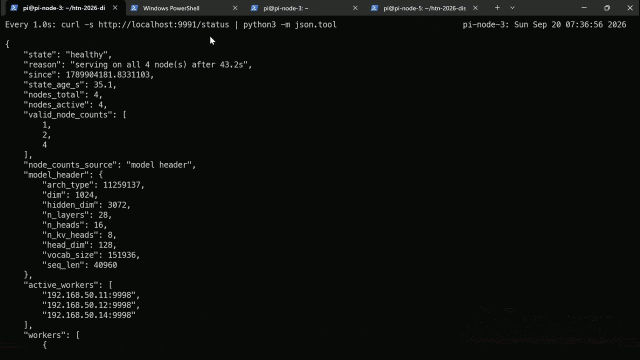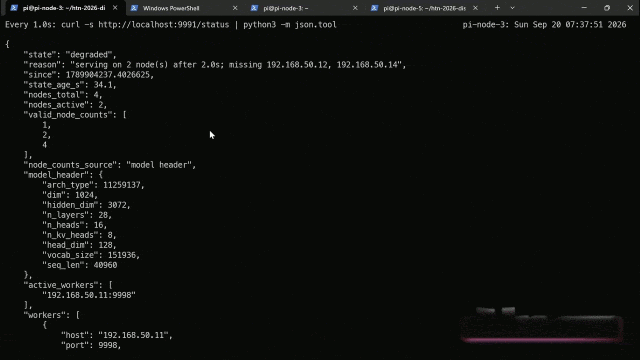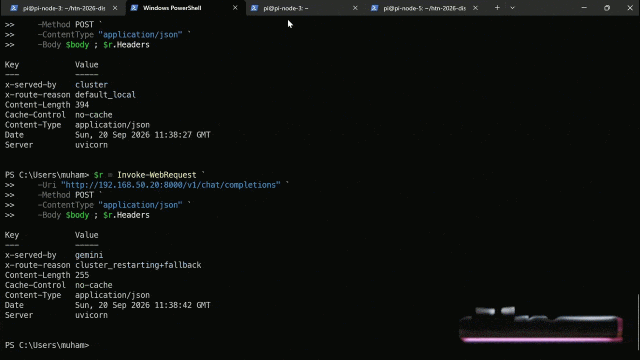
PiHive Dashboard
-
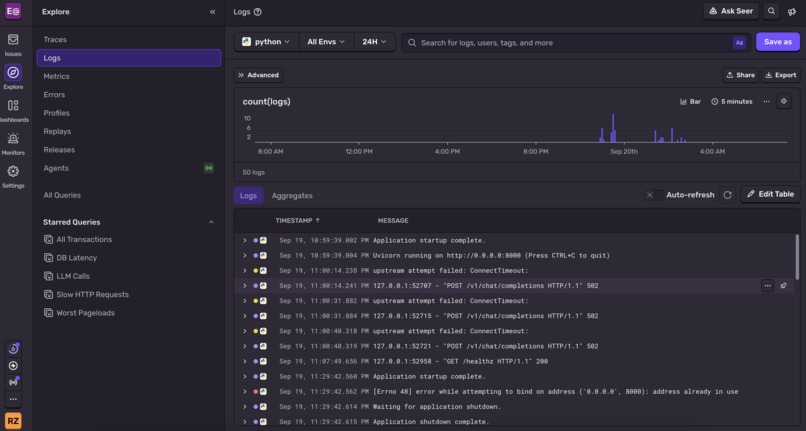
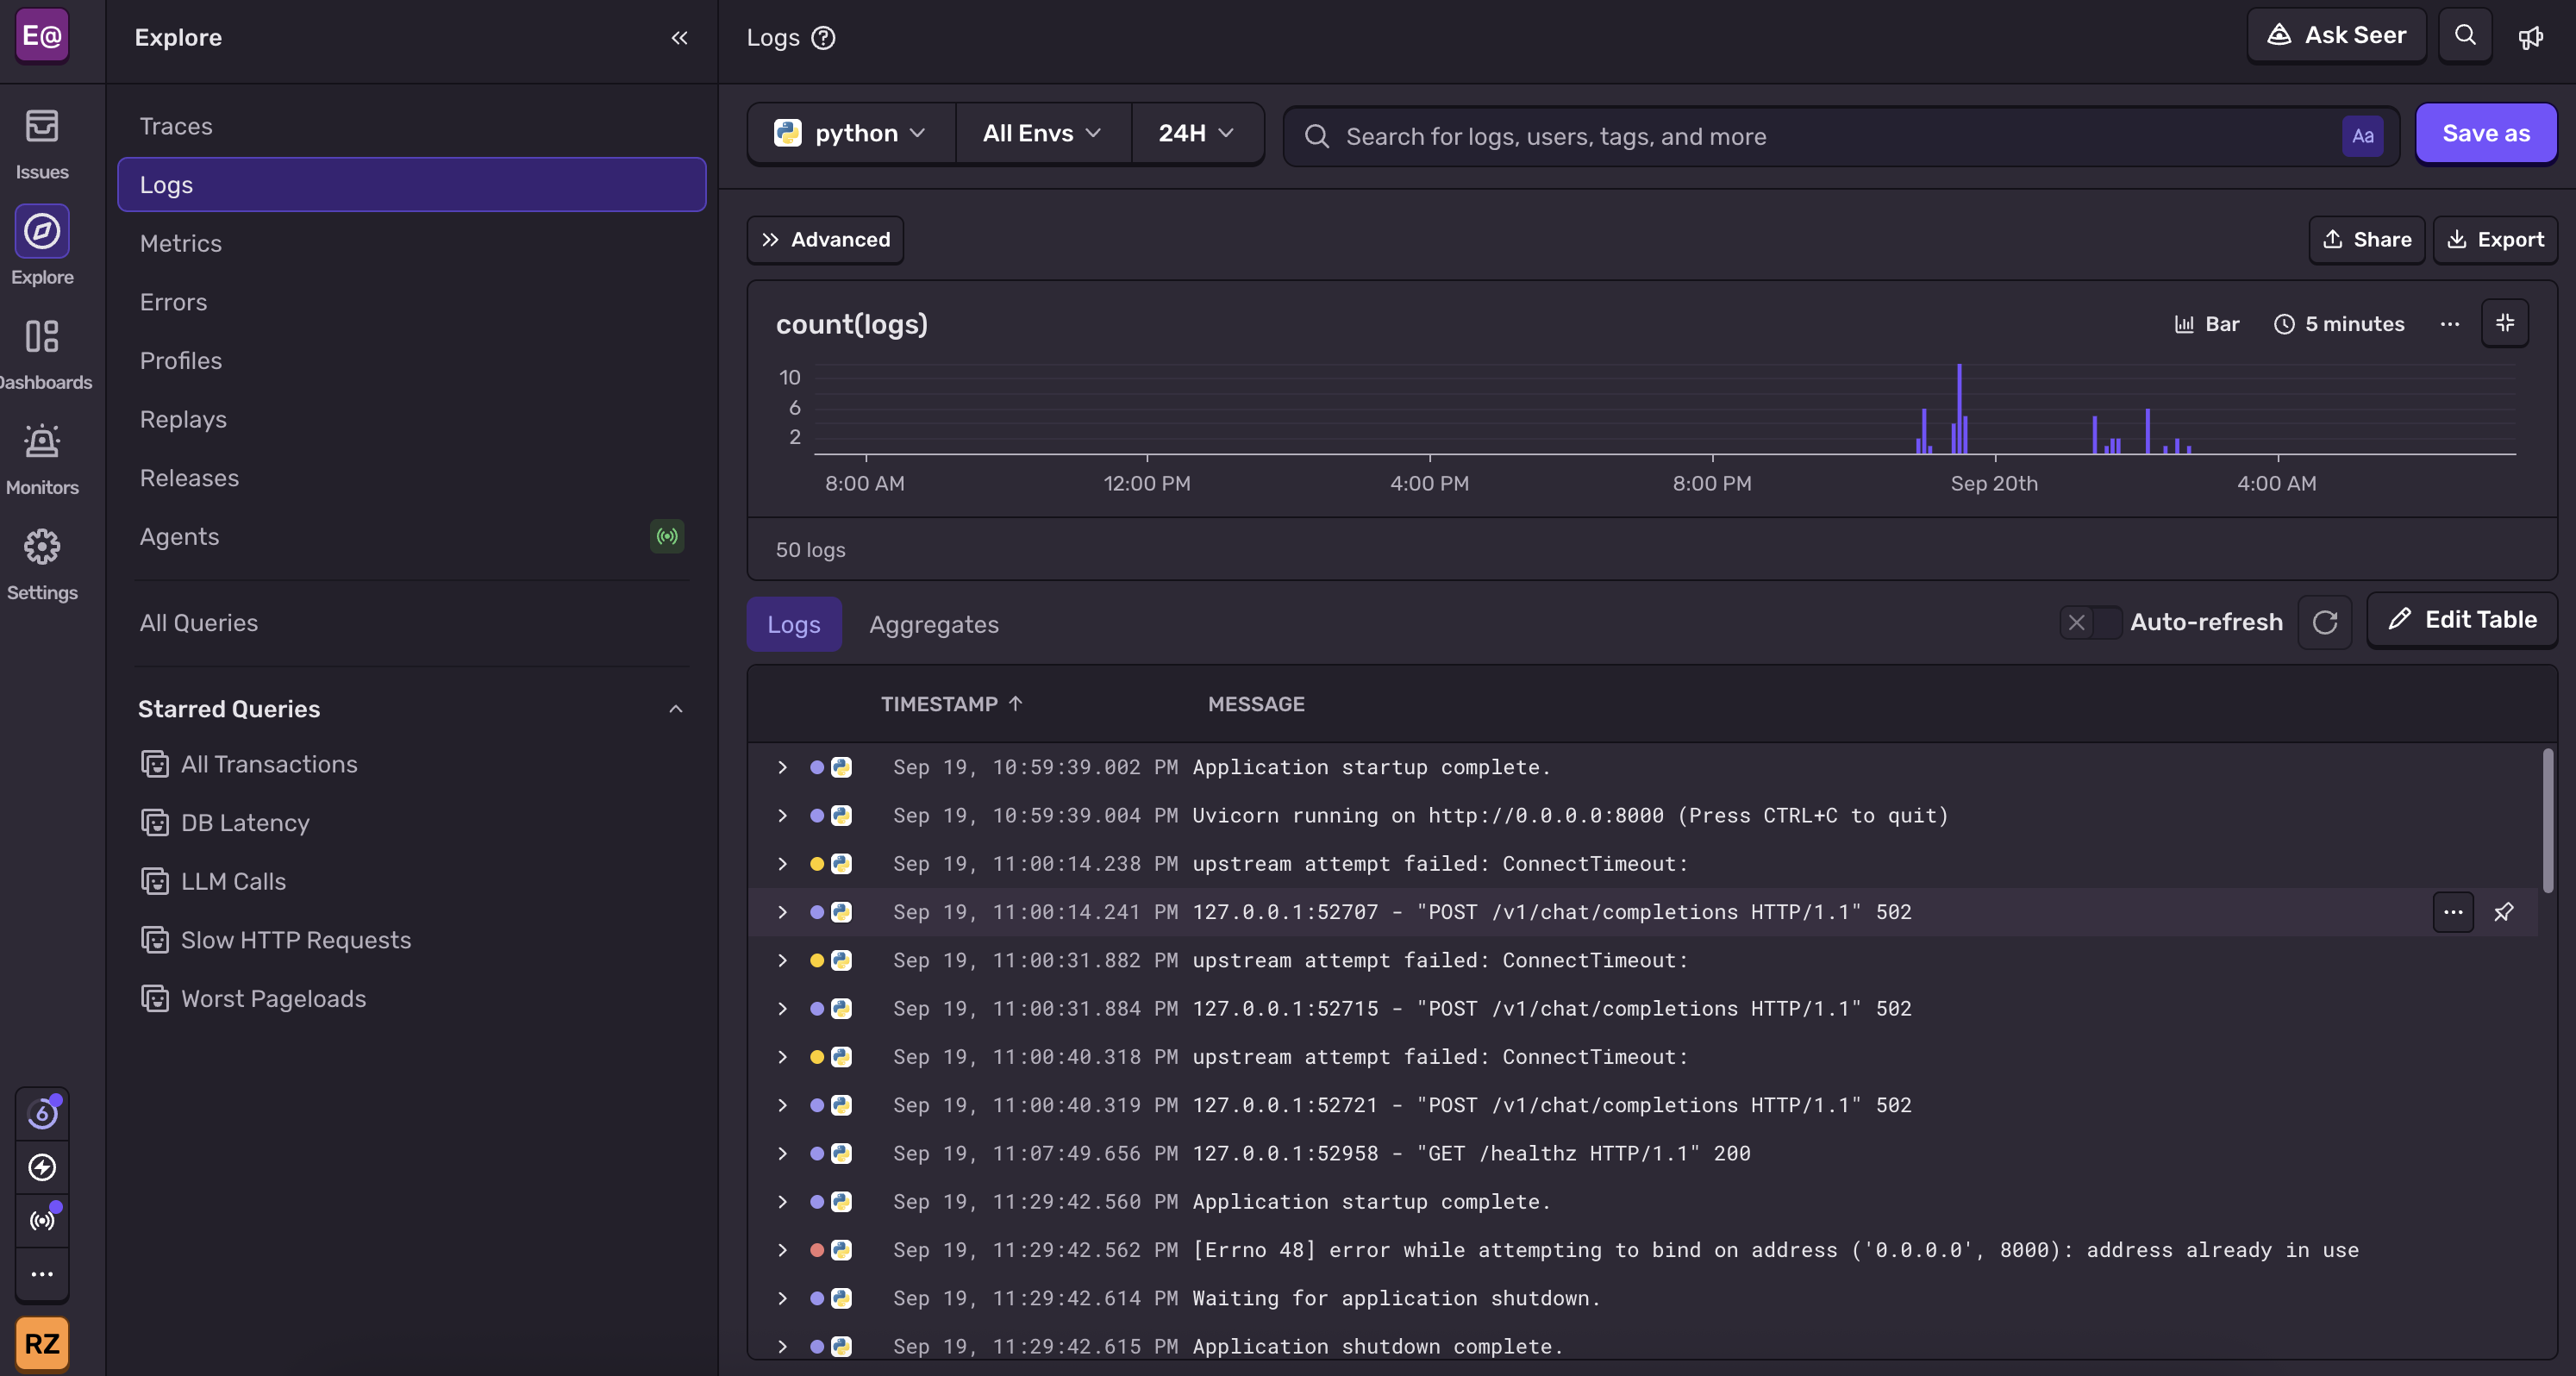
Sentry Real-Time Observability Dashboard
-
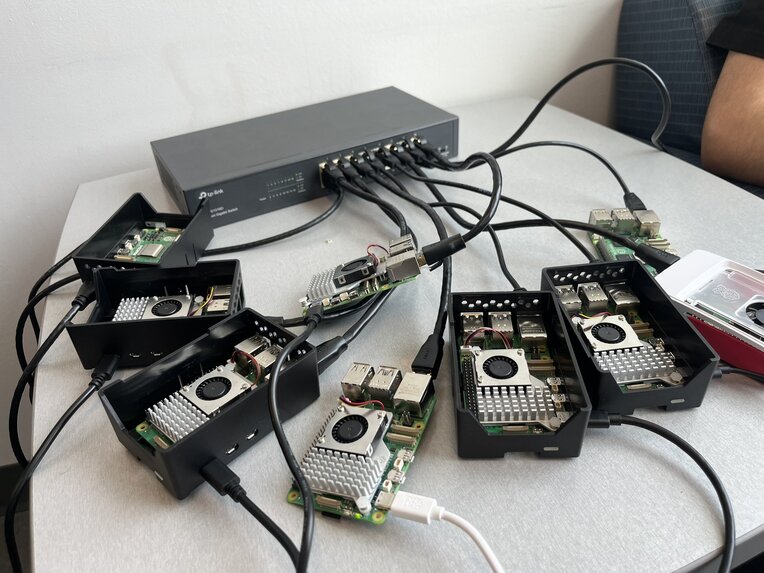
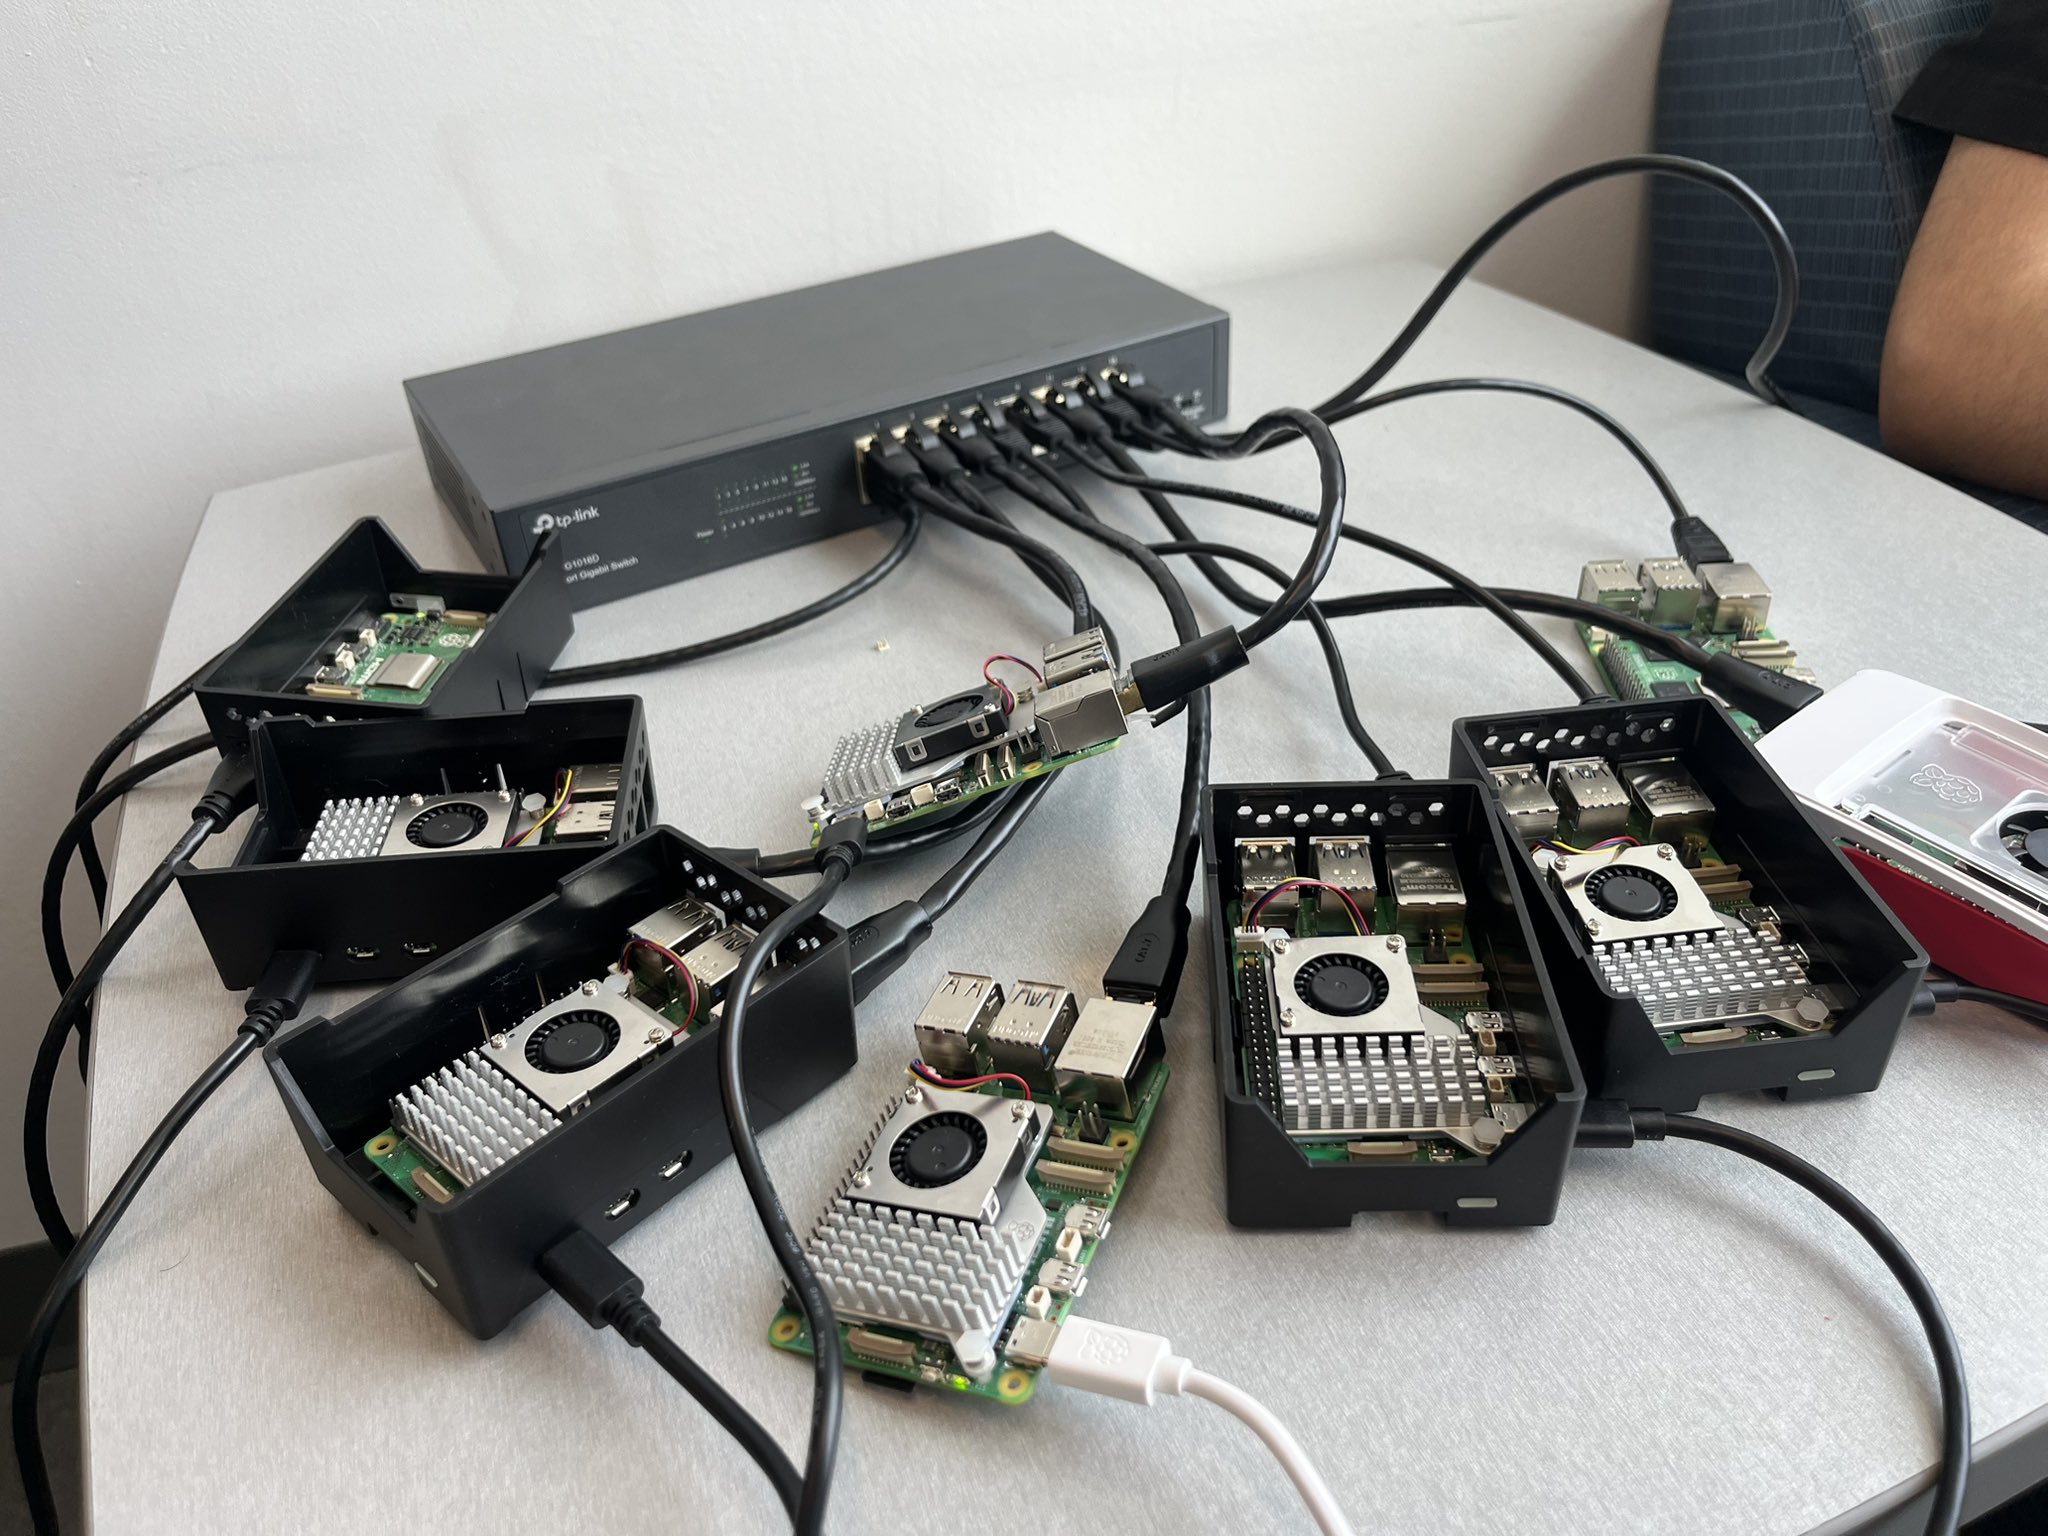
Our "datacenter" rack ;)
-
 GIF
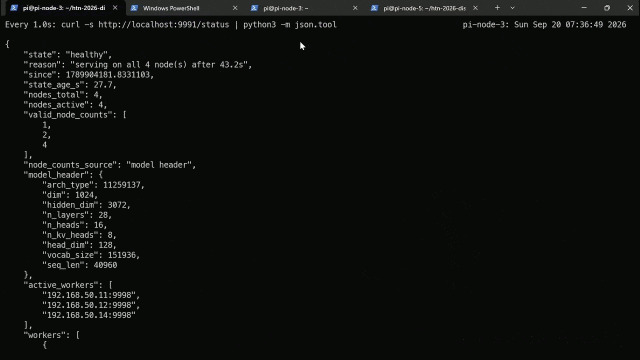
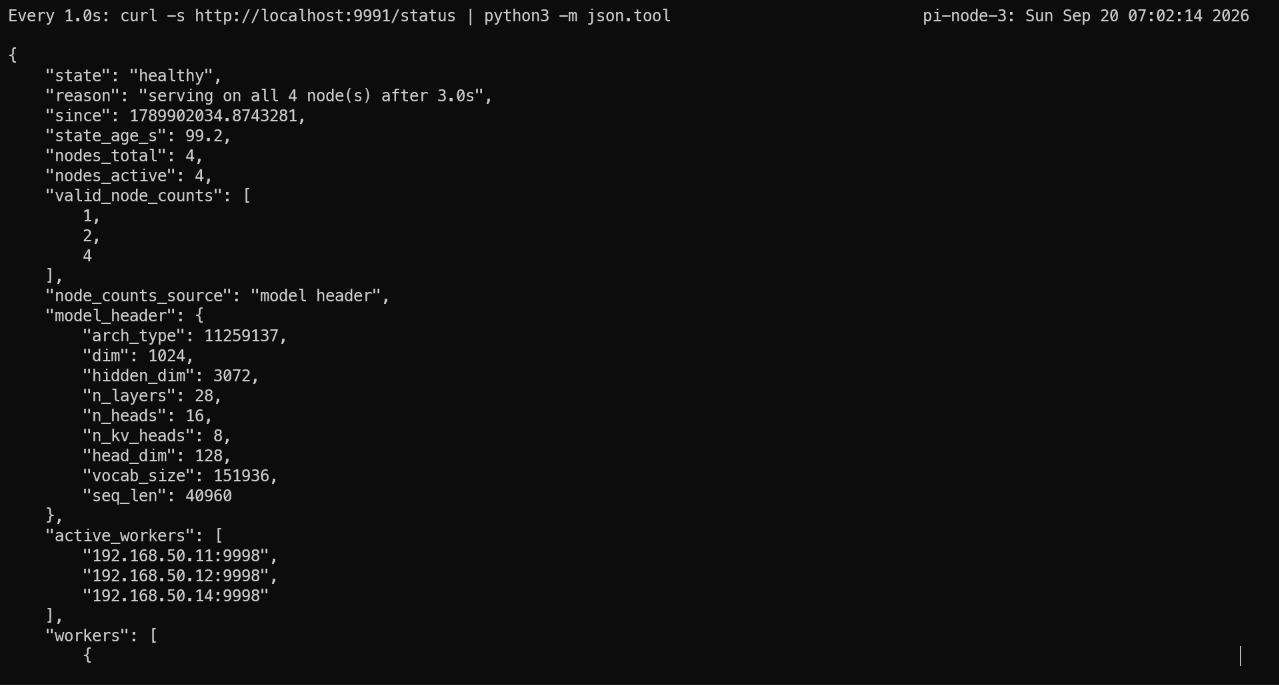
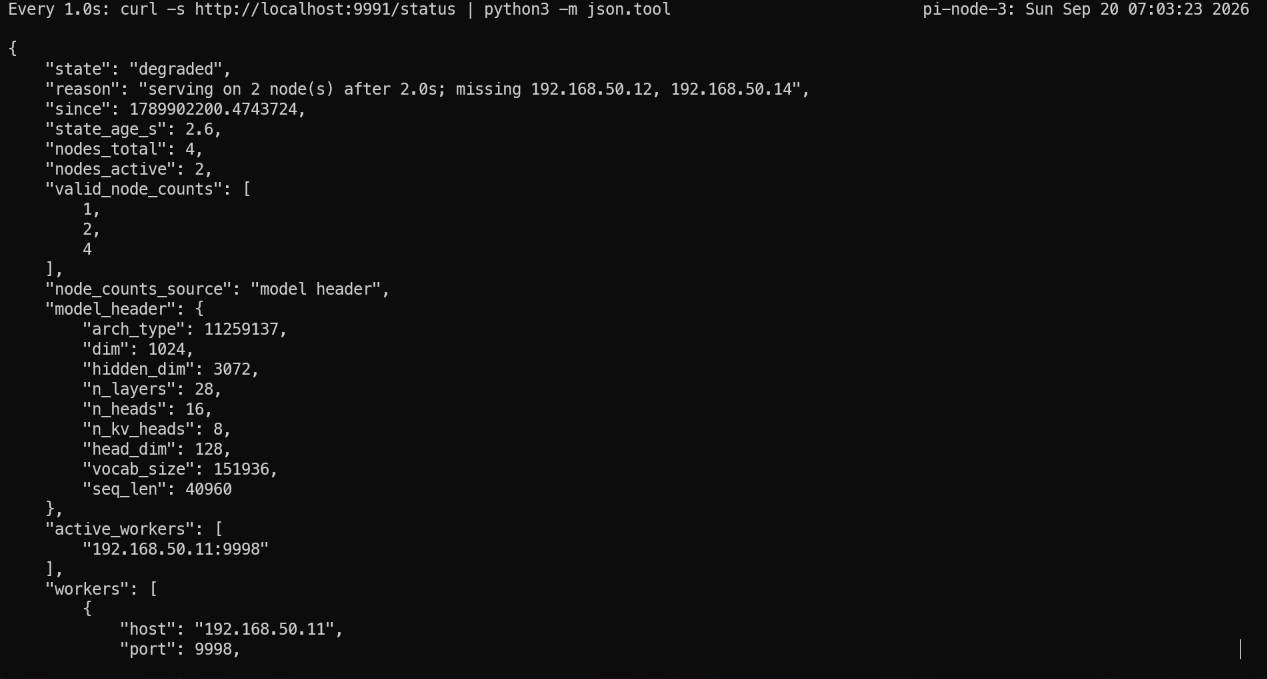
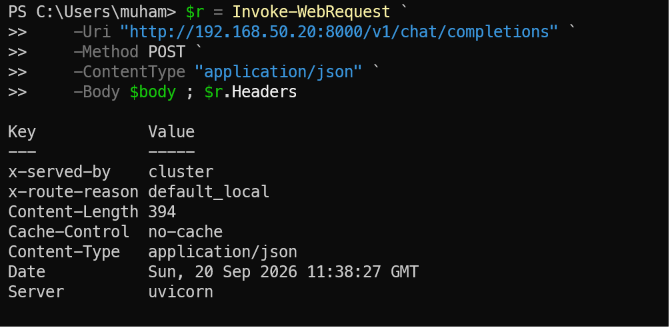
Demo of our cluster serving requests in a healthy+degraded state (after unplugging a Pi), followed by rerouting to online during a restart
-
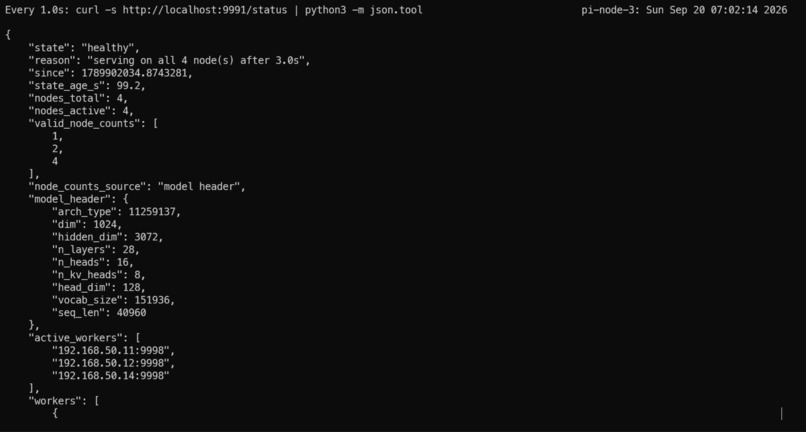
Our cluster running normally
-
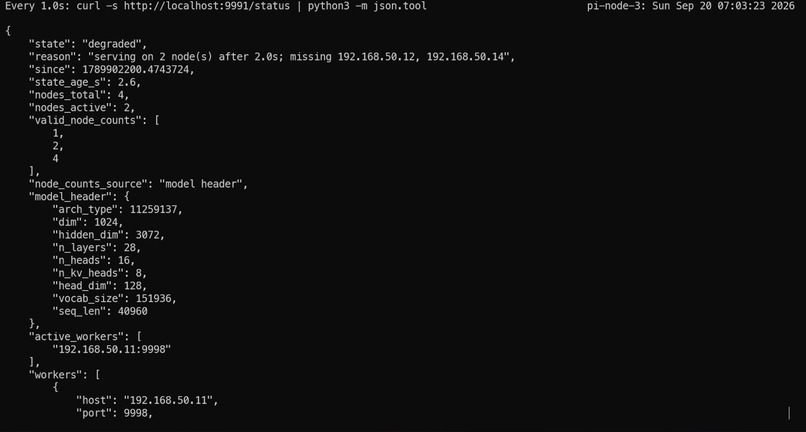
Cluster running with degraded nodes
-
Running models locally
-
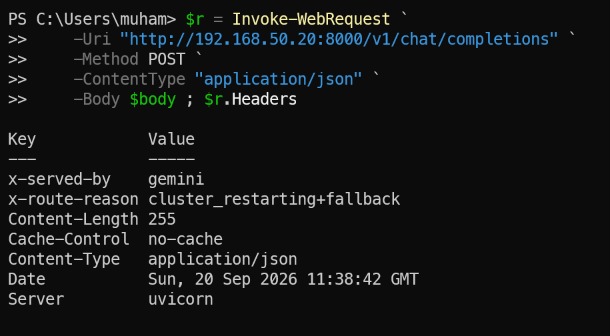
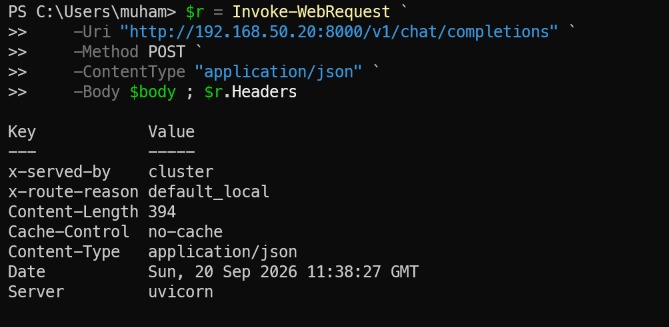
Fallback to online model
PiHive
Your own datacentre at home.
Inspiration
Local inference is heavily gated on hardware: a useful model won't fit on any single cheap device, so "local AI" in practice means "buy a GPU." We noticed the big labs solved this with a pattern... Apple Intelligence and Gemini Nano both run a small model on-device and silently escalate hard requests to a big model in the cloud. But their version requires custom silicon: Neural Engines, TPUs. We wondered: could you get the same architecture out of the cheapest computers you can buy, ganged together?
The usual reasons to own a Raspberry Pi: block ads on your home network, emulate a SNES, run a weather station in the garden, make a doorbell that texts you. Sensible projects for a computer with 8 GB of RAM and no GPU.
We tried to run a 30-billion-parameter language model using nine of them.
it worked.
What it does
PiHive is a cluster of Raspberry Pis running one LLM together via tensor-parallel distributed inference, no GPU anywhere, behind a single-compatible endpoint. A router decides where each request belongs:
- Simple requests stay local... served by the cluster, private and free
- Heavy requests escalate to an H100 on Baseten... long context, hard reasoning
- Frontier-class agentic work escalates to the OpenAI API... with Gemini and Snowflake Cortex as further upstreams in the escalation ladder
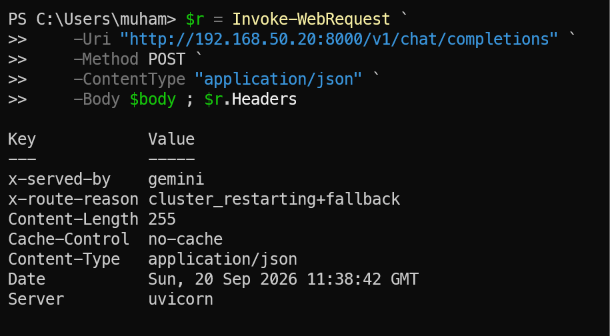
Say you Pull a Pi's power cable while it's mid-answer, the text will keeps streaming. The router catches the dead stream, hands the half-written response to the cloud model, and asks it to continue from exactly where the cluster stopped. No error, No retry, No restart, The sentence just finishes.
The twist: the H100 isn't just the fallback. It's the teacher. We used it to distill the large model into the small one running on the Pis, generated thousands of coding-agent-style training examples from the big model, then LoRA fine-tuned the small one on its outputs. The same GPU that handles the requests our cluster can't is the reason our cluster can handle any at all. Unfortunately, the Baseten servers went down :( We didn't finish training and had to use prebuilt models :(
How we built it
The cluster. 9 Raspberry Pi 5s on a gigabit switch. 8 inferencing, one router. Each token requires all four nodes to synchronize over the network, so we wired everything with ethernet cables, disabled Wi-Fi, and verified ~940 Mbps between every pair before trusting any number. Models tested include Qwen3-30B-A3B and Gemma3-1B-it
The router. FastAPI, OpenAI-compatible /v1/chat/completions with full SSE streaming, plus /v1/responses for Codex. It routes on cluster health first, then prompt size, then explicit escalation, and never returns an error while any upstream is alive. Failover is two-phase: before the first token reaches the client we retry silently elsewhere; after bytes are on the wire we switch to continuation instead. Every decision lands in a JSONL log; that's where the local-percentage number comes from. 76 unit tests, 39 supervisor tests, 34 end-to-end checks.
The supervisor. A dead worker doesn't crash distributed-llama, it hangs it. So ours health-checks every node and relaunches on the largest surviving set the model actually permits, publishing cluster state over HTTP so the router shifts traffic to the cloud during the restart window. Pull a Pi's power and the system degrades instead of dying.
Codex as a teammate. We generated 2,734 coding-agent instruction/response pairs from the cloud model, the idea being to fine-tune the local model on its own teacher's output, so the small model learns the voice of the model that covers for it and the handoff gets harder to spot. Held-out prompts, deduplicated against the training set, judged pairwise with the order swapped to cancel position bias. The dataset and the full pipeline shipped!
Sponsor tech, doing real work
Solana — the trust layer. Solana is usually thought of as crypto; we used it as a public, tamper-proof logbook for the cluster. A custom on-chain program on Devnet holds one Cluster account per router and one Job account per answer. When the cluster forms or changes, the router writes which nodes are serving. When an answer finishes, it writes the request id, the serving tier, and the sha256 of the answer text. The Cluster account keeps running counts of total and locally served answers that nobody can edit after the fact. Only the router's key can write, the Pis hold no keys, and the program rejects unknown nodes and duplicate jobs. Anyone can verify what the cluster did — not just read it off a slide.
Sentry — the observability layer. We went beyond error monitoring: Tracing gave us the per-stage millisecond breakdown behind our latency HUD (and exposed the thermal-throttling Pi that was pacing the whole cluster), Logs turned our routing-decision stream into something searchable at 4am, and AI agent monitoring watched the escalation behavior itself — flagging when the router's handoffs to cloud models looked risky or degraded before they became demo-breaking failures.
Gemini — routing intelligence and fallback. Gemini does lightweight difficulty classification for the router — deciding whether a request belongs on the cluster or in the cloud — and serves as a fallback upstream in the escalation ladder, so a single provider outage can't take down the tier above the Pis.
Snowflake — one more honest tier. Via Snowflake's REST API, Cortex-hosted LLMs sit in the same escalation ladder as Gemini and OpenAI: another genuinely independent upstream the router can hand a stream to, integrated in the same OpenAI-compat layer as everything else.
Baseten — the muscle. The H100 tier that catches everything the Pis can't, and the teacher whose outputs our distillation dataset came from.
Challenges we ran into
Tensor parallelism is only as fast as your slowest node. In a synchronized cluster, the slowest node sets the pace for everyone. All four wait on each other at every layer, so one throttling board doesn't cost you a quarter of your throughpu, it drags the whole cluster to its speed. We found this out the hard way. per-node diagnostics revealed one Pi thermal-throttling while the other three sat idle waiting for it, in a synchronized cluster, one hot node paces everyone.
Failure doesn't look like failure. Kill a worker and the root process doesn't error, it hangs forever. Building graceful degradation meant building detection, restart orchestration, and router-side traffic shifting ourselves, because the inference layer gives you none of it.
OpenAI-compatible is a spectrum, not a standard. Real clients like Claude Code send model names your proxy has never heard of, expect exact /v1/models response shapes, and exercise SSE streaming edge cases. We learned to never 404 on an unknown model name, treat it as a routing hint, rewrite it per-upstream, and route on policy instead.
ENOSPC at the worst moments. Between model weights, quantization artifacts, and five SD cards, we learned to respect disk space the hard way, including one silent half-completed install that cost us an evening of debugging a binary that didn't exist.
Three of us disagreed about which Pi was the root, and all three beliefs were encoded in different config files, so the router was pointed at a worker that serves no HTTP. almost went very sideways.
What we learned
Distributed inference on constrained hardware is a systems problem far more than an ML problem. Network, thermals, disk, and failure handling mattered more than anything model-related.
Tensor parallelism ships activations between all nodes on every layer, so more nodes only helps while per-node compute still dominates communication. More machines is not automatically more speed, and sometimes the model's own architecture decides the answer for you.
Hybrid edge-cloud isn't a compromise. It's what the whole industry converged on. We just showed you don't need custom silicon to build it.
What's next
More nodes (the stack is node-count agnostic — same code runs 2, 4, or 8), smarter routing (learned difficulty classification instead of token-count heuristics), and the pattern generalized beyond coding agents: the same cheap-cluster-plus-selective-escalation architecture fits homes, clinics, and factories, anywhere data is sensitive or connectivity is unreliable.
Built With
- ansible
- baseten
- codex
- distributed-llama
- fastapi
- gemini
- llama
- lora
- openai
- python
- raspberry-pi
- solana
- unsloth
- vscode


Log in or sign up for Devpost to join the conversation.