-
-
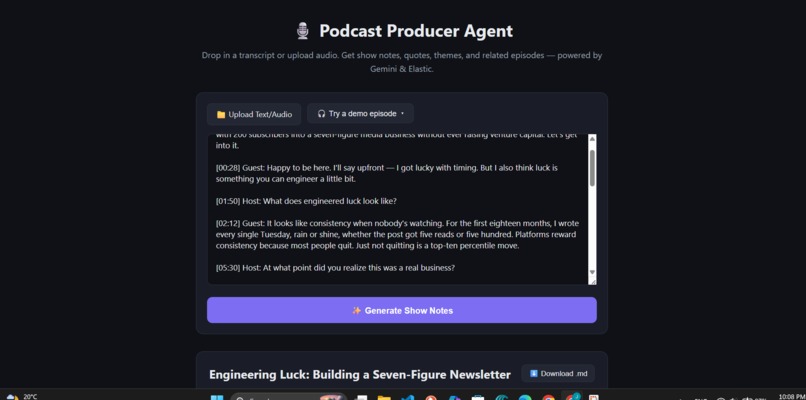
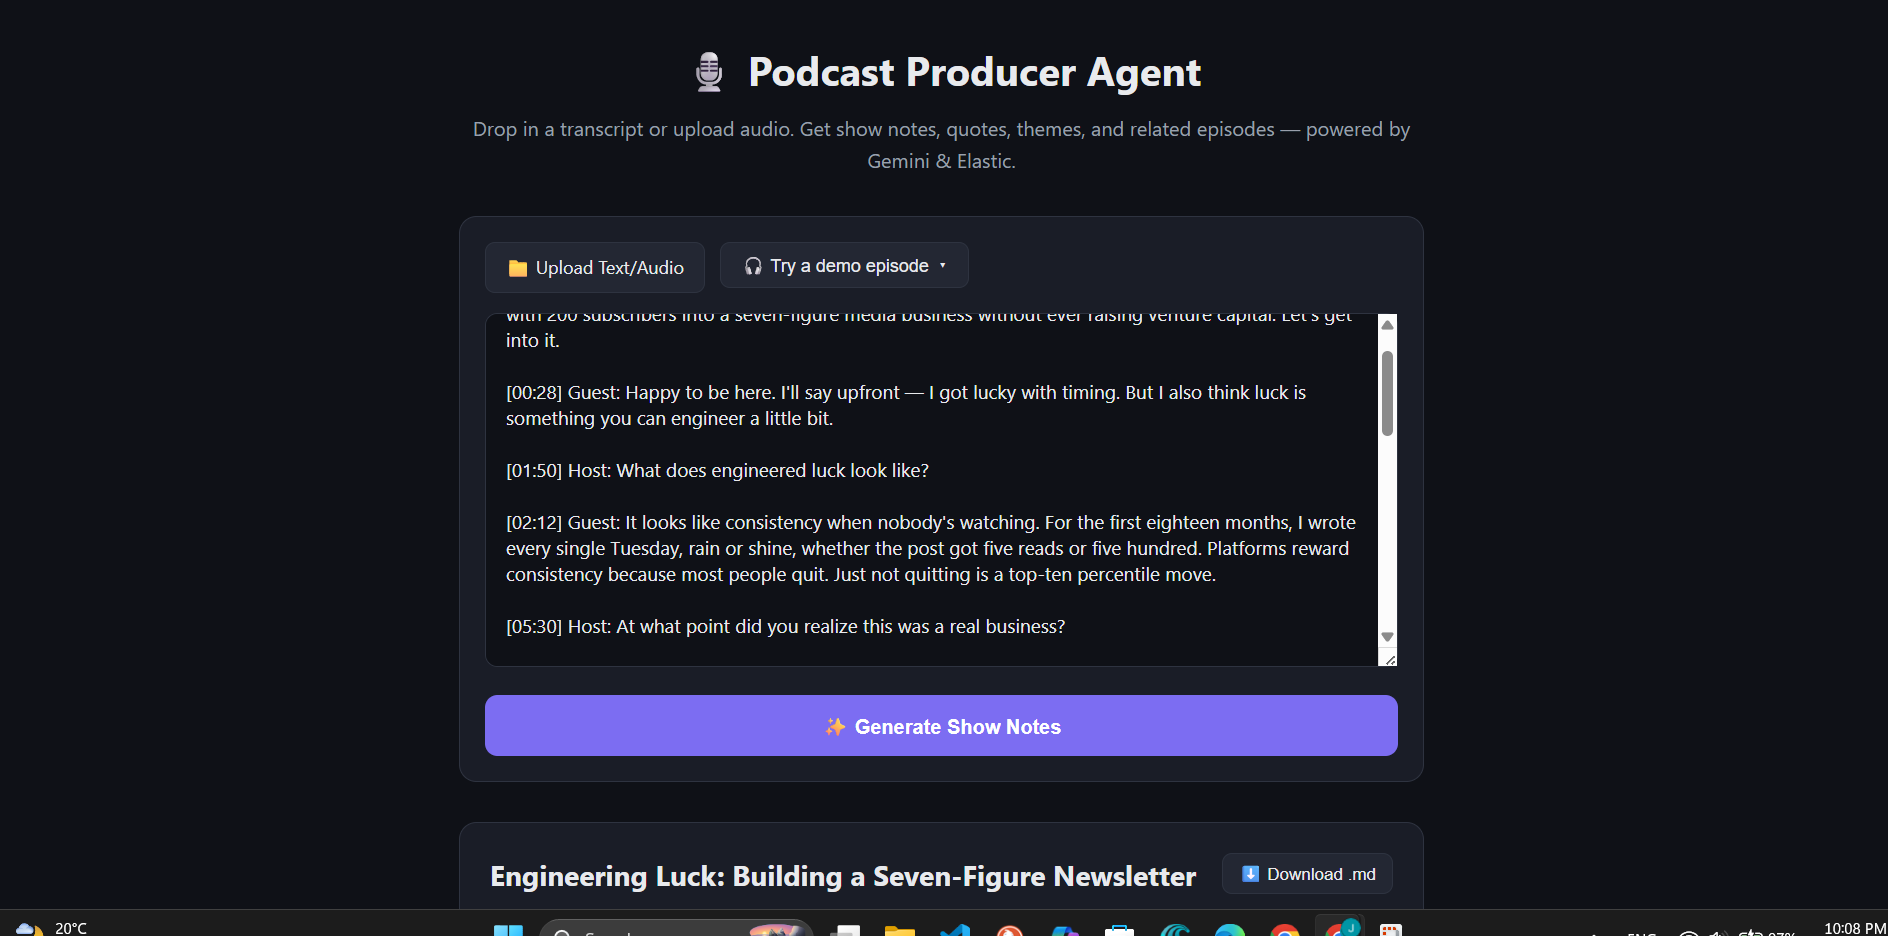
Generating a show note.
Inspiration
Every podcaster knows the secret: the recording is the easy part. After you stop the mic, there's another 1–2 hours of post-production per episode ~ show notes, hunting for quotable moments, drafting social posts, tagging themes, linking back to old episodes. It's repetitive, judgment-heavy work that burns creators out and never scales. We wanted to know: could a team of AI agents absorb that entire workflow?
What it does
Paste a transcript (or upload audio), click once, and in under a minute you get:
- 📝 Show notes with a summary and timestamped chapters
- 💬 Top shareable quotes, each with ready-to-post social copy
- 🏷️ Detected themes with relevance scoring
- 🔗 Related episodes from your catalog, via semantic search
- 💾 Everything persisted, so your library gets smarter with each episode
How I built it
A multi-agent pipeline on Google ADK (Python):
SequentialAgent: podcast_producer_pipeline ├── ParallelAgent: analysis ← run concurrently │ ├── show_notes_agent │ ├── quote_extractor_agent │ └── theme_detector_agent ├── social_clips_agent ← quotes → social posts └── elastic_search_agent ← Elastic MCP: related episodes
The three analysis agents run in parallel (no shared dependency), which roughly thirds the wall-clock time. Downstream agents consume their outputs via ADK session state. The Elastic MCP server (@elastic/mcp-server-elasticsearch, over stdio) powers related-episode discovery — the agent reasons over MCP tools rather than touching Elasticsearch directly.
Stack: Google ADK + Gemini · Elastic MCP · FastAPI · MongoDB Atlas · React/Vite · Cloud Run + Firebase Hosting.
What I learned
- Orchestration beats one big prompt. Focused agents meant simpler prompts, more reliable output, and parallel speedups.
- Not everything should be an agent. Routing a large DB write through an LLM was the wrong tool — a plain function call was instant and reliable.
- Great agent UX is about latency and trust. Showing live progress and returning partial results turned "sometimes hangs" into "always responds."
Challenges I ran into
- A hanging Elastic agent that could stall the whole request. We added a timeout + graceful partial-result fallback, so users still get show notes and quotes even if search stalls.
"Not primary" write errors, fixed by switching to the
mongodb+srv://SRV connection string so the driver finds the primary.Deployment friction: Cloud Run IAM roles, Firebase's org-project quirks, and bundling Node.js inside the Python container for the Elastic MCP server.
What's next
Full long-form audio transcription, a library dashboard visualizing themes across the catalog, and speaker diarization with auto-generated chapter art.
Built With
- cloud-run
- docker
- elastic-mcp
- elasticsearch
- fastapi
- firebase
- firebase-hosting
- gemini
- google-adk
- google-cloud
- javascript
- mcp
- mongodb
- mongodb-atlas
- node.js
- python
- react
- uvicorn
- vite


Log in or sign up for Devpost to join the conversation.