-
-
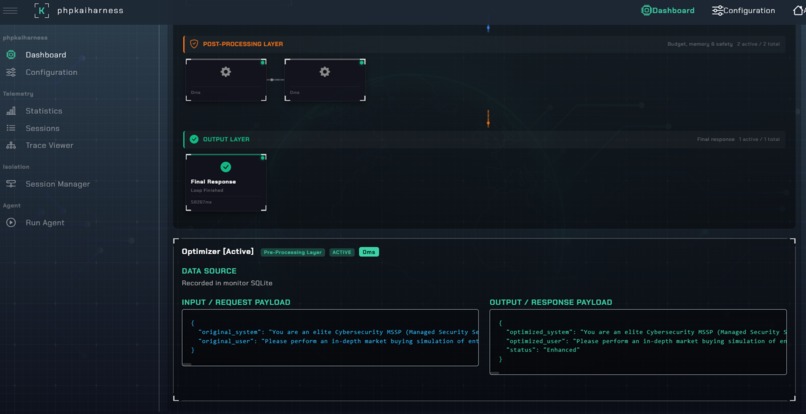
phpkaiharness feature
-
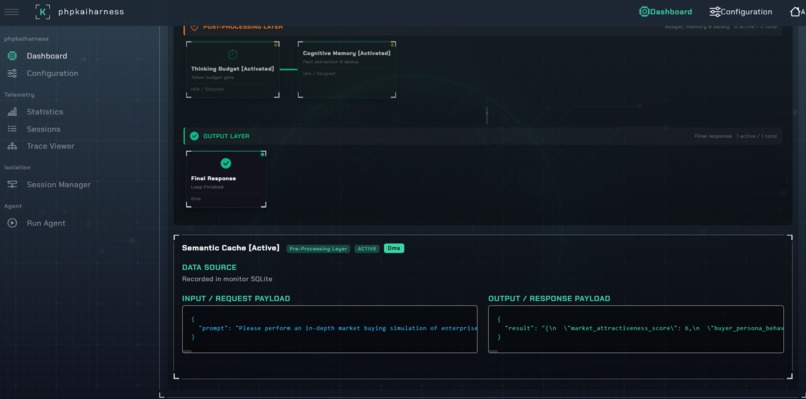
phpkaiharness feature
-
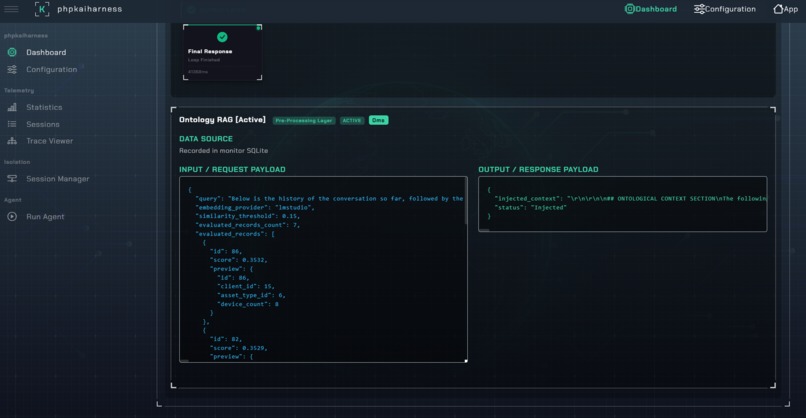
phpkaiharness feature
-
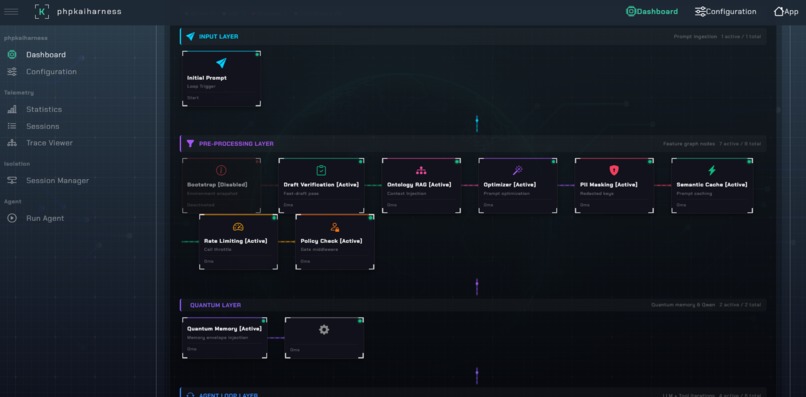
phpkaiharness feature
-
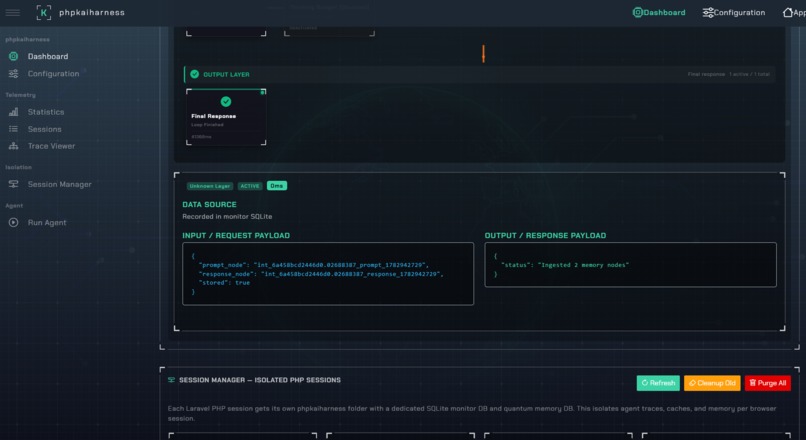
phpkaiharness feature
-
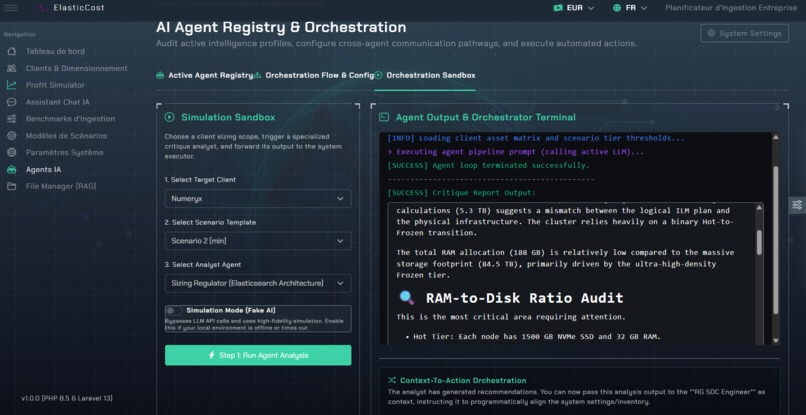
phpkaiharness test from other app
-
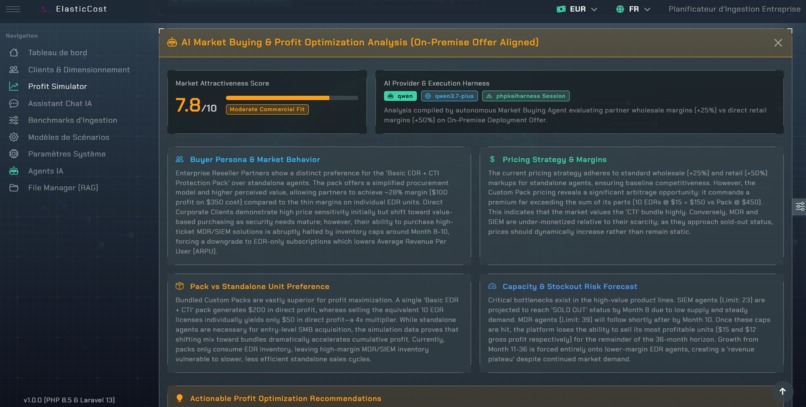
phpkaiharness test from other app
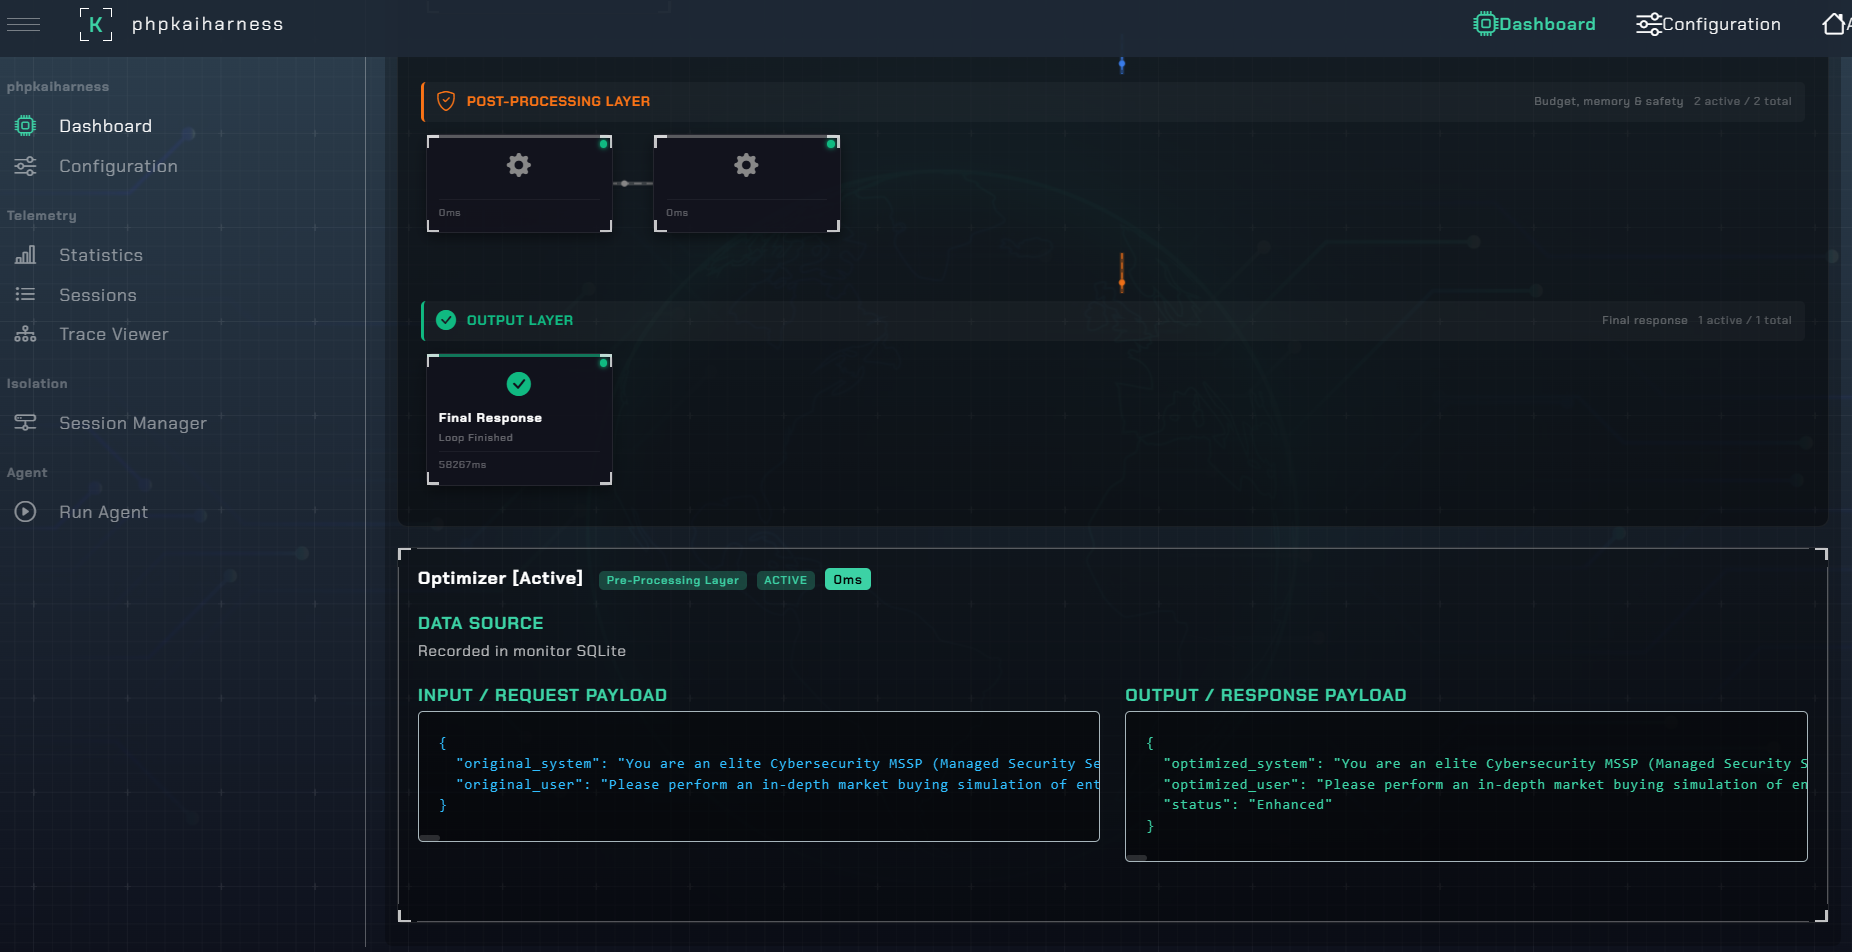
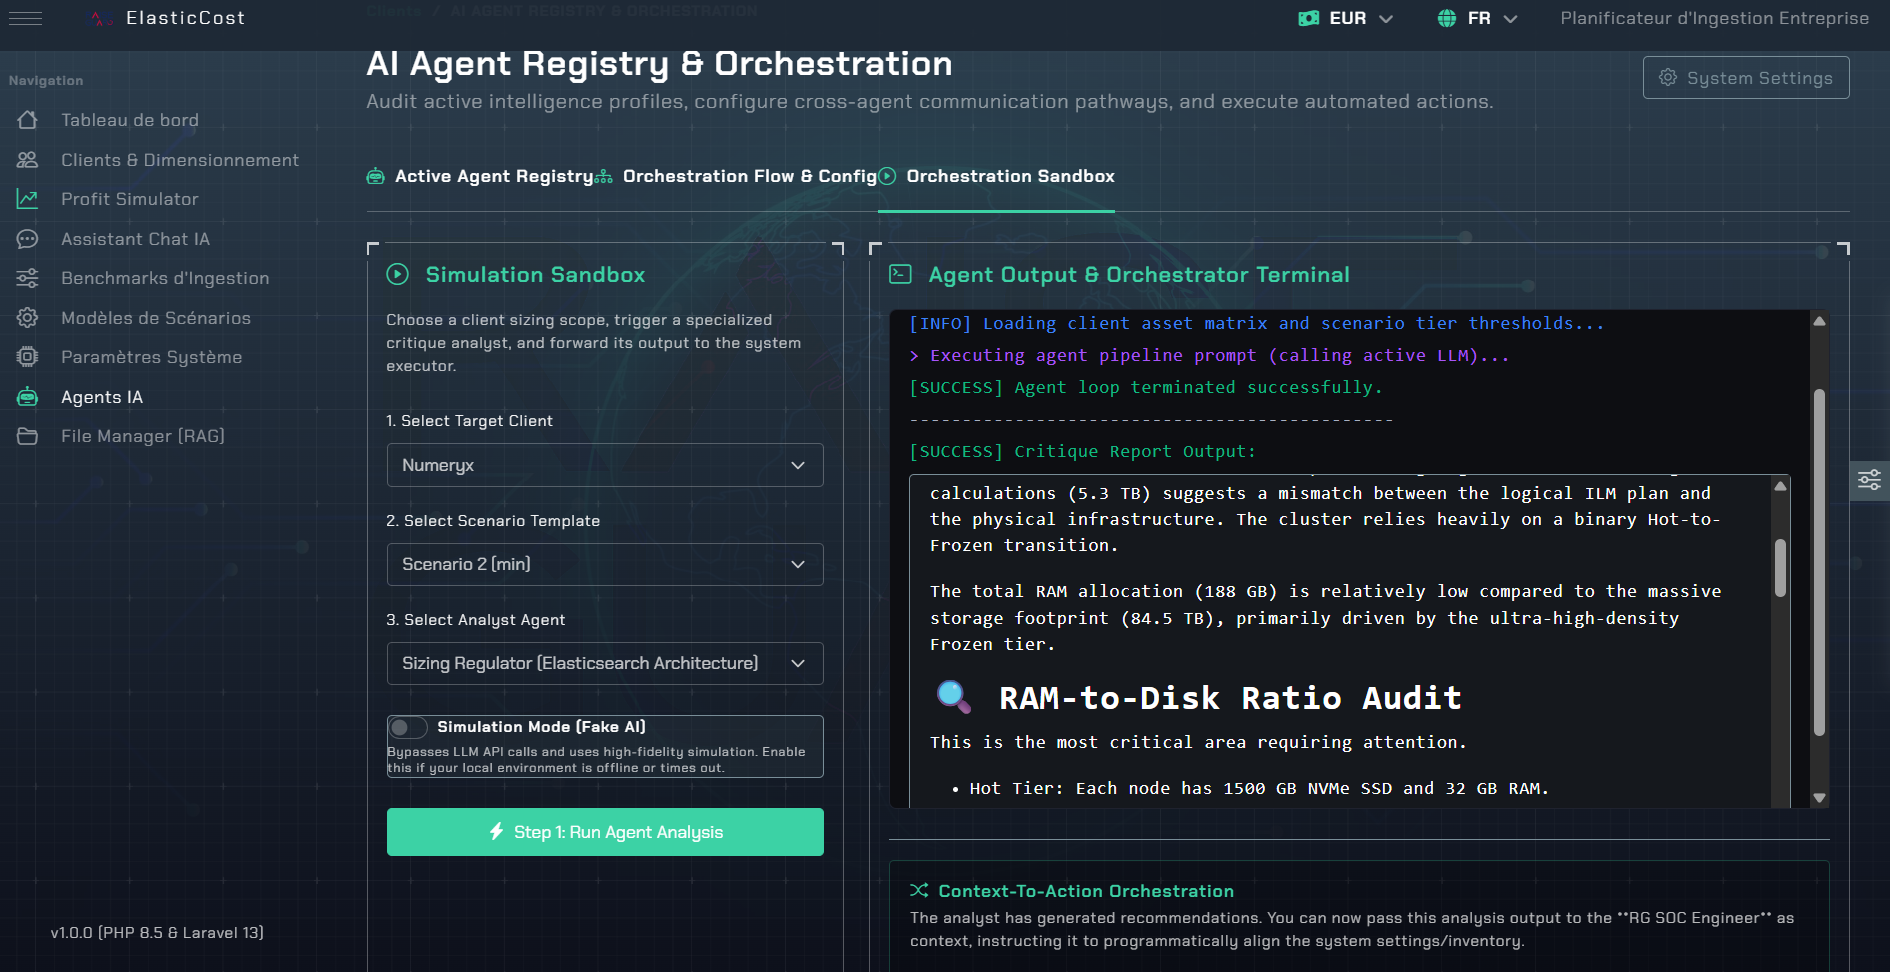
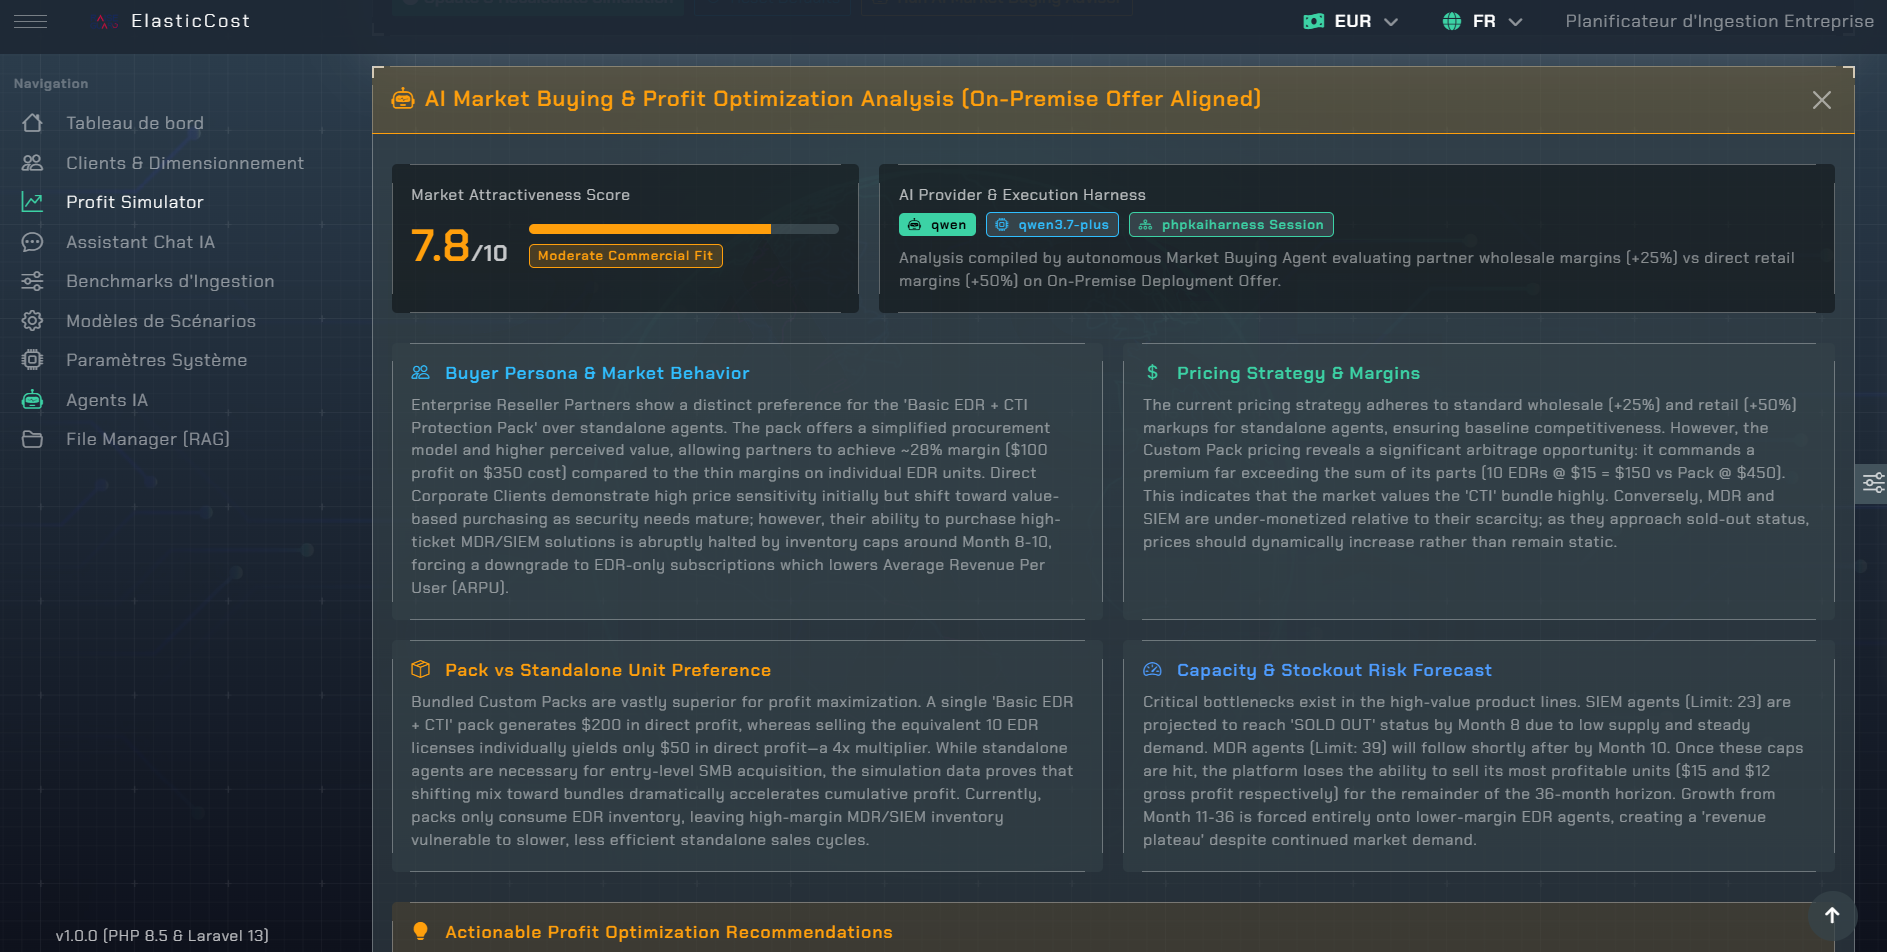
🚀 PHPKAIHARNESS 3.0
The Autonomous AI Agent Operating Layer for Web APP
Production-grade AI orchestration, cognitive memory, semantic intelligence, and enterprise safety, all inside the Web APP ecosystem.
🌟 Overview
phpkaiharness is a next-generation AI Agent Harness built for Web applications. It transforms LLMs into autonomous, context-aware agents capable of:
- Reasoning
- Remembering
- Verifying
- Safely interacting with application data
- Learning across sessions
Combining Cognitive Graph Memory, Quantum Memory, Semantic Cache, RAG Context Injection, and Enterprise Guardrails, the platform delivers faster, smarter, and more reliable AI experiences while reducing token costs.
⚡ Core Features
🤖 Autonomous Agent Engine
Drive the complete:
Think → Act → Observe
execution cycle with:
- Autonomous tool usage
- Configurable max iterations
- SSE token streaming
- Runaway-loop protection
🔀 Intelligent LLM Failover
Automatic provider failover chain:
Qwen Cloud
   ↓
Ollama
   ↓
LM Studio
   ↓
OpenRouter
   ↓
Laravel AI
Capabilities
- Semantic Cache
- Ontological Context Injection
- Cognitive Graph Memory
- Provider circuit breaking
- Provider prioritization
- High availability architecture
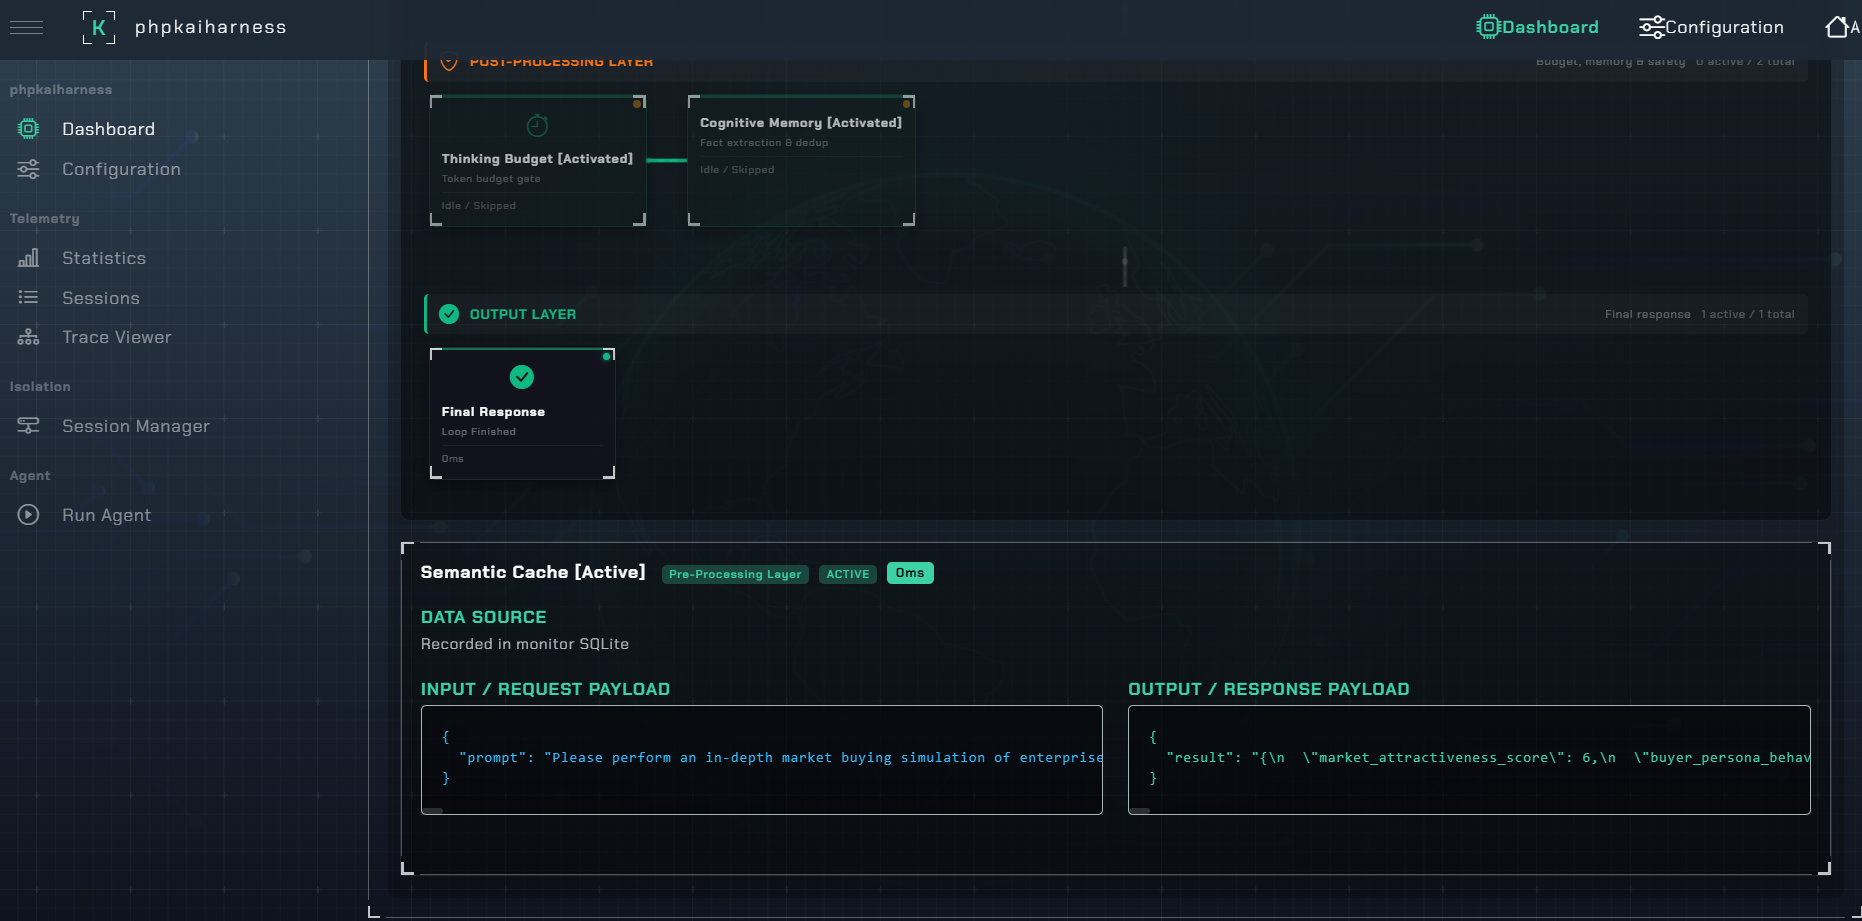
💾 Semantic Cache
SQLite-backed semantic response caching.
Benefits
✅ Up to 97% faster repeated requests
✅ Reduced API costs
✅ Zero-token cache hits
Example
Hot tier ratio for 500GB/day

≈

Hot tier sizing for 500GB per day
Both can return the same cached result.
🕵️ PII Protection Layer
Automatic redaction before requests leave your application.
Protected Data
- Email addresses
- IP addresses
- Credit card numbers
- API keys
Masking is applied to:
- Incoming prompts
- Outgoing responses
⏱️ Rate Limiting
Token-bucket rate limiter backed by SQLite.
Protects against:
- HTTP 429 errors
- API cost spikes
- Excessive request bursts
🛡️ Enterprise Guardrails
Policy-driven execution control.
Features
- Tool allowlists
- Tool denylists
- Argument validation
- Terminal protection
- Scope enforcement
Risky actions are blocked before execution.
🧠 Model Prompt Optimizer
Automatically rewrites prompts for optimal performance.
Supported Profiles
- Qwen 3.5
- Gemma 4
Benefits:
- Better tool calling
- Improved instruction following
- Higher reasoning accuracy
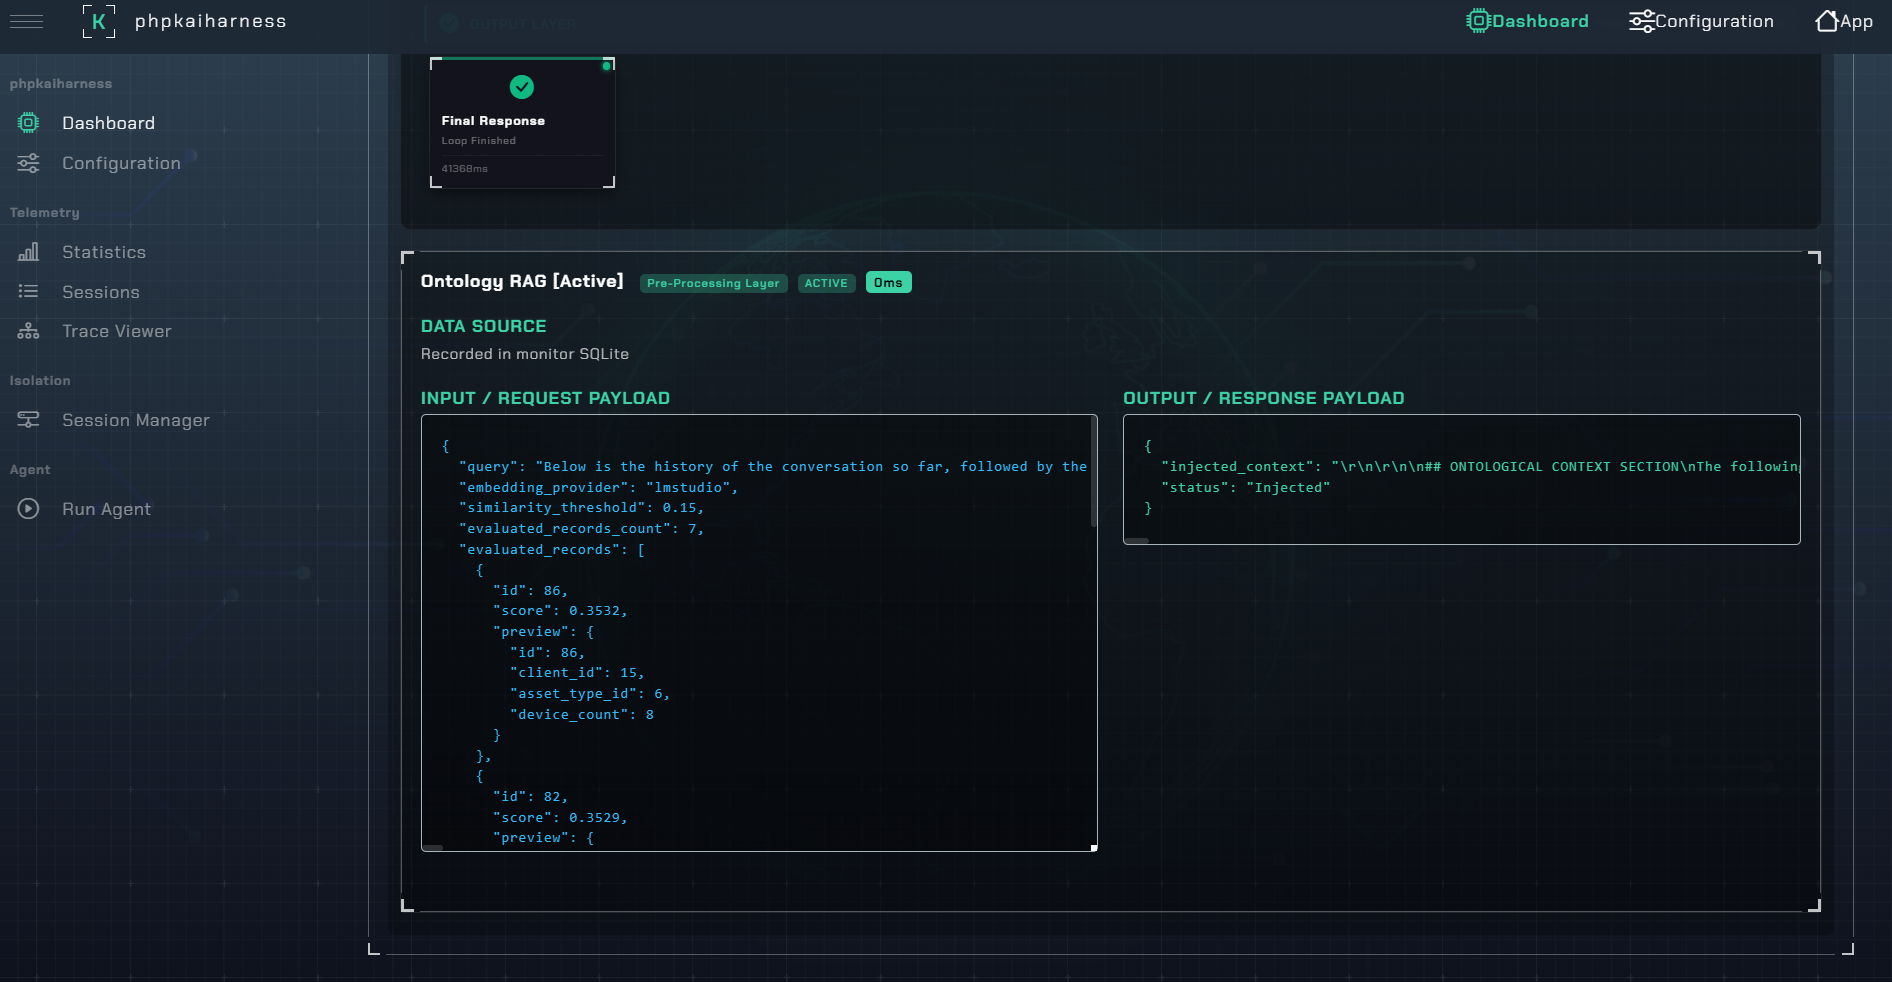
🔗 Ontological Context Injection
RAG-powered live data enrichment.
Workflow
User Prompt
      ↓
Embedding Search
      ↓
Relevant Eloquent Records
      ↓
Context Injection
      ↓
LLM Response
Grounds responses using real application data.
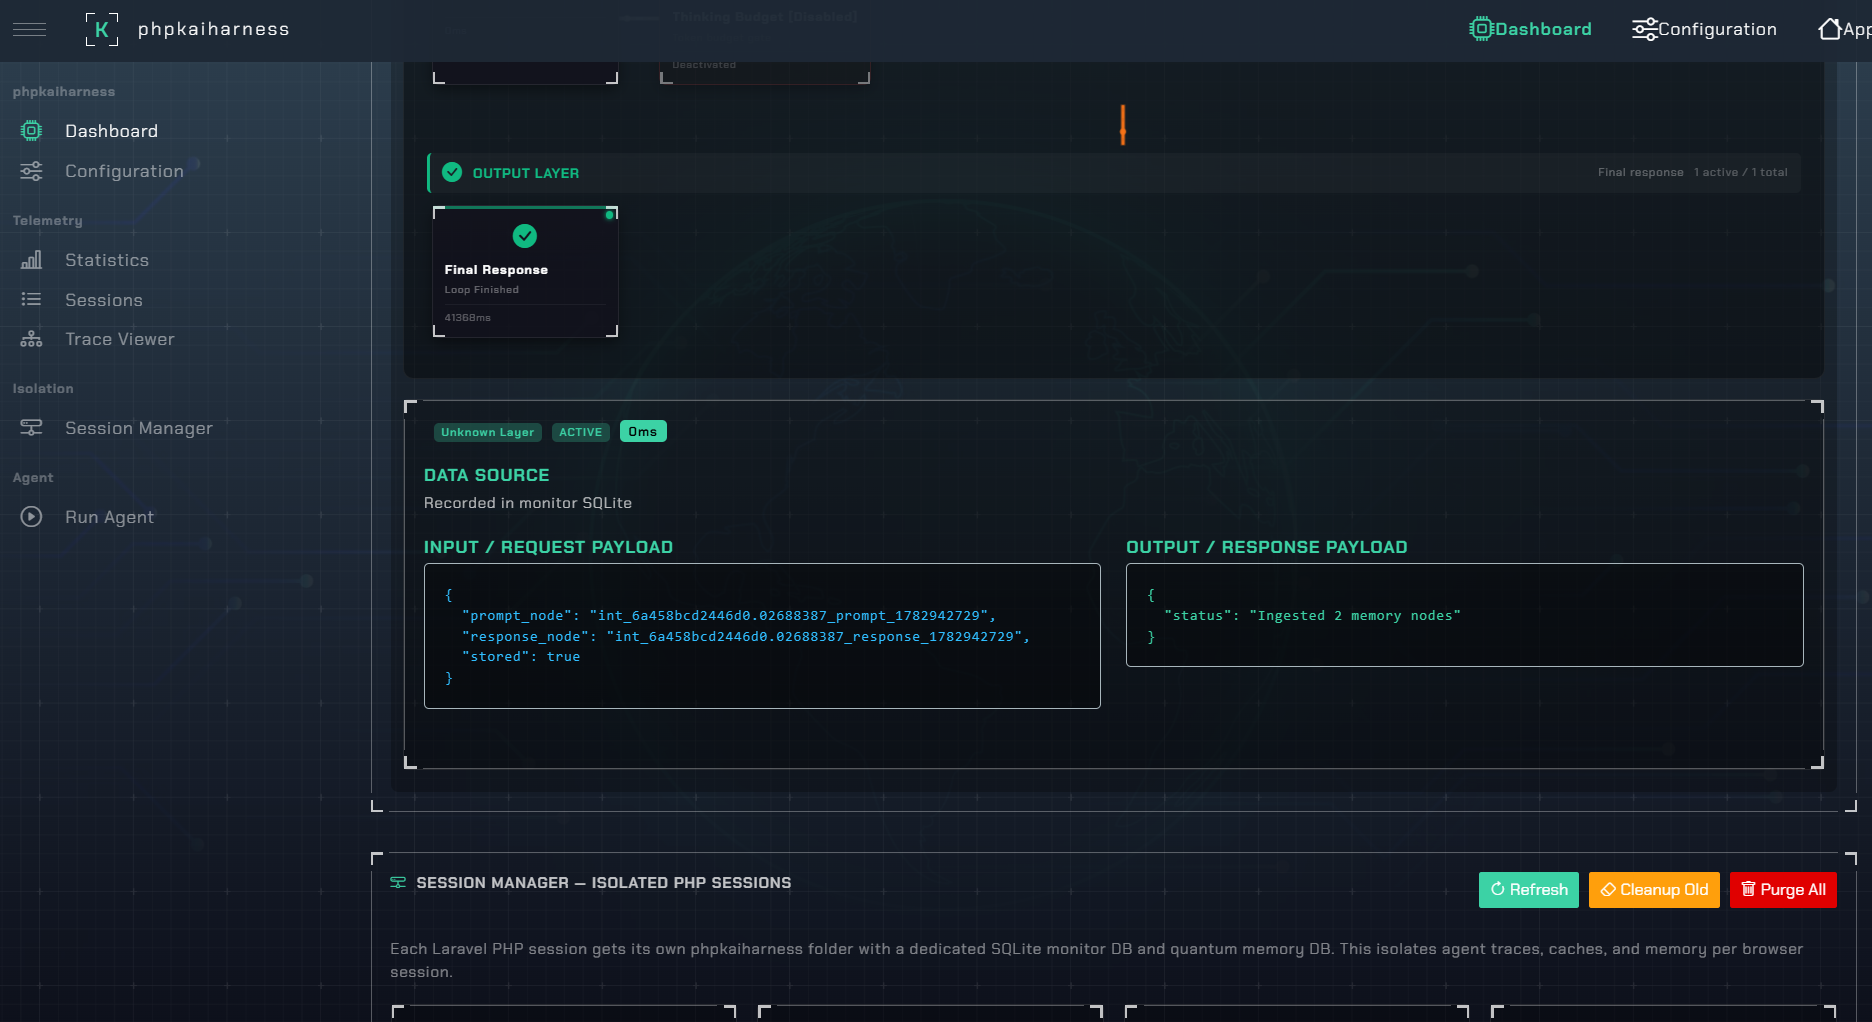
🕸️ Cognitive Graph Memory
Persistent cross-session knowledge graph.
Capabilities
- Entity extraction
- Relationship mapping
- Long-term memory
- Multi-turn reasoning
- Knowledge accumulation
⚛️ Quantum Memory Harness
Quantum-inspired intelligent memory retrieval.
Scoring Formula
S_fused = α · S_cos + β · S_interfere
Where:
- S_cos = cosine similarity
- S_interfere = phase interference score
Advantages
- Multi-hop traversal
- Entangled memory discovery
- Contextual recall
- Enhanced relevance scoring
✅ Draft Verification
Every response goes through a secondary validation step:
Draft Generated
      ↓
Verification Pass
      ↓
Fact Validation
      ↓
Final Response
Reduces hallucinations and factual inaccuracies.
💡 Thinking Budget
Structured reasoning injection:
Think
  ↓
Act
  ↓
Observe
Improves planning quality and complex task execution.
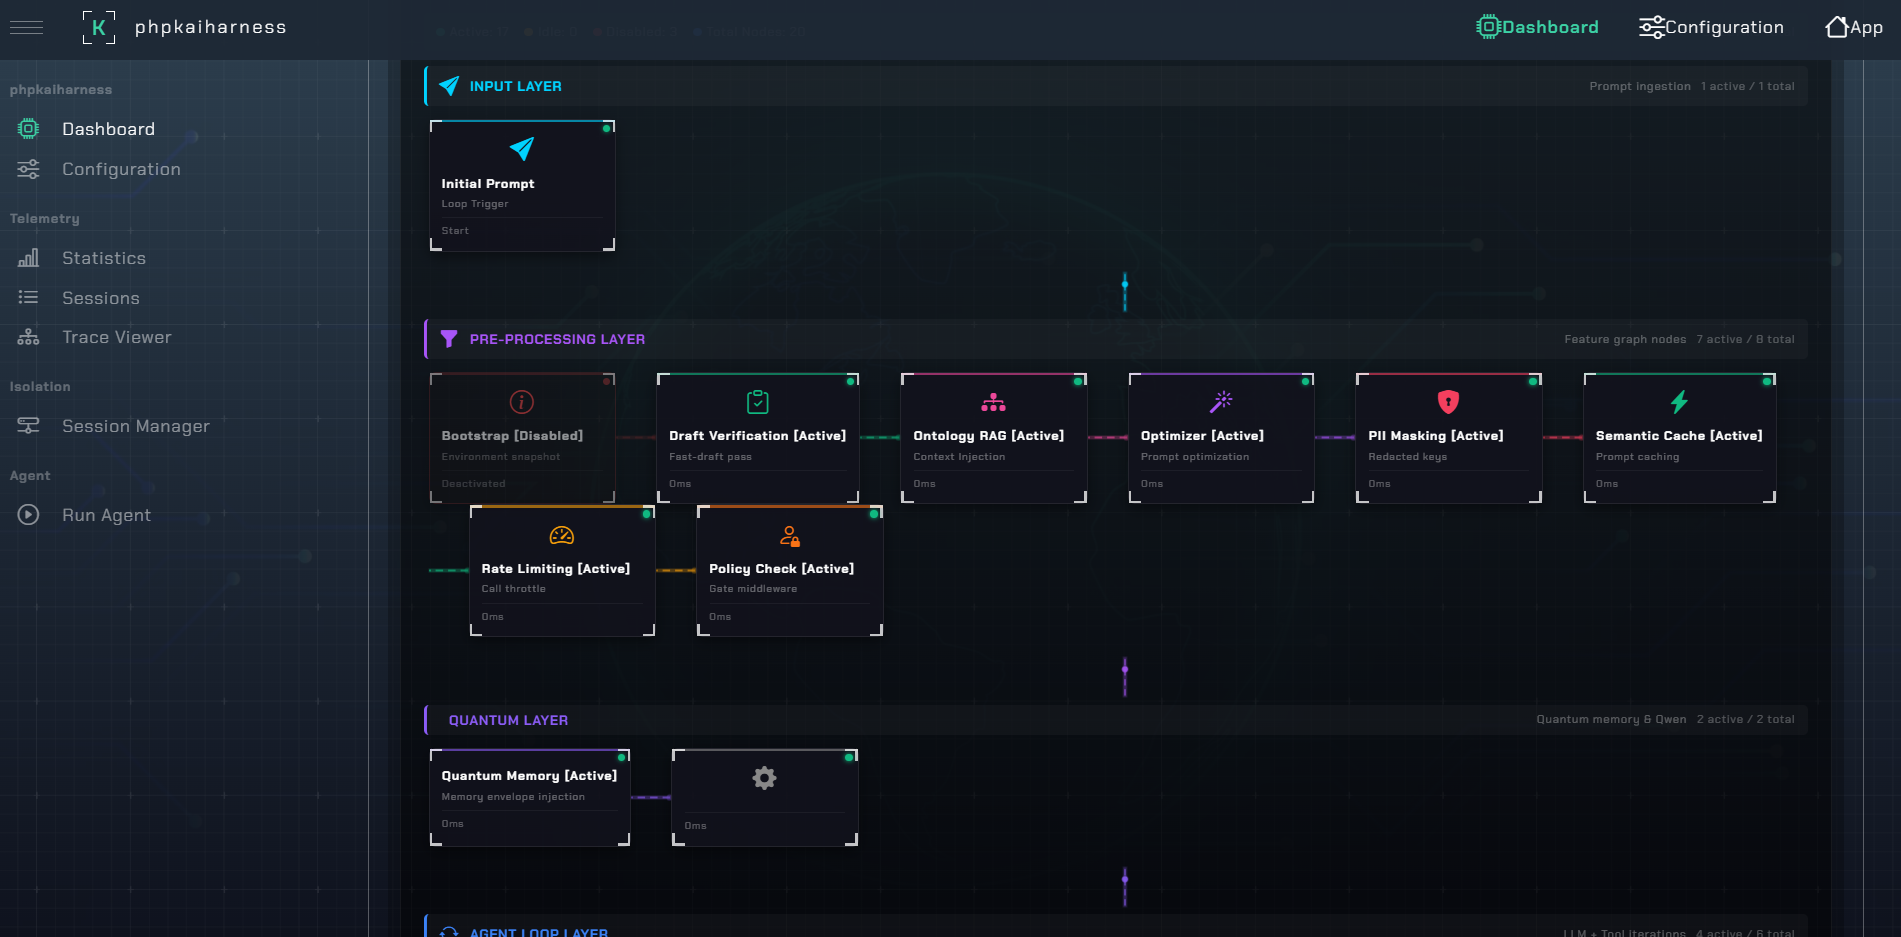
📟 Cyber HUD Dashboard
A futuristic cyber-teal monitoring center.
Includes
- Real-time workflow tracing
- Session explorer
- Agent playground
- Feature configuration panel
- Telemetry analytics
- Live status indicators
Every feature displays:
ACTIVE
or
DEACTIVATED
in real time.
☁️ Native Qwen Cloud Integration
Built-in DashScope support.
Features
- Hybrid credential resolution
- Structured JSON output
- Streaming support
- Qwen reasoning control
- Shared application configuration
Resolution chain:
global_settings
      ↓
Harness Config
      ↓
Laravel AI SDK
      ↓
Environment Variables
🏗️ Technology Stack
PHP 8.5
Laravel 13
SQLite
Qwen Cloud
Laravel AI SDK
Guzzle HTTP
PSR-14 Events
Pest Testing
📊 Benchmark Results
Benchmarked on a production Laravel 13 CTI platform.
🚀 Cache Performance
7 / 17 Requests
= 41%
served directly from cache.
Average Response Time
53.87 ms
versus
2710 ms
for raw API calls.
💰 Token Savings
41%
of benchmark requests consumed:
0 Tokens
Projected production cache hit rate:
70–90%
🧠 Response Quality
Harness Output:
2812 Characters
Raw API:
1990 Characters
Result
+41% richer responses
through memory-enhanced context.
📚 Knowledge Growth
After only 17 sessions:
Cognitive Memory
84 Facts
stored in the graph.
Quantum Memory
182 Nodes
created and linked.
✅ Accuracy Improvements
- Zero hallucinations on cached database queries
- Verified tool results stored permanently
- Memory compounds over time
- Institutional knowledge evolves continuously
🛠 Major Challenges Solved
OpenAI Tool Call Compatibility
Converted internal format:
{
  "id": "tool1",
  "name": "search",
  "arguments": {}
}
to OpenAI-compatible format:
{
  "id": "tool1",
  "type": "function",
  "function": {
    "name": "search",
    "arguments": "{}"
  }
}
Qwen Thinking Model Hangs
Automatically applies:
enable_thinking = false
to:
- qwen3
- qwq
preventing infinite reasoning loops.
Unified Credential Resolution
Implemented a 5-level fallback chain:
Host Database
      ↓
Laravel AI SDK
      ↓
Harness Config
      ↓
.env
      ↓
Default Values
Windows Compatibility
Replaced:
getenv('HOME')
with:
storage_path()
for universal support.
🏆 Achievements
✅ Production Ready
✅ 93 Passing Tests
✅ Cognitive Knowledge Graph
✅ Quantum Memory Retrieval
✅ Real-Time Telemetry
✅ Multi-Provider AI Support
✅ Enterprise Safety Controls
✅ Zero Dependencies Beyond LLM APIs
🔮 What's Next
Vector-Powered Semantic Cache
Replacing Levenshtein matching with:
- pgvector
- sqlite-vec
- Qwen Embeddings
- Native vector stores
Multi-Agent Orchestration
Router Agent
      ↓
Specialized Agents
      ↓
Collaborative Execution
Powered by:
- qwen-turbo
- qwen-plus
- qwen-max
Real-Time WebSocket Telemetry
Future support for:
- Laravel Reverb
- WebSockets
- Live token streams
- Workflow visualization
Distributed Memory Graph
Scaling memory using:
- Tenant sharding
- WAL optimization
- Faster retrieval
- Concurrent writes
Packagist Release
Installation becomes:
composer require kai/phpkaiharness
Memory Quality Decay
Implementing:
- Automatic relevance decay
- Fact quality scoring
- Knowledge graph cleanup
- Noise reduction
🚀 Vision
phpkaiharness is evolving from an AI framework into a self-improving intelligence platform that remembers, verifies, learns, and compounds knowledge over time.
The first request gets an answer. The thousandth request inherits institutional memory. 🧠⚡
Built With
- 12
- 13
- 17
- 4
- 8.5
- alibaba
- by
- cloud
- ecs
- guzzle
- http
- instance
- laravel
- laravel/ai
- pest
- pgvector
- php
- phpunit
- postgresql
- psr-14
- qwen
- sqlite
- v0.8


Log in or sign up for Devpost to join the conversation.