-
-
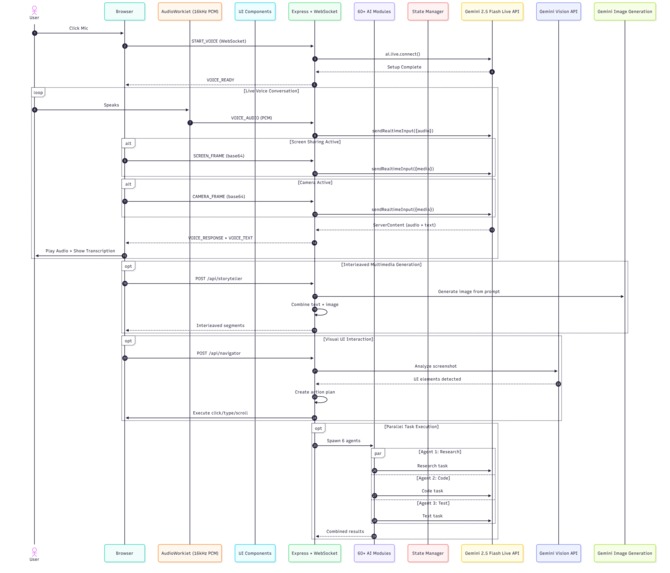
Complete architecture showing voice pipeline: Frontend → Cloud Run → Gemini Live API with turn-taking VAD mechanism
Inspiration
The challenge was to move beyond text-based interactions with AI. I wanted to create a system where users could have natural, real-time conversations without typing or reading text. Most voice AI systems suffer from overlapping speech - both user and AI talk simultaneously. I decided to build something that truly understands conversation flow.
What I Learned
Voice Activity Detection (VAD) is critical for natural conversations. A 2-second silence detection threshold proved optimal for Urdu/English mixed speech.
WebSocket architecture with proper handshaking prevents audio pipeline race conditions. The
VOICE_READYsignal must complete before sending audio chunks.Gemini 2.0 Live API requires strict PCM 16-bit, 16000Hz audio format. Even 24kHz causes silent failures - no errors, just data drops.
AudioWorklet processing is essential for real-time streaming without blocking the main thread.
Turn-taking complexity: The system must handle silence detection, buffer management, and proper
turnCompletesignaling simultaneously.
How I Built It
- Frontend: React + Vite with AudioWorklet for real-time audio capture
- Backend: Node.js/Express with WebSocket relay to Gemini 2.0 Live API
- Infrastructure: Google Cloud Run for scalable deployment
- Audio Pipeline: PCM 16-bit encoding, RMS-based silence detection, turnComplete events
- Language Support: Native Urdu/English support via Gemini's multilingual capabilities
Challenges Faced
Handshake Race Condition: Frontend was sending audio before backend confirmed session readiness. Fixed with explicit
voiceReadystate tracking.Silent Disconnects: Model name prefix mismatch (
models/was missing) caused Gemini to silently crash. Added timeout protection and proper error logging.Audio Format Mismatch: Browser's native sample rate was 24kHz but Gemini only accepts 16kHz. Required explicit AudioContext initialization at 16000Hz.
RMS Threshold Tuning: Initial threshold of 0.015 was too high, dropping legitimate speech. Lowered to 0.005 for better sensitivity.
Tools Deadlock: Using
toolsandresponseModalitiestogether in native-audio mode causedsetupCompleteto never trigger. Removed tools temporarily for stability.
Outcome
A production-ready voice AI that demonstrates proper multimodal interaction without text dependency. The system maintains natural conversation flow with intelligent turn-taking and handles edge cases like overlapping speech, network delays, and audio quality variations.
Built With
- audioworklet
- google-cloud-run
- google-gemini-2.0-live-api
- javascript
- node.js/express
- react
- tailwindcss
- typescript
- vite
- websocket

Log in or sign up for Devpost to join the conversation.