Inspiration*Project name:* PeelCheck
Team: Qiwei Li (solo) — B.S. Computer Science + Mathematics, Washington University in St. Louis (May 2027) Tagline: One photo tells you if that banana is snack, bread, or bin. GitHub: https://github.com/Peoplerepabulic/peelcheck Live demo: https://peelcheck.streamlit.app/ Video: https://youtu.be/WN2--GUFPZQ
Inspiration
Bananas are bought green, forgotten, then tossed when spots appear — even though a spotted banana is perfect for baking. I wanted a tiny Image AI project a solo coder could train end-to-end in one weekend: a real training pipeline, not an API wrapper.
What it does
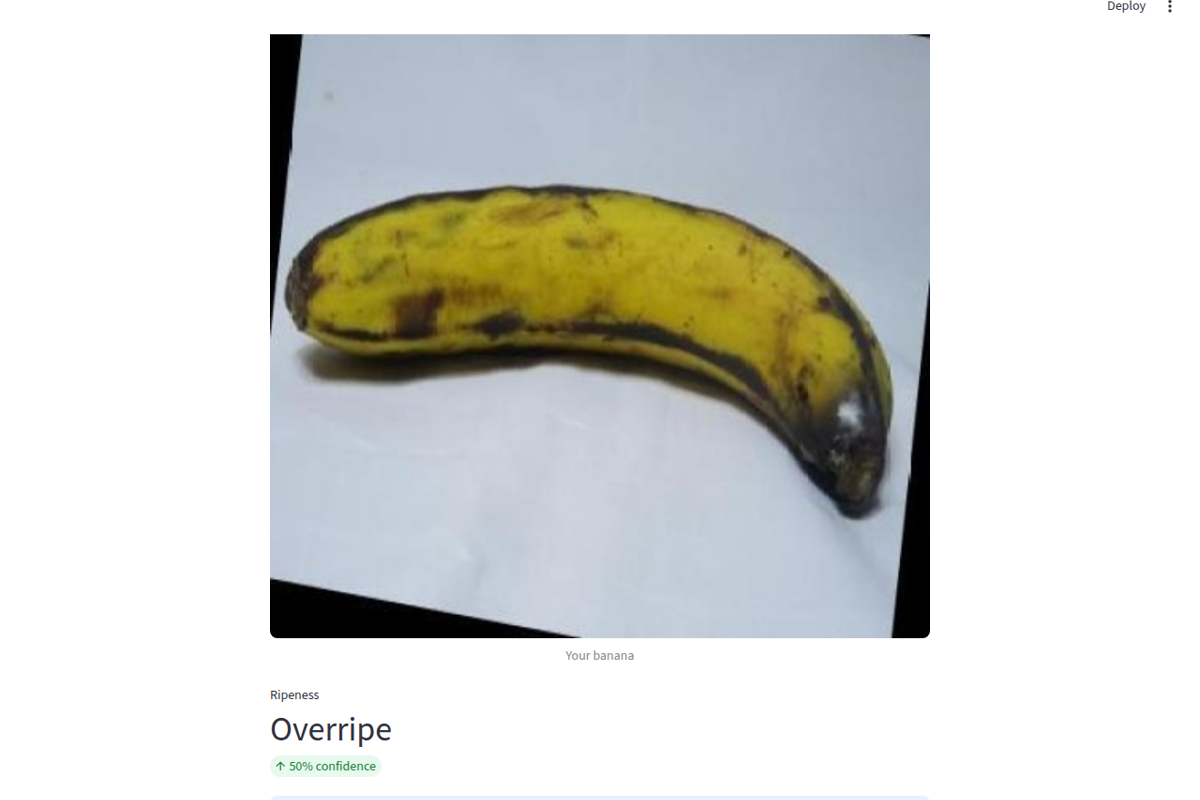
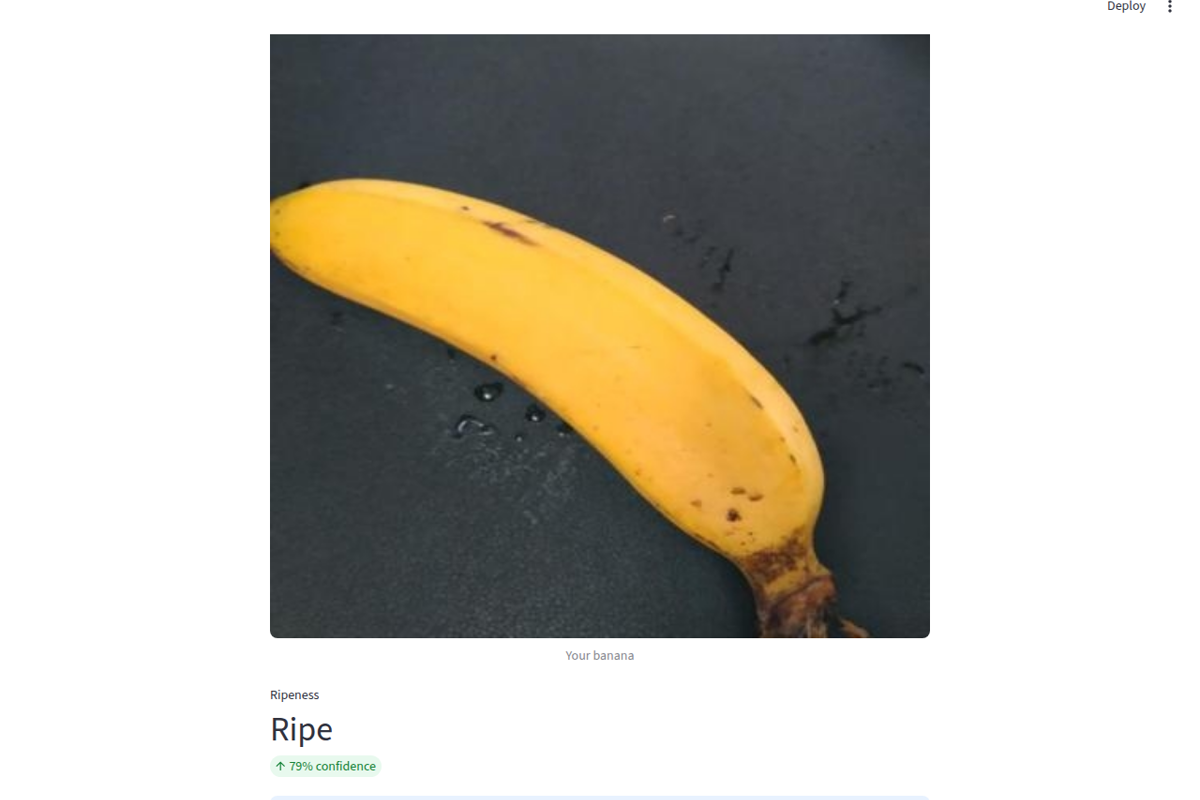
Upload a banana photo and PeelCheck returns one of four stages — unripe, ripe, overripe, or rotten — with confidence for all four stages and a concrete next step: wait or cook it, eat it now, bake/blend/freeze it today, or don't eat it raw. The classifier is the product; remove it and nothing remains.
How I built it
- Data: Kaggle Banana Ripeness Classification Dataset (Apache 2.0): 13,478 images, pre-split train 11,793 / valid 1,123 / test 562 across four classes. The held-out test split was never touched during training.
- Model (shipped): multinomial logistic regression on 47 HSV color features (hue/saturation/value histograms, color-class fractions), trained with balanced class weights in numpy only (
train/train_numpy.py) — reproducible offline in ~2 minutes. Model file is 2.5 KB; inference is instant. Augmentation helpers (brown-spot synthesis intrain/augment.py) were explored in-repo but not used to train the shipped model. - Model (upgrade path, in repo): MobileNetV3-Small transfer-learning fine-tune (
train/train_peelcheck.py+ Colab notebook) exporting ONNX; the demo prefers ONNX > trained NPZ > labeled heuristic preview, in that order. - App: single-page Streamlit demo on Streamlit Cloud — judges can click a live link (no login) and try held-out test images from
assets/demo_test/. - Resources: numpy, Streamlit, Pillow, the dataset above. All code written Oct 9–11, 2026; no cross-submission.
Results
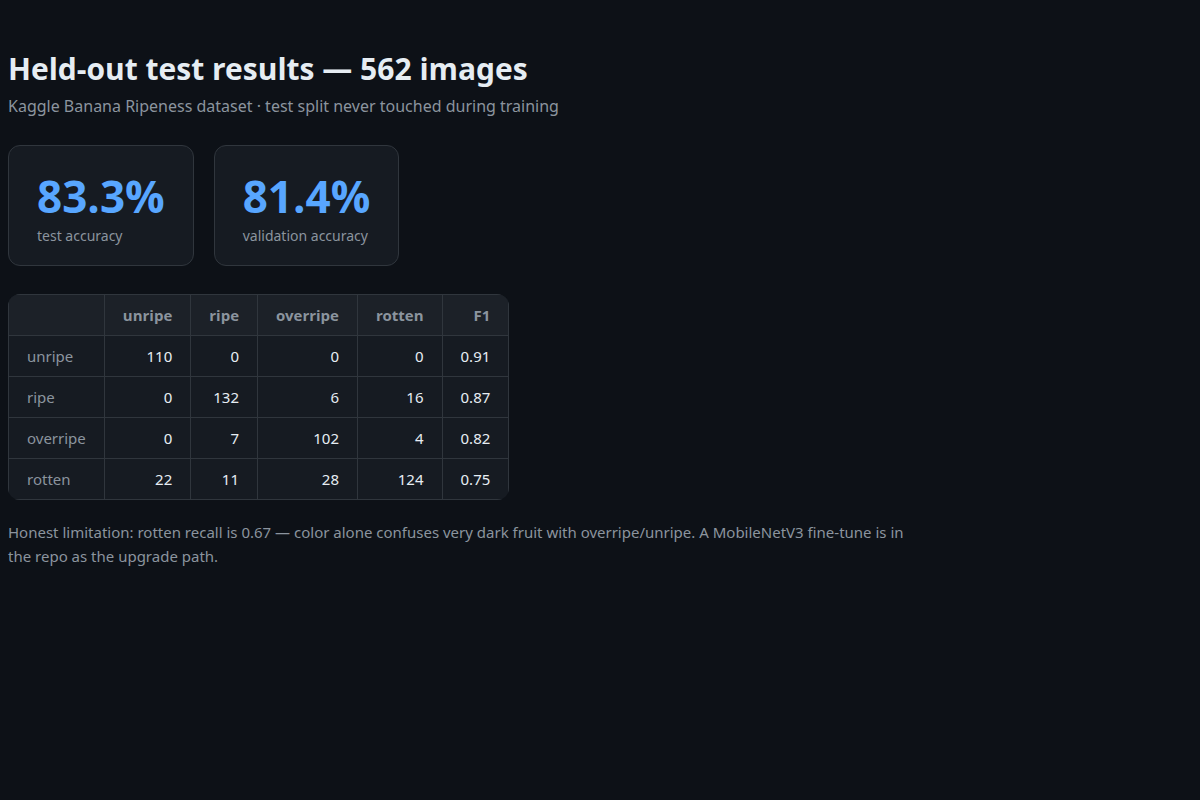
Test accuracy 83.3% (valid 81.4%) on 562 held-out test images. Per-class F1: unripe 0.91 (recall 1.00), ripe 0.87, overripe 0.82, rotten 0.75. Full table in models/metrics.json, confusion matrix in models/confusion_matrix.csv.
Challenges
The deep-learning stack's package downloads kept timing out in my build environment, so I rebuilt the trainer on numpy alone rather than shipping a placeholder — a trained model with real metrics over a pretty shell. Honest limitation: rotten recall is 0.67 — color alone confuses dark rotten fruit with overripe/unripe, which is exactly why the texture-aware MobileNetV3 fine-tune is next.
What's next
Ship the MobileNetV3 fine-tune, add more fruits, and a grocer "sort the shelf" batch mode.
Built With
- computer-vision
- image-classification
- kaggle
- logistic-regression
- machine-learning
- numpy
- pillow
- python
- streamlit


Log in or sign up for Devpost to join the conversation.