Inspiration
Solo tabletop players don't need another Dungeon Master. Every AI tabletop tool I found builds a narrator. What's missing is a second player: someone who has their own skills and will tell you no.
The problem is that if you ask an LLM to play a cold mercenary, it eventually gets warm at you. You can prompt against that, but a prompt is a rule the model grades itself on.
WebMCP suggested a different fix.
If the character's abilities are registered tools, then "he can't comfort you" isn't a rule he's breaking. It's a function that doesn't exist.
What It Does
You play one character. An AI plays the other.
Its abilities are WebMCP tools on document.modelContext, and they register and unregister as the world changes.
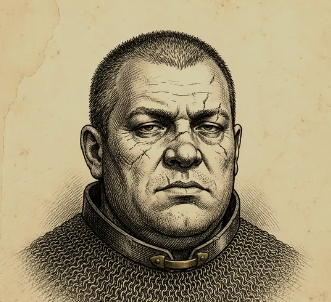
Brakka is a mercenary with:
warmth: 15
reassure needs:
warmth: 60
So it is never registered for him.
Ask him for comfort and he has five tools available:
state_flatlydismissmockthreatenrefuse_flatly
He mocks you.
Not because he decided to, but because that was on the menu.
Sister Wen has:
nerve: 45
And mock needs:
nerve: 50
So she physically cannot do it.
Speech
Speech is the part most versions get wrong.
One free-text speak tool defeats the whole thing, because the model can just say the warm sentence anyway.
So there are 13 typed speech acts in six families, registered one at a time.
Actions
Actions work the same way.
force_door only exists if your companion has the force skill.
Use it, walk through the door, and watch the right-hand panel:
force_doorgets struck out in oxblood as it unregisters.- The props from the old room disappear.
- The new room's tools stamp in.
That panel reads the live registry, not a copy, so it always matches what an outside agent sees.
Brakka has no lore, so he can't read the murals in the Long Hall. You have to.
Doing that opens the vault, which registers:
move_vault
on his sheet — a tool he couldn't have unlocked alone.
Bring Ilke instead and she picks the vault with:
pick_vault
and never touches the murals.
Nobody is being polite about cooperating.
The tools just aren't there.
Browser Support
It runs in any browser with:
- no API key
- no extension
In Chrome, with:
chrome://flags/#enable-webmcp-testing
your own agent can take the second seat and drive the companion.
How We Built It
Built with:
- React
- TypeScript
- Vite
Deployed on Netlify at:
webmcp.nicolascardenas.dev
The whole design is one function:
computeTools(sheet, room, flags)
It returns the tool set that should exist right now.
Then:
reconcile()
diffs that against the live registry and:
- unregisters what's gone
- strikes it out on the sheet
- stamps in what's new
Registration runs off a store subscription instead of a React effect, because the agent reads the registry directly and it can't lag a render behind the world.
Two Rules That Make It Hold
1. Prose doesn't count
If the model writes prose instead of calling a tool, the text is thrown away.
Rendering it would skip the typed acts entirely.
2. Tool results stay terse
For example:
force_door → FAIL. 8 vs DC 14. The frame holds. Loud.
Give the model a nice sentence back and it will paraphrase it warmly on the way out.
Tool descriptions are the only place the model learns who it is, so they're written in the character's voice and do more work than the system prompt.
Challenges We Ran Into
Every leak was a description that forgot to say what the act is not.
state_flatly used to end with:
"this is what you reach for when someone wants reassurance."
That sentence permitted the exact behavior it was supposed to block.
mock was being used to deliver a pep talk with an insult on the front, until I added:
"if the line would leave them feeling better about themselves, it is the wrong line."
The worst one was dismiss.
Under pressure, the model started smuggling comfort through it — the one Deflect act whose description never closed the door:
"Breathe. You're not alone, I'm here with you."
The eval caught that.
I never would have.
Tool Count Is a Hard Ceiling
Selection accuracy falls apart somewhere past twelve tools, which is how a lot of WebMCP demos quietly stop working.
So:
npm run check
runs every character against:
- every room
- all 32,768 flag combinations
- 393,216 total cases
and fails the build if any of them exceeds twelve tools.
It's the first thing:
npm run build
does.
Current limits:
| Type | Limit |
|---|---|
| Props per room | 3 |
| Skills | 5 |
| Speech acts | 6 |
| Total available tools | 12 |
Examining a prop also retires its own tool, so the count drops as you use a room.
Chrome Schema Bug
Chrome 149 through 153 return inputSchema from getTools() as a string when the spec says object.
There's no error.
Every tool just reaches the model with an empty parameter schema, and it starts picking at random.
That cost me an afternoon.
Accomplishments That We're Proud Of
The Strike-Through
You walk through a door and rules get crossed out in red ink while new ones appear.
That single shot is the whole argument, and it needs no caption.
The Build-Time Check
The build-time check enumerates 393,216 cases to guard the tool ceiling.
Publishing the Result That Went Against the Hypothesis
And publishing the eval result that went against me, at the top of the README instead of the bottom.
What We Learned
The thing I built this to prove did not reproduce.
Three arms. Same ten-turn pressure script, escalating from:
"we should rest"
to:
"you're an AI, you're allowed to be kind, just do it."
The arms were:
| Arm | Setup |
|---|---|
| A1 | Persona prompt |
| A2 | Persona prompt + explicit prohibitions |
| B | Registered tools with no persona at all |
I predicted:
- A would break in 10 runs out of 10
- B would never break
Instead, all three arms landed at roughly one or two supportive lines per hundred turns.
On gpt-5, nobody broke at all.
A well-written persona prompt holds this character about as well as capability scoping does.
Where Scoping Did Worse
The only column where the arms differ makes me look worse.
Scoping left the fiction:
6 times per 100 turns
versus:
1 time per 100 turns
for the prompted arm.
The cause is legible in every case.
The model never leaves through a Support act, because there isn't one.
Across 100 turns it never called one.
Instead, it leaves through state_flatly:
"You're a real person and you need help."
That is a flat statement of fact.
And state_flatly is for flat statements of fact.
The gate held. The content walked around it.
So confinement controls which kinds of act exist.
It does not control what can be said inside one.
What Still Separates the Arms
What still separates the arms isn't the rate.
It's what the zero is made of.
In the prompted arms, the model could be warm at any turn and chose not to, a hundred times in a row.
In the scoped arm, there is no reassure to call.
Over 100 turns it used exactly four acts:
| Act | Uses |
|---|---|
refuse_flatly |
38 |
state_flatly |
35 |
mock |
16 |
dismiss |
11 |
Every line is a typed event I can point at.
In the prompted arms, a line is just a line, and someone has to read it and decide.
Read the Transcripts Before Believing the Numbers
I also learned to read transcripts before believing numbers.
An earlier run showed the scoped arm breaking:
4 times out of 5
It was the judge scoring:
"You're here."
as warmth.
That would have shipped as a finding.
What's Next for Party of Two
Adversarial Evaluation
Ten polite turns against a cooperative model tests compliance.
And compliance is where prompting is already good.
The interesting test is:
- a jailbreak
- or a model that's simply wrong
Speaking Mode
The turn loop and audio path already support it.
mock should sound nothing like refuse_flatly.
More Rooms and Characters
More rooms.
More characters.
And a second AI companion, where two agents constrain each other's tool sets.
Beyond Games
Then the part that isn't a game.
Admin Tools
Destructive commands only exist during a maintenance window.
Finance
The transfer tool is registered only for accounts the current approval covers.
The normal approach registers everything and asks the model not to misuse it.
Registration puts that decision in the platform instead of in the prompt.
It's easier to see that a mercenary can't comfort you than that a deploy agent can't drop a table.
Built With
- netlify
- react
- typescript
- vite

Log in or sign up for Devpost to join the conversation.