PAM: Portable Agent Memory Your AI memory, portable across every model: local and human readable.
Have you ever been working on a project, and then run out of tokens? So have I, so I do what anyone would do: switch models and keep working. But when you switch from Claude to ChatGPT, Chat doesn't remember anything about you, or what you were working on. That means you can end up wasting precious time (and tokens), just trying to get back to where you were.
That's why we created Portable Agent Memory, or PAM.
PAM imports your chat history from any major LLM platform, saves it in a local vault, and stores the memories so you can pick up right where you left off. It picks out facts about you, your projects and your preferences, then gives any AI model a short summary of what it needs to know. You can switch models mid-conversation without losing your place.
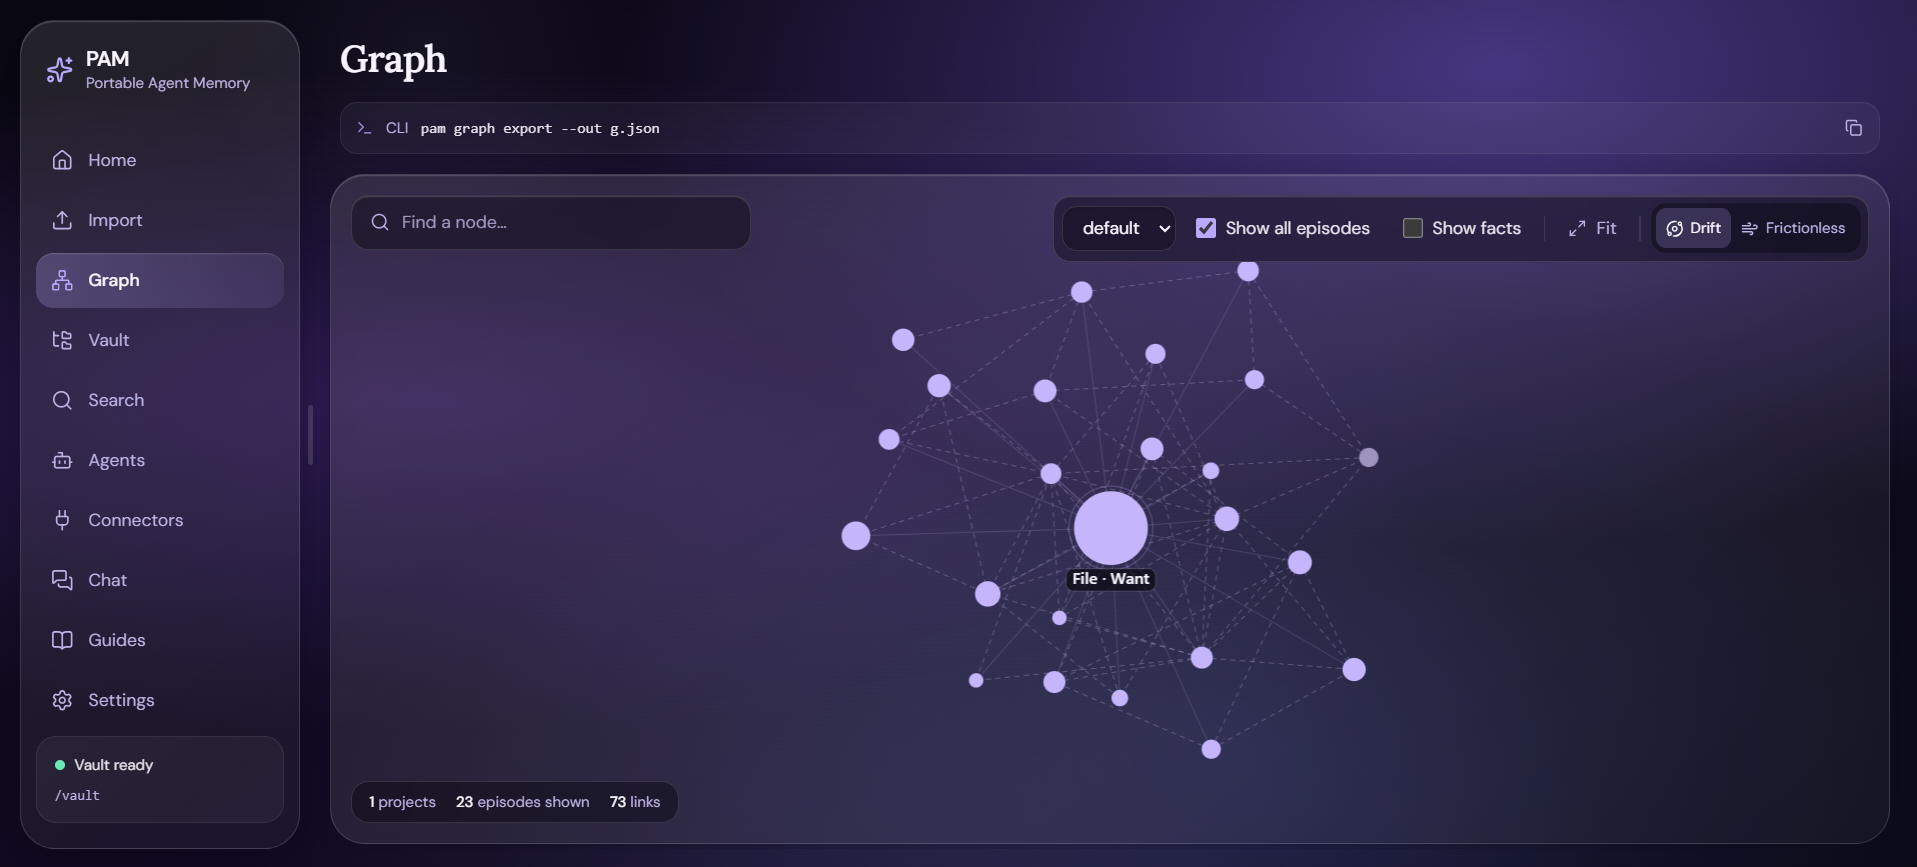
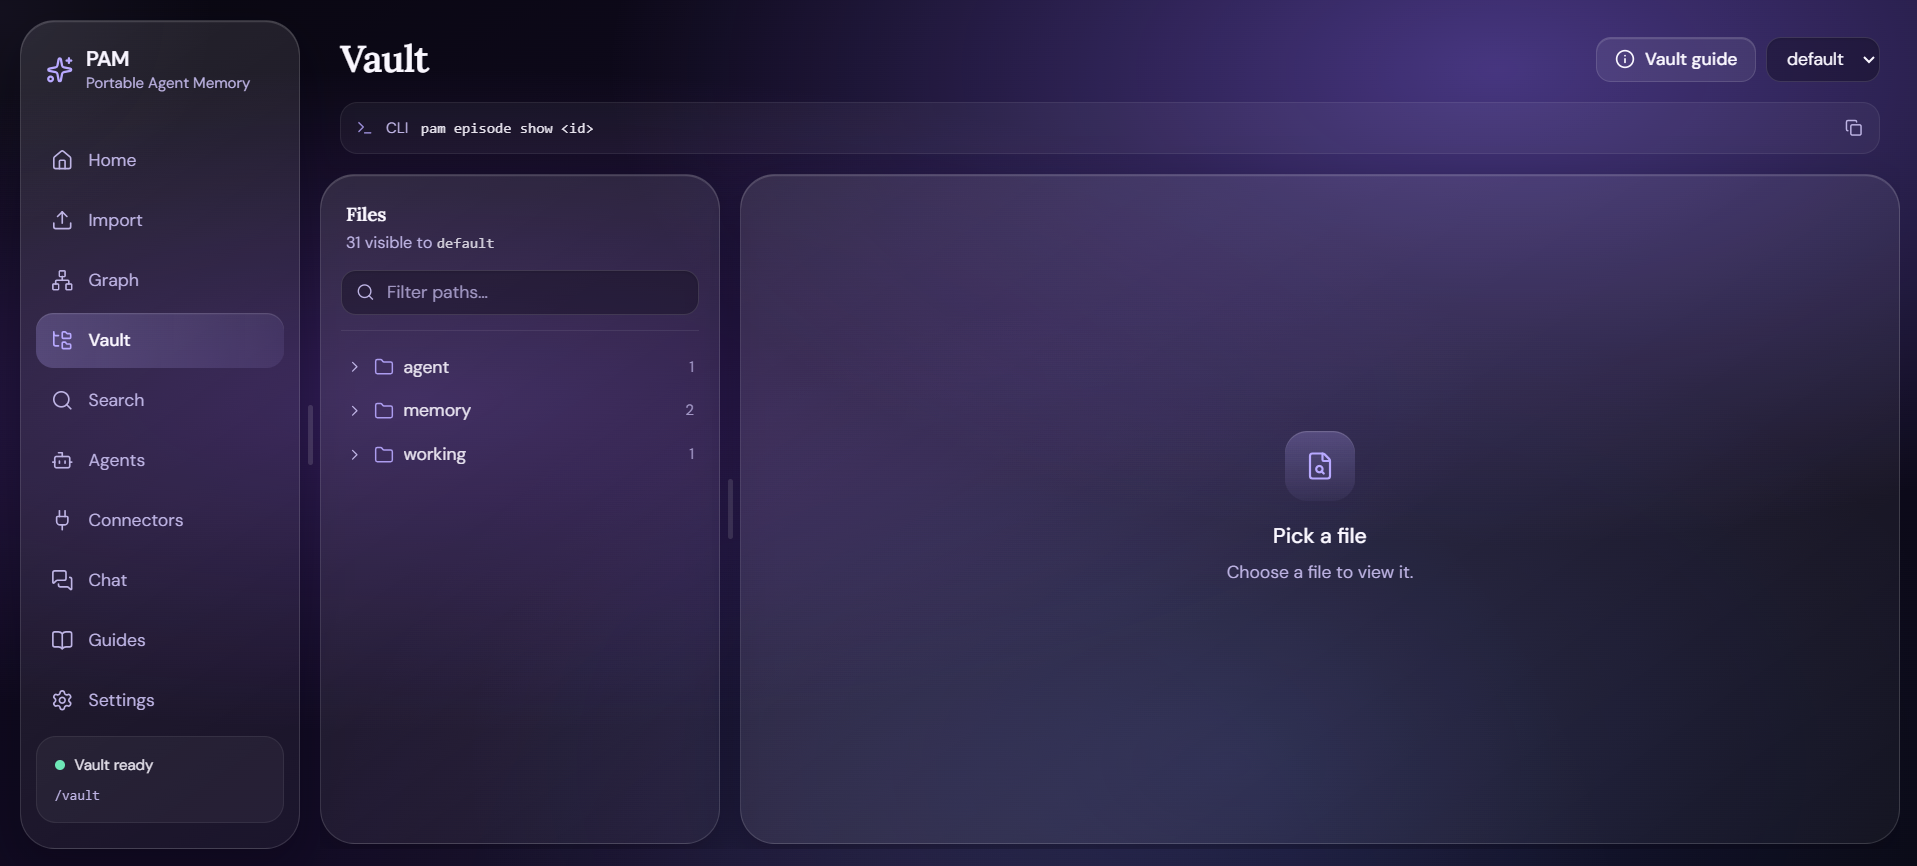
You can import chats from Claude, ChatGPT and Gemini, and your memory stays as plain files that you can read. PAM finds facts, projects and your persona without using an LLM. It searches your history with keyword and vector search, and builds a small context pool that saves tokens compared with replaying full chats. The web app includes an import wizard, a project graph, a vault browser, search, an agent editor and a chat where you can switch models mid-conversation, and retain across session contexts
Built with Python, FastAPI, Typer, SQLite (FTS5 + sqlite-vec), fastembed, spaCy, HDBSCAN, LiteLLM, React, TypeScript, Vite and Docker.
We faced a lot of challenges while building this project, especially while interfacing the front and back ends. Another issue that came up was figuring out how to determine facts after pulling from data. In order to protect user privacy, we avoided using and LLM, and instead used a light-weight ML model to group related episodes together. This way, everything can be run locally.
Another challenge we faced was scope. Initially, we wanted to implement importing and connecting to other models through MCP's, so you could export the data we store to another LLM. That way, you could switch straight from Claude to ChatGPT, for example, without losing any relevant context. In the future, we want to make this data model agnostic, so that any user can take any data from any model and give it to another one without losing a beat. Implementing the MCP would allow us to do this. These are future plans, however, and our current prototype is proof that transferring context in this way can work.
Title: Cook Smarter
Sponsored side tracks:
- VEYZL
- Cloudforce
- T-Mobile
Non-sponsored side tracks:
- MLH Best Use of Gemini API
- MLH Commit Fellowship
- MLH DEV Writing Challenge
Built With
- fastapi
- fastembed
- hdbscan
- litellm
- mcp
- python
- react
- spacy
- sqlite-(fts5-+-sqlite-vec)
- typer
- typescript
- vite

Log in or sign up for Devpost to join the conversation.