-
-
logo_v3
-
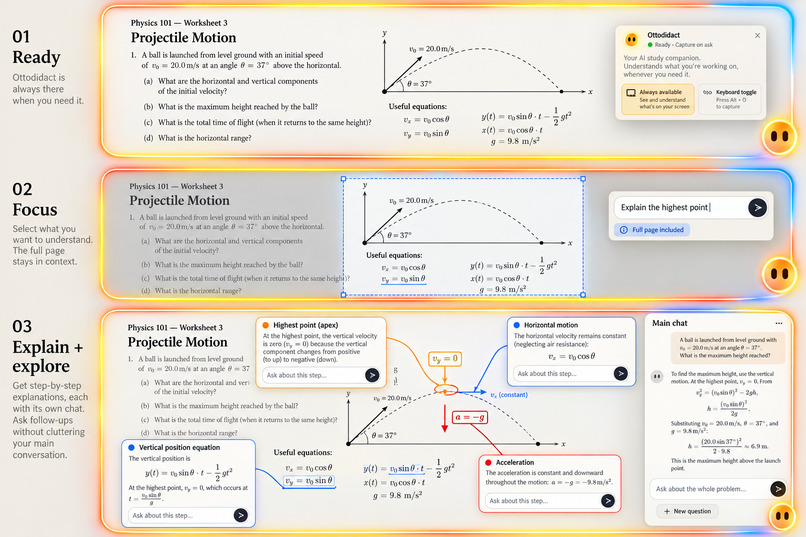
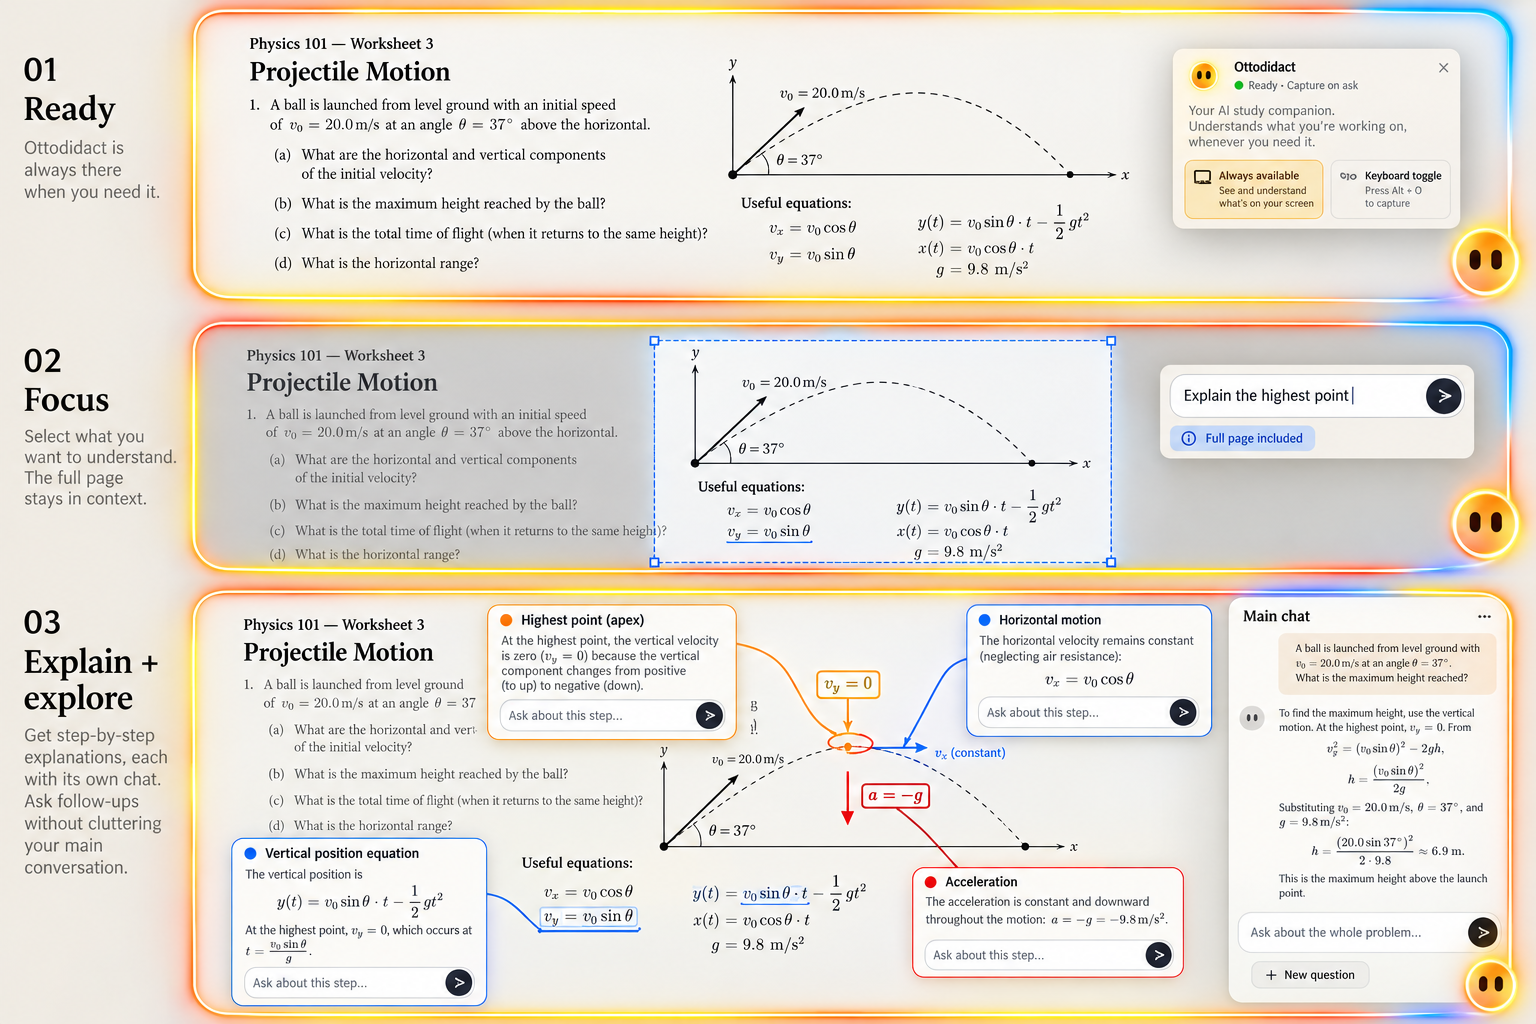
UI design v1
-
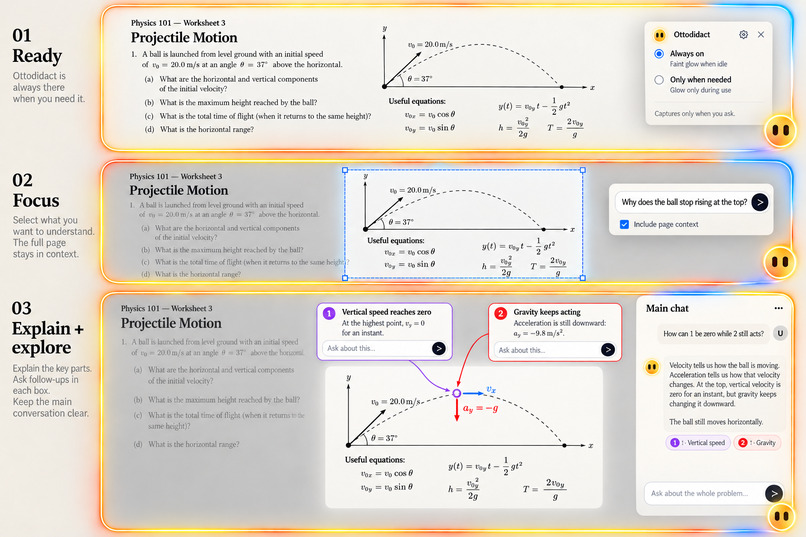
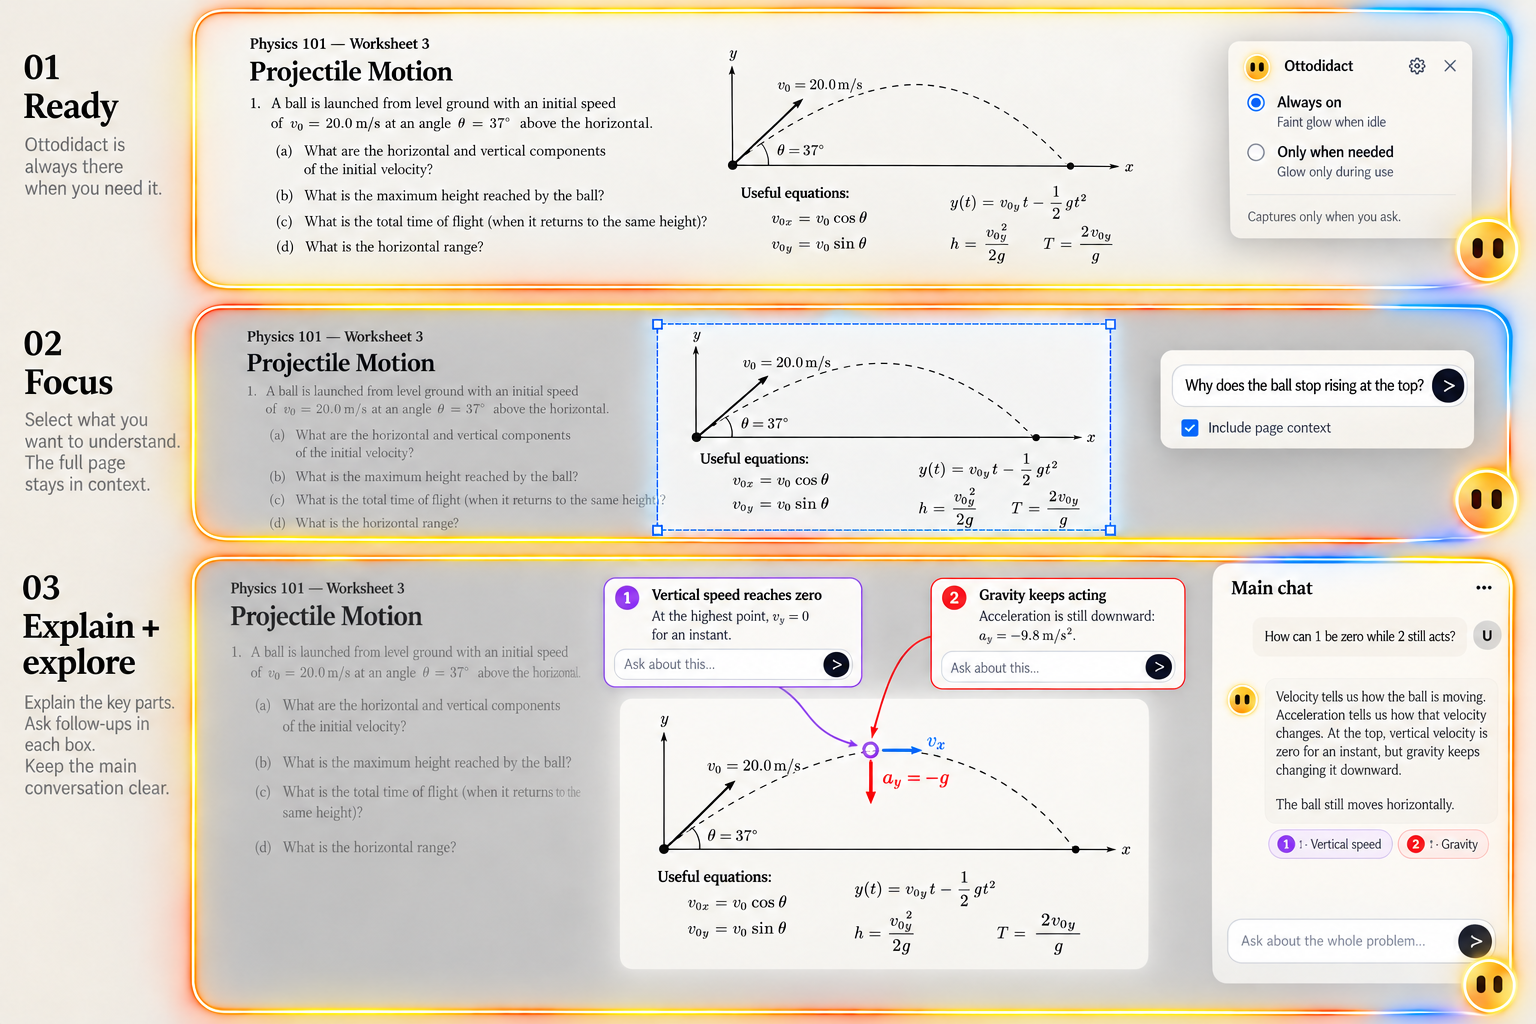
design v2(with more features
-
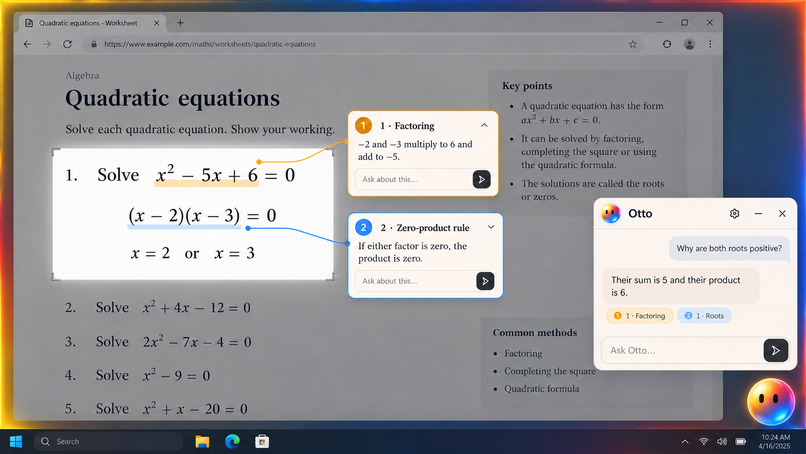
ui v3 with new features to the electron/screen overlay
-
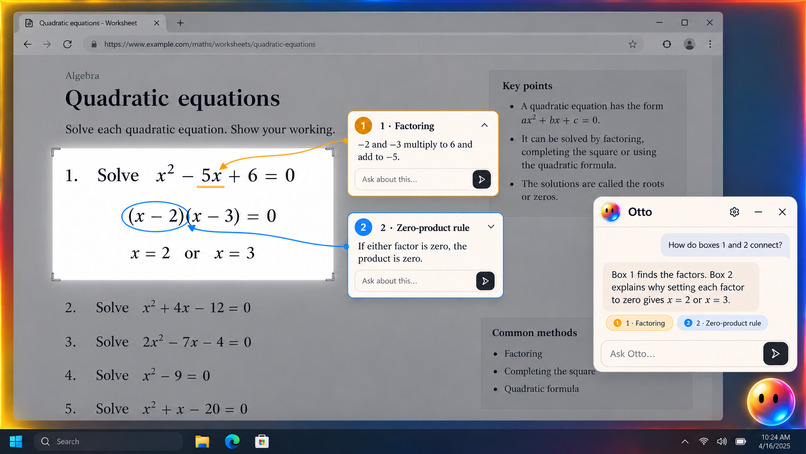
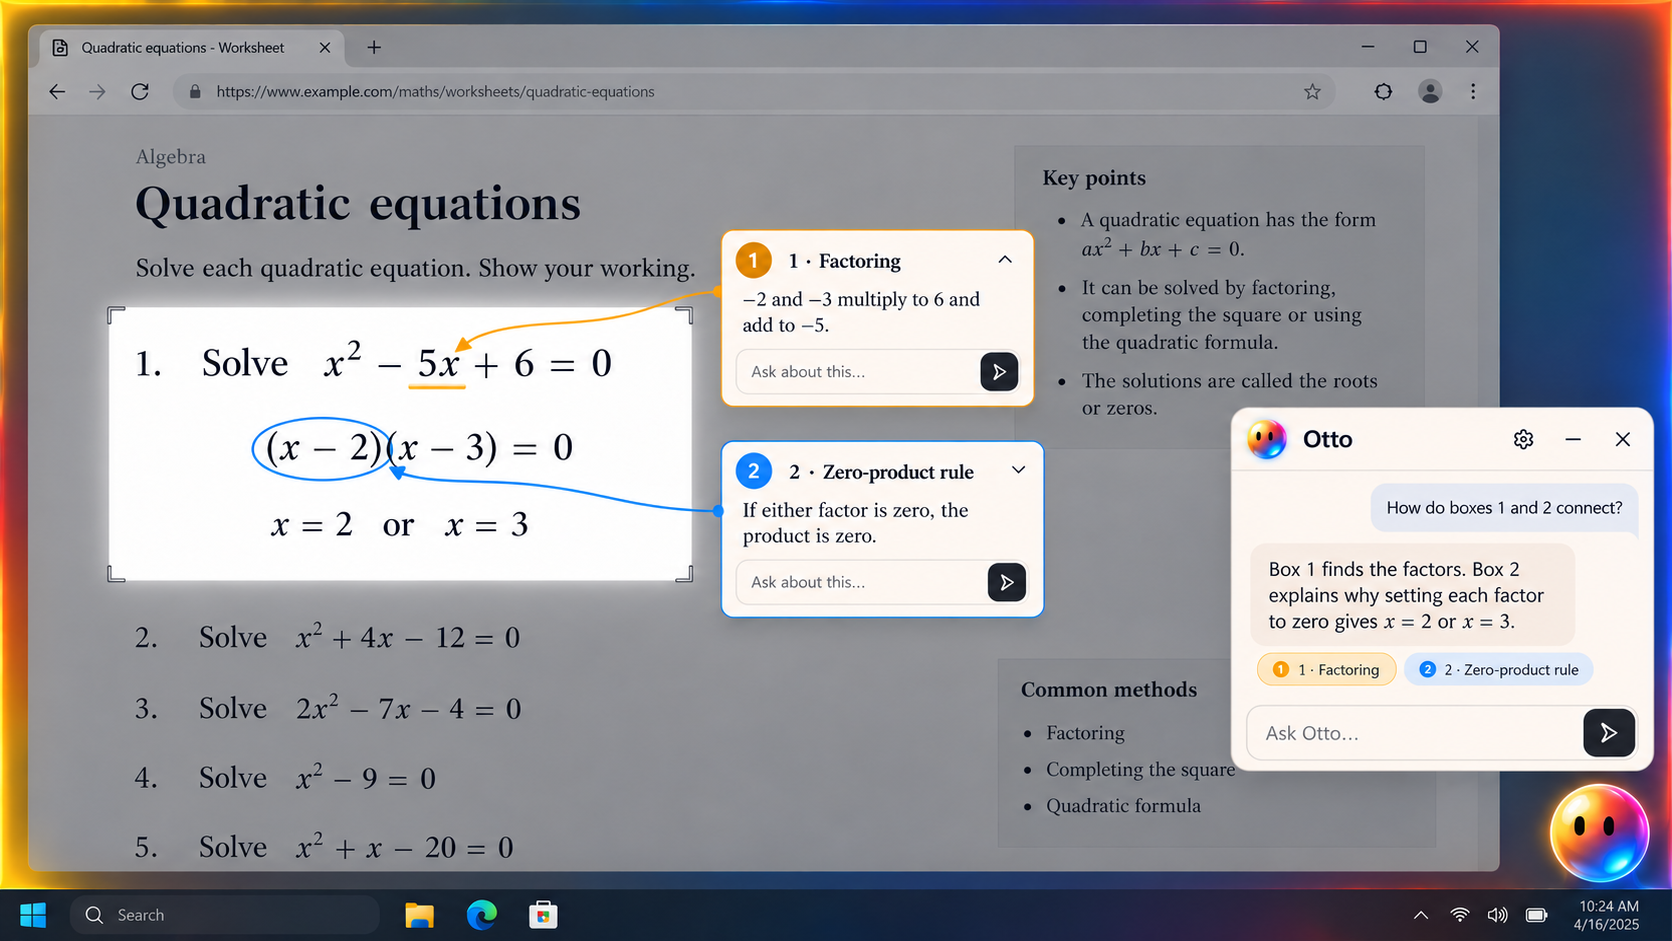
using more variety of markers such as boxes, underline, arrows, highlights, and circling
-
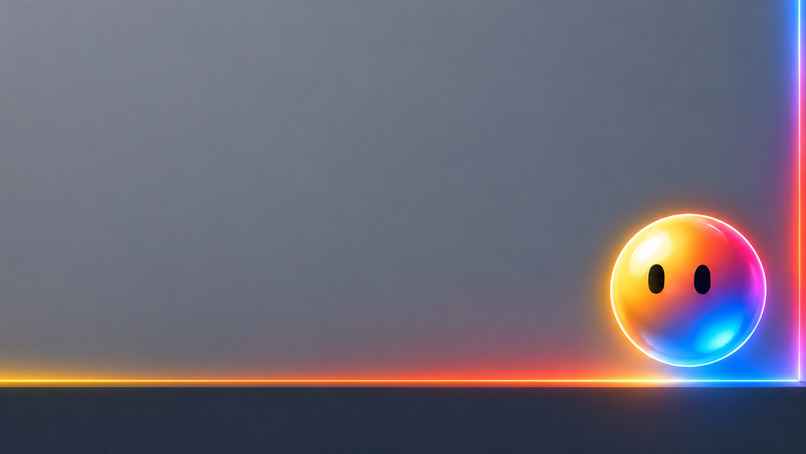
button interaction with edge of screen
-
button design v2
-
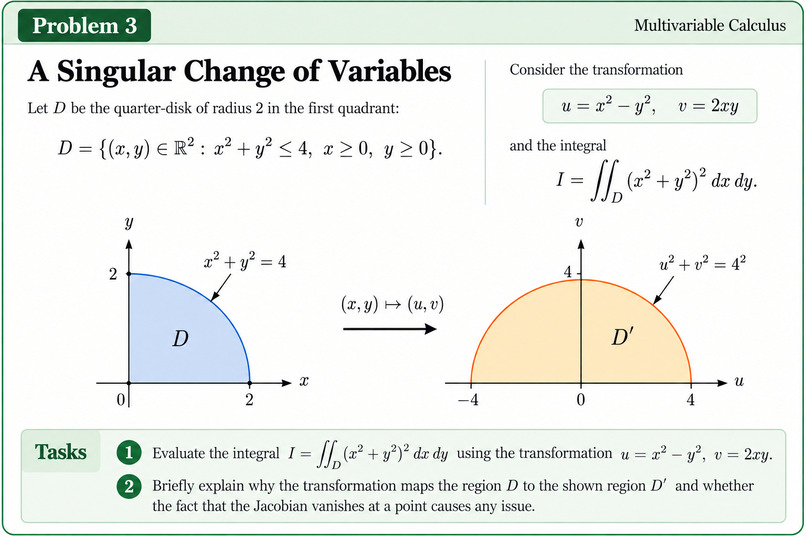
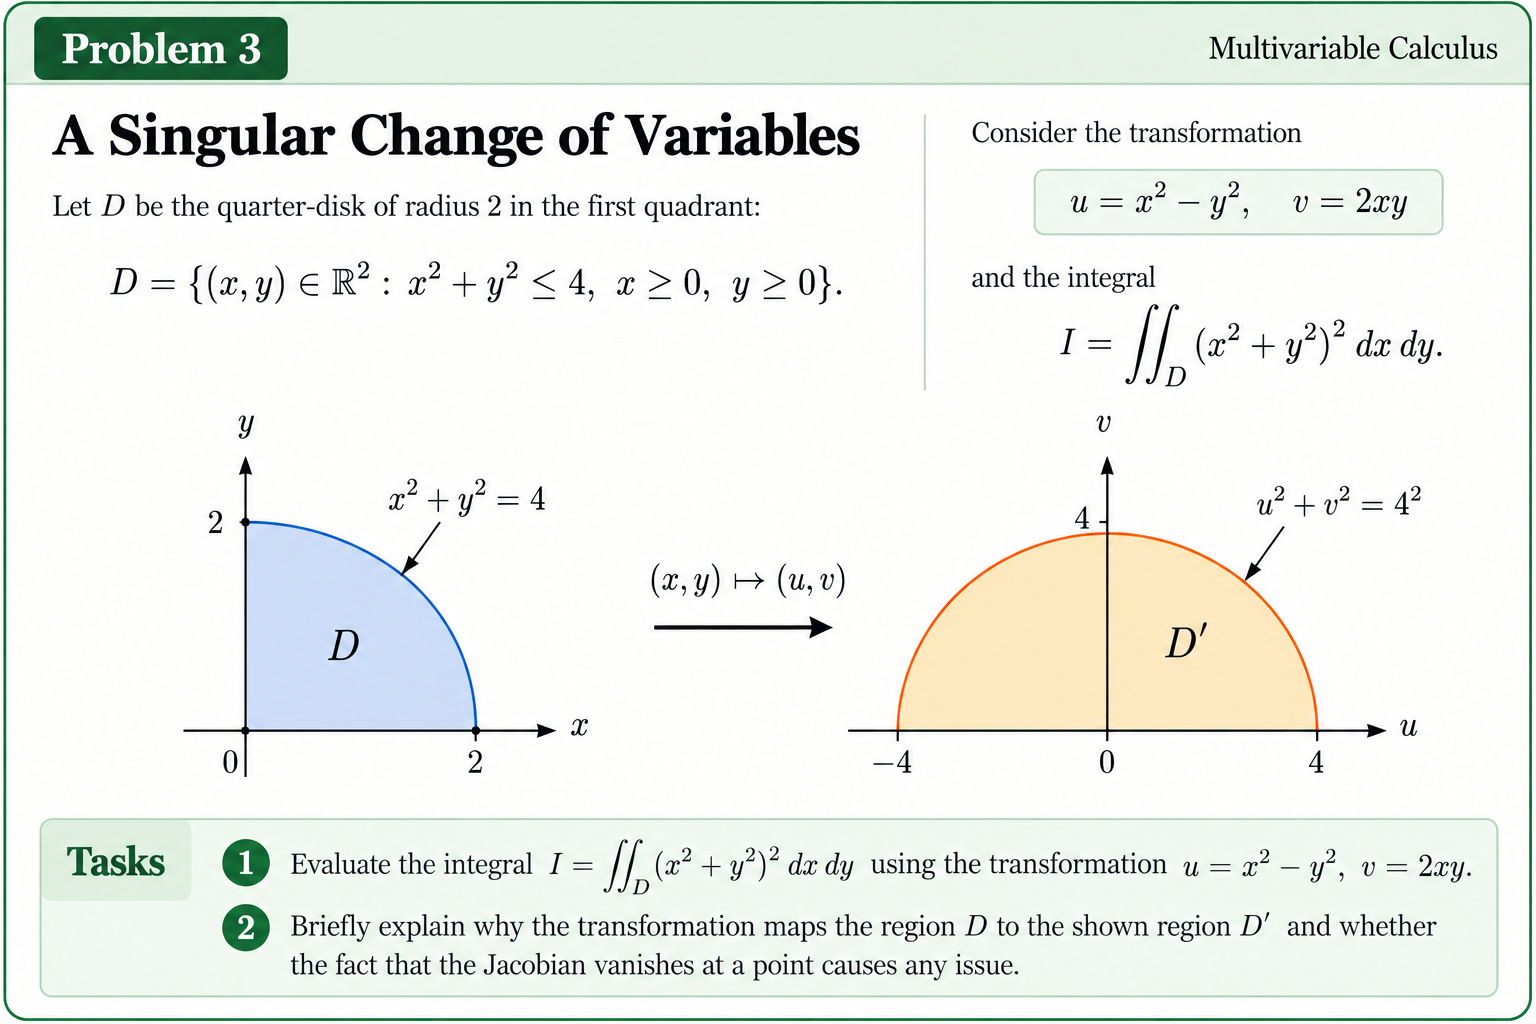
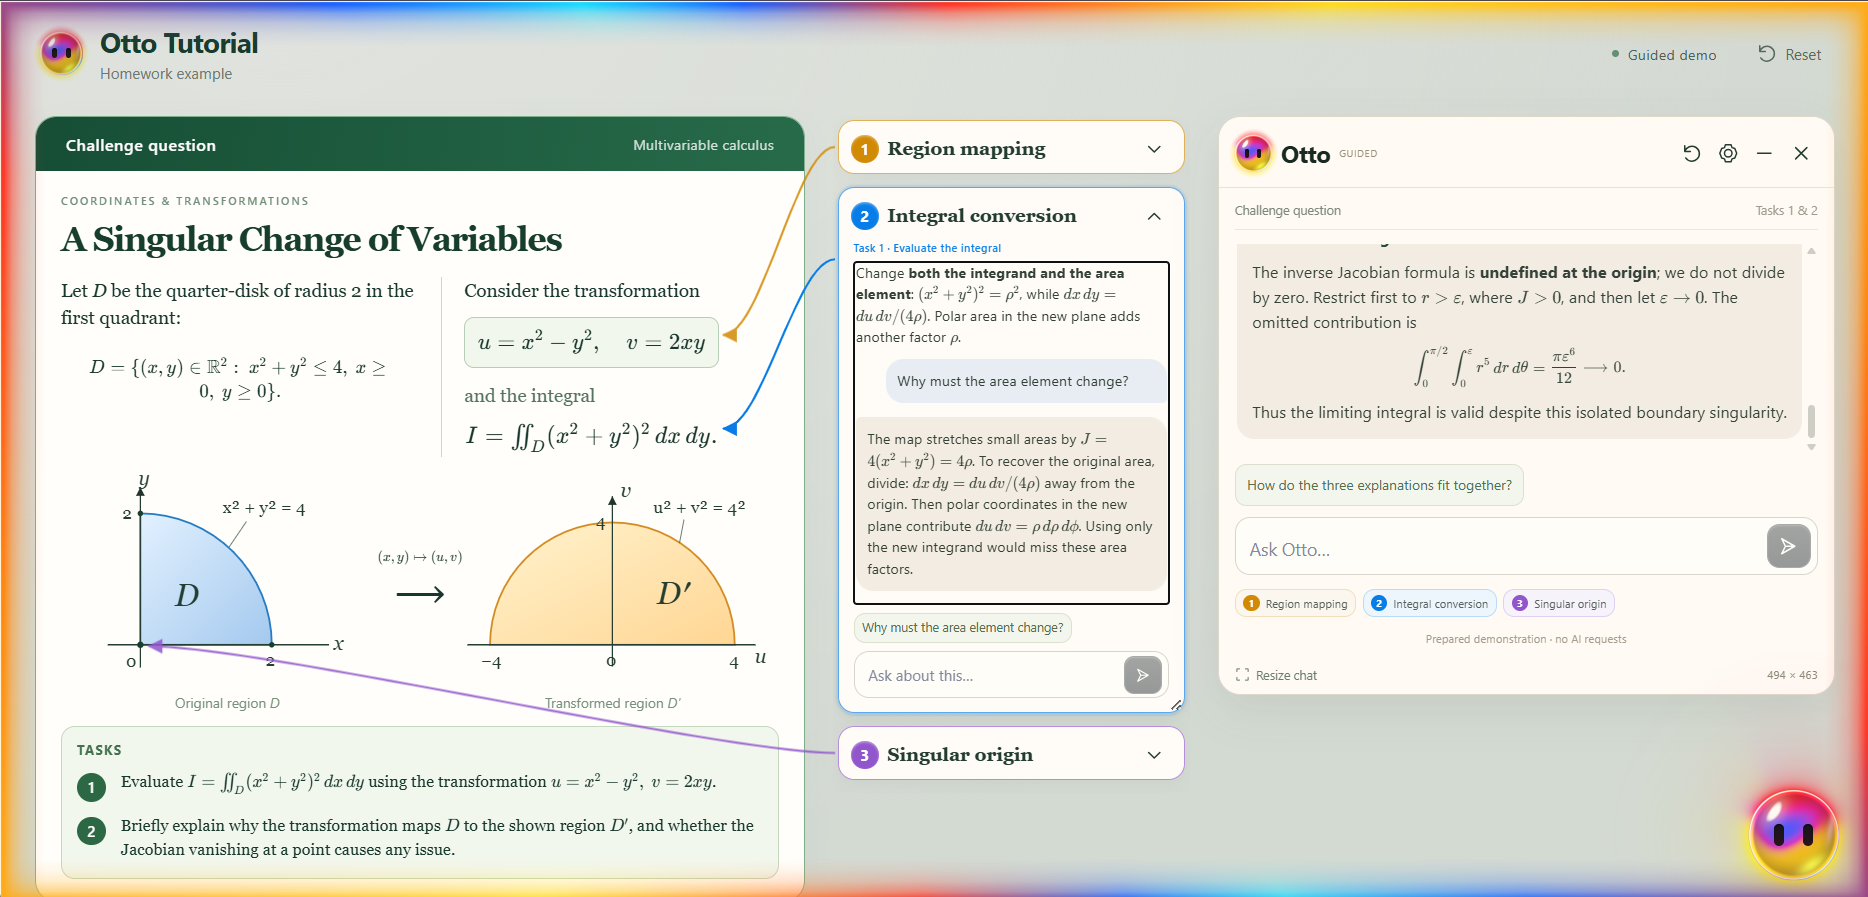
multivariable double intagral calculus to test ottos competency at explanations/usfulness and accuracy with screen overlay
-
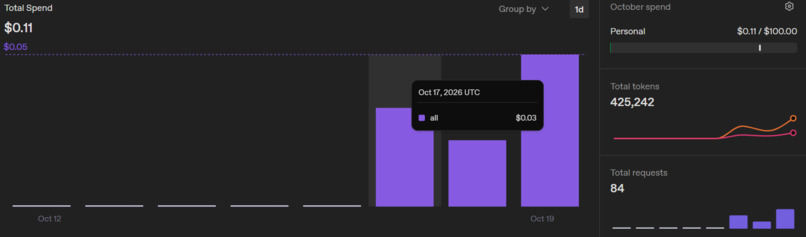
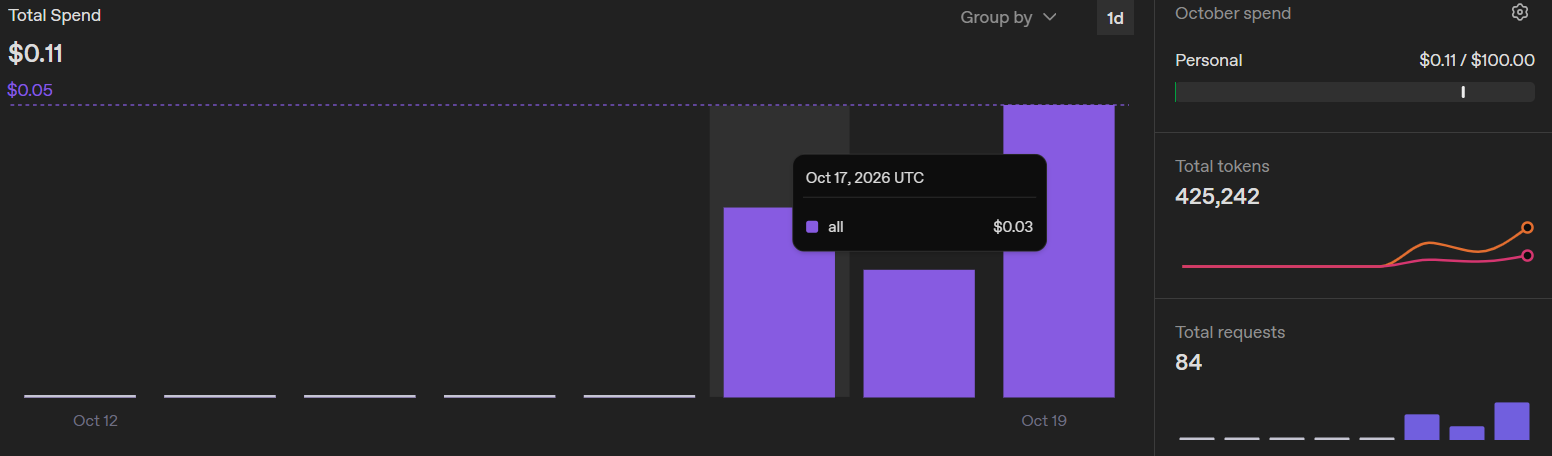
refining token usage to i dont go broke(finetuning my AI)
-
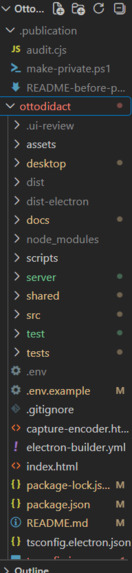
file management is a NIGHTMARE
-
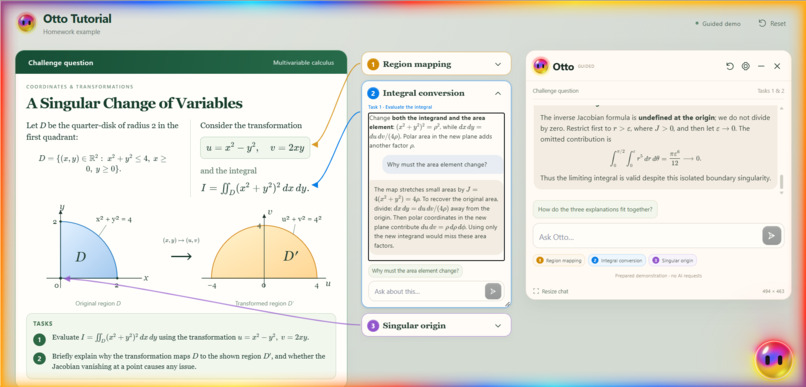
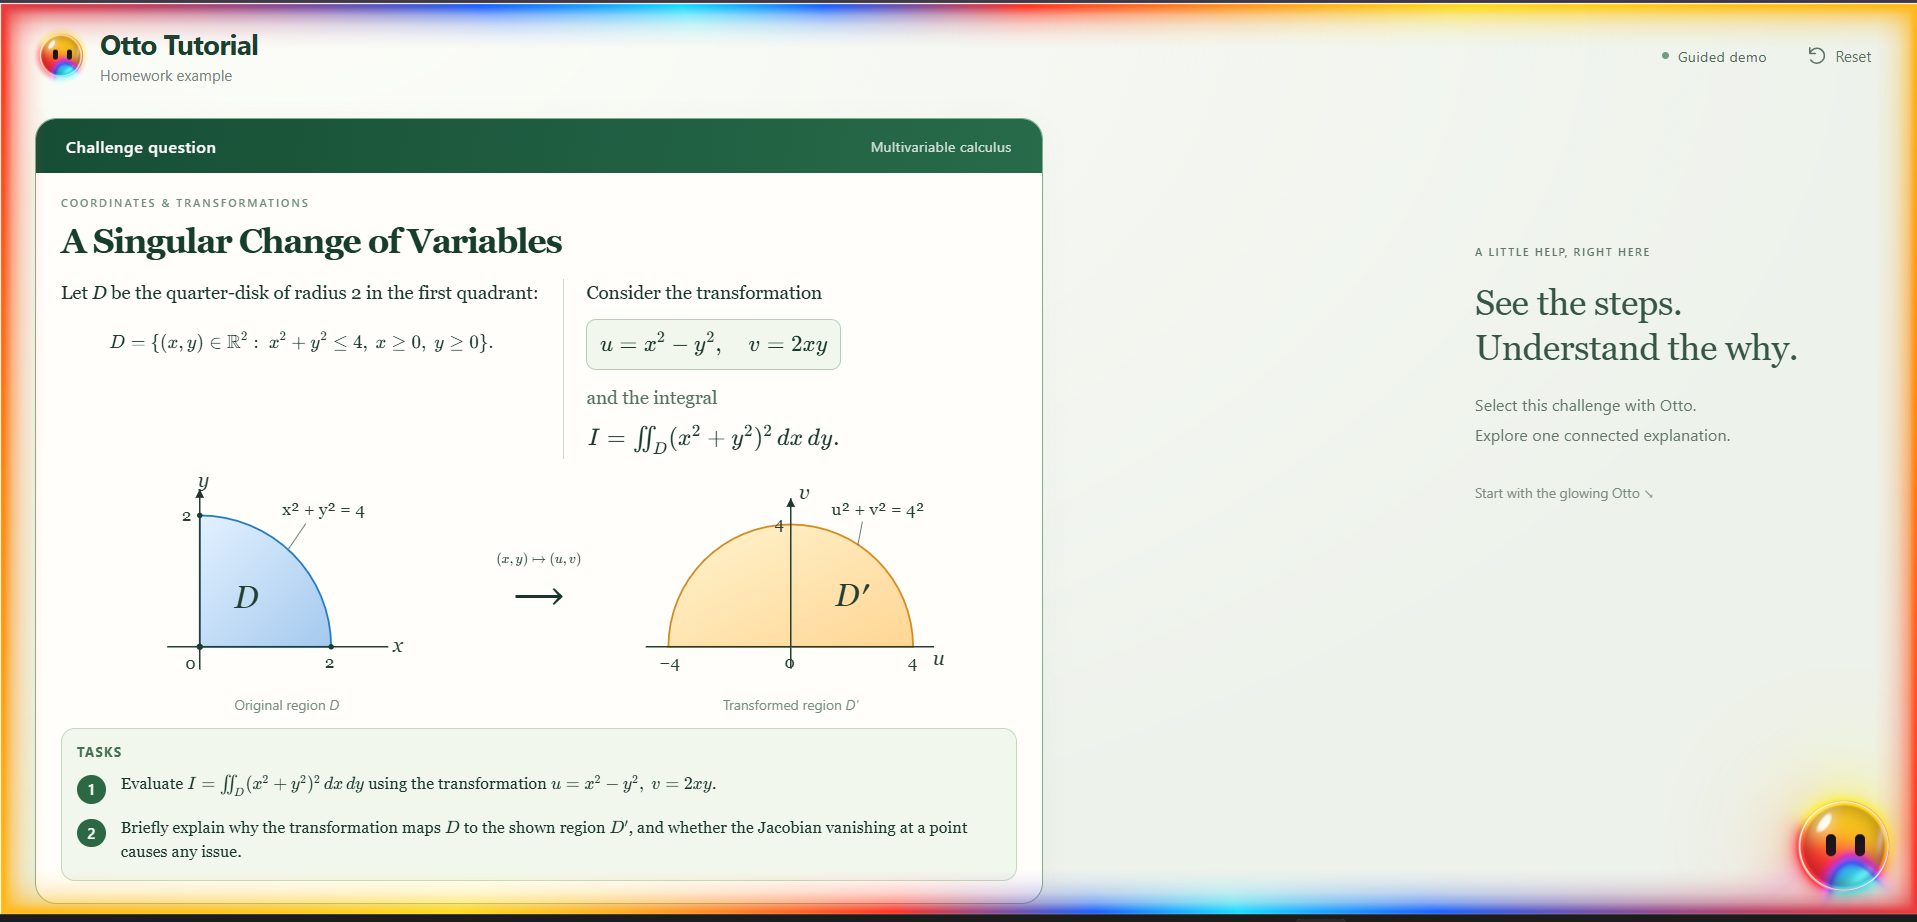
DEMO SITE(electron wont show up in recordings or screenshots) no Ai connected just a demo, api costs money
-
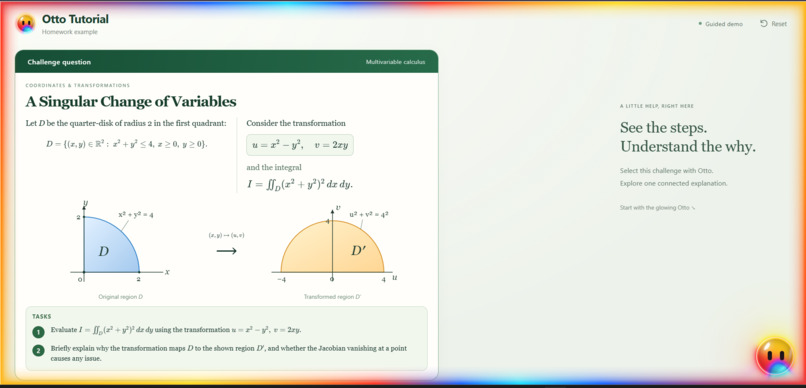
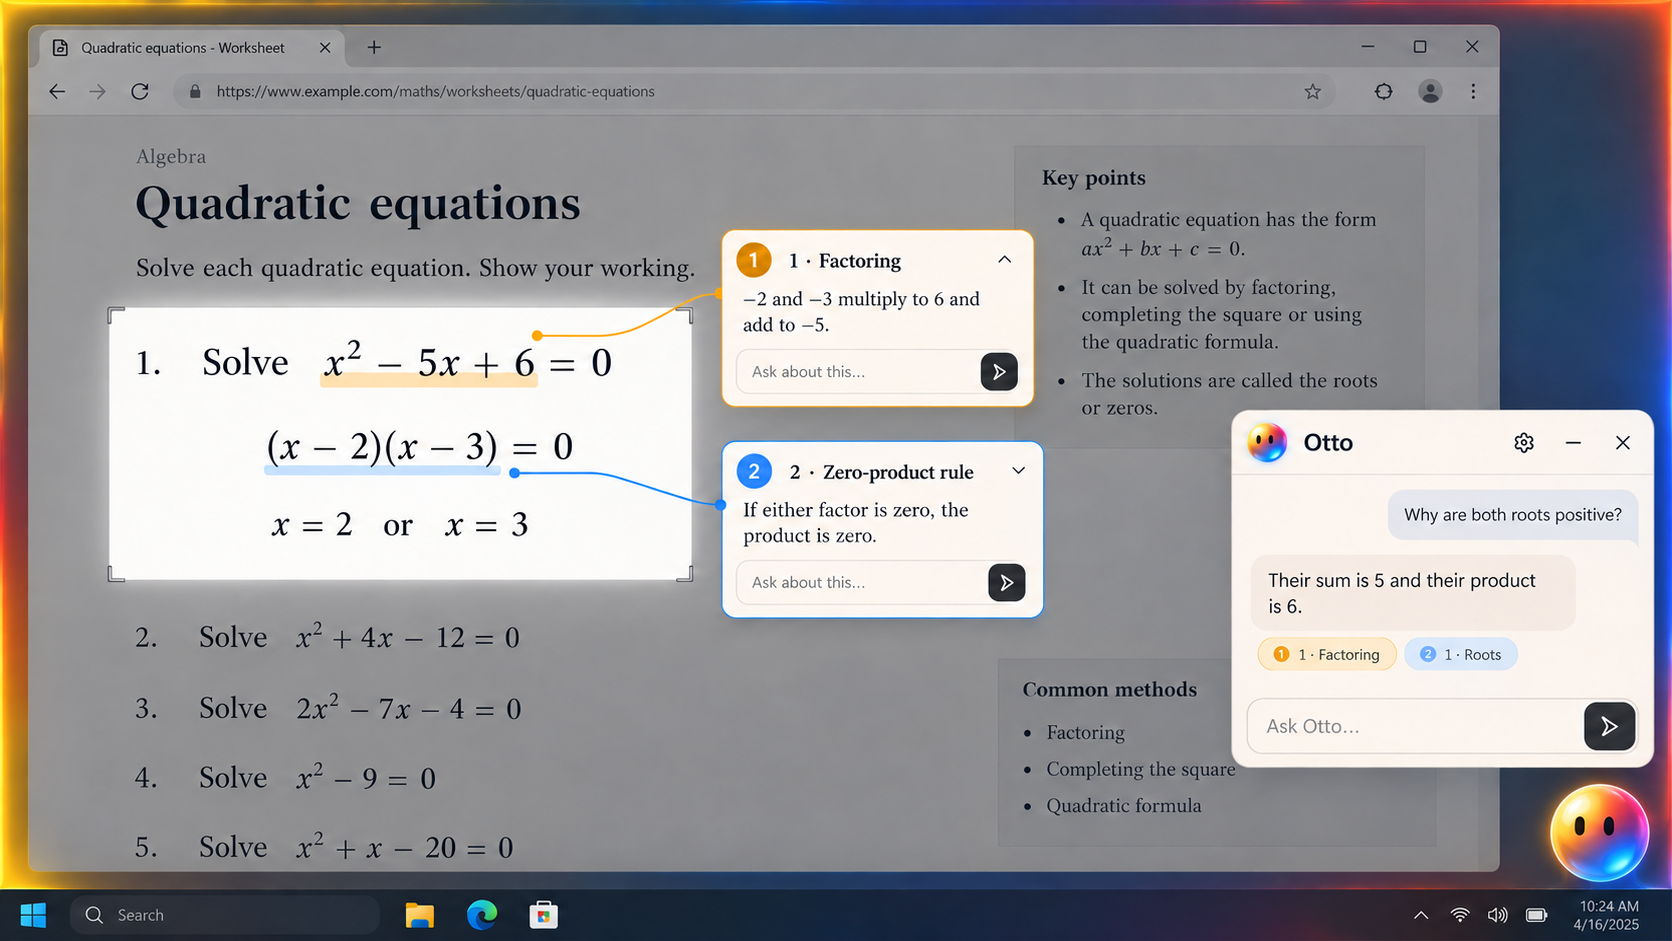
DEMO site, this is how it would look on your screen, it sits ats the bottom and you can navigate to any page and click on it to screen shot
Inspiration
Ottodidact was inspired by Google Lens's visual interaction, ChatGPT's conversational AI, and the step-by-step explanations of a real teacher.
Traditional AI chats often bury the original question under countless follow-ups. We wanted to create an AI tutor that lets students explore individual concepts without losing their original learning path.
What it does
Ottodidact is a desktop AI tutor that understands and explains content directly on your screen.
- Screen Selection: Select any region of your screen, including equations, diagrams, text, or code, and ask Otto about it.
- Visual Explanations: Otto uses arrows, circles, underlines, and highlighted regions to connect explanations to exact parts of the screen.
- Contextual Side Chats: Ask questions about specific steps in separate conversation branches without interrupting the main explanation.
- Persistent Main Conversation: The original question and explanation remain accessible regardless of how many follow-up questions you explore.
- Dynamic Overlays: Explanation cards automatically resize and reposition around screen content.
- Desktop Integration: Otto stays accessible as a floating companion, allowing students to learn across different applications without switching to a chatbot.
How we built it
Ottodidact was developed using Electron, React, TypeScript, and the OpenAI API, combining desktop screen capture, AI vision, and custom visual annotation systems.
Our implementation includes:
- Screenshot processing: Captures selected screen regions and sends visual context to the AI.
- Coordinate-based annotations: Maps AI-identified targets to screen coordinates for arrows, circles, and underlines.
- Dynamic UI positioning: Calculates explanation-card positions, dimensions, and annotation connections.
- Context management: Maintains separate conversation histories for the main explanation and individual side questions.
- AI integration: Uses multimodal language models to interpret visual content and generate contextual explanations.
We combined AI-assisted coding with manual development, code reviews, debugging, and extensive testing to refine the application.
Challenges we ran into
Our biggest challenge was accurate visual annotation placement. Mapping AI-generated coordinates onto screenshots required handling screen scaling, variable content sizes, overlapping elements, and unusual selection boundaries.
Another challenge was dynamic explanation layouts. Cards needed to resize and reposition without covering important content or other conversations.
We also encountered API latency and token costs, particularly when processing large screenshots and maintaining multiple conversations. Optimizing the amount of visual and conversational context sent to the model became an important part of development.
Accomplishments that we're proud of
- Built a functional desktop AI tutor that interacts directly with screen content.
- Implemented contextual side conversations that preserve the original explanation.
- Developed a visual annotation system connecting explanations to precise screen locations.
- Created dynamically positioned and resizable explanation cards.
- Integrated screenshot-based AI understanding into a floating desktop interface.
- Tested the interface across different display scaling settings and edge cases.
Our biggest accomplishment is combining visual grounding, contextual branching, and interactive tutoring into one experience instead of relying on a conventional linear chatbot.
What we learned
We learned that building an effective AI application involves much more than integrating a language model.
Precise coordinate mapping, screen overlays, context isolation, UI collision handling, and token optimization were critical engineering challenges.
We also learned how to use AI-assisted development effectively while maintaining human control over architecture, debugging, and code quality.
What's next for OttodidactAI
- More precise visual grounding: Improve annotation accuracy for small symbols, equations, and complex diagrams.
- Lower latency and API costs: Optimize screenshot processing, model routing, and context reuse.
- Smarter conversation branching: Improve how side conversations retain context without affecting the main explanation.
- Enhanced tutoring: Introduce adaptive explanations based on a student's understanding and progress.
- Broader desktop support: Improve compatibility across applications, screen layouts, and learning environments.
Our long-term goal is to make Ottodidact a universal AI learning companion that works directly with whatever a student is studying. (also we are launching the product on NOV 20th for feed back!, if you read all of this, please give me a change to market and test my product on devpost!)
And as SCUBA CAT ONCE SAID: "KEPP ON SCUBA-ING, and you will reach da surface" (he didnt say that actually)


Log in or sign up for Devpost to join the conversation.