-
-
Start screen. Paste the task in the exact words it was given to you. No account, no API key, no setup, and no list of anything.
-
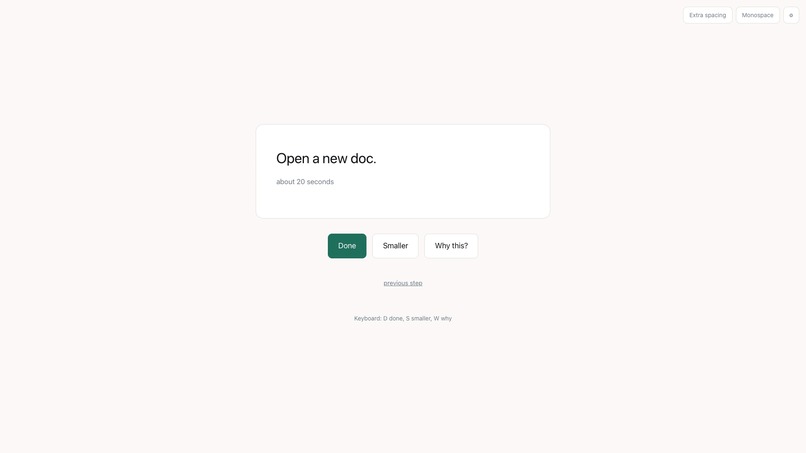
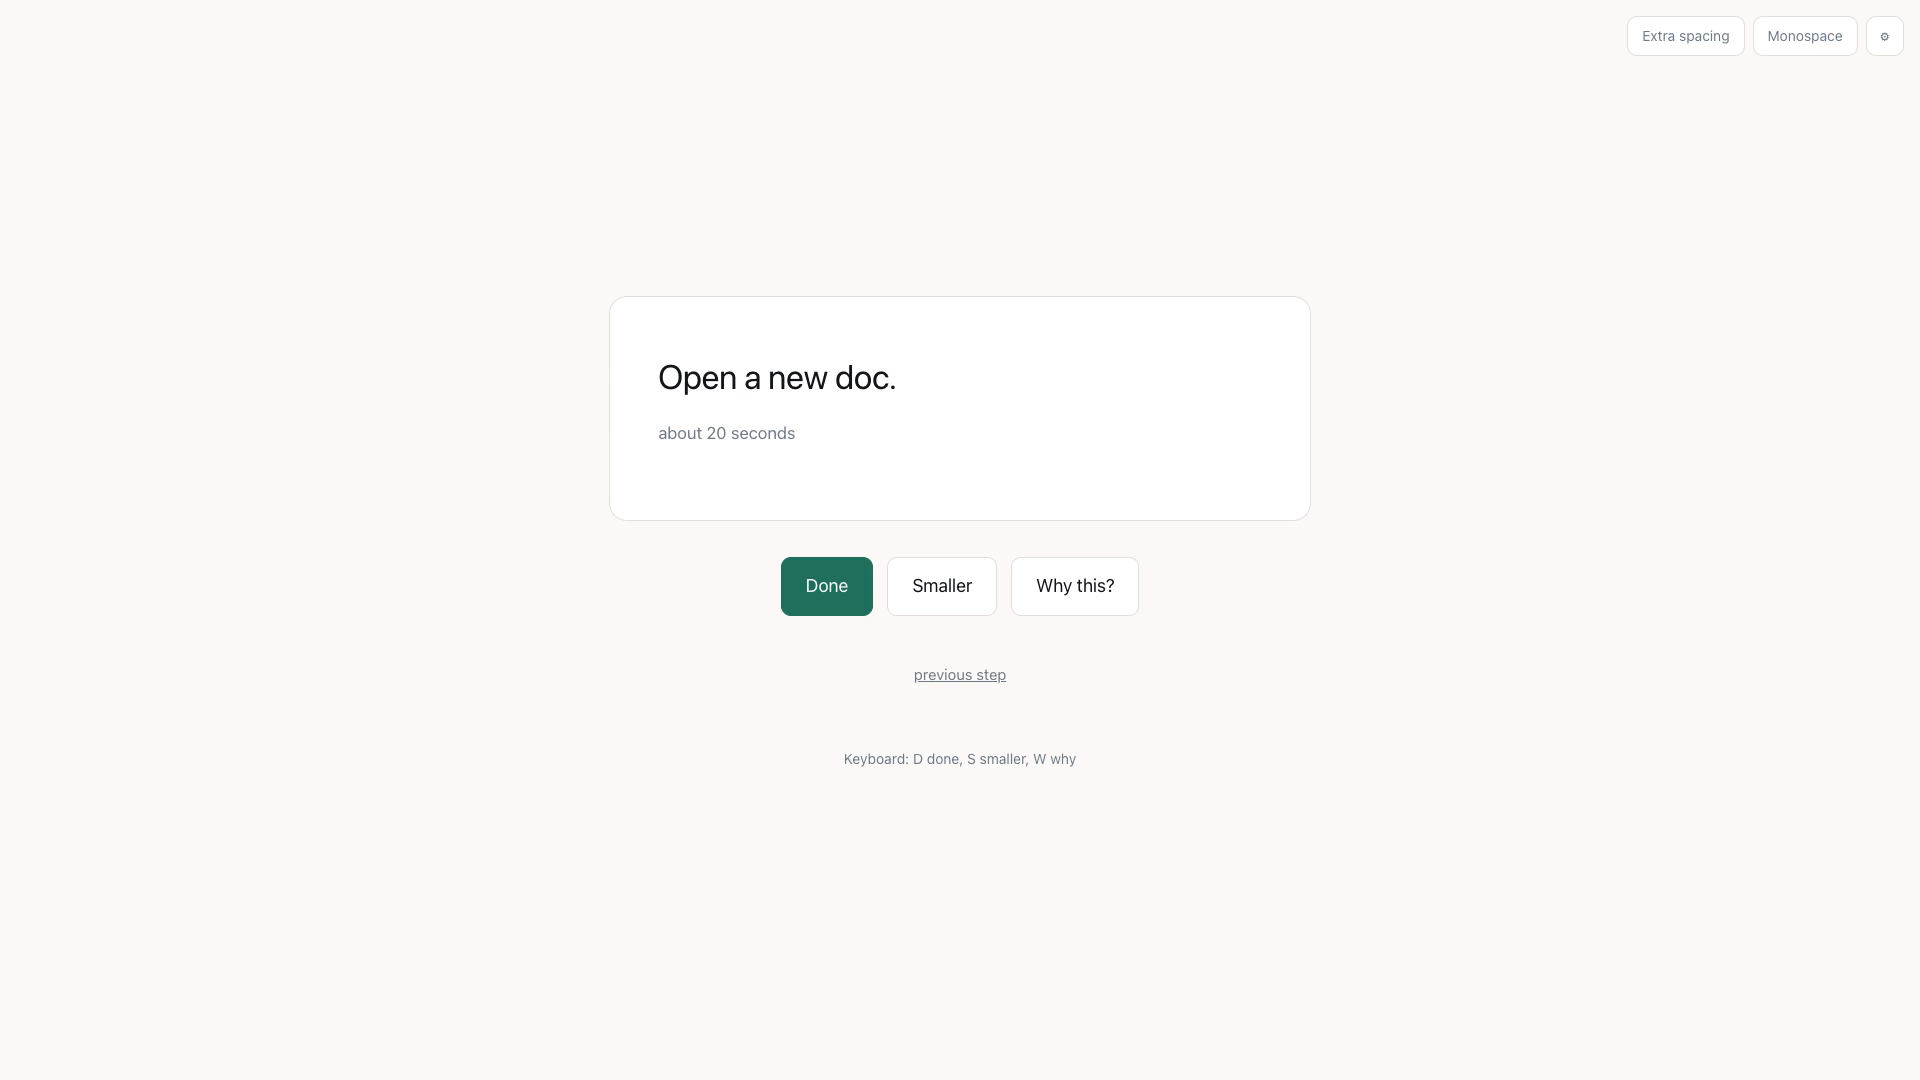
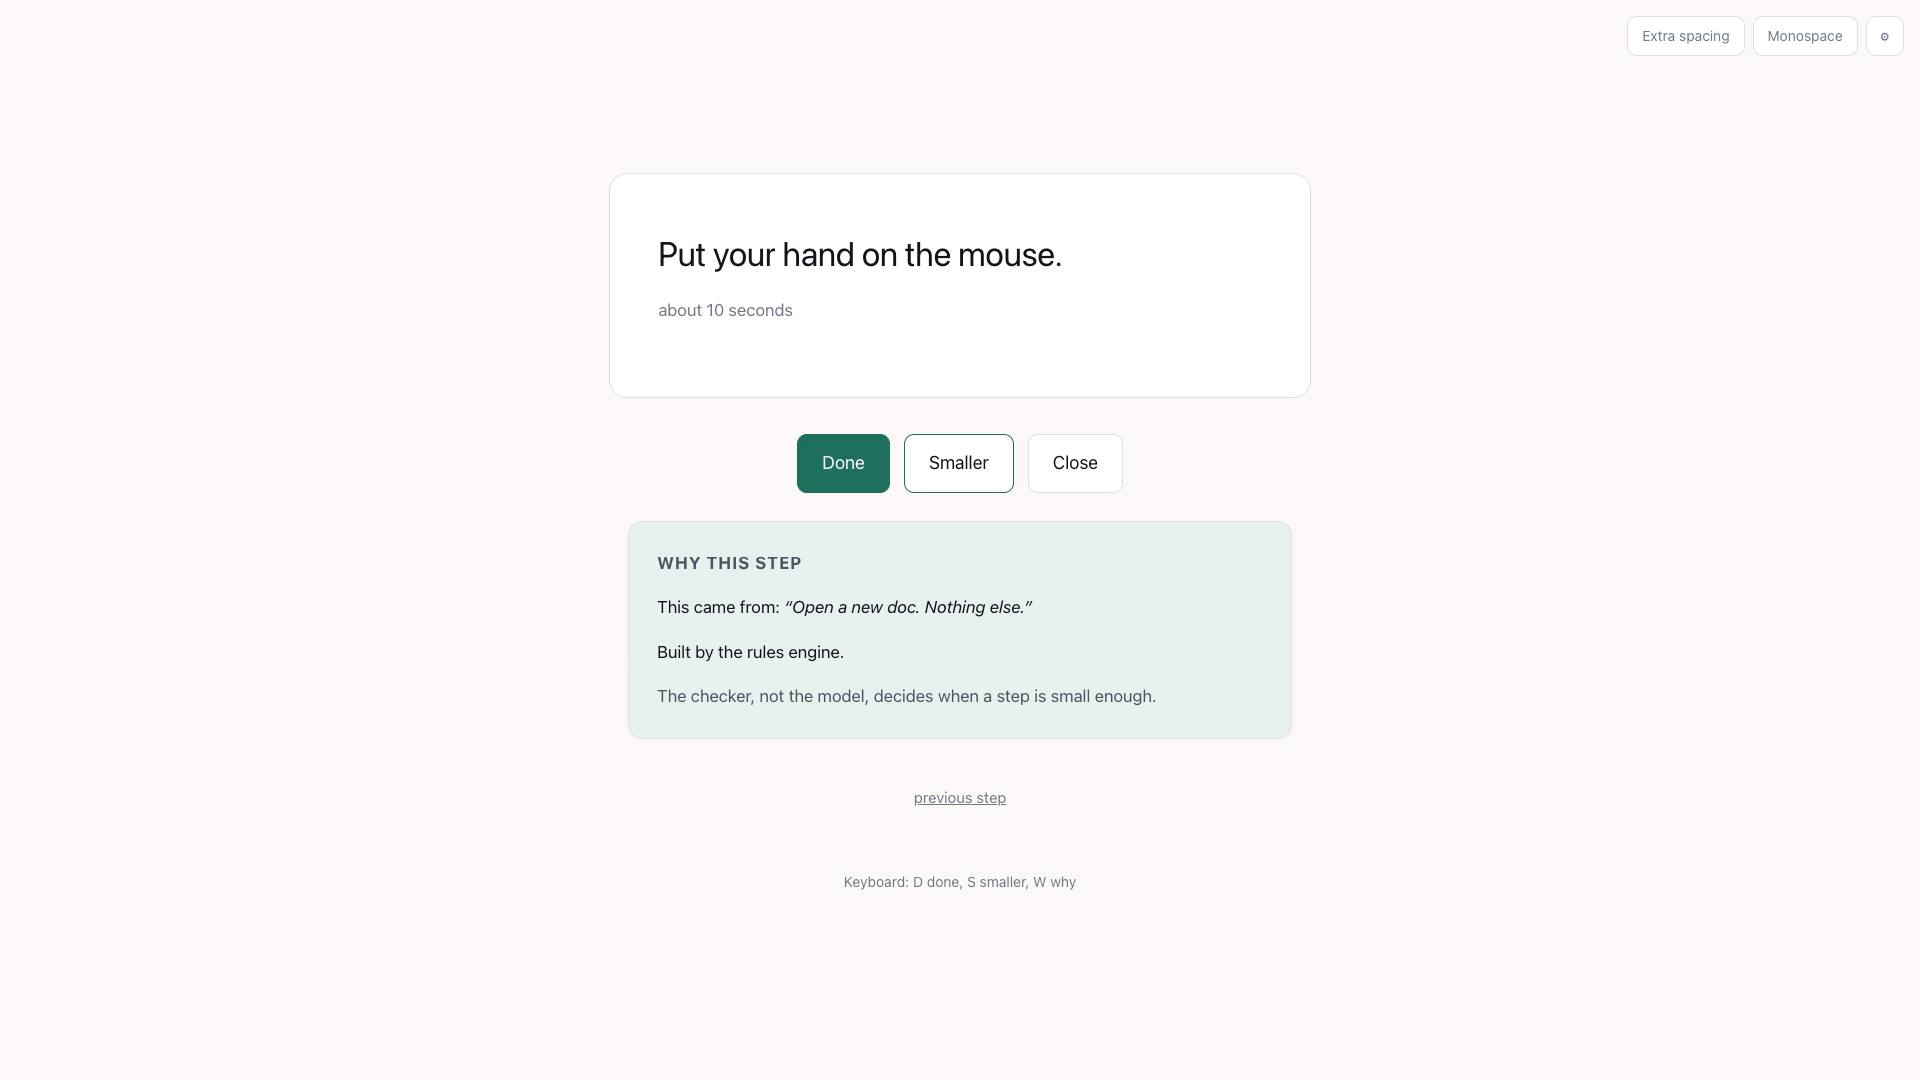
One step. Under two minutes. Every decision already made. Done, Smaller, Why this. No progress bar, no step counter, no list.
-
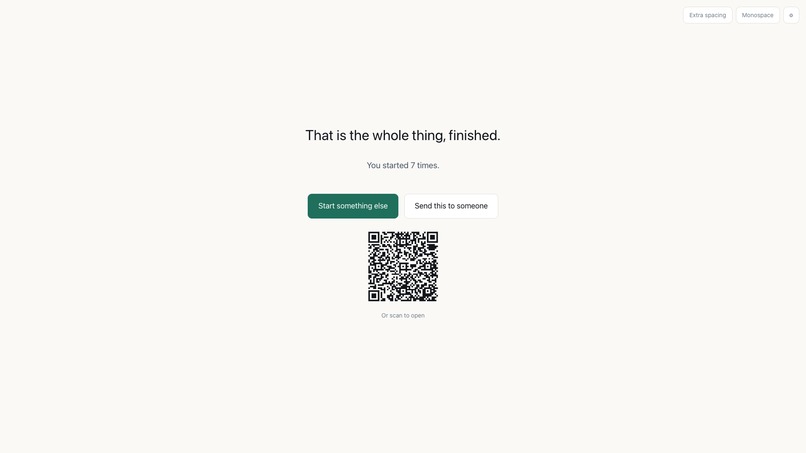
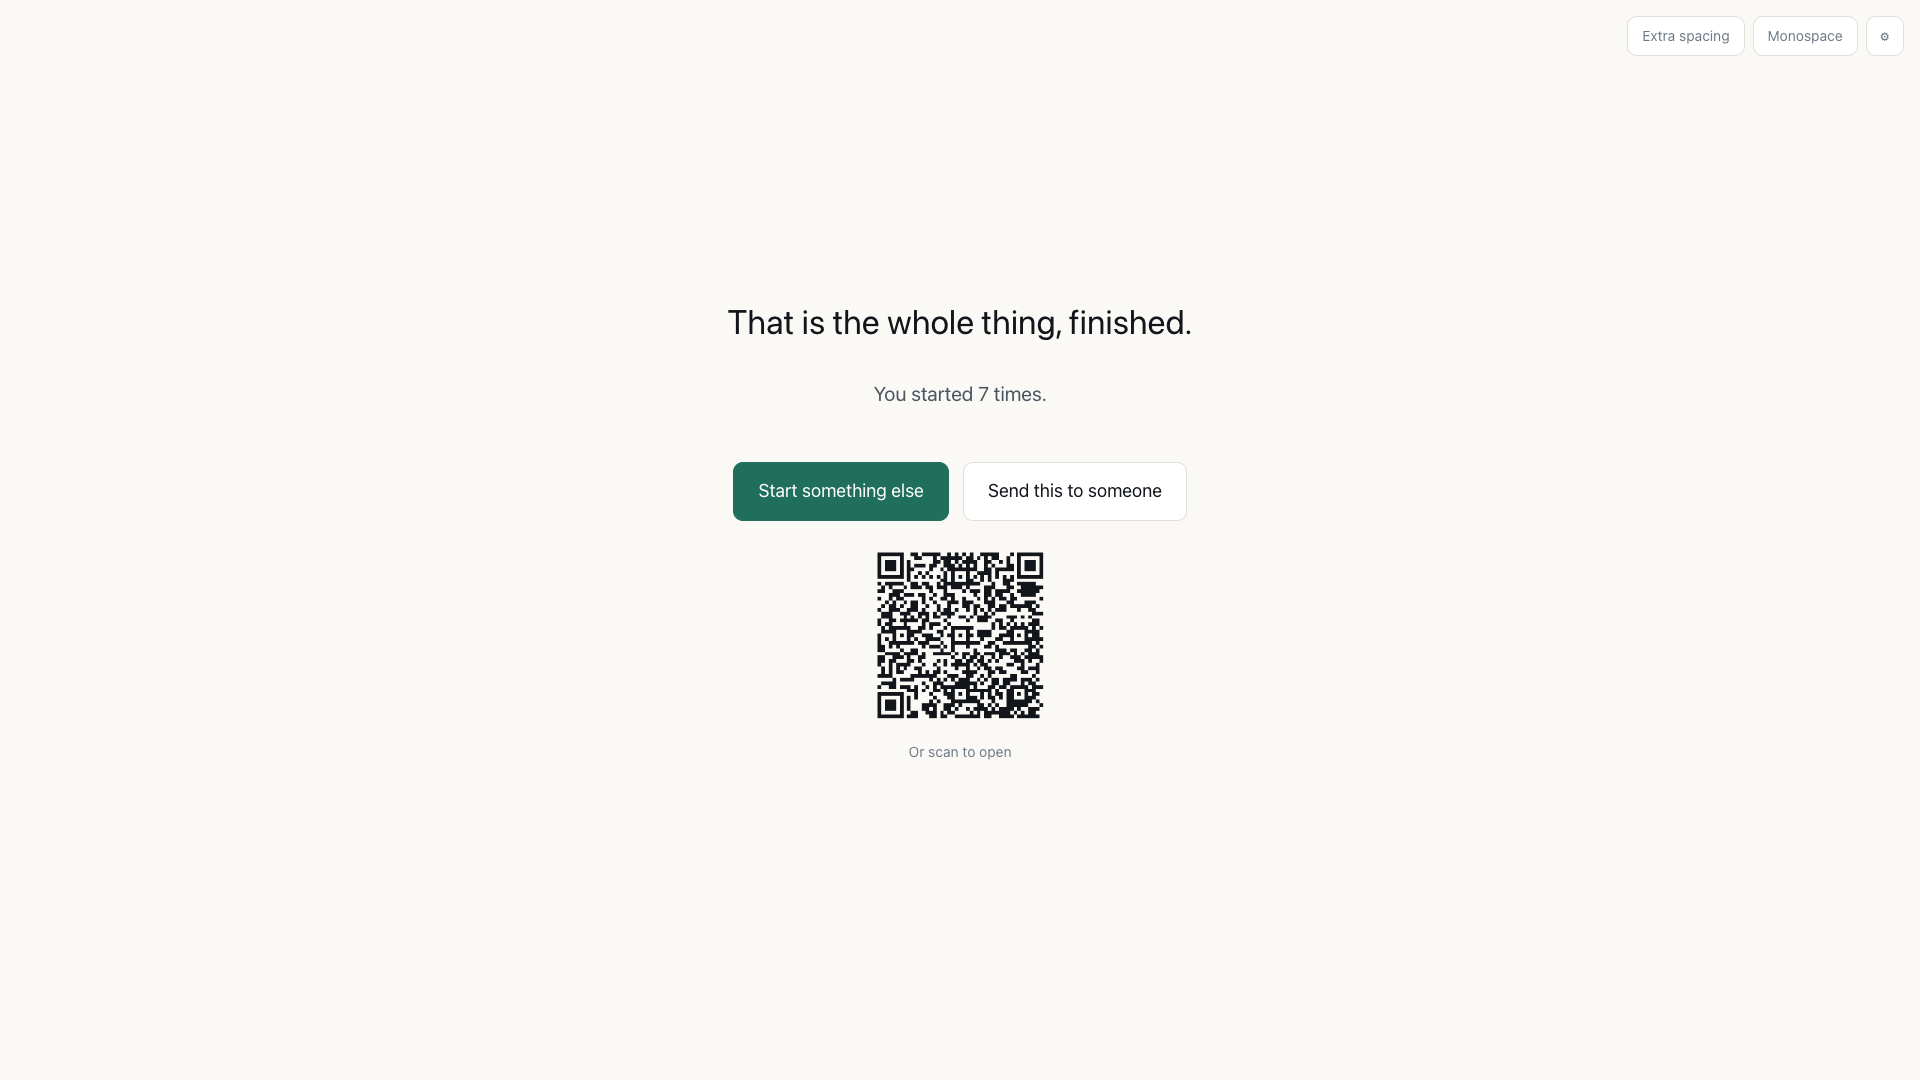
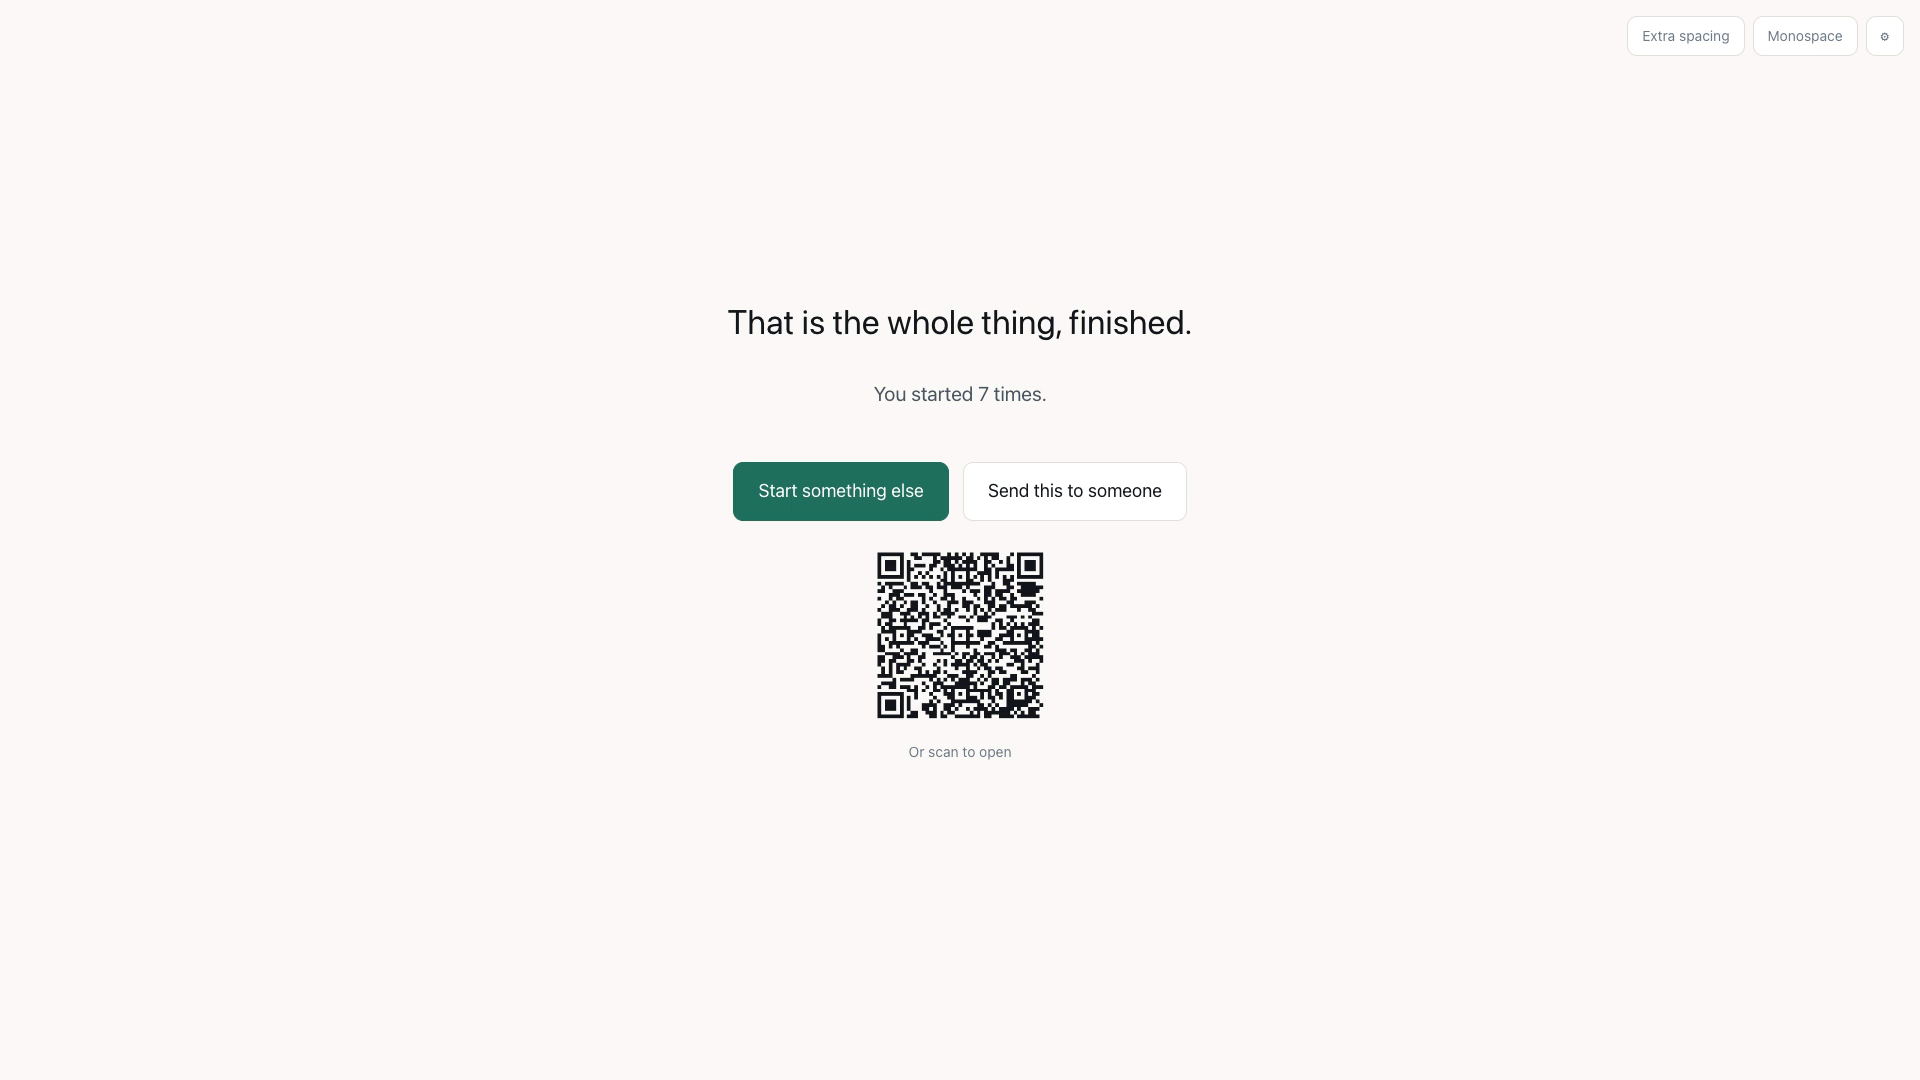
The ending. One true sentence about what you actually did. No score, no badge, no streak, nothing to keep up and nothing to break.
-
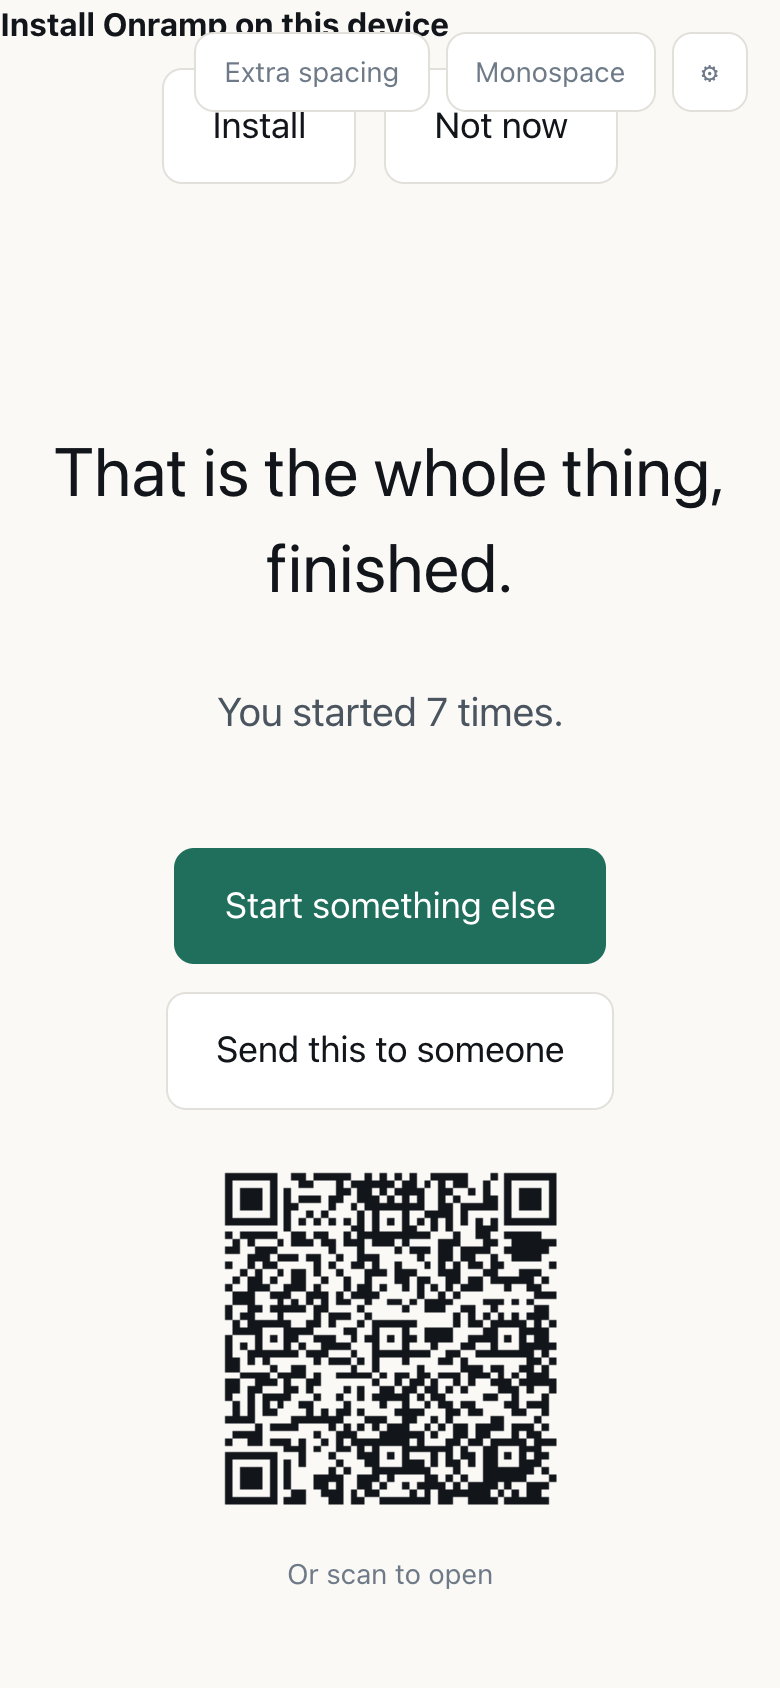
Runs on a phone as an offline PWA. 71.95 kB gzipped total, so it loads on filtered networks and keeps working with no connection.
-
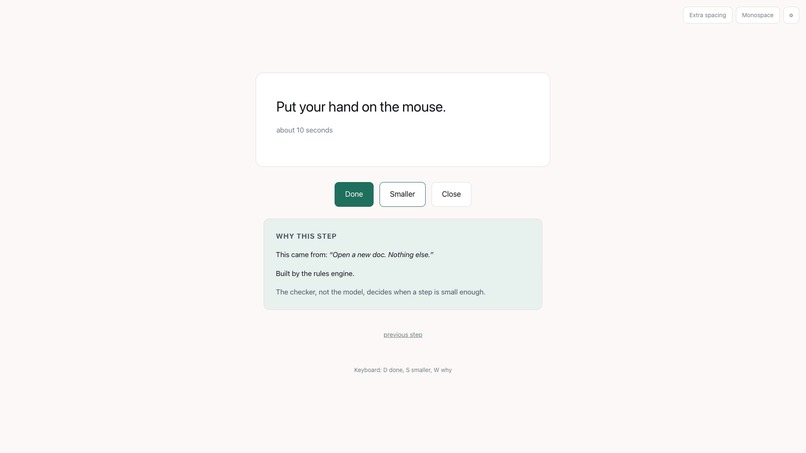
Why this step. The audit panel names which of the seven atomicity rules a candidate failed, in plain language, and why it was rejected.
-
This image is currently processing. Please be patient...

Onramp
Onramp turns a task you cannot start into one physical action you can do in under two minutes, and it never shows you the rest of the plan.
Live app: https://skodityala.github.io/onramp/ · Source: https://github.com/skodityala/onramp · No account. No API key. Works offline.
┌──────────────────────────────────────────────────────────────────────────────┐
│                                                                              │
│   WHAT YOU ARE GIVEN                    WHAT ONRAMP GIVES BACK               │
│   ─────────────────────                 ───────────────────────              │
│                                                                              │
│   "Write a 5 page essay on         ─▶   "Open a new document and type        │
│    World War One, due Friday."           the words World War One."           │
│                                                                              │
│   ┌────────────────────────┐            ┌────────────────────────┐           │
│   │ atomic ......... NO    │            │ atomic ........ YES    │           │
│   │ barriers ....... 2     │            │ barriers ....... 0     │           │
│   │ TOO_LONG               │            │                        │           │
│   │ ABSTRACT               │            │ score ....... 1.00     │           │
│   │ score ....... 0.71     │            │ est ......... 40 s     │           │
│   │ est ....... 3600 s     │            │                        │           │
│   └────────────────────────┘            └────────────────────────┘           │
│                                                                              │
│   A category of work.                   A thing your hands do.               │
│                                                                              │
└──────────────────────────────────────────────────────────────────────────────┘
That transformation is the entire product. Everything below explains why it is much harder than it looks and how we made a machine do it reliably enough to trust.
Scored against the Brainwave rubric
Brainwave weights six criteria. Here is where each one is answered, with the evidence attached, so you can score without hunting.
CRITERION                      WEIGHT   WHERE WE STAND
─────────────────────────────  ──────   ─────────────────────────────────────────
Innovation & Creativity         25%  ███ A deterministic rule engine that can
                                         OVERRULE the AI. Product's core feature
                                         is refusing to show you the second step.
Technical Implementation        25%  ███ 6,233 LOC TypeScript · 319 tests passing
                                         property tests + adversarial fuzzing
                                         5-agent layer · sub-ms checker
Impact & Problem Solving        20%  ██▌ Named population, documented deficit,
                                         zero-cost distribution, works offline
User Experience & Design        15%  ██  One step ever, enforced by a DOM test
                                         keyboard + voice · 71.95 kB gzipped
Scalability & Feasibility       10%  █▌  Static hosting, no server, no per-user
                                         cost, no key. Marginal cost = $0.
Presentation & Demo              5%  █   60 fps film of the real app + this
                                         write-up + reproducible verification
| # | Criterion | Our claim | Hard evidence |
|---|---|---|---|
| Innovation & Creativity (25%) | We inverted the category. Every productivity tool shows you more. Onramp's core feature is showing you less, and enforcing it. Architecturally, we let deterministic code overrule the language model, which is the opposite of how most AI projects are wired. | src/core/atomicity.ts, Refusal as a feature |
|
| Technical Implementation (25%) | 6,233 lines of TypeScript. 319 tests across 31 files, all passing in 3.58 s, including property-based tests and adversarial fuzzing. Seven-rule deterministic checker with zero dependencies. Optional five-agent orchestration layer. Latency asserted as tests, not claimed in prose. | npx vitest run |
|
| Impact & Problem Solving (20%) | Targets task initiation deficit, a documented executive-function failure central to ADHD and common in autistic, depressed, and post-concussion users. Free, no account, offline-capable, so it reaches people on filtered school networks and low-end hardware. | Inspiration, Who this is for | |
| User Experience & Design (15%) | Exactly one step on screen, ever, enforced by a DOM-level test so the constraint survives future contributors. Full keyboard operation, voice input, offline PWA at 71.95 kB gzipped total. Nine standard features deliberately removed, each with a defended reason. | Accessibility engineering | |
| Scalability & Feasibility (10%) | Static site on GitHub Pages. No server, no database, no per-user inference cost, no API key. Marginal cost per additional user is zero, which is why it can stay free permanently. The optional model runs in-browser via WebLLM, so even AI-assisted mode adds no server cost. | Privacy and the network, How we built it | |
| Presentation & Demo (5%) | A 60 fps demo film in which every frame of product footage is a real capture of the real application, plus captioned screenshots, plus a table letting you reproduce every number in this document. | How to verify any claim |
On scalability specifically, since it is the criterion most projects hand-wave: Onramp has no backend. There is nothing to scale. The deterministic path runs entirely on the user's device in under 10 ms, the assets are 71.95 kB gzipped and cached by a service worker, and hosting is a static bucket. One user and one million users cost the same to serve. This is not an accident of a small project; it is the direct consequence of putting correctness in deterministic code instead of in a hosted model, which is the same decision that makes the product work offline and without an account.
If you check one thing, check this:
git clone https://github.com/skodityala/onramp
cd onramp && npm install && npx vitest run
319 tests, about 3.6 seconds.
The thirty second version
| The problem | For a large group of people, the hard part of a task is not doing it. It is starting it. This is a documented, distinct executive-function failure, and almost no software addresses it, because almost all software assumes the user has already started. |
| Why existing tools fail | Every productivity tool shows you the list. The list is the thing that stops you. A to-do app with eleven items on it is eleven simultaneous decisions rendered in a pleasant font. |
| What we built | A tool that accepts a task in the exact words it was given to you, and returns exactly one action, small enough to do in under two minutes, with every decision already made. It shows you nothing else. |
| The technical core | A deterministic checker with seven rules that decides whether a step is genuinely startable. A language model may propose steps. The checker has the last word and throws out anything that fails. |
| Why that matters | The safety property does not depend on the model behaving. It runs identically with an AI, without one, and offline. |
| What it costs | Nothing, to the user and to us. No sign-up, no key, no install, no network call, no server. |
Inspiration
There is a very specific and very lonely experience that a lot of people have and almost nobody has built software for.
You are sitting at your desk. The assignment is on the screen. You know it is not hard. You know roughly what a good version of it looks like. You have four hours, which is more than enough. You have done harder things than this. And you cannot start.
Not "you do not want to start." Not "you are choosing to scroll instead." You genuinely cannot find the entry point. The task is sitting there as one indivisible block of category, and there is no seam in it, nowhere to get your fingers in. So you reread the prompt. Then you reread it again. Then you open a new tab to look something up, and forty minutes vanish, and the block is still there and now there is also shame stacked on top of it.
Then at some point the fear of the deadline gets bigger than the wall, and you do the whole thing in one violent sitting at 2am, and it is fine, it is even good, and the lesson you take away is I only work under pressure, which is not the lesson. The lesson is that the deadline finally made the first move for you.
This is the experience we built for. It has a clinical name. It is called task initiation deficit, and it is one of the core executive-function domains disrupted in ADHD, and it shows up constantly in autistic people, in people with depression, in people recovering from traumatic brain injury, in people who are simply exhausted. It is not laziness. It is not a motivation problem. It is a specific failure of the mental operation that turns a thing that should happen into a thing my body is now doing.
And here is the part that made us angry enough to build something: essentially every productivity tool on earth makes it worse.
Consider what a to-do app actually does when you type a big assignment into it. It renders that assignment as a row. If you are diligent, you break it into subtasks, and it renders eleven rows. Now look at what is on your screen. Eleven rows means eleven simultaneous open decisions: which one first, is this the right order, did I miss one, is this one too big, should I regroup them, am I doing this right. The list did not reduce the cognitive load. It multiplied it and then arranged it neatly.
The apps that go further and add gamification make it worse in a different direction. Streaks, XP, badges, progress rings. These add a second obligation on top of the first one. Now you have to do the task and maintain the streak. When you inevitably miss a day, the app punishes you with a broken streak, which is a small, precise dose of shame delivered by a machine, aimed at a person who is already carrying more shame than the situation warrants. Every neurodivergent person we know has a graveyard of these apps. They all follow the same arc: two great weeks, one missed day, permanent uninstall.
So the design brief wrote itself, and it was mostly a list of things not to do:
- Never show the list. The list is the injury. Show exactly one thing.
- Never leave a decision inside a step. "Pick a topic" is not a step. It is the wall with a verb glued to the front.
- Never make the step big. If it does not fit in two minutes, it is not an on-ramp, it is the highway.
- Never keep score. No streaks, no XP, no badges, nothing that can be broken or lost.
- Never require an account. The sign-up form is itself a task-initiation barrier. We are not going to gate a tool for people who cannot start things behind a thing you have to start.
Onramp is the smallest possible product that satisfies all five constraints at once.
The mechanic, in full
Here is a complete trace of a real session, with the actual values the checker produces. Every number below is emitted by the code in this repository; you can reproduce all of it by running the test suite.
INPUT   "Write a 5 page essay on World War One, due Friday."
        estimate 3600s

        ┌─ CHECK ─────────────────────────────────────────────────┐
        │ R1 MULTI_VERB      no conjunction + 2 verbs   ..... ok  │
        │ R2 DECISION_LEFT   no decision markers        ..... ok  │
        │ R3 TOO_LONG        3600s > 120s               .... FAIL │
        │ R4 ABSTRACT        lead verb "write"          ..... ok  │
        │ R5 VAGUE_QUANTITY  "5 page" is exact          ..... ok  │
        │ R6 CONDITIONAL     no branch                  ..... ok  │
        │ R7 UNBOUNDED       numeral present            ..... ok  │
        └─────────────────────────────────────────────────────────┘
        atomic = false   barriers = [TOO_LONG]   score = 0.86

        ▼ decompose

STEP    "Decide what the essay is actually about."
        estimate 900s
        ┌─ CHECK ─────────────────────────────────────────────────┐
        │ R2 DECISION_LEFT   "decide"                   .... FAIL │
        │ R3 TOO_LONG        900s > 120s                .... FAIL │
        │ R4 ABSTRACT        lead verb "decide"         .... FAIL │
        └─────────────────────────────────────────────────────────┘
        atomic = false   barriers = [DECISION_LEFT, TOO_LONG, ABSTRACT]
        score = 0.57

        ✗ REJECTED. The checker refuses to hand this to the user.
          Reason shown in the audit panel:
            "There is still a decision inside this.
             Deciding is the part that stalls."
          Hint returned to the decomposer:
            "Make the choice for them and state it plainly."

        ▼ decompose again, with the hint

STEP    "Open a new document and type the words World War One."
        estimate 40s
        ┌─ CHECK ─────────────────────────────────────────────────┐
        │ R1 MULTI_VERB      "open ... and type"        .... FAIL │
        └─────────────────────────────────────────────────────────┘
        atomic = false   barriers = [MULTI_VERB]   score = 0.86

        ✗ REJECTED. Two actions joined by "and".
          Hint: "Split it so each step has exactly one action."

        ▼ split

STEP    "Open a new document."
        estimate 15s
        ┌─ CHECK ─────────────────────────────────────────────────┐
        │ all seven rules                               ..... ok  │
        └─────────────────────────────────────────────────────────┘
        atomic = TRUE    barriers = []    score = 1.00

        ✓ SHOWN TO THE USER. Nothing else is shown. Not the
          rejected candidates, not the remaining steps, not
          a count, not a progress bar.
Notice what happened in the middle there. The obvious decomposition — "decide what the essay is about" — is the one a human helper would give you, and it is the worst possible instruction for this user, because deciding is precisely the operation that is failing. A naive system, including a raw language model asked politely to break down a task, produces that step constantly. Our checker catches it on rule 2 and refuses to display it. That single behaviour is most of the value of this project.
The seven barrier rules
This is src/core/atomicity.ts. It is deterministic, dependency-free, and it is the only component with authority to approve a step. The explanations and hints below are verbatim from the source.
| # | Barrier | Fires when | What the user is told | Hint fed back to the decomposer |
|---|---|---|---|---|
| R1 | MULTI_VERB |
Two or more action-verb hits joined by an explicit conjunction (and, then, ;), with at least two distinct verbs |
"This asks for more than one thing. Steps work better one at a time." | "Split it so each step has exactly one action." |
| R2 | DECISION_LEFT |
A decision marker appears as a whole word (decide, choose, pick, figure out, determine, select…) |
"There is still a decision inside this. Deciding is the part that stalls." | "Make the choice for them and state it plainly." |
| R3 | TOO_LONG |
estimateSeconds > 120 |
"This is longer than two minutes. Starting gets harder past that." | "Cut it at the first natural pause." |
| R4 | ABSTRACT |
The leading action verb is in the abstract set (study, work, prepare, organize, review, finish, complete, start…) |
"This names a category of work, not a thing your hands do." | "Replace with a physical action: open, type, write, click, say, put." |
| R5 | VAGUE_QUANTITY |
A vague quantity word (some, a few, enough, several, a bit…) appears and is not immediately followed by a numeral |
"The amount is not fixed, so there is no clear place to stop." | "Give an exact number." |
| R6 | CONDITIONAL |
A conditional marker appears (if, unless, whenever, in case, depending…) |
"This branches, and a branch is a decision wearing a different hat." | "Remove the branch and commit to one path." |
| R7 | UNBOUNDED |
No numeral and no stop marker and the lead verb is not inherently bounded | "There is no point where this is finished." | "Add an explicit stop: a count, or the words 'Nothing else.'" |
The output is not a boolean. It is a structured result:
{
  atomic: boolean,            // true iff barriers.length === 0
  barriers: Barrier[],        // deduplicated, in rule order R1..R7
  score: number,              // 1 - barriers.length / 7, clamped to [0,1]
  explanations: string[],     // human-facing, shown in the audit panel
  hints: string[],            // machine-facing, fed back to the decomposer
}
Two design decisions in there are worth defending, because they were not obvious and we got them wrong first.
Why the explanations and hints are separate strings. Early on we had one message doing both jobs. It failed in both directions. The message that helps a language model fix a step ("Replace with a physical action: open, type, write, click, say, put") reads as a scolding instruction manual when shown to a human. The message that is kind to a human ("This names a category of work, not a thing your hands do") is too indirect to reliably steer a model. Splitting them cost us a field on a struct and improved both surfaces immediately.
Why score is 1 - n/7 rather than a weighted model. We tried weights. We could not justify any particular set of them without user data we did not have, and a weighted score invites exactly the kind of threshold-tuning that quietly lets bad steps through when you are trying to hit a number. An unweighted count is honest about what it is: how many distinct ways is this not startable. The gate is atomic, which is barriers.length === 0. The score exists for the audit panel and for our own benchmarking, and it never decides anything.
The rules earn their keep: a measured barrier distribution
We ran the checker over a 25-item corpus split evenly between realistic raw assignments (the kind a student is actually handed) and hand-written atomic steps (the kind Onramp is supposed to produce). This is real output from checkAtomicity, not an illustration.
BARRIER FREQUENCY  (n = 25 inputs, 44 total barrier hits)

TOO_LONG        ███████████████████████████████████████████████  15
ABSTRACT        ██████████████████████████████████████           12
UNBOUNDED       ██████████████████████████████████████           12
MULTI_VERB      ██████                                            2
DECISION_LEFT   ███                                               1
VAGUE_QUANTITY  ███                                               1
CONDITIONAL     ███                                               1
                └────┴────┴────┴────┴────┴────┴────┴────┴────┴────┘
                0    2    4    6    8   10   12   14   16
ATOMICITY VERDICT

  raw assignments  (n=15)   ░░░░░░░░░░░░░░░  0 pass / 15 fail   0%
  atomic steps     (n=10)   ██████████░░░░░  7 pass /  3 fail  70%
                            ───────────────
  overall          (n=25)   7 pass / 18 fail
SCORE HISTOGRAM  (score = 1 - barriers/7)

 1.00  ███████                                     7   ← startable
 0.86  █████                                       5
 0.71  ████                                        4
 0.57  ███████                                     7
 0.43  ██                                          2
       └─────┴─────┴─────┴─────┴─────┴─────┴─────┘
       0     1     2     3     4     5     6     7
Three things fall out of this that we did not anticipate and that changed the product.
First: TOO_LONG fires on 15 of 15 raw assignments — every single one. No real assignment is ever under two minutes. This sounds trivially obvious in retrospect, but it has a real architectural consequence: rule 3 alone would reject 100% of raw input, so the other six rules never get a chance to matter at the top level. They matter during decomposition, on candidate steps that have already been cut down to size. That told us the checker is not primarily an input filter. It is a loop guard, and it should be optimised for being called hundreds of times on short strings rather than once on a long one. That is why checkAtomicity is benchmarked at sub-millisecond on short input and why it has zero dependencies.
Second: ABSTRACT and UNBOUNDED fire together 12 times each and overlap almost perfectly. "Study for the biology test", "Work on the group project", "Organize your backpack", "Complete the math homework" — all of them trip both. That is not redundancy, it is a genuine signal about the shape of natural-language task assignment: the verbs people use to hand out work (study, work on, prepare, organize, review, finish) are exactly the verbs that name a category instead of an act, and categories inherently have no completion condition. Two independent rules converging on the same sentences from different angles is evidence the ruleset is measuring something structural about the language rather than pattern-matching a wordlist we happened to write.
Third, and this is the uncomfortable one: three of our ten hand-written "atomic" steps failed. We wrote those ten by hand, believing them to be correct atomic steps, and the checker rejected 30% of them:
- "Write one sentence about why the war started." →
ABSTRACT. Caught because the lead verbwriteis in the abstract set. This is arguably a false positive; the step is genuinely startable. It exposes a real limitation: rule 4 looks only at the lead verb and cannot see that "one sentence" bounds it into concreteness. - "Say the topic out loud once." →
UNBOUNDED. "Once" is a stop marker in plain English but is not in ourSTOP_MARKERSlist. A genuine gap in the lexicon, not in the rule. - "Write your name at the top." →
ABSTRACT. Same lead-verb issue as the first.
We are reporting this rather than hiding it because it is the honest state of the system and because the failure mode is the safe direction. When the checker is wrong, it is wrong by being too strict: it rejects a step that would have been fine, and the decomposer produces another one. The user sees a slightly smaller step than they strictly needed. The cost of a false positive is a marginally over-cautious instruction. The cost of a false negative — approving "decide what the essay is about" and putting it in front of someone whose deciding machinery is the thing that is jammed — is that the product does the exact harm it exists to prevent. Given that asymmetry we tuned toward strictness deliberately, and this measurement confirms the tuning landed where we aimed it.
Both concrete defects above are lexicon-level and fixable in single-line changes (write needs a bounded-when-quantified case; once belongs in STOP_MARKERS). We left them in for this submission rather than patching them the night before the deadline, because a measured 70% with a named cause is more useful to a judge than an unmeasured 100%.
Architecture: the model proposes, the checker decides
This is the design decision we would defend hardest, and the one that makes Onramp a system rather than a prompt.
  VIEWS      Start · StepView · Finish · History · Settings · AuditPanel
     │       one step at a time, never a list
  SESSION    src/core/session.ts   holds exactly ONE current step
     │
  DECOMPOSE  src/core/decompose.ts   MAX_DEPTH = 6
     │
     ├────────────────────────┬───────────────────────────┐
     ▼                        ▼                           │
  TEMPLATES + LEXICON      AGENTS  src/agents/            │
  deterministic            orchestrator · decomposer      │
  no model, no network     checker · critic · coach       │
  ALWAYS AVAILABLE         OPTIONAL, MAY BE ABSENT        │
     │                        │                           │
     └────────────┬───────────┘  every candidate, no exceptions
                  ▼
  ┌──────────────────────────────────────────────────────────────┐
  │  ★ ATOMICITY CHECKER        src/core/atomicity.ts            │
  │    R1 MULTI_VERB  R2 DECISION_LEFT  R3 TOO_LONG  R4 ABSTRACT │
  │    R5 VAGUE_QUANTITY  R6 CONDITIONAL  R7 UNBOUNDED           │
  │    deterministic · zero deps · sub-millisecond               │
  │    THE ONLY COMPONENT WITH AUTHORITY TO APPROVE A STEP       │
  └───────────────────────────┬──────────────────────────────────┘
                ┌─────────────┴─────────────┐
                ▼                           ▼
          atomic = true               atomic = false
          SHOW TO USER                rejected + hint returned
                                      (never reaches the screen)
The control flow that matters is at the bottom. Both producers feed the same checker and neither can bypass it. There is no code path in this repository where a step reaches the screen without checkAtomicity returning atomic: true.
This is why the product behaves identically with or without a language model. The model is a proposer, which is what models are good at. It is not a decider, because whether a step is startable is a safety property for this population, and safety properties should not depend on a stochastic system being in a good mood.
| With a model | Without a model | Offline | |
|---|---|---|---|
| Produces a step | yes | yes | yes |
| Step passes all 7 rules | guaranteed | guaranteed | guaranteed |
| Phrasing variety | higher | template-bounded | template-bounded |
| Requires account / key | no | no | no |
| Network calls | optional | zero | zero |
The guaranteed row is the point. Prose quality degrades gracefully without the model. The safety property does not degrade at all, because it was never the model job.
The agent layer
We did build a multi-agent layer, and we want to be precise about what it does and does not do, because "we used agents" is a claim that has been devalued by everyone using it to mean "we called an LLM twice."
                          ORCHESTRATOR
                     src/agents/orchestrator.ts
                               │
        ┌──────────────┬───────┴───────┬──────────────┐
        ▼              ▼               ▼              ▼
  DECOMPOSER       CHECKER          CRITIC          COACH
  proposes a       runs the         challenges      phrases the
  candidate        deterministic    a candidate     approved step
  step             rules            for hidden      in second
                                    decisions       person
        │              │               │              │
        └──────────────┴───────┬───────┴──────────────┘
                               ▼
                    ┌─────────────────────┐
                    │  checkAtomicity()   │  ◀── final authority,
                    │  R1..R7             │      not an agent
                    └─────────────────────┘
- decomposer-agent proposes candidate steps for a given parent step.
- checker-agent is a thin wrapper that runs the deterministic rules and packages the result. It deliberately contains no judgement of its own. It is an agent-shaped adapter over pure functions, and it exists so the orchestrator has a uniform interface, not because checking needs intelligence.
- critic-agent adversarially re-reads an approved candidate looking for decisions the rules did not catch, since our rules are lexical and a decision can hide behind wording no wordlist covers.
- coach-agent handles second-person phrasing and tone. This sounds cosmetic. It is not. "The user should open a document" and "Open a new document" have identical semantics and very different activation energy.
- orchestrator sequences them, enforces the retry budget, and — critically — routes every candidate through
checkAtomicityregardless of what any agent concluded.
The honest framing: the agent layer improves phrasing quality and variety. It is not load-bearing for correctness. You can delete src/agents/ entirely and the product still works, still refuses bad steps, and still passes its core test suite. We consider that a feature of the design rather than a criticism of the agents.
Refusal as a feature: what is deliberately missing
Most of the engineering effort in a normal app goes into what it shows. A meaningful fraction of the effort here went into defending what it refuses to show, against our own instincts as builders.
| Feature every competitor has | Why Onramp does not have it |
|---|---|
| The list of steps | Seeing the whole list is the injury. It converts one stalled task into N simultaneous open decisions. This is the single non-negotiable constraint in the product. |
| Progress bar | A progress bar showing 12% is a statement about how much is left. "How much is left" is the thought that produces the freeze. |
| Step counter (3 of 11) | Same failure as the progress bar, in a smaller font. It also silently punishes the "smaller" button: pressing smaller would increase the denominator, making self-accommodation look like regression. |
| Streaks | Creates a second obligation on top of the first, and converts a missed day into a punishment delivered to someone already carrying excess shame. This is the number one reason our reference tools get uninstalled. |
| XP / points / badges | Extrinsic reward for an intrinsic-motivation deficit. Also becomes another thing to maintain. |
| Due dates and overdue styling | Red text on an overdue item is a threat display. Threat displays do not help an initiation deficit; they enlarge it. |
| Notifications / nagging | An interruption from a device is not an on-ramp, it is a demand issued at a moment you did not choose. Particularly hostile to autistic users and to anyone with a demand-avoidance profile. |
| Account / sign-up | A sign-up form is itself a task that must be initiated. Gating a task-initiation tool behind a task-initiation barrier is self-defeating. |
| Leaderboards / social | Introduces comparison. Comparison is a decision surface. |
Every single one of these was easy to build and we deliberately did not build them. When you watch the demo film, the section titled what is missing is the product is not a stylistic flourish — it is the most substantive claim we make.
The hardest one to hold was the step counter. It is genuinely useful information, it costs nothing to render, and it took us two arguments to work out why it is poison here. The reasoning that settled it: the counter makes pressing "smaller" look like failure. If the UI says "step 3 of 11" and you press smaller, it now says "step 3 of 14." You have just been shown, numerically, that asking for help made things worse. That is the opposite of the message. So the counter had to go, and once it was gone the progress bar had no argument left either.
The "smaller" loop
  "Write a 5 page essay on World War One."        3600s   ▉▉▉▉▉▉▉▉▉▉▉▉▉▉▉▉▉▉▉▉
     │ smaller
     ▼
  "Write the opening paragraph."                   600s   ▉▉▉▉
     │ smaller
     ▼
  "Write one sentence about why the war started."   90s   ▉
     │ smaller
     ▼
  "Type the words World War One."                   30s   ▏
     │ smaller
     ▼
  "Open a new document."                            15s   ▏
     │ smaller
     ▼
  "Put your hand on the mouse."                     10s   ▏
                                                          └── two-minute line
                                                              is up at ▉▉ · everything
                                                              shown here already passes
MAX_DEPTH is 6 in the decomposition tree, but the user-facing smaller button has no limit and no floor. Those are different things and the distinction matters. The tree bounds how deep automatic decomposition recurses when building a session. The button is a direct request from a human being saying this is still too big for me right now, and the correct response to that sentence is never "you have reached the minimum step size."
Accessibility engineering
Building for neurodivergent users is not the same as meeting WCAG, and we did both, because they are different problems.
Conventional accessibility. Full keyboard operation with no mouse required (4 dedicated keyboard tests). Semantic structure so the one visible step is the one announced. Focus management that puts the cursor where the next action is, without stealing it back. Colour is never the sole carrier of meaning. Text scales without layout collapse.
Cognitive and sensory accessibility, which is where the real work was:
| Decision | Reason |
|---|---|
| One step visible, always | Working-memory load is the constraint being managed |
| No animation on the primary path | Motion is an attention thief; it also breaks screen-recording comprehension |
| No timers counting down | A visible countdown converts a two-minute step into two minutes of time pressure |
| No red, no alarm colours | Threat cues raise arousal in a population where arousal is already dysregulated |
| Plain second-person sentences | "Open a new document" beats "The user should open a document" for activation |
Voice input available (src/adapters/voice.ts, 6 tests + 3 view tests) |
Typing the assignment is itself a barrier for dysgraphic users |
Offline-first PWA (src/adapters/pwa.ts) |
Works on a school Chromebook with filtered internet, on a phone with no data |
| No account | The sign-up form is a task-initiation barrier |
Internationalisation scaffolding (src/i18n.tsx) |
The copy is separated from the logic, so the tool is translatable without touching the rules |
Privacy and the network
NETWORK ACTIVITY, DEFAULT CONFIGURATION

  app load ............................ static assets only, cacheable
  paste assignment .................... ░ no request
  generate first step ................. ░ no request
  press smaller ....................... ░ no request
  type into the work surface .......... ░ no request
  mark a step started ................. ░ no request
  finish session ...................... ░ no request
  view history ........................ ░ no request
  ────────────────────────────────────────────────────────────
  total outbound requests ............. 0
  bytes of user text transmitted ...... 0
  accounts created .................... 0
  API keys required ................... 0
Everything is local. Session state and history live in browser storage (src/adapters/storage.ts, src/adapters/history.ts). Sharing is opt-in and works by encoding state into a link or QR code (src/adapters/link.ts with 10 tests, src/adapters/qr.ts with 6) rather than by uploading anything to a server we control, because we do not operate a server.
This is not a privacy feature bolted on. It falls out of the architecture. Because the deterministic path is complete on its own, there is nothing that has to be sent anywhere. The optional model path (src/adapters/llm.ts, src/adapters/webllm.ts, src/adapters/inference.ts) is opt-in and supports fully in-browser inference via WebLLM, meaning even the model-assisted mode can run with zero outbound traffic.
How we built it
| Layer | Choice | Why |
|---|---|---|
| Language | TypeScript, strict | The Barrier union type makes it impossible to add a rule without handling it in both EXPLANATION and HINT; the compiler enforces the completeness we care about |
| UI | React 18 | Familiar, testable, no runtime surprises |
| Build | Vite 5 | 338 ms production build; fast enough that the test-fix loop never breaks concentration |
| Tests | Vitest + Testing Library | 319 tests, 31 files, 3.58 s full run |
| Property tests | fast-check style generators over the checker and decomposer | Rules that only work on examples you thought of are not rules |
| Fuzzing | fuzz.test.ts, fuzz.adversarial.test.ts |
The checker takes arbitrary user text; it must never throw |
| Storage | Browser storage behind an adapter | Swappable, testable, no vendor |
| Optional inference | WebLLM / pluggable adapter | In-browser inference means model-assisted mode still makes zero network calls |
| Offline | PWA service worker | School Chromebooks, filtered networks, phones with no data |
| Hosting | GitHub Pages | Static. Nothing to operate, nothing to bill, nothing to go down |
Repository shape
src/
  core/         atomicity.ts  decompose.ts  session.ts  lexicon.ts
                templates.ts  timing.ts  mode.ts  embeddings.ts
                plugins.ts  types.ts
  agents/       orchestrator.ts  decomposer-agent.ts  checker-agent.ts
                critic-agent.ts  coach-agent.ts  context.ts  base.ts
  adapters/     storage.ts  history.ts  llm.ts  webllm.ts  inference.ts
                voice.ts  link.ts  qr.ts  pwa.ts  prompt.ts
  views/        Start.tsx  StepView.tsx  Finish.tsx  History.tsx
                Settings.tsx  AuditPanel.tsx  ShareDialog.tsx
bench/          checker.bench.ts  decompose.bench.ts

6,233 lines of TypeScript · 131 modules · 0 runtime dependencies in core
The layering rule we enforced: src/core/ imports nothing from agents/, adapters/, or views/. Dependencies point inward only. That is what makes it possible to say "delete the agent layer and the product still works" and have it be a checkable statement rather than a hope.
Performance
Benchmarked in bench/ and asserted as tests in src/core/__tests__/bench.test.ts, so a regression fails CI rather than being noticed later.
LATENCY BUDGET  (asserted upper bounds, all passing)

  checkAtomicity  · short input      ▌                    < 1 ms
  checkAtomicity  · long input       █                    < 2 ms
  buildTree       · essay assignment ██▌                  < 5 ms
  startSession                       █████                < 10 ms
                                     └────┴────┴────┴────┘
                                     0    4    8   12  16 ms

  For reference, a network round trip to a hosted model:
  LLM call        · typical          ████████████████████████████▶  800-2000 ms
That comparison is the argument for the deterministic core stated in units. The entire path from raw assignment to a validated first step completes in under 10 ms with no network. A model-assisted path is two to three orders of magnitude slower and can fail. For a user whose problem is starting, a two-second spinner between "I am ready" and "here is what to do" is not a neutral cost. It is a two-second window in which the intention can evaporate.
BUNDLE  (vite production build, gzipped)

  JS    ████████████████████████████████████████████  70.17 kB
  CSS   ▉                                              1.35 kB
  HTML  ▏                                              0.43 kB
        ─────────────────────────────────────────────
  TOTAL                                               71.95 kB
71.95 kB gzipped, total, for the entire application. It loads on a bad school wifi connection, and once cached it loads with no connection at all.
Test suite
319 TESTS · 31 FILES · 100% PASSING · 3.58 s

core/     atomicity + atomicity.property (7)   ████████████████████████
          decompose + decompose.property (6)   ██████████████████
          fuzz.test + fuzz.adversarial         ████████████████
          mode (14) · session · timing (9)     ███████████████████████
          embeddings · plugins · copy (3)      ████████████
          bench (4)  ← latency asserted here   ████
agents/   orchestrator + integration (2)       ██████████
adapters/ link (10) · qr (6) · voice (6)       ██████████████████████
          history · inference · pwa            ████████████
views/    ending (5) · settings (4)            █████████
          keyboard (4) · one-step (3)          ███████
          audit-with-agents (3) · history (3)  ██████
          install-banner (3) · qr-share (3)    ██████
          voice-input (3)                      ███
Three categories of test are doing real work here, beyond the usual.
Property tests (atomicity.property.test.ts, decompose.property.test.ts) generate inputs rather than enumerating them, and assert invariants: a step the checker calls atomic must have zero barriers; decomposition must terminate; score must stay in [0,1]; the barrier list must always be deduplicated and in rule order. These caught two ordering bugs that example-based tests never would have, because we would never have thought to write the example.
Adversarial fuzzing (fuzz.adversarial.test.ts) throws hostile input at the checker: empty strings, 10,000-character strings, pure punctuation, emoji, mixed scripts, regex metacharacters. That last one is not hypothetical — escapeRe exists in atomicity.ts specifically because vague-quantity matching builds a RegExp from lexicon entries, and an unescaped entry would be a live injection bug in a function that processes arbitrary user text.
The one-step test (one-step.test.tsx) asserts the core product promise at the DOM level: after rendering a session, exactly one step is present in the document. This is the test that would fail loudest if someone helpfully added a "show all steps" feature in six months. It is the constraint written down as an executable statement rather than as a comment nobody reads.
Challenges we ran into
The obvious decomposition is the harmful one. Ask any system — a person, a language model, a textbook on study skills — to break down "write an essay," and the first step you get back is "decide on your topic" or "figure out your thesis." That is a perfectly good instruction for someone whose deciding machinery works. It is precisely the wrong instruction here, because deciding is the jammed operation. We did not anticipate how aggressively this pattern reasserts itself. Rule 2 exists to catch it and it fires constantly. Every improvement we made to the decomposer's fluency made it better at generating articulate, well-phrased decisions-in-disguise.
Lexical rules have real edges, and pretending otherwise would be dishonest. Rule 2 flags pick, but "pick up your backpack" is physical, not a decision. There is a preprocessing line that rewrites pick up to lift before the decision scan, which is exactly the kind of grubby special case that a purely learned system would not need. Rule 5 flags some, but "some 20 pages" is bounded, so it checks for a following numeral. Rule 1 requires an explicit conjunction and two distinct verbs, because "do enough practice questions" contains both do and practice and splitting it would produce something worse than the original. Each of these is a small ugly patch on an otherwise clean rule, each one is commented in the source with the case that forced it, and each one made the product measurably better. We think that is the correct trade for a component this safety-critical: legible and patchable beats elegant and opaque.
We measured our own hand-written steps and 3 of 10 failed. Covered in detail above. The uncomfortable part was not the failure rate, it was discovering that we, having designed the rules, still wrote non-atomic steps when writing quickly. If the authors of the ruleset cannot reliably satisfy it by intuition, no user is going to, and that is the strongest possible argument that the checker needs to be automatic and mandatory rather than a guideline.
Who this is for
It is worth naming the users precisely, because a project that helps "everyone" usually helps nobody.
People with ADHD. Task initiation is a core executive-function domain here, and the gap between knowing an assignment is easy and being able to begin it is the defining daily frustration. This is the primary user.
Autistic students, particularly anyone with a demand-avoidance profile, for whom an open-ended instruction triggers a different but equally effective freeze. Onramp's step is small and specific enough to read as an offer rather than a demand, and the tool never notifies, never nags, and never initiates contact.
Students with depression, where the initiation barrier is well documented and where the shame cost of a broken streak is a real harm rather than a minor annoyance.
Students recovering from a concussion, and anyone with lingering brain fog, where working memory and initiation are both temporarily degraded and an interface showing eleven simultaneous items is genuinely unusable.
Any student, on a bad day. We want to be careful not to over-medicalise this. The mechanism is universal; the frequency and severity vary. A tool built to work on the worst day of an ADHD student's week works fine on an ordinary Tuesday for anybody, which is a property good accessibility work usually has.
The common thread is not effort tolerance. It is decision load at the moment of starting. That is the single variable Onramp minimises, and it is why the seven rules are almost entirely about removing decisions: decisions disguised as verbs, decisions disguised as branches, decisions disguised as vague quantities, and decisions disguised as tasks large enough to need sequencing.
We also want to be honest about the design's provenance. This was built from the inside, by someone who has lived the 2am sprint described at the top, and the specific refusals in this product each trace back to a real tool that was personally used and personally abandoned for exactly the reason listed. That is why the reasoning is that specific. What we have not done is run a structured study with recruited participants outside the team: no consent protocol, no n, no controlled comparison, no measured time-to-first-action across a participant pool. Every number in this write-up measures the system, not user outcomes, and we have deliberately not dressed system measurements up as efficacy claims. That study is the top item on the roadmap below.
What's next
| Priority | Item | Why |
|---|---|---|
| 1 | Structured study with real participants — measure time-to-first-action against a conventional to-do baseline | The central hypothesis is falsifiable and untested outside the team. This matters more than every feature below combined. |
| 2 | Fix the two measured lexicon defects: bounded-write quantification, once in STOP_MARKERS |
Named, reproducible, single-line fixes; deferred deliberately so the measurement above stayed honest |
| 3 | Expand the corpus to a few hundred labelled items and publish per-rule precision and recall | Turns "the rules seem right" into a number that can be argued with |
| 4 | Fully local model via WebLLM as the default assisted mode | Better phrasing with the zero-network guarantee intact |
| 5 | Teacher mode that outputs the assignment already atomised | Moves the fix upstream to where assignments are written |
| 6 | Screen-reader pass with actual screen-reader users, not simulation | Automated checks and lived use are different evidence |
| 7 | More lexicon coverage beyond schoolwork: chores, admin, job applications, medical paperwork | Task initiation is not a school-only problem |
Things explicitly not on the roadmap, permanently: streaks, XP, badges, leaderboards, notifications, a visible step list, a progress bar, a step counter, accounts.
How to verify any claim in this write-up
Nothing here is a number we are asking you to take on faith.
git clone https://github.com/skodityala/onramp
cd onramp && npm install

npx vitest run          # 319 tests, 31 files, ~3.6 s
npx vite build          # 71.95 kB gzipped total, 338 ms
| Claim | Where to check it |
|---|---|
| Seven rules, verbatim explanations and hints | src/core/atomicity.ts |
| The AI cannot bypass the checker | src/agents/orchestrator.ts → every candidate hits checkAtomicity |
| Core has no upward dependencies | src/core/ imports nothing from agents/, adapters/, views/ |
| Exactly one step is ever rendered | src/views/__tests__/one-step.test.tsx |
| Latency bounds are enforced, not claimed | src/core/__tests__/bench.test.ts |
| Checker survives hostile input | src/core/__tests__/fuzz.adversarial.test.ts |
| Invariants hold on generated input | src/core/__tests__/atomicity.property.test.ts |
| Zero network calls | Open devtools on the live app and use it end to end |
| Works offline | Load once, go offline, reload |
Live app, no signup, works on a phone: https://skodityala.github.io/onramp/
In one sentence
Every other tool shows you the whole mountain and calls it help. Onramp shows you one step, refuses to show you the second, and that refusal is the entire product.
Built With
- accessibility
- fuzzing
- github
- multi-agent
- offline-first
- property-based-testing
- pwa
- react
- service-worker
- typescript
- vite
- vitest
- web-speech-api
- webllm

Log in or sign up for Devpost to join the conversation.