-
-
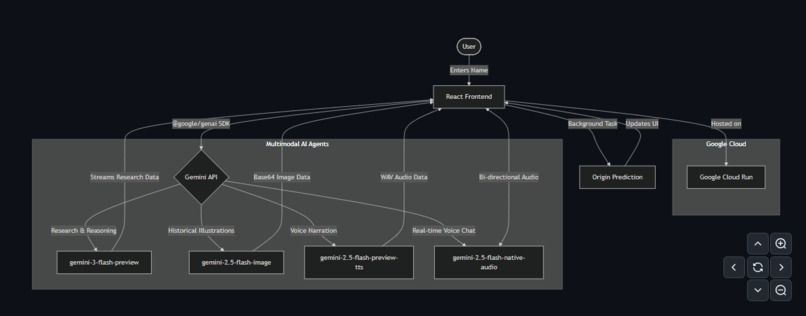
Architecture diagram (Github)
💡 Inspiration
I have always been fascinated by the sheer variety and diversity of human names. Every name is a window into a specific time, place, and culture. I wanted to create a tool that doesn't just give you a definition, but takes you on an immersive journey through the history of your own identity. The core question was simple: "You have a name. Why not find out its origin?"
📖 What it does
Onomastica Research Lab is a multimodal AI agent that acts as a professional onomastician (name historian). When a user enters a name, the agent performs deep archival research, weaving together:
- Linguistic Analysis: Streaming etymological roots in real-time.
- Visual Storytelling: Generating context-aware historical illustrations (antique maps, ledger pages).
- Professional Narration: Providing an academic audio guide through the findings.
- Live Consultation: A real-time voice assistant that allows you to ask follow-up questions about your lineage.
🛠️ How I built it
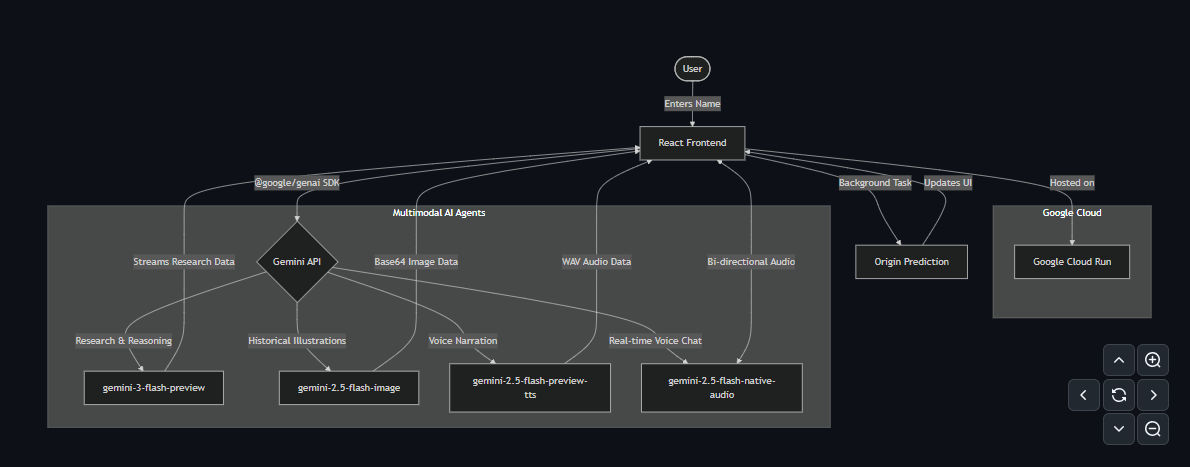
The project started with "vibe coding"—literally programming in English within Google AI Studio. I spent the early stages prototyping the research protocols and multimodal flows to ensure the agent felt like a real historian. Once the prototype was solid, I moved to a full-stack React and Express architecture, leveraging the @google/genai SDK to connect to Gemini's multimodal suite. The entire application is containerized and deployed on Google Cloud Run.
🚧 Challenges I ran into
Navigating the Google Cloud Platform was a steep learning curve. Managing projects, service accounts, and API keys felt like a maze at first. I also hit several quota limits during the prototyping phase, which forced me to optimize my prompts and streaming logic.
Perhaps the most significant challenge was a "hard reset" early in development: I lost a significant portion of my codebase due to an AI error. This taught me the painful but vital lesson of rigorous version control and Git management—a mistake I won't make again!
🏅 Accomplishments that I'm proud of
I am incredibly proud of the interleaved media stream. Getting the images, text, and audio to trigger and render in a way that feels like a cohesive "documentary" was a major technical hurdle. I’m also proud of the Live Assistant, which brings a human touch to what could otherwise be a static data search.
📚 What I learned
I went from knowing very little about cloud infrastructure to successfully deploying a production-ready application on Cloud Run. I learned the basics of the Google Cloud Console, the intricacies of real-time audio processing with the Web Audio API, and most importantly, how to orchestrate multiple AI models (Flash, Image, and TTS) into a single, seamless user experience.
🔮 What's next for Onomastica
The next step is to give the Live Assistant "Vision" capabilities, allowing it to "see" the specific historical documents it generates so it can discuss visual details with the user. I also plan to integrate deeper genealogical APIs to connect these etymological insights with real-world family tree data.


Log in or sign up for Devpost to join the conversation.