-
-
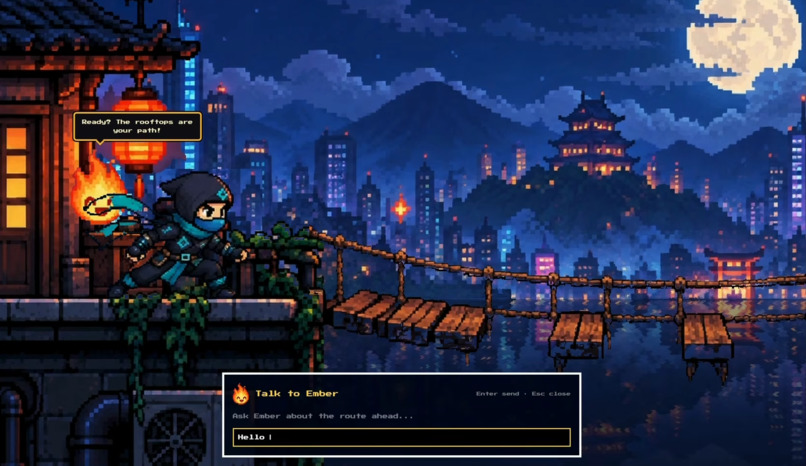
Playing the game and chatting with ember
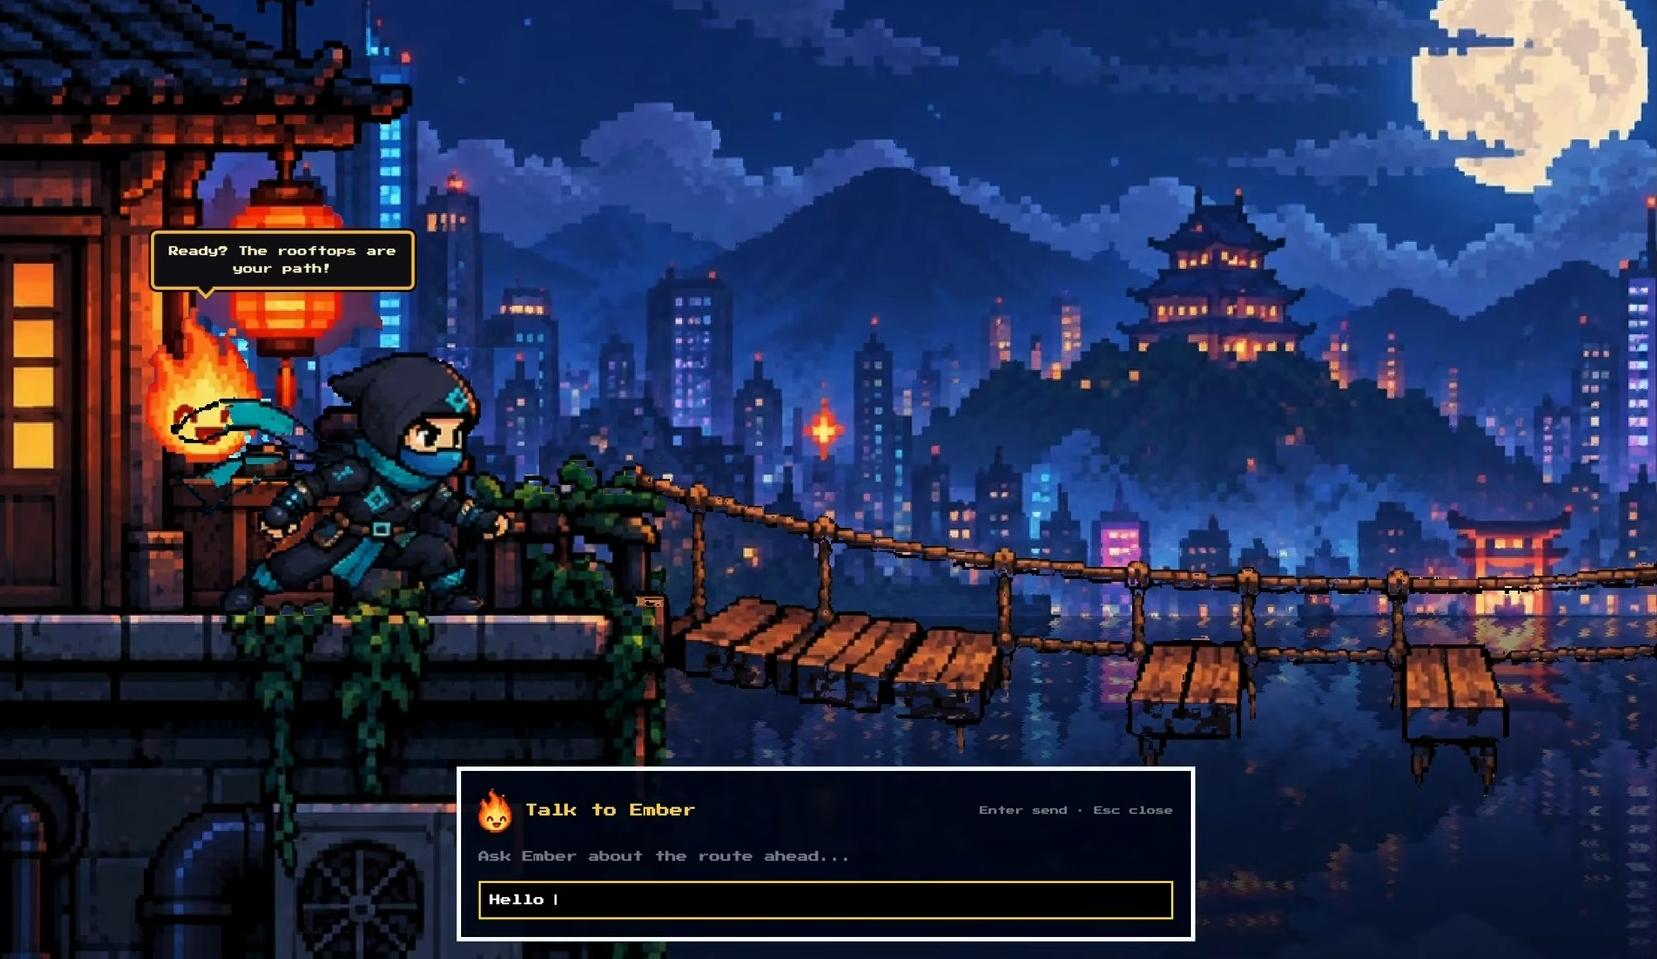
Inspiration
Building complex AI workflows often involves fighting latency and juggling fragmented cloud infrastructure. We created Ninjaverse to streamline high-performance AI deployment, leveraging powerful GPU acceleration to deliver real-time, low-latency intelligent workflows in a unified platform.
What it does
Ninjaverse is an AI-powered platform designed to automate, optimize, and scale complex computational tasks. By combining high-speed cloud infrastructure with optimized model execution, it enables users to run real-time cloud and local AI agents and high-throughput workflows seamlessly.
How we built it
- Cloud & Compute: Built and deployed using Nebius cloud infrastructure and NVIDIA GPU acceleration.
- Backend: Python and FastAPI handling high-concurrency API requests and model orchestration.
- Frontend: Modern, reactive web dashboard for real-time visual feedback and workflow management.
- Code Repository: Managed and version-controlled via GitHub (Priyatham-sai-chand/NinjaVerse).
Challenges we ran into
- Optimizing model loading times and memory usage across parallel GPU execution pipelines.
- Balancing real-time streaming response rates with minimal latency across cloud nodes.
- Seamlessly integrating containerized environments with high-performance compute clusters.
Accomplishments that we're proud of
- Achieved ultra-low latency real-time execution using NVIDIA acceleration.
- Built a clean, intuitive end-to-end user workflow from complex AI backend architectures.
- Successfully deployed and scaled the application on Nebius infrastructure within the hackathon timeline.
What we learned
- Best practices for configuring high-performance GPU instances on Nebius.
- Strategies for minimizing cold starts and latency bottlenecks in real-time AI pipelines.
- Techniques for effective GPU memory allocation during simultaneous multi-agent execution.
What's next for Ninjaverse
- Expanding multi-agent orchestration capabilities for complex, multi-step tasks.
- Integrating advanced observability tools to monitor real-time GPU performance and token usage.
- Opening up custom template support for developers to plug in their own custom models.


Log in or sign up for Devpost to join the conversation.