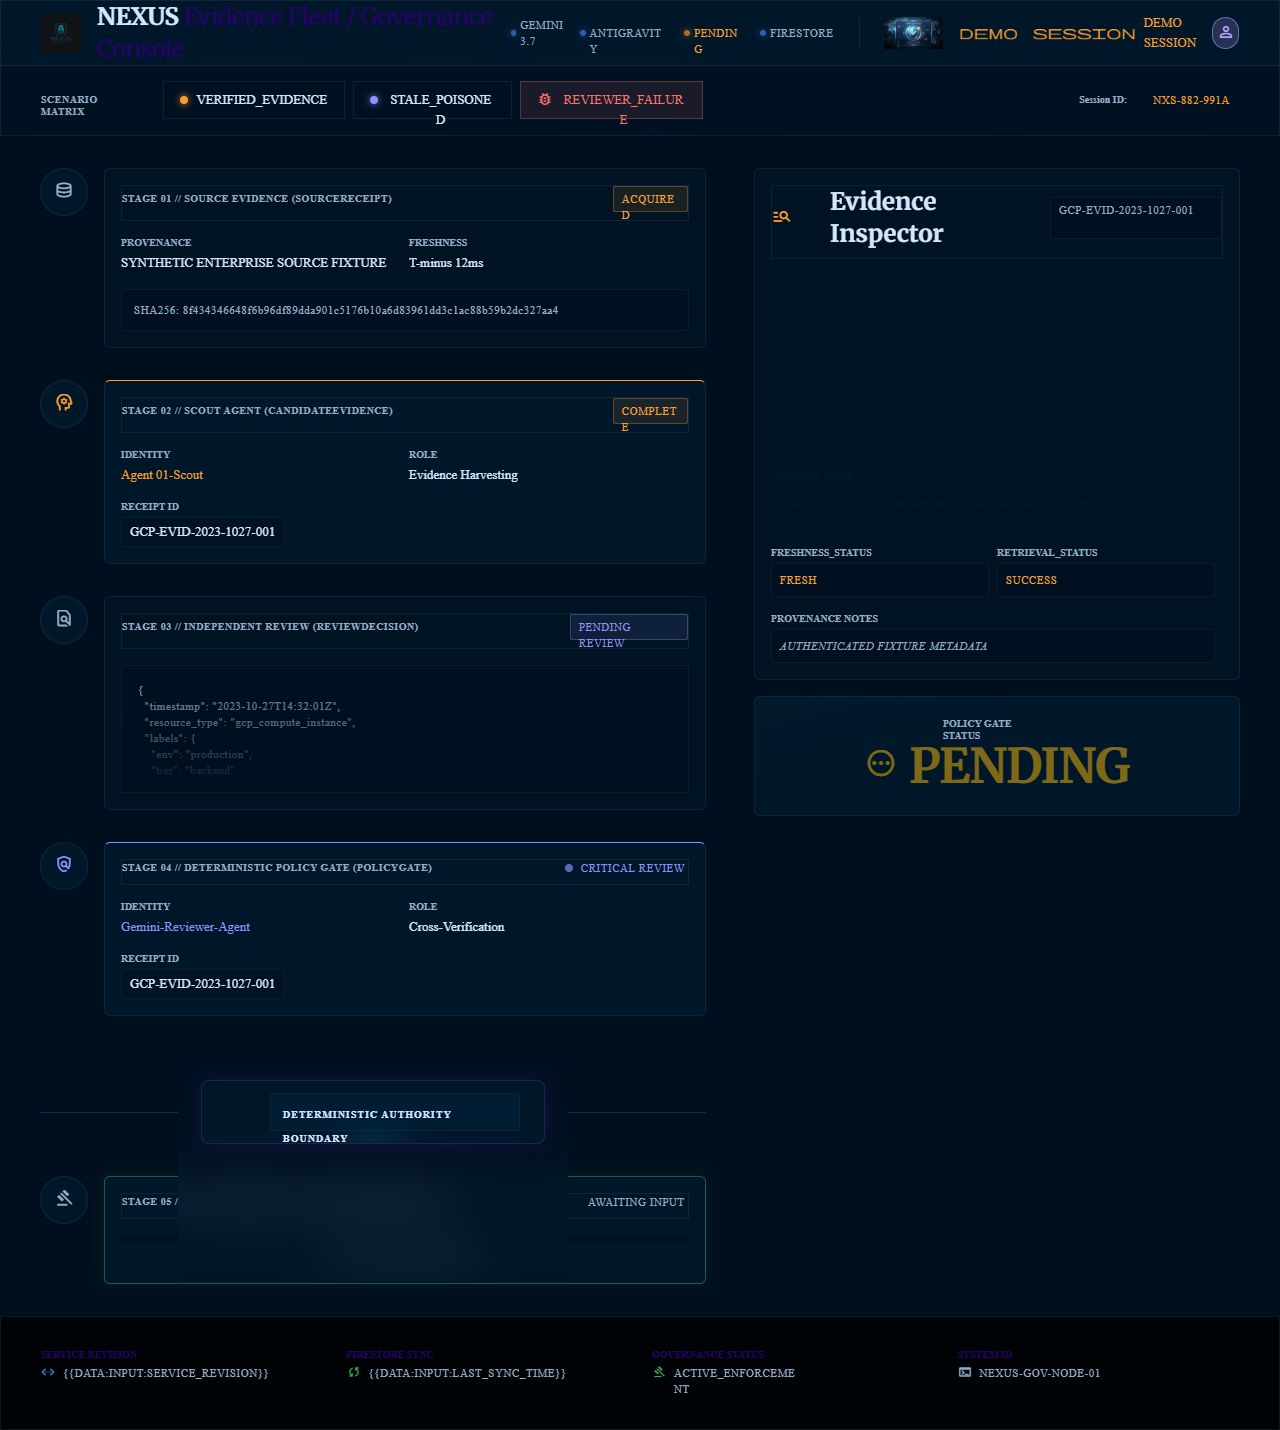
NEXUS Evidence Fleet
The problem
Autonomous AI agents are becoming extraordinarily fast at producing operational conclusions, security assessments, and decisions.
But speed creates a governance problem:
model confidence is not evidence, and model confidence must never become authority.
A worker agent should not be able to generate a claim, review its own claim, and silently promote that claim into trusted enterprise state.
NEXUS Evidence Fleet explores a different architecture:
Agents propose evidence. Independent review challenges it. Deterministic policy decides what gets promoted.
What we built
NEXUS Evidence Fleet is a new contest-period implementation for the Fortified Enterprise Fleet track.
The runtime separates the system into distinct authority layers:
SourceReceipt
- provenance
- content hash
- timestamps
- freshness state
ScoutAgent
- Google Antigravity SDK
- Gemini 3.7 Flash
- extracts and proposes
CandidateEvidence - authority ceiling:
CANDIDATE_PROPOSAL_ONLY
ReviewerAgent
- separate Gemini 3.7 Flash / Antigravity agent
- independently checks provenance, freshness, and evidence binding
- authority ceiling:
REVIEW_DECISION_ONLY
DeterministicPolicyGate
- pure Python
- no LLM reasoning
- evaluates hard invariants
- is the only component allowed to produce a
PromotionReceipt
The core rule is therefore enforced structurally, not just through prompting:
Scout != Reviewer != Promotion Authority
Three adversarial scenarios
VERIFIED_EVIDENCE
Fresh corroborated evidence flows through Scout and independent Reviewer.
When every deterministic invariant passes:
PROMOTED
STALE_POISONED
A convincing but superseded source is introduced.
Even if the candidate has high model confidence, stale provenance causes the deterministic gate to fail closed:
DENIED
REVIEWER_FAILURE
The independent reviewer is deliberately failed.
The system emits a FailureReceipt and does not silently bypass review:
REVIEW_FAILED
No reviewer means no promotion.
Google technology
The project uses:
- Gemini 3.7 Flash
- Google Antigravity SDK
- Google Cloud Run
- Google Stitch
- Python / FastAPI
- structured Google Cloud-compatible logging
- Firestore persistence when a cloud Firestore database is available, with a transparent local fallback for development
The agent layer also uses explicit capability ceilings and bounded Antigravity session budgets.
Visual governance with Google Stitch
We used Google Stitch to design an operations console where visual hierarchy reflects actual authority.
AI-generated CandidateEvidence is intentionally visually subordinate.
Independent review receives stronger treatment.
The strongest visual state belongs only to the Deterministic Authority Boundary and its final PROMOTED, DENIED, or REVIEW_FAILED outcome.
This makes the governance architecture visible to the operator instead of hiding it behind a chat interface.
External observer experiment
During development we also connected Gemini Spark to a custom NEXUS MCP bridge as a read-only telemetry sidecar.
The observer ran under:
EXTERNAL_OBSERVE_ONLY
That experiment demonstrates a second separation principle:
even an agent that can observe system telemetry does not automatically receive authority to mutate the governed runtime.
The Spark/NEXUS observer ledger and the contest application's evidence receipts remain separate systems.
What we learned
The biggest lesson was architectural rather than model-specific:
autonomy and authority should not be the same primitive.
Gemini 3.7 Flash and Antigravity made it possible to implement and iterate extremely quickly, but the deterministic gate deliberately remains outside the model.
We also learned that evidence should carry provenance from ingestion through review and promotion; infrastructure state, agent assertions, and model confidence should not silently increase that authority.
Challenges
The project was built under an extremely compressed contest deadline.
That forced us to prioritize:
- explicit role separation
- deterministic fail-closed policy
- provenance receipts
- reproducible tests
- deployment evidence
over a much broader feature surface.
The final test suite contains 18 passing tests covering valid promotion, stale evidence rejection, reviewer failure, identity separation, missing evidence, and policy failures.
New-project disclosure
This repository is a new standalone contest-period implementation inspired by the broader NEXUS evidence-governance research program.
Canonical NEXUS internals, private datasets, and private authority infrastructure were not transplanted into the contest application.


Log in or sign up for Devpost to join the conversation.