-
-
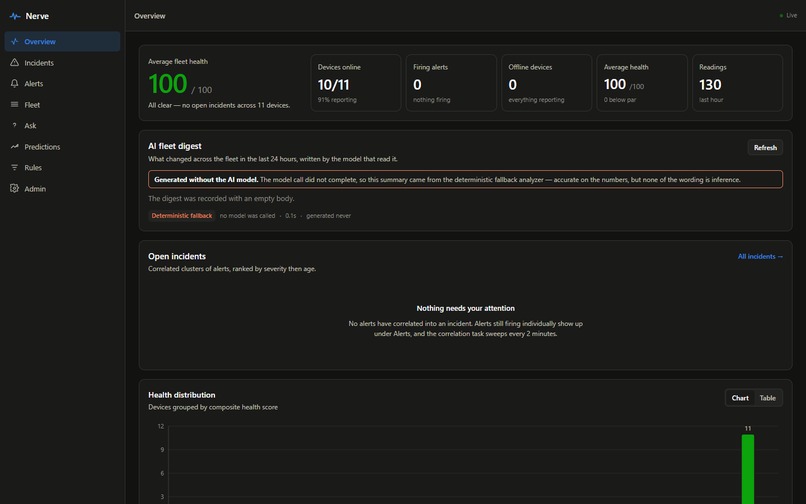
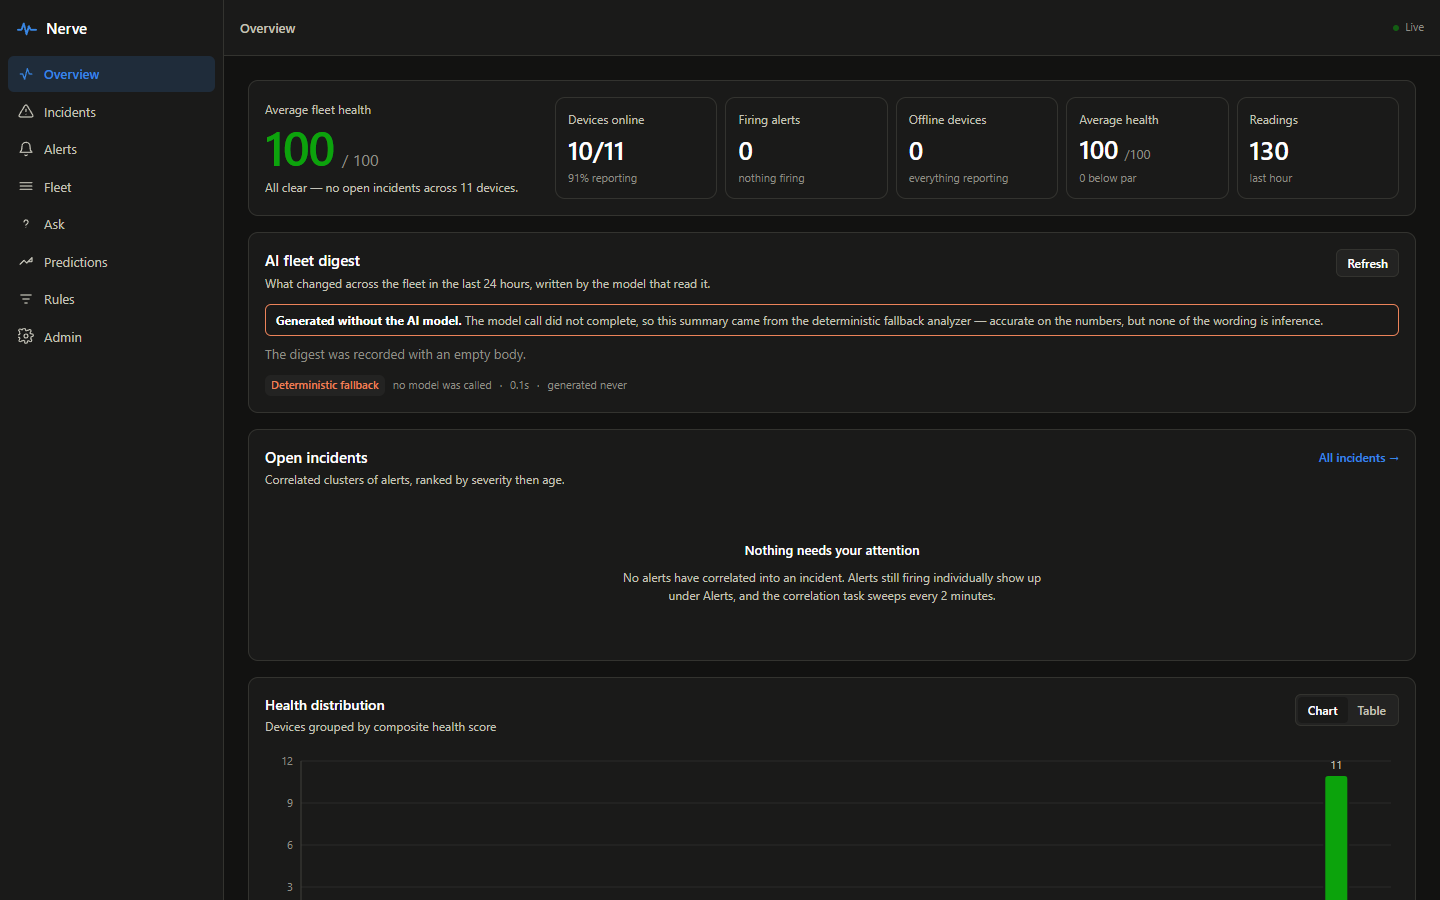
Fleet overview - one hero number, live status counts, health distribution and per-site rollup.
-
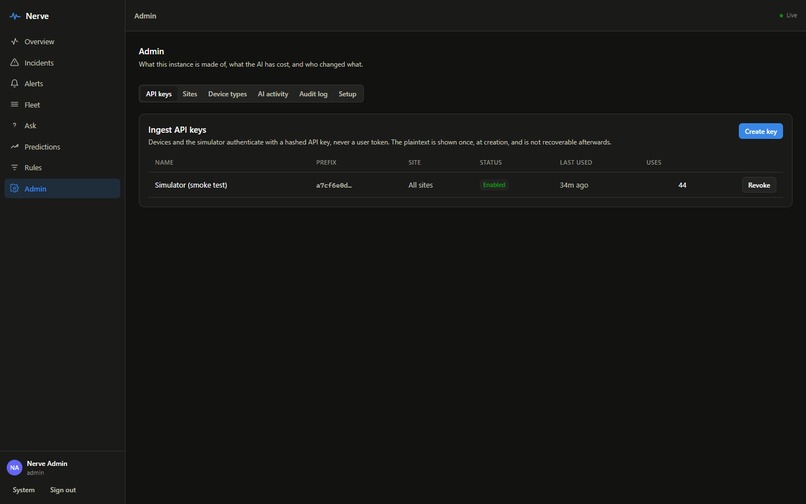
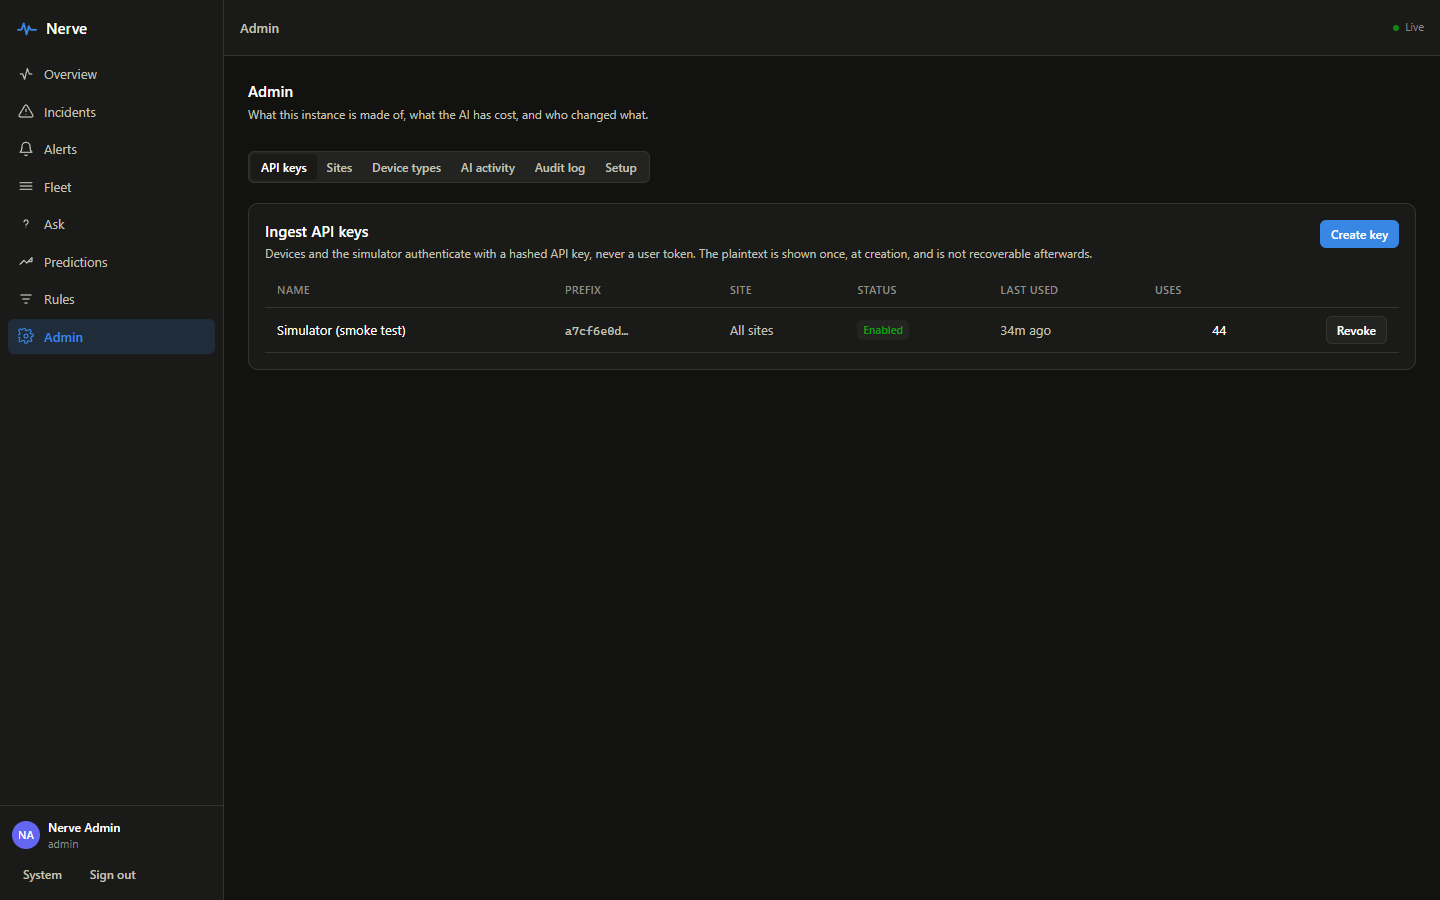
Every AI inference logged with its model, tokens, latency and whether the fallback ran.
-
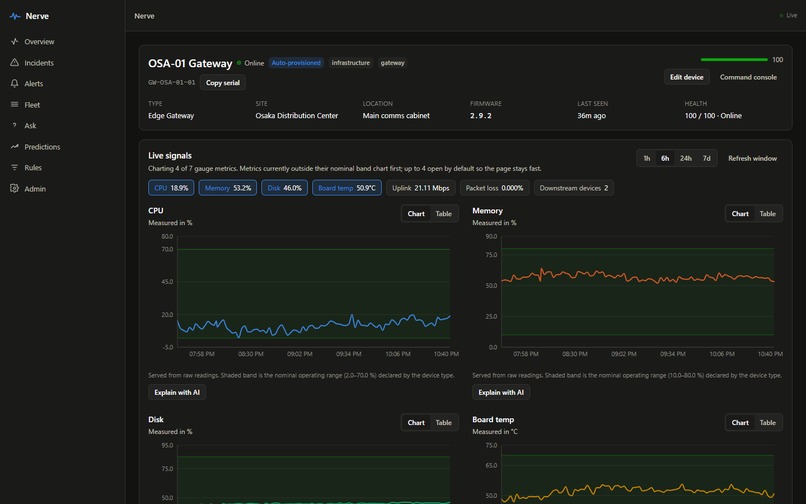
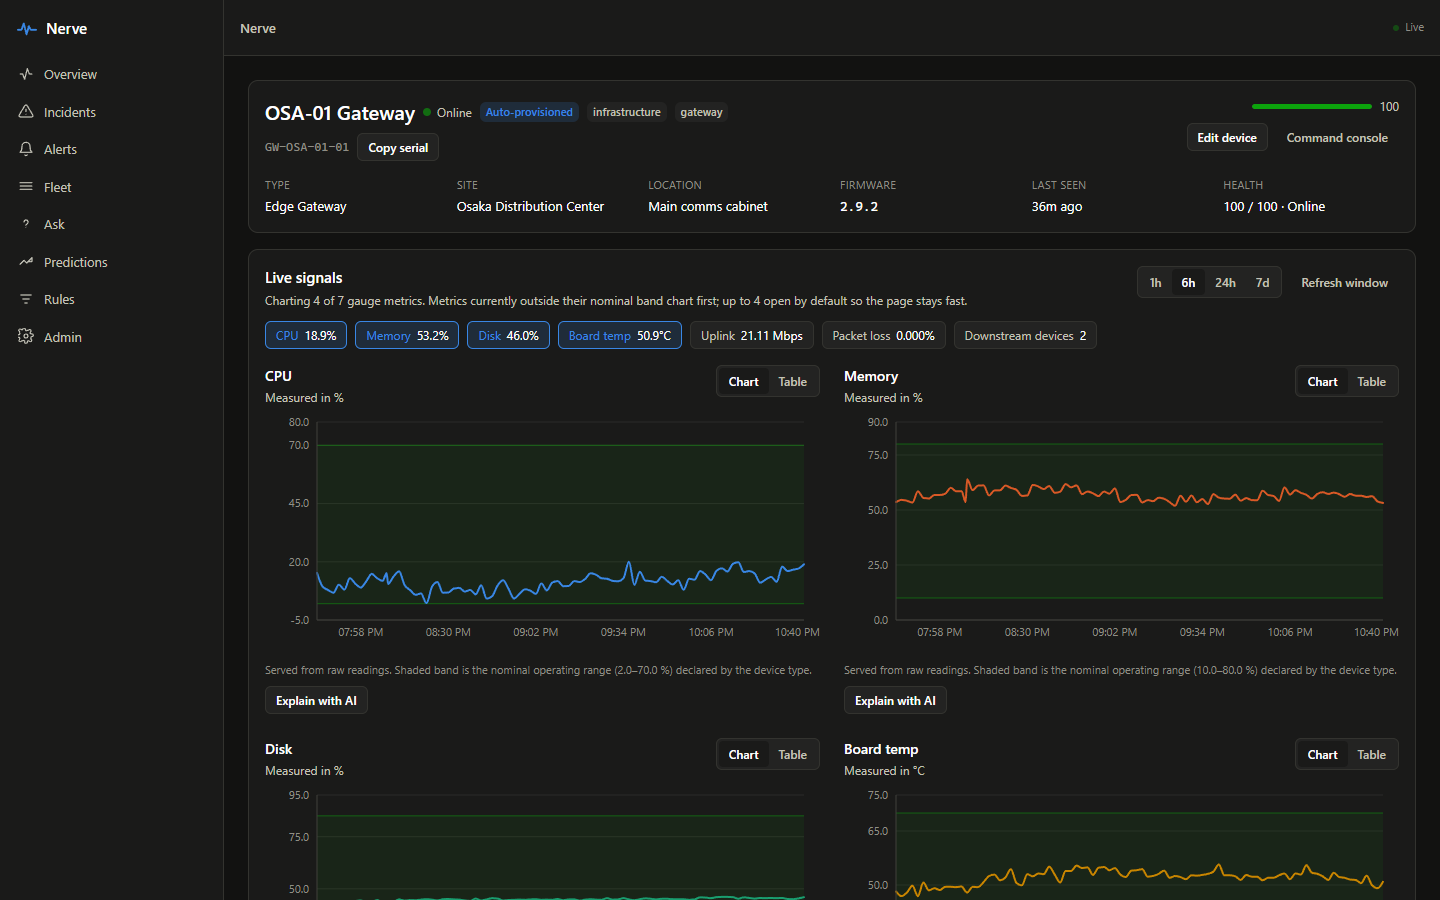
Real telemetry with the nominal operating range shaded behind it, declared by the device type.
-
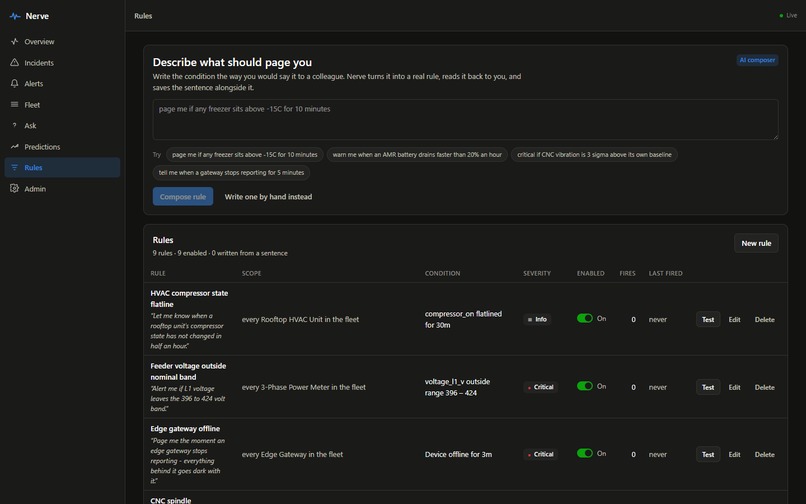
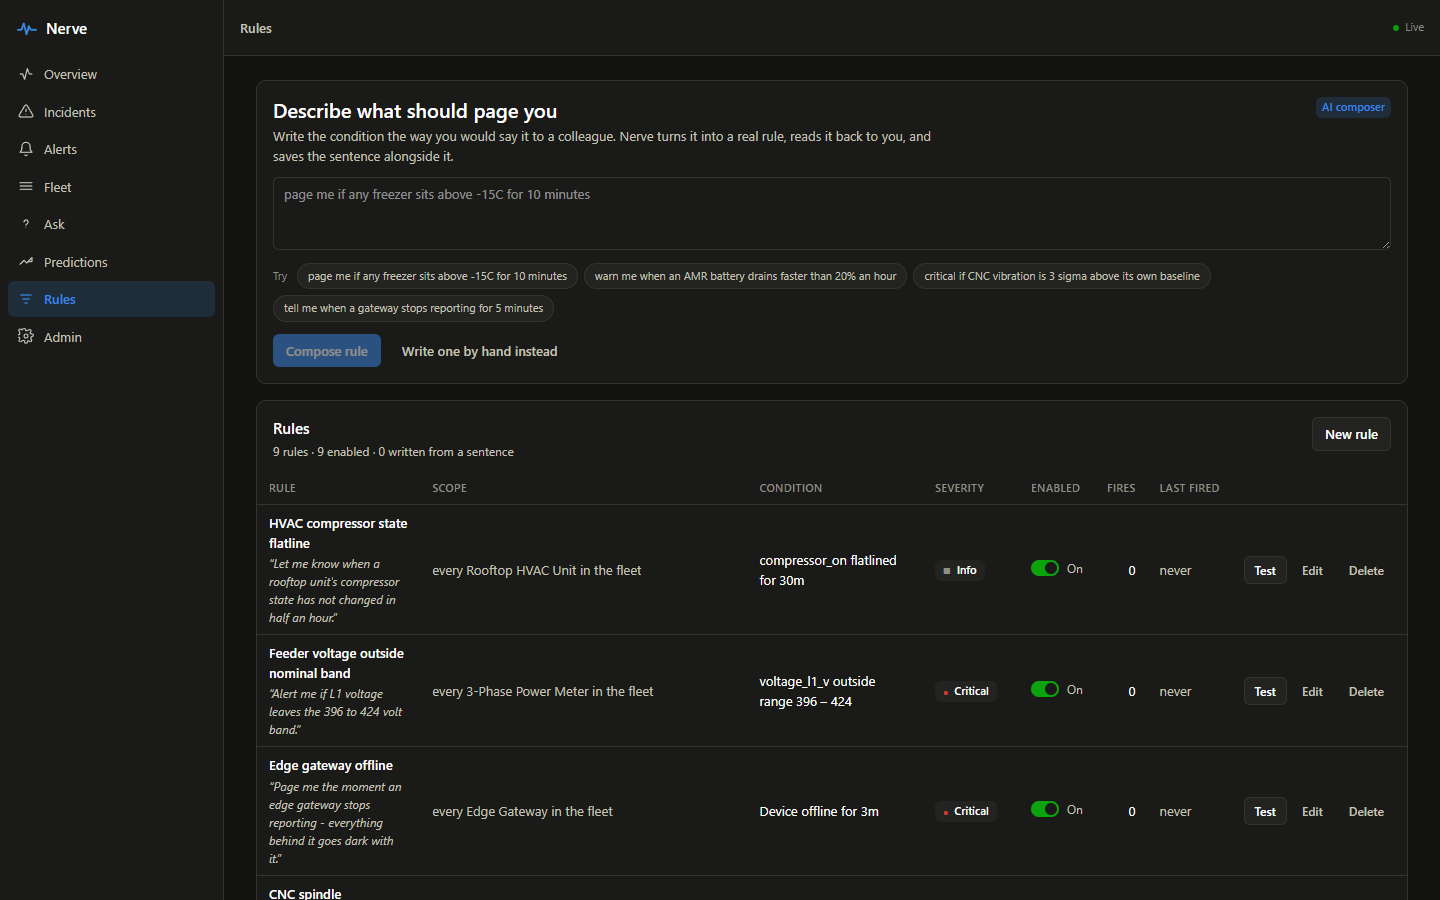
Rules keep the English sentence you typed, so they explain themselves six months later.
-
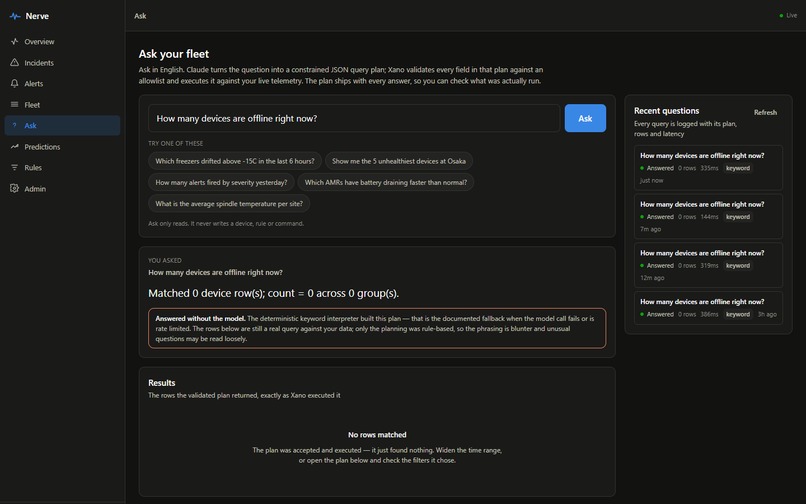
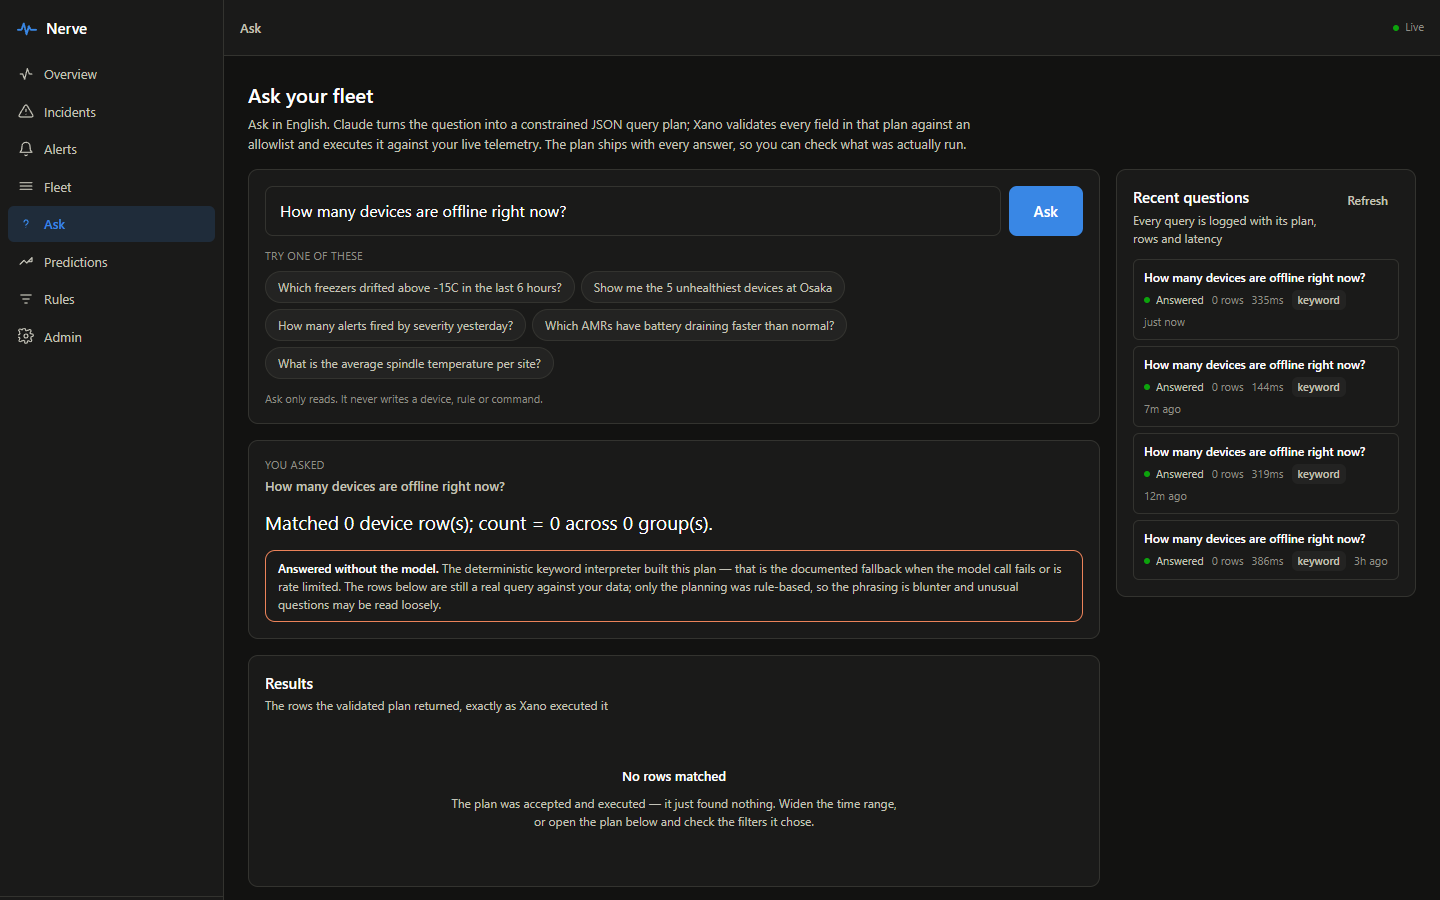
Ask in English. The model plans a query, Xano validates every field against an allowlist, then runs it.
-
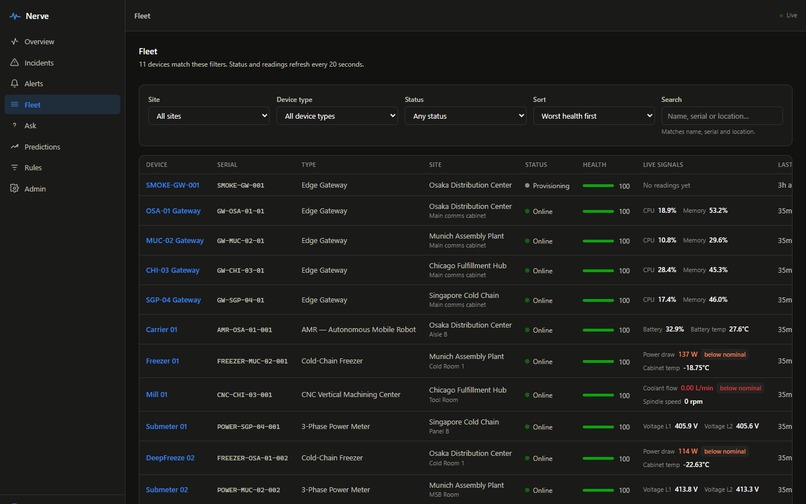
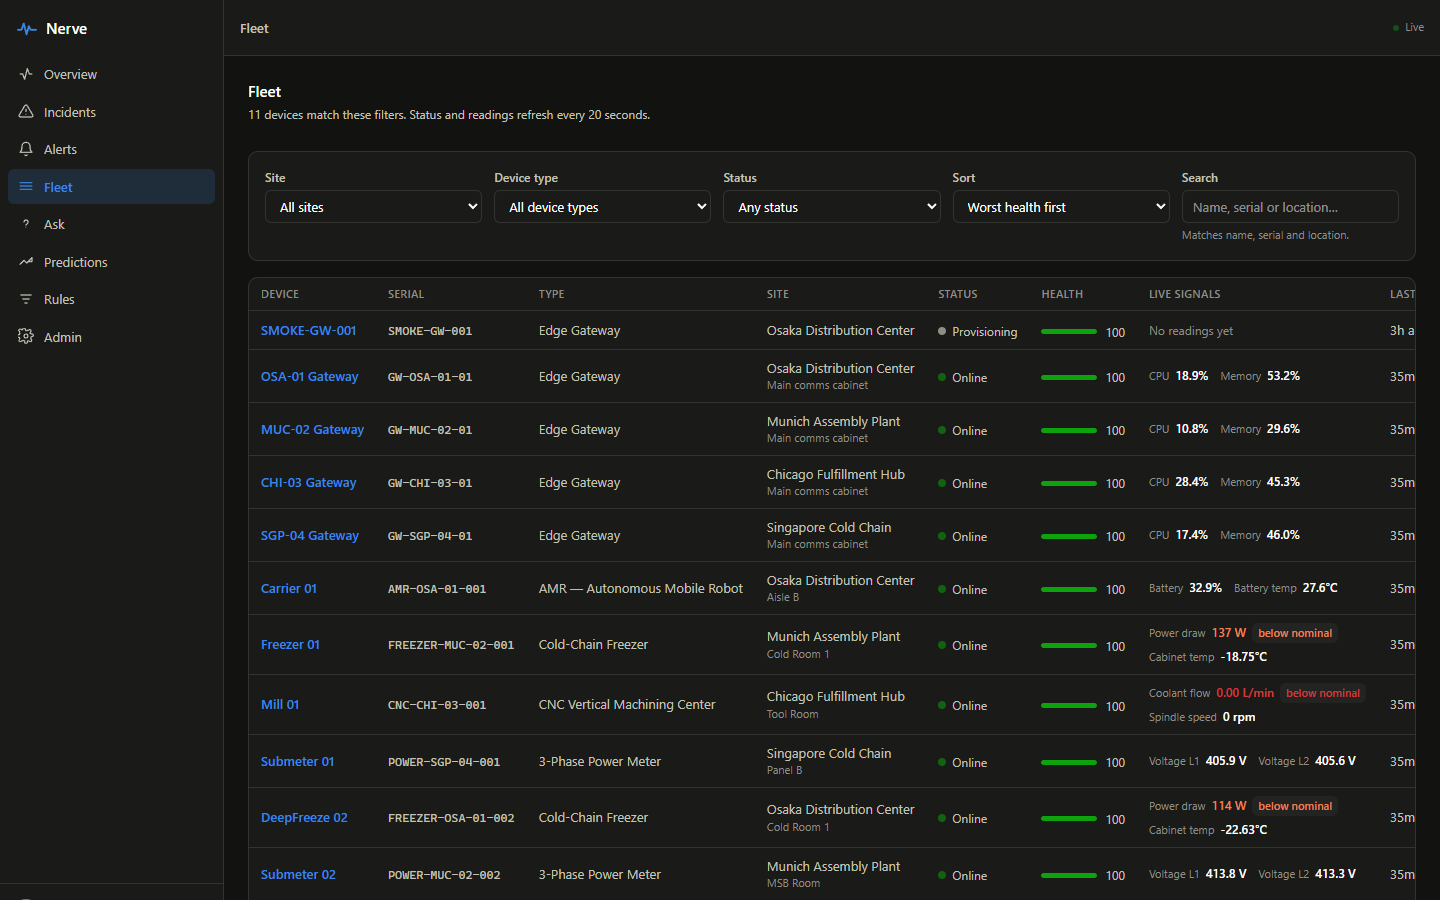
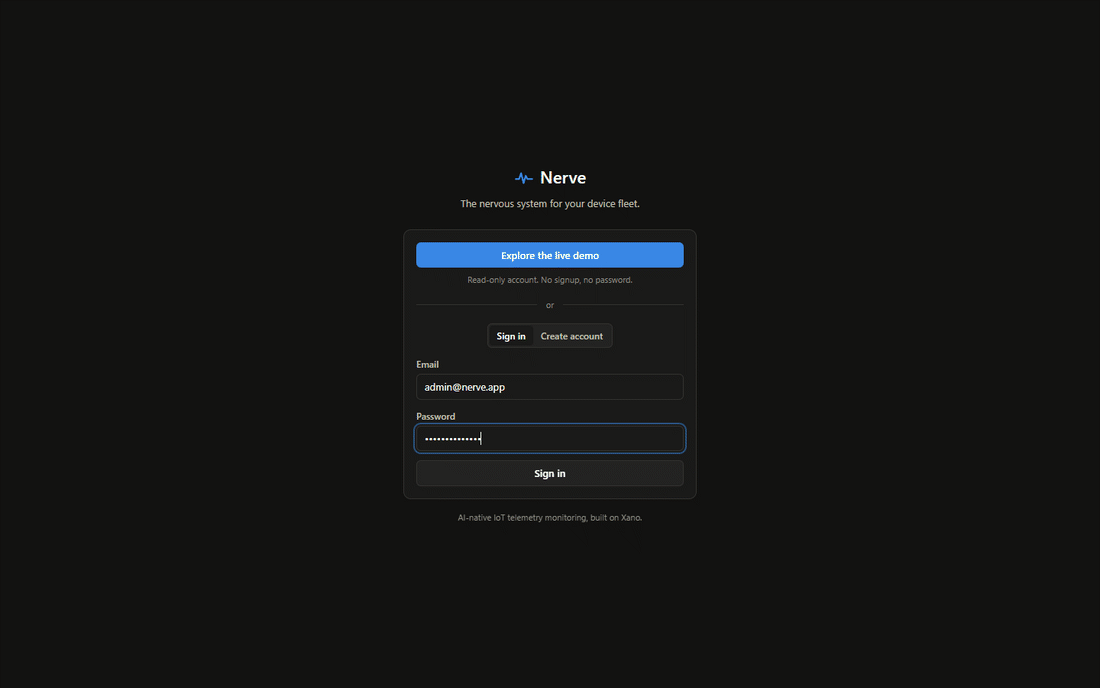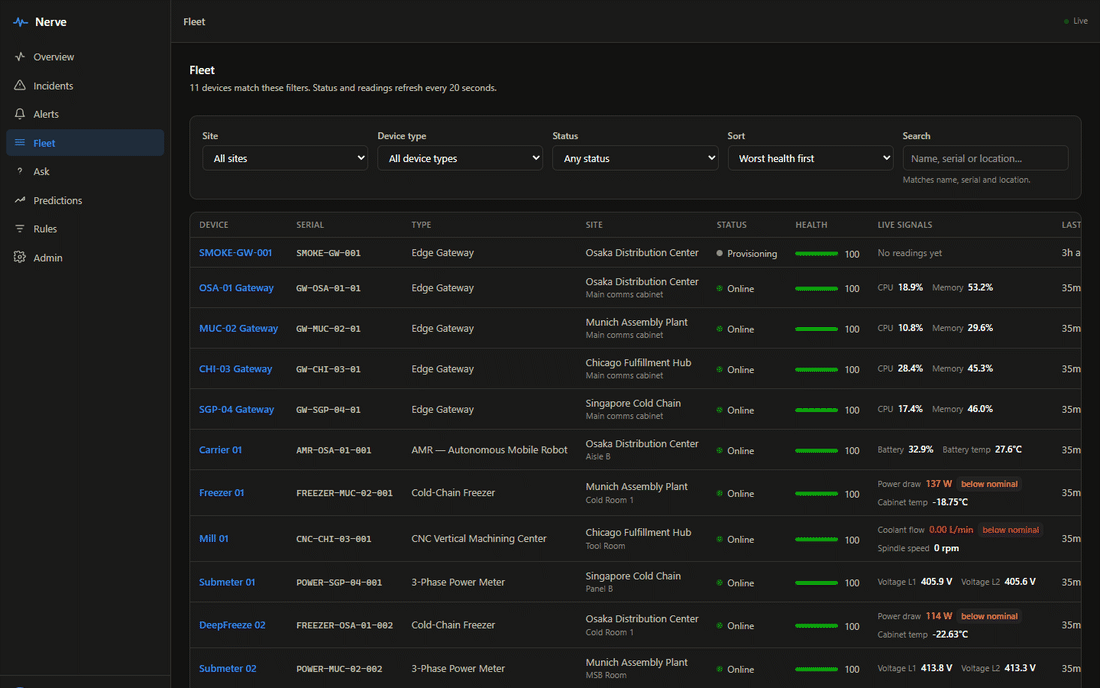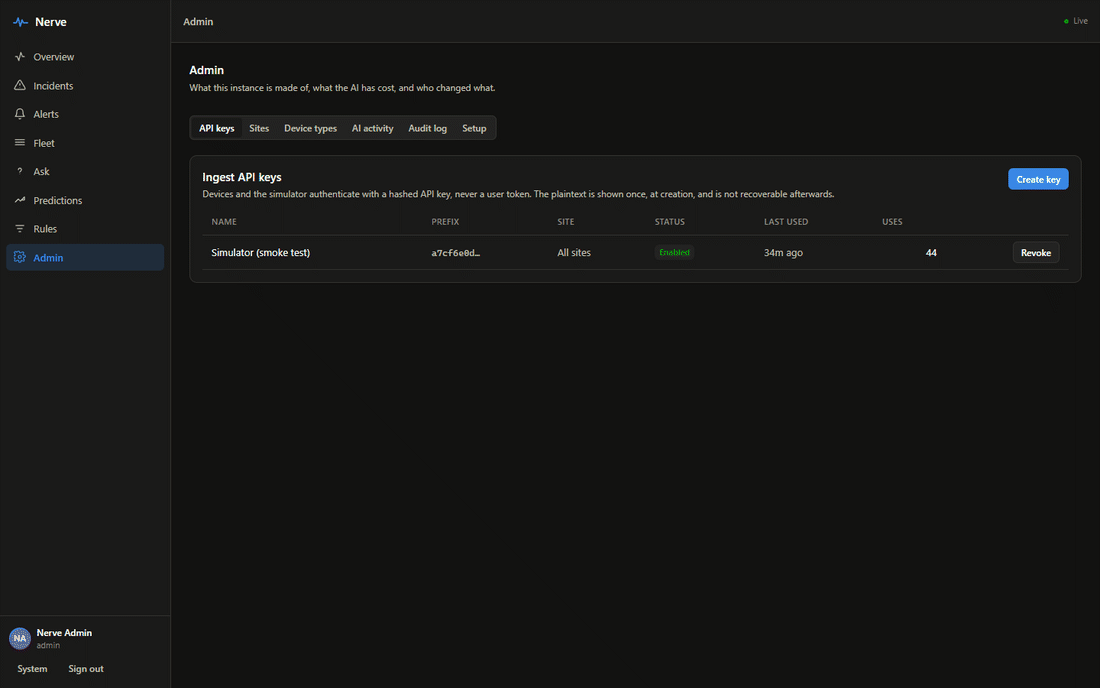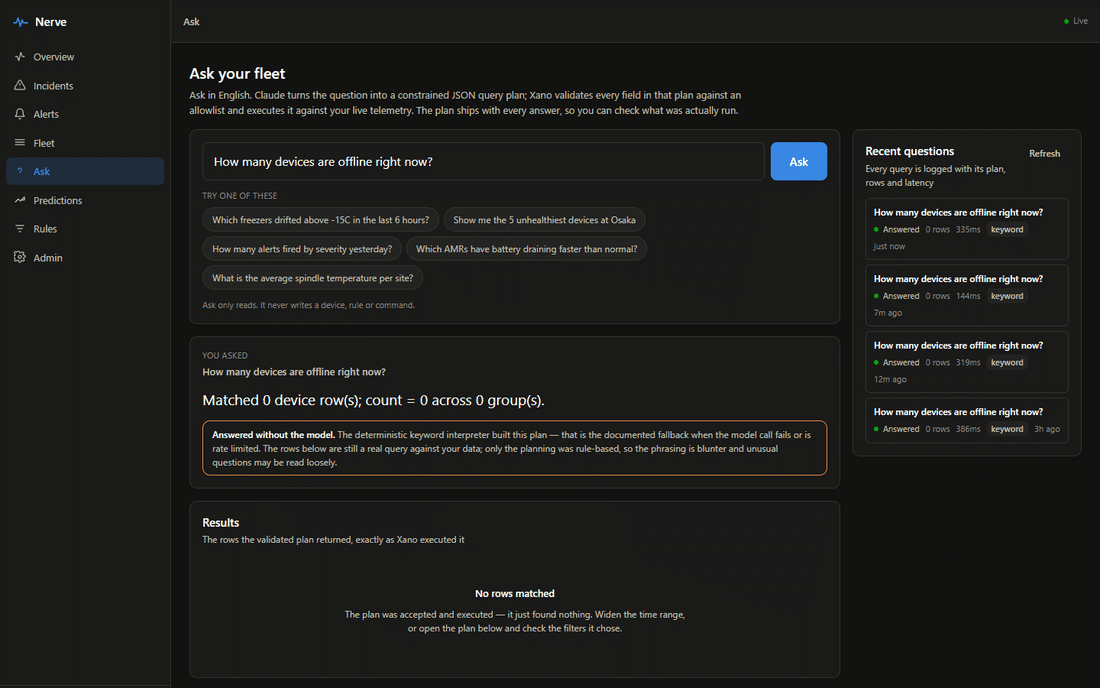
Fleet grid - filters round-trip through the URL, with live CPU and memory per row.
-
 GIF
Nerve end-to-end: overview, fleet, live telemetry with nominal bands, and the Ask console.
Inspiration
I build fleet-management software for autonomous mobile robots. So the tool I was rebuilding isn't one I researched — it's the one I fight with.
Three things drove this:
Datadog charges you for asking questions. Custom-metric cardinality is a billing event, so a fleet of 5,000 devices × 12 metrics becomes a line item you negotiate. The result is that people instrument less than they should. You end up blind by budget.
AWS IoT Device Management makes onboarding a project. Thing types, thing groups, policies, certificates — six console screens before one device reports a number.
And when something finally breaks, every one of these tools shows you a red graph and stops. Six freezers warming at one site produces six alerts and six pages, not one answer. The diagnosis is still entirely your problem, at 3am.
The premise of Nerve is that an operator should be handed a short list of incidents with hypotheses, not a long list of alerts.
What it does
Nerve is AI-native IoT telemetry monitoring. It turns a firehose of device signals into a short list of incidents worth your attention.
Ask the fleet a question in English. "Which freezers drifted above -15°C in the last 6 hours?" The governing rule is the model plans, Xano executes: Claude returns a constrained JSON query plan — never SQL, never a free-form filter — Xano validates every field of that plan against a hardcoded per-entity allowlist, clamps the row limit, and only then runs it as a real database query. A plan referencing anything unlisted is rejected, not executed. The UI shows you the validated plan next to the answer, because that's what separates this from a chatbot guessing.
AI incident correlation. A propped-open loading door warms six freezers at once. Threshold monitoring gives you six alerts. Nerve clusters them into one incident — keyed on site + device type + metric, or on a shared gateway for cascade faults — then asks Claude for a root cause, a confidence score, the evidence it reasoned over, and a remediation checklist. The evidence panel matters more than the answer: it means you can check its work.
Learned baselines instead of hand-tuned thresholds. Every device keeps an EWMA mean and variance per metric, updated incrementally, so anomaly detection is O(1) per sample with no historical scan — and each device learns its own normal instead of needing a configured exception.
Rules that explain themselves. Type "page me if any freezer sits above -15°C for 10
minutes", and Nerve restates in English what it understood before you save. The rule
keeps the sentence you typed, so six months later it isn't an anonymous temp_c > -15.
You can also dry-run a rule against real history — "would have fired 47 times across 6
devices in 24h, probably too sensitive" — without creating a single alert.
Predictive maintenance from trends, not breaches. An AMR battery losing usable capacity still charges to "100%", so no threshold ever trips. Nerve least-squares fits the rollup series, extrapolates to the hard limit, and shows you the fit inputs — samples, r², window — so the forecast is a checkable claim rather than a guess with a date on it.
Commands are first-class. Restart, calibrate, return-to-dock, enter-maintenance — all issued from the incident view to every affected device in one action, audit-logged. You don't leave the diagnosis to go find another tool.
Device onboarding is one API call. POST /ingest/register — a device announces itself
with a serial and an API key, and is provisioned, typed and charted immediately, because
its device type already declares its metric schema (units, nominal bands, hard limits).
How we built it
Backend: Xano, authored as local XanoScript files and pushed with the Xano CLI.
- 17 tables with composite indexes, json columns, enums and table references
- 46 endpoints across 3 API groups (
nerve-auth,nerve-ingest,nerve) - 8 custom functions, including
fn_claude— the single Anthropic wrapper every AI feature reuses - 6 background tasks: offline sweep, metric rollups, AI incident correlation, predictive sweep, daily digest, retention pruning
- 2 realtime channels, JWT auth with three roles, and hashed API-key auth for devices
Design decisions that mattered:
telemetryis wide, not long — one row per reading with all metrics in a single json column, so a 12-metric device costs one insert instead of twelvedevice.metrics_latestis denormalized, so the fleet grid is one query, not one per device- The AI is server-side by design. The Anthropic key lives in a Xano environment
variable and never reaches the browser. Every inference is logged to
ai_insightwith model, token counts, latency, and afallback_usedflag — so nobody has to take an AI claim on faith.
Frontend: Vite + React 19 + TypeScript + Tailwind 4 + Recharts, hosted on Xano static hosting. The chart palette isn't eyeballed — it's validated for colour-vision separation in both light and dark modes, and where light-mode contrast falls below 3:1 every chart ships direct labels plus a table view.
A reproducible device simulator. 36 virtual devices across 4 sites and 6 device types,
with 8 named fault scenarios. Signals aren't base + noise: each metric is a
mean-reverting random walk with a diurnal component, and metrics are physically coupled —
a freezer's power tracks its compressor, an idle CNC's spindle drops to zero, 3-phase power
is computed as √3·V·I·pf. That matters because the correlations the AI is asked to explain
have to genuinely exist in the data rather than being asserted by a fixture.
AI tooling: Claude Code (Opus 5) for the entire build, driving the Xano CLI and the Xano Developer MCP.
Challenges we ran into
Learning XanoScript without a feedback loop. XanoScript is declarative and unfamiliar,
and the obvious workflow — write, push, read the error — is slow and mutates a live
workspace. So the first thing built wasn't a feature: scripts/xs-validate.mjs drives the
Xano Developer MCP over stdio and validates every .xs file against the real language
server before it ever reaches Xano.
Then it turned out to be taking two minutes per file. Two compounding causes: npx was
re-checking the npm registry on every spawn, and close() killed the npx shim but not
the node grandchild it spawned, so the surviving process held the event loop open until
the caller's timeout — validation had actually finished in seconds. Fixed both:
120 seconds for one file → 9 seconds for all 106.
The docs contradict themselves, and the parser is the only authority. db.query takes
where, not search. Table references use table, not dbtable. And the documented
filter aliases — num_max, array_keys, fsort — are all rejected by the language
server, even though array_keys ships with a worked example. Real xano workspace pull
output was the only reliable ground truth.
The bug that would have silently disabled the entire product. $map|get:$key resolves
correctly. $map|get:$key:0 returns null — even when the key exists and holds 2.
Passing a default breaks the lookup. It was used in 180 places. Live symptoms:
device_count: null on every site; /ai/digest labelling a deterministic fallback as
model output; and in fn_claude, ($raw|get:"content":[]) would have blanked every AI
answer on a successful HTTP 200 with fallback_used: false — silently AI-less while
reporting success. Validation caught none of it. Reading one live response caught all of it.
A bootstrap deadlock nobody would have found by reading. Signup promoted the first user
to admin. But POST /auth/demo provisions the shared demo account on first use, and the
demo button is the primary action on the login screen — so on any real workspace the demo
row took the "first user" slot, every subsequent signup fell through to viewer, and
/admin/seed, /api-keys and /audit-log became permanently unreachable. Confirmed
live before fixing. It now gates on "does a non-demo admin exist", which is both
bootstrap-safe and self-healing.
The Free plan blocks four things. Middleware ("Please upgrade to access middleware"), background tasks, static hosting, and a hard 10 requests per 20 seconds instance-wide. Middleware was portable — the API-key auth moved into a custom function called as each ingest endpoint's first stack step. The rest genuinely need Essential. The rate limit also exposed a bug of my own: my retry backed off 400ms→1.6s, which is worse than useless against a 20-second window, because every attempt lands inside the same window and consumes quota it can't have regained.
Xano silently rejected my API group canonicals. I asked for auth and ingest;
canonicals must be unique instance-wide, so Xano assigned JWbfzXh1 and qr_uMgcM
instead. Every request 404'd with "This workspace no longer exists", and a fresh instance
would have produced different slugs again.
Custom request headers aren't readable in XanoScript on this Xano version. x-api-key,
X-Api-Key, api-key and api_key all 401'd a valid key, while Authorization: Bearer
and a declared input both authenticated it. Bearer became the documented transport.
Accomplishments that we're proud of
Every bug above was found by running the thing, not reading it. Validation proved
106/106 files parse. It proved nothing about whether they work. The get() default bug,
the bootstrap deadlock, the rejected canonicals, the unreadable headers, and a React
StrictMode bug that silently swallowed every error in the app — all of them passed
typecheck and validation cleanly and were caught by an end-to-end smoke test and by reading
live responses.
The honesty machinery is a feature, not scaffolding. Every AI inference is logged with
its model, token counts and latency, and fallback_used is surfaced in the UI as
"Generated without the AI model — accurate on the numbers, but none of the wording is
inference." Confidence is always shown. The evidence the model reasoned over is stored
alongside its conclusion. An AI feature that can't be audited is one you shouldn't trust,
and this one can be.
The model never touches the query. /ai/query was the easy place to shell out to
LLM-generated SQL. It doesn't: the model fills a schema, Xano validates every field against
an allowlist, and an invalid plan is rejected rather than executed.
The simulator is genuinely reproducible. Same seed, byte-identical output — verified,
after catching a Math.random() call in the battery model that had quietly destroyed it.
A demo you can't rehearse isn't a demo.
What we learned
Validation and verification are different things, and only one of them tells you the truth. 106/106 files validating clean was worth having — it caught reserved variable names and non-existent filters early. It also gave zero warning about the eight bugs that would have broken the product in front of a judge. Every one surfaced the moment real data moved through the real pipeline.
Trust the parser over the prose. Three separate times the official docs asserted
something the language server rejected. Real pull output from the live workspace was the
only source that never lied.
"It returned 200" is not "it worked". The most dangerous failure in the whole build was
a successful HTTP 200 carrying an empty AI answer with fallback_used: false — a lie the
system told confidently, twice, by two different routes.
Xano collapsed an enormous amount of backend surface. 17 tables with composite indexes, JWT auth, six cron tasks and an outbound LLM integration are all declarative files. No server, no migrations, no deploy pipeline. What remained hard was exactly the part that should be hard: modelling telemetry whose cross-metric correlations are physically real, so there's something genuine for the AI to find.
What's next for Nerve
Immediate
- Promote the 6 background tasks (written and validated, blocked only by the Free-plan gate) so correlation, rollups and predictions run continuously instead of on demand
- Ship Xano Realtime end-to-end — channels are defined; the client subscribe path is wired but unproven under load
- Deploy the SPA to Xano static hosting for a public demo URL
Near term
- Alert grouping feedback. When an operator splits or merges an incident, that's a training signal about the correlation key. Capture it.
- Multi-metric anomaly detection. The EWMA baseline is per-metric. Bearing wear shows up as vibration and temperature moving in lockstep — a covariance model would catch it earlier than either metric alone.
- Real device integration. The ingest API is deliberately transport-agnostic; an
MQTT→
/ingest/telemetry/batchbridge would take real hardware in one adapter.
The honest gap Predictive maintenance currently extrapolates a linear fit. That's right for disk fill and battery fade, and wrong for anything with a knee in the curve. It needs either a physics-informed model per component or enough labelled failures to learn the shape — and being clear about which predictions it can't make is more valuable than quietly making bad ones.
Built With
- anomaly-detection
- anthropic-claude
- claude-code
- ewma
- iot
- javascript
- jwt
- llm
- model-context-protocol
- node.js
- postgresql
- predictive-maintenance
- react
- recharts
- rest-api
- tailwind-css
- telemetry
- time-series
- typescript
- vite
- xano
- xanoscript

Log in or sign up for Devpost to join the conversation.