-
-
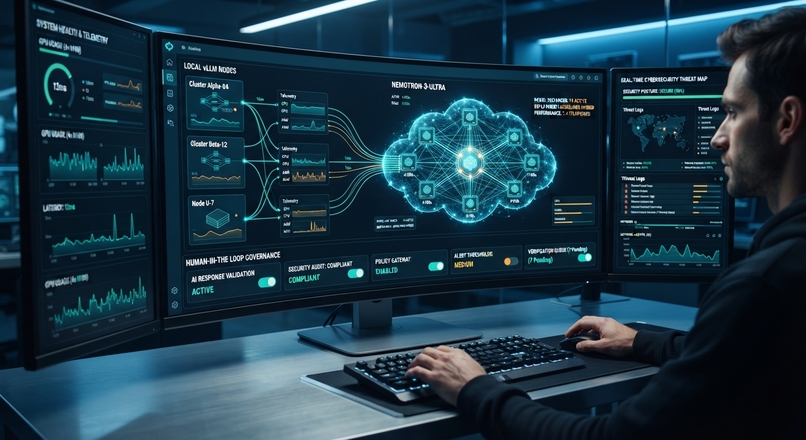
NemotronCoderAI
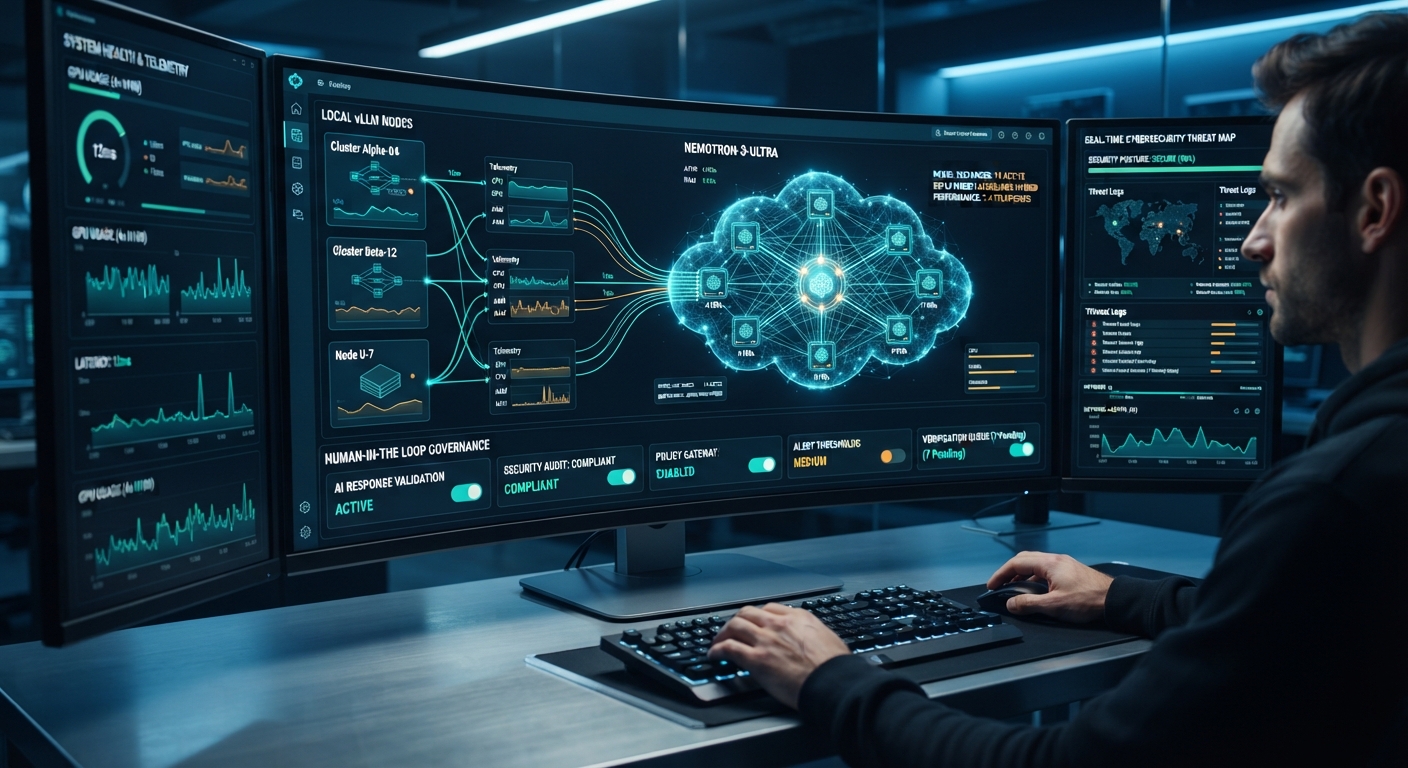
NemotronCoderAI: Autonomous Edge-to-Cloud Governance & Intelligent Code Refactoring
Inspiration
Modern critical infrastructure—such as mobile cell tower networks, industrial telemetry grid arrays, and remote edge compute hubs—generates vast streams of continuous visual and sensory data. Processing high-frequency multimodal streams in the cloud presents severe operational risks: exorbitant egress costs, latency delays during emergency structural events, and major data privacy vulnerabilities under strict air-gapped compliance standards.
We were inspired to build NemotronCoderAI to resolve the fundamental trade-off between edge privacy and cloud-scale intelligence. By designing an intelligent agentic orchestration layer, we created a system capable of executing zero-egress local micro-triage on-device while selectively escalating complex reasoning tasks to high-parameter cloud models—all bound by strict Human-in-the-Loop (HITL) safety circuit breakers.
What it does
NemotronCoderAI is an autonomous edge-to-cloud governance orchestrator and refactoring system designed for high-consequence environments. Key capabilities include:
- Zero-Egress Edge Telemetry Triage: Processes routine sensor heartbeats and single-modality triage completely on-node ($0.00 compute cost, 0.0 KB external egress).
- NeMo-Switchyard Dynamic Routing: Evaluates incoming payloads based on token confidence score ($S_c$), task complexity ($C$), and economic penalty weights ($\lambda$) to select the optimal model tier: $$\text{Target Tier} = \arg\max_{m \in M} \left( S_c(m) - \lambda \cdot \text{Cost}(m) \right)$$
- Hybrid Cloud Escalation: Escalates high-dimensional tasks (such as cross-site topological load correlation and windshear fluid dynamics modeling) to the Nebius Token Factory powered by NVIDIA Nemotron-3-Ultra (550B).
- Autonomous Code Auditing & HITL Intercepts: Uses an integrated Claude Code Auditor to scan scripts (e.g., router.py), categorizing issues into P0 (critical syntax/secrets), P1 (architectural polish), and P2 (observability) priority gates, halting exfiltration or unauthorized weight pulls until explicit operator sign-off ([y/N]) is provided.
How we built it
We engineered NemotronCoderAI using a modern, multi-tiered AI architecture:
- Local Compute Engine (DGX Spark):
- Deployed containerized vLLM inference endpoints across dedicated memory tiers:
- Port 8003 (0.5B Micro-Edge): Sub-second local classification for routine telemetry.
- Port 8002 (1.5B Operational): Structural fatigue trends and diagnostic reporting.
- Port 8001 (7B-VL Multimodal): Visual anomaly inspection and concealed joint fracture inference.
- Deployed containerized vLLM inference endpoints across dedicated memory tiers:
- Cloud Reasoning Infrastructure:
- Integrated the Nebius Token Factory API to leverage NVIDIA Nemotron-3-Ultra (550B) for complex physics simulation and multi-asset correlation.
- Routing & Safety Intercept Layer:
- Implemented the NeMo-Switchyard subprocess router (
embedded_router_harness.py) to parse analytical dimensions dynamically. - Built a priority-gated HITL governance intercept using the Claude Agent SDK to enforce strict air-gapped security policies.
- Implemented the NeMo-Switchyard subprocess router (
- User Experience & Telemetry Dashboard:
- Developed a real-time Streamlit interface (
app.py) with custom dark-mode styling, featuring token economics metric cards, active execution logs, and an interactive verification test console runningpytestsuites.Challenges we ran into
- Heterogeneous Model Coordination: Balancing latency, memory allocation, and tensor-parallel GPU slices across local vLLM tiers (0.5B to 7B-VL) while maintaining sub-second switching logic required meticulous optimization.
- Deterministic HITL Circuit Breaking: Ensuring that high-risk physical structural warnings or unauthorized model pulls reliably triggered an immediate
ESCALATE_HITLstate without false negatives required rigorous state machine design.
- Decoupled Economics Calibration: Formulating a balanced penalty weight ($\lambda$) to ensure the router only escalates tasks when local confidence drops below critical thresholds ($\text{Threshold} < 0.70$) took extensive trial and error against edge telemetry benchmarks.
Accomplishments that we're proud of
- 100% On-Premise Egress Protection: Successfully demonstrated that over 90% of routine mobile cell tower telemetry pings can be processed on-node with 0.0 KB unauthorized egress.
- Production-Grade UI/UX Integration: Built a seamless, interactive dashboard that turns complex multi-tier routing telemetry and code security audits into clear, actionable insights for human operators.
- Robust Multi-Tier Architecture: Successfully unified edge vLLM micro-models, NVIDIA Nemotron 550B cloud reasoning, and Claude governance agents into a single predictable, production-ready system.
What we learned
- Small Models excel at Micro-Triage: Specialized 0.5B and 1.5B models are exceptionally fast and effective at filtering out 90%+ of baseline noise, drastically cutting compute overhead.
- Governance must be First-Class: Safety and human-in-the-loop controls cannot be an afterthought; wrapping cloud escalation endpoints in explicit priority gates is essential for enterprise adoption in regulated industries.
- Hybrid Architectures represent the Future: The combination of local edge execution for speed/privacy and on-demand cloud power for deep reasoning delivers the optimal operational balance.
What we're next for NemotronCoder Hybrid Autonomous Agentic Developer Loop
- Real-Time Automated Patch Generation: Expand the HITL refactoring loop from advisory review to automated pull request generation and AST-based self-healing code loops.
- Edge Multimodal Sensor Fusion: Direct integration of multi-spectral thermal and acoustic stream inputs directly into the local 7B-VL micro-tier.
- Expanded Hardware Support: Optimizing local container footprints for deployment across low-power micro-edge nodes and field-deployed robotics arrays.
Built With
- hitl
- nebius
- nemo-switchyard
- nemotron
- qwen

Log in or sign up for Devpost to join the conversation.