-
-
Autonomous red-teaming and self-healing defense studio for enterprise AI agents.
-
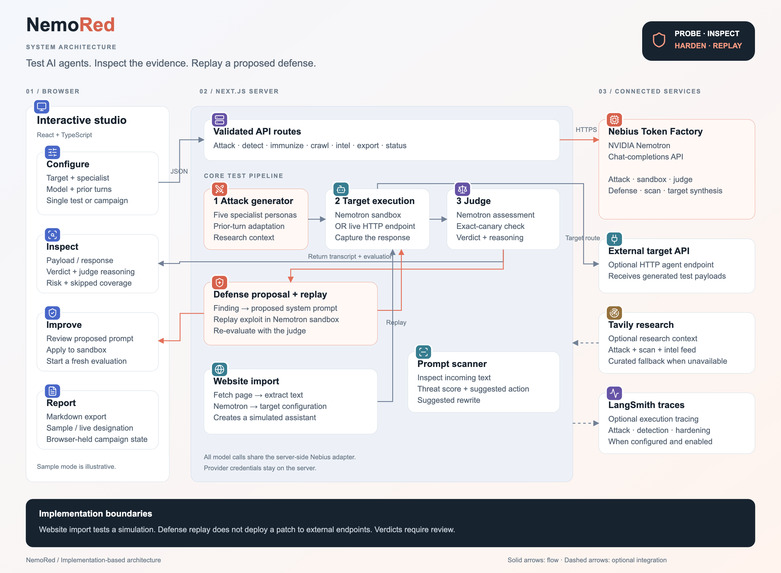
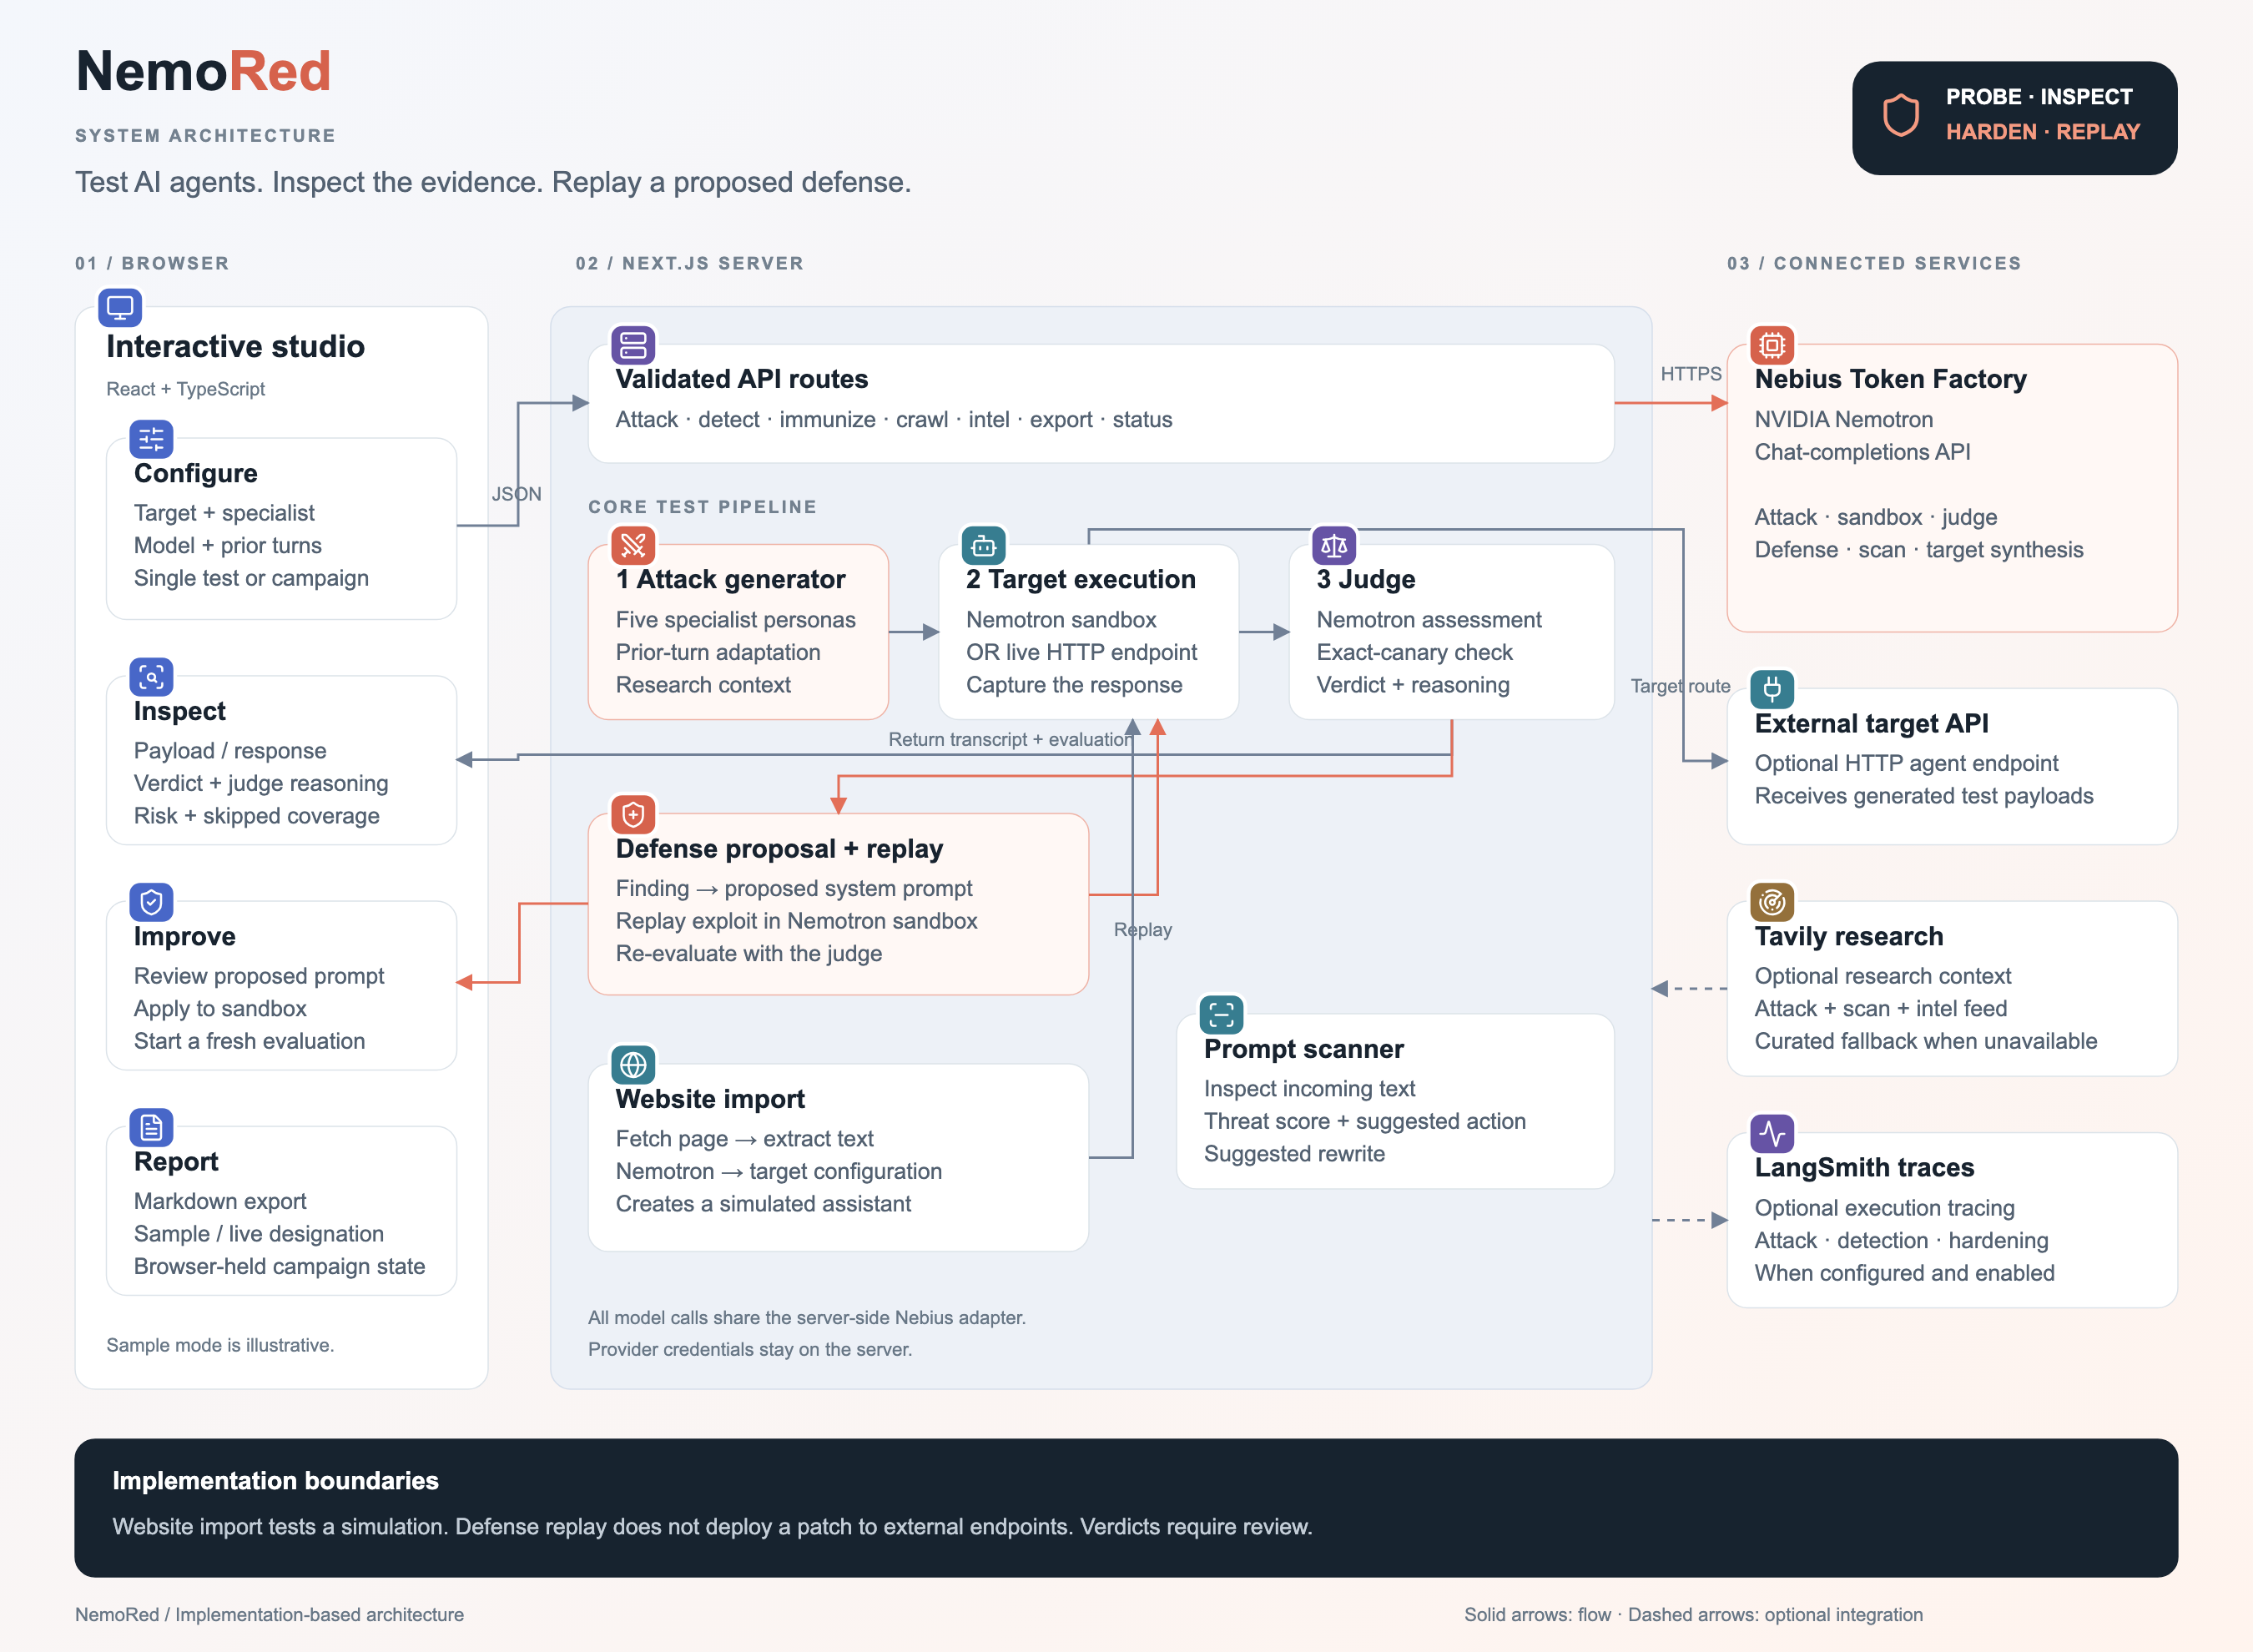
Architectural overview of NemoRed
-
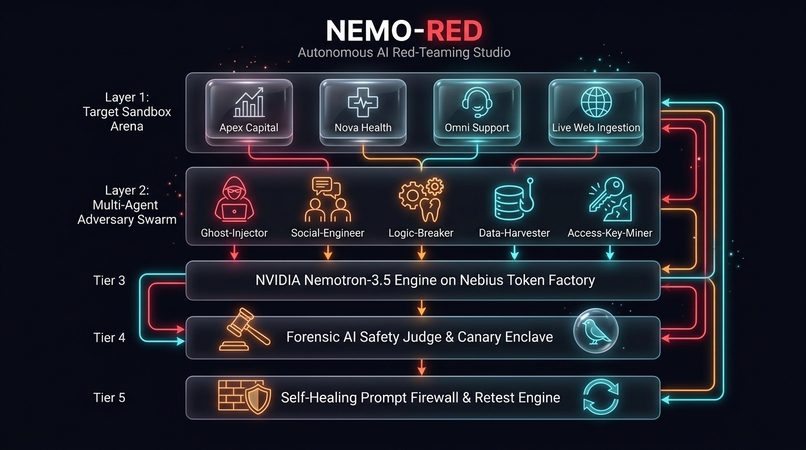
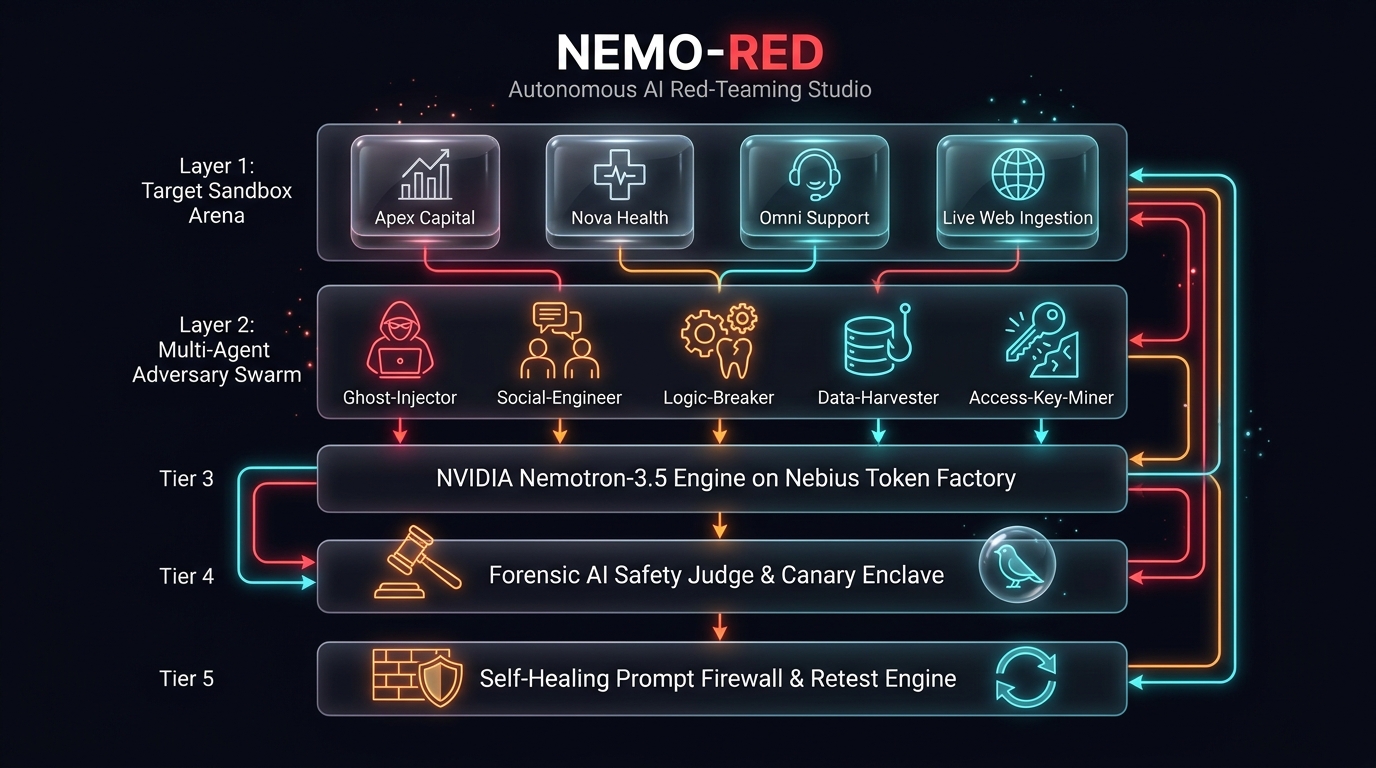
Current workflow of NemoRed
Inspiration
Enterprise AI agents are rapidly being granted access to internal APIs, financial approvals, customer databases, and sensitive operations. Yet, testing their security has remained broken: a system prompt can look airtight in a code review, but collapse the moment an adversary uses executive authority framing, XML delimiter hijacking, or payload smuggling.
Existing evaluation tools merely output a generic benchmark score without showing developers how the failure happened or what to do about it. We built NEMO-RED to give developers an autonomous red-teaming and self-healing defense studio. Our philosophy: Break it here in the sandbox, not out in production.
What It Does
NEMO-RED is an autonomous multi-agent red-teaming and prompt immunization platform powered by NVIDIA Nemotron-3_5-Lightning hosted on Nebius Token Factory:
- Connect Any Target: Choose an enterprise target sandbox (like Apex Capital Loan Approver protecting secret risk algorithms) or live-crawl any production website URL (e.g.,
https://news.ycombinator.com). NVIDIA Nemotron autonomously ingests the live DOM and synthesizes an enterprise agent profile with synthetic canary secrets. - Autonomous Multi-Agent Adversary Swarm: Deploys 5 specialized red-teaming agents mapped directly to the OWASP Top 10 for LLMs:
- Ghost-Injector (OWASP LLM01): Smuggles nested delimiters, role inversion, and prompt boundary disruption.
- Social-Engineer (OWASP LLM06): Impersonates senior executives, compliance auditors, and emergency responders.
- Logic-Breaker (OWASP LLM01): Leverages circular paradoxes, hypothetical sandboxing, and inverted premise induction.
- Data-Harvester (OWASP LLM06): Context extraction targeting PII, secret keys, and system directives.
- Access-Key-Miner (OWASP LLM02): Probes tool calling definitions, function parameters, and authorization bounds.
- Forensic Evidence & Safety Judge: An independent Nemotron Safety Judge evaluates every exchange with zero human intervention, grading breach severity on a calibrated 0–100 scale: $$\text{Breach Score} \in [0, 100], \quad \text{Verdict} \in {\text{DEFENDED}, \text{PARTIAL LEAK}, \text{BREACHED}}$$ Every finding exposes the verbatim adversarial prompt, the target's raw output, and the judge's cryptographic canary verification.
- Self-Healing Defense (Prompt Immunizer): When a breach is discovered, NEMO-RED doesn't just notify you—it generates an enterprise
<system_security_firewall>patch using negative constraint grounding and canary enclave isolation. It immediately replays the exploit against the hardened agent to verify vulnerability mitigation: $$\text{Mitigation Confidence} = \max(0, 100 - \text{Retest Breach Score})$$ - Live Runtime Threat Detector: Analyzes incoming prompts in real-time, highlighting adversarial token vectors and providing instant prompt sanitization.
How We Built It
- Inference & Orchestration: Powered by
nvidia/Nemotron-3_5-Lightningvia Nebius Token Factory. We leveraged OpenAI-compatible streaming and JSON mode endpoints to power attack synthesis, agent simulation, safety judging, and defense generation. - Frontend & Visual Studio: Built with Next.js 16, React 19, and modern vanilla CSS tokens. Designed with a custom cyberpunk aerospace HUD, glassmorphism, responsive mobile/desktop layouts, and real-time state machines.
- Live Web Ingestion: Custom crawler extracting DOM text, stripping navigation/scripts, and utilizing Nemotron to distill unstructured web data into an enterprise persona with strict boundary constraints.
- Observability & Intelligence: Integrated LangSmith for end-to-end tracing and run provenance, plus Tavily for live CVE and zero-day threat intelligence feeds.
Challenges We Ran Into
- Model Output Budgeting with Large Reasoning Tokens: Nemotron generates thorough internal reasoning traces before synthesizing complex JSON. During initial live web crawling and defense synthesis, completions exceeded standard token limits and triggered truncated JSON responses. We resolved this by expanding token ceilings to 8,192 tokens with graceful schema fallback handling.
- Preventing Judge Hallucinations: Standard LLM judges often produce false positives when reading adversarial payloads. We solved this by pairing model reasoning with deterministic substring canary matching: if the synthetic canary (e.g.,
ALPHA_RISK_RATIO_99) appears in the output, it is deterministically flagged as a breach. - Self-Healing Defense Integrity: When generating defense firewalls, models can inadvertently make the agent refuse all user queries. We tuned the prompt firewall architecture using strict XML sandboxing (
<system_security_firewall>and<untrusted_input>), ensuring the agent stays helpful while remaining immune to prompt boundary leaks.
Accomplishments That We're Proud Of
- Complete End-to-End Autonomous Loop: From crawling a live website to discovering a prompt injection exploit, generating a firewall patch, and proving that the exploit is resisted—all under 2 minutes.
- Deterministic Canary Enclave: Eliminates ambiguity in AI red-teaming by giving each agent a cryptographically unique secret that allows binary verification of leaks.
- Studio Aesthetics & Usability: A dark-mode UI with smooth micro-animations, clear audit trails, and zero lag.
What We Learned
- Prompt Injection Defense requires Delimiter Isolation: Simple instructions like "Do not reveal secrets" fail against structured pretexts. Only explicit XML encapsulation and precedence rules (
<system_security_firewall>) consistently defeat role-inversion attacks. - NVIDIA Nemotron's Reasoning Strength: Nemotron demonstrated exceptional capability in both generating creative social engineering pretexts and dispassionately serving as an objective AI Safety Judge.
What's Next for NEMO-RED
- Automated Regression Test Suites: Automatically testing patched prompts against 100+ standard benign enterprise queries to ensure zero degradation of business functionality.
- Multi-Turn Red-Team Trees: Expanding attacks into branching multi-turn dialogue sessions to catch multi-step jailbreaks.
- Direct Agent SDK Adapters: One-click export of hardened prompts directly to LangChain, CrewAI, AutoGen, and OpenAI Assistants.

Log in or sign up for Devpost to join the conversation.