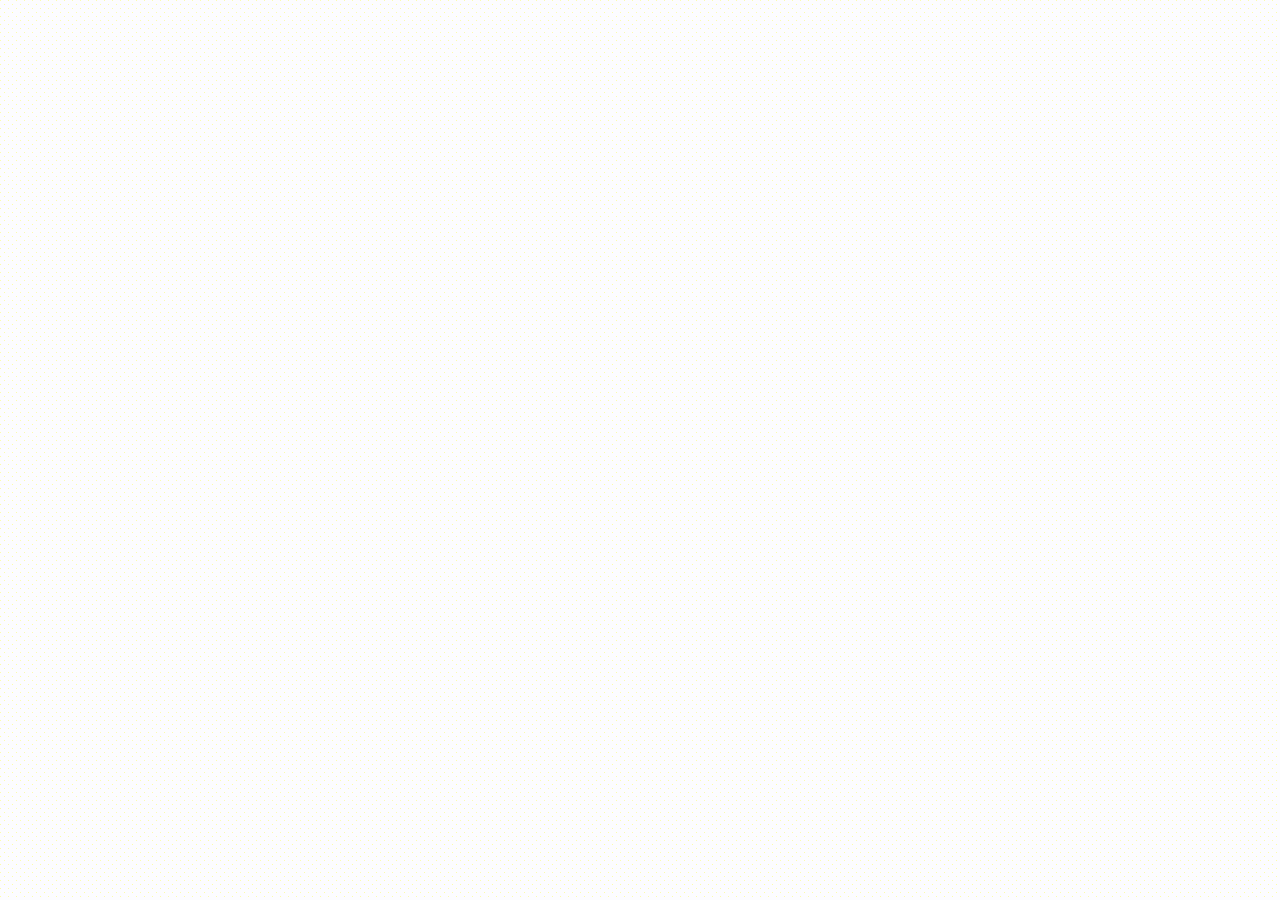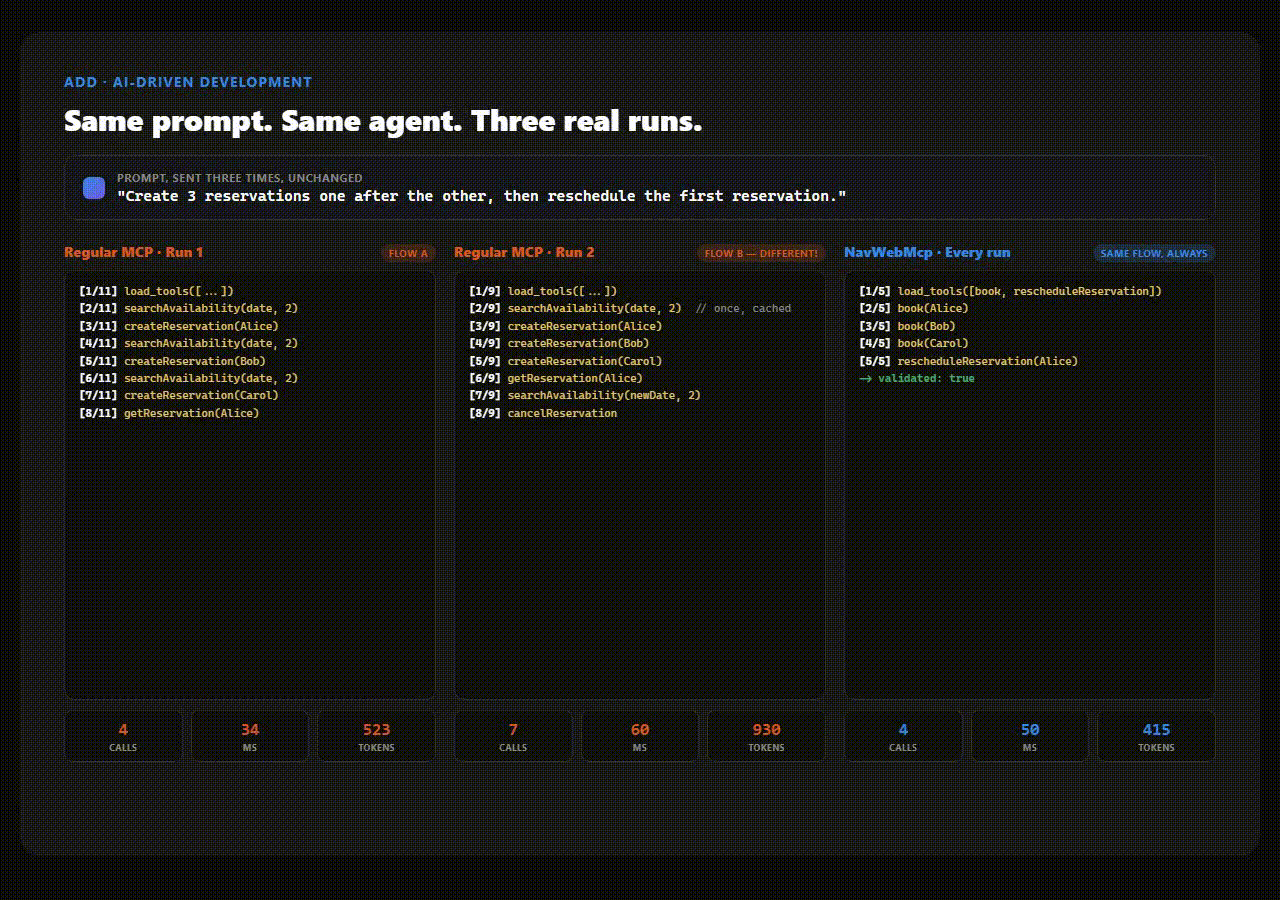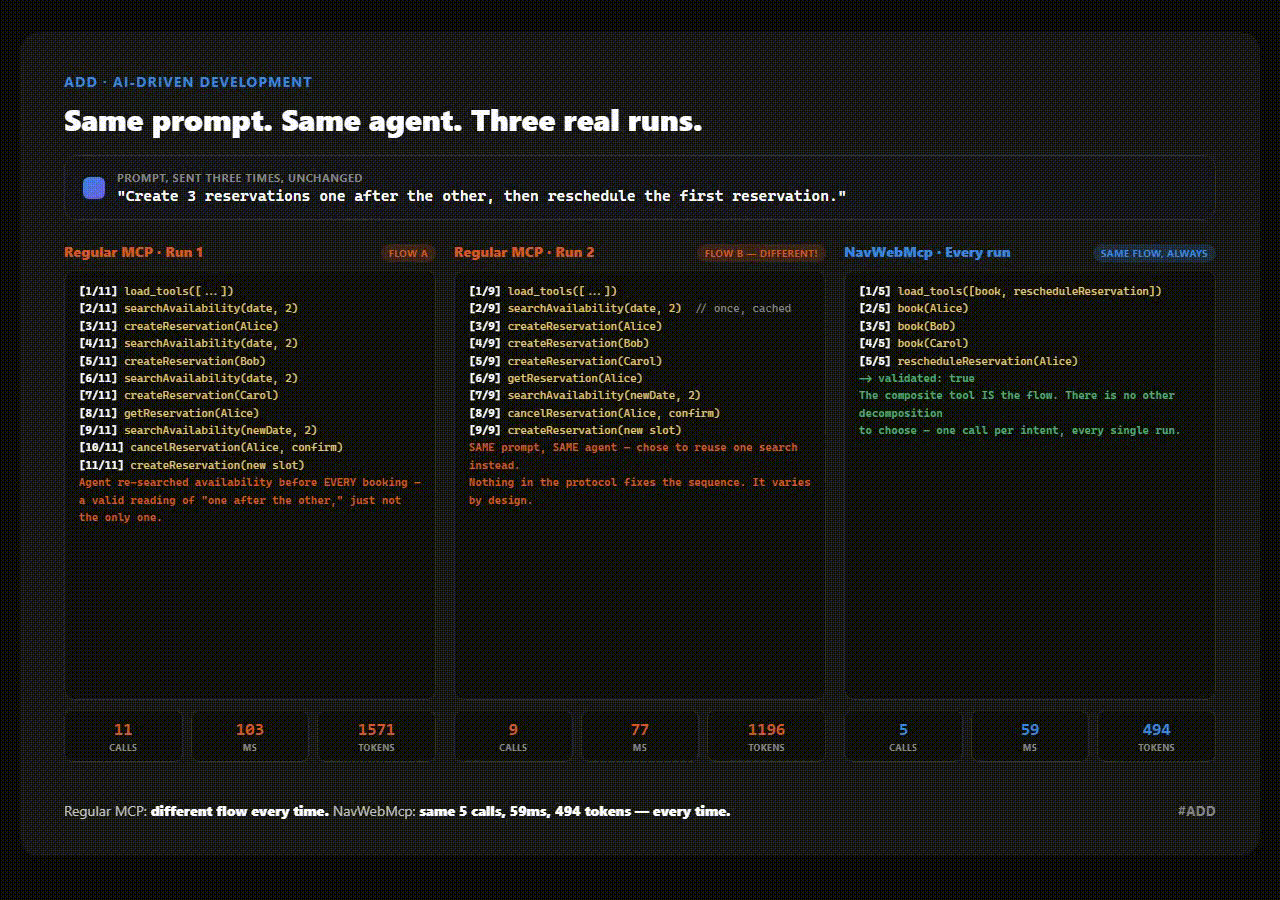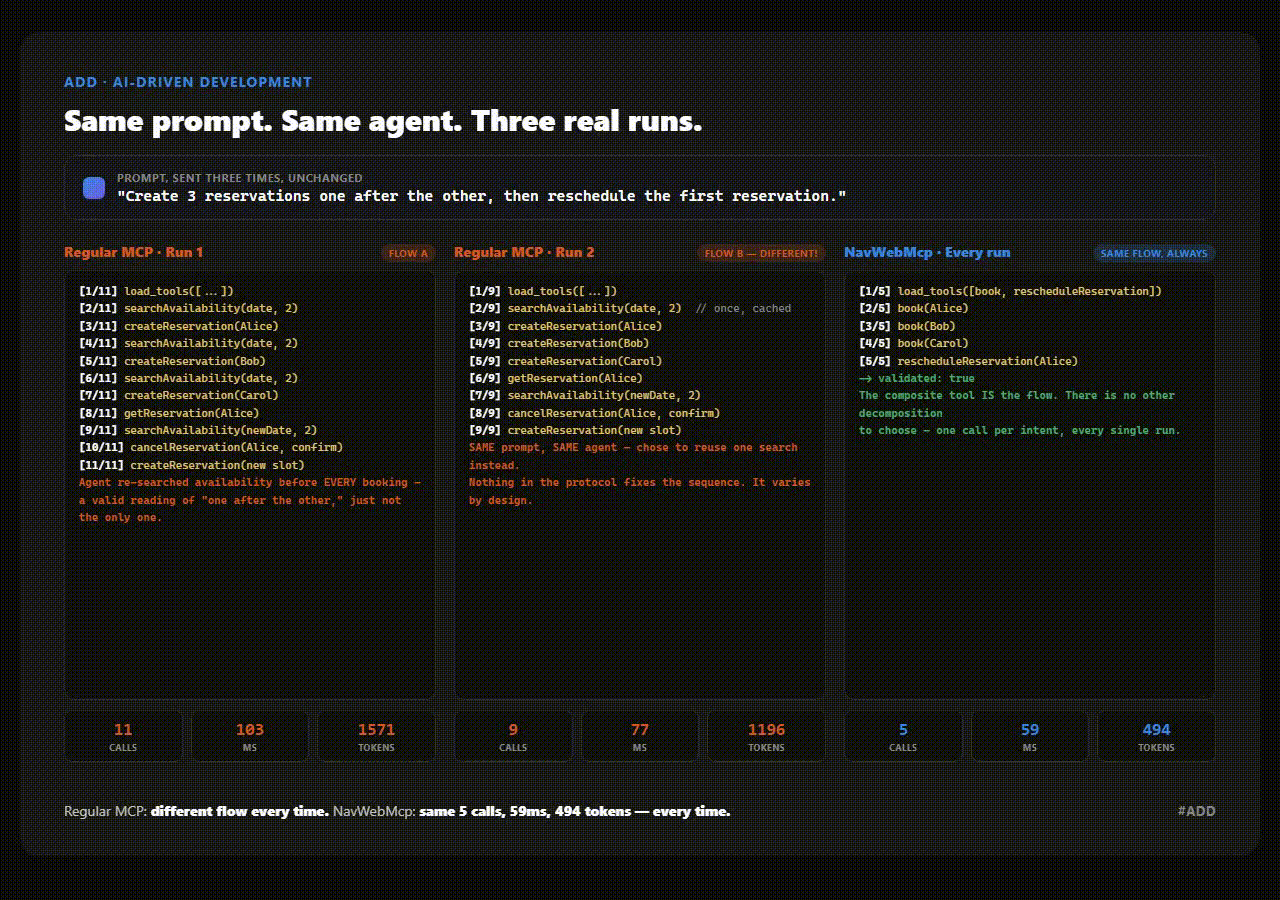
NavWebMcp — Devpost Submission
This is a young repo that takes the MCP and WEBMCP approach and tries to build a new approach that takes the benefits of both and give answers to their weaknesses.
Inspiration
Every existing way an agent touches a web app pays the same tax: either the agent orchestrates a sequence of raw API calls itself — search, then create, then verify — reasoning about your domain on every single round-trip, or it drives the page like a human would, reading an accessibility tree and clicking through a UI built for eyes and fingers, not for a model. Both cost tokens and latency that have nothing to do with the actual task, and both grow worse as the surface area of the app grows and it is not deterministic.
WebMCP (document.modelContext) is a promising browser-native answer to half of that problem — a page can register callable tools for an agent the same way it registers event listeners for a user. But the draft standard stops at "here's how a tool gets registered." It doesn't say how an agent should discover fifty tools without paying for fifty tools' worth of schema on every connection, how to layer permissions on top, or how to collapse a five-call workflow into one. That gap — protocol on top of primitive — is what NavWebMcp exists to fill. This repo is also a deliberate proof point for the AOD/ADD methodology (AI-Oriented Development / AI-Driven Development): intent specs framed up front, implementation delegated to agents, and every claim independently verified before being accepted — including, especially, the benchmark numbers below.
What it does
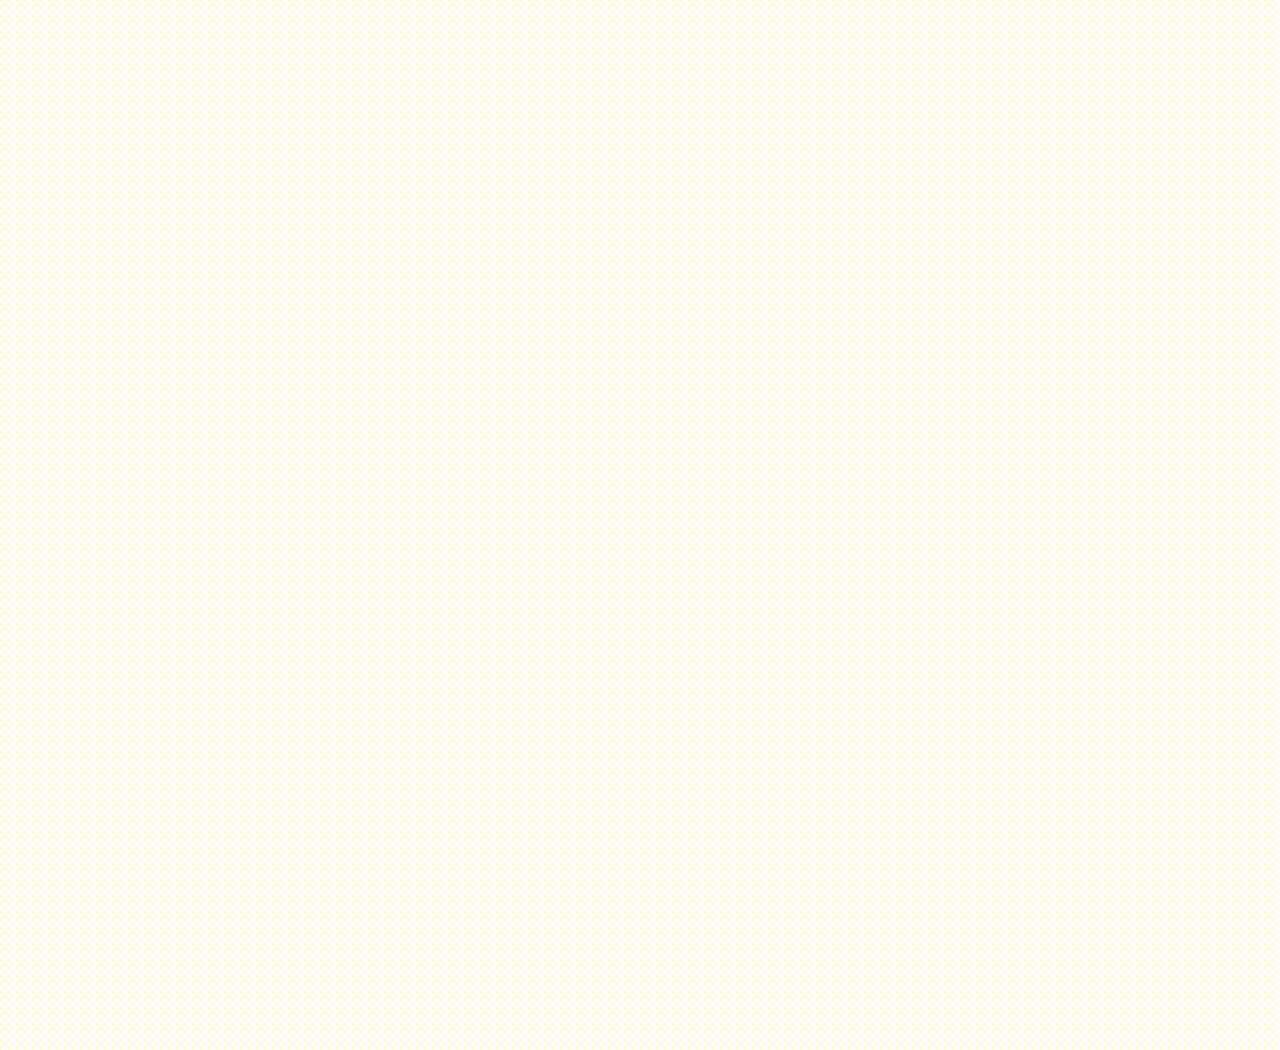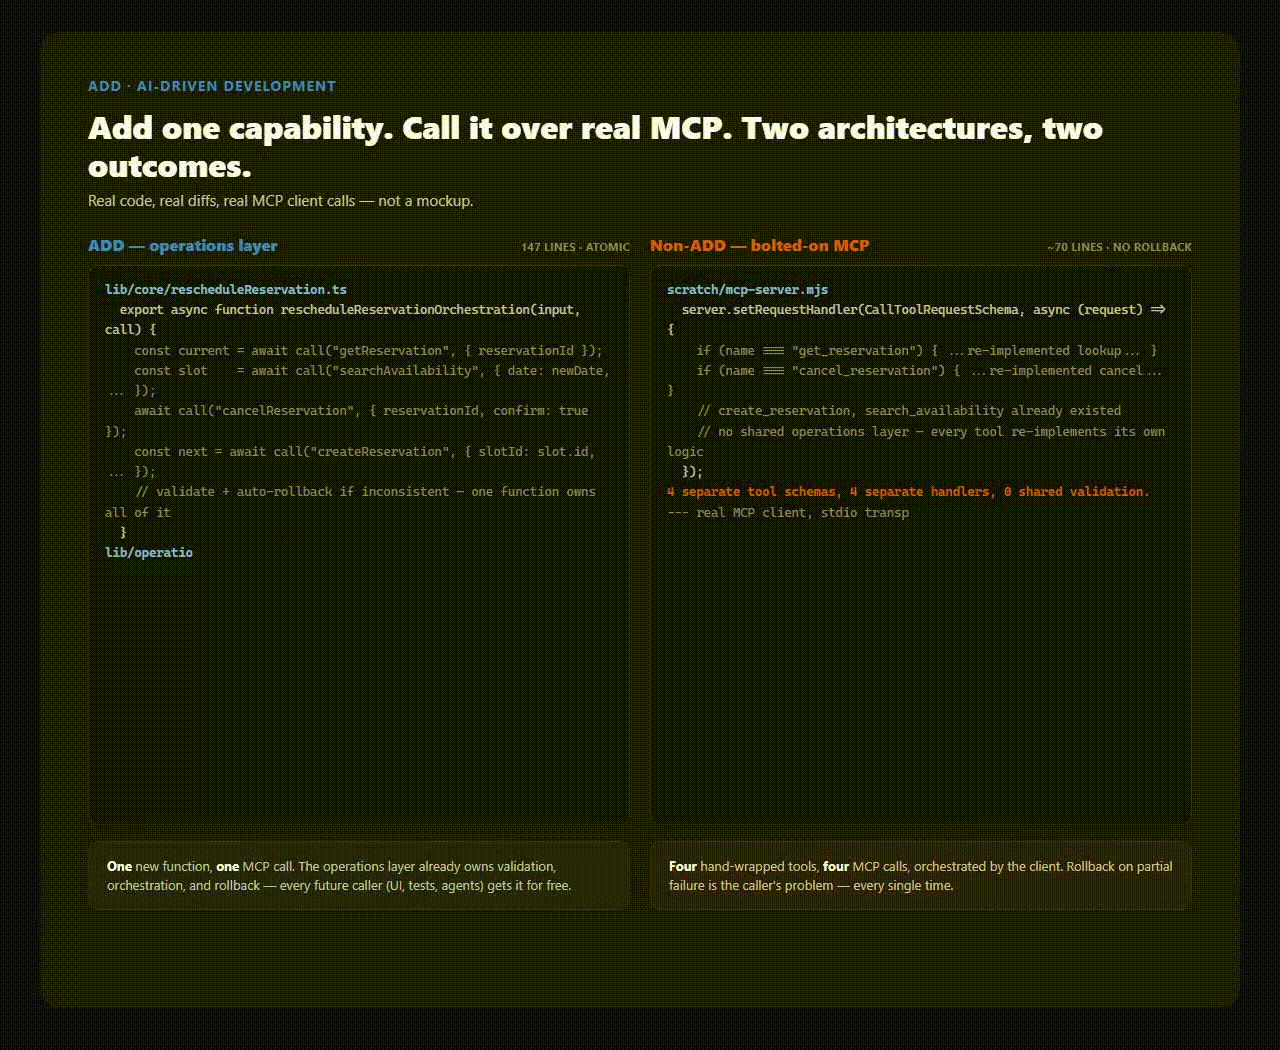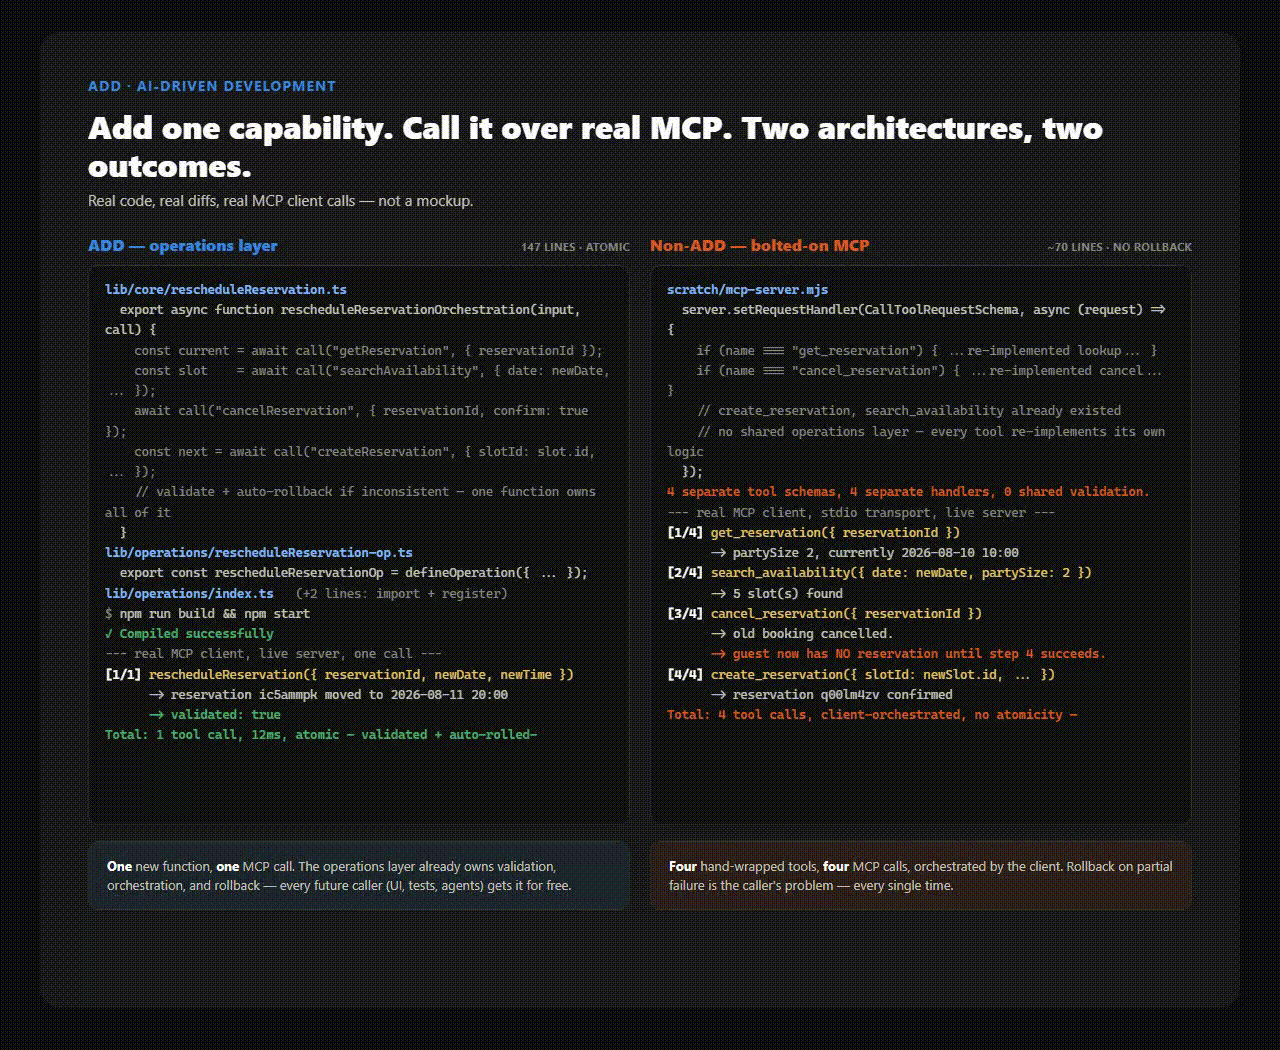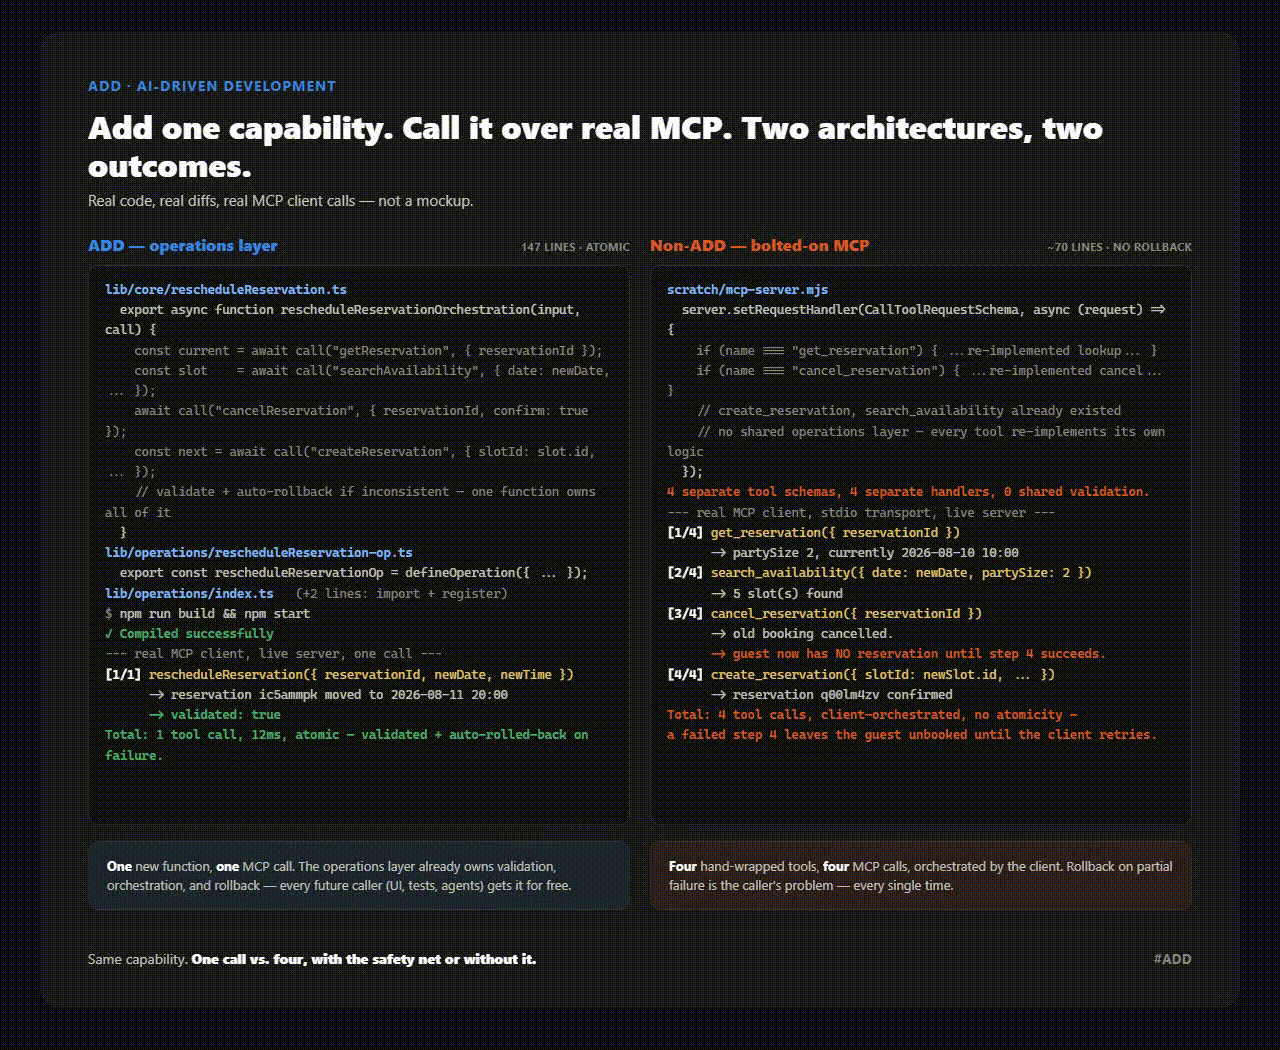
AgentBridge is a reference implementation of NavWebMcp, a protocol layered on top of WebMCP that adds progressive tool disclosure, RBAC, and composite operations. Instead of an agent stitching together searchAvailability → createReservation → getReservation, it calls one tool — book({ date, time, partySize, name }) — and gets back a validated result. The multi-step orchestration (precondition checks, the write, post-condition validation, and a compensating rollback on failure) runs invisibly behind that single call.
On connect, an agent sees only 8 lightweight navigation/meta tools (~180 tokens total) — explore, search, describe_tool, invoke, load_tools, unload_tools, getContext, getCapabilities. The other 48 business operations across reservations, CRM, front-office, tasks, housekeeping, and finance are discovered on demand and either invoked directly or promoted to native tools — so registry size never inflates the cost of connecting. getContext and getCapabilities, called in parallel right after connecting, tell the agent who the user is and exactly what their role permits before it explores anything, so it can ask the user one consolidated question instead of a drip-feed of prompts. Every operation carries a role list (customer, support, admin) checked at every call boundary, and destructive operations carry an enforced confirmation gate.
The same 48 operations are exposed identically over two surfaces from one registry: in-page WebMCP (session-cookie auth, for browser-native agents) and MCP Streamable HTTP (bearer-token auth, for external agents connecting with no browser at all). That second point matters more than it sounds: hostVipGuest, a 7-step chain spanning CRM and front-desk, has no UI in this app whatsoever — there is nothing a click-driven tool could even target — yet it's fully callable over MCP HTTP because the tool was never built to depend on a rendered page. It's designed to work identically whether the connecting client is Claude Code, Claude Desktop, MCP Inspector, ChatGPT, or OpenAI's Codex — the orchestration runs in-process against the same handler code no matter who's calling.
We proved it against a working demo: a hospitality platform with 56 operations, three composite tools, three role-scoped demo users, and a live audit log streamed over SSE.
How we built it
Next.js 15 (App Router, React 19) and TypeScript, with Zod as the single source of truth for both runtime validation and JSON Schema generation on both surfaces. @modelcontextprotocol/sdk plus mcp-handler provide the MCP Streamable HTTP transport; zod-to-json-schema converts the same Zod shapes for in-page WebMCP tool registration. Playwright and Vitest back the test and benchmark harnesses.
The core design decision was keeping orchestration surface-agnostic: lib/core/book.ts, seatGuest.ts, and hostVipGuest.ts take a call function as a dependency and know nothing about HTTP, cookies, or bearer tokens. The browser wrapper injects serverCall (fetch("/api/call"), cookie auth); the MCP operation injects makeDispatch(ctx) (in-process, bearer auth). Same business logic, same validation, same RBAC — the only thing that changes is what's plugged into one function parameter. Adding a new operation means writing one file in lib/operations/ and registering it in one index — it then appears on both surfaces automatically with disclosure, RBAC, and audit logging already wired.
Following AOD/ADD, the process itself was: write the intent (what the protocol needed to guarantee) before writing code, delegate implementation to agents against that spec, and independently verify — most concretely, by insisting every number in the README's benchmark tables come from an actual measured run (scripts/bench.mjs, scripts/speedbase.mjs, n=5, real MCP transport, real headless browser) rather than an estimate.
Challenges we ran into
Getting progressive disclosure right without breaking usability was the hardest design problem — too little detail at connect time and the agent flails; too much and the token savings evaporate. The explore/search/describe_tool split (navigate by path, discover by pattern, fetch schema only when needed) came out of iterating on that trade-off.
Keeping the two surfaces genuinely equivalent — not just superficially similar — meant RBAC, confirmation gates, and audit logging all had to live at the operation-registry level rather than in either surface's adapter, or they'd have silently drifted apart the first time someone touched only one of the two files.
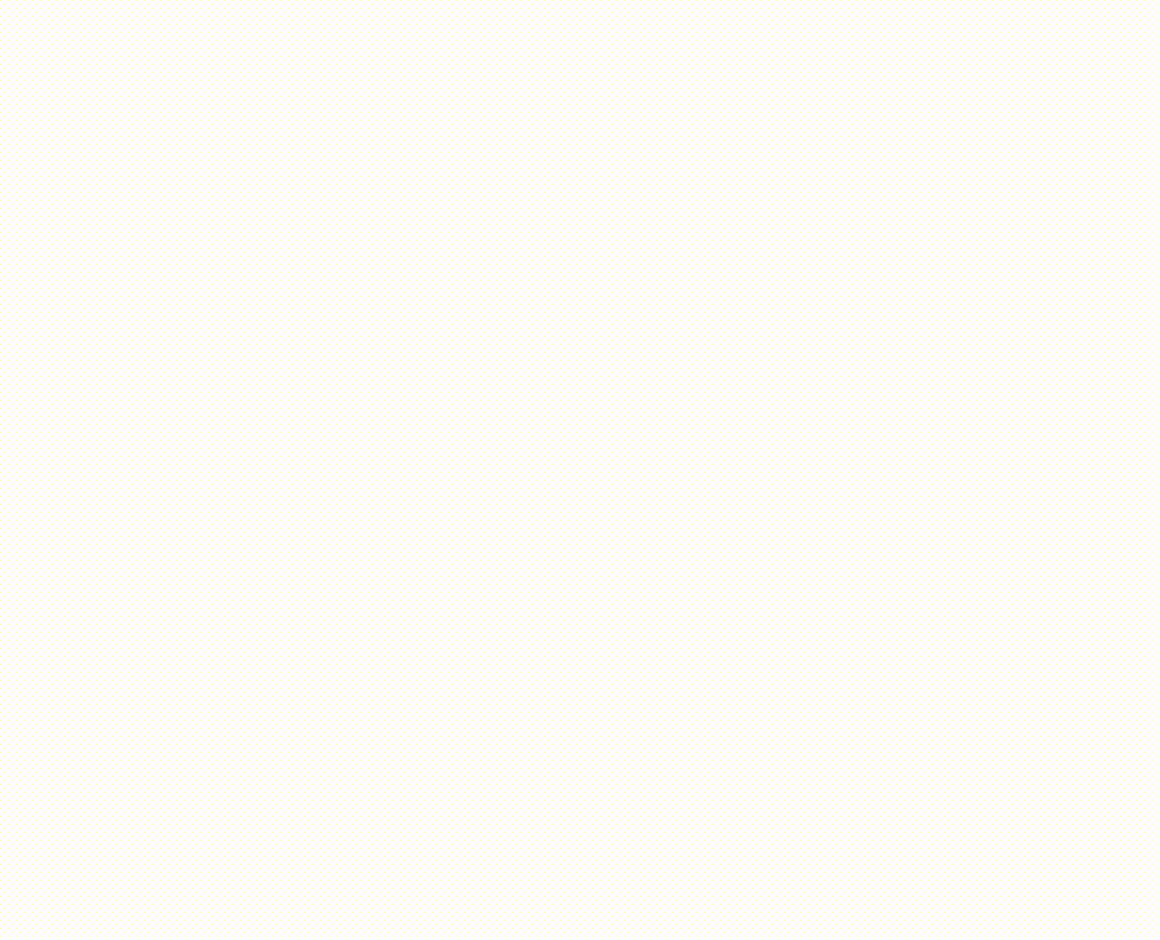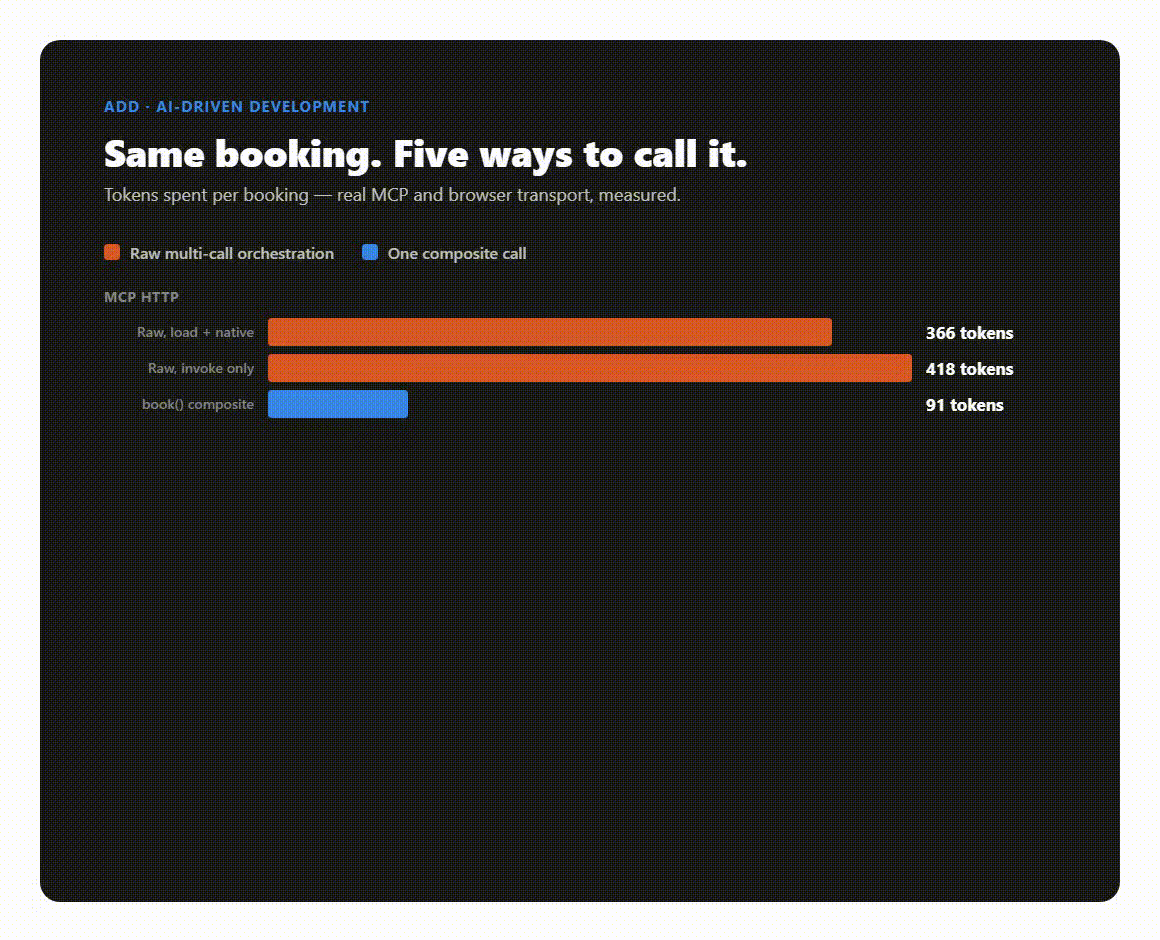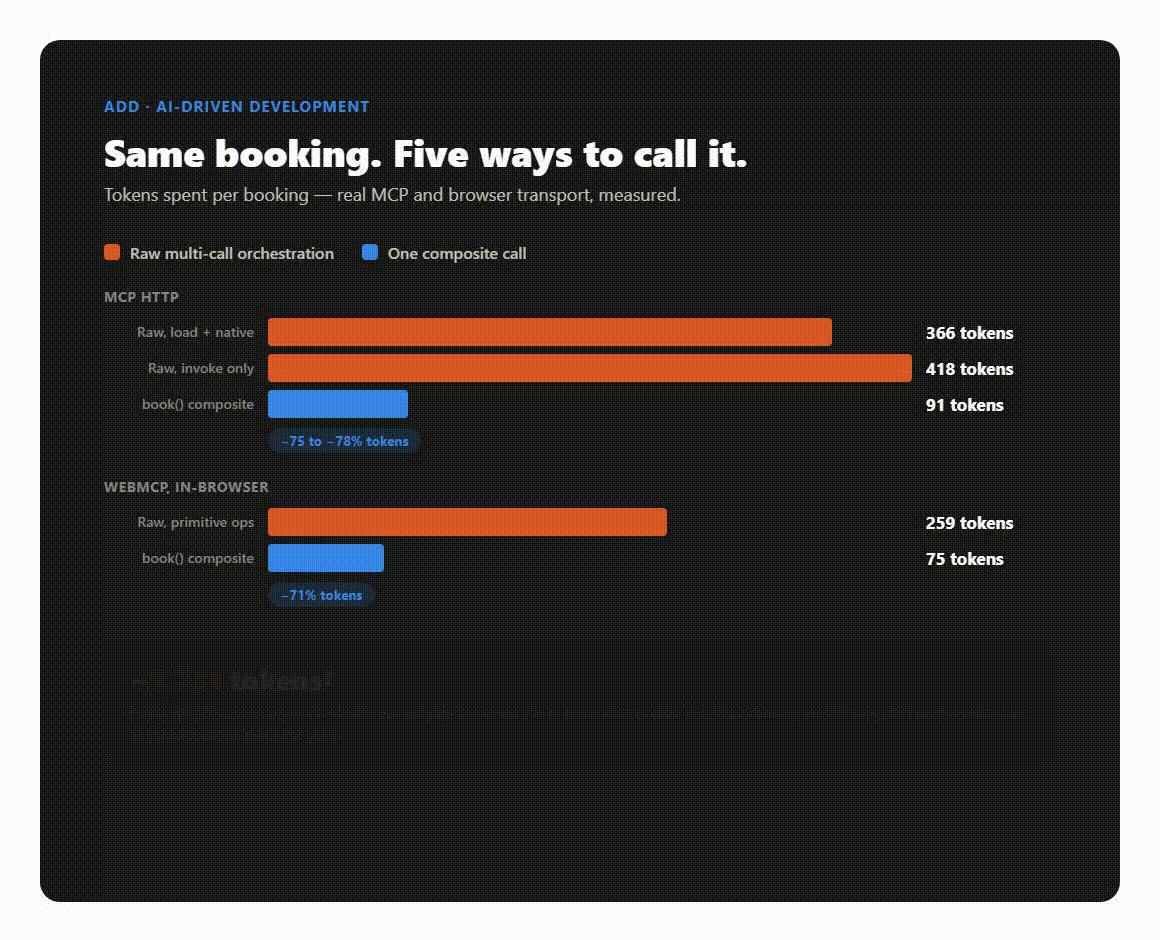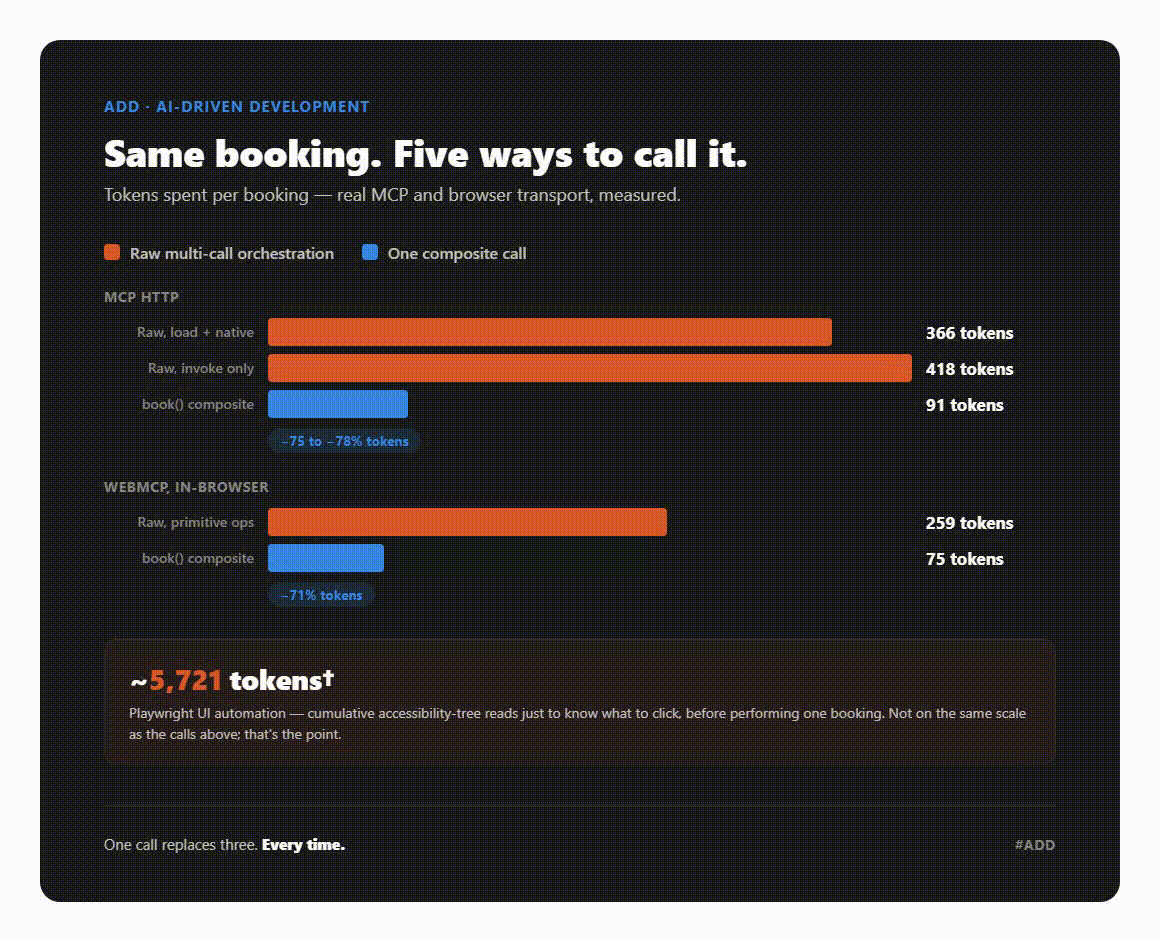
Benchmarking honestly was its own challenge: it's easy to produce numbers that flatter the architecture. We insisted on comparing against a real Playwright browser-automation lane, not a hypothetical one, which is also what surfaced the finding that mattered most — hostVipGuest has no Playwright row at all, because there's no UI for it to drive. That's not a benchmark gap, it's a demonstration of the actual capability boundary of UI automation versus tool calls.
Versioning also took more thought than expected: a single version number couldn't distinguish "the protocol contract changed" from "this role's tool set changed," so getCapabilities() deliberately returns two separate fields — a hand-bumped protocolVersion and an automatically computed, role-scoped capabilityHash — so agents can tell which kind of change happened and react accordingly.
Accomplishments that we're proud of
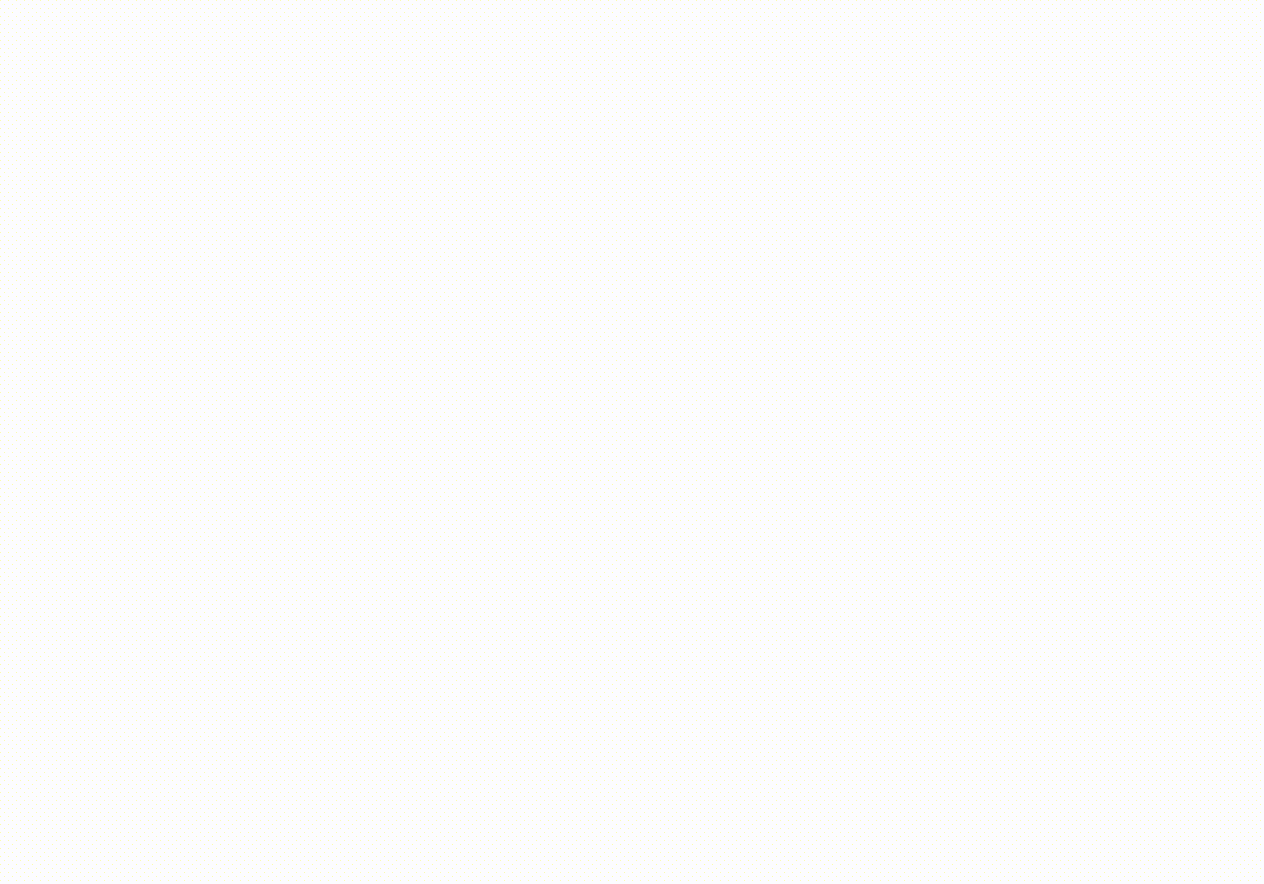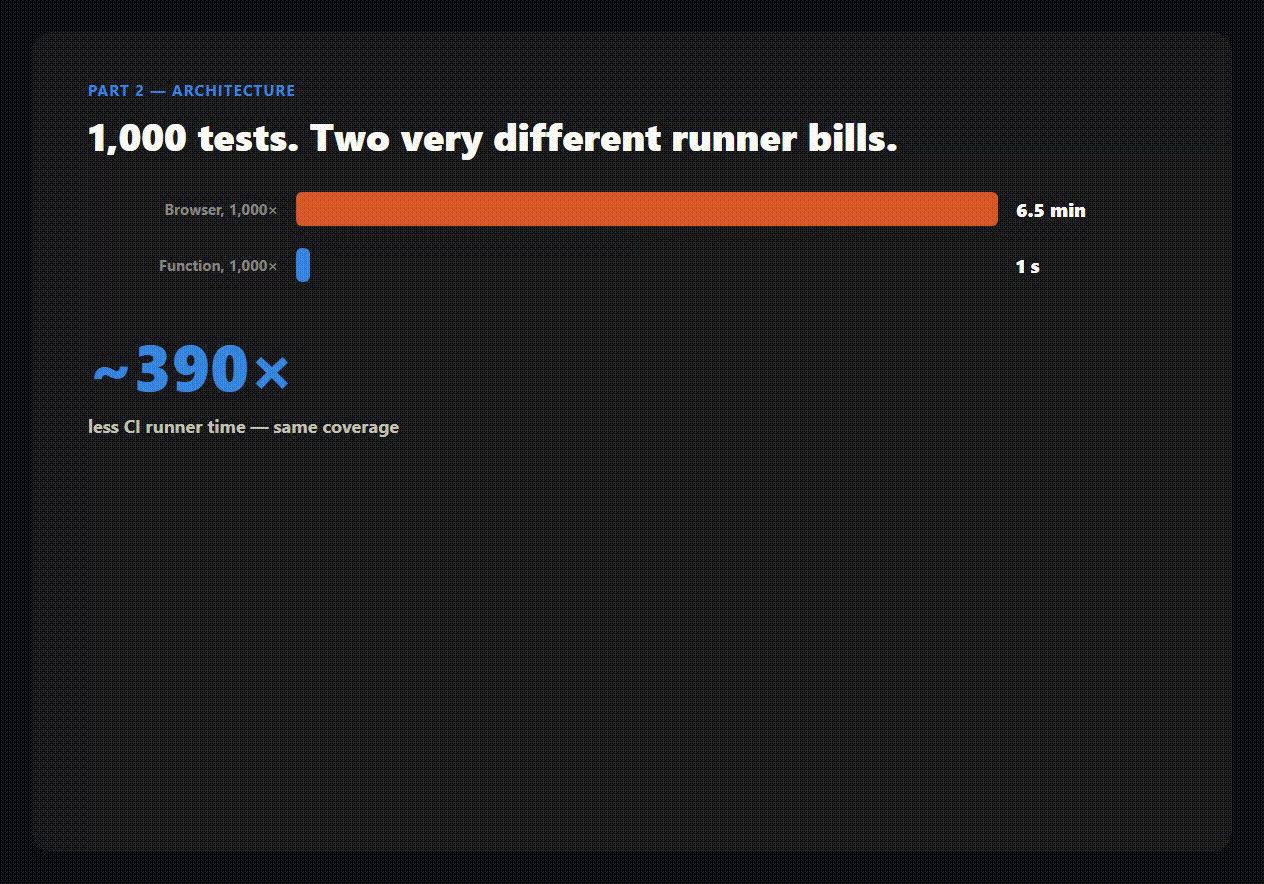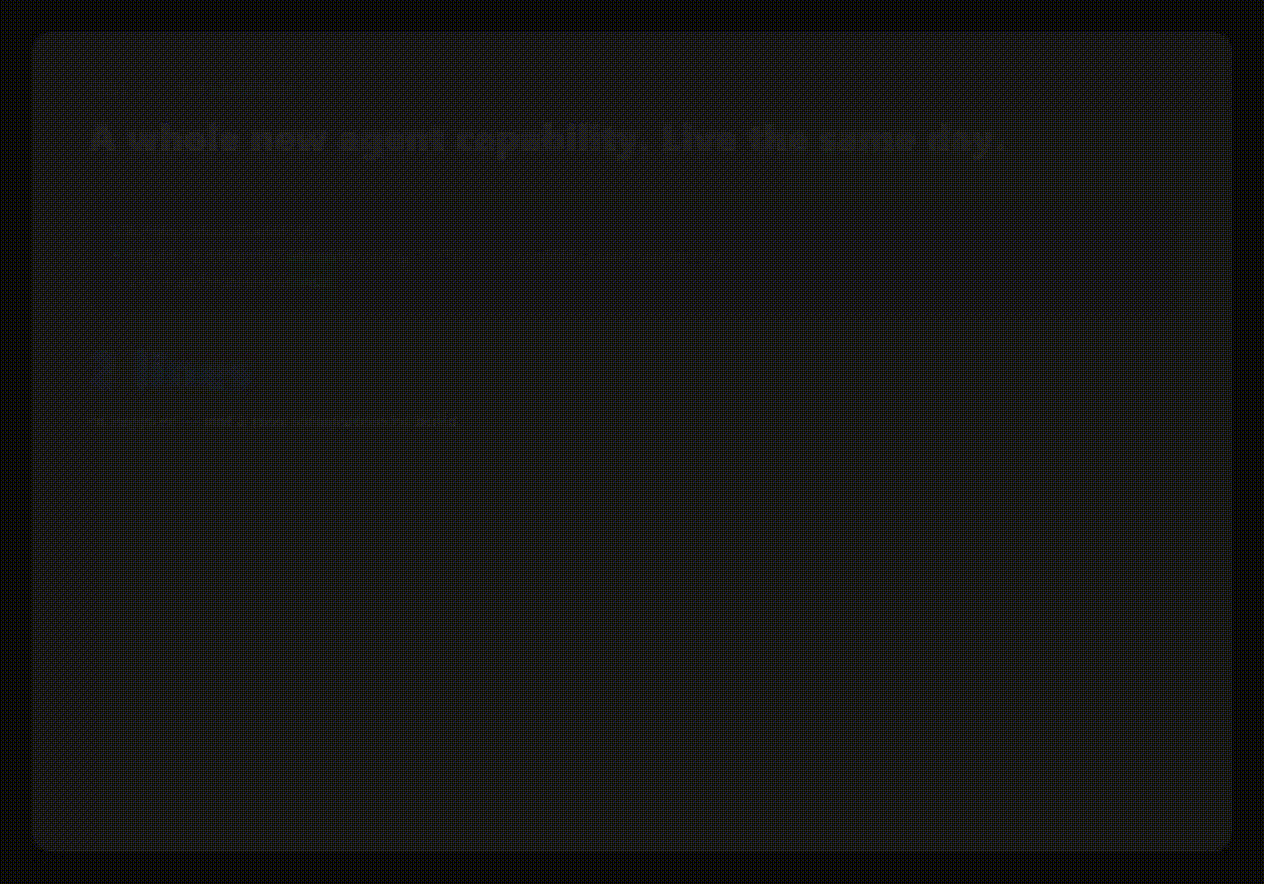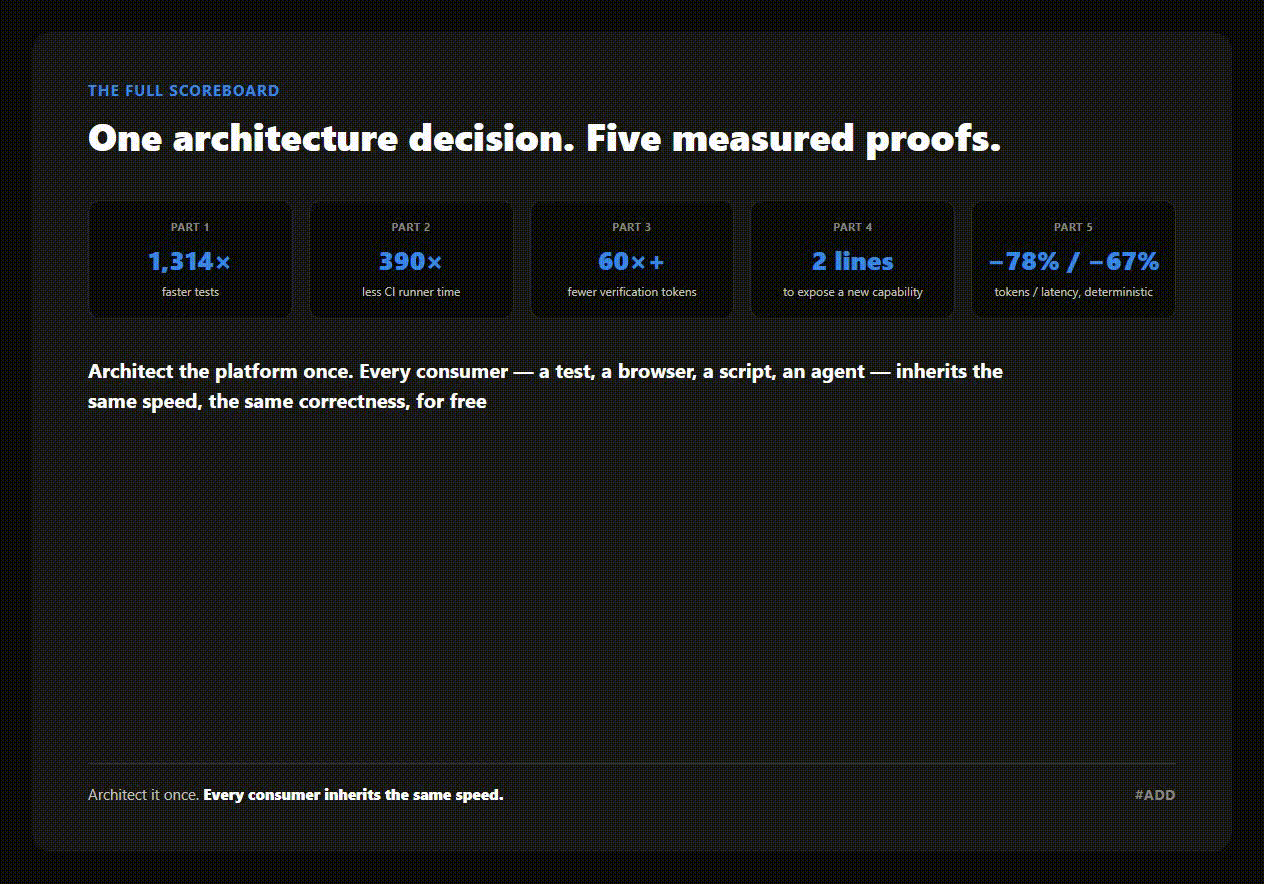
The benchmark numbers are real, not estimated, and they're strong: composite calls cut tokens by 72–87% and latency by 67–88% versus raw multi-call orchestration, on both the MCP HTTP and in-browser WebMCP surfaces, with 5/5 reliability across every lane. The saving compounds with orchestration complexity — a 7-op CRM+front-desk chain collapses to a single call with an 87% latency reduction — and testing the operation layer directly is up to 1,300× faster than driving the same flow through a browser.
We're equally proud of the fact that the protocol holds up structurally: one operation registry drives two authentication models, two transports, and two calling conventions with zero duplicated business logic, and RBAC/audit/disclosure behavior is provably identical on both because they're enforced in one shared place, not two.
And we shipped the consumer half of the protocol too — skills/navwebmcp-agent/, a portable agent skill for connecting efficiently, discovering operations, and preferring composite calls — versioned independently of the server implementation, so it isn't tied to this one demo app.
What we learned
The biggest lesson: token and latency cost in agent tooling is mostly a protocol design problem, not a model problem. The same LLM calling the same underlying operations pays wildly different costs depending on whether it has to orchestrate three calls itself or one — that's architecture, not intelligence.
We also learned that "the agent needs a browser" is frequently just false. Once business logic is expressed as composable server-side operations, the browser becomes one optional caller among several rather than a load-bearing dependency — which is what let hostVipGuest exist at all without any UI, and what makes the MCP HTTP surface a first-class citizen rather than a fallback.
Finally, disciplined versioning (separating a global protocol version from a per-role capability hash) is worth the extra field from day one — retrofitting that distinction after agents are already caching a single version number is much harder than designing it in up front.
What's next for NavWebMcp
The next protocol version closes the one asymmetry left in 1.0.0: the in-page WebMCP surface currently registers only the three composite tools, while MCP HTTP already exposes the full 56-operation registry. Bringing the browser surface to parity — under the same capabilityHash/protocolVersion versioning discipline established in CHANGELOG.md — means any of the 48 primitive operations becomes callable in-page, not just the composites, with no change to RBAC or audit behavior on either side.
Alongside that, we're growing the composite-operation catalogue itself. book, seatGuest, and hostVipGuest prove the pattern; the next version adds more multi-step chains wherever a workflow currently costs an agent 3+ raw calls, using the same precondition/write/postcondition/rollback shape so every new composite inherits the same guarantees rather than reinventing them.
To use the next version, adopting an operation doesn't change: define it once in lib/operations/, register it in the index, and it appears on both surfaces automatically with disclosure, RBAC, and audit logging already wired — that adoption path is deliberately stable across protocol bumps so upgrading the version doesn't force a rewrite of operations.
We're not waiting for a second demo app to validate any of this: we're already starting rollout onto our production platform, applying the same registry + composite-operation pattern there. That's the real test of NavWebMcp — proving the architecture holds up under a live platform's operations and roles, not just this reference hospitality app — and what we learn from that rollout is what will shape the next protocol version's actual feature set, rather than speculative additions.
We're also designing a pre-fetch layer that removes discovery from the LLM's reasoning path entirely. Today, narrowing 48 operations down to the relevant few still costs an explore/search round-trip the agent has to reason about. The next feature sends the user's raw text straight to NavWebMcp — no LLM involved at that step — where a vector DB matches it against operation embeddings and returns just the functions that semantically fit. Only that pre-filtered set is handed to the LLM as context, via a hook into the same API surface. It's progressive disclosure taken one step further: instead of the agent spending a call and a reasoning pass to figure out which tools it needs, the platform decides that deterministically before the LLM is even invoked, so the model's first real action is calling the right tool rather than searching for it.
Built With
- ai-agents
- bearer-token
- css
- html5
- http
- javascript
- json-schema
- mcp-server
- model-context-protocol
- next-js
- node.js
- oauth
- playwright
- rbac
- react
- rest-api
- server-sent-events
- typescript
- vitest
- webmcp
- zod

Log in or sign up for Devpost to join the conversation.