Naratta AI — Project Story
Inspiration
Every great podcast or movie trailer starts the same way: someone researches a topic, writes a script, casts voices, and produces the final audio — a process that usually takes a small team days. We wanted to know if an autonomous agent could compress that entire pipeline into minutes, without faking any of the steps. [Personalize: add the actual moment/conversation that sparked this — e.g., a specific podcast you love, a frustration with how long audio production takes, a "what if an agent just did this" moment during brainstorming.]
What it does
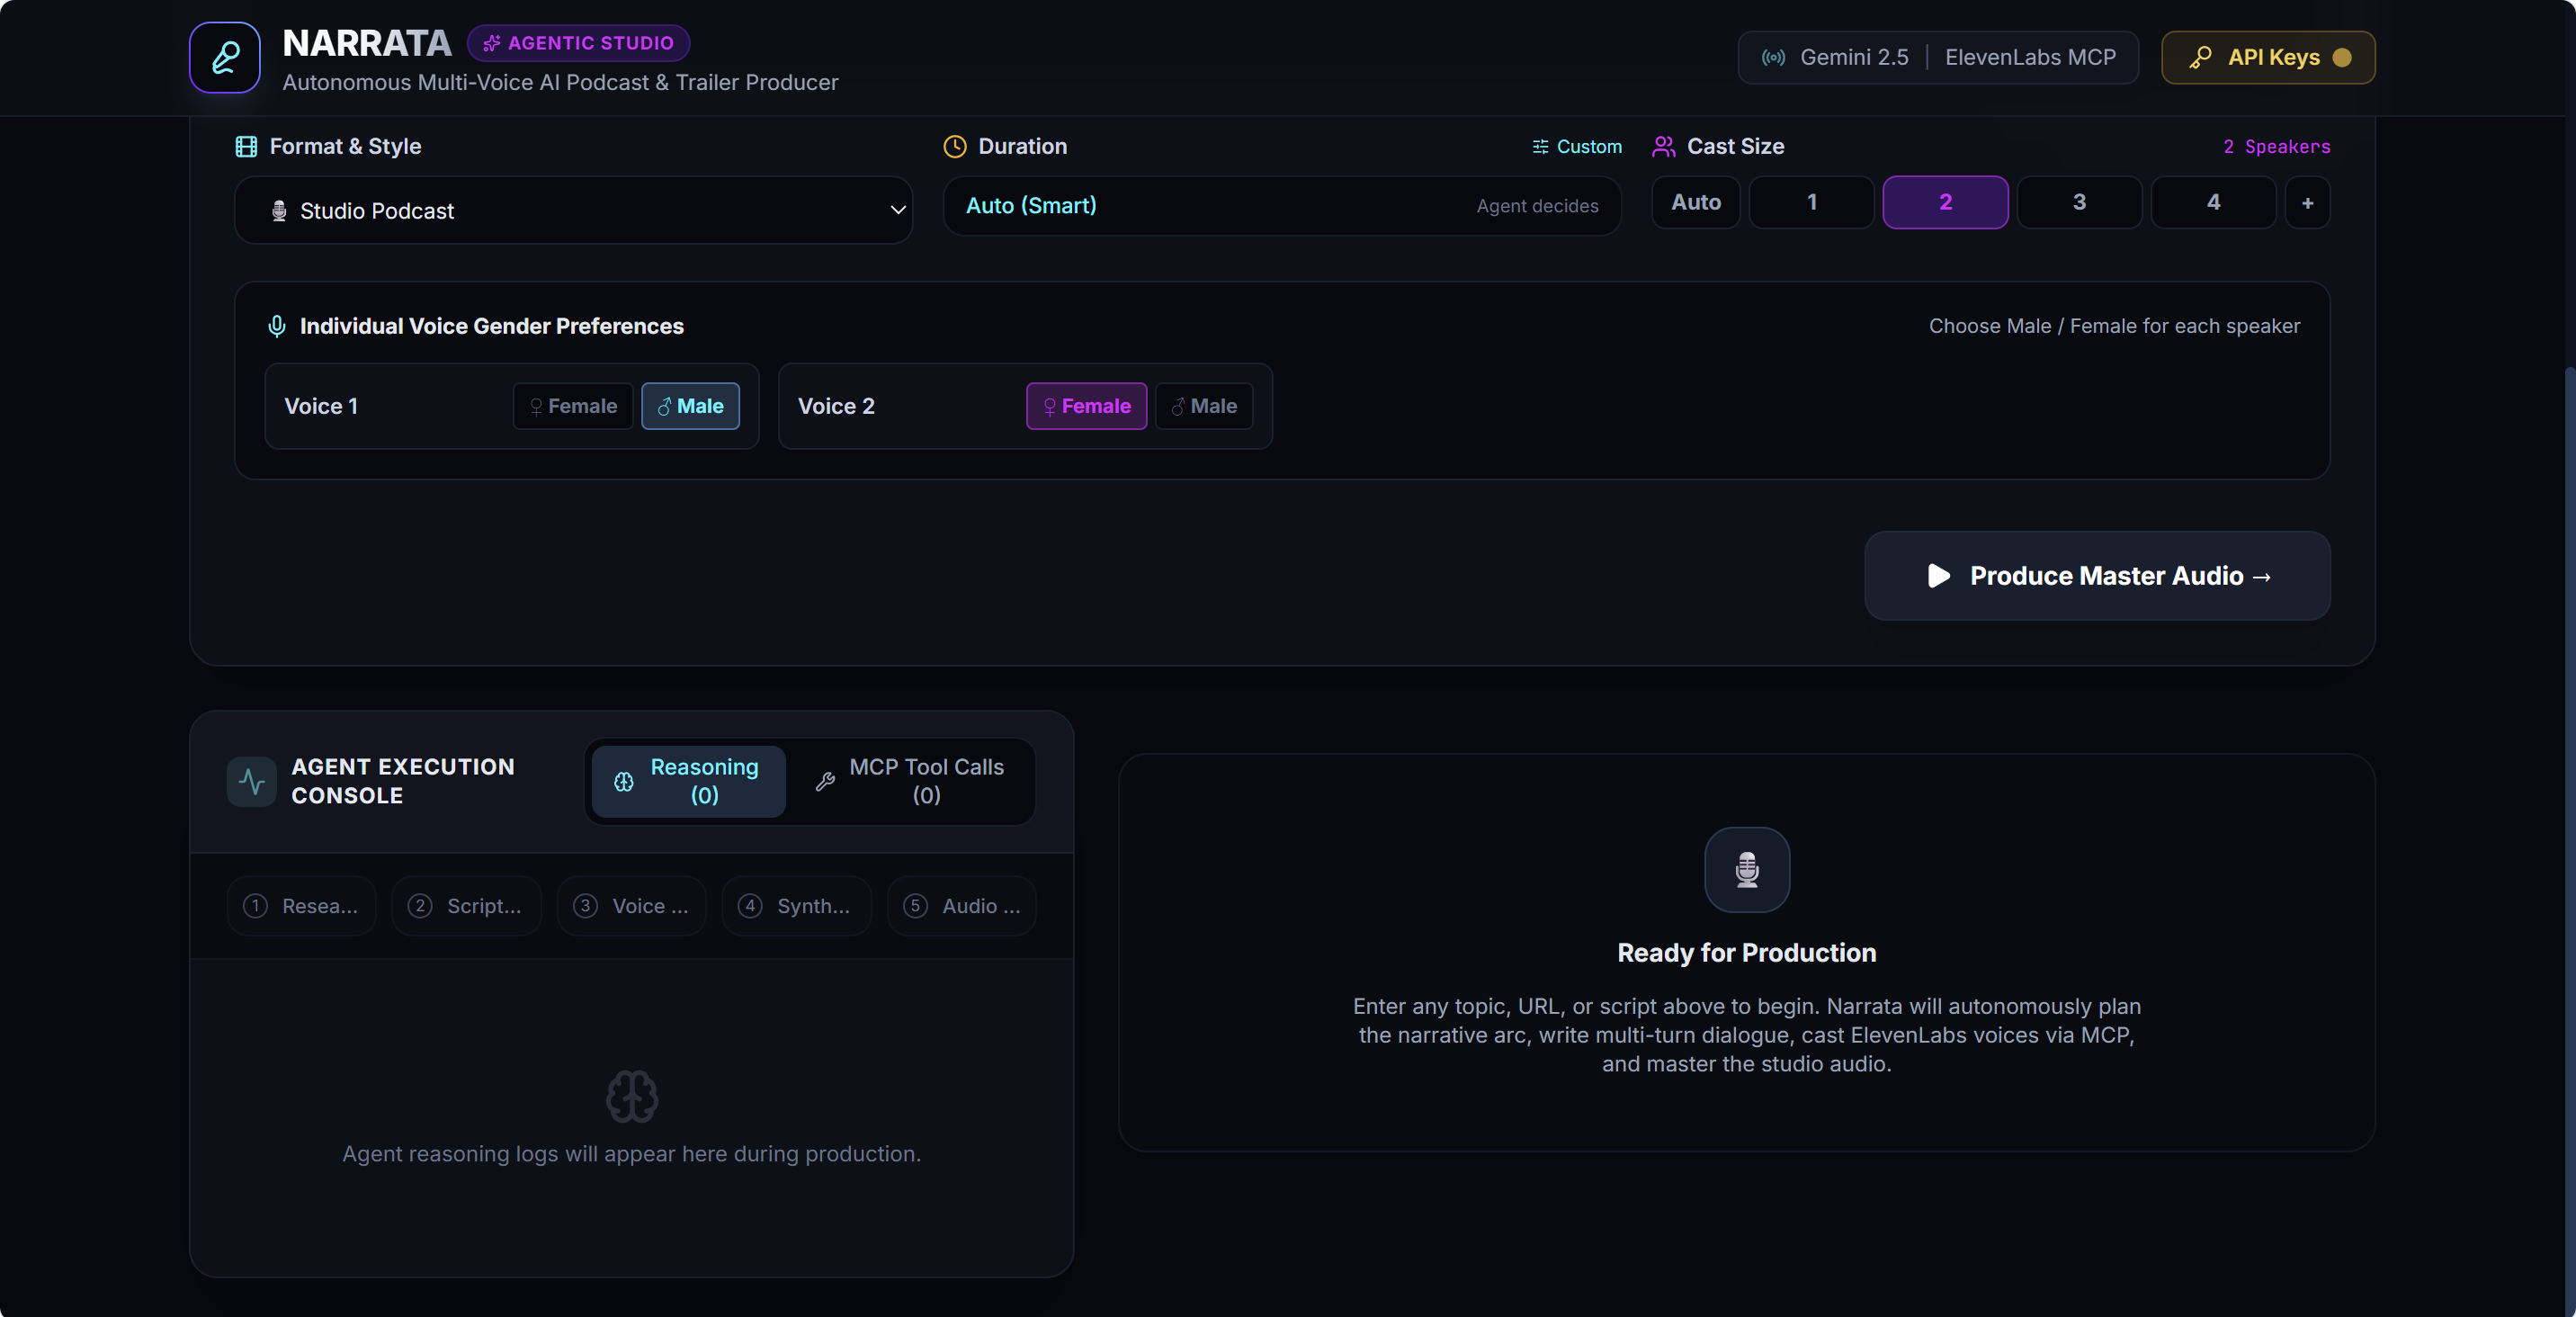
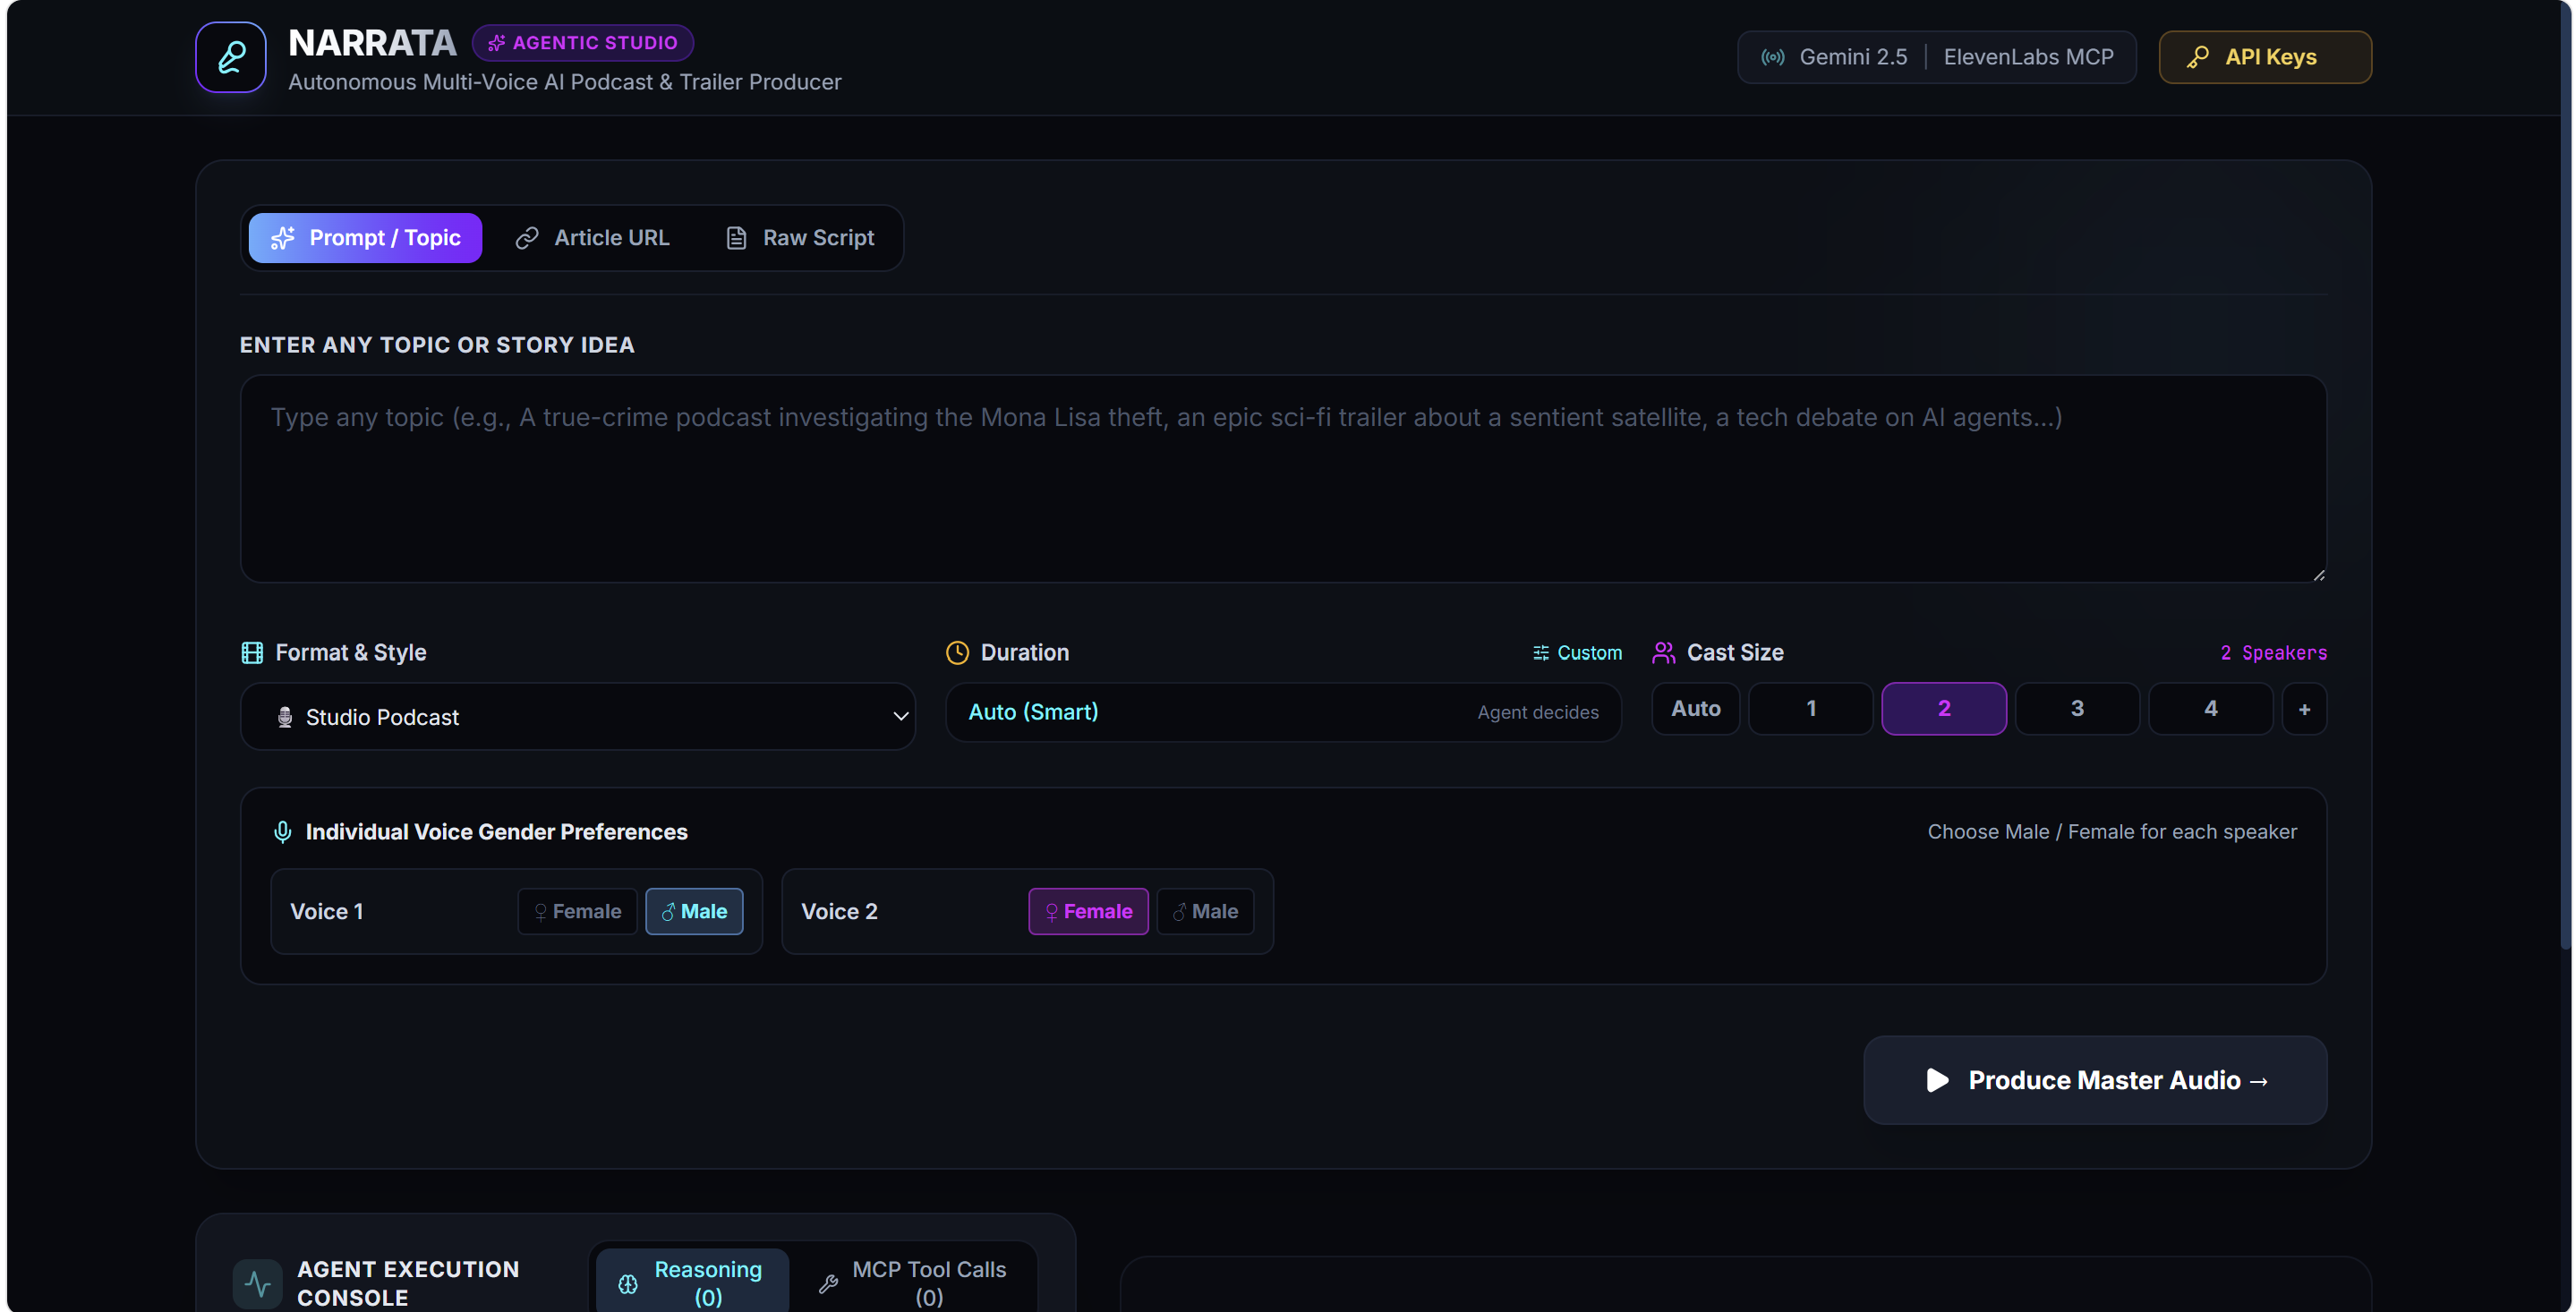
Naratta AI takes a topic, an article URL, or a raw script and turns it into a finished, multi-voice audio production — a podcast segment or trailer-style narration — with zero hardcoded content. Under the hood, an agent:
- Researches and outlines the topic (or ingests your script directly)
- Writes a full narration/dialogue script, tagging each line by speaker
- Dynamically casts voices for each speaker based on tone and character
- Synthesizes each line as real audio via ElevenLabs
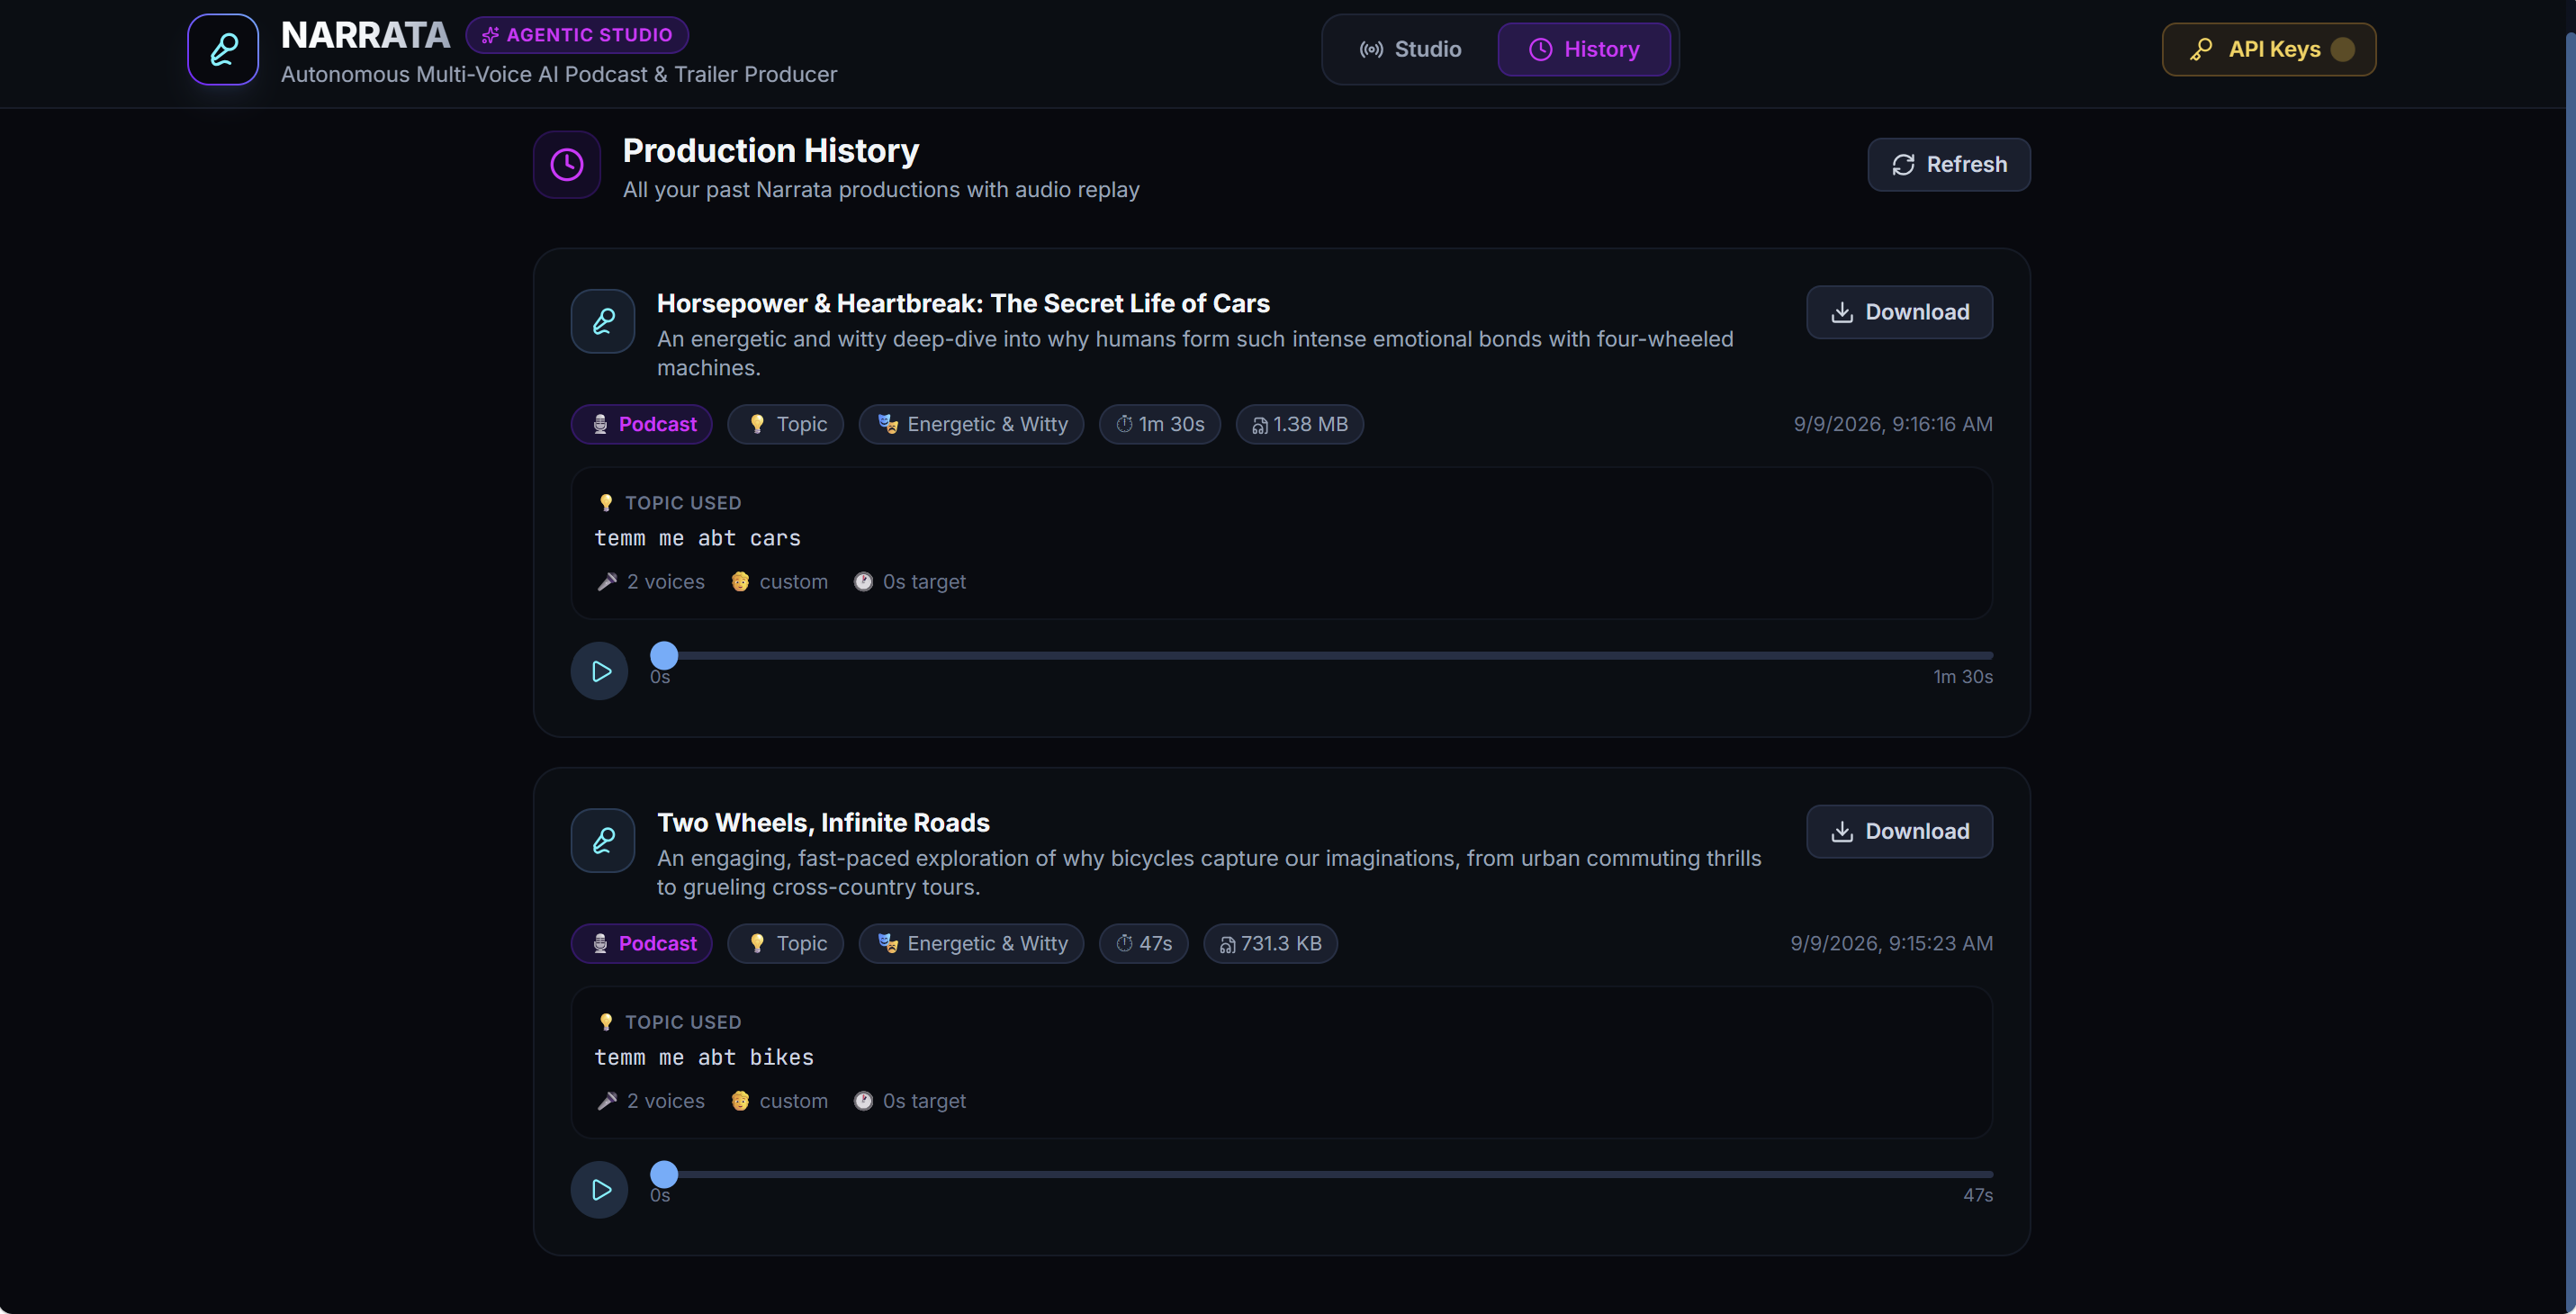
- Assembles everything into one polished audio file, playable and downloadable in the app
Every run produces genuinely different output — different research, different script, different voice cast — because nothing is pre-written or cached.
How we built it
The agent is orchestrated with Google Cloud Agent Builder (built on the Agent Development Kit), using Gemini as the reasoning engine for research, outlining, and scriptwriting. We integrated ElevenLabs' MCP server as a first-class tool the agent calls directly — for voice selection and text-to-speech synthesis — rather than wrapping it behind a custom API layer, so the agent genuinely decides which voice fits which character at runtime.
The frontend is a lightweight web app that surfaces the agent's plan and progress step-by-step (research → script → cast → synthesize → assemble), so the "thinking" is visible rather than a black box. The backend stitches the per-line audio clips from ElevenLabs into a single coherent file with natural pacing, and the whole thing is deployed on Cloud Run so it's a real, live, shareable demo. [Personalize: name your actual stack choices — Python vs Node, any libraries for audio stitching, GCP services used, team roles.]
Challenges we ran into
- Keeping voice casting dynamic. It would have been far easier to hardcode a narrator voice ID and call it done — the real challenge was having the agent query ElevenLabs' voice catalog and reason about which voice fits a character's tone, every single run.
- Audio stitching and pacing. Concatenating dozens of short TTS clips into something that sounds like one coherent recording — not a robotic sequence of disconnected lines — took real tuning of pause lengths and volume normalization.
- Making the agent's reasoning visible. Judges and users needed to see the agent plan and act in steps, not just receive a final MP3, so we had to design the orchestration to expose intermediate state rather than treat it as an opaque pipeline.
Accomplishments that we're proud of
- A genuinely functional, end-to-end agent — not a demo with a pre-recorded "wow" moment — that produces different, real output every time it runs.
- A real integration with a partner MCP server used as an actual tool call, not a mocked stand-in.
- A deployed, live app anyone can try with their own topic.
- [Personalize: add a specific output you were proud of — a topic that produced a surprisingly good script or voice pairing.]
What we learned
Building on Agent Builder and Gemini together taught us how much value comes from designing an agent's steps to be inspectable — exposing the plan, the script, and the casting decisions builds trust in a way a single black-box output never could. We also learned firsthand how much production quality in audio work comes down to the unglamorous middle step (pacing and stitching), not just the flashy generation step.
What's next for Naratta AI
- Support for longer-form content: full podcast episodes and multi-scene trailers, not just single segments.
- Background music and sound-effect layering, agent-selected based on tone.
- Multi-language narration and dubbing.
- User accounts and a library of past productions.
- Exploring additional media partner integrations (e.g., video generation) so Naratta can produce visual trailers, not just audio.
Built With
- 11labsmcp
- docker
- dvc
- envconfig
- fastapi
- geminiapi
- genaisdk
- google-cloud
- html5
- httpxsoup4
- luicidereact
- pydantic
- python
- react19&typescript
- sse
- tailwindcss
- univorn
- vite6


Log in or sign up for Devpost to join the conversation.