-
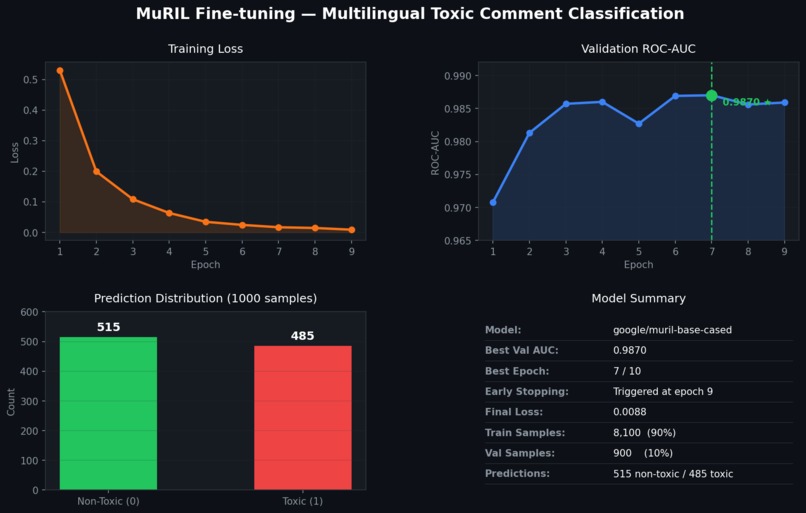
Output result :It consist of no of epoch ,accuracy and prediction information
Multilingual Toxic Comment Classification with MuRIL
Inspiration
Toxic content online doesn't respect language boundaries. In a country like India, where hundreds of millions of people express themselves in Hindi, English, and everything in between, most moderation tools are built only for English. We wanted to build something that actually works for the real, multilingual internet — where a hateful comment in Hindi is just as dangerous as one in English.
What We Learned
- Fine-tuning transformer models on domain-specific data can push validation ROC-AUC above 0.98 even on relatively small datasets (~9,000 samples)
- MuRIL significantly outperforms general multilingual models on Hindi-English mixed text because it was pre-trained specifically on Indian language corpora
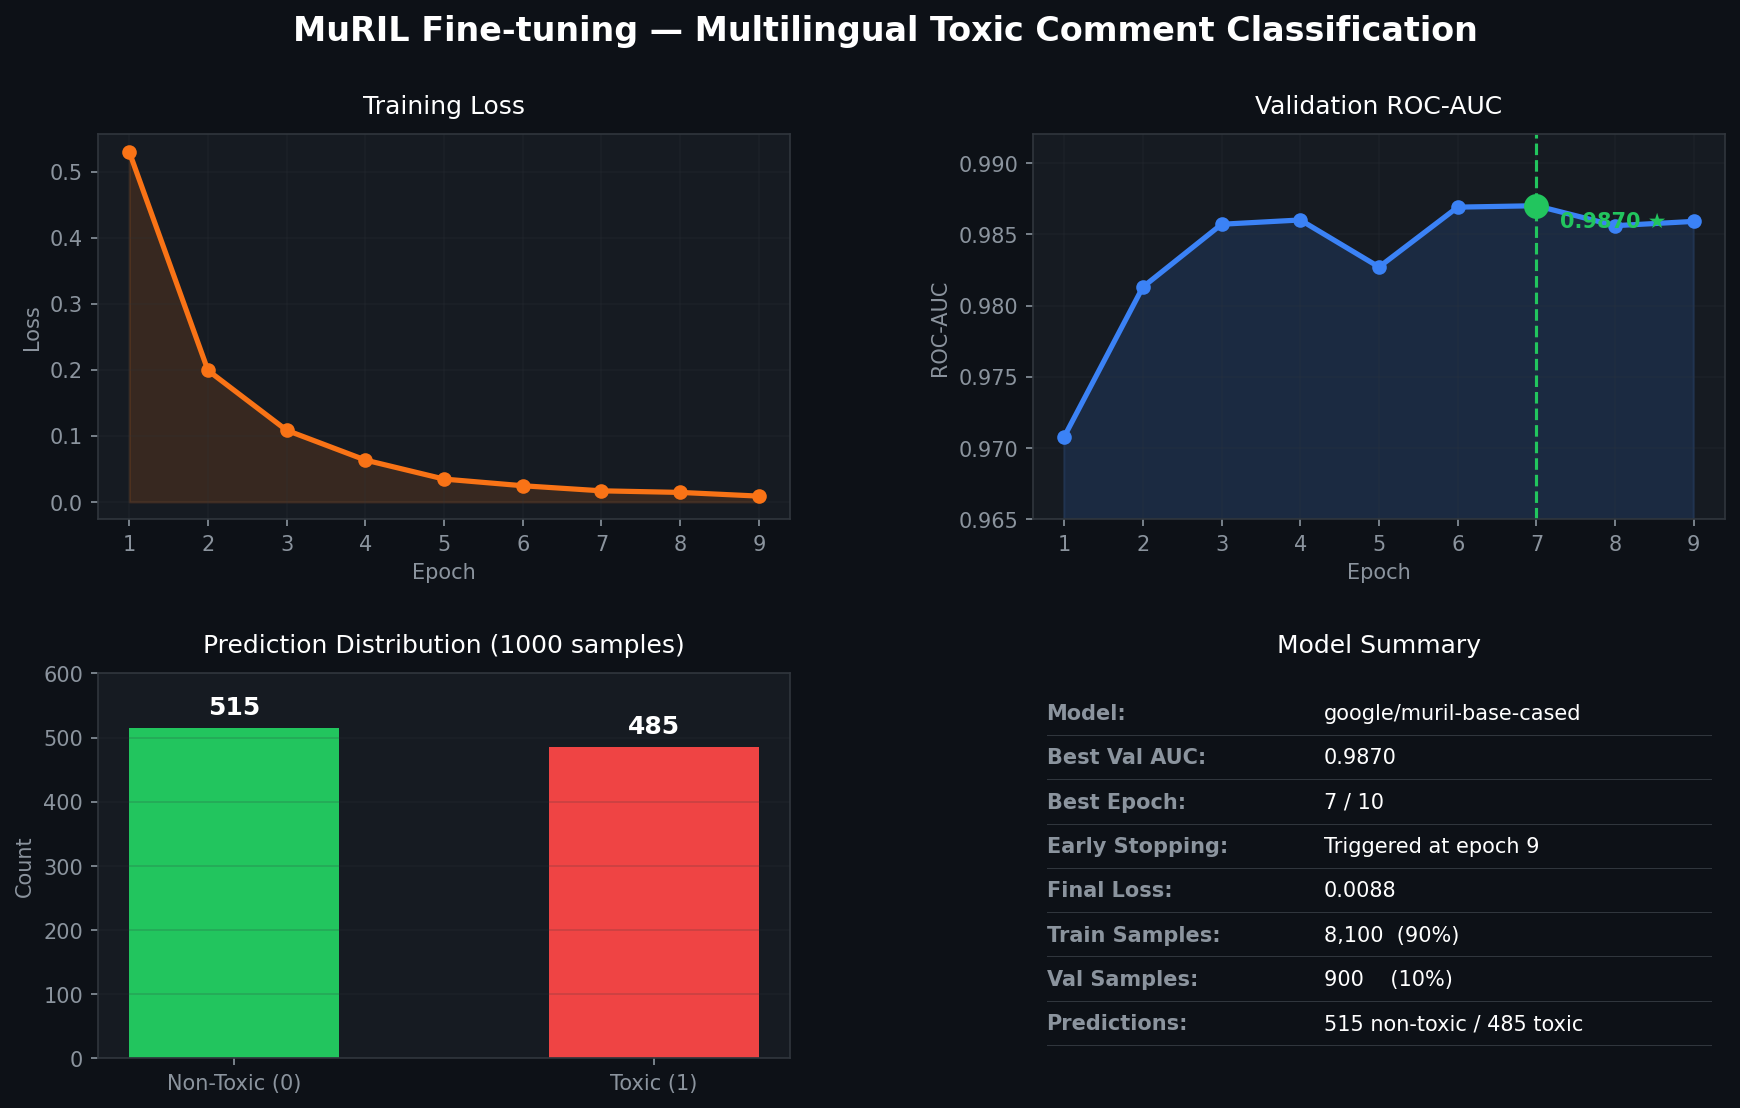
- Early stopping is critical — our model peaked at epoch 7 and began overfitting shortly after, which early stopping caught automatically
- The ROC-AUC metric is more reliable than accuracy for classification tasks because it measures the model's ability to rank toxic vs non-toxic comments across all possible thresholds, formally defined as:
$$\text{AUC} = \int_0^1 \text{TPR}(\text{FPR}^{-1}(t)) \, dt$$
How We Built It
We fine-tuned Google's MuRIL (google/muril-base-cased) — a BERT-based model
pre-trained on 17 Indian languages — on the provided labeled dataset.
Training Setup
- Model:
google/muril-base-cased - Optimizer: AdamW with weight decay
0.01 - Learning rate:
2e-5with linear warmup over 10% of steps - Batch size: 16
- Max sequence length: 128 tokens
- Train/Val split: 90/10 stratified
Training Strategy
We used early stopping with patience of 2 epochs to avoid overfitting:
$$\text{Early Stop if } \text{AUC}{epoch} < \text{AUC}{best} \text{ for 2 consecutive epochs}$$
The model converged as follows:
| Epoch | Loss | Val ROC-AUC |
|---|---|---|
| 1 | 0.5302 | 0.9708 |
| 2 | 0.1992 | 0.9813 |
| 3 | 0.1085 | 0.9857 |
| 4 | 0.0634 | 0.9860 |
| 6 | 0.0245 | 0.9869 |
| 7 | 0.0168 | 0.9870 ✓ best |
| 9 | 0.0088 | 0.9859 |
Challenges We Faced
- Windows multiprocessing: PyTorch's DataLoader with
num_workers > 0crashes on Windows — fixed by settingnum_workers=0and wrapping code inif __name__ == '__main__' - GPU setup: Getting CUDA working correctly with a brand new RTX 5050 (Blackwell architecture) required installing the right PyTorch CUDA build
- Ambiguous text: Hindi political commentary is extremely context-dependent — the same sentence can be sharp criticism or toxic hate speech depending on framing, which makes even human labeling difficult
- Code-mixed text: Many samples mixed Hindi and English mid-sentence, which traditional models handle poorly — MuRIL's Indian language pre-training was key to handling this naturally

Log in or sign up for Devpost to join the conversation.