Inspiration
On a small channel, every chatter counts, and most small streamers stream alone. That means one person has to win the boss fight and keep up with chat at the same time. Something always gives: a first-time chatter says hi and nobody answers, a question scrolls away, the raid lands in the middle of a dodge. Those viewers leave without a word, and the streamer usually never finds out who they were.
We didn't want a bot that talks for the streamer. We wanted something that helps the streamer talk to their own community: something that watches chat like a good moderator and taps them on the shoulder only when it matters.
What it does
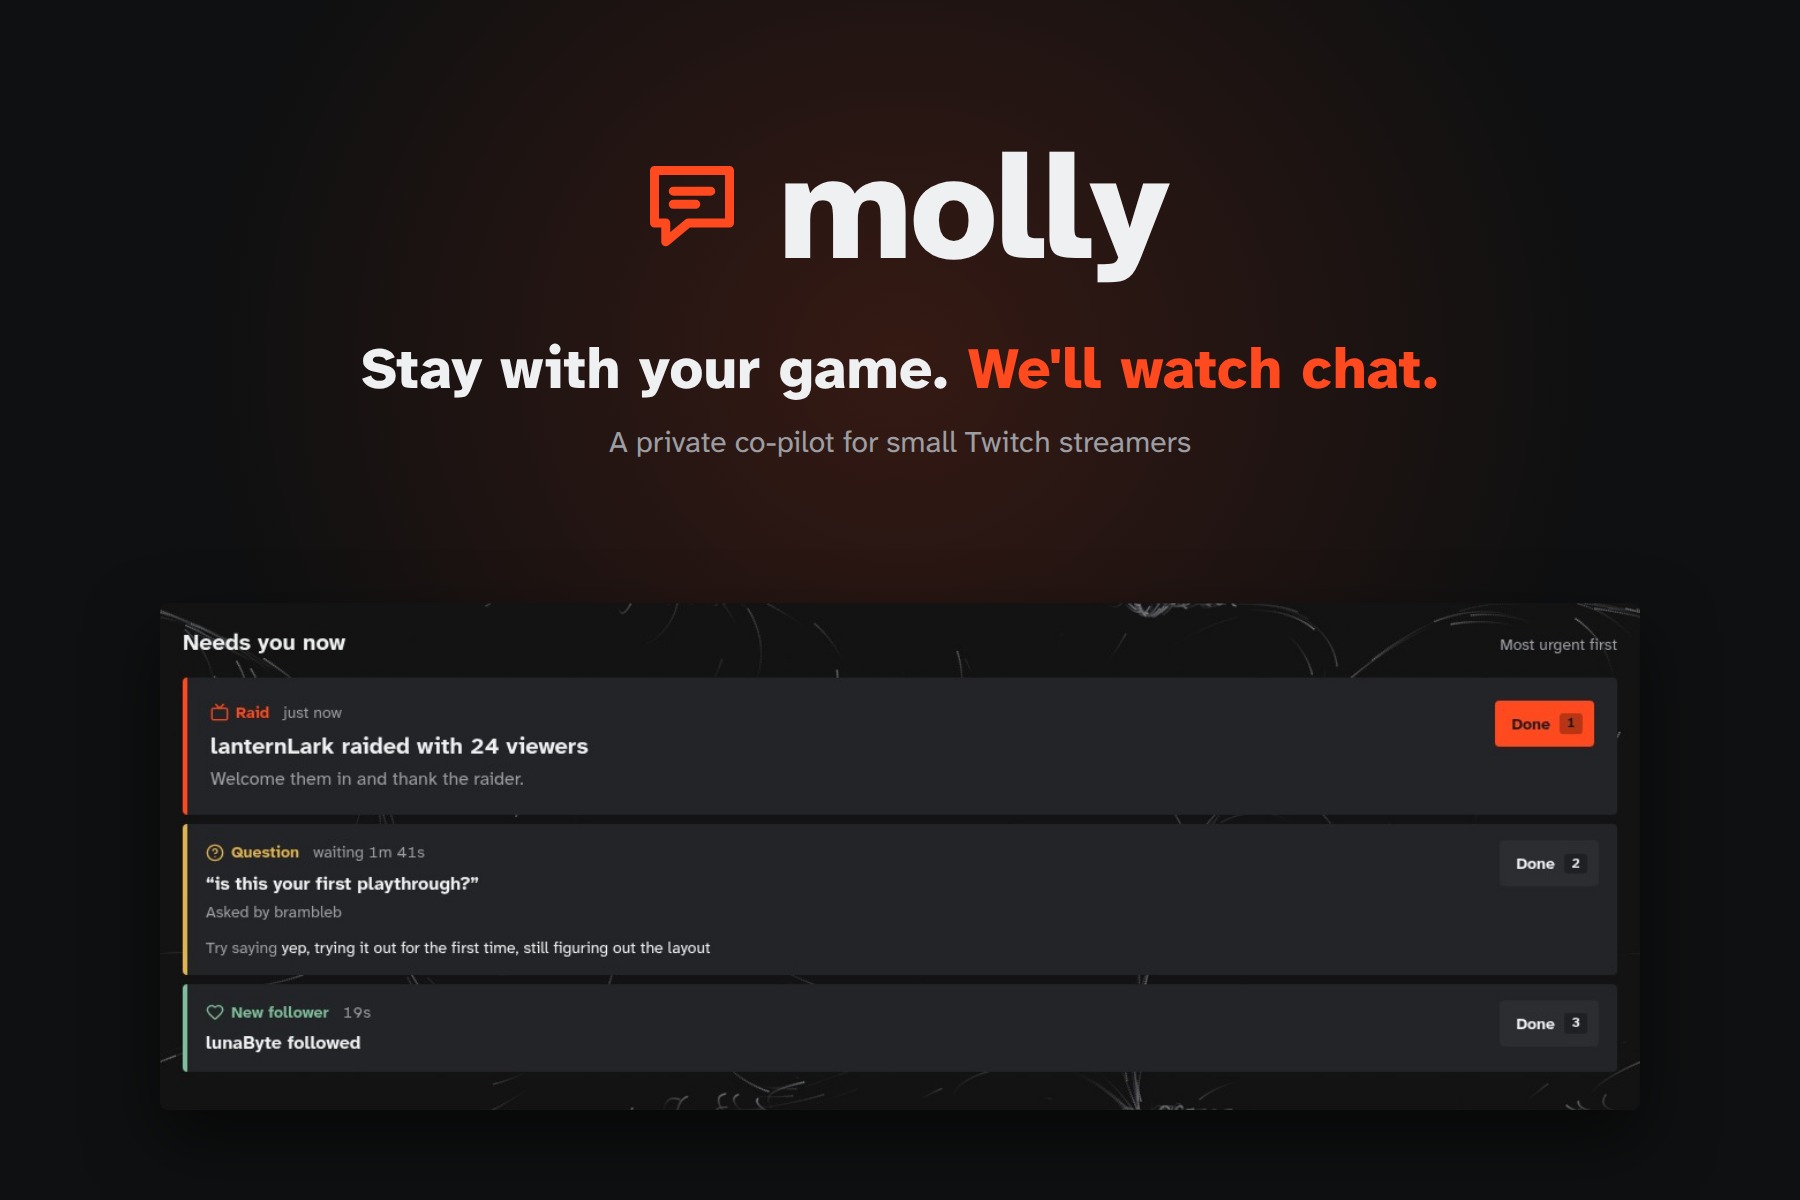
Molly runs locally and turns live chat into a short to-do list you can read at a glance:
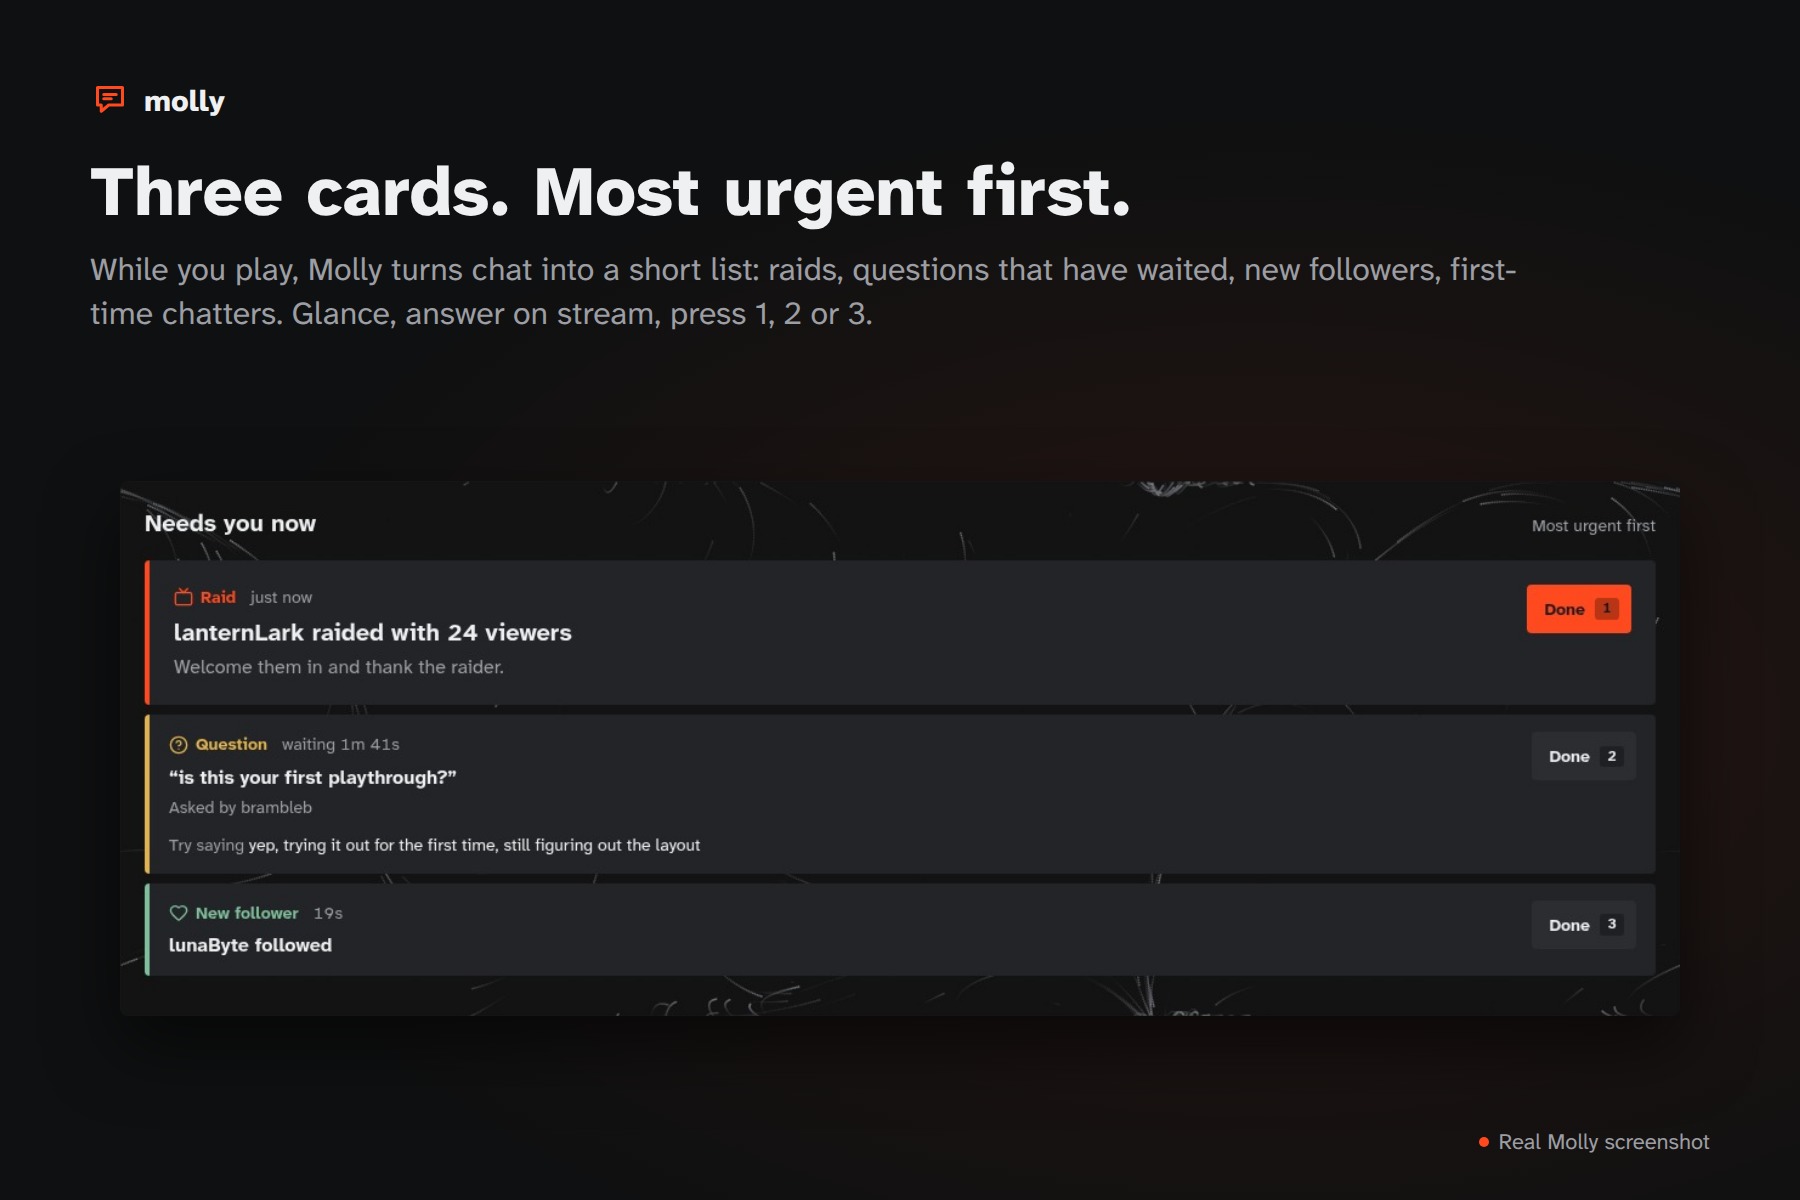
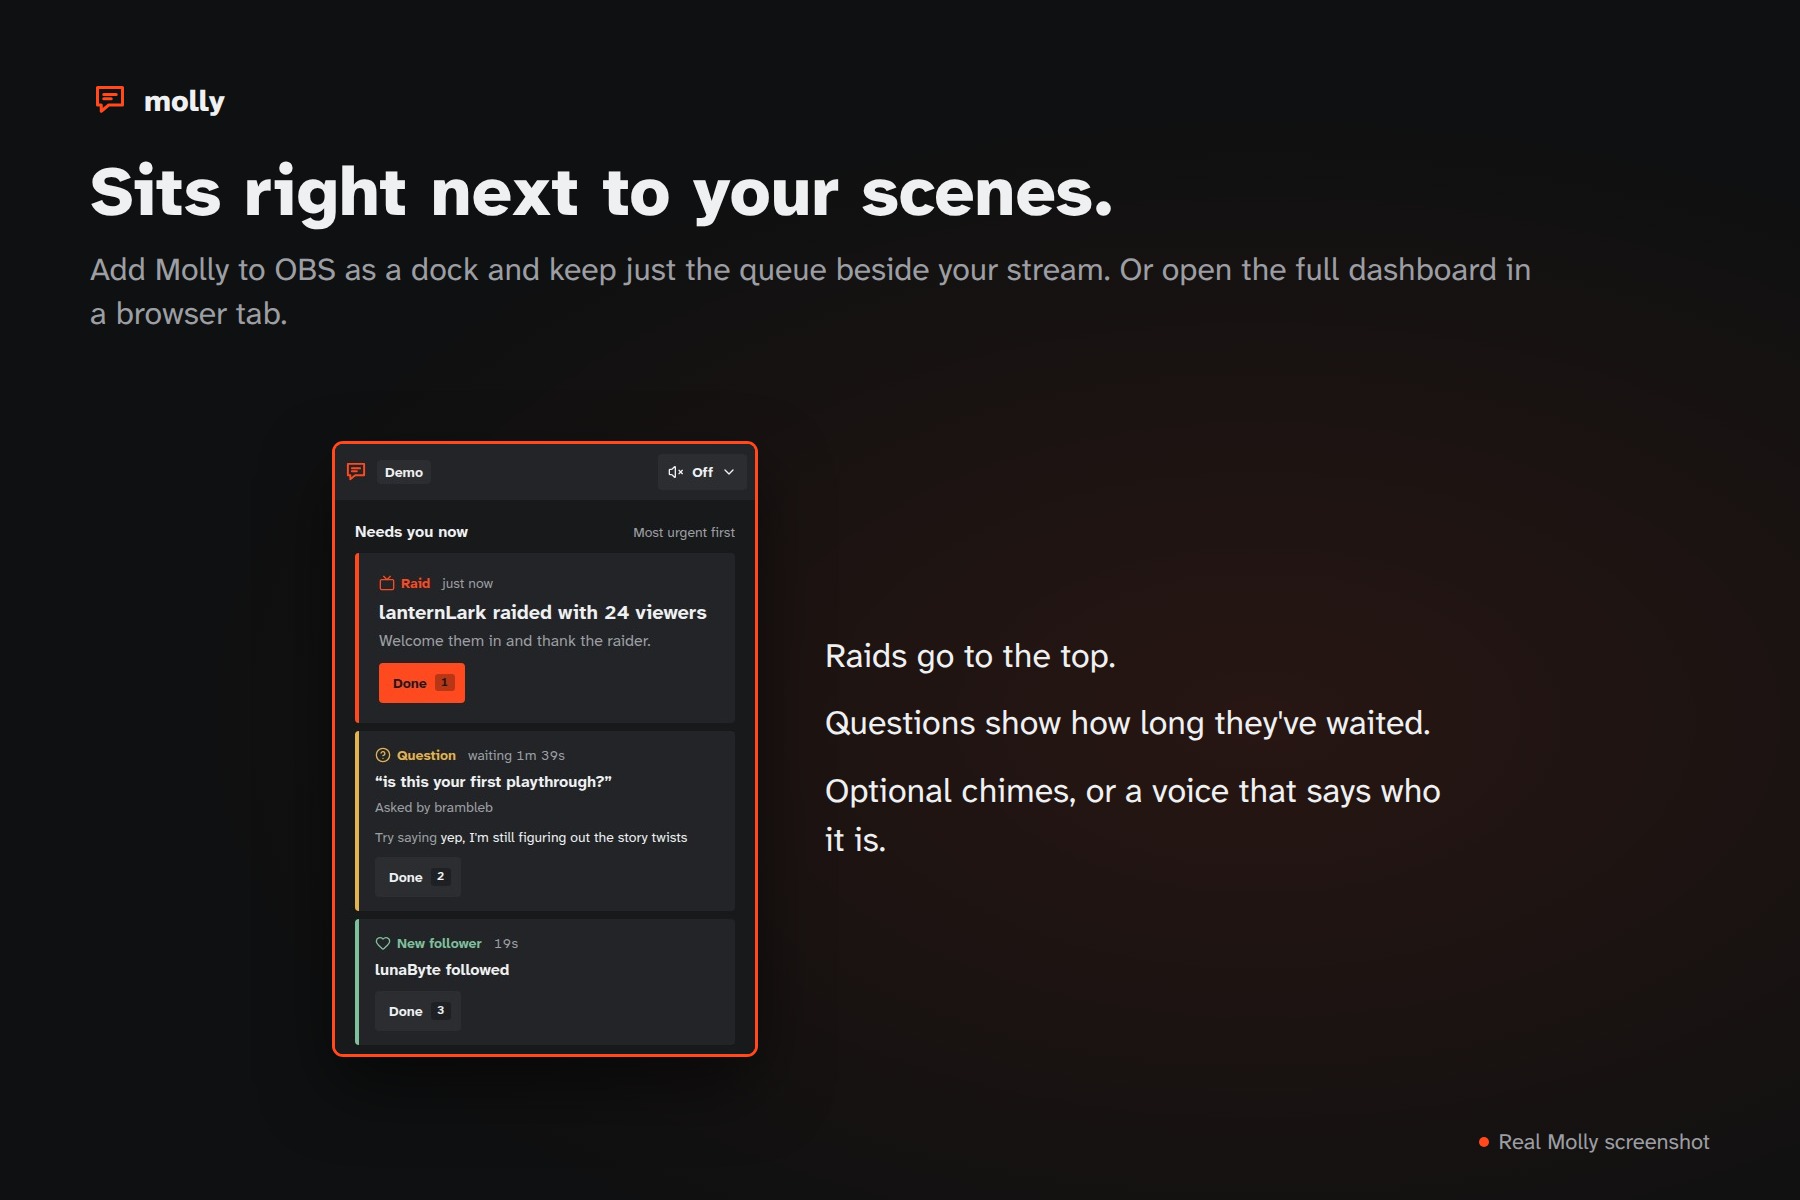
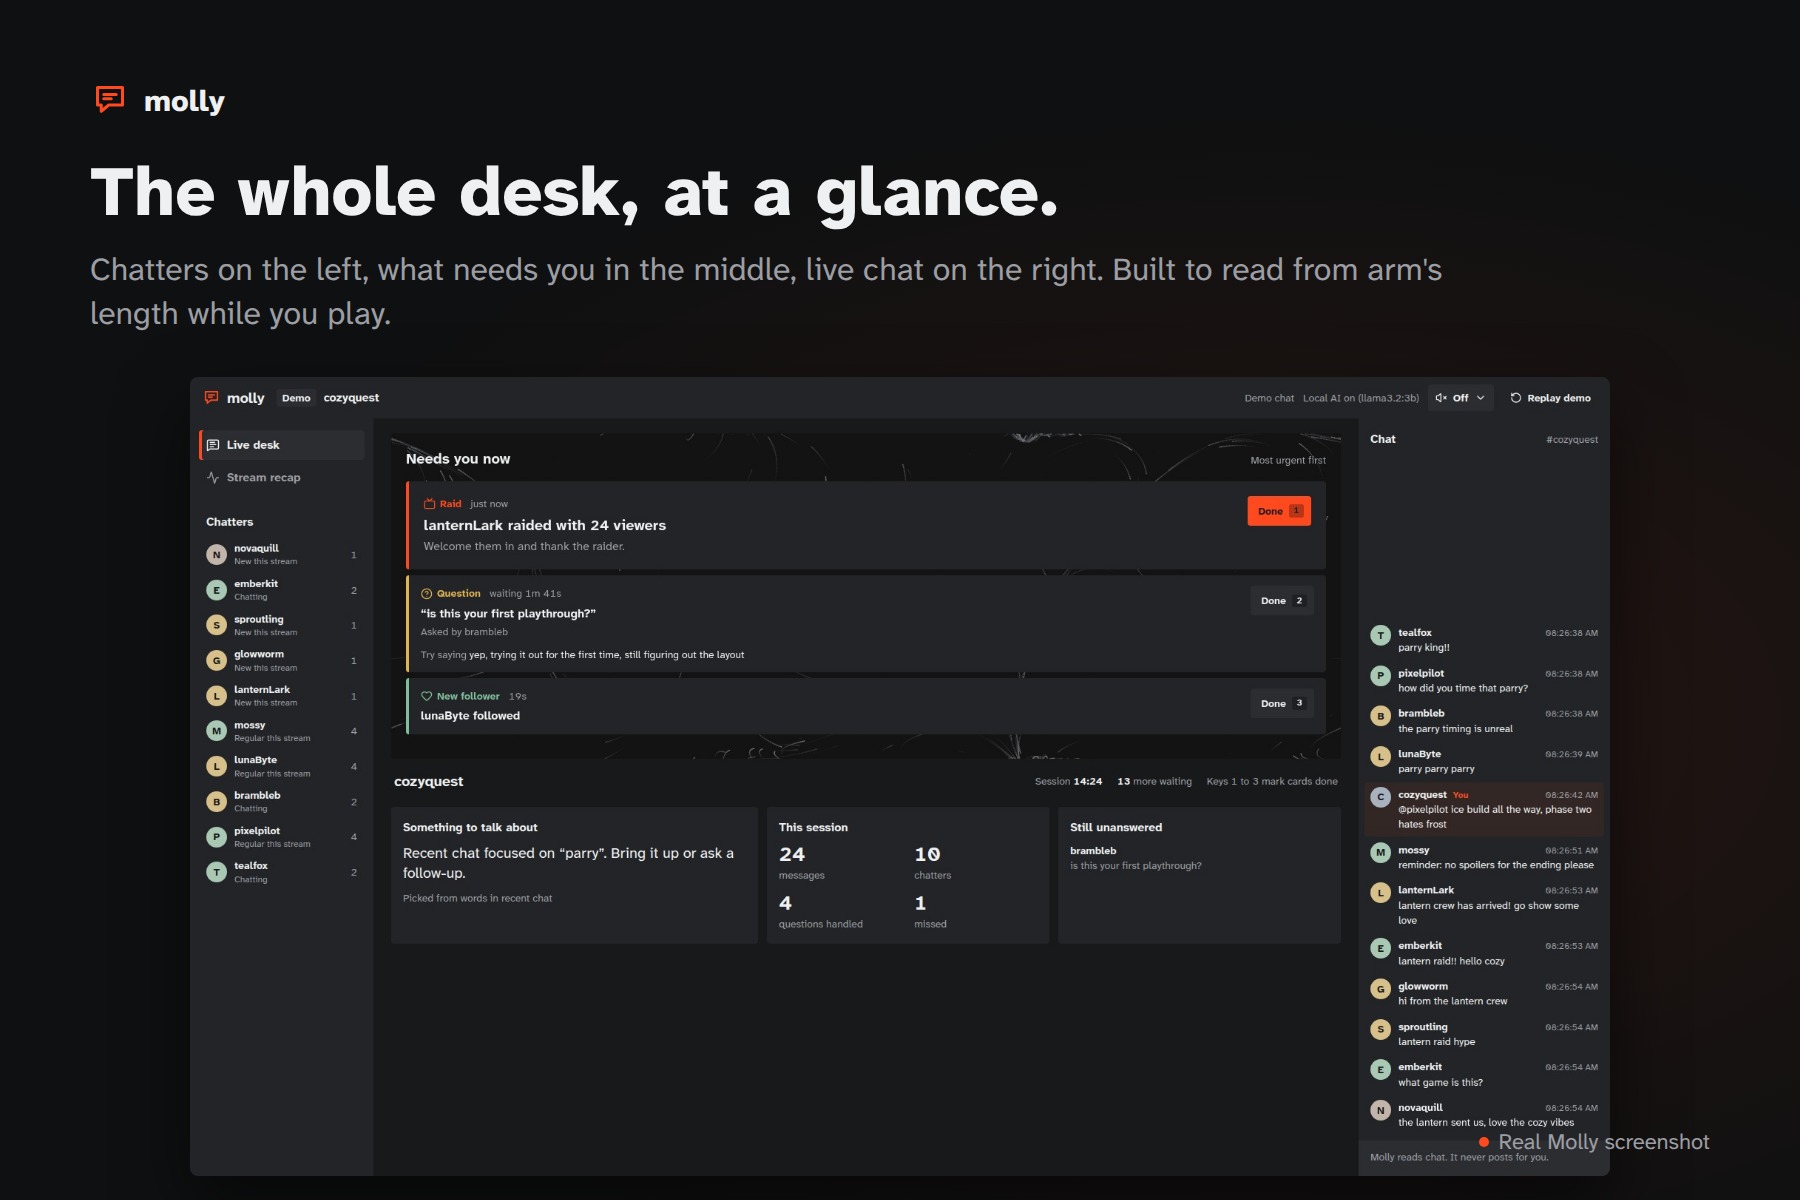
- Three cards, most urgent first. Raids come first. Questions that have waited over a minute and new follows come next, then first-time chatters, then chat spikes and quiet stretches. Only the top three show; the rest wait behind them.
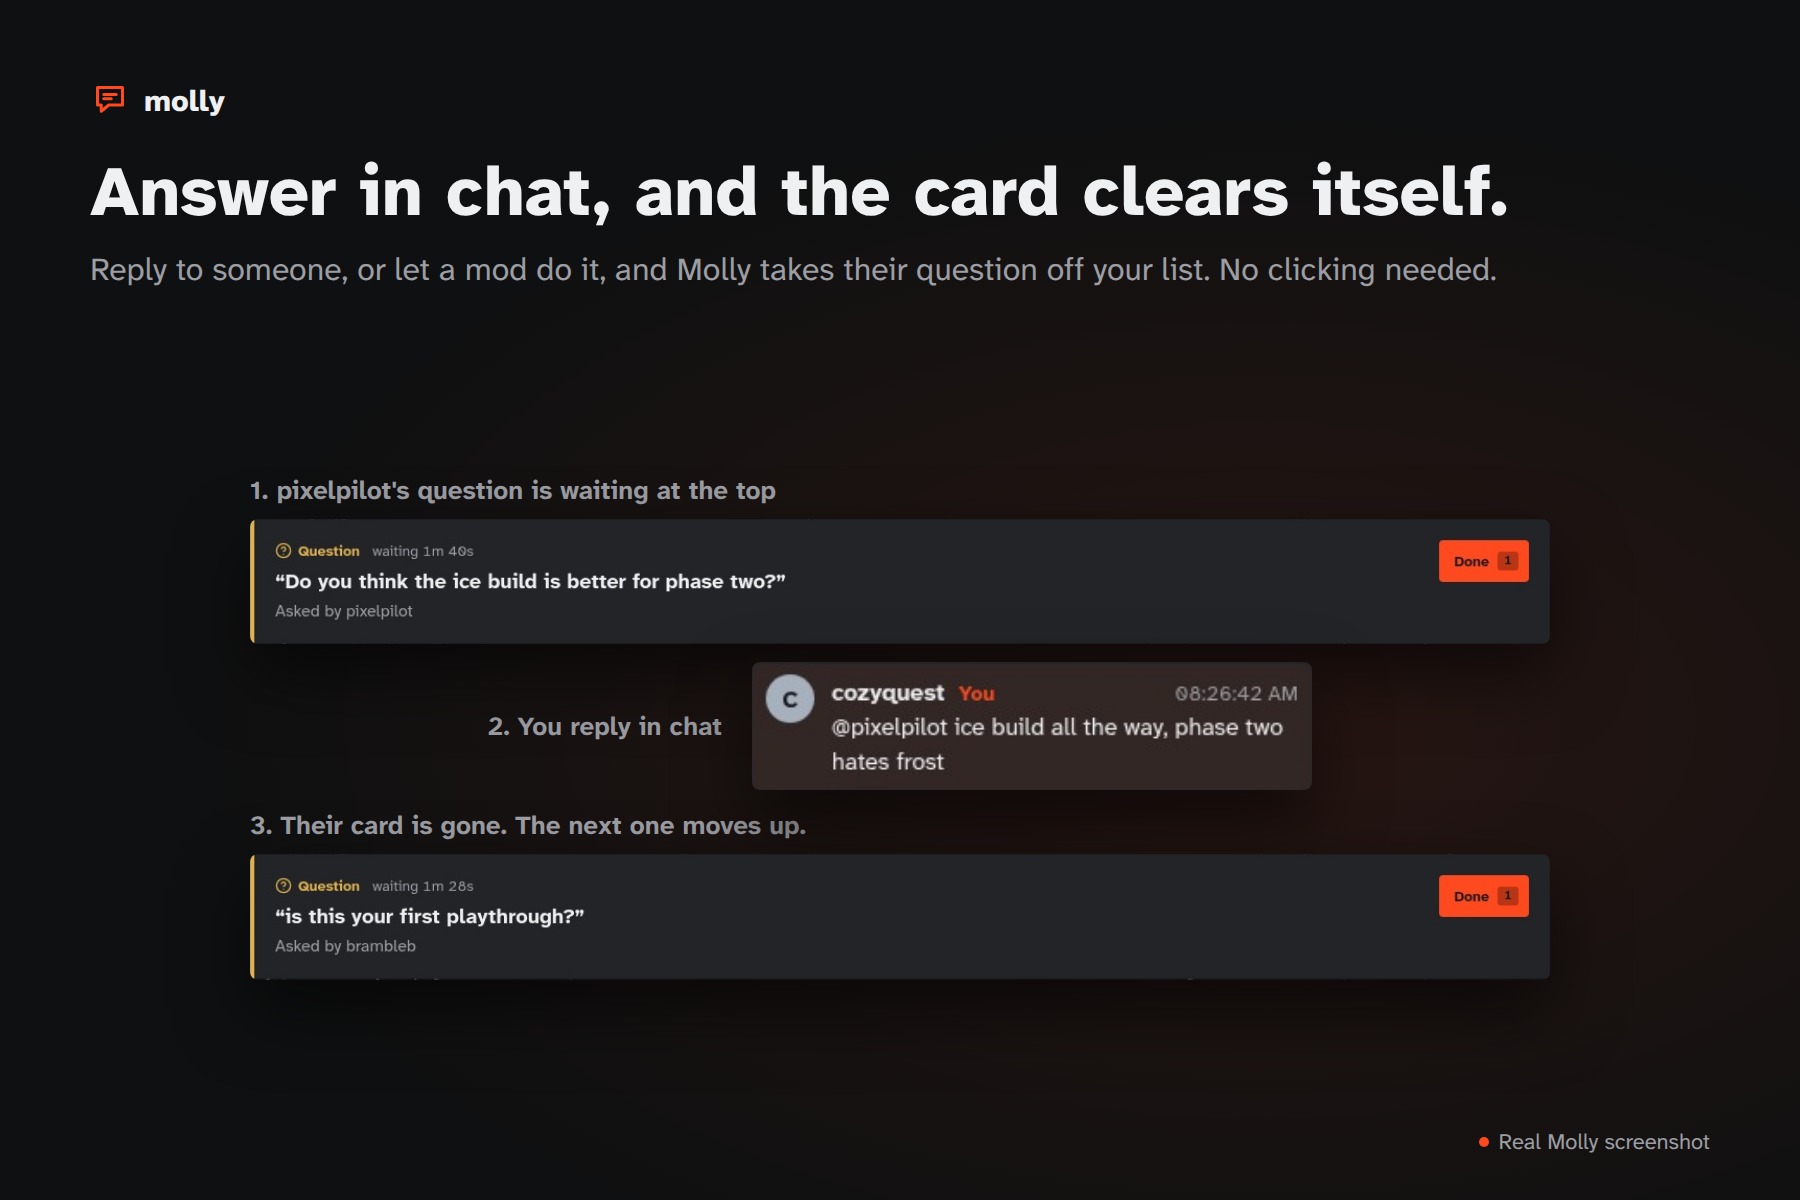
- Questions clear themselves. When you reply to a question in chat, or a moderator does, or someone @mentions the person who asked, Molly removes that card. Your own messages and common bots never create cards.
- One key to clear a card. Click Done or press 1, 2 or 3, and the next card moves up.
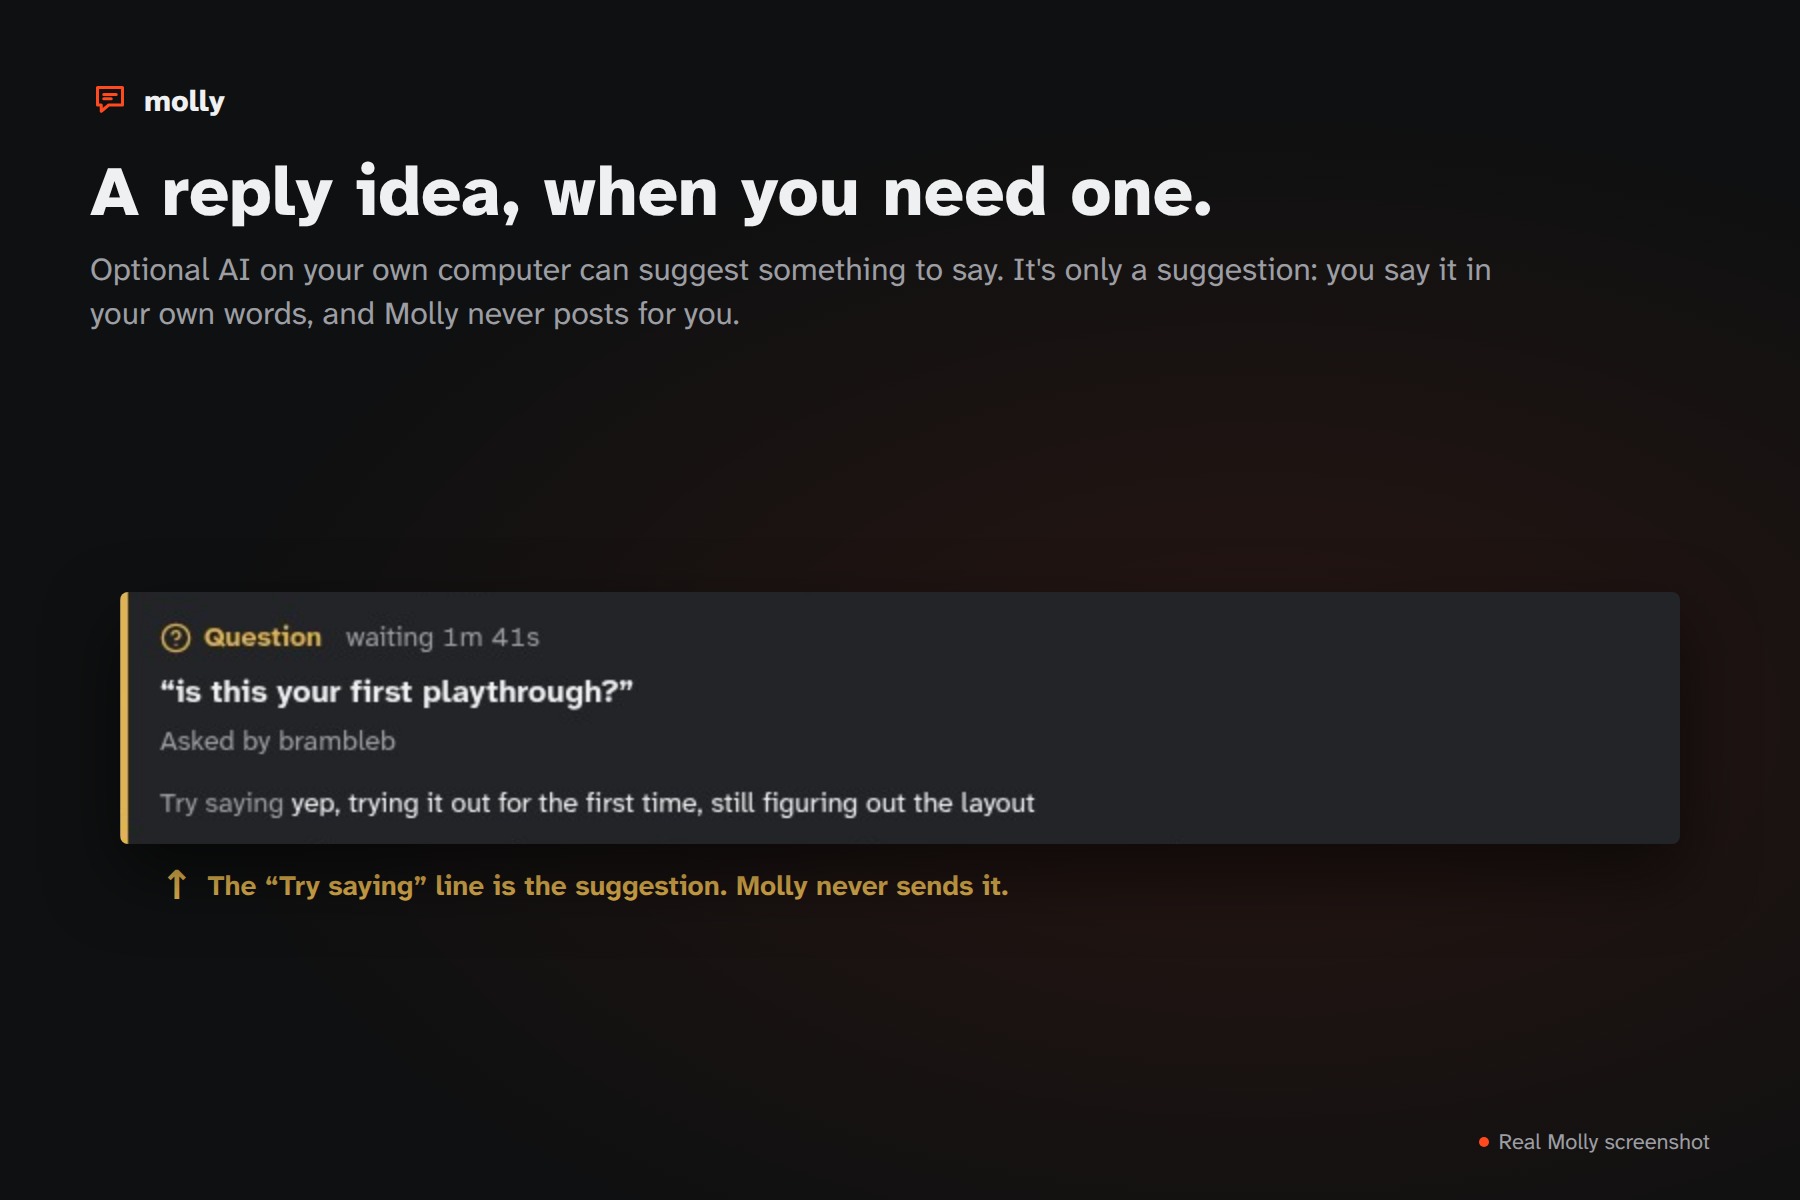
- Optional local AI. With Ollama on your machine, Molly spots questions that have no question mark, suggests a short reply ("Try saying…") for you to say in your own words, writes a talking point when chat goes quiet, and summarizes the session. Without Ollama, simple rules handle all of this instead.
- Sound cues you can turn on. A different chime for raids, questions, follows and first-time chatters, with an optional spoken line like "Question from pixelpilot". They're off by default.
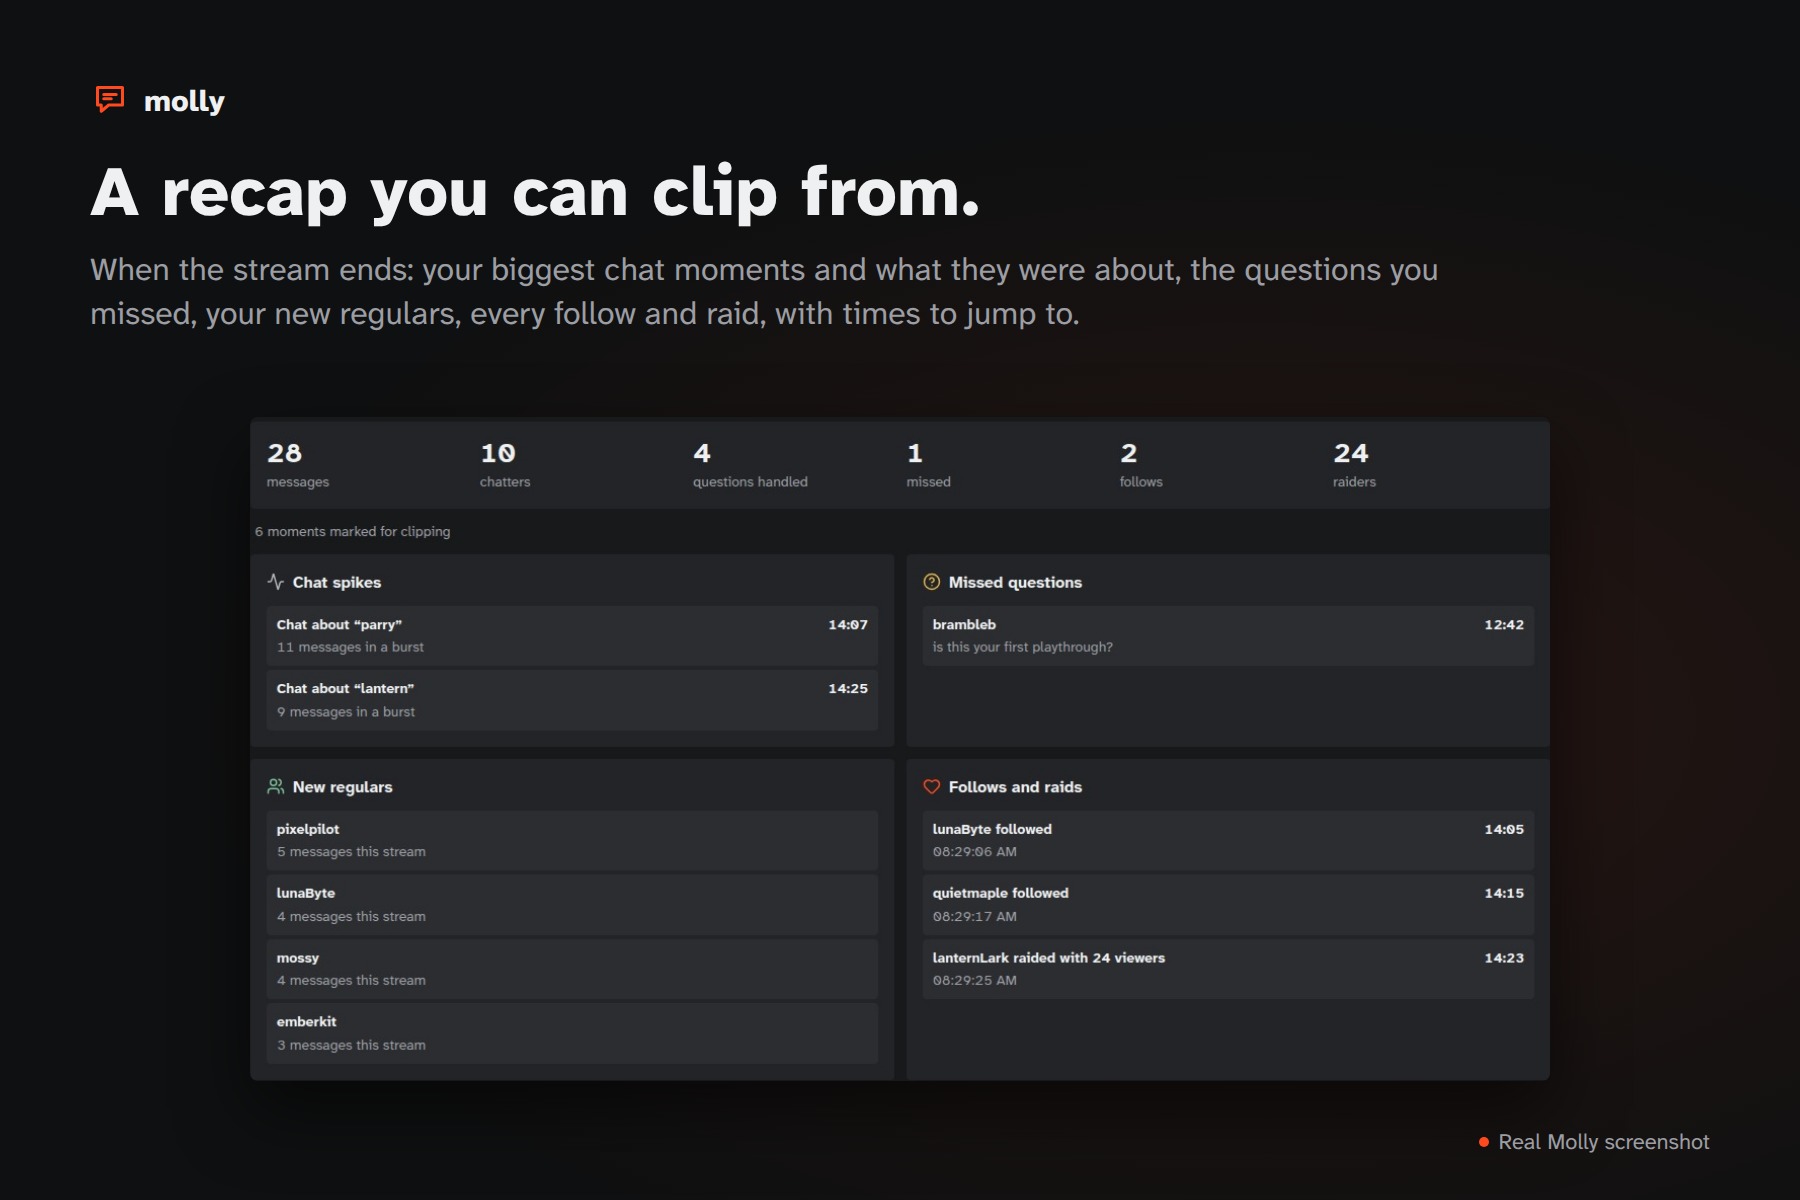
- A clip-ready recap. The biggest chat spikes and what they were about, the questions you missed, your new regulars, and every follow and raid, each with an h:mm:ss timestamp. While you're live, timestamps line up with your Twitch VOD. You can download the recap as text, and in live mode it's saved automatically when you stop Molly.
- Built for OBS. Use the full dashboard in a browser tab, or add
/dockas an OBS custom dock to keep only the queue next to your scenes.
How we built it
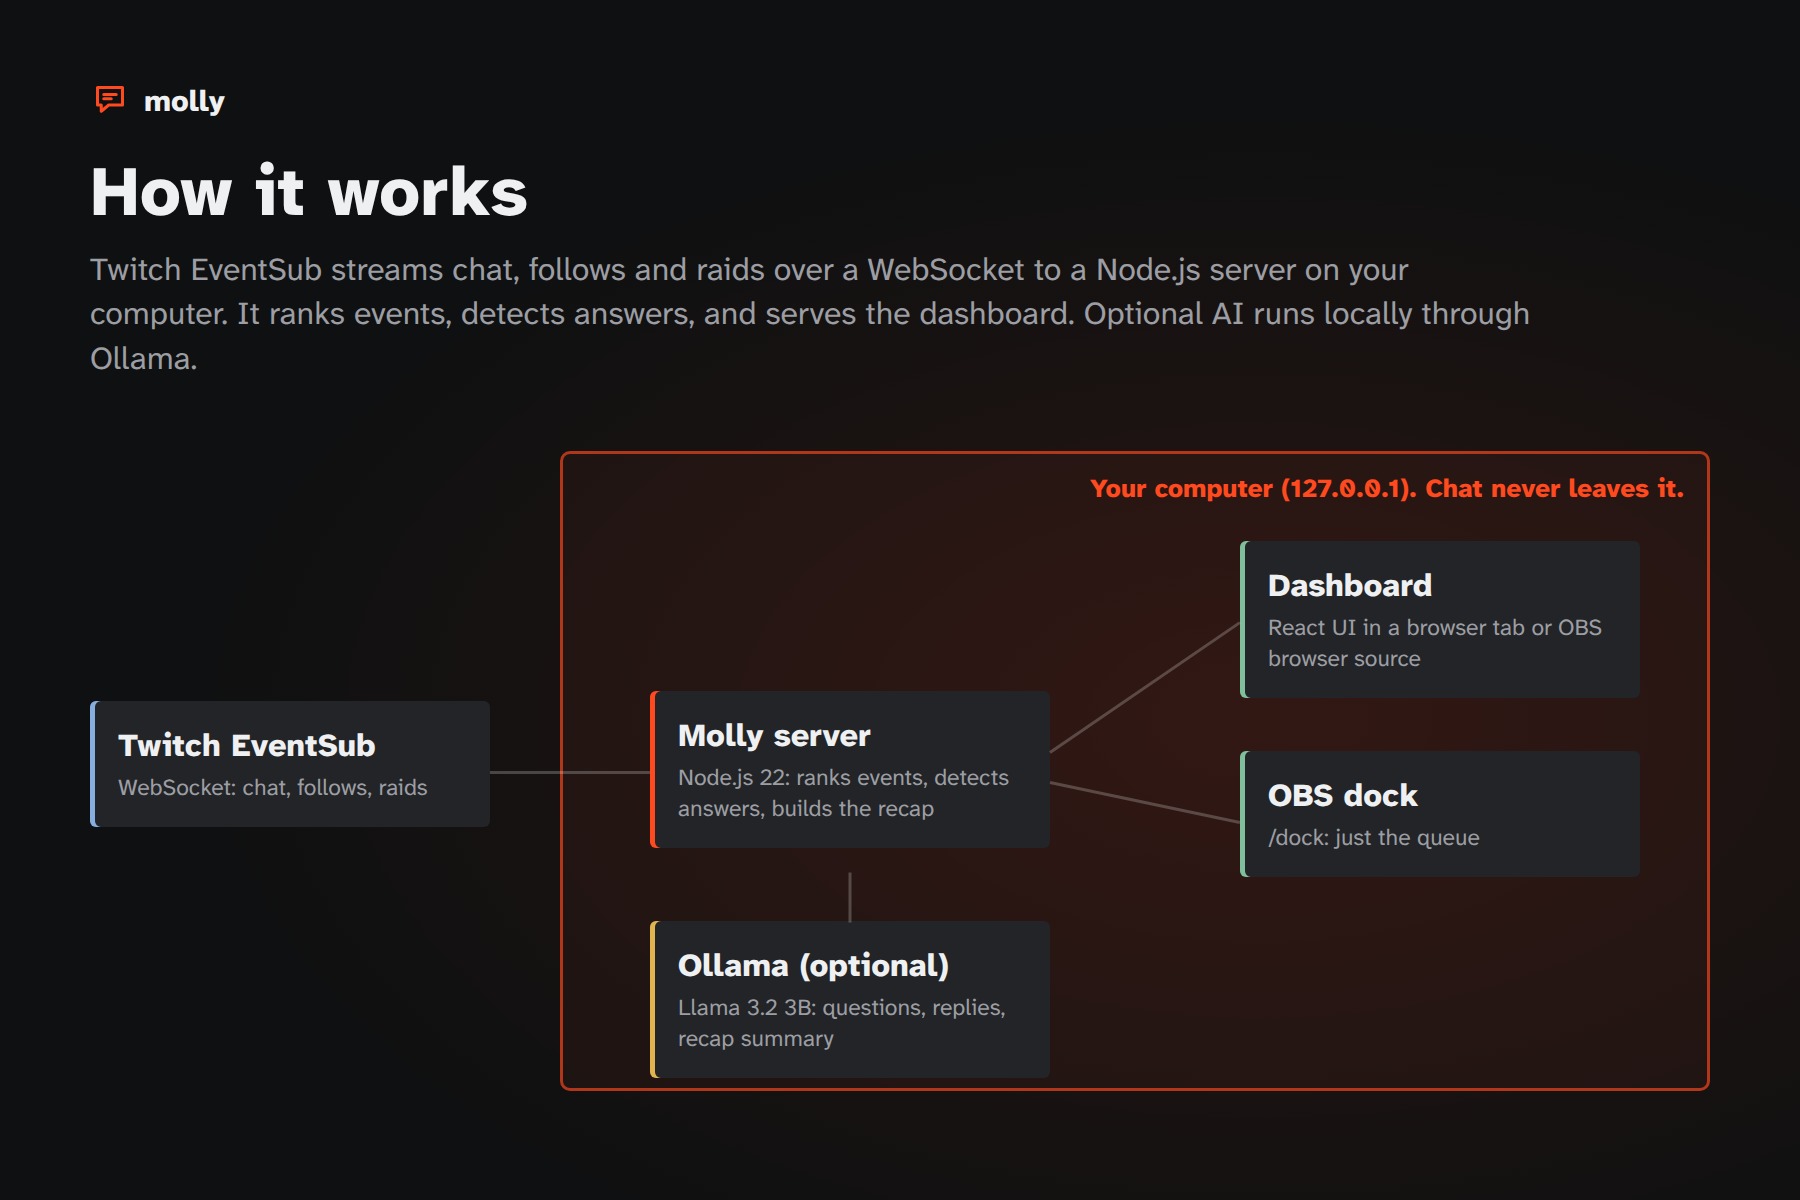
- Backend: Node.js 22 with only built-in modules: no npm packages, no database, no cloud. It connects to the Twitch EventSub WebSocket and subscribes to chat messages, follows and incoming raids. It checks the token at startup and every hour, watches the keepalive, and switches over cleanly when Twitch asks it to reconnect. The server listens only on
127.0.0.1. - Triage engine: It ranks events into cards, tracks how long questions have waited, detects answers from chat replies and @mentions, merges bursts of chat into single spikes labelled with their topic, and builds the recap.
- Local AI: It calls Ollama (we used
llama3.2:3b) one request at a time, with a 20-second timeout, so a slow model never holds up chat. Chat messages are passed to the model as data to analyze, never as instructions, and the model's answers are checked before use. Molly refuses any Ollama address that isn't on the same machine. - Frontend: React, TypeScript, Vite, Tailwind CSS and shadcn/ui, with lucide icons. The built files are included in the repo, so the demo needs no
npm install. The layout works like a streaming app (chatters, the queue, chat) and was designed to be read from arm's length. It uses the Atkinson Hyperlegible font, colors that meet WCAG AA contrast, and a single orange accent. - Demo mode: a recorded chat session that replays a boss fight, a "parry" chat spike, a raid, and questions with and without question marks, so you can judge Molly without going live.
- Tests: 11 end-to-end tests with
node:test. They cover the 3-card limit, answer detection, ignoring bots, replay, the recap download, and the AI layer against a fake Ollama server, including slow, failing and malformed responses. - How we worked: we built Molly with AI coding agents. OpenAI Codex built the first MVP from our spec and later the local-AI layer and the React rebuild. Our prompts are logged in
docs/codex-prompts.md. Other AI coding tools helped with reviews, bug fixes and UI polish along the way.
Challenges we ran into
- Knowing when a question has been answered. Twitch doesn't tell you that, so we combine reply threads, @mentions and who sent the message (the broadcaster or a moderator), and we ignore the streamer's own messages and bots.
- Showing the right card at the right time. A card that only surfaces after a minute can be stale, and one that surfaces too early is noise. The 60-second wait and the priority order took a lot of tuning against the replayed chat.
- Slow local AI. A 3B model on a laptop CPU can take 5 to 20 seconds per request. Molly runs AI work in the background, drops requests that are no longer relevant, and switches to the simple rules if Ollama keeps failing, then reconnects once it's back.
- Readable at a glance. Our first designs had small grey labels and outlined boxes that disappeared on a second monitor. We rebuilt the cards around who asked, what they asked, and how long they've waited.
Accomplishments that we're proud of
- It works on a real channel: we tested live mode against Twitch EventSub with a real account.
- Questions clear themselves when you answer them. That small feature is what makes the queue trustworthy.
- Everything runs on your machine, even the AI, and Molly never posts a single message for you.
- You can try it with one command (
node scripts/setup.js) and only Node.js 22 installed: no npm install and no Twitch account needed.
What we learned
- Streamers don't need more alerts. They need fewer, better-ranked ones, plus a way to clear them without looking away from the game.
- Local AI is good enough to suggest a reply, but the streamer should always say it in their own voice. Molly suggests and never speaks for you.
- Small details matter a lot for something you glance at: typeface, contrast, and how old a card is.
What's next for Molly
- Per-channel tuning: wait times, which cards appear, and spike sensitivity.
- Mod mode: let a trusted moderator's Molly share and clear the same queue.
- Shortcuts that work while the game window is focused, plus a Stream Deck button for "done".
- Exporting recap markers straight to Twitch clip and highlight tools.
Built With
- amazon-polly
- llama-3.2
- node.js
- obs
- ollama
- openai-codex
- react
- shadcn-ui
- tailwind-css
- twitch-eventsub
- typescript
- vite
- web-audio-api
- websocket

Log in or sign up for Devpost to join the conversation.