-
-
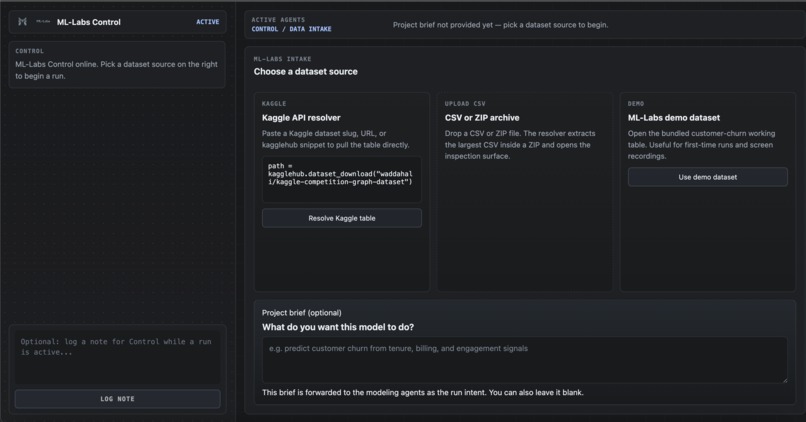
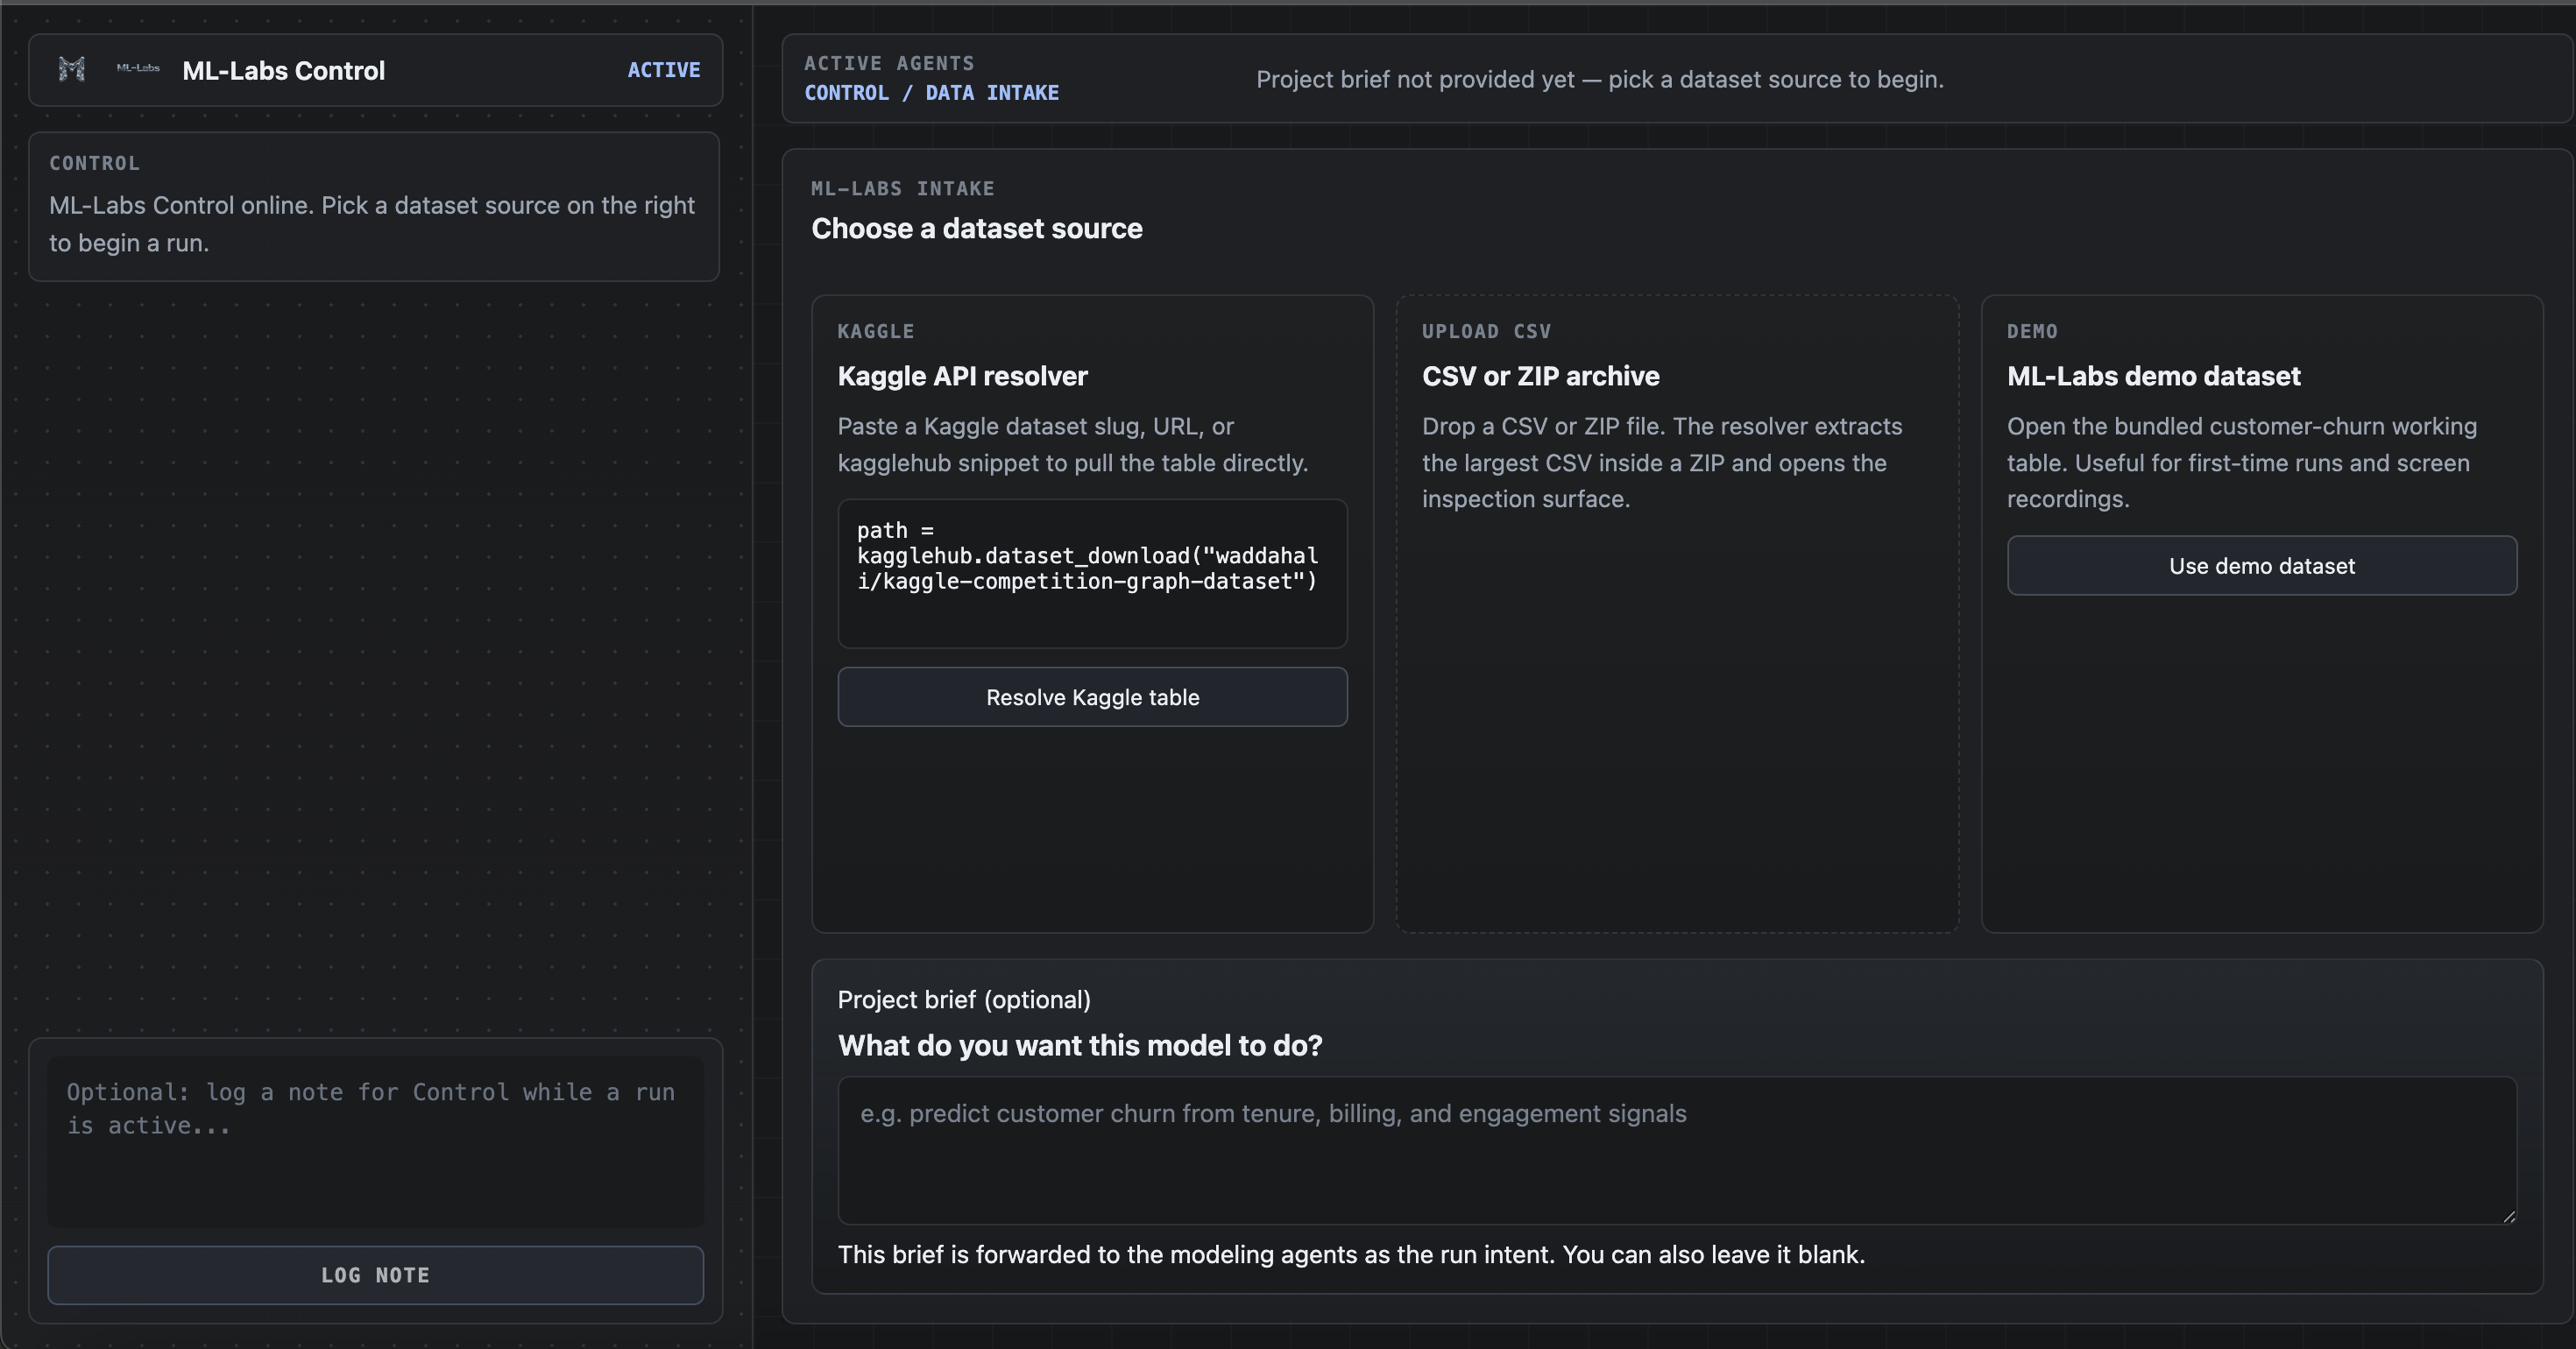
ML-Labs control center
-
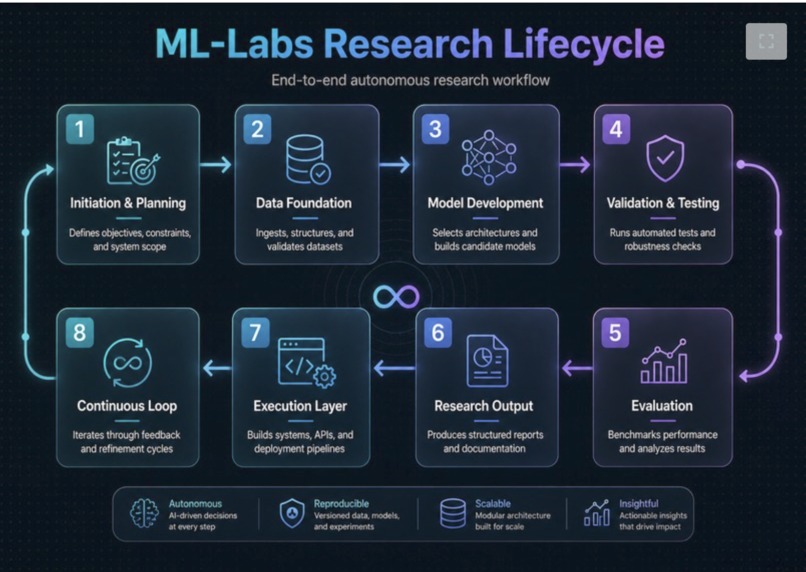
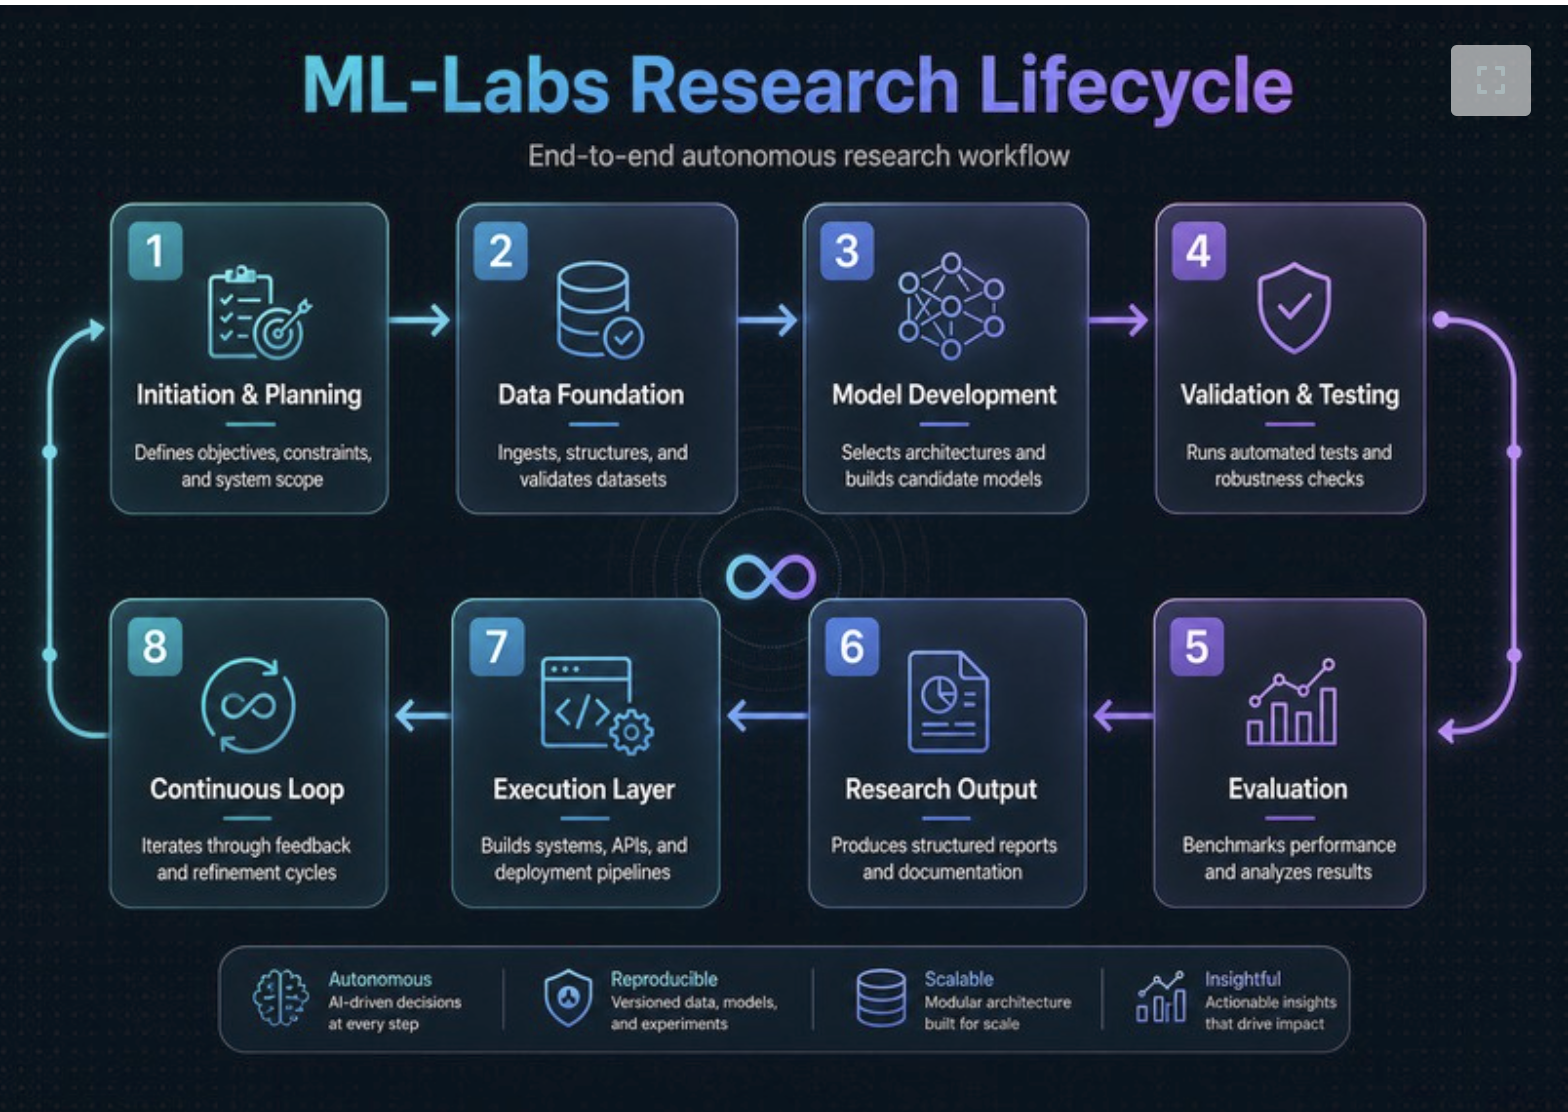
Diagram of ML-Labs research lifecycle, built to model the life cycle occurring at high-end, sophisticated research labs
-
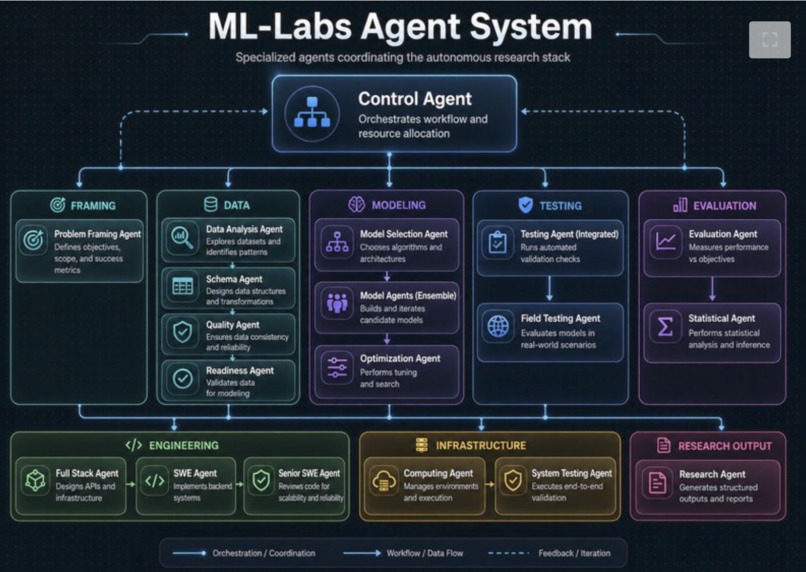
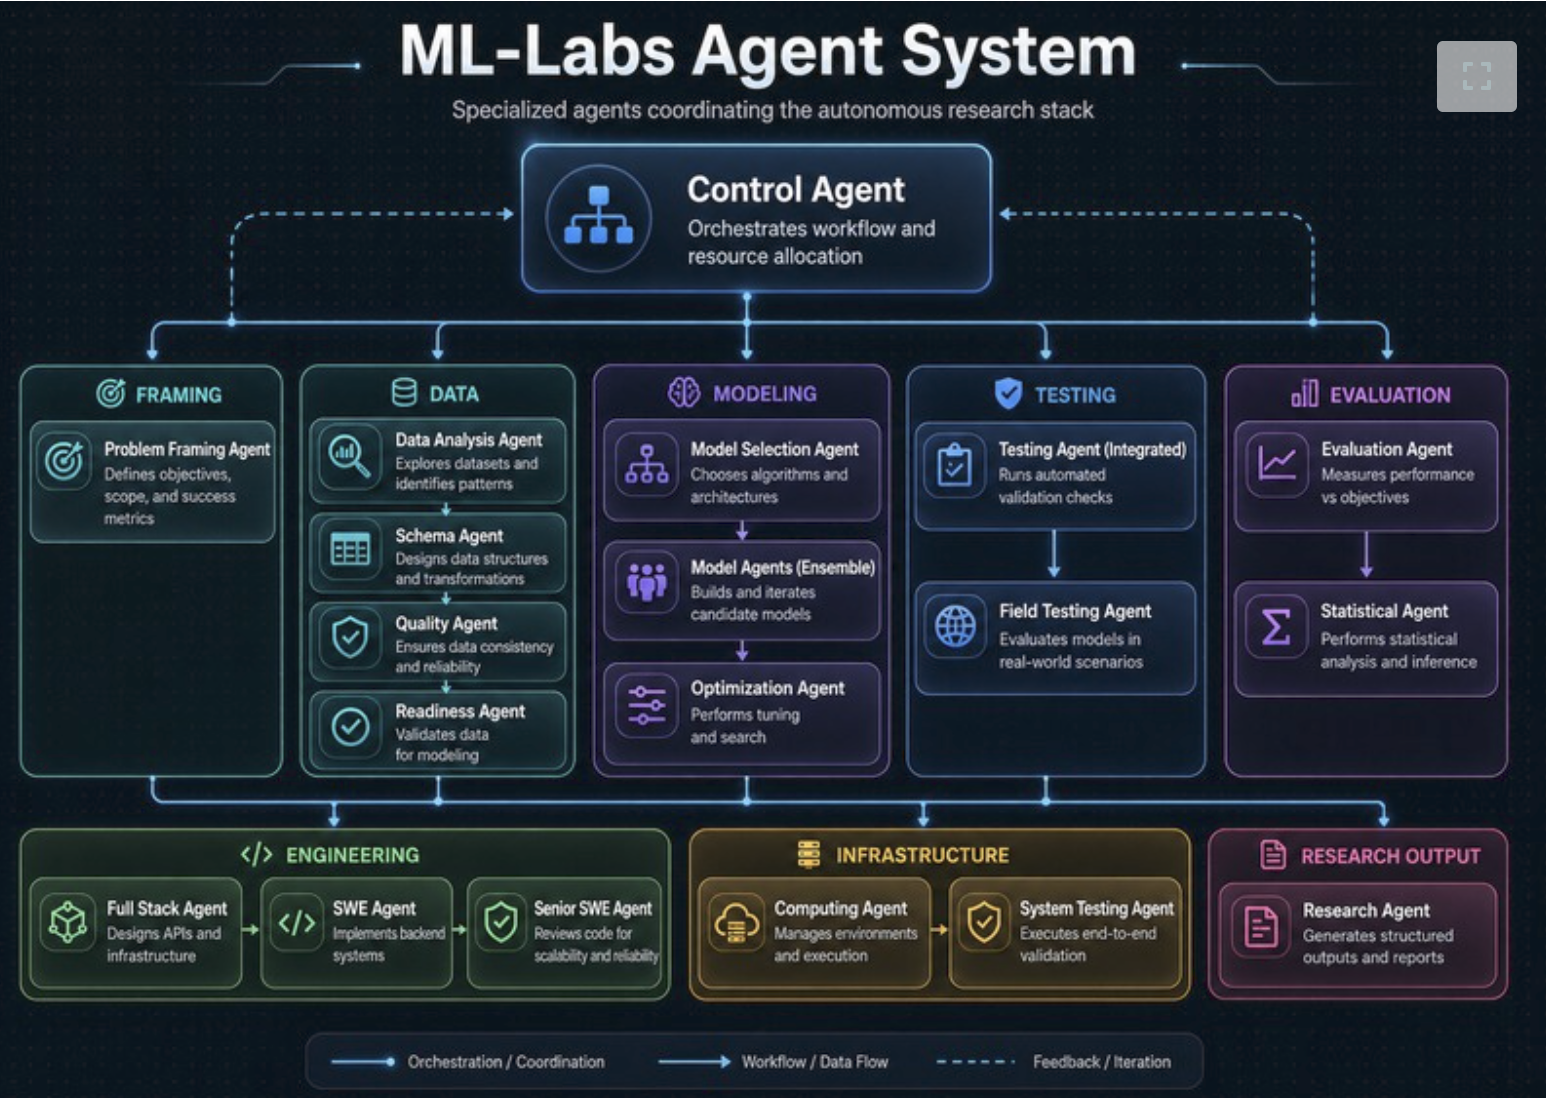
Diagram of ML-Labs multi-agent architecture, built using agents that model positions at real research labs with specialized skills/tools
-
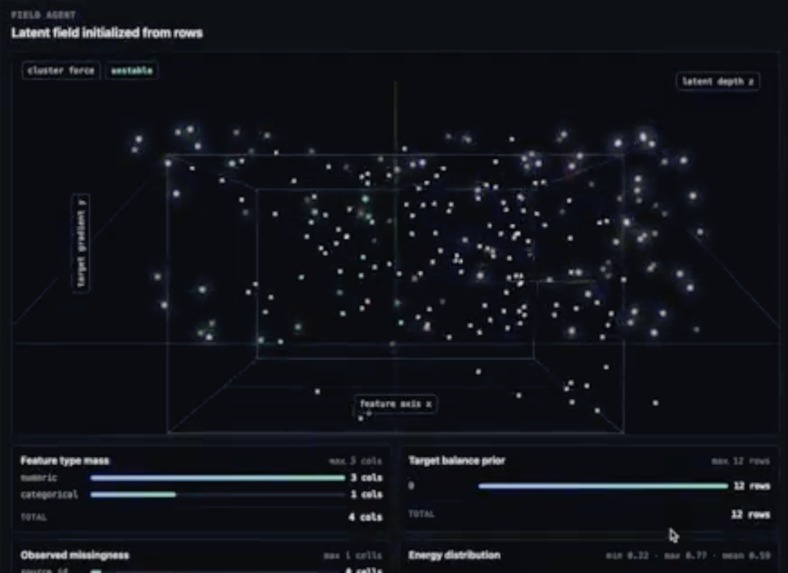
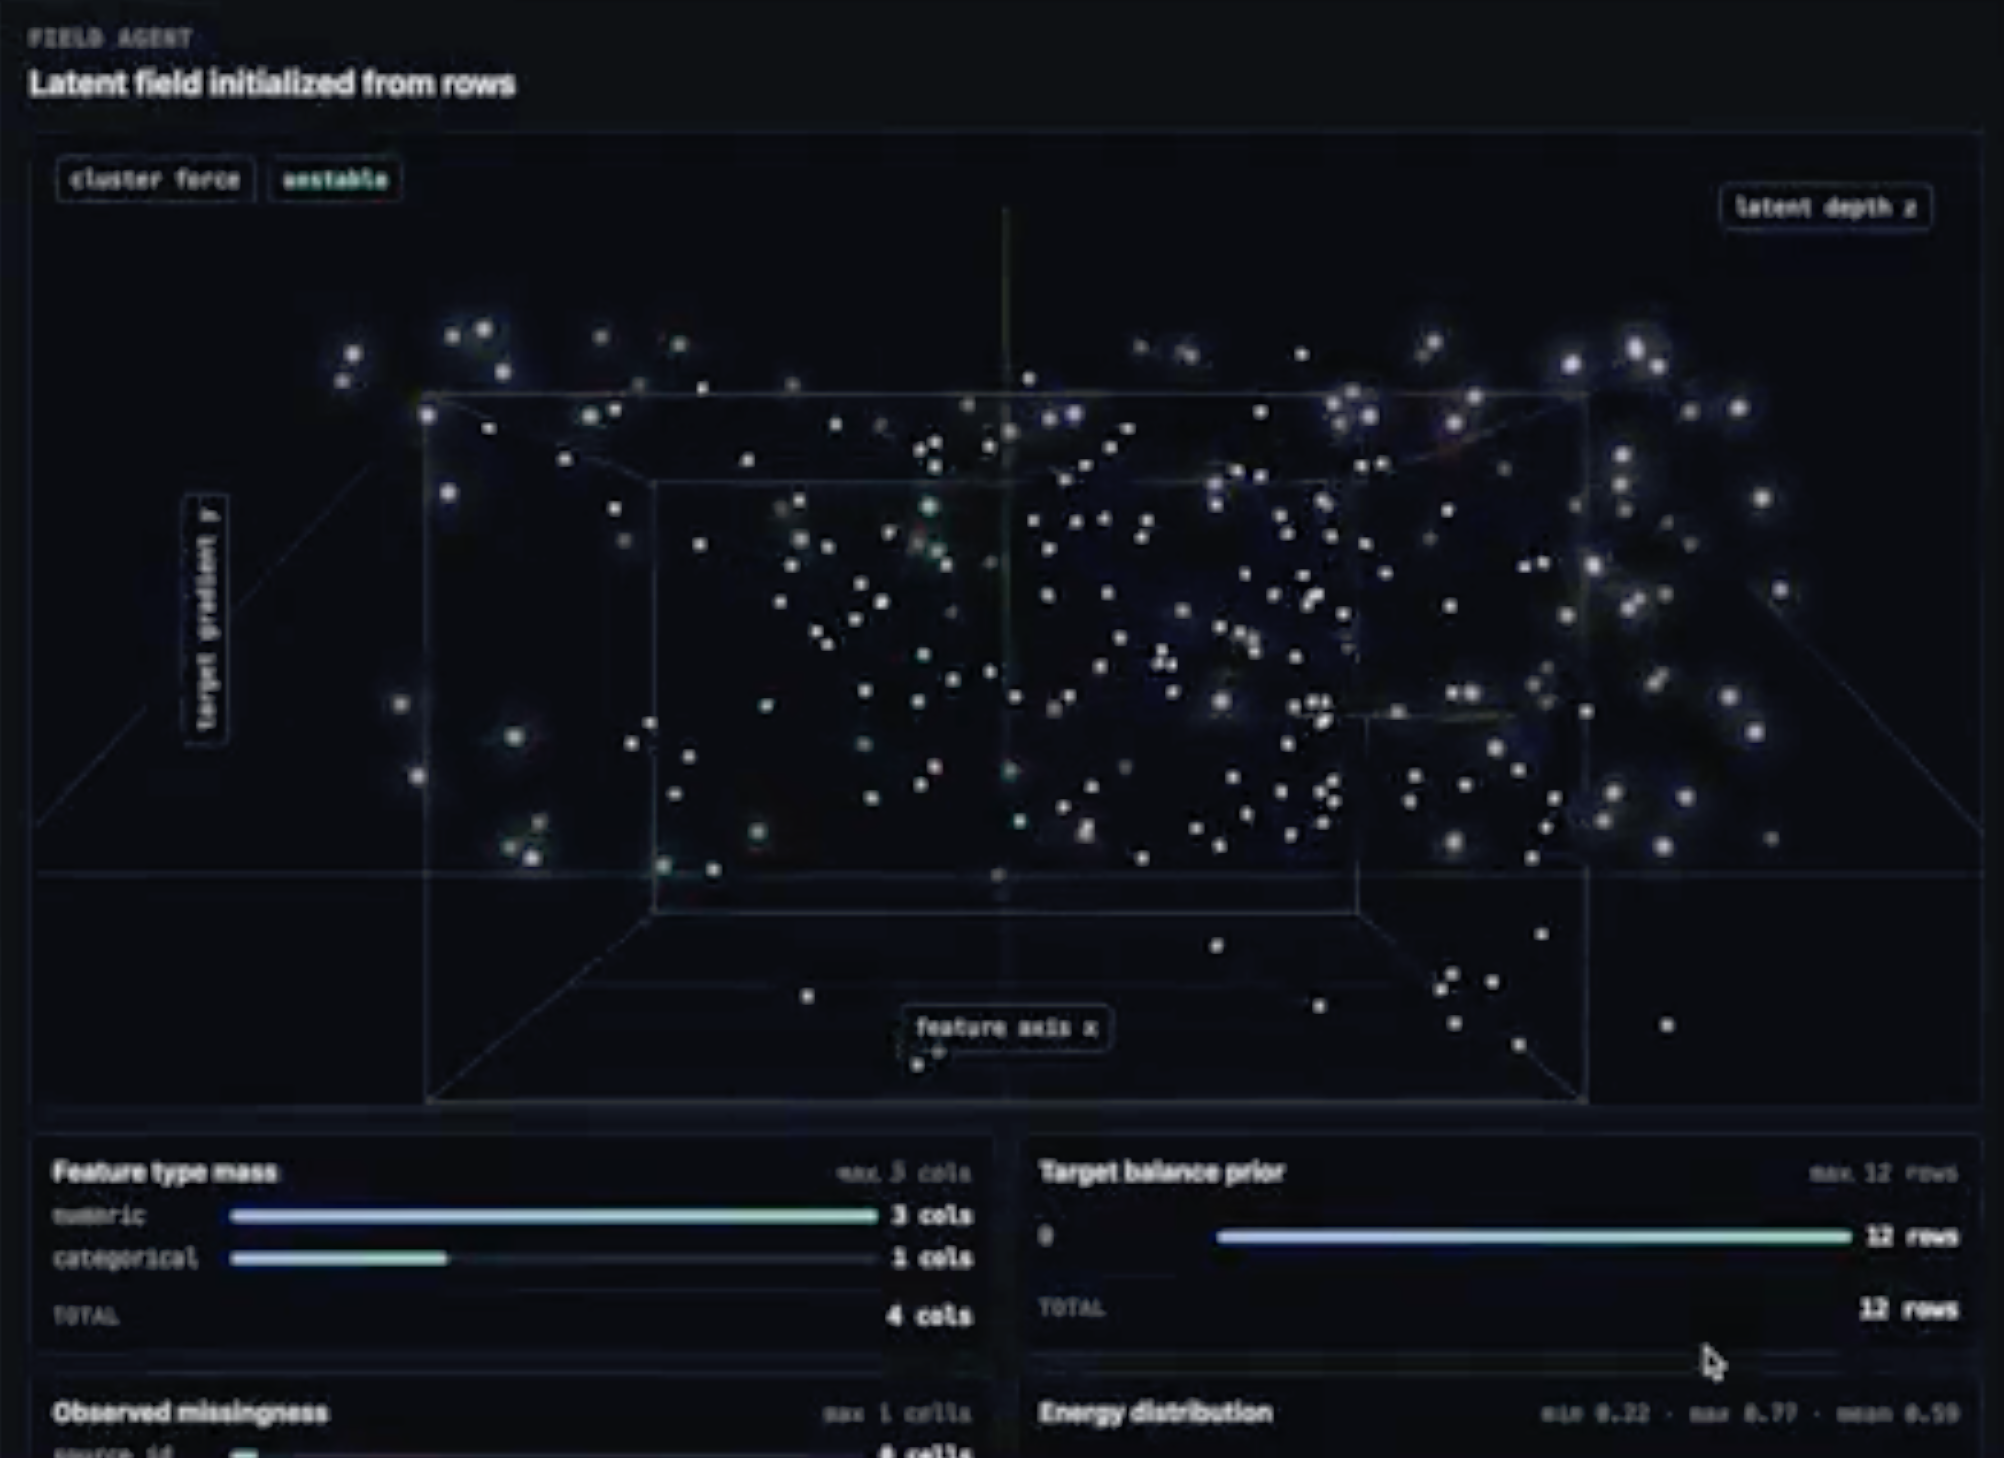
3D graph neural network computed by ML-Labs' computing agent based on competition data
ML-Labs
Inspiration
ML-Labs came from a frustration I kept running into while building machine learning projects. The actual work of research was never just training a model. It was hours of finding usable data, cleaning broken datasets, debugging preprocessing, rerunning failed experiments, comparing results across tools, and trying to hold the whole workflow together manually.
After enough late nights doing that over and over, I stopped wanting a better script or a better notebook. I wanted to build the lab itself.
A lot of this project was shaped by nights where nothing worked the first time. Models broke, pipelines failed, context got lost between stages, and small bugs would ruin full runs. But that was also what made the idea feel so necessary. The more time I spent rebuilding the same workflow by hand, the more obvious it became that machine learning research needed a more scalable architecture. That became ML-Labs.
What It Does
ML-Labs is an autonomous machine learning research system that executes the full research lifecycle end-to-end.
It can:
- Source and ingest datasets
- Analyze and profile data
- Prepare features
- Design and run experiments
- Train and optimize models
- Validate results
- Generate visualizations
- Package outputs into structured research artifacts
- Deploy production-ready APIs
Instead of acting like a single assistant, it operates as a coordinated lab of specialized agents working across the research pipeline.
What makes it especially powerful is that it is not built for one narrow task. It is built as a scalable research engine. The same architecture can support different datasets, workflows, and modeling problems without needing to rebuild the entire system every time.
That shift from a one-off pipeline to a reusable autonomous lab is the core of the project.
How We Built It
I built ML-Labs as a multi-agent system because real research is not one action. It is a chain of specialized decisions.
A single model trying to do everything would not be reliable enough, modular enough, or scalable enough. So I split the workflow into specialized agents responsible for distinct phases:
- Data Sourcing Agent
- Data Profiling Agent
- Feature Engineering Agent
- Experiment Planning Agent
- Model Training Agent
- Validation Agent
- Reporting Agent
- Deployment Agent
The hard part was not just building the agents individually. It was making them function as one coherent research system.
I had to build:
- Shared context flow
- Agent orchestration
- Intermediate output handling
- Execution monitoring
- Failure recovery
- Cross-stage communication
so that each stage could pass meaningful work to the next without the entire pipeline collapsing.
Over time, that process turned ML-Labs from an ambitious concept into a system with real architectural depth and scalability.
Mathematical Foundation
One example of how the Experimentation or Evaluation Agent ranks candidate models is through a weighted research objective:
$$ S(M) =
w_1 \cdot A(M)
w_2 \cdot L(M)
w_3 \cdot C(M) + w_4 \cdot R(M) $$
Where:
- $S(M)$ = overall model score
- $A(M)$ = predictive accuracy or performance metric
- $L(M)$ = validation loss
- $C(M)$ = computational cost
- $R(M)$ = robustness score
- $w_i$ = tunable weighting coefficients
The agent evaluates multiple candidate models and selects:
$$ M^* = \arg\max_{M \in \mathcal{M}} S(M) $$
where:
- $\mathcal{M}$ is the set of all candidate models
- $M^*$ is the optimal model chosen by the research system
This allows ML-Labs to optimize not only for performance, but also for efficiency, reliability, and scalability.
Challenges We Ran Into
The biggest challenge was making autonomy actually hold up under pressure.
It is easy to make a project sound advanced. It is much harder to make a system reliably carry context across multiple research stages, recover from broken runs, and still produce outputs that feel rigorous and usable.
Another major challenge was balancing scale with quality.
I did not want a flashy system that could technically do many things but did none of them well. I wanted something that could scale across workflows while still feeling technically serious.
That meant a lot of debugging, redesigning, and rethinking assumptions whenever the architecture looked good in theory but failed in practice.
A huge personal challenge was simply pushing through the repetition. Many of the hardest parts of this project were built during long nights of debugging models, tracing pipeline failures, and fixing one issue just to expose the next one.
But that process is exactly what made the system stronger.
Accomplishments That We're Proud Of
What I am most proud of is that ML-Labs became more than a cool idea.
It became a real autonomous system with enough scope to feel like infrastructure, not just a demo.
I am proud of how much of the machine learning workflow it actually covers. It does not stop at analysis suggestions or model generation. It handles the full arc from raw data to validated results and deployable outputs.
That level of end-to-end automation is what makes the project feel ambitious.
I am also proud that the architecture is inherently scalable.
Because the system is modular and agent-based, it can expand to new workflows, domains, and research tasks without needing to be rebuilt from scratch.
That gives ML-Labs the potential to grow from a single project into a much larger research platform.
What We Learned
I learned that the hardest part of serious machine learning work is often not the modeling itself.
It is the infrastructure around it.
The invisible work of sourcing data, coordinating steps, debugging runs, evaluating outputs, and keeping everything consistent is where enormous amounts of time get lost.
I also learned that if you want true autonomy, you need more than intelligence.
You need:
- Structure
- Modularity
- Clear interfaces
- Context continuity
- Strong orchestration
Without those elements, even powerful models remain disconnected tools.
Most importantly, I learned that ambitious systems are built through iteration, not inspiration alone.
A lot of the real progress on ML-Labs came from working through broken systems long enough to understand how to make them robust.
What's Next for ML-Labs
The next step is pushing ML-Labs beyond workflow automation and deeper into autonomous scientific discovery.
Future development includes:
- Stronger cross-agent coordination
- More advanced experiment planning
- Persistent long-term memory across runs
- Adaptive evaluation frameworks
- Expanded support for diverse machine learning domains
- Improved failure recovery mechanisms
- Autonomous hypothesis generation
The goal is to preserve the modular architecture while increasing the system's ability to reason, adapt, and discover.
Long-Term Vision
The long-term vision is for ML-Labs to become a true research engine: a system that does not just help with machine learning, but scales into an always-available autonomous laboratory capable of exploring questions, designing studies, running experiments, and producing serious results at a level that would traditionally require an entire research team.
Built With
- ai
- api
- c++
- css
- kaggle
- luma
- ml
- multi-agent
- netlify
- next.js
- node.js
- numpy
- pandas
- python
- react
- render
- scikit-learn
- tailwind
- typescript

Log in or sign up for Devpost to join the conversation.