-
-
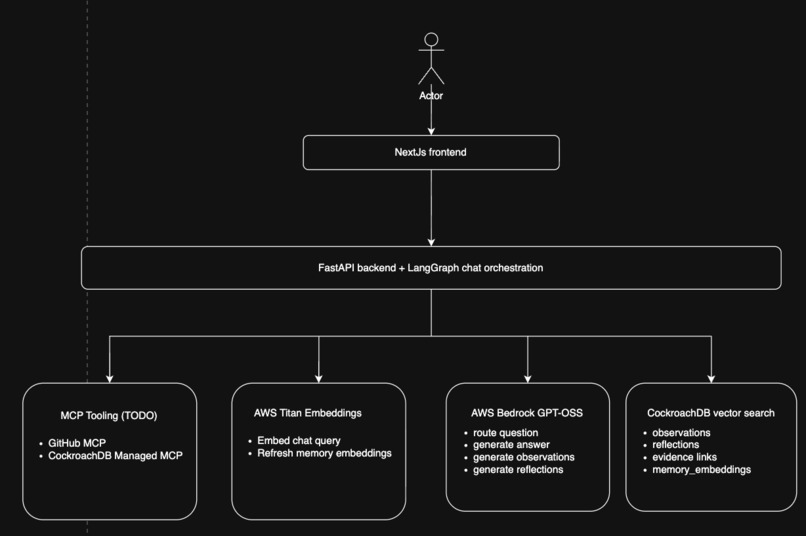
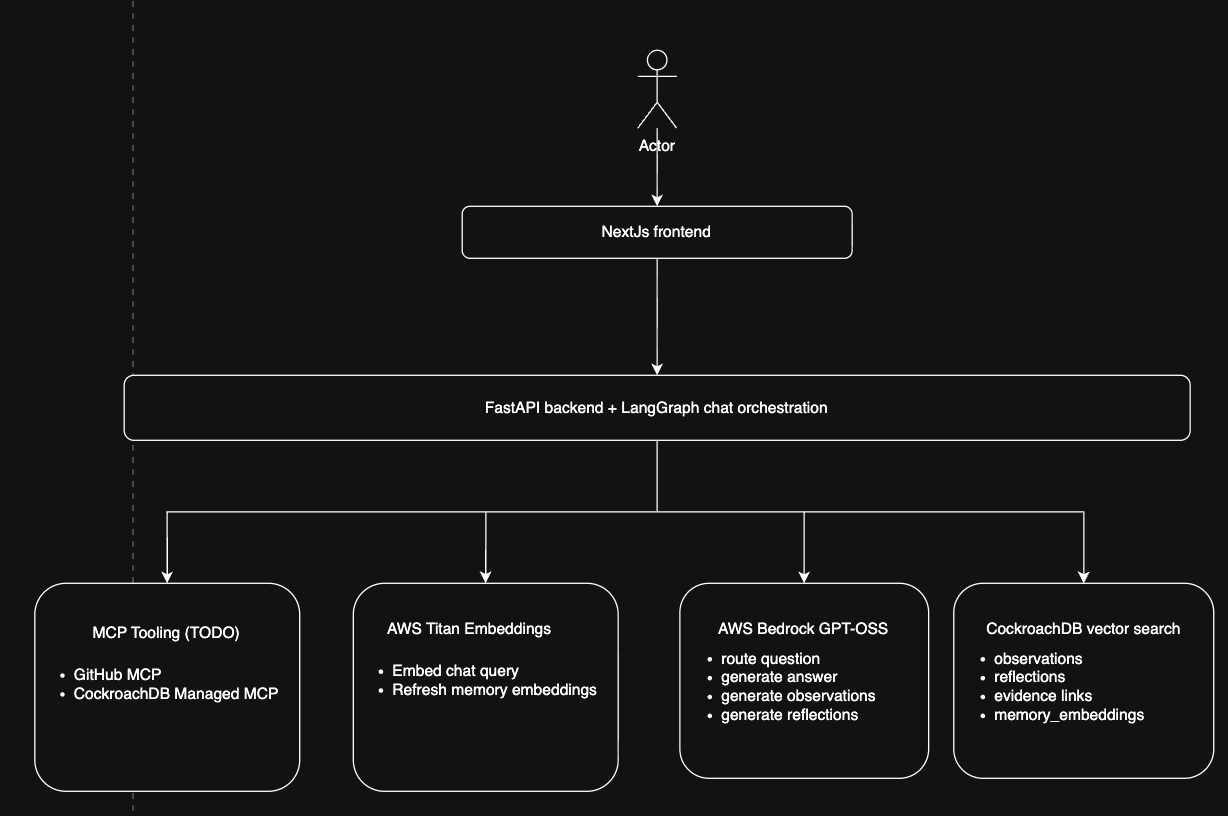
memoe-high-level-prototype-architecture
Inspiration
Memoe is inspired from my research and work in the SRE & Operations world. I believe that correlating knowledge from more relevant sources will enrich the context needed by engineering stakeholders or an SRE practice, for enabling and strengthening reliability strategies. I find it frustrating that most solutions and organizations invest heavily in operational signals (metrics, logs, traces, profiles, etc) and tools (DataDog, Grafana, etc) but fail to recognize foundational aspects of service such as change management, and customer support related operations. Since changing organizational walls / boundaries is difficult, this is my attempt at democratizing information instead.
What it does
Memoe is meant to help reduce MTTR and dissolve boundaries in complex environments by discovering patterns and risk through multi-dimensional evidence, sourced from organizational knowledge sources.
Through deterministic memory, Memoe is able to observe activity, generate observations and reflections, that an SRE practice can leverage to improve software & processes.
How we built it
The data foundation is based on the steampipe project (steampipe.io) which provides an interface that makes major platforms query surfaces. This provides a clear schema that forms predictable input and through procedural memory, we can guide LLMs in response. For the local demo, I work with fixtures and plan for an ETL to ingest, normalize and enrich later. I found more meaning and alignment with the hackathon's requirements to learn and deliver on memory as the driving factor and I hope this demonstrates something.
The fixtures are available on GitHub as well as an intended aws-based ETL architecture.
The rest was finding the right interface to converse with Memoe then generate observations and reflections for the services in scope. So Memoe simply interacts with the cockroachdb server, two models (AWS titan for embeddings and gpt-oss for conversations) to help the controller think about risk, gaps and patterns from operational data.
Challenges we ran into
I had to learn a lot in a very short time, embedding models, LangGraph and vector searching to make this a reality. This were great but fulfilling challenges and I'm happy I engaged. Deploying this was also the other challenge that I chose to not prioritize because the experience I have delivered would not be fit as-is to go live since what I have to show is a conversational interface with the ability to generate observations and reflections. The cost and security factors are too young to promote. A production-grade experience would certainly require more; auth, observability and operational readiness that doesn't fit my hackathon scope. Additionally, I joined later, still have a full time job and couldn't find someone to collaborate with. I believe doing this collaboratively would have gotten it further and so that's a consideration I'm making for future challenges.
Accomplishments that we're proud of
- Memoe is able to generate meaningful reflections and observations. I initially thought this was too high level of an idea but I'm willing to continue working on this.
- Learning about memory and how fundamental it is to an agentic experience was also mind blowing, thank you and shout out to the organizers to this.
What we learned
- Embedding models, the various types of agentic memory (working, procedural, semantic / episodic, temporal) and play around with them here. ## What's next for Memoe
- Data ingestion: I am working on data ingestion as a separate service; in my experience, these are far more scalable when handled separately because the data can be relevant for more processes. I'm also in doubt about cockroachdb's ability to handle the data I'm ingesting. I see this data falling under the OLAP category more than OLTP but I'm happy to discuss.
- Observability: I have instrumented some parts of Memoe to help me debug and improve as I was building, but this can be far more mature to meet production standards and so, Memoe needs an observability improvement to make sure that maintainers can keep Memoe running. This is a prototype and thus I was not able to get it to a production-grade capacity. The ideas and experience are with me, the time was the greatest challenge.
- Production readiness: Memoe needs to leverage CockroachDB's scalability features. I was impressed with cockroachDB's horizontal scaling which reminded me of other tools I've come across with somewhat similar approaches and surely Memoe's storage is a core part of making this a production-grade experience.
Built With
- amazon-web-services
- cockroachdb
- docker
- python
- typescript
Log in or sign up for Devpost to join the conversation.