-
-
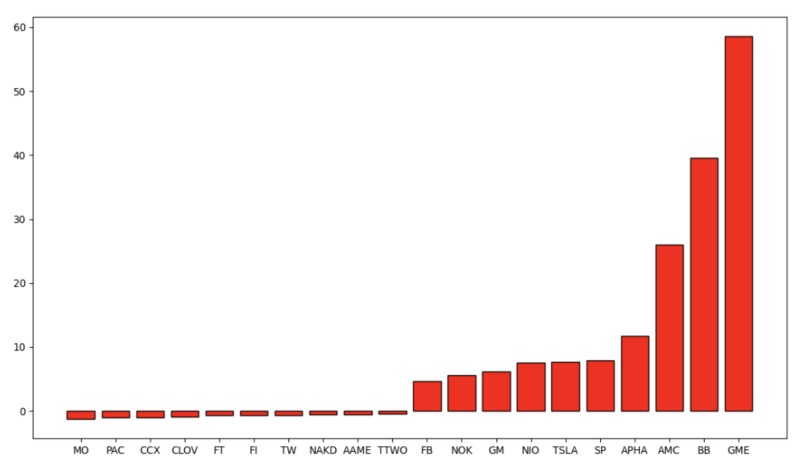
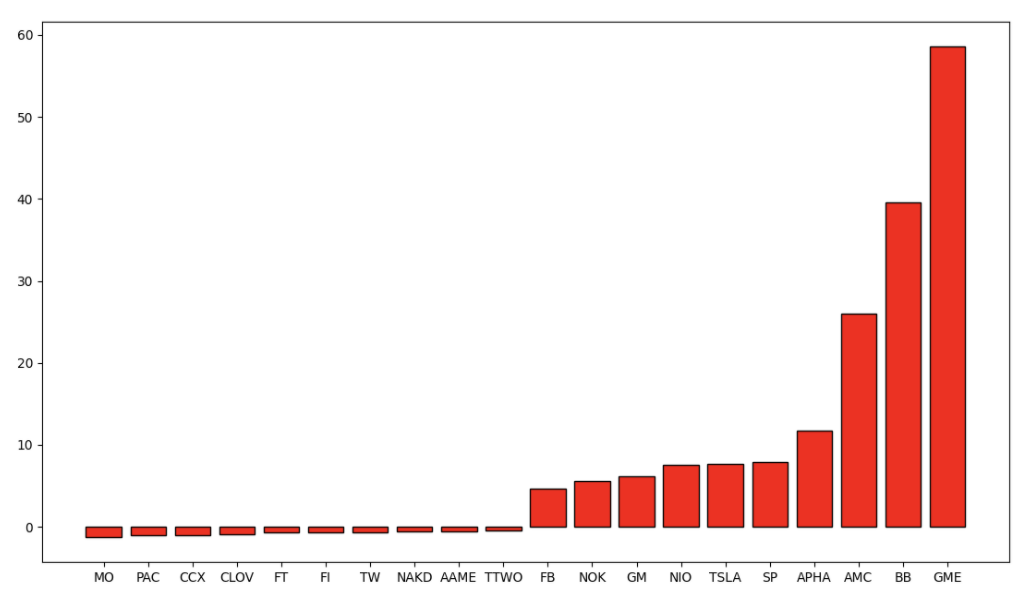
Sentiment Regression Analysis
-
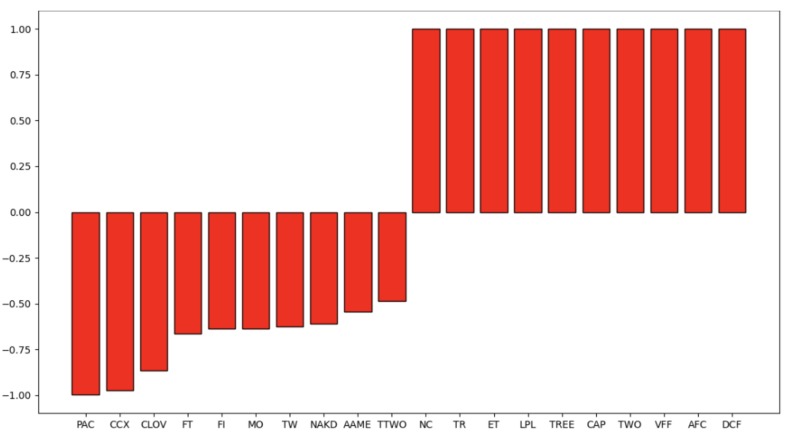
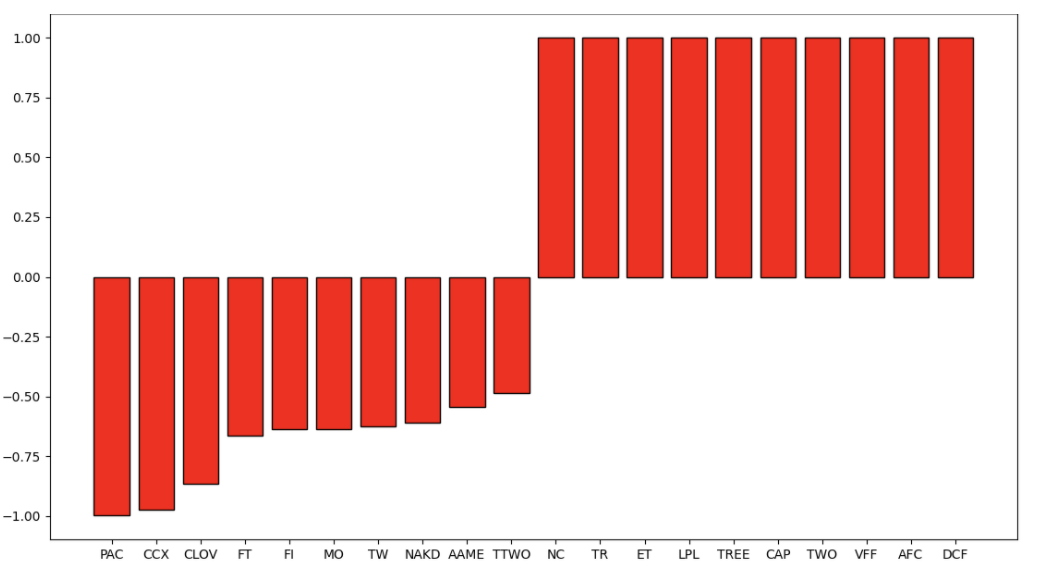
Average Sentiment Analysis
-
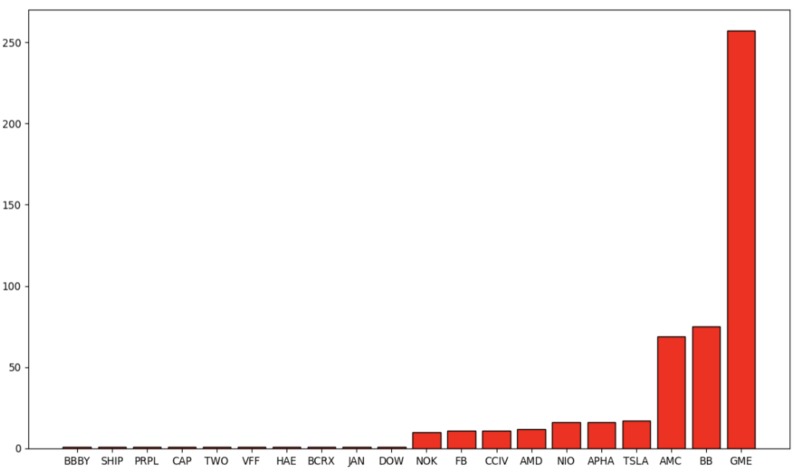
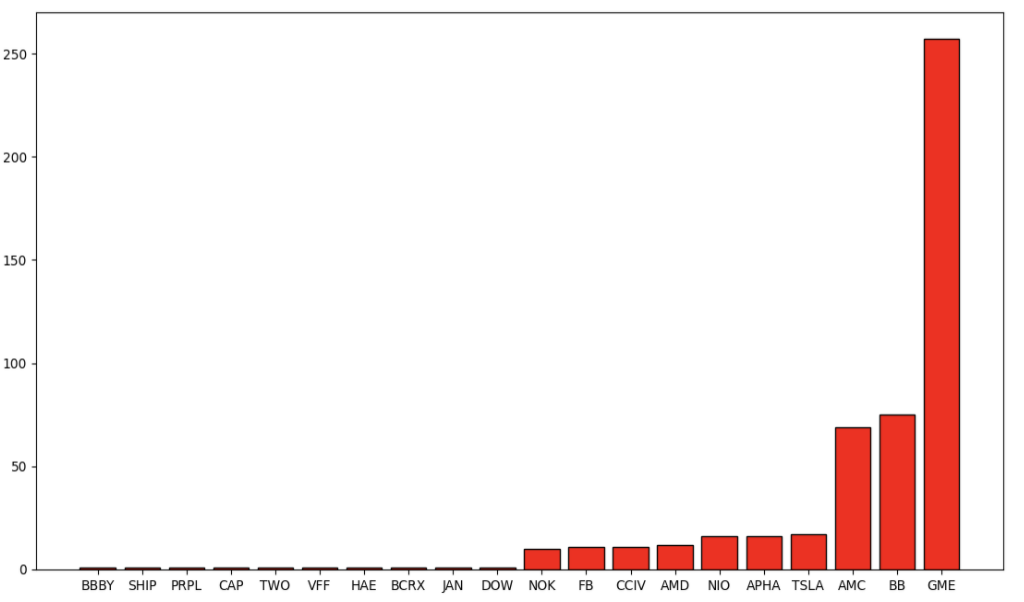
Mentions
-
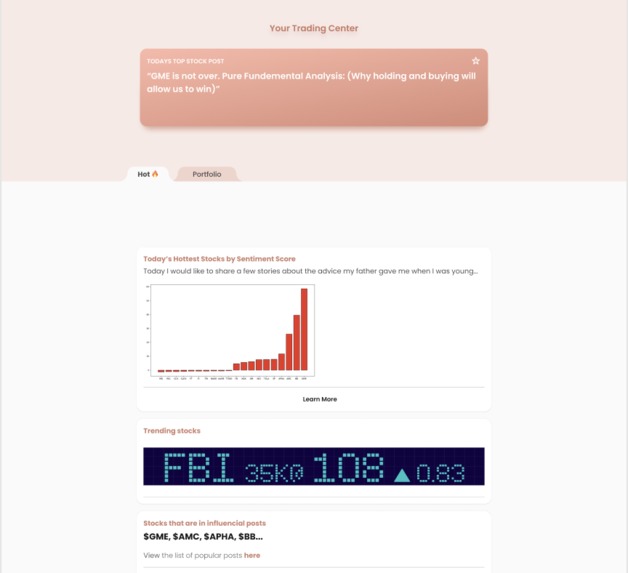
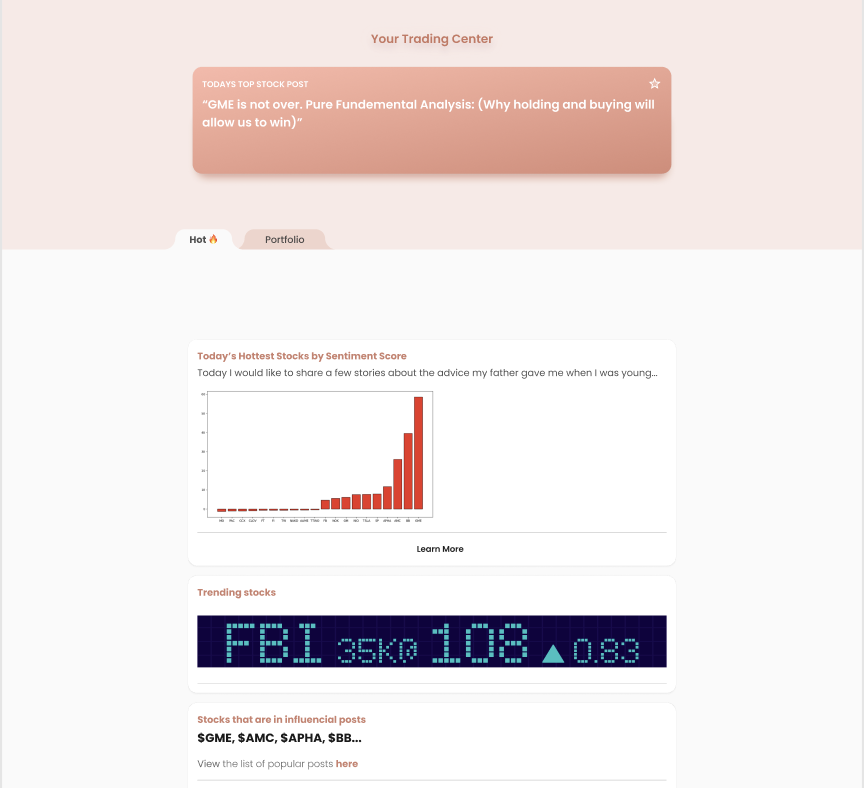
Our web platform prototype
Inspiration
Recently, we have observed that stocks can be heavily influenced by social media, especially Reddit. Now more than ever, people are investing their money in the stock market, but have trouble knowing where to start. Our goal was to determine how much trends in trading forums can affect the stocks market, and additionally, can we select which stocks are being talked about the most, while using machine learning to analyze the sentiment of these trends, to see if it can predict a sudden rise or drop in a stock. From this data, we believe we can give traders–new and old–comprehensive information on the social sentiment and influences of popular stocks.
What it does
Based on our inspiration, we decided to concentrate on the social factors affecting stock trends, and not historical data. Our program looks at all of the tickers on the stock market, and finds matches within top reddit posts and comments. It then uses sentiment analysis on the text said post or comment, and determines if the text is talking about the stock in a favorable or unfavorable way, on a scale from -1 to 1. Once we have this information, we plot 3 metrics for estimated stock activity: The top 10 most talked about stocks, stocks with highest aggregated sentiment scores, and the highest and lowest average sentiment scores.
An additional feature we added is a machine learning NLP information extraction model along with Reddit post karma and awards to filter subreddits to extract the most important and influential Reddit posts.
How we built it
We scraped popular trading forums on Reddit for posts including a large dictionary of stock tickers using PRAW. We then built a sentiment analysis and information extraction algorithm using NLTK, trained on Reddit posts and stock data. We also used pandas to filter posts by a list of current companies traded on the New York Stock Exchange, NASDAQ, and American Stock Exchange.
Challenges we ran into
One of the largest problems facing us was the challenge of parsing large amounts of text into a format that would be able to be manipulated by the computer. For example, the computer cannot tell the difference between the stock ticker capital “A” and someone typing the word “A” at the beginning of a sentence. This happened with a large number of the tickers. Additionally, we ran into the problem of people not using the full name of companies in colloquial language. For example, someone may say Toyota is going up, while our data file lists Toyota as Toyota Motor Vehicles Incorporated Common Stock. We decided there was no way to reasonably check for every possible permutation of what a company could be called.
Accomplishments that we're proud of
We are proud that although none of us had experience with web scraping, we were able to successfully use the Reddit API to get data and be able to compare that with a separate csv of tickers in order to quantify social influence on stocks.
What's next for Lift Off
We started creating a web based platform for viewing a myriad of data that we believe to be highly important. Moving forward, we would like to visualize features that we implemented such as using information extraction and Reddit post karma and awards to filter subreddits and present important posts to users, in order to drastically decrease time endlessly scrolling through unimportant information.
Additionally we hope to use our algorithm and platform on separate forums such as Investopedia and Twitter.


Log in or sign up for Devpost to join the conversation.