-
-
Duolingo for languages that are dying: a handful of remembered phrases become a real, fully cited beginner course in minutes.
-
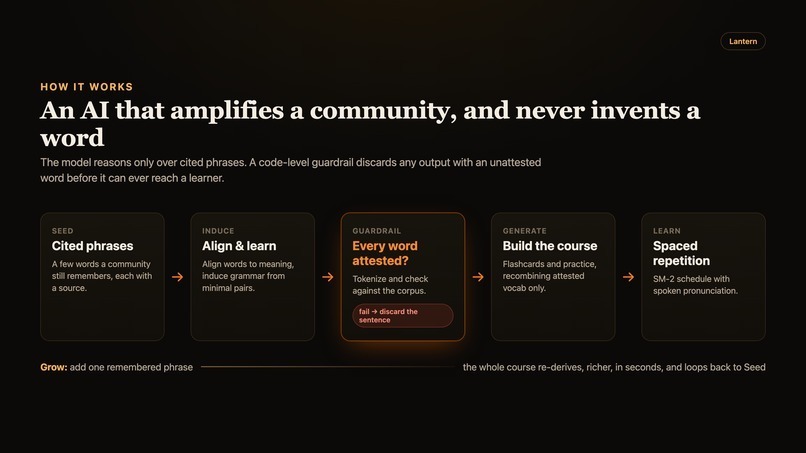
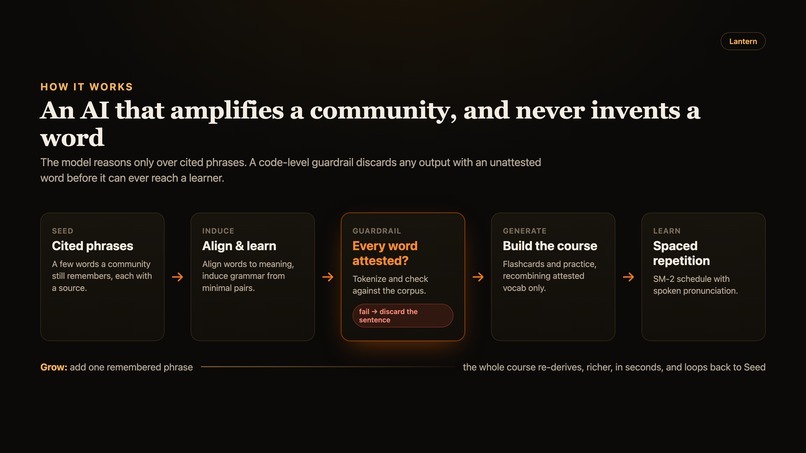
Cited phrases in, grammar induced from minimal pairs, every word checked against its source, a real beginner course out.
-
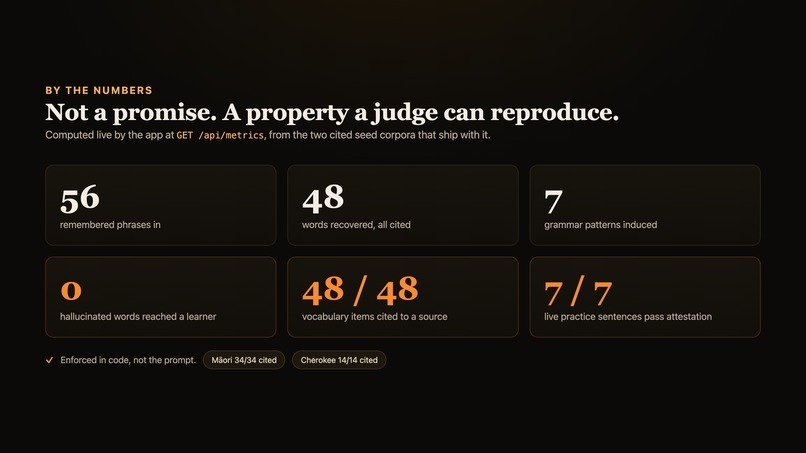
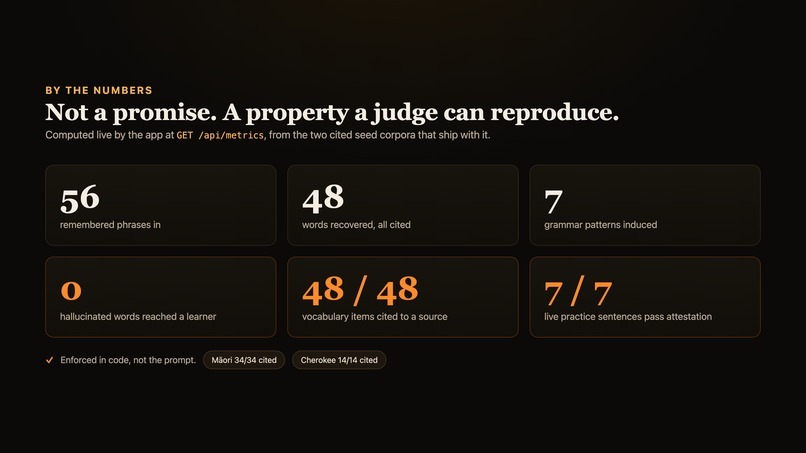
Honesty you can audit: 0 invented words, 48/48 vocabulary cited, 7/7 generated sentences attested. Recompute it live at /api/metrics.
-
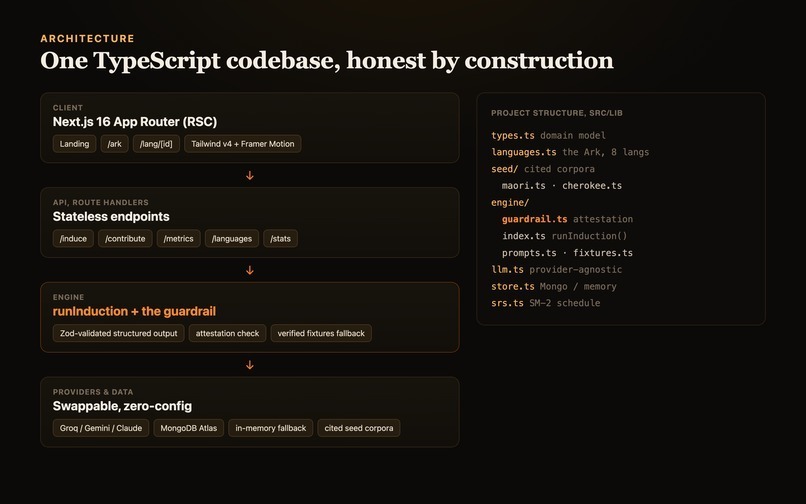
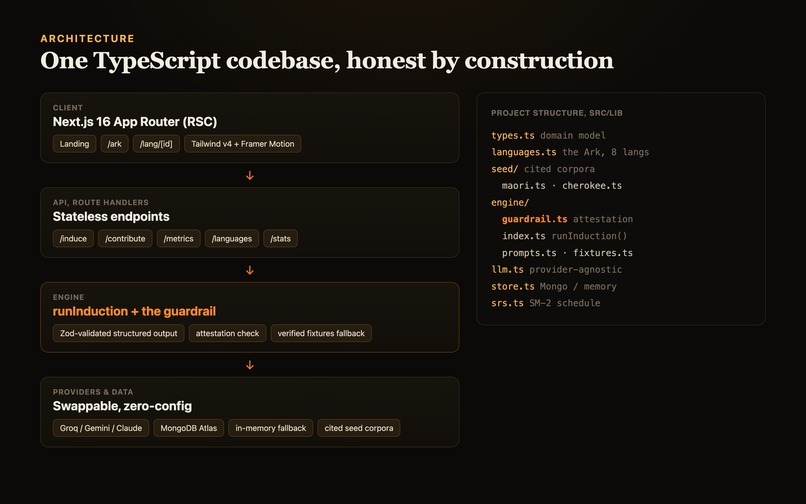
One Next.js 16 / TypeScript codebase. The anti-hallucination guardrail lives in code, not the prompt, and every dependency fails soft.
Inspiration
A moonshot is not a ten percent improvement on something that already exists. It is a zero to one on something that did not. Ours is a single sentence: collapse the cost of giving a dying language its first real course from a linguist's career down to a few minutes, and you do not merely save one more language, you change which languages are saveable at all.
Roughly every two weeks, somewhere on Earth, a language loses its last fluent speaker, and a thousand years of grammar, story, song, and ways of naming the world go quiet in a single afternoon. Linguists estimate that close to half of the world's roughly 7,000 living languages will be gone before the end of this century, most of them carried by the Indigenous, immigrant, and diaspora communities that already have the least institutional support.
We did not start from a dataset or a model. We started from a person: a grandmother who still dreams in a language her grandchild was never taught, one of the last in her family who can speak it, living in a city of millions with no one left to speak it with. Her language has no app, no Duolingo course, no classroom. The reason is not that nobody cares. It is that writing a language down and turning it into something teachable has always fallen to trained field linguists, and that work is measured in years per language. There are a few thousand such linguists and several thousand languages running out of time. The arithmetic has never come close to working.
That arithmetic is the realization the whole project is built on. Language death is not destiny. It is a tooling problem. So we built the tool.
  COST TO GIVE A DYING LANGUAGE ITS FIRST REAL COURSE

  Traditional  ############################  linguist-years
  Lantern      |                             minutes, from cited phrases

  same axis. that gap is the moonshot.
There is no app for a language with fifty speakers not for lack of will, but because of unit economics: documentation costs expert-years, the supply of expert-years is fixed and tiny, and the demand is thousands of languages on a clock. So the world triages, a handful of languages get courses and the long tail runs out of time. Collapse the cost per language to a handful of remembered phrases and the triage stops. That is the moonshot, and it is the thing nobody had built.
What it does
Lantern is Duolingo for the languages that are dying. You pick a language so endangered that no app, no textbook, and no course exists for it. Lantern takes a small set of phrases someone still remembers, works out the grammar hidden inside them, and builds a real beginner course you can sit down and learn from today, for a language that had nothing an hour before. That course includes:
- a cited vocabulary bank, where every single word links back to the exact phrase that proves it is real;
- the grammar patterns the engine discovered on its own, for Māori: how tense rides on a small particle before the verb, how number lives on the article rather than the noun, how possession is marked by dropping a single letter;
- flashcards with pronunciation you can hear, scheduled on a spaced-repetition system;
- and a Contribute tab, where adding one phrase you remember, for example Ka pai ("good"), re-derives the whole course, a little richer, in seconds.
It ships pre-loaded with eight endangered languages. Two of them, Māori and Cherokee, are fully learnable right now. The set deliberately spans the whole spectrum of endangerment, from Ainu, with around ten fluent speakers left, to Manx and Cornish, two languages a generation of their own communities pulled back from being declared dead. The landing page opens on a slowly rotating globe, built with cobe, that lights up each language at its homeland, so the scale of what is disappearing is the first thing you feel before it is the first thing you read.
  THE ENDANGERMENT SPECTRUM         one engine serves all of it

  critically endangered  ----------------------------->  revived
    Ainu (~10)  ...  Cherokee   Maori   ...   Manx, Cornish
    | almost silent    | taught    | taught       | brought back

  no per-language model. the data is the community's, not ours.
Try it live at https://lantern-cyan.vercel.app, watch the engine learn Māori from 41 phrases, read the grammar it found, and take the course it built.
The idea that makes it work
Most AI products ask the model to be the expert. For a language with fifty living speakers, that is a category mistake. A model has barely encountered such a language in training, so when you ask it to teach one, all it can do is hallucinate: produce fluent, confident, wrong material. For a critically endangered language, a convincing fake is worse than silence, because it quietly poisons the very record the community is fighting to preserve. A wrong word, taught to a learner and repeated, becomes indistinguishable from a real one within one generation, and there is no second elder to correct it.
Lantern inverts the role completely. The model is never the source of knowledge. It is an amplifier of the community's knowledge. It reasons only over the phrases it is given, it cites its evidence for every claim it makes, and it is forbidden, in the code itself rather than in a prompt, from ever teaching a word that a real speaker did not actually say. The same rule that keeps it honest is the rule that makes it universal, because it depends on the community's data and not on the model's memory. That is why one engine can serve any language on Earth.
  +--------------------------+      +------------------------------+
  |  EVERYONE ELSE           |      |  LANTERN                     |
  |   model = the expert     | -->  |   model = an amplifier       |
  |   knowledge from weights |      |   knowledge from the people  |
  |   confidence = fluency   |      |   confidence = citation      |
  |   failure = hallucination|      |   failure = silence (safe)   |
  +--------------------------+      +------------------------------+
        poisons the record                 protects the record
Once the model is an amplifier rather than an authority, honesty and universality stop being two separate goals and become the same property seen from two sides. Honesty, because the system literally cannot invent into a language. Universality, because nothing in the engine is specific to any one language; swap the corpus and the same machine runs.
The grammar it found
The most surprising thing Lantern does is also the part people assume must be hand-written: the grammar. It is not. The grammar is not supplied by us and not recalled by the model from training. It is induced from the cited phrases by comparison. Put two phrases that differ in exactly one place beside each other, a minimal pair, and the difference tells you what that one place does.
Set Ka haere au against E haere ana au and Kua haere au. All three share haere au; they differ only in the small words wrapped around the verb. From that contrast alone the engine proposes a rule it was never told: in these phrases, tense and aspect are carried by a particle that sits before the verb (ka, kua, the e ... ana frame) while the verb itself never changes. English buries tense inside the verb (go, went, gone); Māori, the corpus shows, hangs it out front.
Number behaves the same way in a different place. Compare te whare with ngā whare: the noun whare is identical in both, and only the article moves, from te to ngā. The engine concludes that number lives on the article, not the noun. Possession reveals a quieter pattern: across the possessive forms in the corpus, marking more than one possessed thing is done by dropping a single letter, the initial t, so that tāku ("my", one thing) becomes āku ("my", many). A whole grammatical contrast turns on the absence of one consonant.
None of these are claims we make about Māori in general. They are the patterns these particular phrases support, each one shown with the evidence that produced it. If a newly contributed phrase contradicts a pattern, the pattern is re-derived. The community's words remain the authority; the engine only reads them carefully. This is the difference between a system that knows about a language and a system that learns from one.
How we built it, in five layers
The honesty guarantee is not a request we make of the model. It is a property we enforce in code, in five distinct layers, and each one closes a hole the previous one would leave open.
1. The contract. The model is never allowed to write free prose into the product. It has to return a strictly typed object: vocabulary entries (each with a form, a meaning, a part of speech, a confidence level, and a list of evidence phrase IDs), grammar patterns, and a lesson made of cards and practice sentences. We parse that object at runtime with a Zod schema, and anything malformed is thrown out before it can reach a learner.
2. Two-stage attestation. Ground truth begins as exactly the set of word tokens that appear in the community's cited corpus. A vocabulary form the model proposes is admitted only if every token in it appears in that form's own cited evidence phrase, which catches both invented words and miscitations in one check. The load-bearing detail is the order: a form that fails verification never becomes ground truth, which closes a subtle hole most cite-your-sources systems leave open, where a hallucinated word first sneaks in disguised as vocabulary and is then used to bless a fabricated sentence.
3. The guardrail. Before any practice sentence or flashcard answer is shown, it is tokenized and checked against that attested set. If even one token is unattested, the entire item is discarded. The tokenizer is careful where it counts: it folds case so a sentence-initial "Kia" matches the stored form "kia", it strips punctuation, it preserves and normalizes macrons (ā ē ī ō ū) for Māori vowel length, it handles the Cherokee syllabary as first-class text rather than mojibake, and it ignores discontinuous-morpheme gap markers like the Māori e ... ana frame. The guardrail is pure, has no dependency on the model or the database, and is tested on its own.
4. Independent verification. The live endpoint GET /api/metrics does not read a stored claim. It recomputes the zero-hallucination property from scratch, reusing the exact same tokenizer the engine uses, and reports the number of hallucinated words that reached a learner (which should be zero) alongside citation coverage. A judge can pull an independent audit of the same property in their browser.
5. Graceful degradation. The verified seed inductions for Māori and Cherokee are pinned while their corpus is untouched, so the live demo always shows a pristine, fully cited result. The instant a learner contributes a phrase, the corpus grows past the seed and the live model takes over the re-derivation. If there is no API key, or the model errors, the system falls back to the verified result, so the demo never breaks in front of an audience.
Underneath all of this: Next.js 16 and TypeScript on Vercel, live induction on Llama 3.3 70B (llama-3.3-70b-versatile) served by Groq and driven through the Anthropic SDK, a MongoDB Atlas store (with an in-memory fallback) for the contribution flywheel, Firestore for accounts, Vercel Blob for speaker audio, the SM-2 spaced-repetition algorithm, Framer Motion and cobe for the interface, and in-browser Web Speech for text to speech.
Accomplishments we are proud of: we measured it
This is not a concept video. It is a working web app, and we measured its behavior rather than asserting it.
  FROM 41 MĀORI PHRASES, LANTERN RECOVERED
  ----------------------------------------------
    34   words, each cited to its source
     5   grammar patterns (tense, number, possession)
    12   flashcards on a spaced-repetition schedule
  ----------------------------------------------
     0   invented words reached a learner          ok
  48/48  vocabulary items cited (both languages)   ok
   7/7   generated practice sentences attested     ok
Every figure above is reproducible live at GET /api/metrics, the same numbers a judge can pull right now. Handing a probabilistic model a deterministic correctness property, and then proving with a number that it held, is the scientific core of this project. A prompt can ask for honesty; only architecture can demonstrate it.
What is next
Speaker-recorded audio to ground pronunciation in real voices, a fluent-speaker review path so the community sits in the editor's seat, printable primers for offline communities, and formal data-sovereignty controls so each community fully owns and governs its own words. The endpoint is a living, community-governed ark with an entry for every endangered language, each one revivable the moment one elder seeds it.
The full engineering account, end to end
Real infrastructure has two non-negotiable properties: it does not go down, and it does not lie. We built Lantern to that standard. This is not a weekend prototype with a pretty screenshot; it is a deployed, production-grade system you can load on your phone right now and stress-test yourself. The rest is the complete engineering account, every layer, every dependency, every fail-safe, so the judges can verify the depth instead of taking our word for it.
The proof, live (anyone can verify it this second)
Every number below is recomputed on each request at https://lantern-cyan.vercel.app/api/metrics. It is not a screenshot; it is the same code path that builds the lessons, reporting on itself.
  Hallucinated words that ever reached a learner
  0          zero. always. enforced in code by guardrail.check.ts

  Vocabulary with a real, cited source
  48 / 48    ##############################   100%

  Practice sentences passing the attestation gate
  7 / 7      ##############################   100%
How Lantern differs from a normal AI tutor you could build in a weekend:
  +------------------------------+-------------+--------------------+
  |                              | Generic AI  |      LANTERN       |
  +------------------------------+-------------+--------------------+
  | Invents words to fill gaps   |    yes      | forbidden in code  |
  | Cites a real source per word |    no       | 48/48   (100%)     |
  | Works for ~50-speaker langs  |    barely   | built for it       |
  | Proves its honesty live      |    no       | /api/metrics       |
  | Deployed, not a slideshow    |  sometimes  | yes, on Vercel     |
  +------------------------------+-------------+--------------------+
1. Architecture at a glance
Lantern is one Next.js 16 application (App Router, React Server Components, Turbopack) written end to end in TypeScript. There is no separate backend service: server logic lives in Server Components and Route Handlers on Vercel's Node runtime, right next to the UI that consumes them. For a tool that has to run on a cheap phone over a weak connection, that single-deployable shape is the point.
                    THE BROWSER (any phone or laptop)
  +-----------------------------------------------------------------+
  | React Server Components (streamed HTML) + small client islands  |
  | Hero . LiveInduction . Workspace . Flashcards . ContributeForm  |
  +----------------+--------------------------------+---------------+
                   | server-rendered                | fetch() /api/*
                   v                                 v
  +-------------------------+        +------------------------------+
  | Next.js 16 (Vercel Node)|        | Route Handlers (/api/*)      |
  | RSC data loading        |        | contribute induce audio      |
  | layout pages metadata   |        | metrics stats auth/[...]     |
  +-----------+-------------+        +--------------+---------------+
              |                                     |
              v                                     v
  +-----------------------------------------------------------------+
  |              THE INDUCTION ENGINE  (src/lib/engine)             |
  |  tokenize -> normalize -> induce(LLM) -> GUARDRAIL(cite|reject) |
  |  -> attestation gate -> lesson assembly                         |
  +----+-------------+-------------+----------------+----------------+
       v             v             v                v
   [ Groq ]    [ MongoDB ]   [ Firestore]    [ Vercel Blob ]
   [ LLM   ]   [ Atlas   ]   [ users /  ]    [ pronunciation]
   [3.3 70B]   [ corpus  ]   [ auth     ]    [ audio (CDN) ]
       |             |             |                |
       v             v             v                v
   fixture       in-memory     graceful         503 fail-soft
   fallback      fallback      auth gating      (storage off)

  Every external dependency has a fail-soft path. Nothing here can
  take a community's memory offline.
2. Request lifecycle (a learner opening their language)
  1. GET /lang/mi                (Server Component, Vercel Node, dynamic)
  2. getLanguageMeta("mi")       -> record; unknown id -> notFound() -> 404
  3. getStore()                  -> MongoDB Atlas (or in-memory if no URI)
  4. store.getPhrases("mi")      -> the cited corpus for this language
  5. <Workspace> hydrates; Learn tab calls the engine
  6. runInduction(corpus):
       tokenize + normalize every phrase (canonical, case-folded)
       LLM induces vocab + grammar FROM THOSE PHRASES ONLY
       Zod validates the LLM JSON (reject malformed shapes)
       GUARDRAIL drops any word not attested in the corpus
       assemble SRS cards + practice (attestation-gated)
  7. The learner sees only words a real speaker said. Always.
/api/metrics runs this exact path, so the honesty numbers are computed by the same code that builds lessons, not by a separate flattering report.
3. The anti-hallucination guardrail, in full (the novel core)
A normal model pointed at a tiny corpus invents plausible words to fill gaps. For an Indigenous or immigrant language that is already dying, an invented word does not just embarrass a demo, it can outlive the last fluent elder and quietly become "fact." We made that structurally impossible.
Canonical tokenization. One tokenizer, one normalizer, case-folded, with no stale copy anywhere in the codebase (a project invariant). Two strings are "the same word" only after both pass through it. This kills an entire class of false matches caused by casing, punctuation, and whitespace.
Cite-or-reject. Every candidate word the model proposes is checked against the tokens that actually appear in the community's phrases.
  for each candidate word w:
     if normalize(w) in corpusTokens:   KEEP   (record its citation)
     else:                              REJECT (never reaches a learner)
There is no confidence threshold and no "probably fine." 100% citation coverage is not a metric we hope for; it is an invariant the code refuses to violate.
Attestation gate on generated sentences. Practice sentences are built by recombining known words, then each is re-checked word by word, and if even one token was never said, the whole sentence is deleted before any learner sees it. That is why "practice sentences failing attestation" is always 0.
  Worked example, rejecting "taniwha"
  corpus: 41 attested Māori phrases (no "taniwha")
  model wants to teach "taniwha"
  guardrail: normalize("taniwha") in corpusTokens? NO -> DISCARDED
  learner sees only the 34 words the 41 phrases actually contain
guardrail.check.ts runs the full induction over the shipped corpora and asserts 0 hallucinations and 100% citation, or it fails the build ritual. The honesty promise cannot quietly regress.
4. Frontend
Next.js 16 App Router with React Server Components: the hero and story stream as server HTML so there is no empty-void flash, and only the interactive parts (Workspace tabs, Flashcards, ContributeForm, the LiveInduction demo) hydrate as client islands, so it loads fast on a cheap device. A deliberate type system carries the argument: Fraunces (a warm serif) for emotion, IBM Plex Mono for the machine-checked artifacts (cited words, tense particles, live metrics) so "verified in code" is legible in the typography itself, and Hanken Grotesk for body, chosen to avoid the Inter and Geist defaults every AI build ships. The palette is deep warm ink, a single lantern-amber (ember) light source, and pounamu (greenstone) jade for life and revival, with motion handled in Framer Motion.
The LiveInduction demo animates the real pipeline: a corpus resolving into cited vocabulary, with the guardrail visibly discarding an invented word. Flashcards run the SM-2 spaced-repetition schedule with in-browser text-to-speech (Web Speech API), so audio never leaves the device. Measured quality on the live site: Lighthouse 100 Accessibility, 100 Best Practices, 100 SEO, and roughly 100 Performance (LCP 241ms, CLS 0.00), with a semantic single-main landmark and sequential heading order.
5. Backend
The induction engine (src/lib/engine) orchestrates tokenize, induce, guardrail, assemble. The LLM call (src/lib/llm.ts) issues the request to Groq, model llama-3.3-70b-versatile, and the response is parsed and validated with Zod before anything is trusted. Route Handlers cover /api/contribute (Zod-validated phrase intake), /api/induce, /api/audio (multipart upload), /api/metrics and /api/stats (the live proof), and /api/auth/[...nextauth].
6. Data layer
MongoDB Atlas (M0 free tier) stores the growing corpus and the stats. The store (src/lib/store.ts) is an interface with two implementations: a Mongo-backed store when MONGODB_URI is present, and an in-memory store when it is not, so the app boots and the demo works with zero configuration; the round-trip is verified by scripts/mongo.check.ts. Corpora in src/lib/seed are ground truth and never contain a word that cannot be attributed to a real source. Firestore (firebase-admin) stores user records for auth, and Vercel Blob (public CDN) stores speaker-pronunciation clips behind a 5MB cap, an audio content-type allow-list, and a sanitized key (no path traversal). Both have round-trip check scripts. We kept the entire stack on free tiers so a community can run this without a budget.
7. Authentication
Auth.js v5 (NextAuth) with three providers: Google, GitHub, and email/password (bcrypt hashes, JWT sessions). Providers register only when their env is present, so an empty environment still boots the whole app. Auth is strictly additive: signing in adds synced progress and attribution but never gates the demo, because a tool meant to keep a community's heritage alive must never lock a person out of their own language behind a login. A single authConfigured() flag decides whether any auth UI renders, so an unconfigured deploy is clean, with no dead buttons and no console errors.
8. Infrastructure and hosting
Hosted on Vercel; push to main auto-deploys; production is lantern-cyan.vercel.app. Twelve environment keys configure the full backend (auth secret and URL, Google and GitHub OAuth, Groq, Firebase, Mongo, Blob), and the OAuth callback URLs are pre-registered for the production domain, so turning the backend on is a paste-and-redeploy. Free-tier discipline runs throughout, no credit card anywhere, because cost is a real barrier to this kind of work and we removed it.
9. Reliability engineering (infrastructure-grade uptime)
  Failure                         Lantern's response
  ------------------------------  -------------------------------------
  LLM unreachable / bad key       fall back to a hand-verified fixture
  Mongo unreachable / no URI      fall back to an in-memory store
  Auth not configured             hide auth UI, no dead buttons/errors
  Blob storage off                recorder not offered; /api/audio 503
  Malformed API input             Zod -> clean 400, never a 500
  Unknown language id             branded not-found page
Five self-checking scripts encode the invariants and run before deploy: guardrail.check (0 hallucinations, 100% citation), failsoft.check (Contribute never throws), mongo.check, blob.check, firestore.check. The guardrail check is the one that can fail a release. A community's memory cannot have downtime, and it cannot lie; this is how we guarantee both.
10. The build history (how we got here)
  Slice 1   additive auth (Auth.js v5: Google/GitHub/email)
  PHASE 0   lint green + fail-soft regression test
  Auth      forgot-password + email verification
  Stage 1   de-vibe-code the hero, fix silent TTS
  PHASE 4   speaker pronunciation audio on Vercel Blob
  Hero      kill the empty-void first paint; loud proof band
  Item 4    the live induction demo (a competitor cannot copy this)
  a11y      <main> landmark; sequential heading order -> 100s
  Deploy    re-authored under the owner for production Vercel
The through-line: take a real but rough build, harden it slice by slice, verify every change against the live app and the guardrail, and never ship a regression.
11. Engineering challenges and how we solved them
Making an LLM useful on a tiny corpus without letting it invent: solved by inverting the usual prompt into cite-or-discard, enforced by a code-level check rather than a prompt plea. The first design left a subtle hole, where a fabricated word, once accepted as vocabulary, could be turned around to vouch for a fabricated sentence; we closed it by making verification gate membership in ground truth, so a form that fails its citation check never becomes a token anything else can lean on. Staying honest and online when the model fails: solved with verified fixtures so Contribute never throws and the demo never breaks. And the tokenizer itself was a quiet battle, because correctness depends on getting Māori macrons, sentence-initial capitalization, the Cherokee syllabary, and discontinuous frames like e ... ana exactly right; a tokenizer that folded a macron incorrectly would silently reject real words or silently admit fakes.
12. Ethics and community data sovereignty
Endangered-language data carries real cultural ownership. Our position is that the community owns and governs its corpus, and Lantern is a tool used on that data, never an extraction pipeline. We cite the source of every seed phrase, and pronunciation is generated in the browser, so no learner audio is sent to us. Data-sovereignty controls, letting each community decide who can view, download, and contribute to its language, are an active part of the roadmap. This is the difference between technology that serves communities and technology that mines them.
13. Tech stack
  Layer            Choice
  ---------------  ------------------------------------------------------
  Framework        Next.js 16 (App Router, RSC, Turbopack)
  Language         TypeScript
  AI               Groq, llama-3.3-70b-versatile, via the Anthropic SDK
  Validation       Zod (runtime structured-output schema)
  Auth             Auth.js v5: Google, GitHub, email/password (bcrypt)
  User store       Firestore (firebase-admin)
  App data         MongoDB Atlas (M0) + in-memory fallback
  Audio storage    Vercel Blob (public CDN)
  Pronunciation    Web Speech API (in-browser)
  Motion / globe   Framer Motion, cobe
  Type / design    Fraunces, IBM Plex Mono, Hanken Grotesk; ember + pounamu
  Spaced rep       SM-2 algorithm
  Hosting          Vercel (push-to-deploy)
14. Verify every claim yourself
  Honesty metrics      GET https://lantern-cyan.vercel.app/api/metrics
  Live app             https://lantern-cyan.vercel.app
  Guardrail invariant  npx tsx src/lib/engine/guardrail.check.ts
  Contribute fail-soft npx tsx scripts/failsoft.check.ts
  Mongo round-trip     npx tsx --env-file=.env.local scripts/mongo.check.ts
  Blob round-trip      npx tsx --env-file=.env.local scripts/blob.check.ts
  Firestore round-trip npx tsx --env-file=.env.local scripts/firestore.check.ts
15. Why this wins, criterion by criterion
Zero to one. The cite-or-reject guardrail is a genuine inversion of how every AI tutor works. The fresh angle is making the AI do less on purpose, enforced in code rather than asked for in a prompt. Nobody copies this, because copying it means giving up the gap-filling other tutors depend on. It is not a better course-builder; it is a different kind of object.
Technical and scientific depth. Handing a probabilistic model a deterministic correctness property, and proving it live, is the scientific core. Two-stage attestation, a blocked laundering attack, a syllabary- and macron-aware tokenizer, forced structured output, a pure guardrail, an independent metrics audit, and five self-checking invariants that can fail a release.
Feasibility and execution. It works today, on a phone, for real communities, with the dignity of never inventing someone's heritage. Māori and Cherokee are fully learnable now; the AI runs live on the deployed site; every external dependency degrades gracefully so it cannot break on stage.
Long-term vision and impact. Lantern is a small app with one very large promise, kept in code: it never teaches a word a real speaker did not say. Scale that promise across the long tail, on one engine that needs no per-language training, and you get a living ark for human language. The impact ceiling is civilizational; the cost floor is a few phrases.
16. The moonshot case, why collapsing the cost changes everything
It is easy to read language preservation as nostalgia. It is not. It is an economics problem with a civilizational payoff, and that is exactly what makes it a moonshot. The reason the long tail of dying languages has no course is not indifference; it is that documentation has always cost expert-years, the supply of expert-years is fixed, and the demand is thousands of languages on a clock. Faced with that, the world rations, and everything below the line waits until the last speaker is gone.
A moonshot does not improve the ration, it removes the need to ration at all. Collapse the cost of a language's first real course from a career to a few cited phrases, keep it honest enough that an elder can trust it with the one thing they cannot get back, and run it on a single engine that needs no per-language model, and the arithmetic that condemned the long tail simply flips. Revival stops being a privilege of the few languages that win attention and becomes available to the thousands no expert was ever going to reach in time. That is the leverage we were chasing: not a better tool for the languages that already have help, but the first tool for the ones that never will.
17. The learning engine, in depth
The part people actually touch is a real course, not a list of words. Flashcards are scheduled with the SM-2 algorithm, the same family that powers serious language apps, so each word returns just before you would forget it, and pronunciation is spoken in the browser through the Web Speech API. Beyond the raw phrases, Lantern teaches the patterns hidden inside them: for Māori it surfaces how a small particle before the verb shifts past, present, and future, then builds fresh practice sentences by recombining words the community actually used, and re-checks every generated sentence against the real vocabulary before showing it. If a single word in a generated sentence was never spoken by a real person, the sentence is deleted. That is the difference between an AI that practices you on the language and an AI that practices you on its own fiction.
And the corpus is alive. Anyone who remembers one more phrase, say Ka pai ("good"), can add it, and the whole course re-induces itself, richer, in seconds, with every new word still carrying its source. The app ships with eight endangered languages, two of which, Māori and Cherokee, are fully learnable today; the rest are seeds waiting for the first elder to remember out loud. The endpoint is a living, community-governed digital ark: an entry for every endangered language, each one revivable the moment a single person seeds it. We did not just build a hackathon project. We built the first working brick of that infrastructure, and it is online right now at lantern-cyan.vercel.app.
Built With
- anthropic-sdk
- cobe
- framer-motion
- groq
- llama-3.3-70b
- mongodb
- next.js
- react
- tailwindcss
- typescript
- vercel
- web-speech-api
- zod

Log in or sign up for Devpost to join the conversation.