-
-
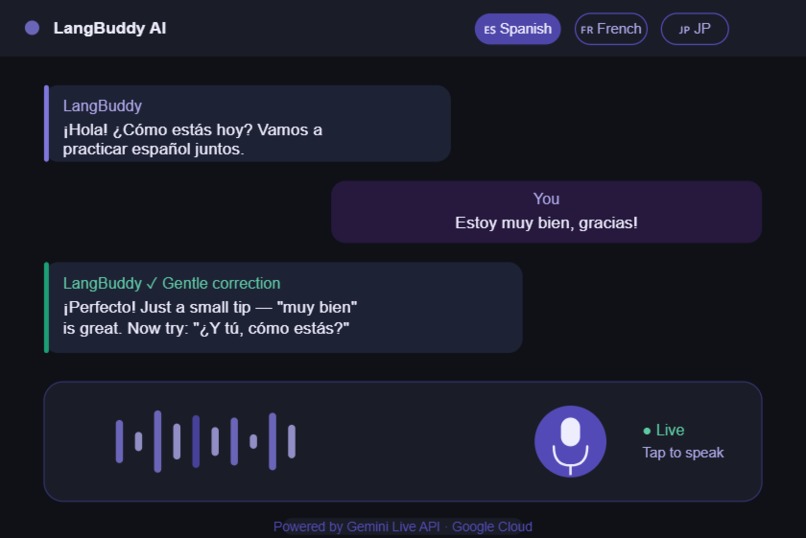
App UI mockup
-
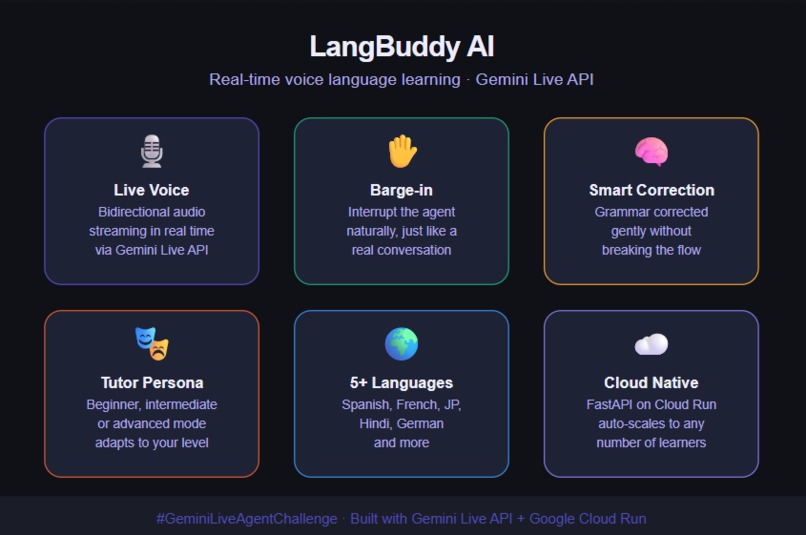
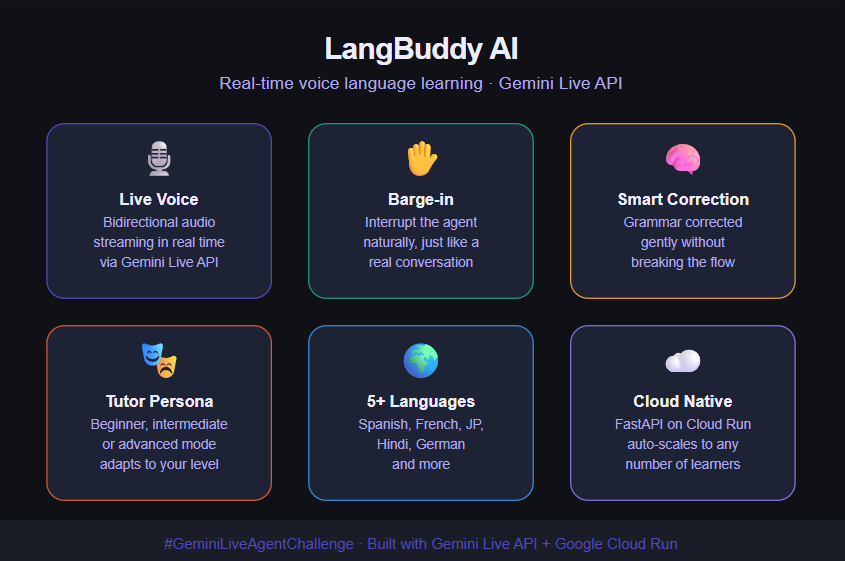
Features overview
-
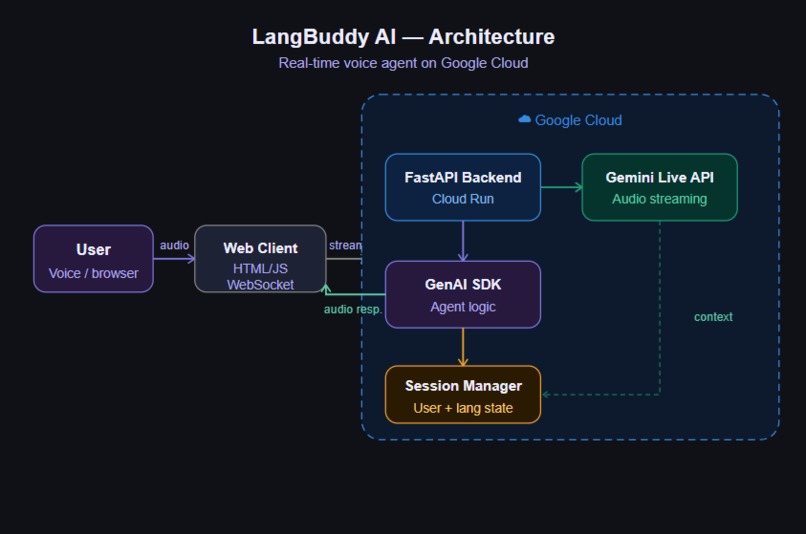
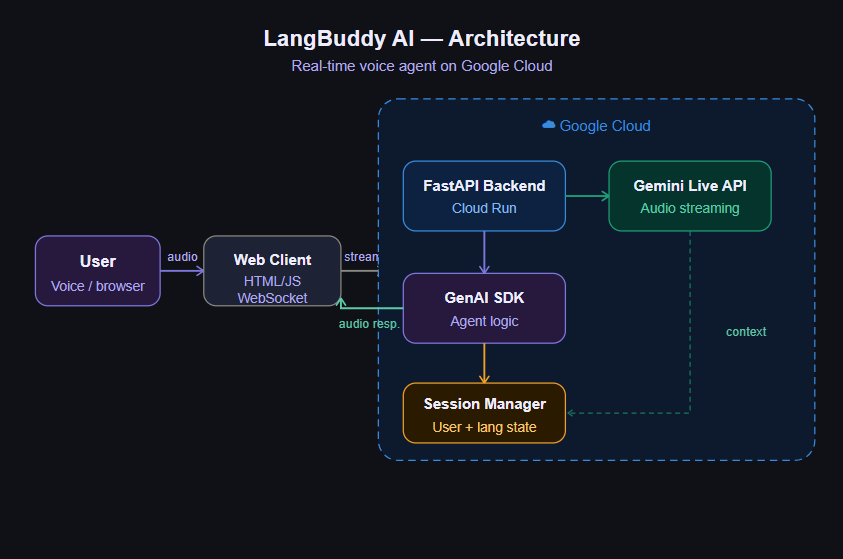
Architecture diagram
🌍 Inspiration
Learning a new language is hard not because of vocabulary or grammar rules but because there's nobody to talk to. Apps give you flashcards. YouTube gives you lectures. But nothing gives you a real conversation partner who is always available, infinitely patient, and gently corrects you without breaking your confidence.
That's why I built LangBuddy AI — a real-time voice conversation partner that lets you actually speak in your target language and get intelligent, natural responses back, just like talking to a native speaker who happens to be a great teacher.
🤖 What It Does
LangBuddy AI is a Live Agent powered by Google's Gemini Live API. You speak to it in any language you're learning as Spanish, French, Japanese, Hindi, and more and it:
- 🎙️ Listens and responds in real time with natural, flowing audio
- ✋ Supports barge-in — interrupt it mid-sentence just like a real conversation
- 🧠 Corrects your grammar gently without breaking the dialogue flow
- 🎭 Adapts its persona — beginner, intermediate, or advanced tutor mode
- 🌐 Runs entirely on Google Cloud for low-latency, scalable performance
🛠️ How I Built It
The stack is intentionally simple and cloud-native:
| Layer | Technology |
|---|---|
| AI Core | Gemini Live API (bidirectional audio) |
| Agent Framework | Google GenAI SDK |
| Backend | Python + FastAPI |
| Hosting | Google Cloud Run |
| Frontend | HTML/JS with WebSocket client |
| State management | In-memory session manager |
The backend opens a bidirectional WebSocket connection with the Gemini Live API, streaming raw audio in and receiving audio responses out. The GenAI SDK handles turn-taking logic, barge-in detection, and the agent's tutor persona via a carefully engineered system prompt.
# Simplified connection to Gemini Live API
async with client.aio.live.connect(model=MODEL, config=config) as session:
    await session.send(input=audio_chunk, end_of_turn=False)
    async for response in session.receive():
        yield response.data
The frontend is a minimal browser client that captures microphone audio, streams it over WebSocket to the FastAPI backend, and plays back the AI's audio response in real time.
☁️ Google Cloud Deployment
LangBuddy AI runs on Google Cloud Run — a fully managed serverless platform that scales automatically to handle concurrent learners. The Gemini Live API connects directly through Vertex AI endpoints, keeping all data processing within the Google Cloud ecosystem.
Deployment is automated via a cloudbuild.yaml script — just push to the repo and Cloud Build handles containerization and deployment.
🧗 Challenges I Faced
1. Real-time audio latency Streaming raw audio over WebSockets while keeping latency under 300ms required careful buffer tuning. Too large a buffer = laggy response. Too small = choppy audio.
2. Barge-in implementation Getting natural interruption to feel smooth was tricky. Gemini Live API supports it natively, but the client-side logic needed to detect when the user starts speaking and immediately signal the session to stop its current output.
3. Persona consistency Keeping the tutor persona consistent across a long conversation — always encouraging, always correcting gently, never breaking into English unless asked — required iterating on the system prompt significantly.
📚 What I Learned
- How Gemini Live API's bidirectional streaming works under the hood — it's genuinely different from a request/response model
- How to deploy a low-latency WebSocket server on Cloud Run with proper concurrency settings
- How powerful system prompts are for shaping agent personality and behavior
- The nuance of designing voice UX — pauses, corrections, and tone matter as much as content
🚀 What's Next
- Add vision mode — hold up your textbook and LangBuddy reads and quizzes you on it
- Progress tracking — remember vocabulary mistakes across sessions
- Pronunciation scoring — grade your accent in real time
- Support for 20+ languages
Built With
- ai
- api
- cloud
- fastapi
- gemini
- genai
- javascript
- live
- python
- run
- sdk
- vertex
- websocket

Log in or sign up for Devpost to join the conversation.