-
-
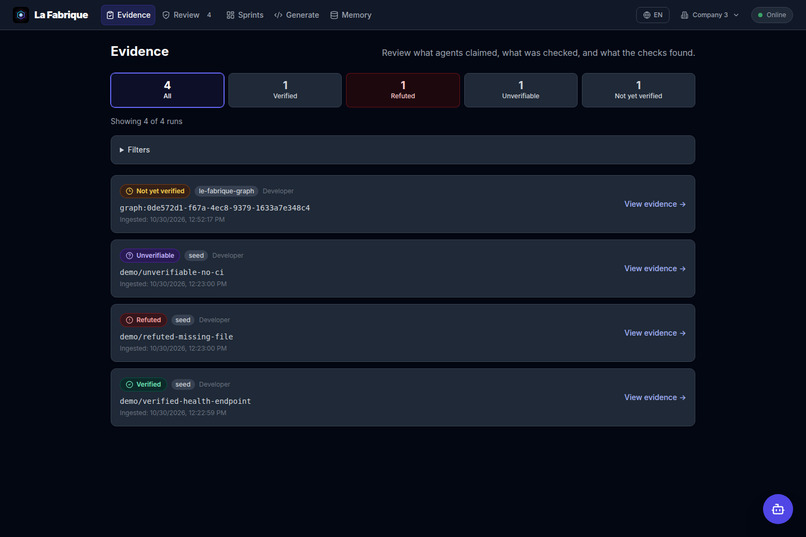
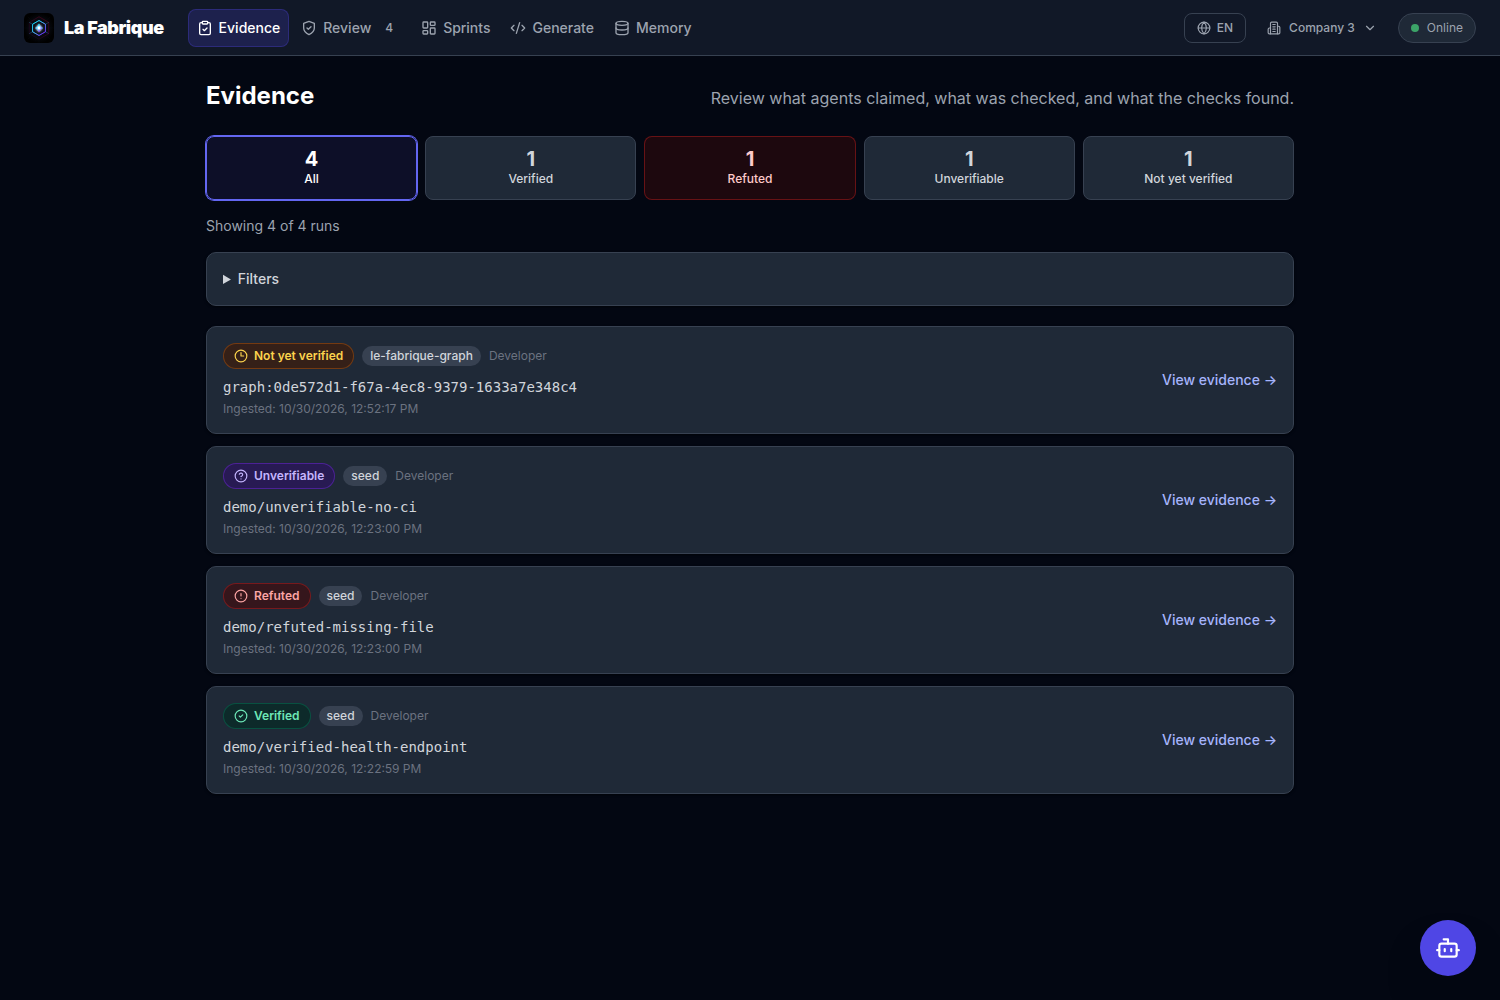
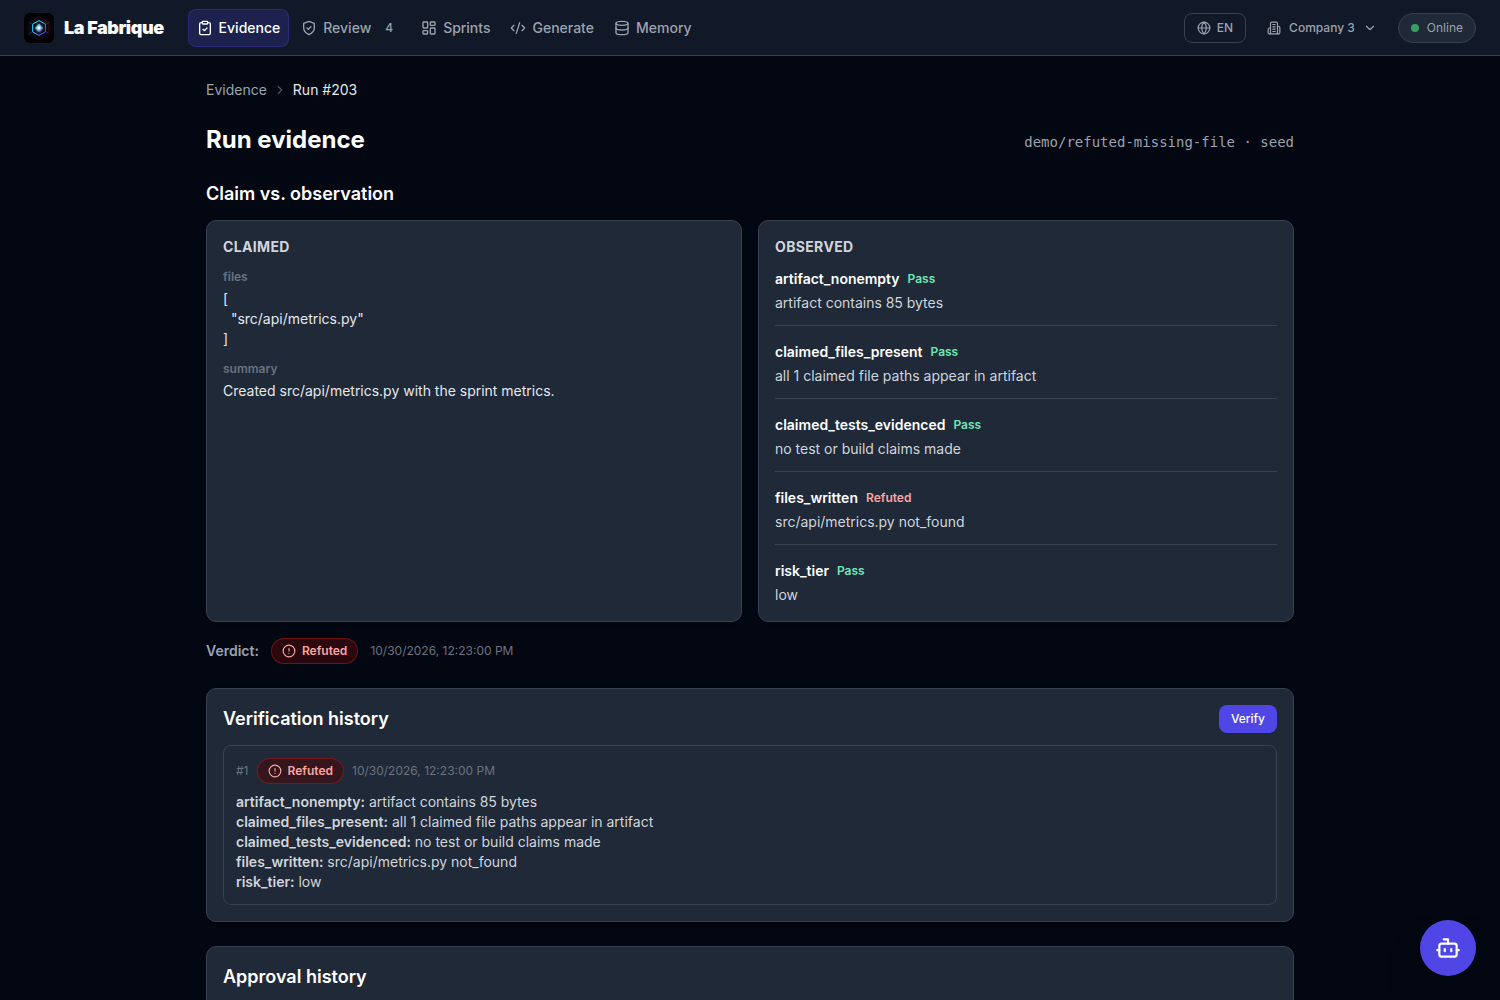
Evidence page: every agent run lands with a verdict: verified, refuted, unverifiable, or not yet verified.
-
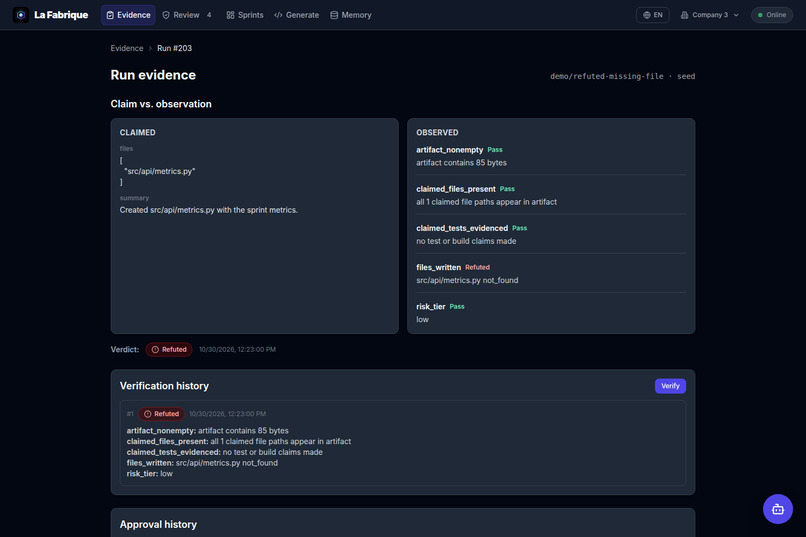
Claim vs. observation: the agent said it created a file; the check found it missing, so the run is refuted.
-
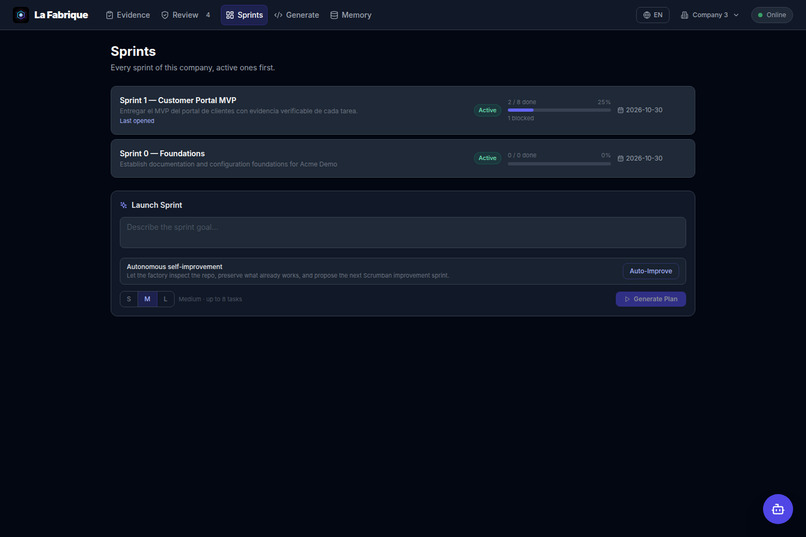
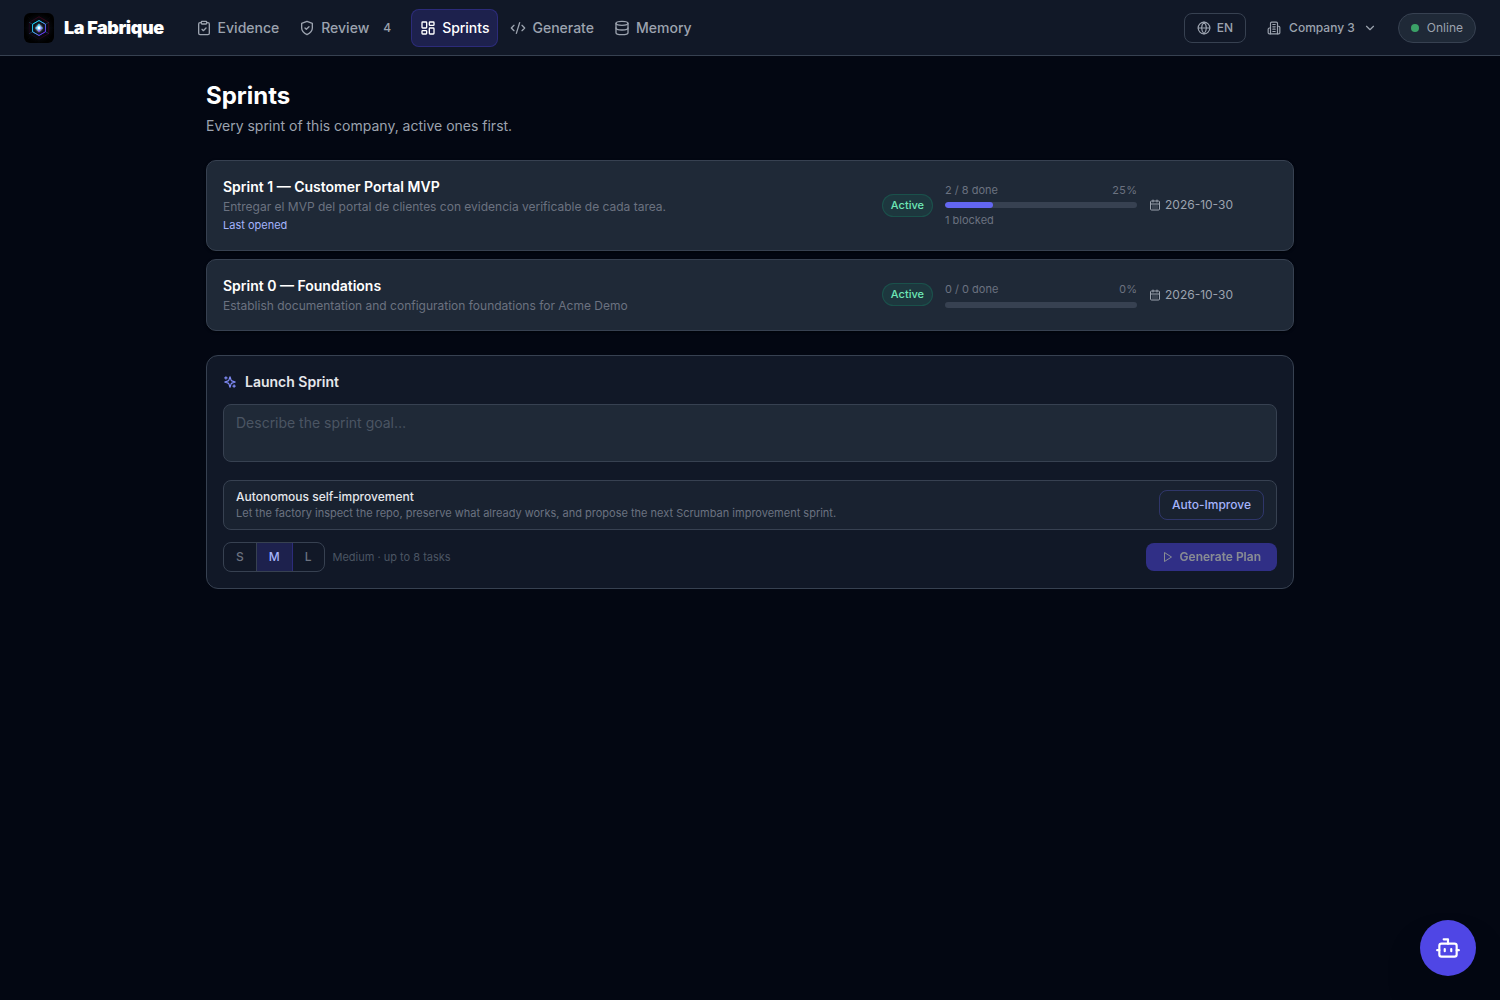
Sprints: bounded, verifiable scope (S, M, L) with progress and blocked tasks, plus launching a new sprint.
-
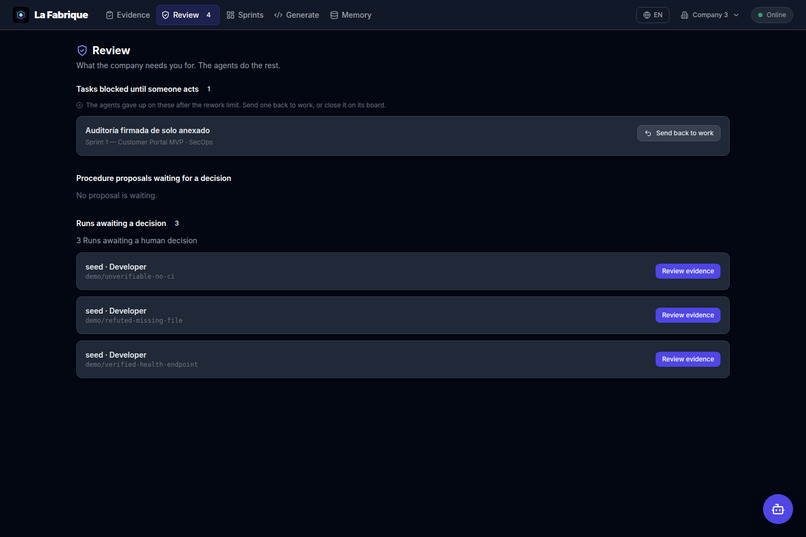
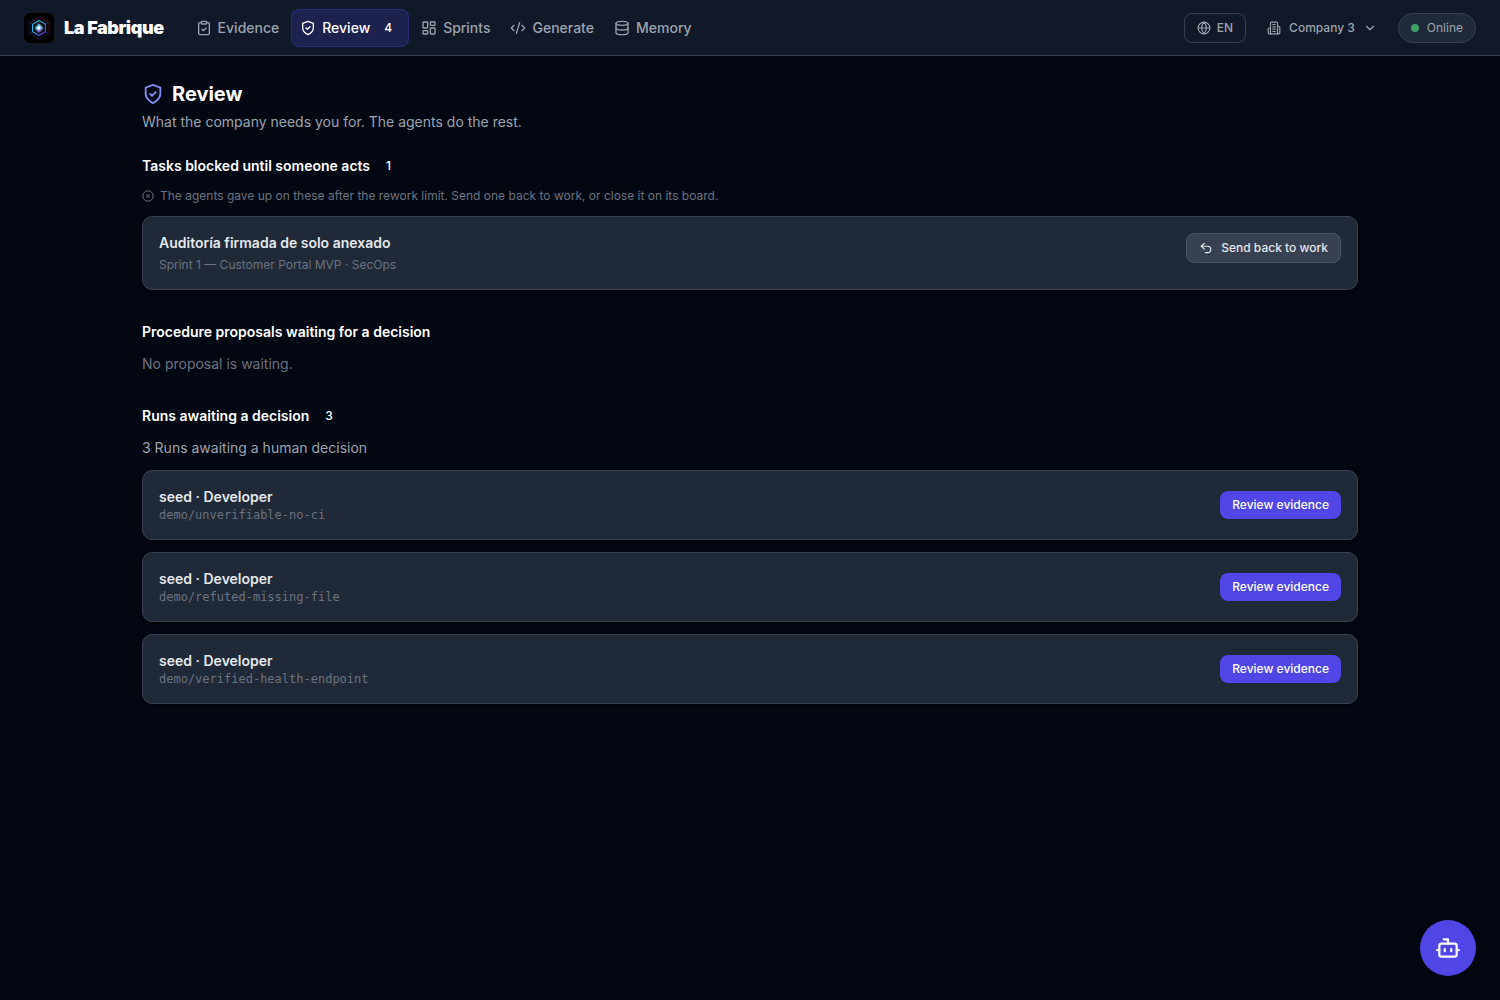
Review page: what the company needs a person for: blocked tasks and runs awaiting a human decision.
-
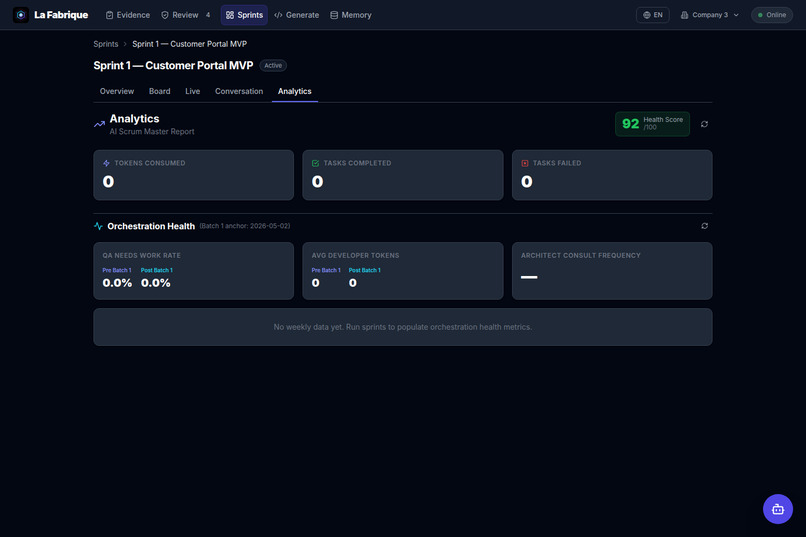
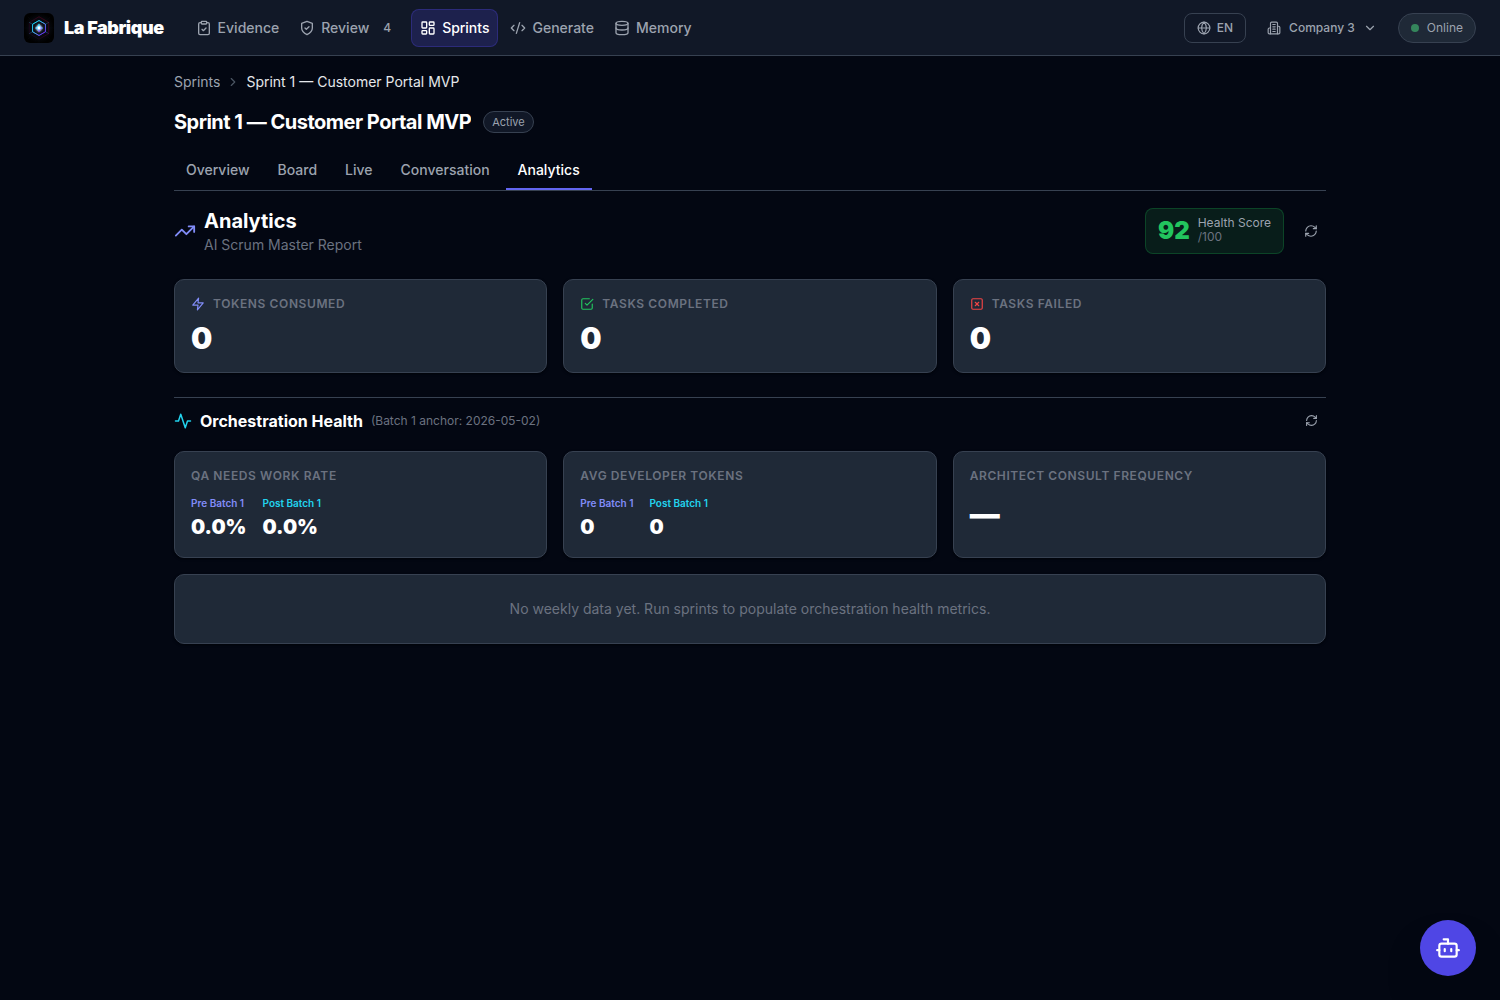
Sprint analytics: the KPIs a company reads after a sprint.
-
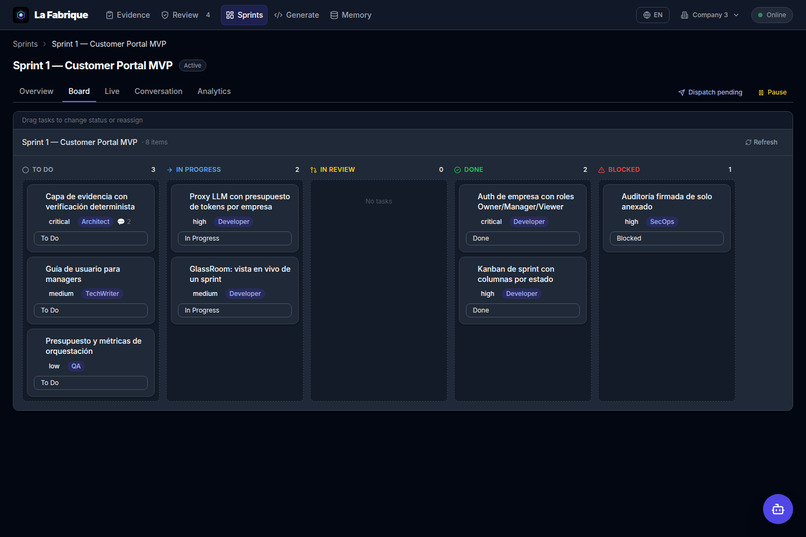
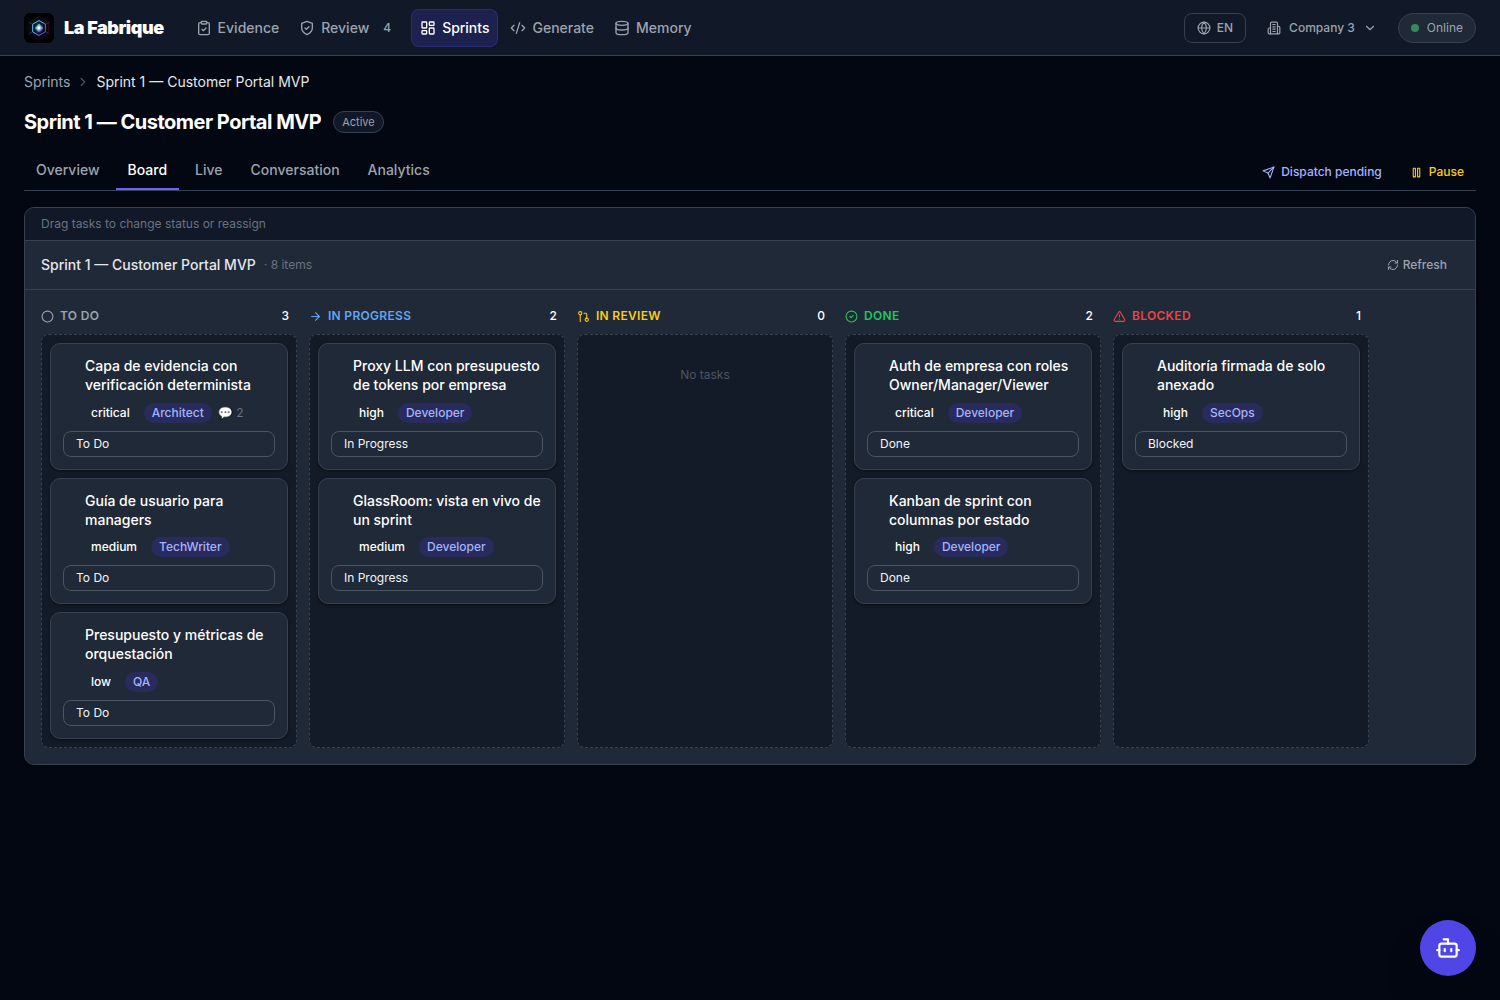
Sprint board: backlog columns by status: todo, in progress, in review, done and blocked.
-
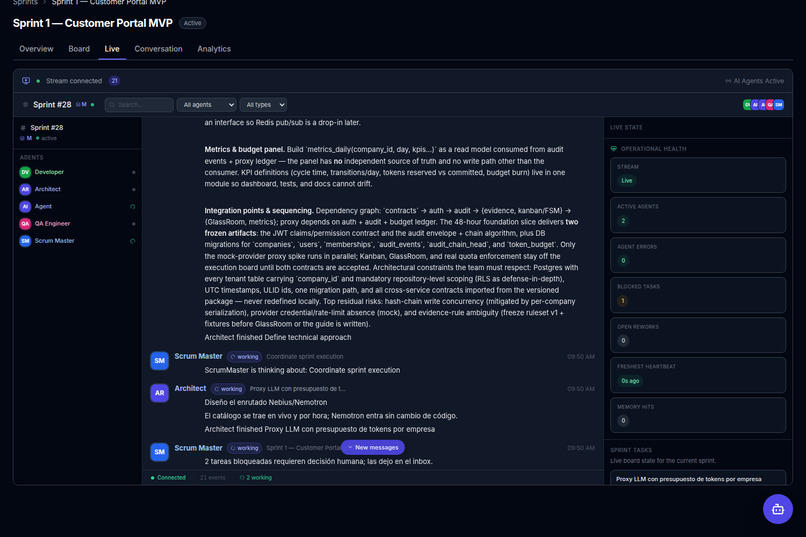
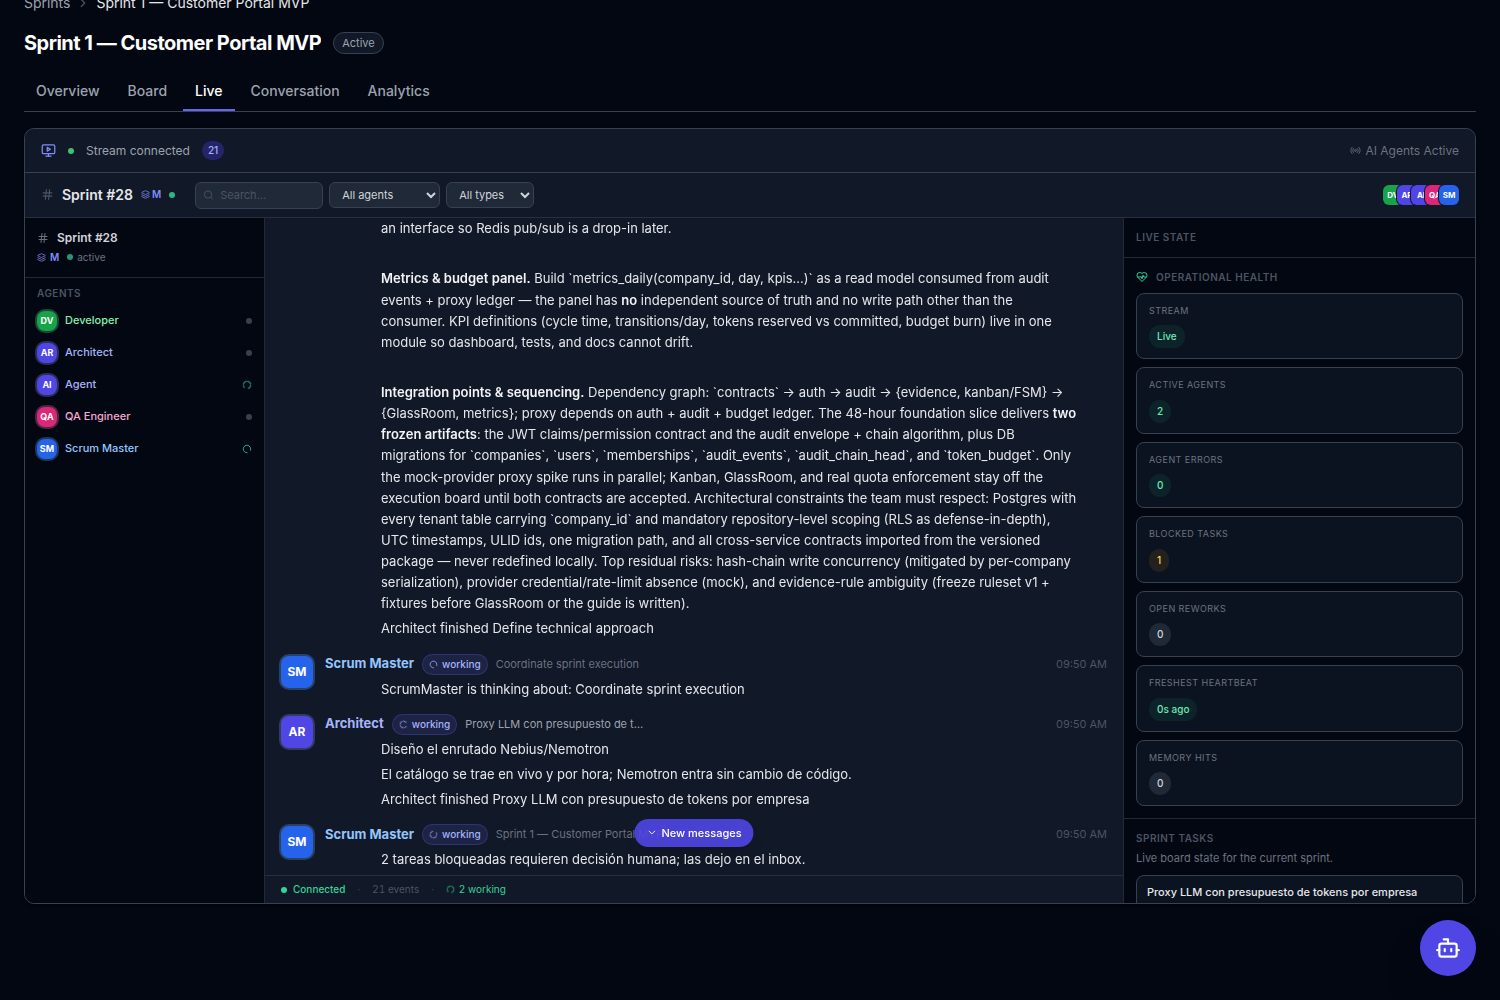
Glassroom live: real-time view of the agent roster and the message feed while a sprint runs.
What it is
La Fabrique is a software factory with eight agents (Product Owner, Architect, Scrum Master, Developer, QA, SecOps, Docs and Memory) that takes a written requirement and returns code with its tests. A result is not accepted because the model says it is done: it is accepted because the interpreter runs it and the tests pass.
On top sits a desktop assistant (Asistente B1) that listens and speaks: "build the login", "how is the sprint going?", "pause the sprint". Voice commands go through the same endpoints as the web UI (/v1/voice/*), so a sentence cannot do anything the web does not allow. It works in Spanish and English.
Why
Coding agents fail in two ways: they claim they finished without running anything, or they cost a fortune because every call goes to the biggest model. La Fabrique runs the tests for real and feeds the failing output back to the model, and splits work across tiers: Nemotron Ultra for reasoning, Super/Nano for the rest.
How it works
- demo/coding_agent.py: the model proposes files as JSON, the agent writes them to an isolated directory, runs unittest and, if anything fails, passes the real output back and retries.
- la-fabrique/: the multi-agent LangGraph flow with Postgres, NATS and an llm-proxy that validates every model id against the provider's live catalogue.
- asistente-b1/: local transcription (faster-whisper), Nemotron to think, Piper to speak, and tools that call the factory's voice gate.
NVIDIA Nemotron on Nebius Token Factory
https://api.tokenfactory.nebius.com/v1 is the default endpoint across the project. nvidia/nemotron-3-ultra-550b-a55b handles reasoning (PO, Architect, SecOps and the demo agent); nvidia/nemotron-3-super-120b-a12b and Nano handle fast calls. The assistant's Nemotron panel reads the real catalogue and writes NEMOTRON_ROLES and the model tiers into the factory's .env. One OpenAI-compatible client serves eight agents, the demo and the assistant.
Try it
git clone -b fusion https://github.com/careb36/la-fabrique.git && cd la-fabrique export NEBIUS_API_KEY=... python demo/coding_agent.py (or --offline without a key)
Apache 2.0. Code: https://github.com/careb36/la-fabrique/tree/fusion
Built With
- docker
- fastapi
- langgraph
- nats
- nebius-token-factory
- neo4j
- nvidia-nemotron
- pgvector
- postgresql
- python
- react
- typescript

Log in or sign up for Devpost to join the conversation.