-
-
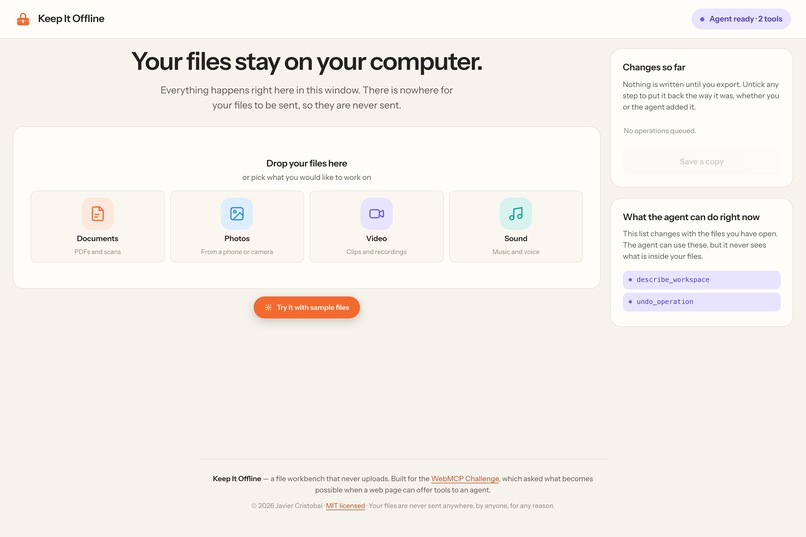
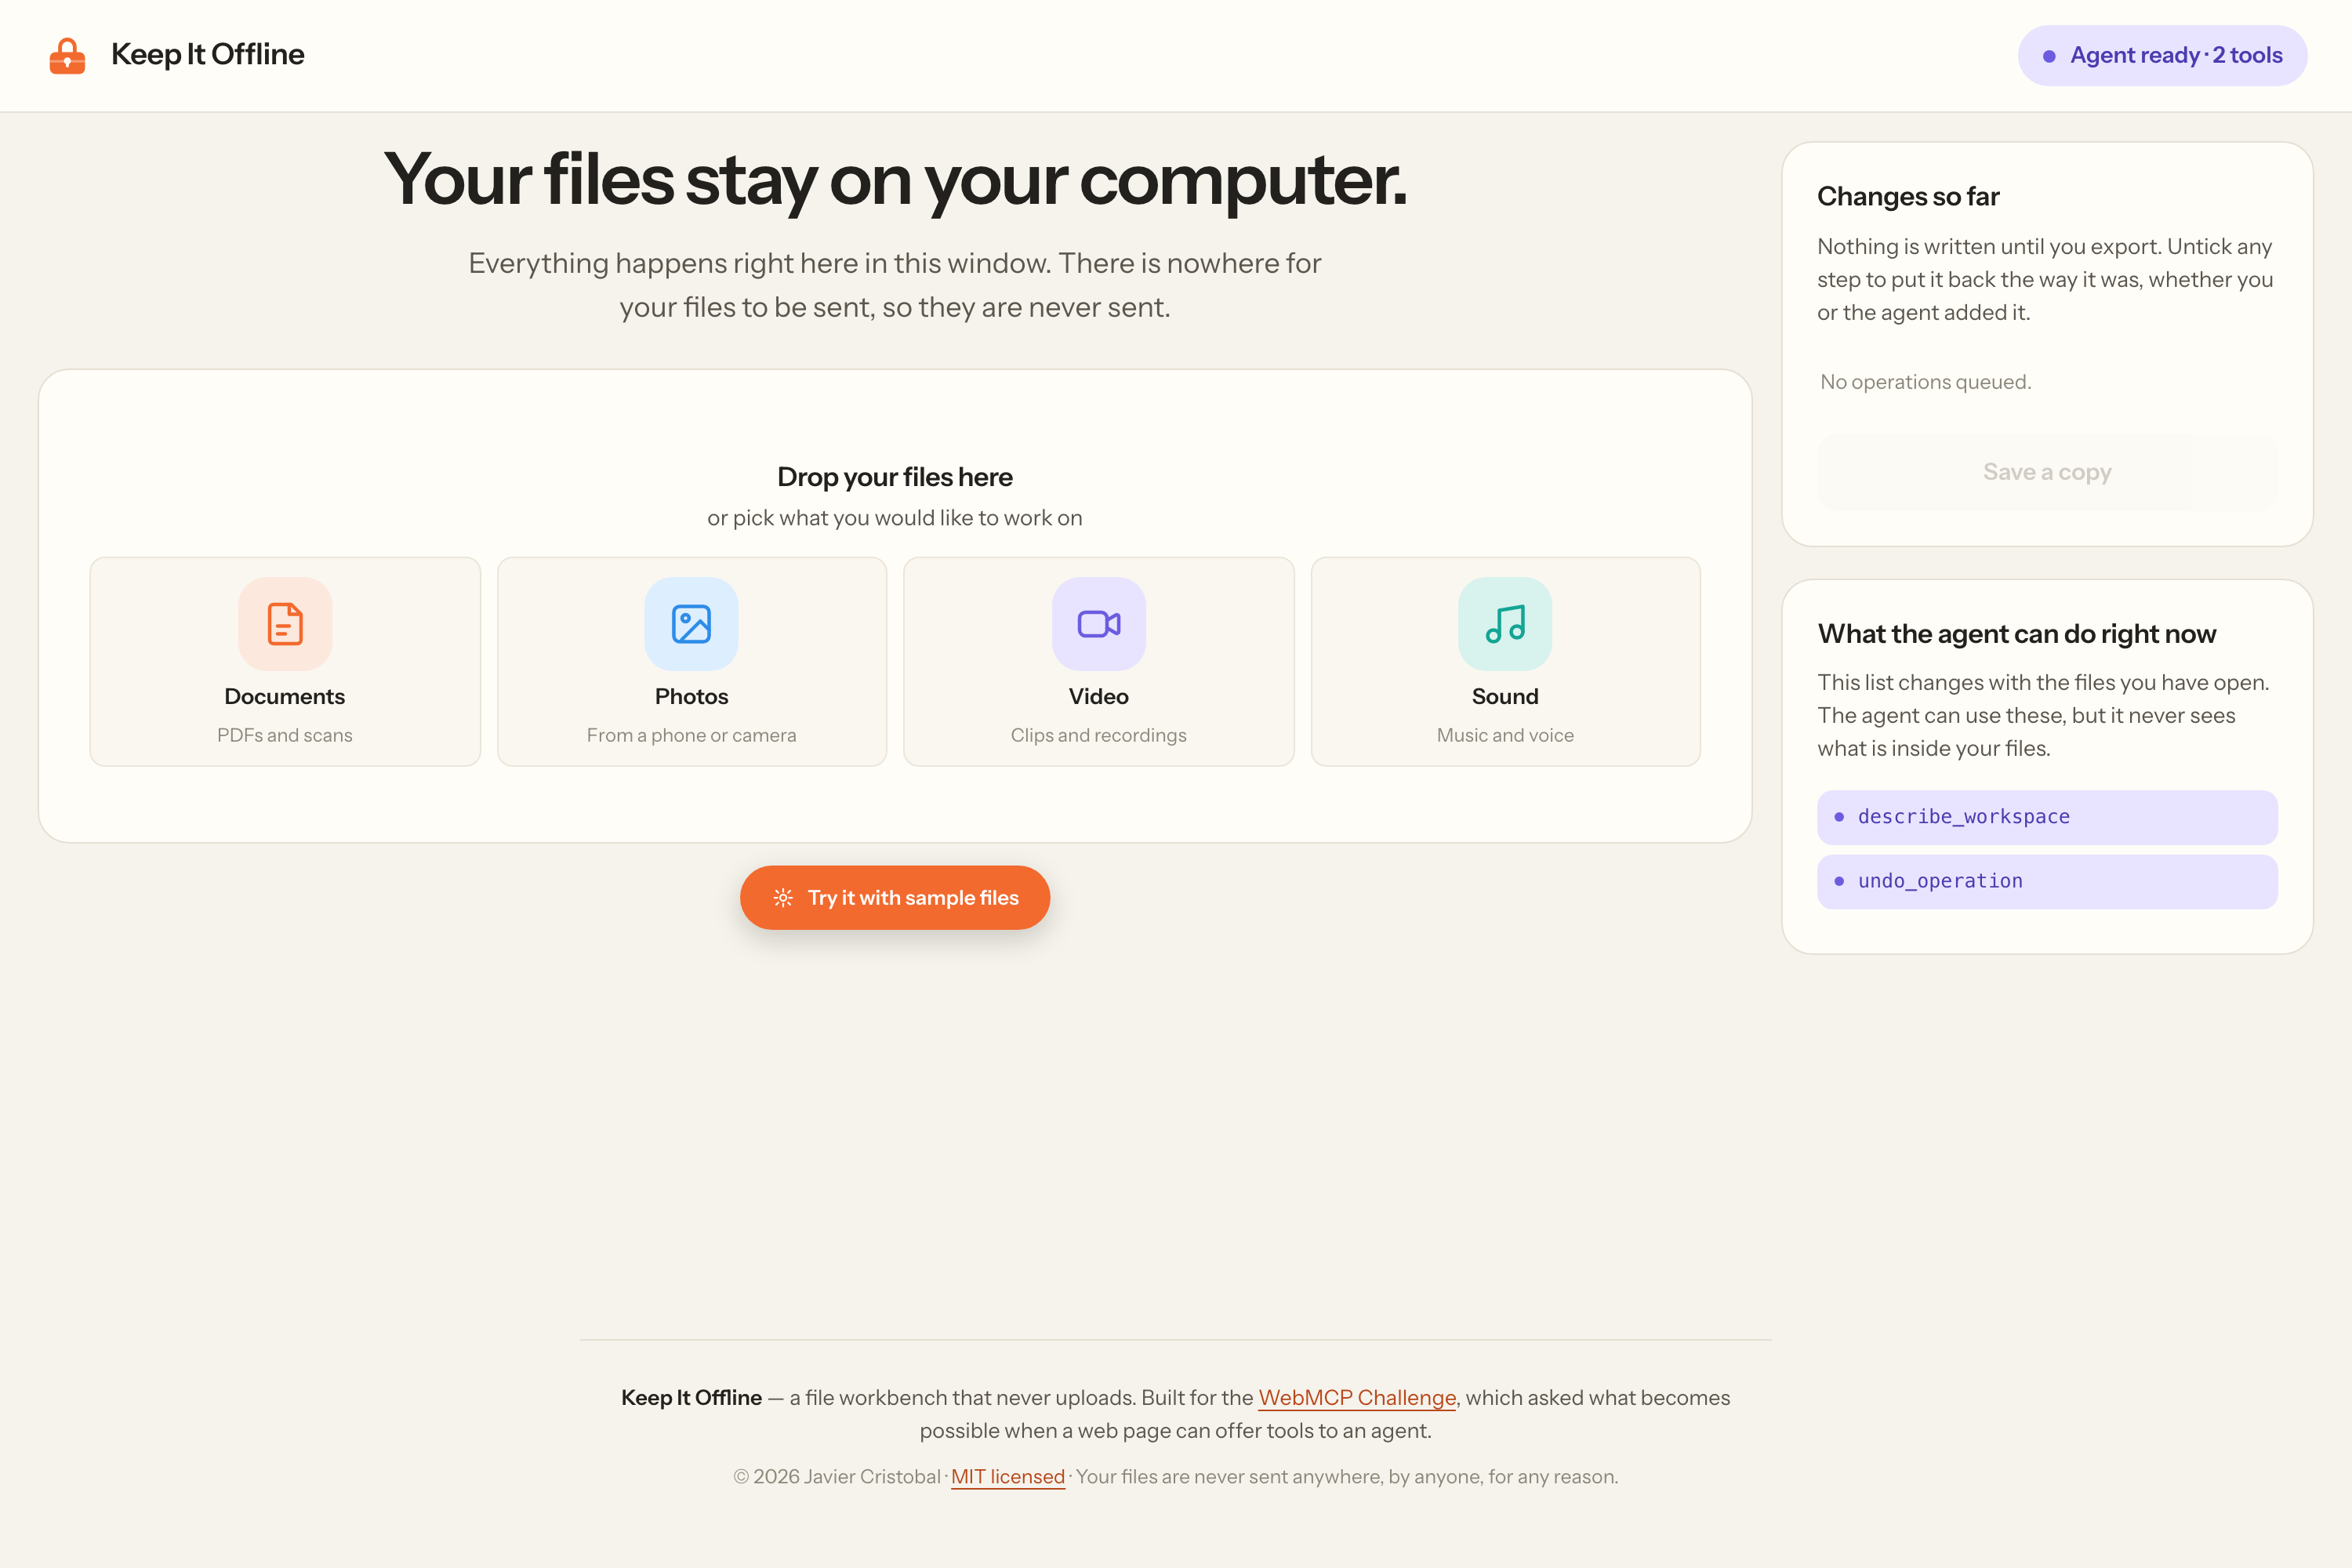
empty bench
-
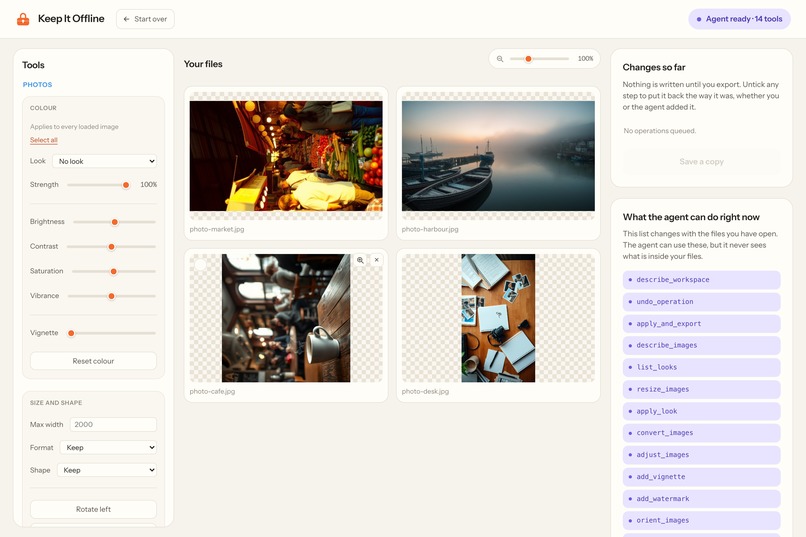
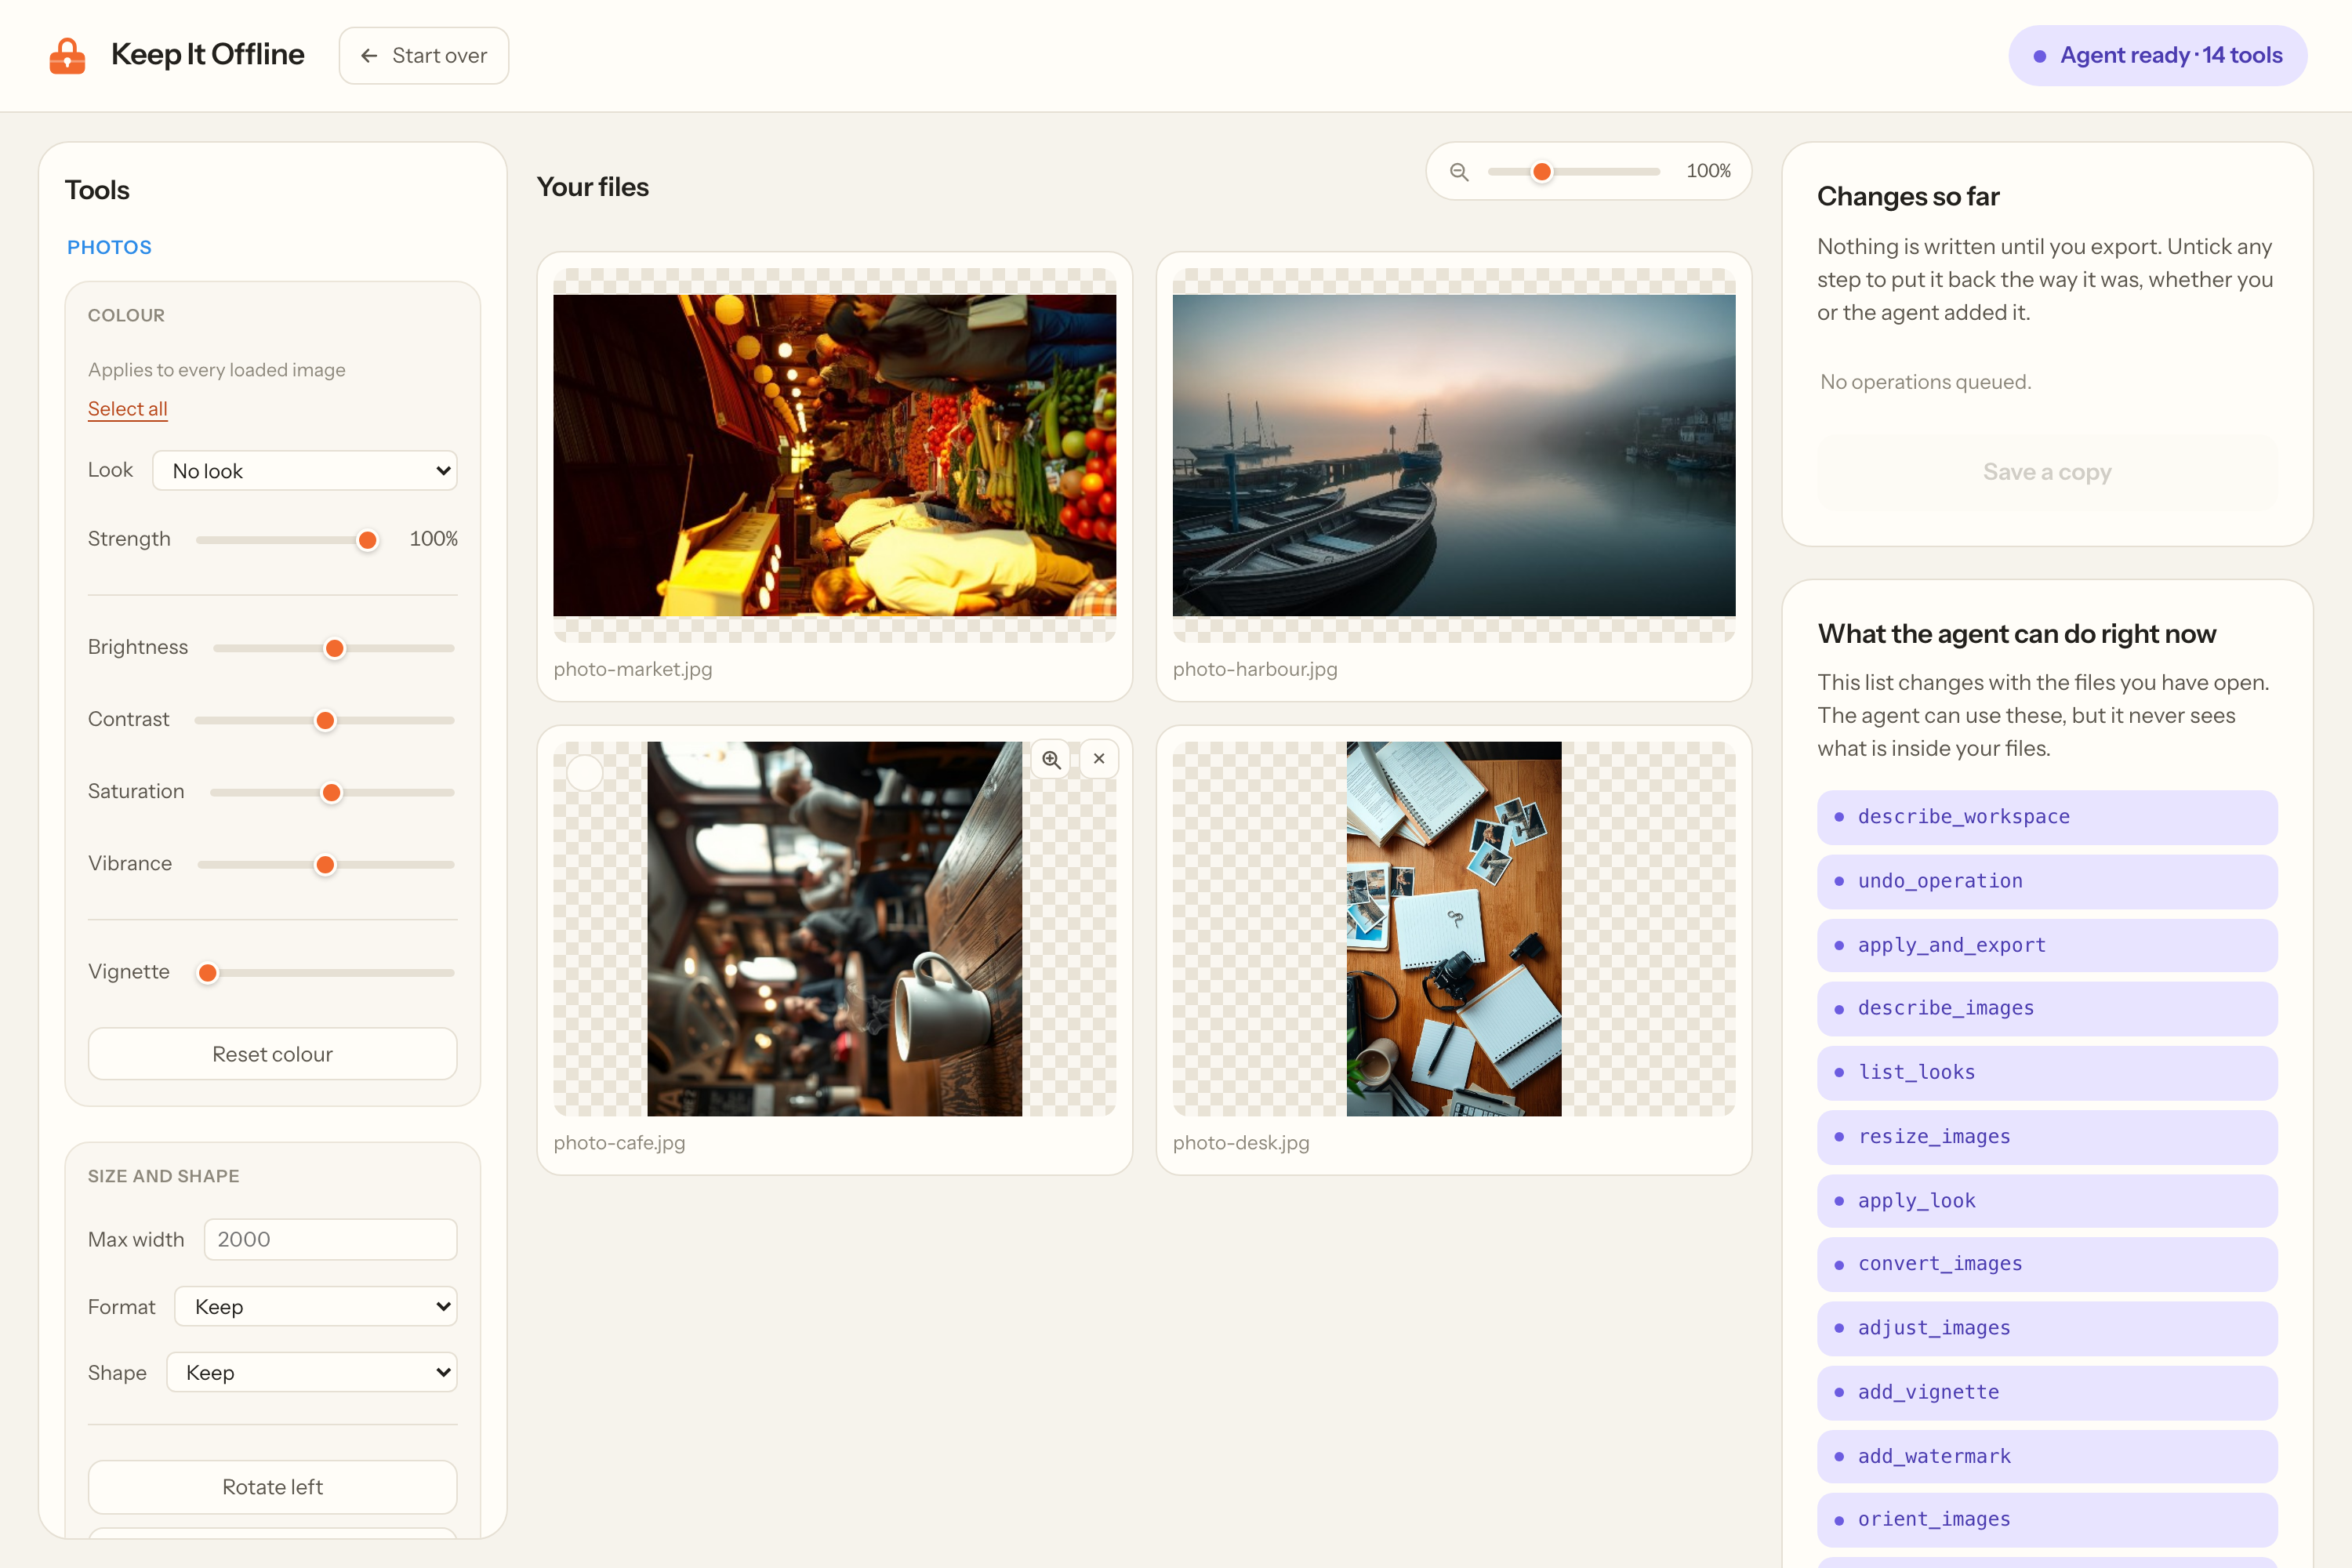
photos loaded
-
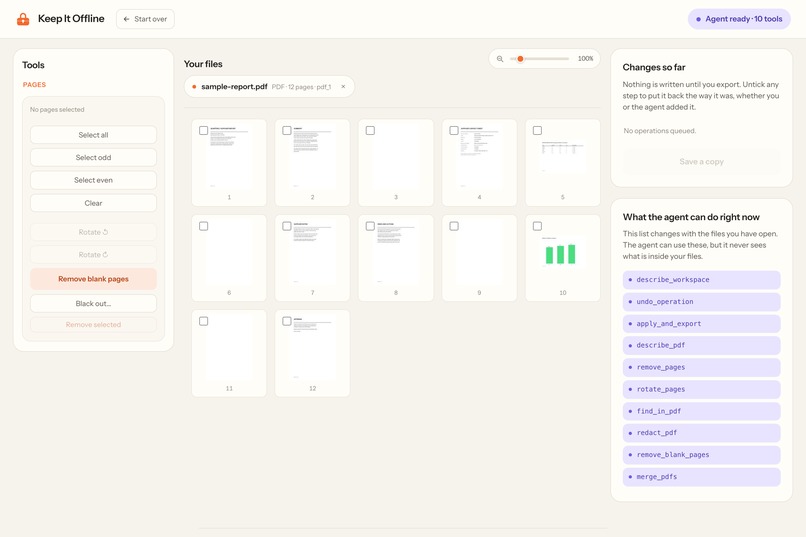
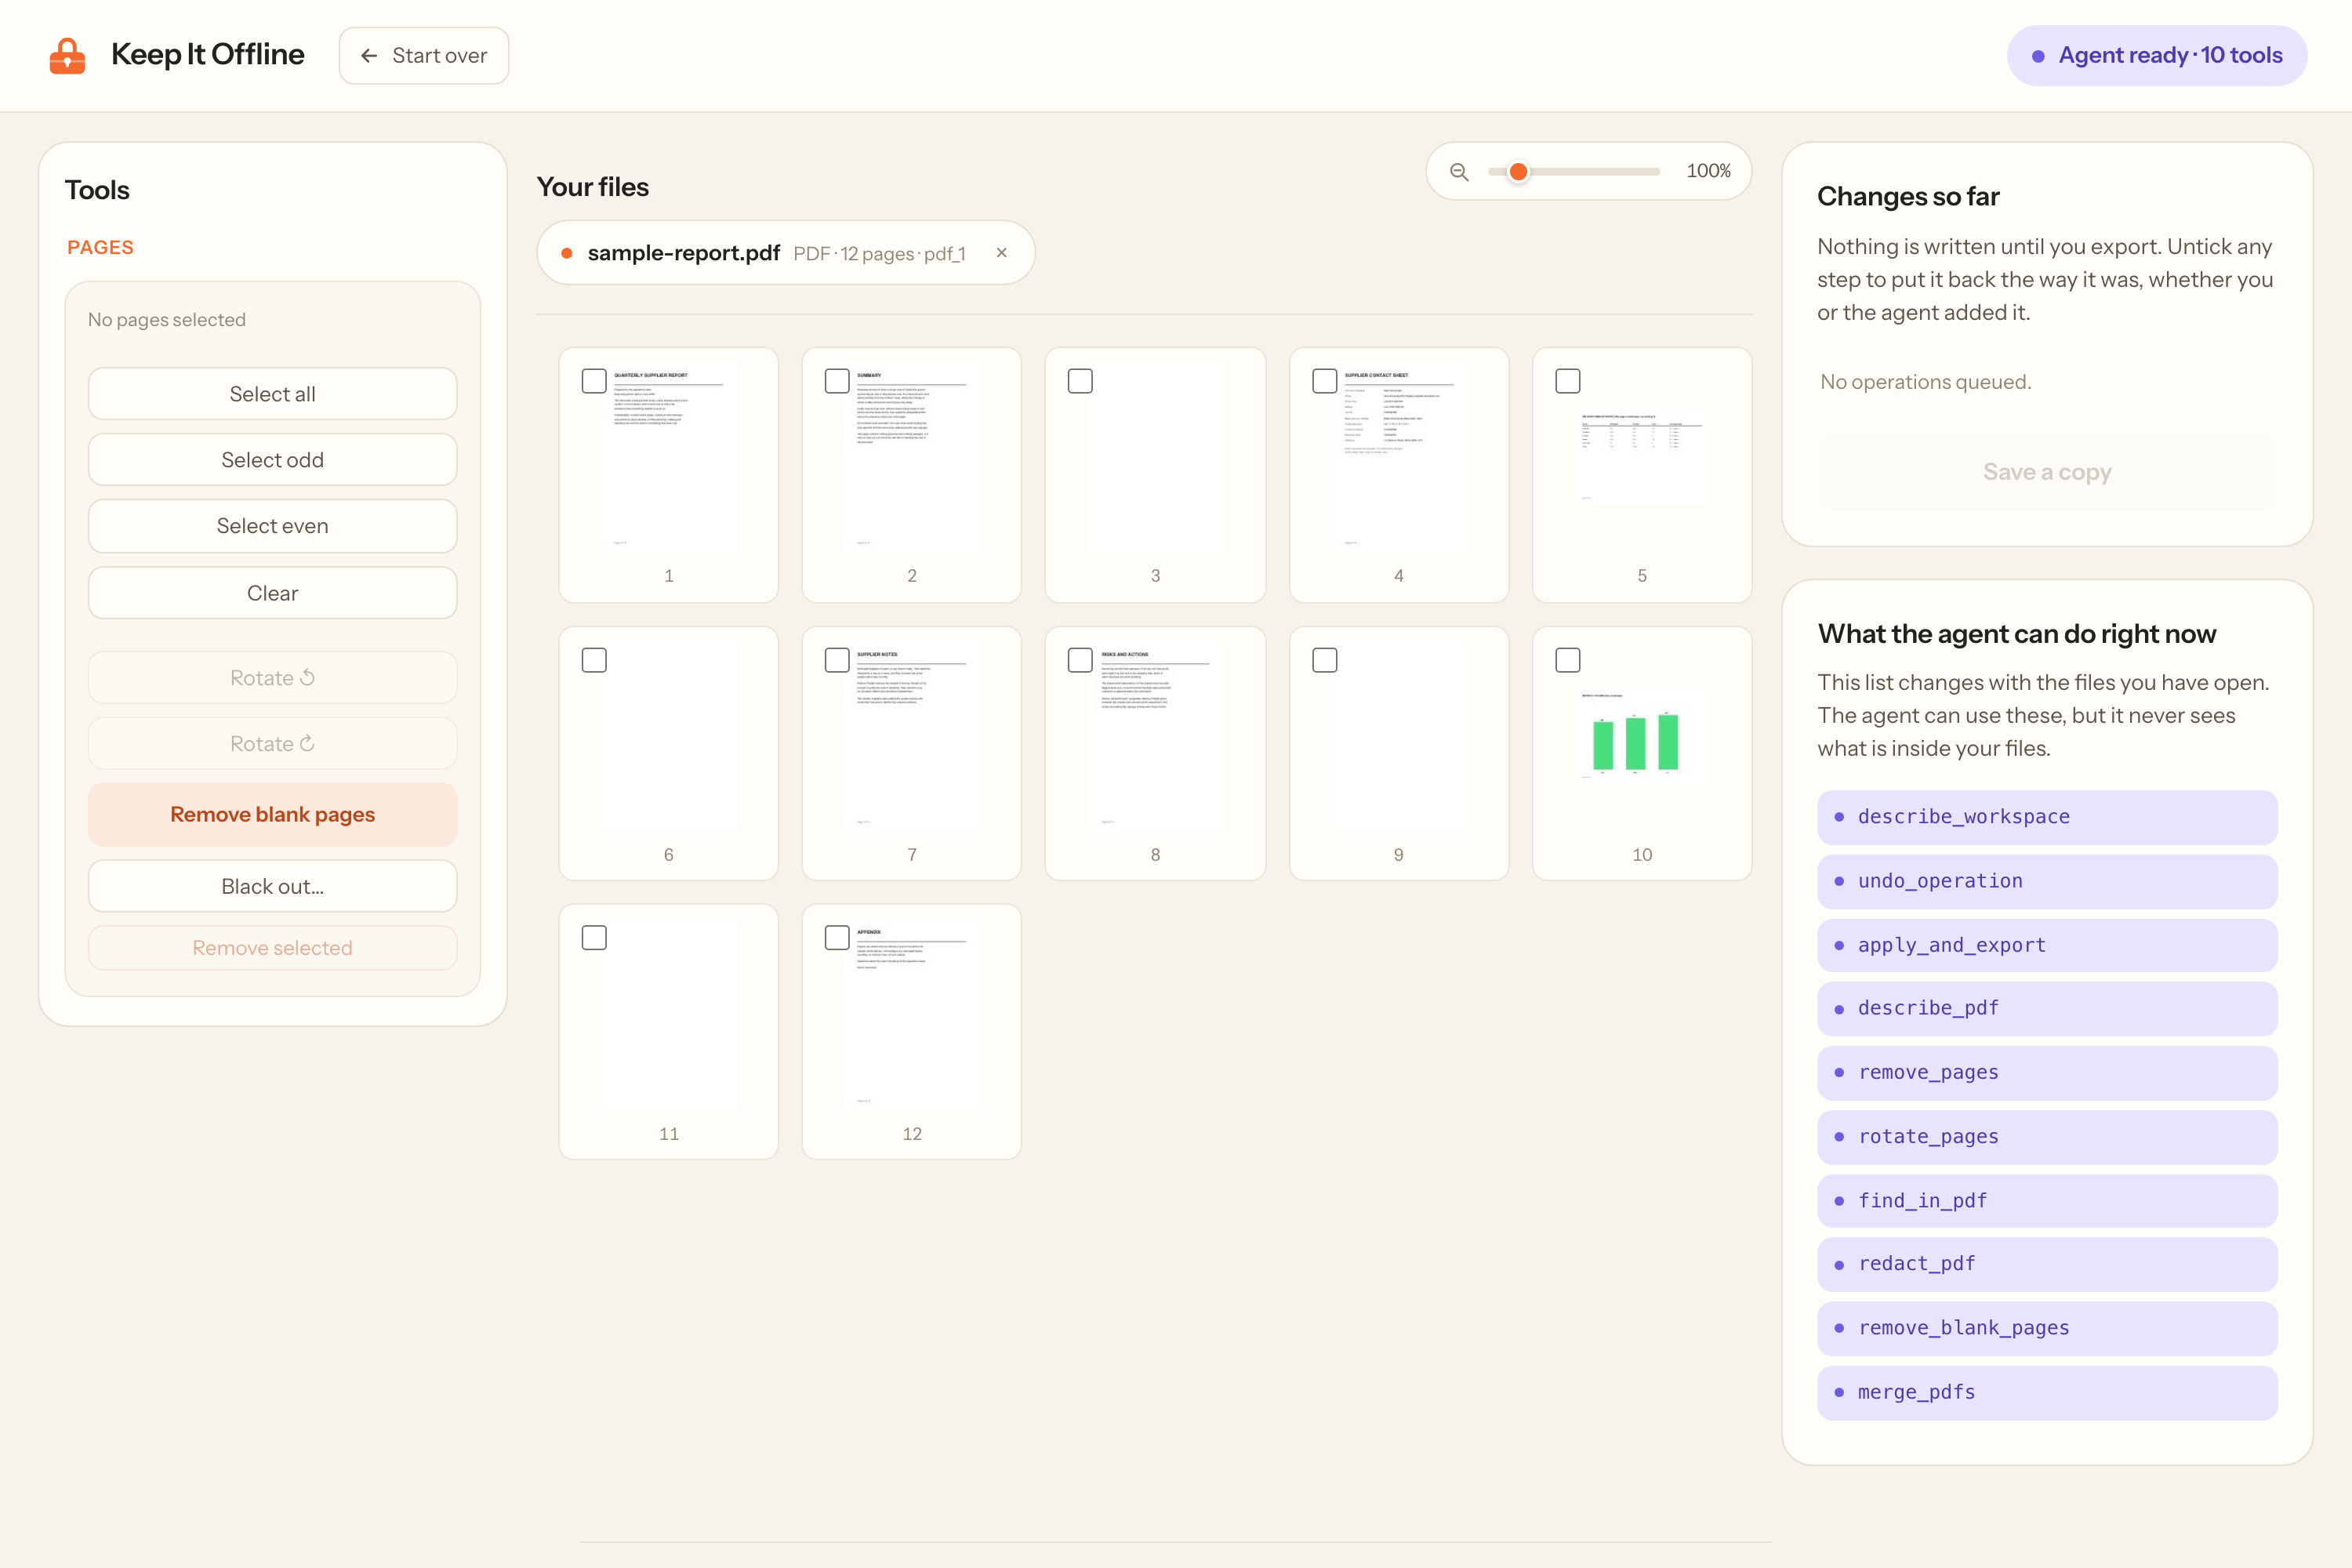
pdf pages
-
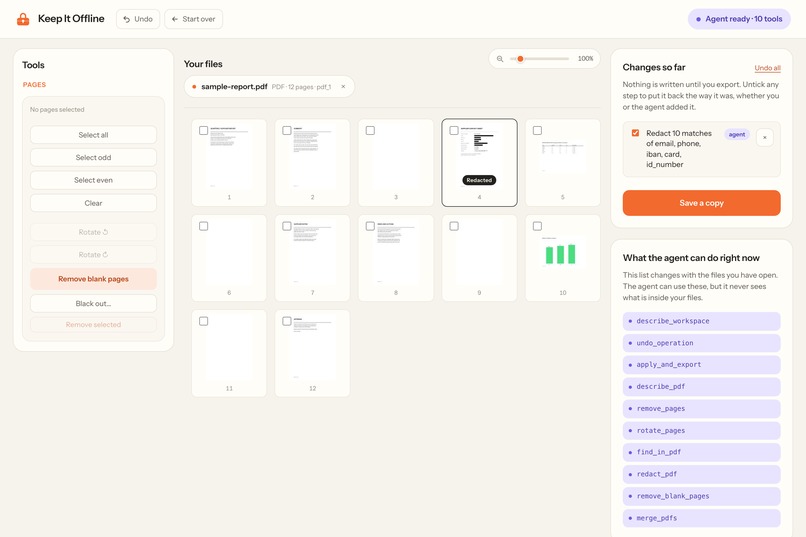
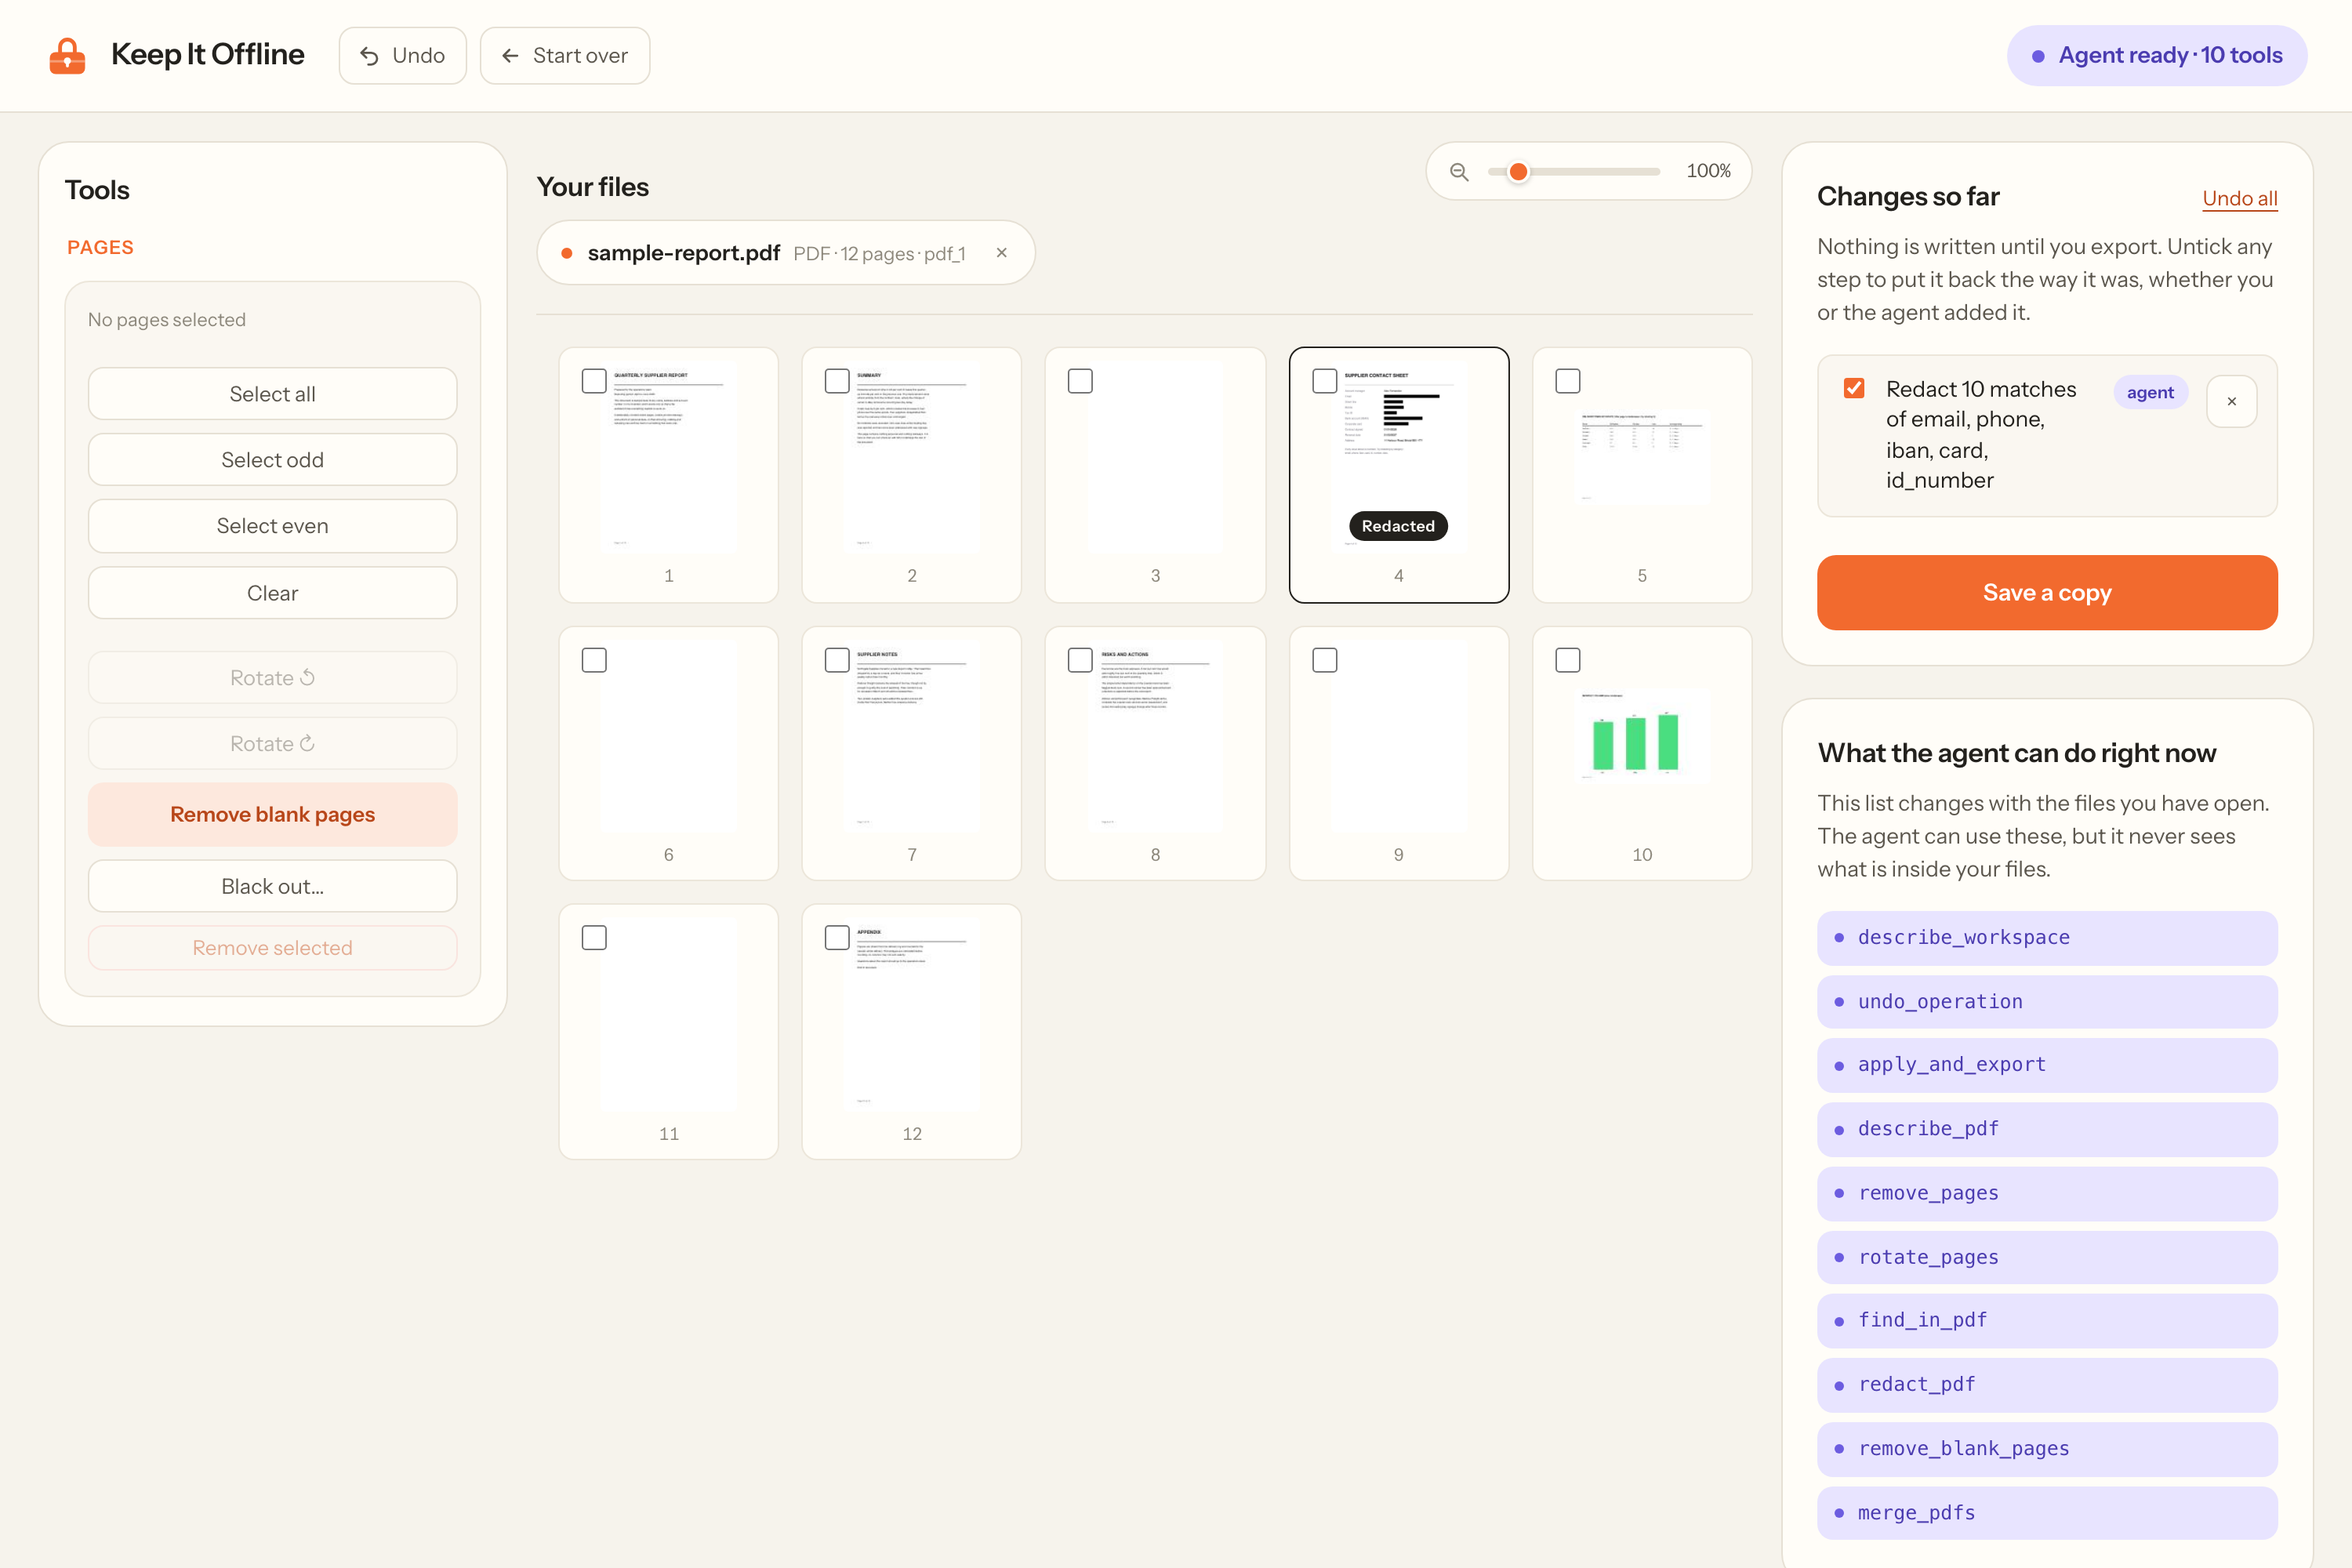
redaction
-
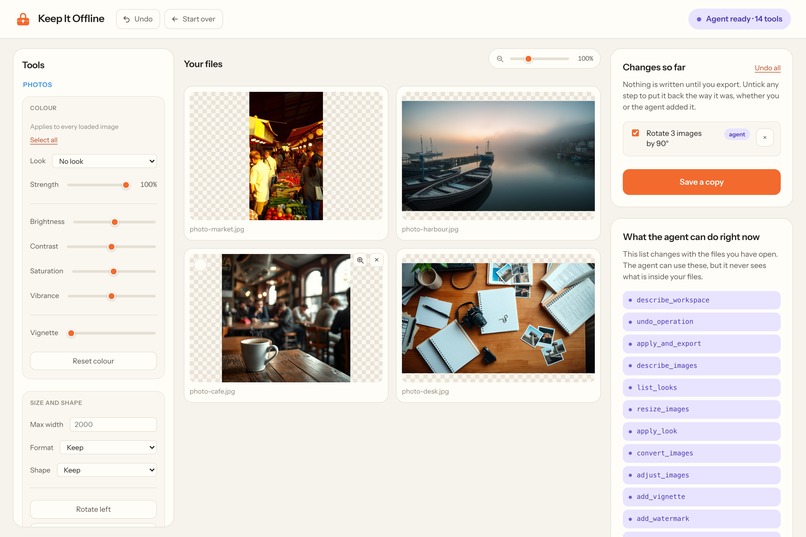
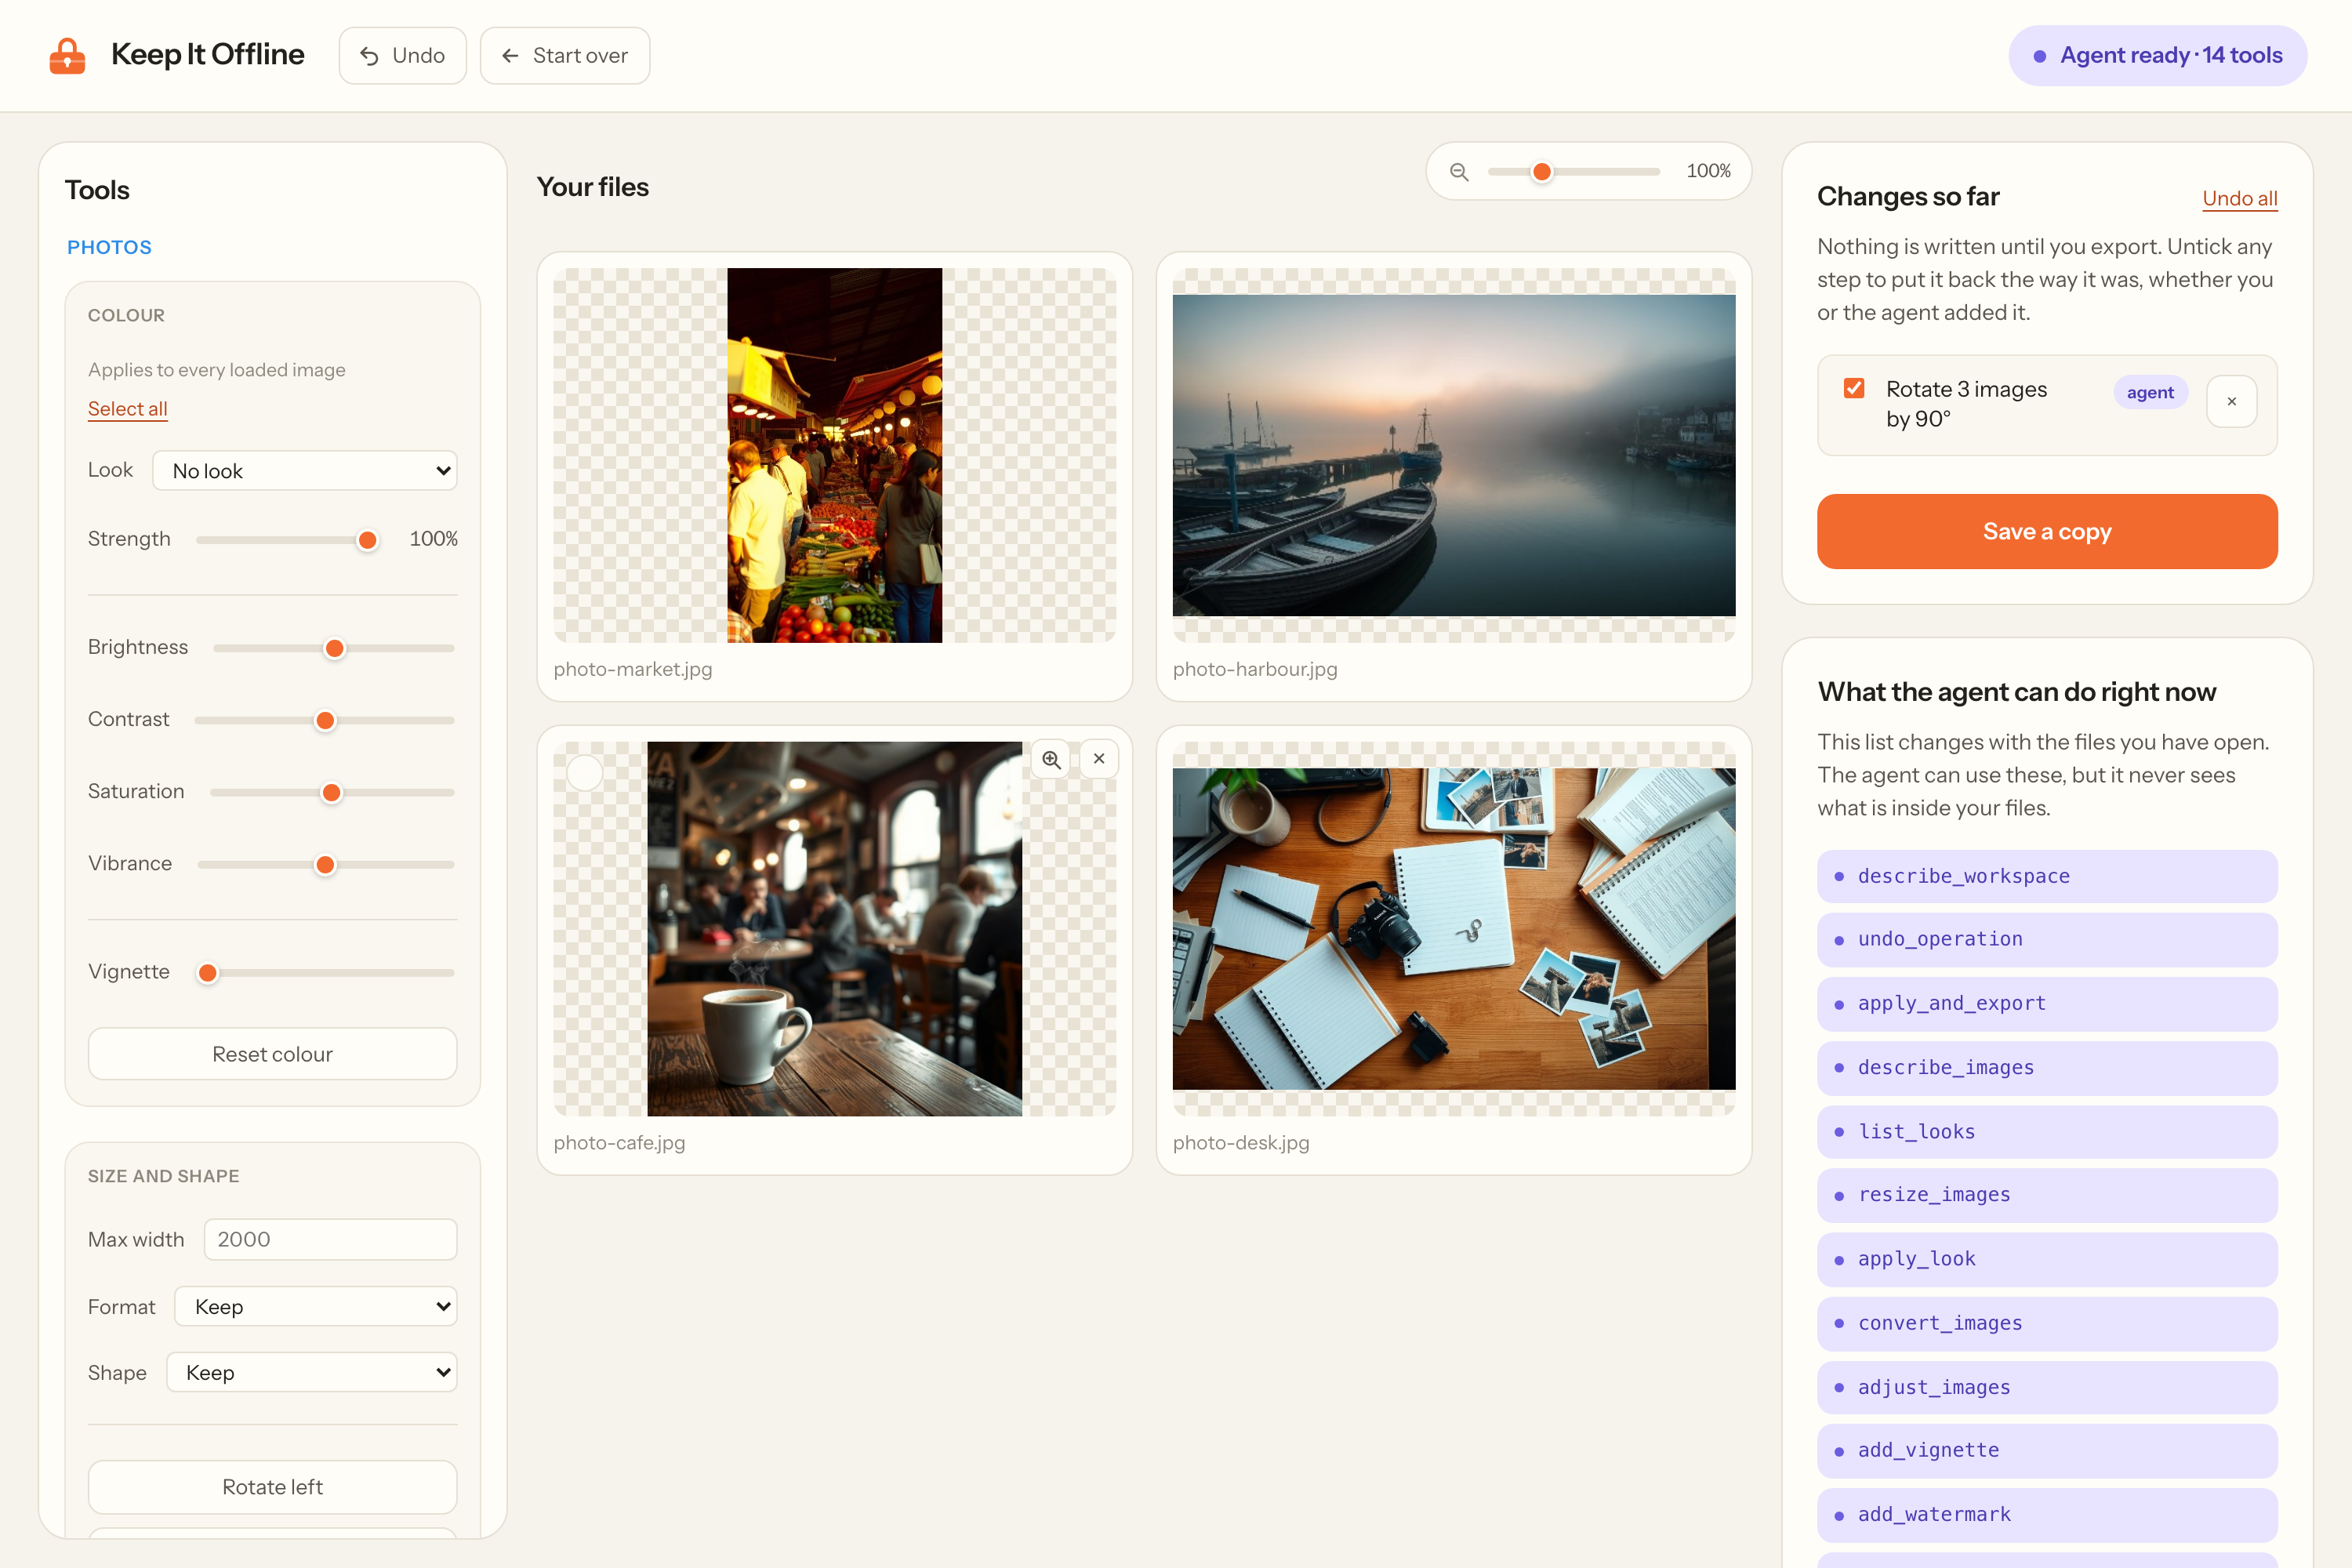
agent rotated
-
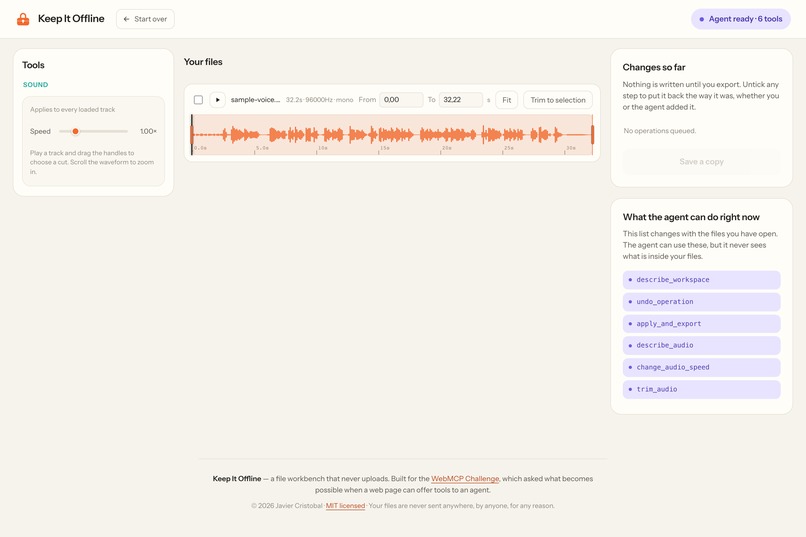
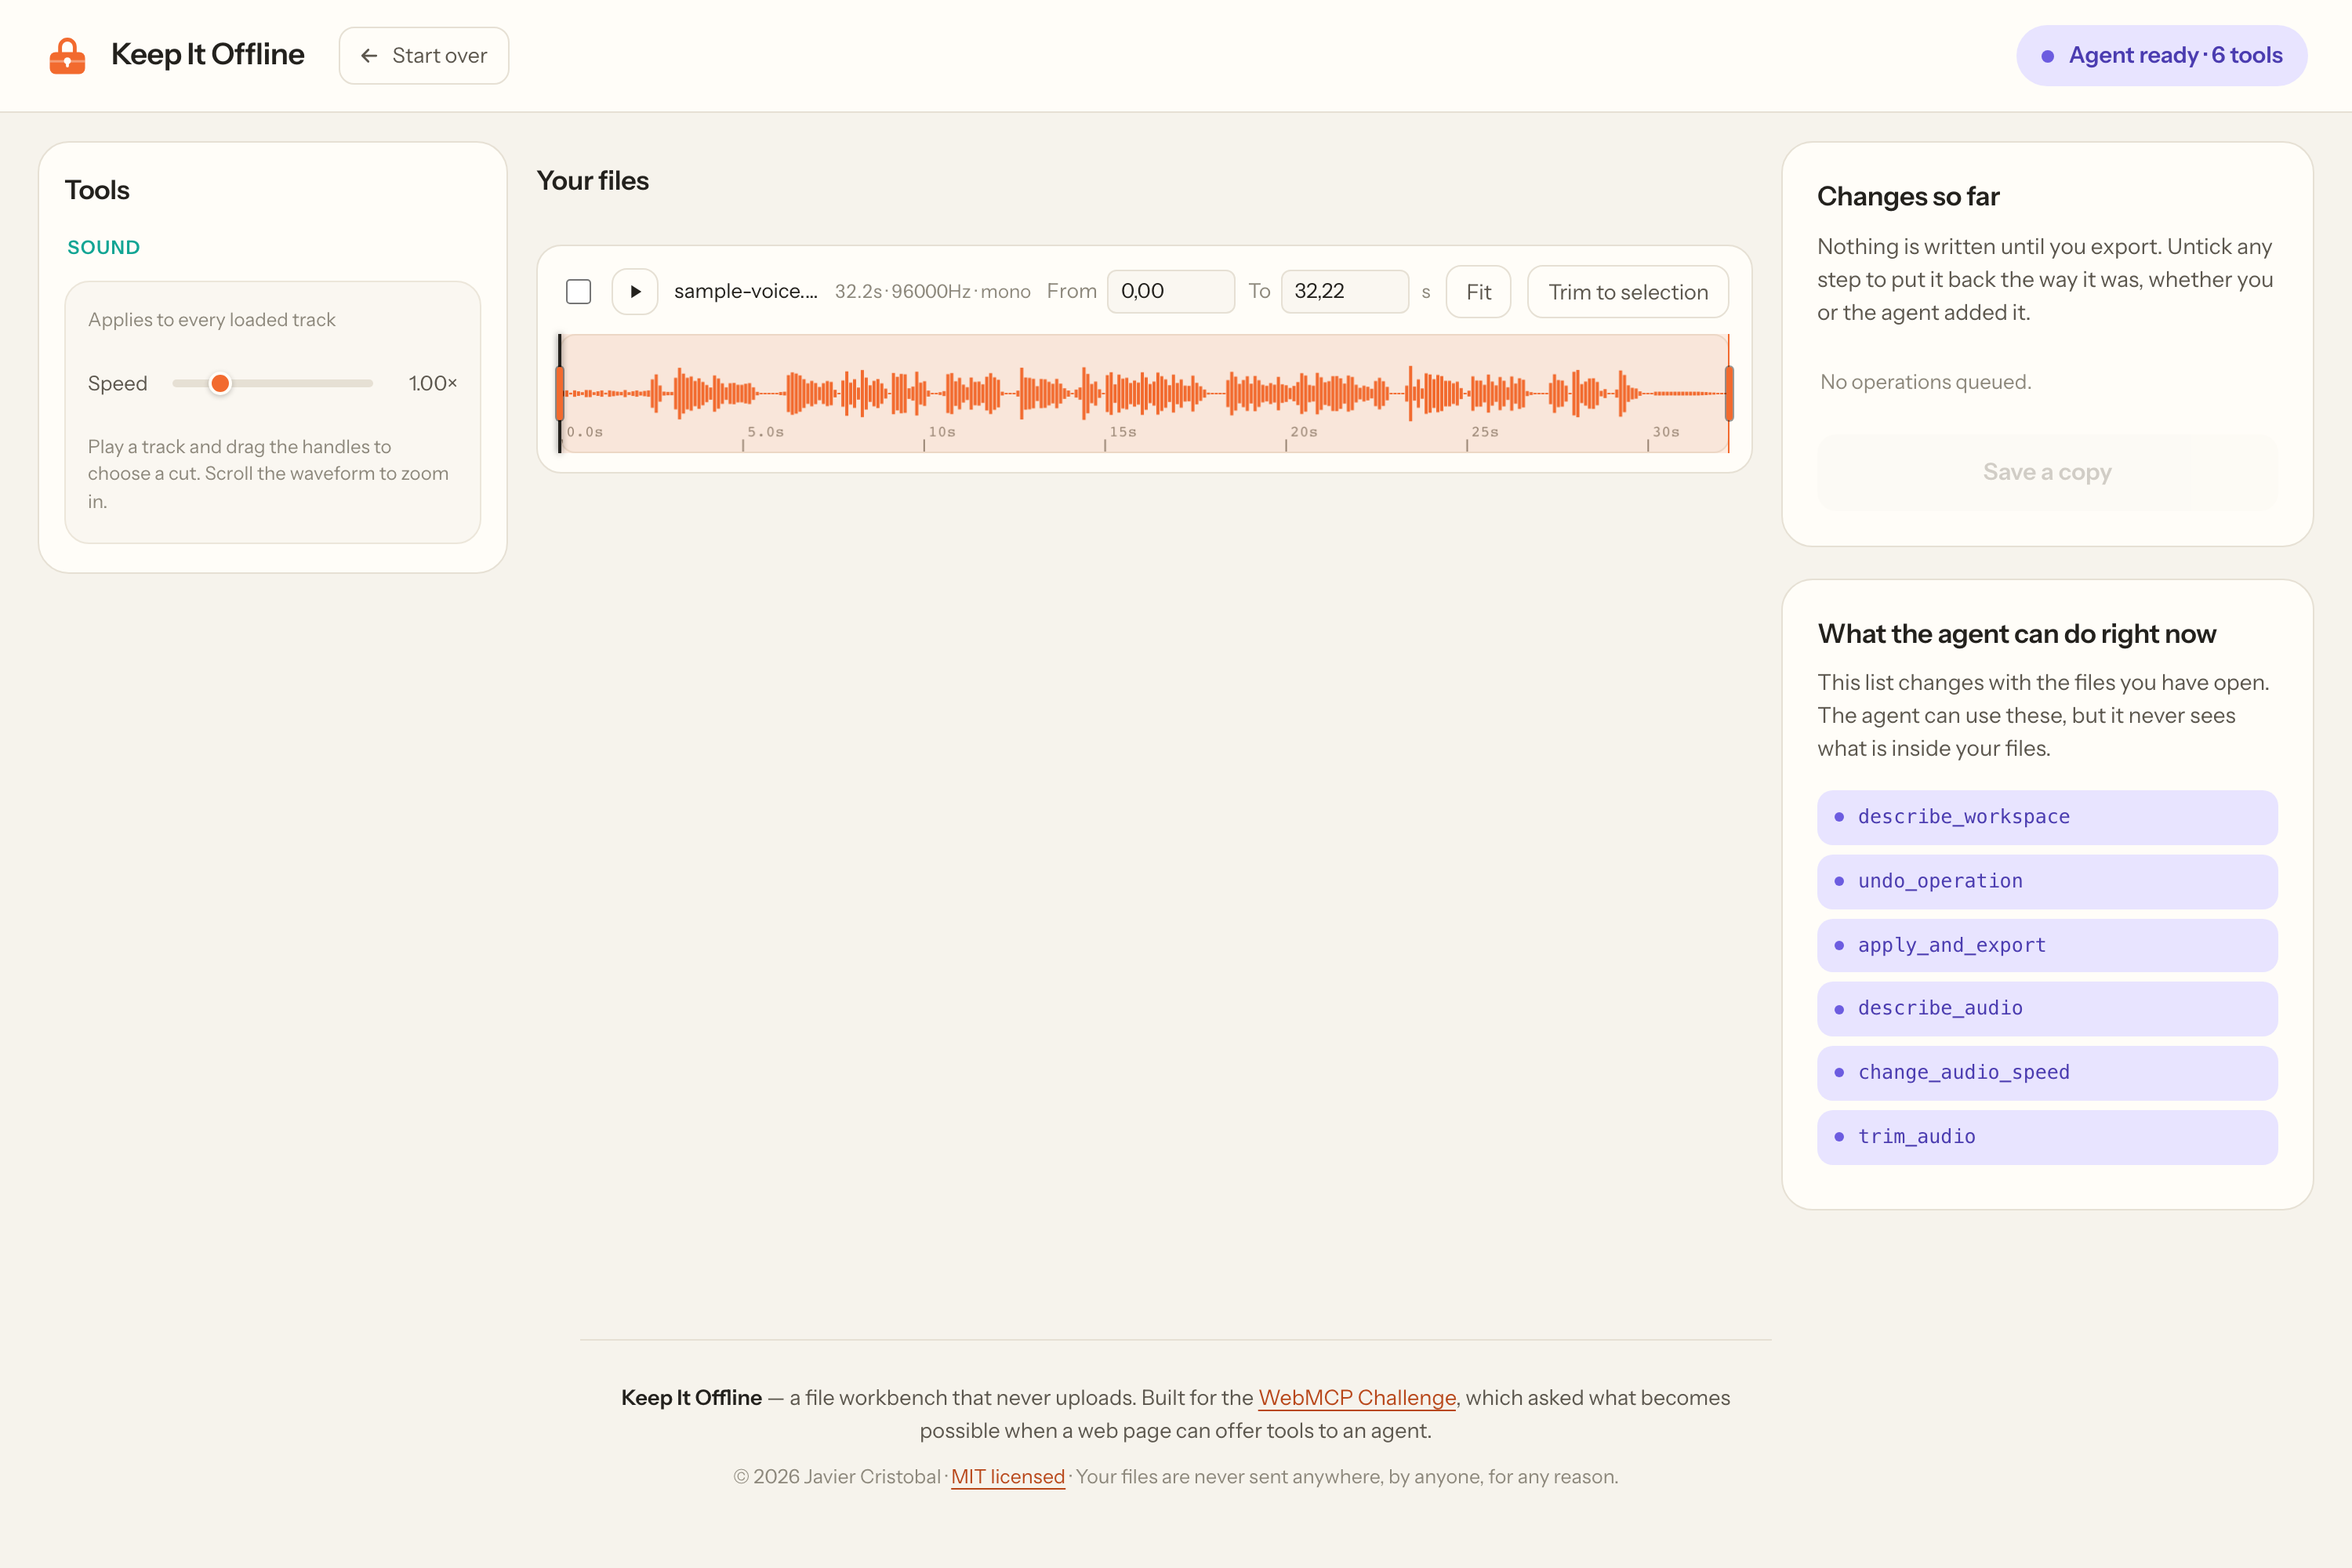
audio
-
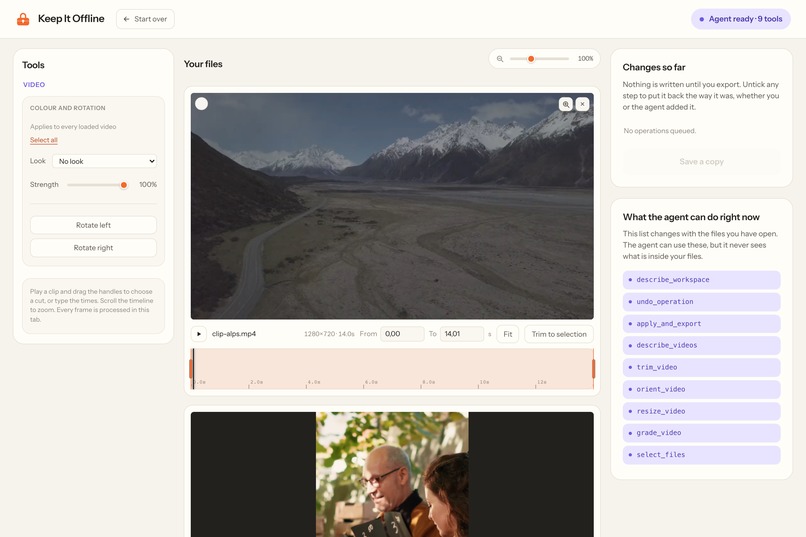
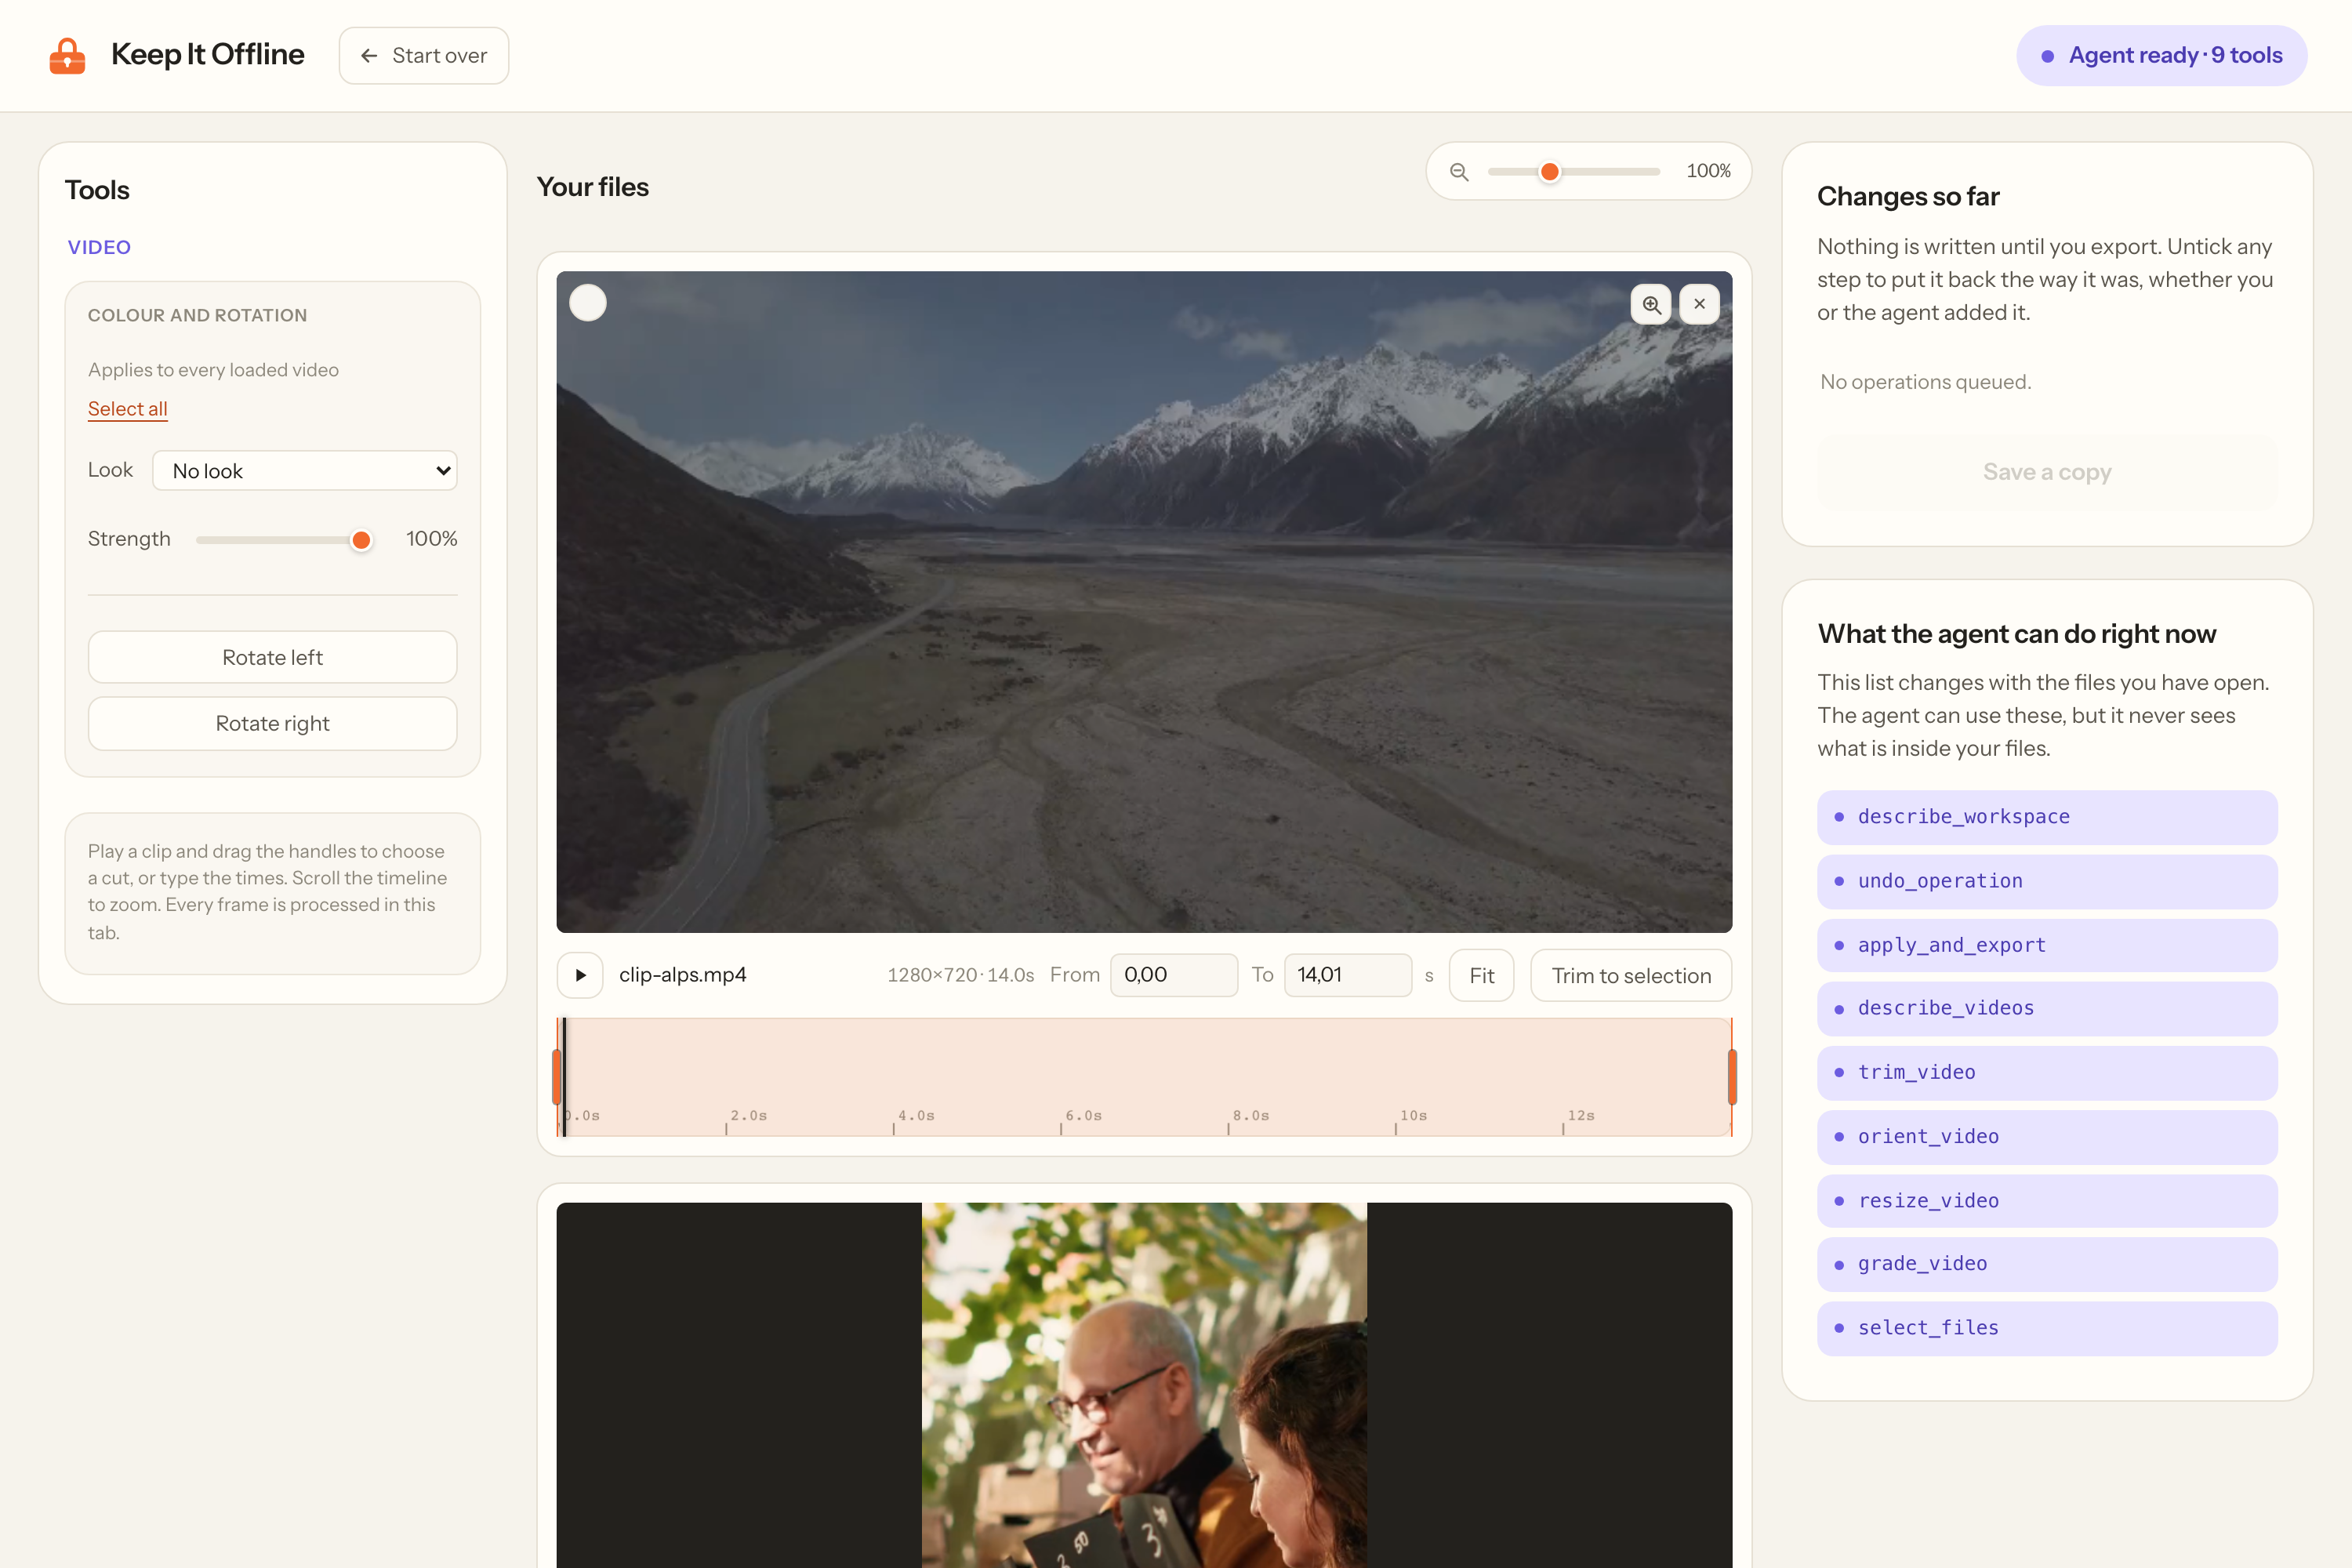
video
I got the inspiration from one of the many online tools that, unfortunately, force you to upload your documents in order to work on them.
What it does This is file workbench for PDFs, photos, video and audio that runs entirely in the browser tab. It registers 29 WebMCP tools (more coming!) so an agent can drive all of it, but the tools return facts about your files, never their contents. You can ask it to black out every bank account and it gets back { matches: 10, pages: [4] }, never the numbers. Every tool also has a button, so you can use it without an agent as well.
How we built it Vanilla JS, no framework and no build step, so the repo is what runs. Tools go through document.modelContext.registerTool(). The registered set tracks page state (2 tools on an empty bench, 29 with every file kind loaded), the agent and the UI share one state object, and Web Workers keep heavy work off the main thread. Every dependency is vendored, and a CSP with connect-src 'self' makes the browser itself block an upload.
Challenges we ran into Redacting for real, since black rectangles leave the text extractable underneath, so pages are flattened to images.
Accomplishments that we're proud of An agent that redacts a document it is never allowed to read. The page runs the search locally and strips the matches out of the return value, so they never enter the model's context.
What we learned That there are way too many things that could go wrong for such a "simple" app!
What's next for Keep It Offline More type of files and more tools!
Built With
- ai-agents
- canvas
- chrome
- content-security-policy
- css3
- fflate
- file-api
- html5
- indexeddb
- javascript
- local-first
- mediarecorder
- model-context-protocol
- netlify
- offline
- pdf-lib
- pdf.js
- privacy
- vanilla-js
- web-audio-api
- web-workers
- webcodecs
- webmcp

Log in or sign up for Devpost to join the conversation.