-
-
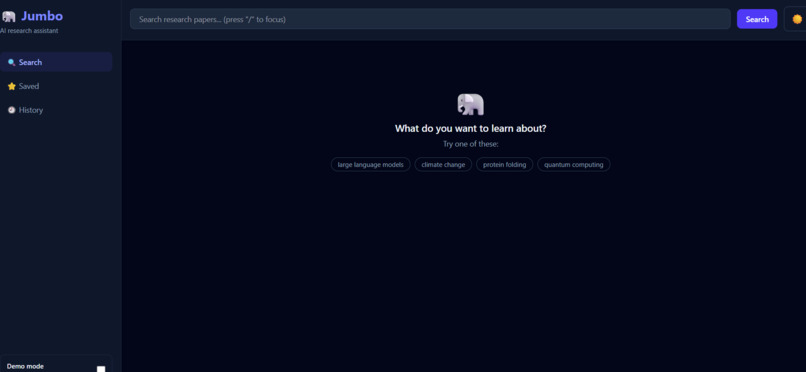
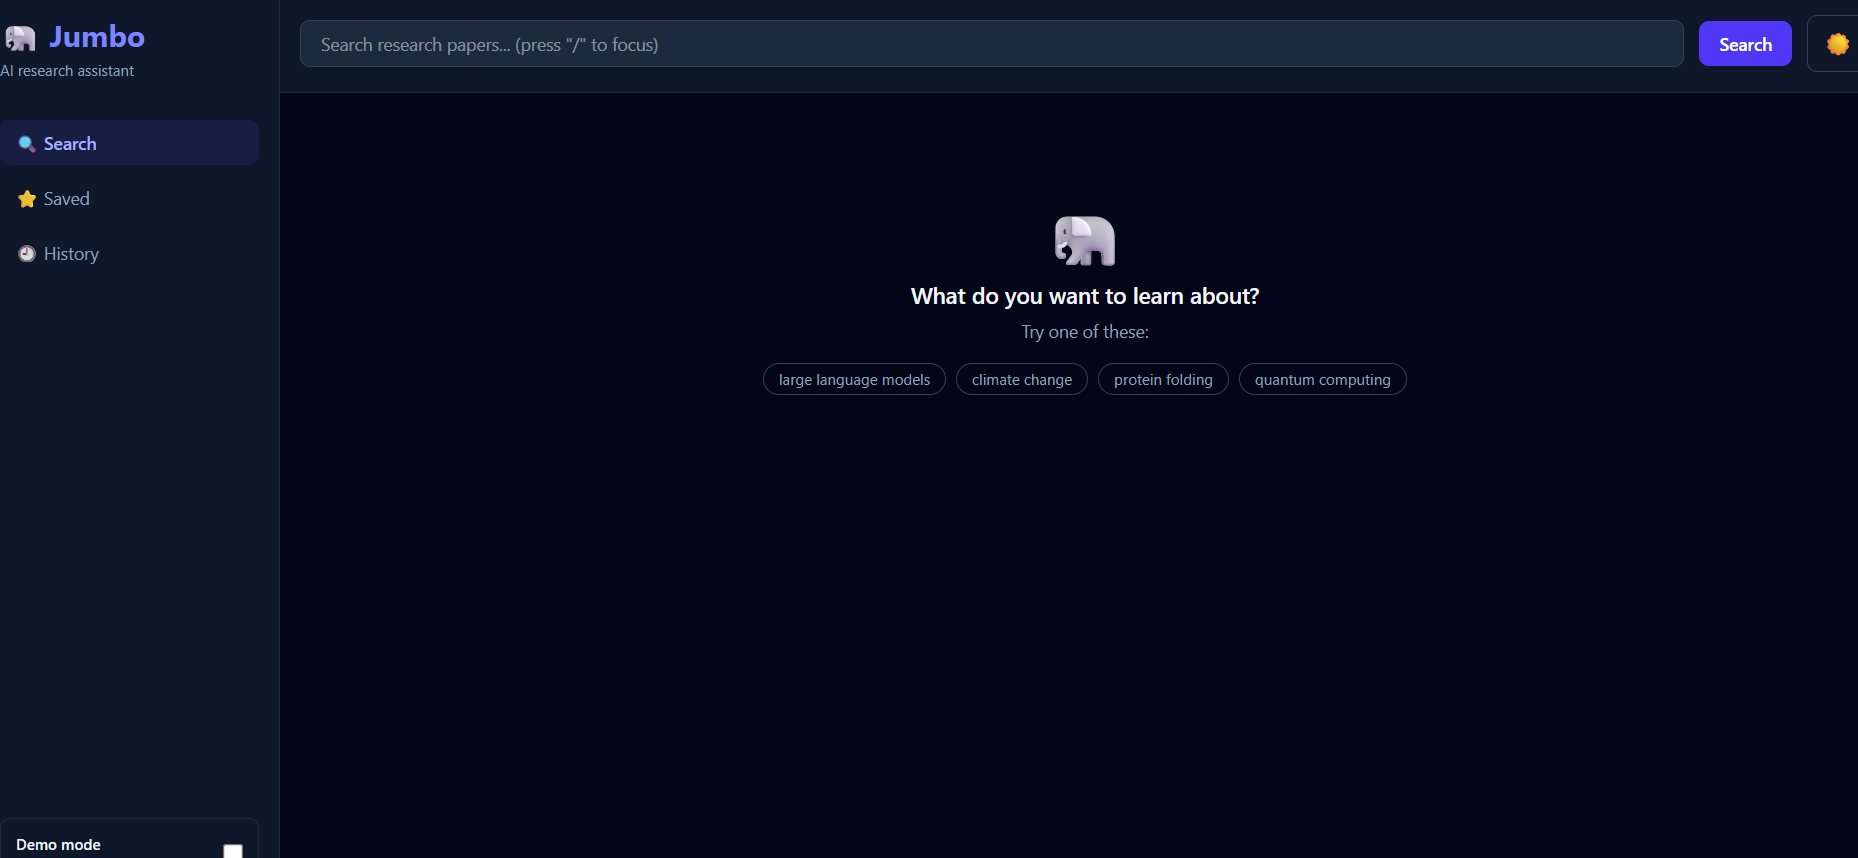
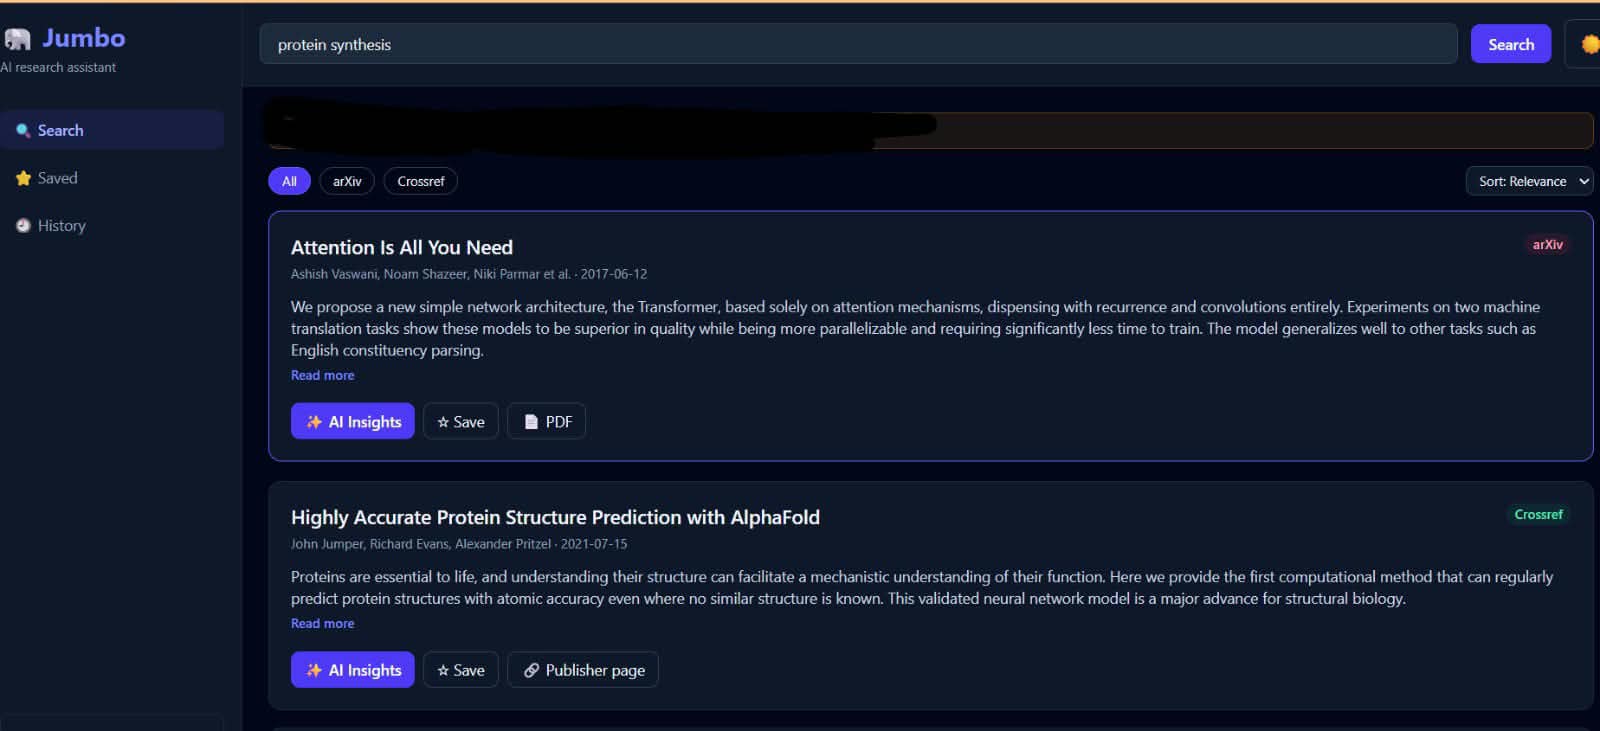
dashboard interface
-
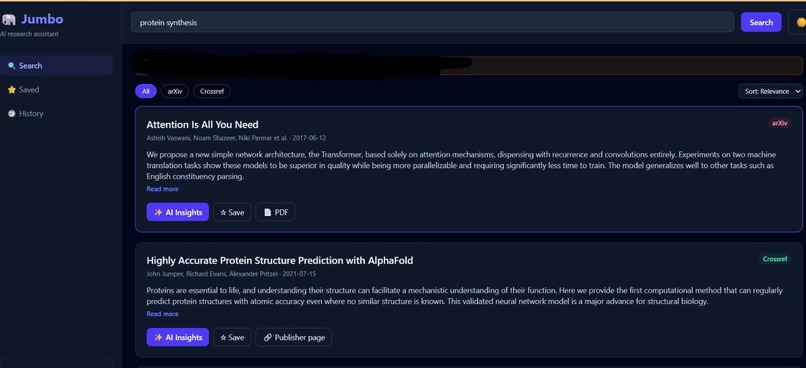
how the search feature works
-
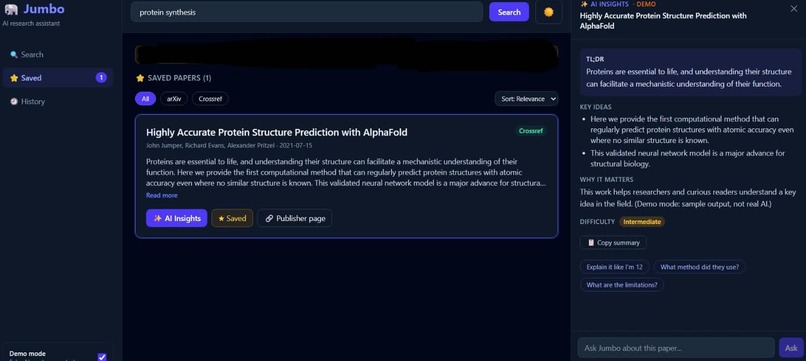
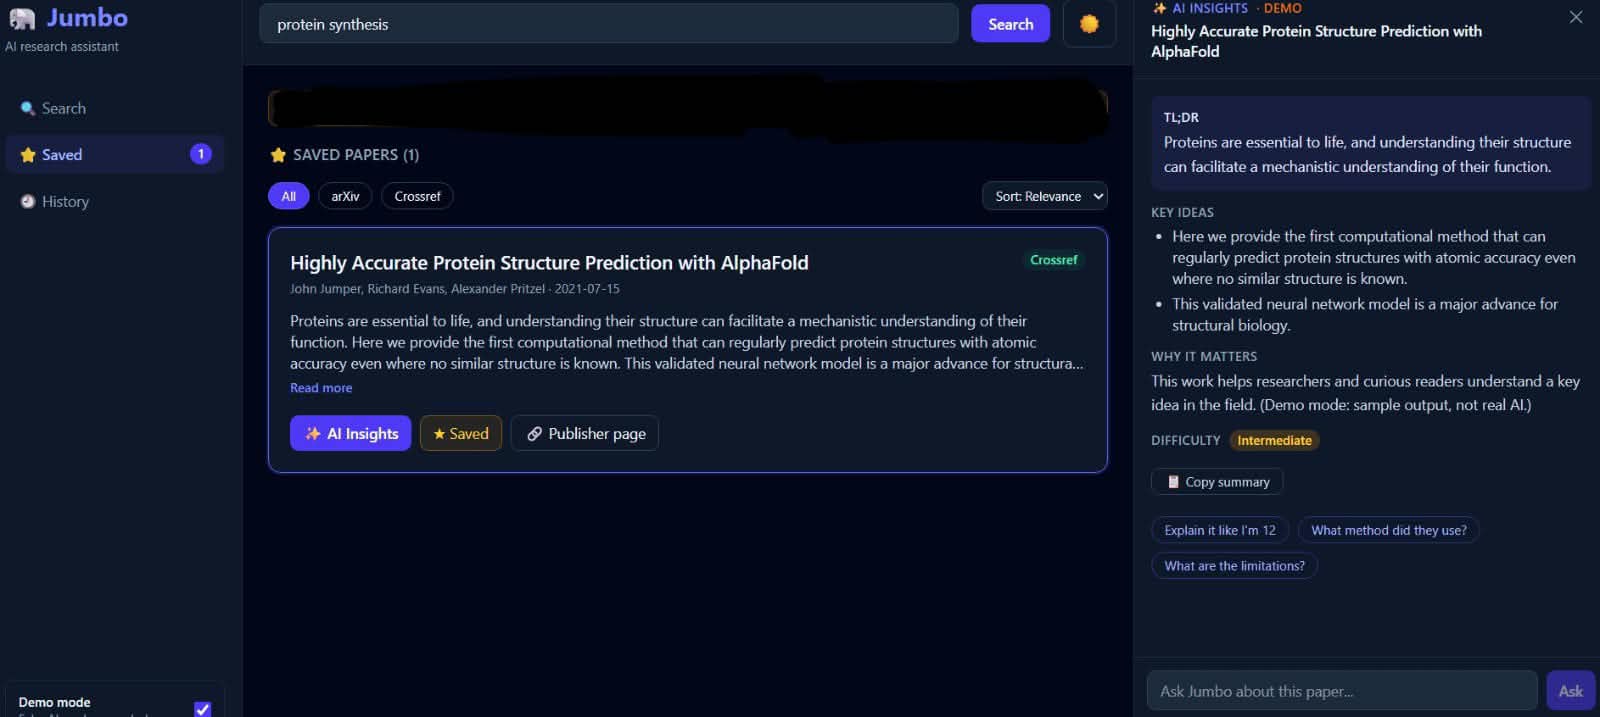
how ai insights work
Inspiration
Millions of research papers are published every year, and even experts cannot read them all. For students and curious people, the language is dense and hard to follow. We asked a simple question: what if anyone could understand a scientific paper in under a minute? That is how Jumbo was born, an AI research assistant that makes papers readable.
What it does
Jumbo helps you discover papers and understand them in plain English.
- 🔍 Dual-source search: queries arXiv (preprints) and Crossref (published journals) at the same time and merges the results.
- ✨ AI Insights drawer: a one-sentence TL;DR, key ideas, why the paper matters, and a difficulty rating.
- 💬 Ask Jumbo: chat with a paper through follow-up questions such as "Explain it like I'm 12". Answers are grounded in the abstract, and Jumbo admits when the abstract does not contain the answer.
- ⭐ Saved library, history, filters and sorting, plus light and dark mode.
How we built it
Architecture: React + Vite + Tailwind (frontend) → FastAPI (backend) → arXiv and Crossref APIs, plus an OpenAI-compatible LLM API for the AI features.
- Frontend: React, Vite and Tailwind CSS.
- Backend: Python and FastAPI with
httpxfor parallel API calls, hosted on Render. - AI: NVIDIA Nemotron (
MODEL-ID) through an OpenAI-compatible API. Because the backend only reads three environment variables (key, base URL, model), it also works with Nebius Token Factory unchanged. - Prompt engineering: a strict system prompt fixes the output format and limits the model to the abstract, with a low temperature \( T = 0.3 \) for consistent answers.
Under the hood, these language models are Transformers built on scaled dot-product attention:
$$ \text{Attention}(Q, K, V) = \text{softmax}\left(\frac{QK^{\top}}{\sqrt{d_k}}\right)V $$
Sampling temperature controls how random the model's word choice is. The probability of picking token \( i \) with score \( z_i \) is:
$$ p_i = \frac{e^{z_i / T}}{\sum_{j} e^{z_j / T}} $$
A lower \( T \) makes answers more focused, which is what we want for factual summaries.
Search engineering: arXiv and Crossref run in parallel, and their results are interleaved as \( a_1, c_1, a_2, c_2, \dots \) with duplicate titles removed, so neither source dominates. Searches are cached for \( \tau = 600 \) seconds, which makes repeat searches instant.
Challenges we ran into
- Two data formats: arXiv returns XML and Crossref returns JSON with markup inside abstracts. We normalised both into one clean paper shape.
- Keeping AI honest: we constrained prompts to the abstract and added an explicit "I don't know" rule to reduce made-up answers.
- Billing barrier: Nebius Token Factory required a payment card for credits, which we did not have, and our request to the organizers went unanswered before the deadline. We kept building with a labelled Demo mode and fallback mode, then moved to NVIDIA's free hosted Nemotron API. The provider-agnostic backend made that a three-variable change.
- Free-tier hosting: cold starts on Render's free plan taught us to add caching and clear loading states.
Accomplishments that we're proud of
- A complete full-stack app, built and deployed as complete beginners within the hackathon deadline.
- Honest design: AI answers stay grounded in the abstract, and demo or fallback content is always labelled.
- A backend that works with any OpenAI-compatible provider, including NVIDIA and Nebius.
What we learned
- How to build and deploy a full-stack app with React and FastAPI.
- How OpenAI-compatible APIs let you swap AI providers by changing only the
base_url. - How to design prompts and interface states (loading, empty, error) that users can trust.
What's next for Jumbo
- 📄 Full-text PDF analysis instead of abstracts only
- 🆚 Side-by-side comparison of several papers
- 🕸️ Citation maps and related-paper discovery
- 👤 Accounts with synced libraries
- 🌍 Explanations in more languages
- 📤 Export saved papers to BibTeX and Markdown
Built with
React, Vite, Tailwind CSS, Python, FastAPI, httpx, NVIDIA Nemotron, OpenAI-compatible API, Nebius Token Factory (supported), arXiv API, Crossref API, GitHub


Log in or sign up for Devpost to join the conversation.