🧠 About the project
Inspiration
I run hackathons and builder communities, and one problem keeps coming up: judging is fragmented and inconsistent.
Judges have to manually piece together signals across GitHub repos, demo videos, screenshots, and pitch decks. Important details get missed, and decisions are often based on incomplete understanding.
Judge Angel was inspired by this exact pain.
I wanted to rethink judging not as scoring, but as evidence synthesis across modalities.
What it does
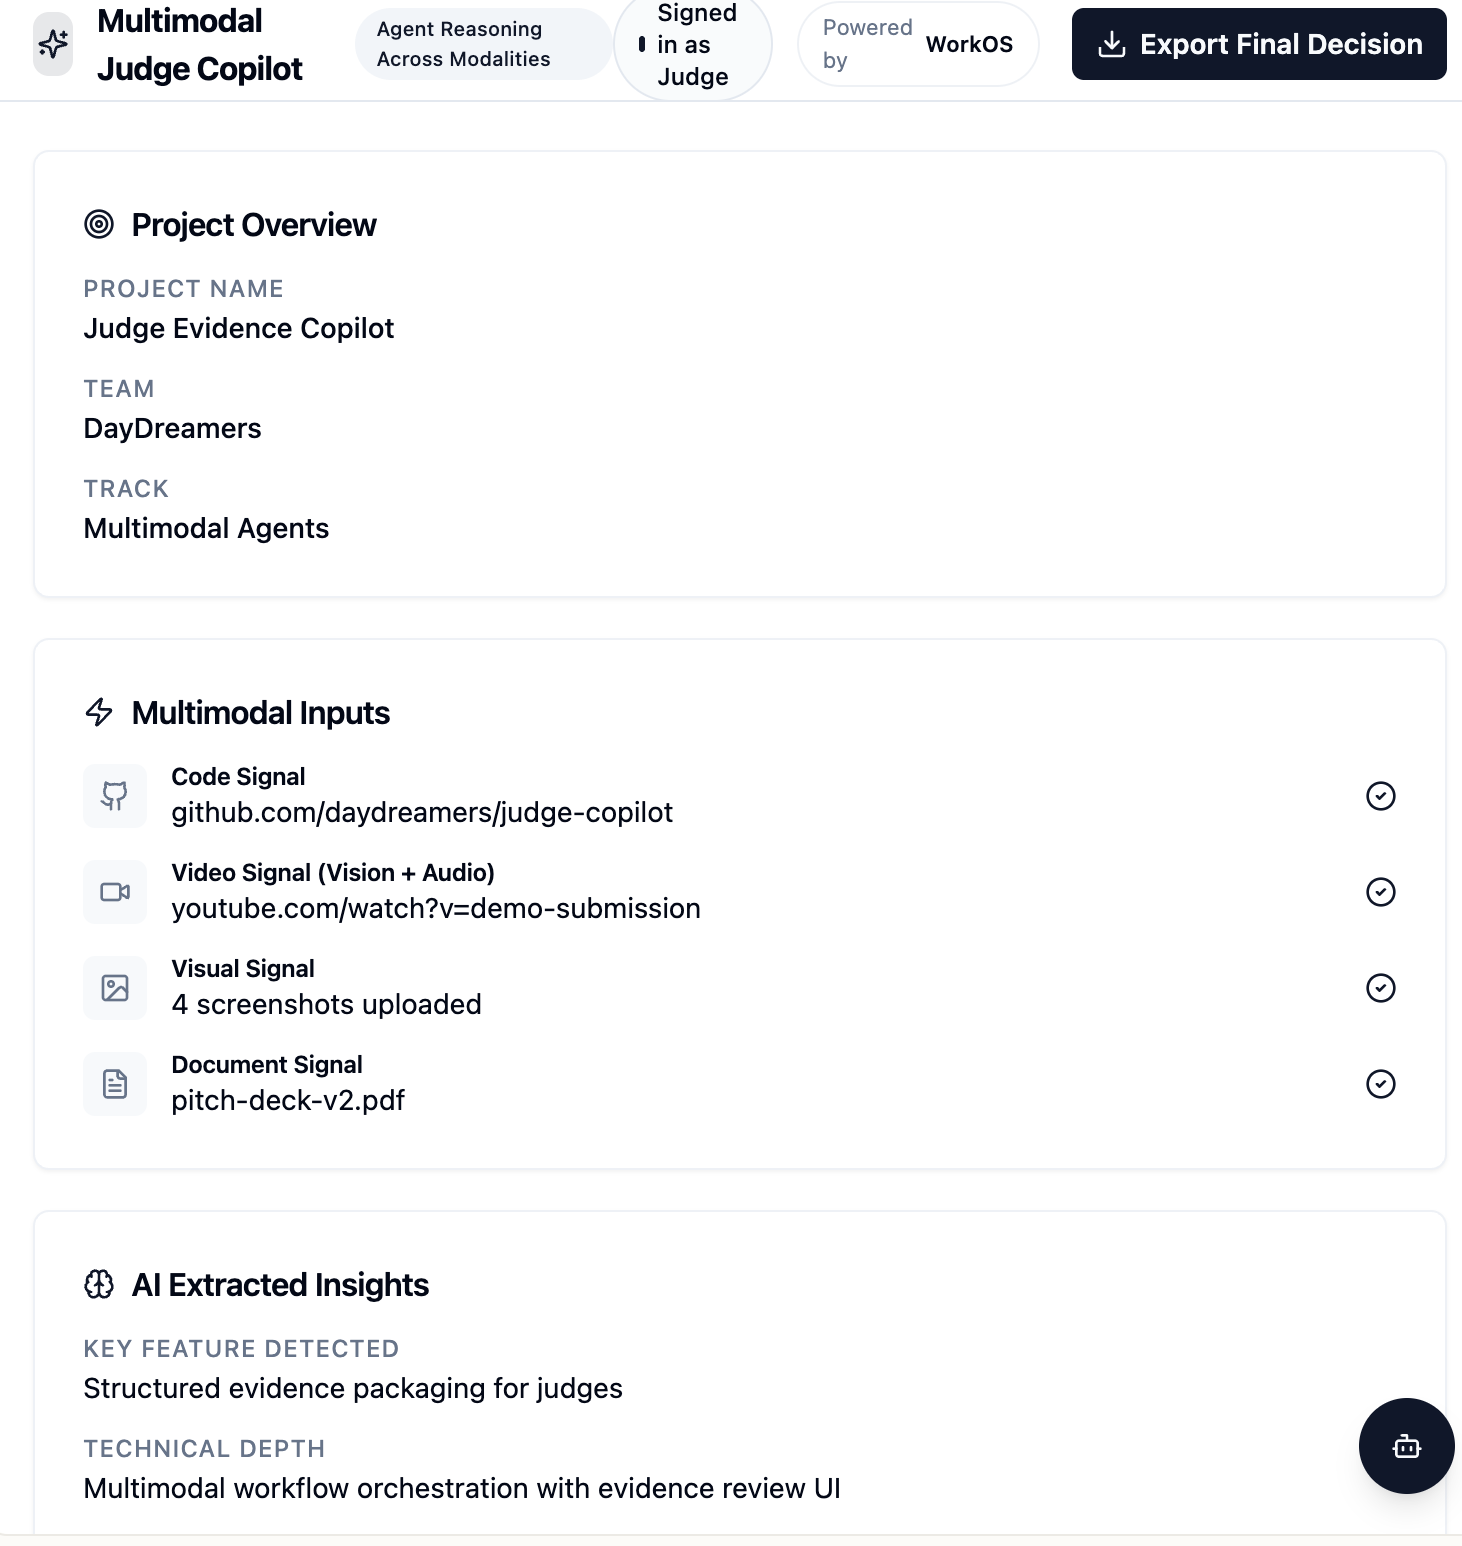
Judge Angel is a multimodal judge copilot that turns messy submissions into structured, explainable evidence.
It treats every submission as a set of signals:
- Code Signal (GitHub repo)
- Video Signal (Vision + Audio) (demo walkthrough)
- Visual Signal (screenshots, UI states)
- Document Signal (pitch deck, claims)
Instead of just displaying them, Judge Angel:
- extracts key insights
- verifies whether claims match implementation
- detects inconsistencies across modalities
- generates a structured judging rationale
The core idea is simple:
We verify whether what teams claim actually matches what they built.
How we built it
We focused on building a fast, clear vertical slice aligned with real judging workflows.
- Lovable to generate and iterate the full-stack app quickly
- Assistant-style UI to create a judge copilot that reasons over evidence
- WorkOS-inspired role design to model secure judge access and permissions
We structured the product around three key components:
Evidence Pack
A unified view of all submission materialsCross-Modal Verification
A layer that checks consistency between repo, video, visuals, and docsJudge Agent
An AI copilot that reasons over all signals and generates a final rationale
Challenges we faced
The hardest challenge was defining what it means for an AI system to “understand” across modalities.
- How do you compare a demo video with a codebase?
- How do you validate whether a claim in a pitch deck is actually implemented?
- How do you make AI outputs feel like reasoning instead of summarization?
We addressed this by introducing cross-modal verification, where the system checks alignment between different evidence sources instead of treating them independently.
Another challenge was balancing speed and depth in a hackathon setting, so we focused on building a convincing, high-impact slice rather than a fully production-ready system.
What we learned
- Multimodal AI becomes powerful when applied to real workflows
- Judges don’t need more data, they need structured understanding
- Trust comes from clarity, explainability, and consistency
What’s next
Judge Angel can extend beyond hackathons:
- startup demo evaluation
- grant and fellowship selection
- hiring and portfolio review
Built With
- assistant-ui
- github
- lovable
- multimodal
- react
- typescript
- vercel
- workos
