-
-
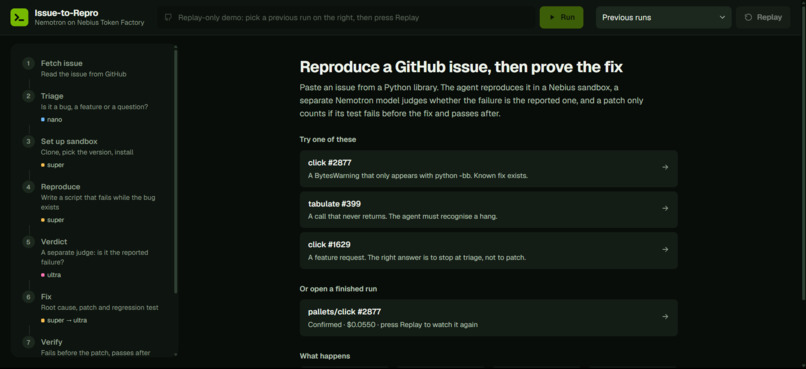
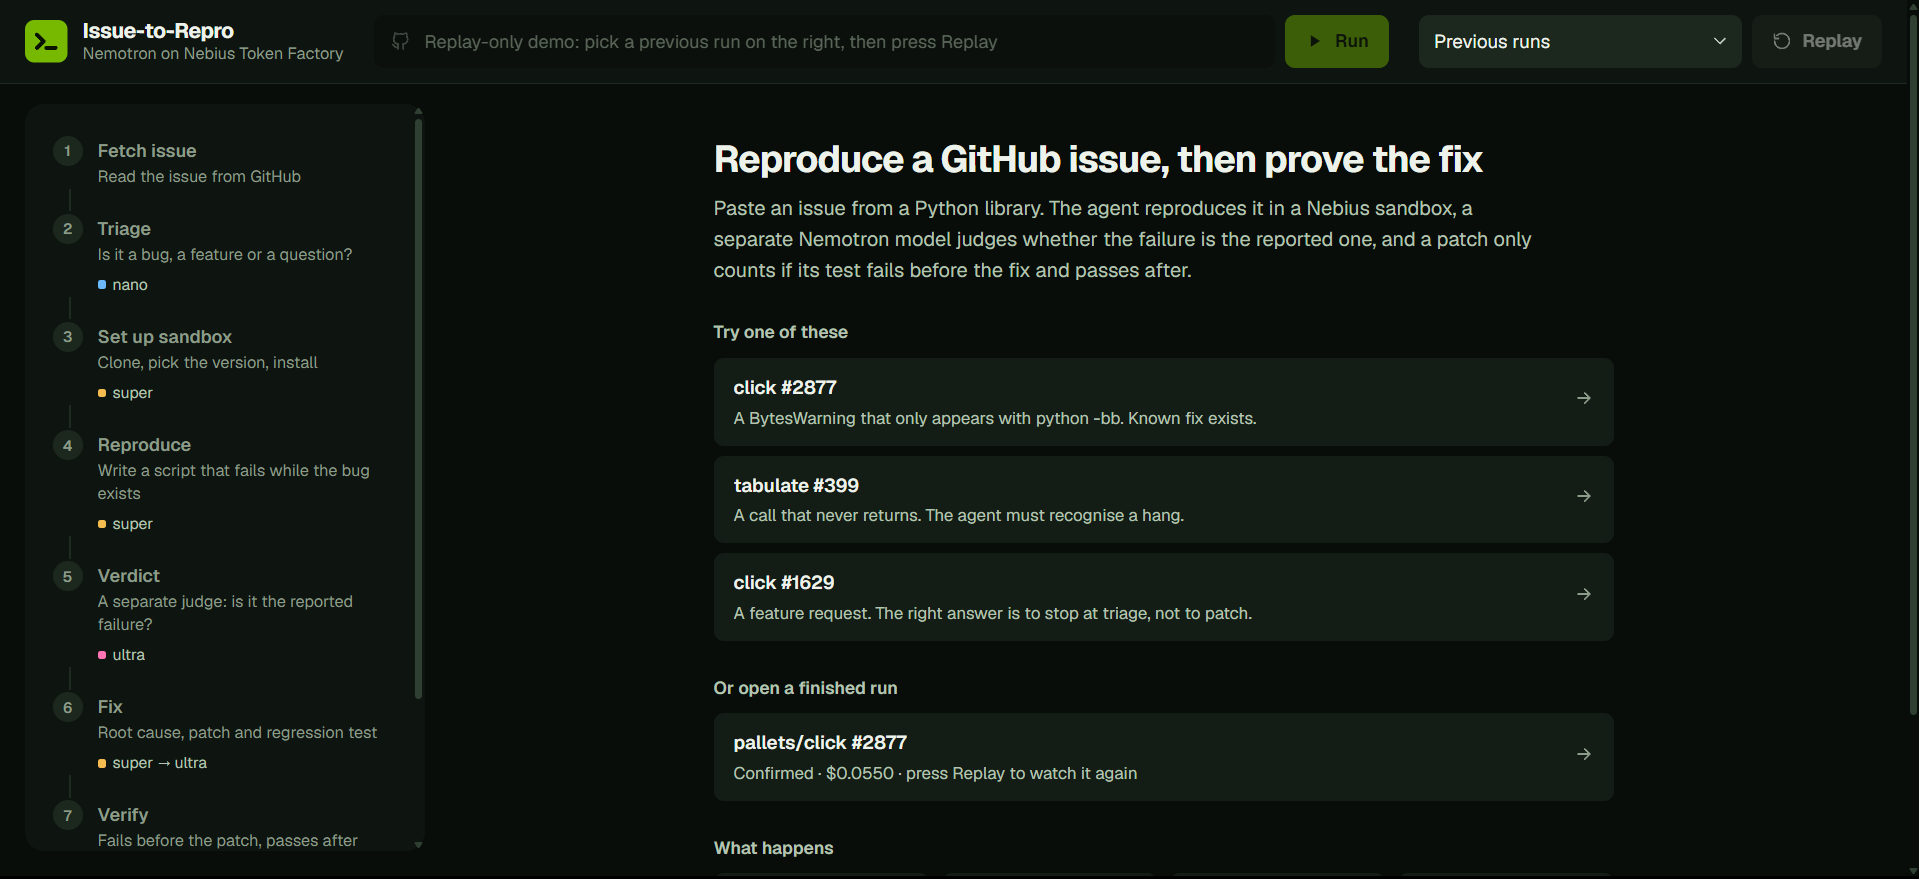
Home Page
-
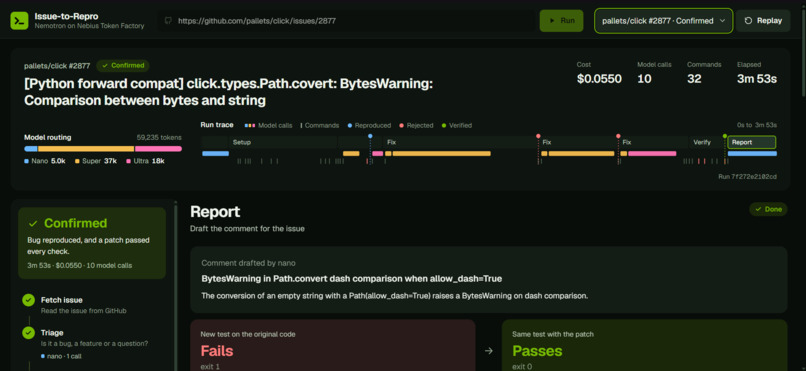
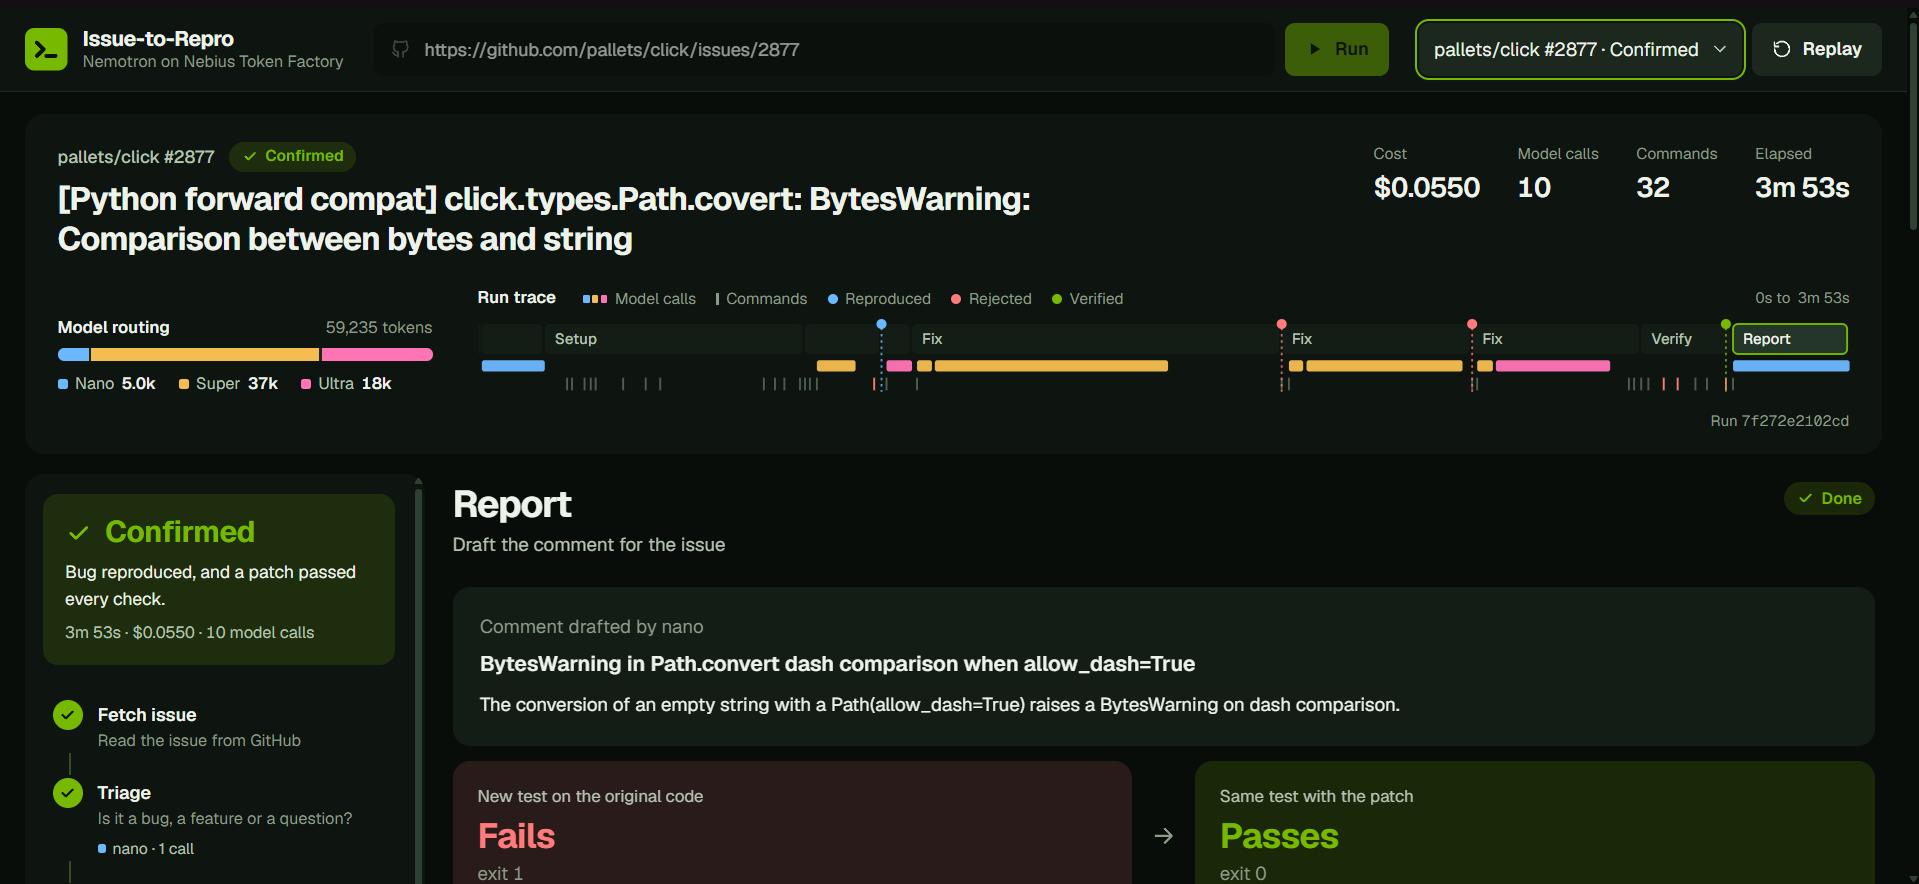
Github issue link added and is ran to show results
-
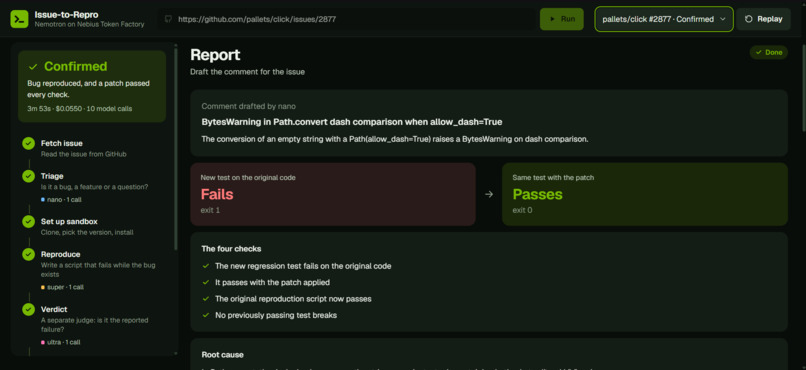
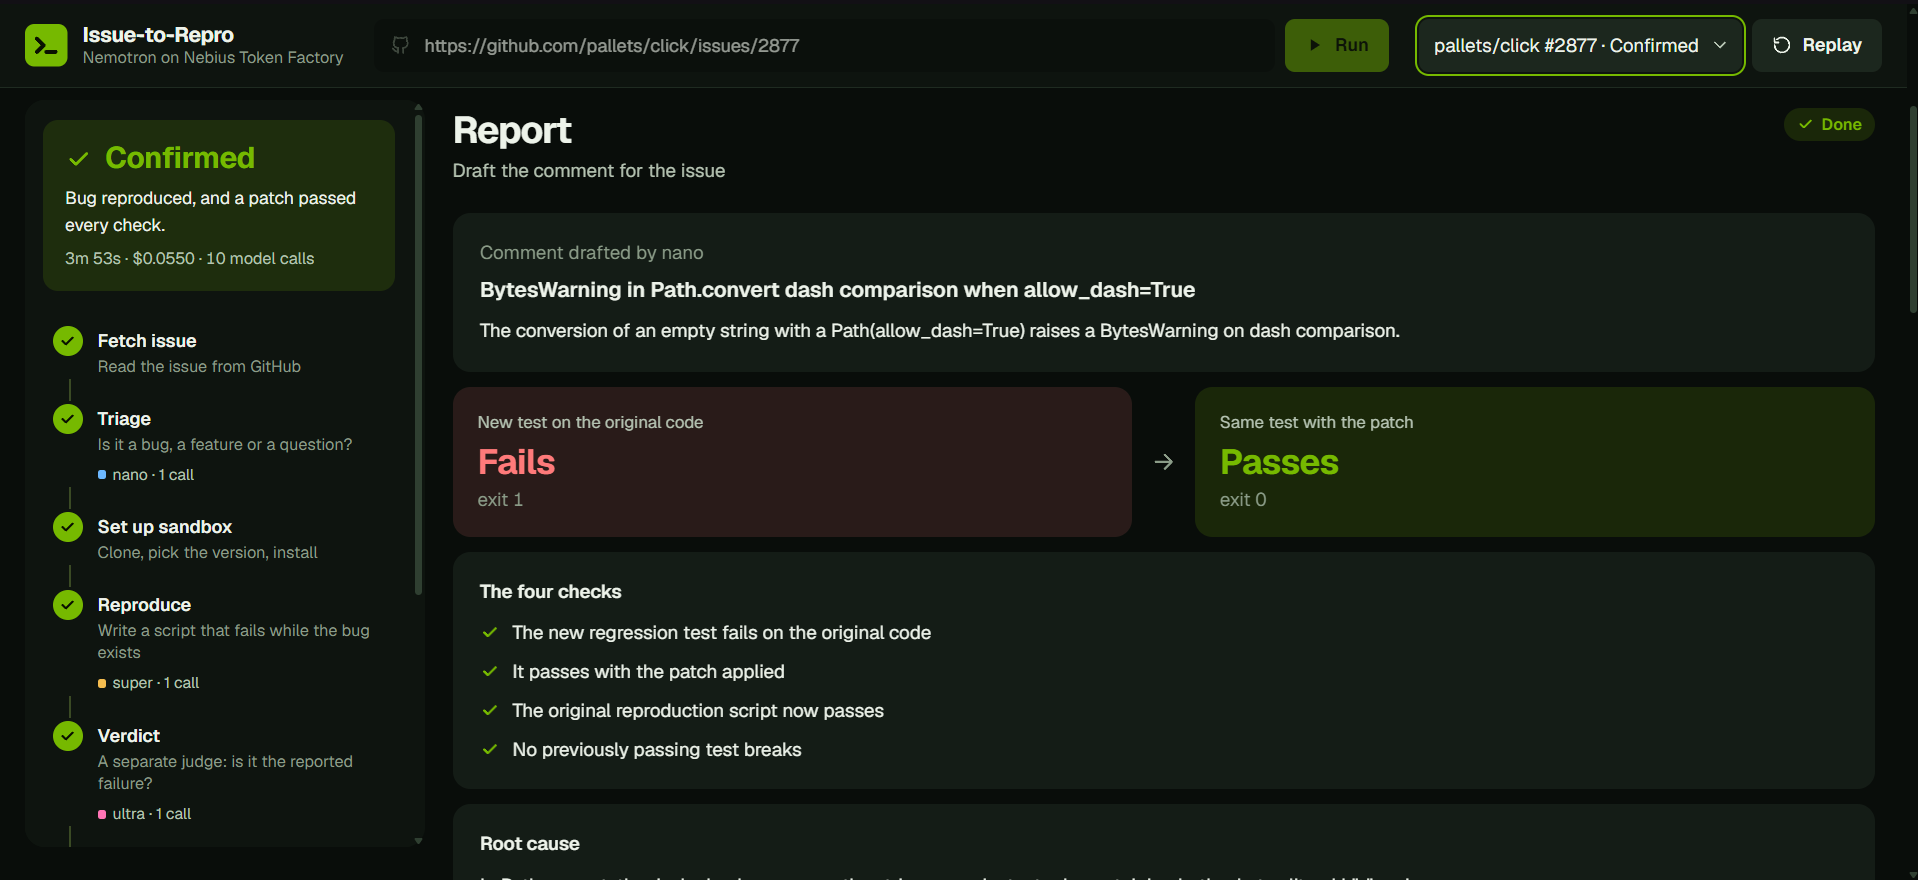
Report with 4 checks and root cause
-
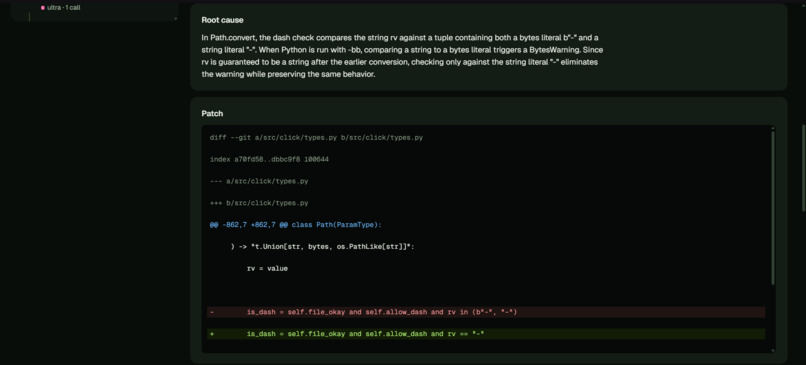
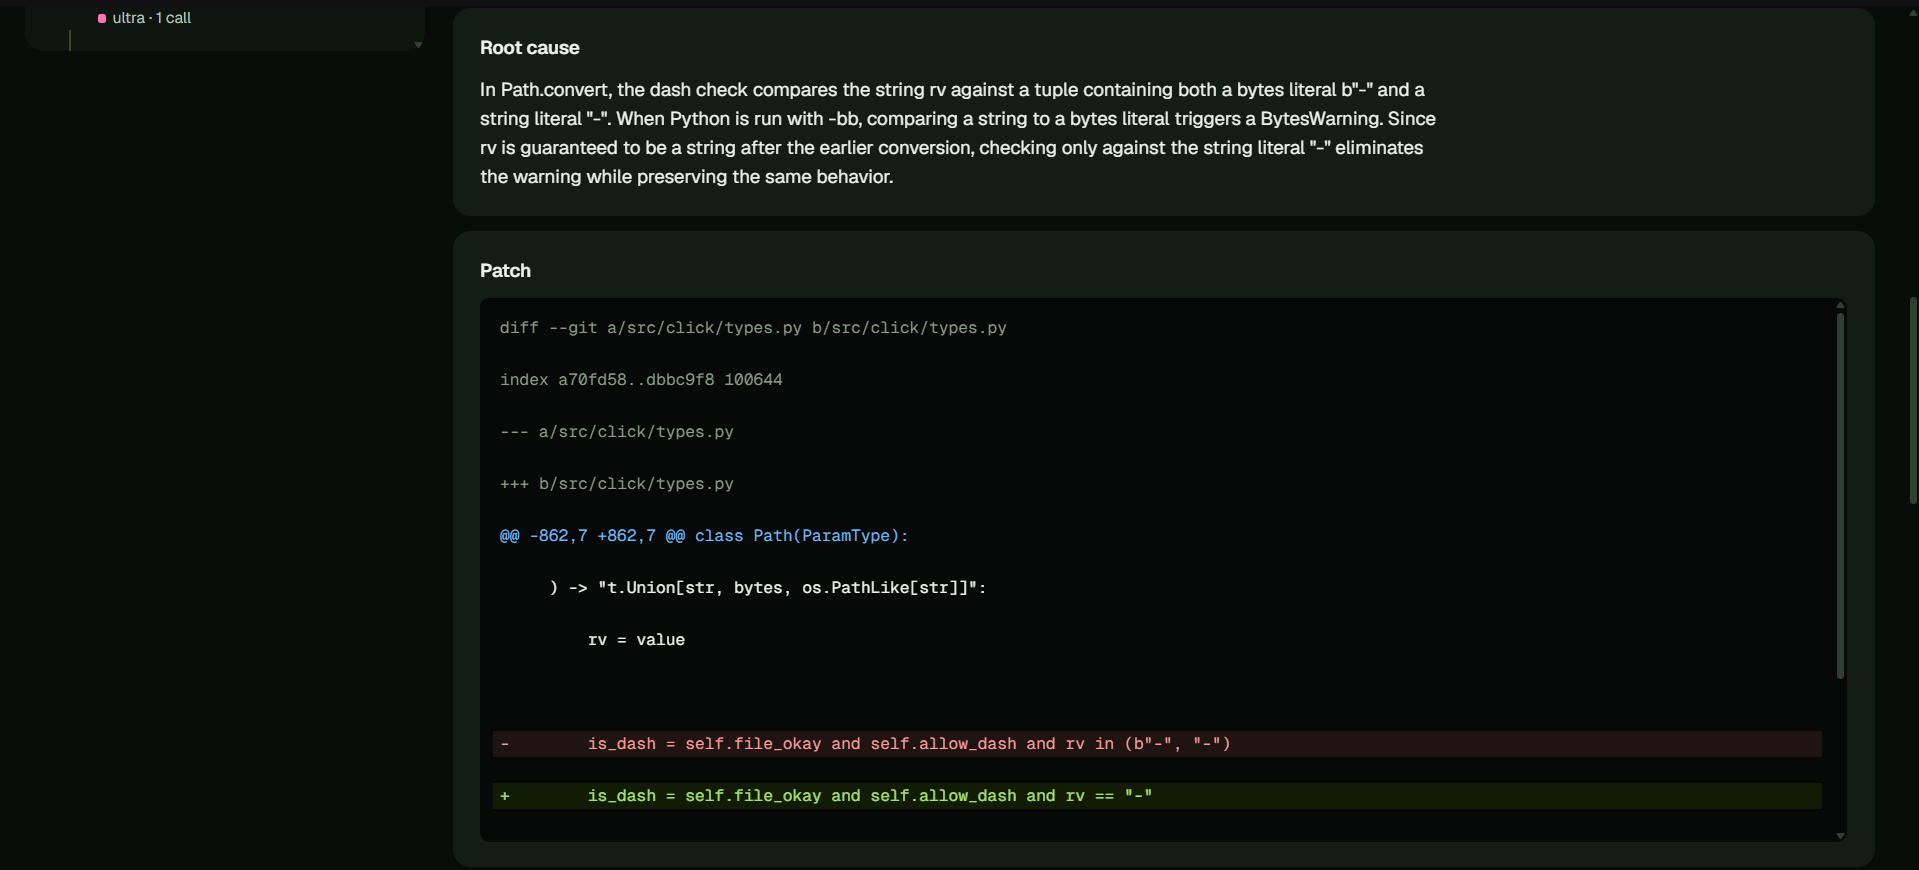
Patch code
Inspiration
Every maintainer knows the first hour of a bug report: before anyone can fix it, someone has to reproduce it. Reports are vague, versions are missing, and some "bugs" are feature requests or only happen on Windows. We wanted an agent that does that first hour, and, just as important, one that knows when to say "I couldn't."
What it does
Issue-to-Repro returns one of five honest outcomes:
- CONFIRMED: a reproduction script, a patch, and a regression test, with proof that the test fails on the original code and passes on the patched code.
- NOT_REPRODUCED, NEEDS_MAINTAINER, SETUP_FAILED or ERROR, each with the reason.
A fix is never accepted on a model's say-so. Plain code runs the checks:
- the new test fails on the original code,
- it passes on the patched code,
- the original reproduction now exits 0,
- the project's own test suite shows no new failures (a suite that hangs after the patch counts as a failure).
How we built it
A state machine, each stage using the smallest Nemotron 3 model that can do the job, all served by Nebius Token Factory:
| Stage | Model | Job |
|---|---|---|
| TRIAGE | Nemotron 3 Nano | bug, feature or question? |
| SETUP / REPRO / FIX | Nemotron 3 Super | install the project, write the repro, write the patch |
| VERDICT | Nemotron 3 Ultra | skeptical judge: does the failure really match the report? |
| REPORT | Nano | summarize, claiming nothing that was not done |
Everything runs inside Nebius Token Factory Sandboxes. The FastAPI backend streams live events (SSE) to a web UI that shows the stages, token use and running dollar cost. Each run has hard caps on tokens, time and money. Cost per 1M tokens grows steeply with the tier, so using Ultra only where judgement matters keeps a typical run to a few cents:
$$\text{cost} = \sum_{t \in {\text{nano, super, ultra}}} \left( p^{\text{in}}_t \, n^{\text{in}}_t + p^{\text{out}}_t \, n^{\text{out}}_t \right)$$
Results
On 8 real, closed issues from click, tabulate and cachetools (each pinned to the commit just before the real fix), 6 of 8 outcomes were correct in our latest full run, for $0.39 in total: 4 bugs confirmed, plus the Windows-only bug and a feature request correctly declined. The two misses ended in "needs a maintainer", not in a wrong fix. One confirmed patch is identical to the maintainers' own fix.
We also audited the CONFIRMED patches by hand and published what we found: one leaves a cache over its size limit in an edge case. So CONFIRMED means "every automatic check passed", not "correct in every case", and the report says a maintainer should review the patch.
What we learned
- Make model output checkable. Anything the model claims, code should be able to confirm by running something.
- Repair mechanical mistakes, check checkable ones, and send judgement to a reviewer model. Models put the wrong indentation on edits four times in a row; code now repairs that.
- An eval number needs a code version and a rate, not a single run. Results vary run to run, so our harness records every run and reports a match rate.
- When a verifier rejects a correct answer, ask whether the oracle is wrong. In one case the reproduction script, not the patch, was the problem.
Challenges
- Reasoning tokens eat the budget. Nemotron "thinks" before answering, and thinking counts toward
max_tokens, so some fix calls came back empty. We now escalate to a stronger tier after an empty reply. - A hole in our own gate. A patch that made an existing test hang slipped through because we treated "the suite did not finish" as "could not run". Now it is a failure.
- Stacked retries. Retry layers in the client and the agent multiplied during outages, so we separated "retry the world's hiccups" from "never retry a no".
- A network outage polluted our eval history. We made the harness wait for the network and exclude infrastructure errors from the match rate.
- Cost. One Ultra call costs many times a Nano call, so every extra model call had to earn its place.
What's next
Reviewer probes that try edge cases the tests do not cover, support for more languages than Python, and a GitHub bot that comments the verified reproduction directly on the issue.
Built with
Nebius Token Factory · Nebius Token Factory Sandboxes · NVIDIA Nemotron 3 Nano / Super / Ultra · Python · FastAPI · SQLite · Server-Sent Events · Docker · Vercel

Log in or sign up for Devpost to join the conversation.