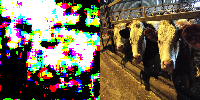

I trained a LSTM-convnet (encoder-decoder) neural network architecture to map text input into image output. It works relatively well as can be seen in the examples. Dataset: http://vision.cs.uiuc.edu/pascal-sentences/
Updates

Leave feedback in the comments!