-
-
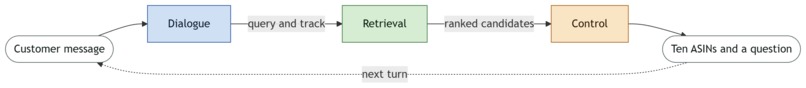
Overall Architecture Diagram
How your solution addresses the problem statement
The shopper knows what they want but only reveals it when asked, so the idea is to extract relevant information and keeping it. We verified that BM25 alone already contains the target in its top 500 for all 200 sessions, which means the bottleneck is ordering, not recall. The agent is built in three stages.
Dialogue turns the conversation into a query. Every message is accumulated and joined into one search string, because each fact is disclosed once and never repeated. A lexical cue detects intent overrides and resets the shown-item set while keeping the accumulated query, since the abandoned preference still describes the target. Each turn is routed buying or browsing.
Retrieval turns the query into a ranked list. BM25 over SQLite FTS5 with per-field weights runs
alongside a bge-small-en-v1.5 bi-encoder searching 50,000 precomputed vectors by exact cosine
similarity. The two lists merge by reciprocal rank fusion, which combines on rank position because
BM25 scores and cosine similarities are not on a comparable scale, with weights conditioned on the
track. The top 20 are then reordered in a single listwise LLM call using permutation generation,
loosely following RankGPT.
Control selects and asks. Identifiers are validated against the catalog, unseen items are
preferred so ten turns reach up to 100 distinct products, and every turn sets
ask_attribute="other", which returns the next two undisclosed constraints of any type rather than
one attribute. That single choice is the largest contributor to the score.
Results on the 200 public sessions: composite 0.828623 against the provided BM25 baseline
of 0.10671. Hit@10 0.965, MRR 0.6087, MTTC 2.83. With no API key the agent falls back to
the fused retrieval order and still scores 0.800304, so a missing or failing key never breaks a
run. A full evaluation costs about $0.10 and 546k tokens.
Development tools used
- Python 3.12.10
- Git and GitHub, VS Code
- The organizers'
local_evaluator.pyas the sole scoring harness, left unmodified - Claude Code for pair programming and ablation analysis
APIs used
- OpenAI API (
gpt-4o-mini) paid API for LLM listwise reranking, one call per turn - litellm as a provider-agnostic router, so Gemini, Groq or Anthropic can be swapped in by changing one model string with no code change
- Hugging Face Hub for a one-time encoder download at setup
Libraries and frameworks used
sentence-transformers6.0.0 for query and document encodingtorch2.13.0+cpunumpy2.5.2 for the exact cosine search over a 50000 x 384 matrixlitellm1.98.0 andpython-dotenv1.2.3sqlite3FTS5 from the standard library for BM25 (from starter agent)
Datasets and assets used
- Frozen 50,000-item Amazon Reviews 2023
Clothing_Shoes_and_Jewelrycatalog, provided - 200 public evaluation sessions, provided
BAAI/bge-small-en-v1.5sentence encoder, pinned to revision5c38ec7c- Generated offline:
embeddings.npy, a 50000 x 384 float32 matrix, built by a documented command in repo and not committed

Log in or sign up for Devpost to join the conversation.